En 30 segundos
In this February 2026 short, Matthew Berman highlights Google’s Gemini 3.1 Pro benchmark table and explains the pattern-matching structure of ARC-AGI-2. Google reports 44.4% on Humanity’s Last Exam without tools, 77.1% on ARC-AGI-2, 94.3% on GPQA Diamond and 80.6% on SWE-Bench Verified under the listed settings. The 94.3% figure is for GPQA, not ARC-AGI-2.
- 1Humanity’s Last ExamGoogle reports 44.4% without tools on the full text and multimodal set.
- 2Abstract reasoningARC-AGI-2 uses example transformations; Google lists a verified Gemini 3.1 Pro score of 77.1%.
- 3Separate science scoreThe chart’s 94.3% corresponds to GPQA Diamond, not ARC-AGI-2.
- 4Coding scoreThe reported SWE-Bench Verified score is 80.6% for a single attempt, near the table’s 80.8% for Opus 4.6.
Conclusiones
- Google reported 44.4% on the full Humanity’s Last Exam without tools for Gemini 3.1 Pro Thinking (High).
- Its ARC Prize-verified ARC-AGI-2 score was 77.1%; the nearby 94.3% is the GPQA Diamond score.
- Google reported 80.6% on SWE-Bench Verified using a single attempt, close to the listed Opus 4.6 result of 80.8%.
- These historical benchmark results depend on the model and evaluation settings and do not establish performance on every task.
Lee el texto editado por capítulos
Gemini 3.1 Pro benchmark highlights
Berman points to the no-tools Humanity’s Last Exam score and explains ARC-AGI-2. He then highlights the GPQA and coding results shown in Google’s benchmark table.
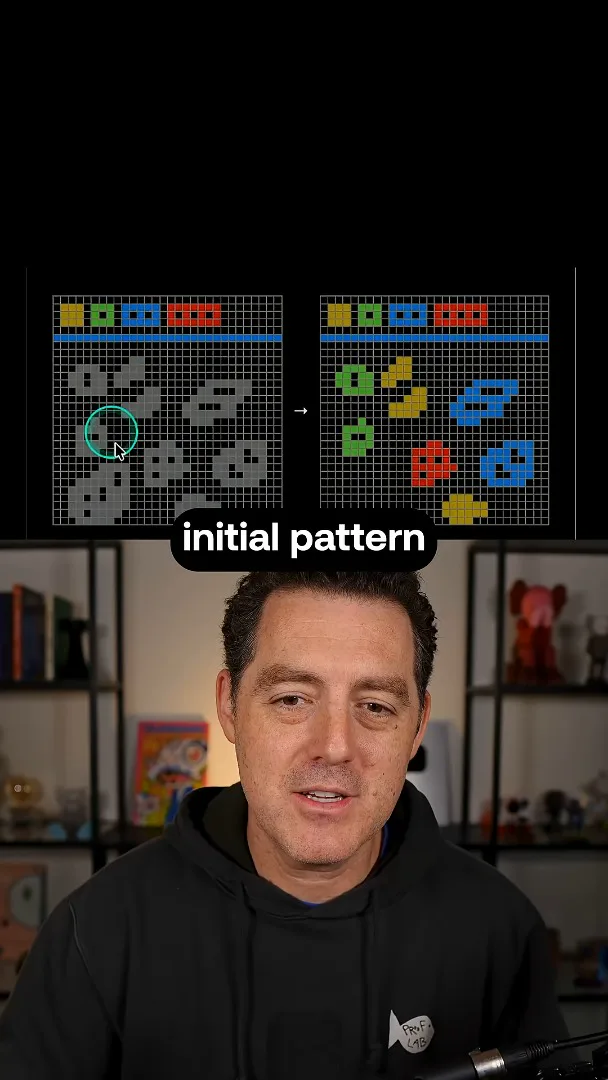
Google’s launch table shows Gemini 3.1 Pro Thinking (High) at 44.4% on the full Humanity’s Last Exam without tools. I also highlight ARC-AGI-2, which gives examples of a visual transformation and asks the system to solve a new instance. Google reports an ARC Prize-verified score of 77.1% on that benchmark.
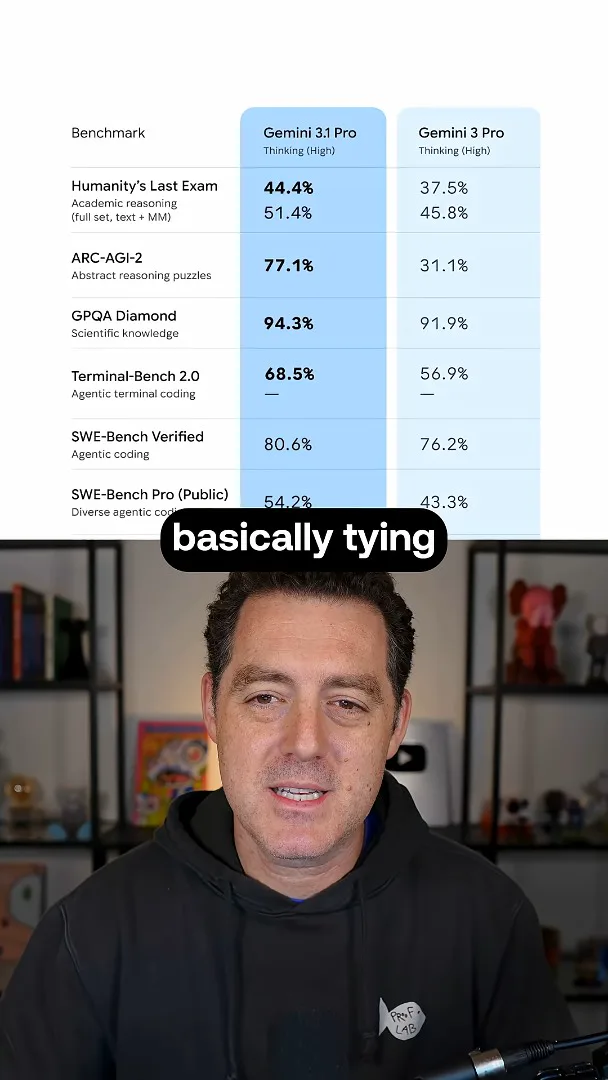
The 94.3% figure shown next is for GPQA Diamond, a scientific-knowledge benchmark, rather than ARC-AGI-2. Google’s table also reports 80.6% on SWE-Bench Verified with a single attempt, close to the 80.8% listed for Claude Opus 4.6. These are launch-era results under specific configurations, not a guarantee of equivalent performance across all coding tasks.
Más de este canal
 34:21EN
 Matthew Berman· 27 oct 2026Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 0:26ENMatthew Berman· 25 oct 2026Sam Altman on Human Values and Problem-Solving in an AI WorldSam Altman · OpenAIIn a short interview excerpt, Altman considers the enjoyment of solving hard problems and the human role in interpreting results.
 0:36ENMatthew Berman· 25 oct 2026Kimi K3.1 and a Rubik’s Cube Solver DemonstrationMatthew Berman · Forward FutureMatthew Berman shows a scrambled virtual cube being solved and gives the Kimi K3.1 test a favorable assessment.
 0:21ENMatthew Berman· 24 oct 2026An AI-Generated Kimi Benchmark Chart Used Invented ScoresMatthew Berman · Forward FutureMatthew Berman asks for a graph of Kimi K3.1 Pro benchmarks, then discovers that the displayed figures are illustrative placeholders.
 25:50ENMatthew Berman· 24 oct 2026Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.
 32:20ENMatthew Berman· 23 oct 2026Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.