En 30 segundos
Matthew Berman asks DeepSeek for a 1,000-word essay and estimates that it generates at roughly 200 tokens per second. He then highlights the displayed DeepSeek-V4.1-Flash API pricing and calls the model a fast, inexpensive workhorse. The speed and response length are his estimates from one demonstration, not a measured benchmark. The input prices he quotes apply to cache misses; prices and available models can change.
- 1Essay demonstrationBerman requests a 1,000-word essay and estimates its speed at roughly 200 tokens per second.
- 2Input pricesThe September 2026 slide lists $0.15 off-peak and $0.30 peak per million cache-miss input tokens.
- 3Output pricesThe slide lists $0.60 off-peak and $1.20 peak per million output tokens.
Conclusiones
- Berman estimates about 200 tokens per second and six seconds for his requested essay, without providing a measured token count.
- The displayed V4.1 Flash off-peak rate was $0.15 per million cache-miss input tokens and $0.60 per million output tokens.
- The displayed peak rates were $0.30 per million cache-miss input tokens and $1.20 per million output tokens.
- Speed and cost vary with the workload, serving conditions and pricing schedule.
Lee el texto editado por capítulos
Speed test and API pricing
Berman demonstrates an essay request and estimates generation speed. He then reviews V4.1 Flash peak and off-peak prices and gives his impression of the model.
I ask DeepSeek for a 1,000-word essay about DeepSeek and am impressed by how quickly the response appears. I estimate around 200 tokens per second and approximately six seconds for the response. This is a visual estimate from one run: the video does not establish the actual output token count, completed word count or a repeatable throughput measurement.
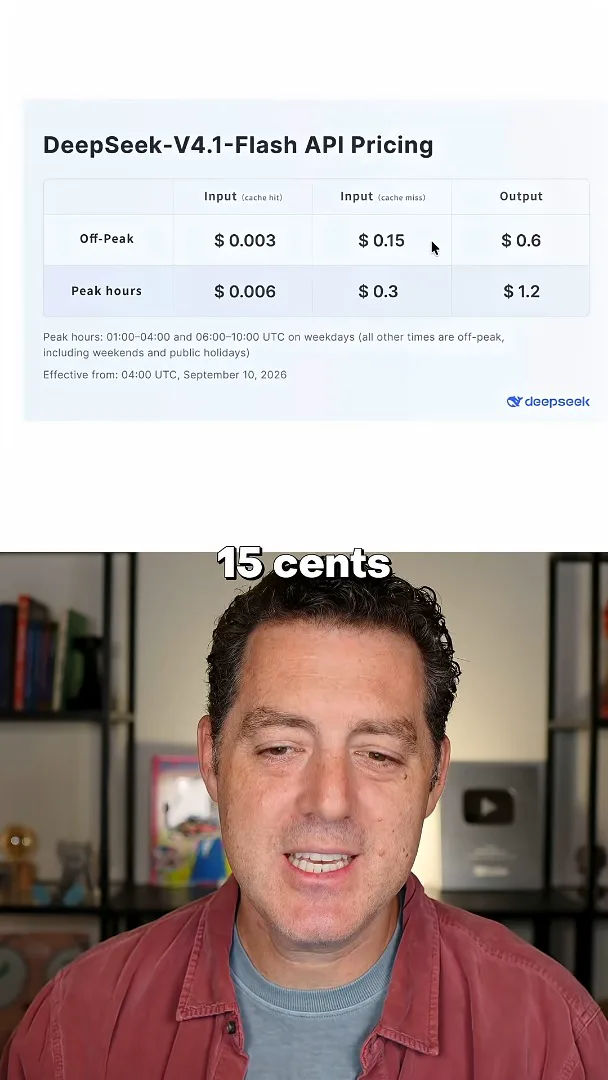
The on-screen DeepSeek-V4.1-Flash API slide lists a September 2026 rate of $0.15 per million input tokens off-peak and $0.30 during peak hours for cache misses. It also shows lower cache-hit rates of $0.003 and $0.006 respectively. These are historical API rates, not a guarantee of current prices.
For output, the slide lists $0.60 per million tokens off-peak and $1.20 at peak. I consider it a fast, efficient and inexpensive workhorse, though actual speed, cost and suitability depend on the task and service conditions.
Más de este canal
 34:21EN
 Matthew Berman· 27 oct 2026Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 0:26ENMatthew Berman· 25 oct 2026Sam Altman on Human Values and Problem-Solving in an AI WorldSam Altman · OpenAIIn a short interview excerpt, Altman considers the enjoyment of solving hard problems and the human role in interpreting results.
 0:36ENMatthew Berman· 25 oct 2026Kimi K3.1 and a Rubik’s Cube Solver DemonstrationMatthew Berman · Forward FutureMatthew Berman shows a scrambled virtual cube being solved and gives the Kimi K3.1 test a favorable assessment.
 0:21ENMatthew Berman· 24 oct 2026An AI-Generated Kimi Benchmark Chart Used Invented ScoresMatthew Berman · Forward FutureMatthew Berman asks for a graph of Kimi K3.1 Pro benchmarks, then discovers that the displayed figures are illustrative placeholders.
 25:50ENMatthew Berman· 24 oct 2026Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.
 32:20ENMatthew Berman· 23 oct 2026Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.