En 30 segundos
In January 2026, Matthew Berman discusses OpenAI’s agreement to add Cerebras inference capacity, comparing specialized chips, a speed chart and the competing demands of model training and deployment. He argues faster responses could improve coding workflows, but his 100-times-faster ChatGPT scenario is not established by the displayed benchmark. The video includes a paid Zapier sponsorship. Later Cerebras filings clarify the contract and rollout, and its June results announced an IPO and valued the deal at more than $20 billion.
- 1A phased capacity dealOpenAI and Cerebras announced 750 MW of low-latency inference capacity. Later filings describe staged deployment from 2026 to 2028 and separate service terms for each tranche.
- 2Groq and NvidiaGroq said it licensed inference technology non-exclusively to Nvidia and remained independent while some of its leaders and staff joined Nvidia.
- 3A specific benchmarkThe video shows output speed for gpt-oss-120b with 1,000 input tokens. Its figures compare providers under that test and do not establish a 100-fold ChatGPT improvement.
- 4Wafer-scale memoryCerebras has substantial on-chip memory; some systems also use external memory, so not everything is necessarily on the wafer.
- 5Why speed mattersBerman says rapid responses make coding iteration and other interactive work less frustrating, while he is comfortable waiting for deep research.
- 6Capacity trade-offsHe suggests specialized inference capacity might free resources for model training, but the allocation and effects on future model quality are uncertain.
Conclusiones
- OpenAI and Cerebras announced a multi-year agreement for 750 MW of inference capacity, to be deployed in stages through 2028.
- The displayed gpt-oss-120b chart reports 3,137 versus 465 output tokens per second for Cerebras and Groq, about 6.7 times, not proof ChatGPT will be 100 times faster.
- Cerebras combines computation and memory on a wafer-scale chip, but its documented weight-streaming systems can also use external memory.
- Nvidia and Groq announced a non-exclusive technology license and the transfer of some staff, while Groq remained independent.
- Faster inference can improve interactive workflows, though end-to-end latency also depends on the model, request, workload and other system components.
- More inference capacity could change resource allocation, but better future models and universal user benefits are Berman’s predictions, not guaranteed outcomes.
Lee el texto editado por capítulos
The rise of specialized AI hardware
Berman places the Cerebras deal in the context of Google’s TPUs and Nvidia’s Groq licensing agreement. He argues that fast, economical inference is commercially important.
OpenAI has announced a partnership with Cerebras to bring more high-speed inference capacity online. I want to unpack why this matters, beginning with Google’s Gemini 3 and the hardware competition around it. Inference is the work a model does when it processes a request and produces a response.
Google released Gemini 3 in November 2025, and I saw it as a strong frontier model on many benchmarks. Google used its own TPUs for training and serving; that illustrates that Nvidia GPUs are not the only hardware capable of supporting major models. It was not, however, the first powerful model trained on non-GPU hardware.
On Christmas Eve, Nvidia and Groq announced a deal involving Groq’s inference technology. Groq described it as a non-exclusive license, said founder Jonathan Ross, president Sunny Madra and other team members would join Nvidia, and said Groq would remain independent. Reports put the deal’s value around $20 billion; my claim about an antitrust motive is an interpretation, not an established explanation.
I see inference as a central source of AI revenue: training involves substantial upfront costs, while a deployed model can serve many requests. Faster, cheaper service could improve margins as demand grows. The economics are more complicated than a model being trained once and served forever: post-training, updates, inference costs and pricing all matter too.
The OpenAI agreement and the speed chart
He describes the reported deal and compares providers on an OpenAI open-weight model. The displayed measurements concern a specific benchmark, not a general guarantee for ChatGPT.
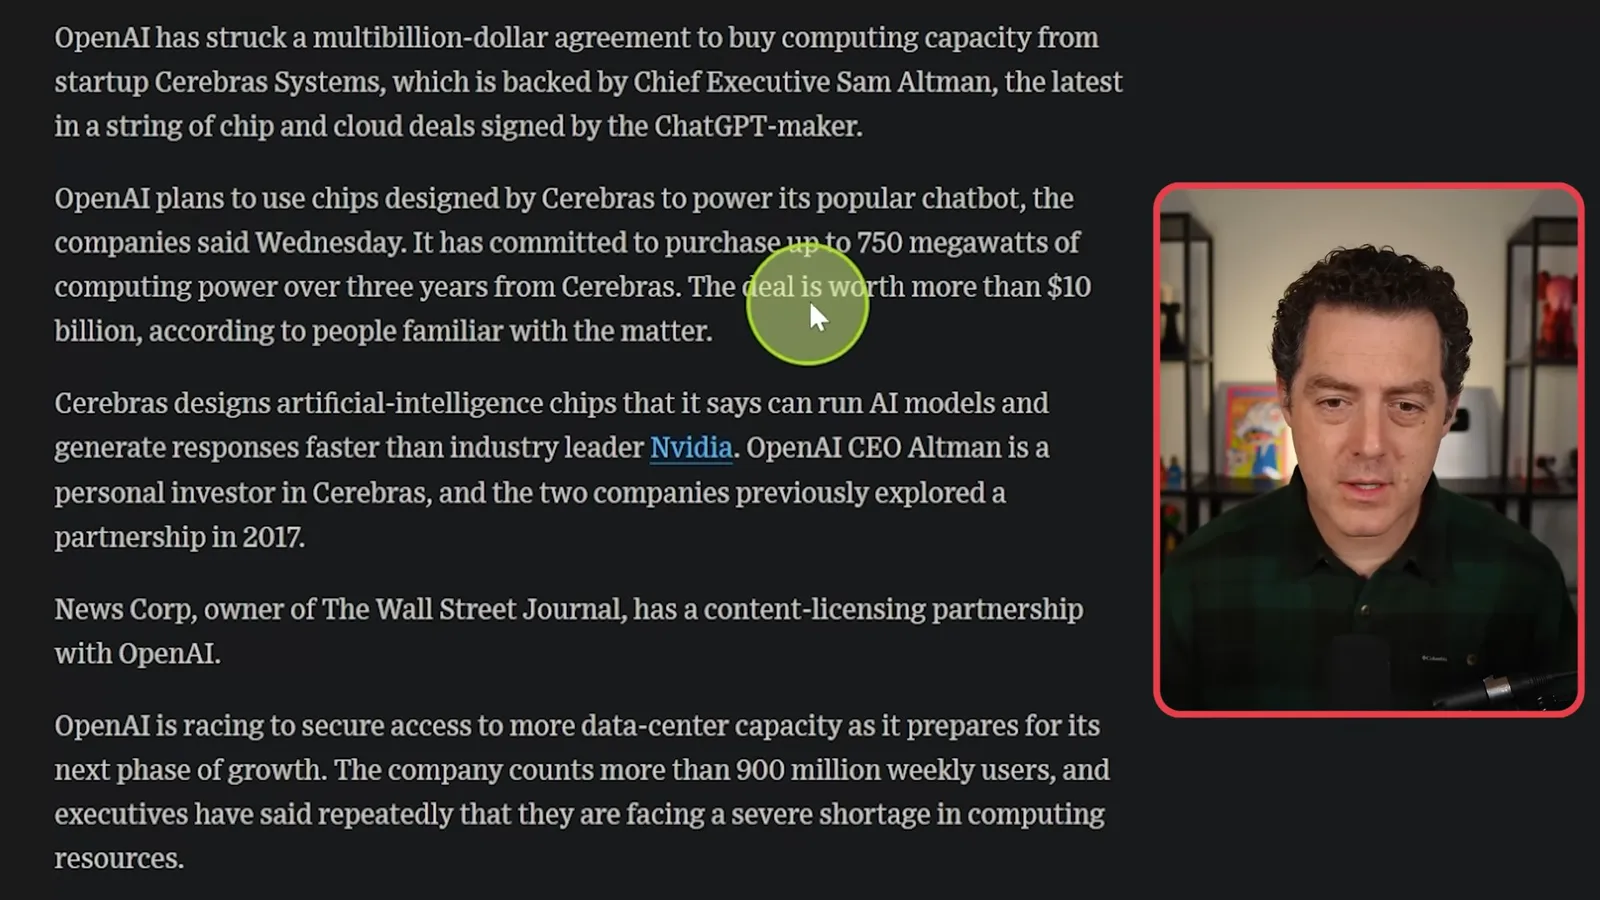
The Wall Street Journal reported that OpenAI’s Cerebras deal was worth more than $10 billion and involved 750 megawatts over three years. The companies announced a multi-year agreement for staged deployment beginning in 2026; a later Cerebras filing says the 750 MW is to be deployed in tranches through 2028, each with a three- or four-year term that OpenAI can extend to five. In June 2026, Cerebras described the agreement as worth more than $20 billion.
I can imagine OpenAI eventually acquiring Cerebras, but that is speculation, not part of the announced deal. Cerebras CEO Andrew Feldman had recently appeared on our live show without mentioning it. I also suspect OpenAI values a diversified supply of compute rather than relying too heavily on one hardware vendor; the companies did not establish that as the sole reason for their choice.
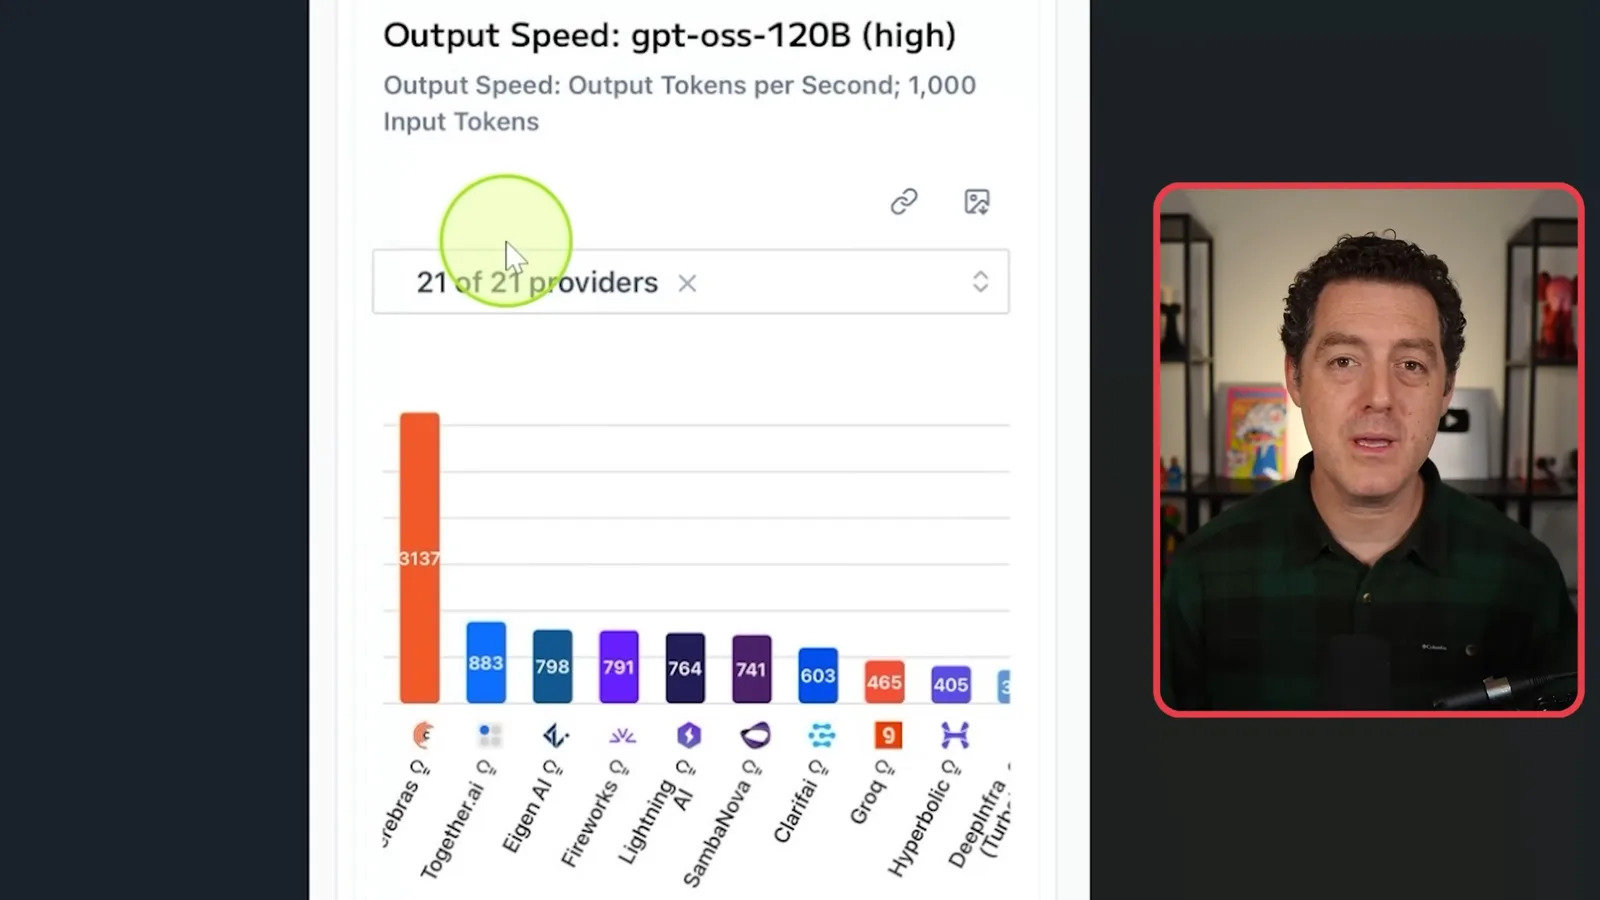
To illustrate speed, I show a chart for OpenAI’s open-weight gpt-oss-120b model at high reasoning effort, with 1,000 input tokens. The chart lists 3,137 output tokens per second for Cerebras and 465 for Groq—roughly 6.7 times in that particular comparison. Provider configuration and measurement conditions matter, and this does not establish that ChatGPT as a whole will be 100 times faster.
The video includes a paid promotion for Zapier Agents, which connects AI models and tools to applications. Its product and integration claims are the sponsor’s promotional claims.
Wafer-scale memory and the value of speed
Berman discusses Cerebras hardware and plays a clip of Andrew Feldman on memory supply. He then explains why he values response speed for coding and other interactive uses.
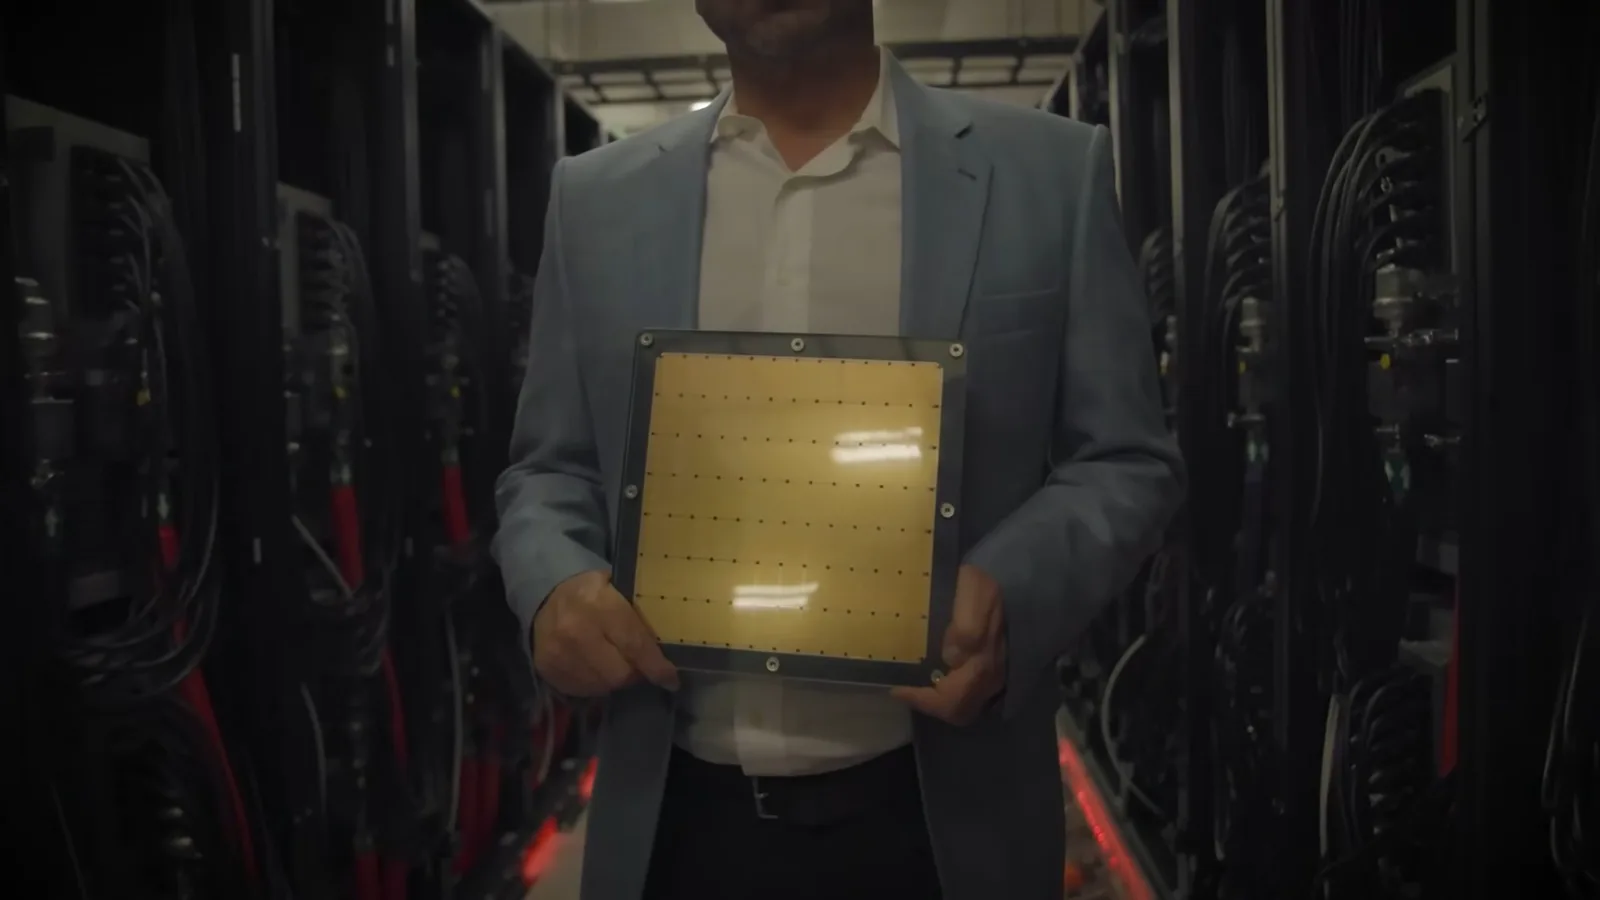
Cerebras also uses a distinctive wafer-scale architecture, combining compute and substantial memory on a large chip. I say everything is on the wafer, but that is too broad: Cerebras documents weight-streaming systems that store model weights in external MemoryX and stream them to the chip. The hardware configuration and workload therefore matter when considering its memory needs.
In a clip from our live show, Feldman says Cerebras does not use the memory whose rising price and limited supply we were discussing. He argues that competing hardware vendors waiting for such components could give Cerebras an advantage. That statement concerns the particular memory market being discussed, not immunity from every supply-chain constraint.
I imagine a much faster ChatGPT and emphasize that speed belongs alongside cost and quality in the AI trade-off. In a poll I ran on X, quality received the most votes, while I recall speed getting around 2%. That informal poll captures my audience at the time, not a representative measure of all users.
For coding, waiting for an agent to finish can interrupt the flow of work. Queued tasks and parallel agents help, but faster responses would allow more iterations; I see similar value in many interactive uses. Deep research is an exception for me: I am comfortable starting it and returning later when the answer is ready.
Capacity, training and an earlier interview
He speculates about training capacity and Cerebras’s IPO, then shares Greg Brockman’s comments on chip development. The video ends with his view that the demand for compute will benefit users.
I expect specialized hardware to play a large part in inference, while general-purpose accelerators continue to play a role in training. TPUs also show that major models can be trained on hardware other than Nvidia GPUs. Actual speed and costs depend on the model and system, so a specialized chip is not automatically faster for every workload.
Additional inference capacity might reduce competition for other computing resources, potentially leaving more capacity for training. I predict that could help OpenAI build better models, but the company’s allocation decisions and the resulting model quality are not established by this deal. Extra capacity is not proof that all existing GPUs will move to training.
At the time of the video I thought the agreement might support Cerebras’s IPO ambitions and encourage other labs to examine its capacity. That was a prediction. As a later development, Cerebras reported in June 2026 that it had completed its IPO.
I had earlier asked OpenAI’s Greg Brockman why frontier labs did not use more services from companies such as Groq and Cerebras, and whether software changes were a barrier. In the interview excerpt, Brockman recalls OpenAI’s excitement about Cerebras in 2017, but says non-GPU architectures proved harder to build than expected.
Brockman says OpenAI spoke with chip companies about the shape of its workloads and found that some did not adopt its perspective on large models. In his view, successful hardware developers paid attention to deep-learning expertise and where workloads were heading. His recollection is an account of those conversations, not proof of any particular company’s internal decisions.
I conclude that more companies are recognizing the value of specialized inference, pointing to Nvidia’s Groq license and OpenAI’s Cerebras partnership. I believe the race for capacity could benefit users, although demand, pricing, access, reliability and implementation will all shape the actual outcome.
Más de este canal
 34:21EN
 Matthew Berman· 27 oct 2026Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 0:26ENMatthew Berman· 25 oct 2026Sam Altman on Human Values and Problem-Solving in an AI WorldSam Altman · OpenAIIn a short interview excerpt, Altman considers the enjoyment of solving hard problems and the human role in interpreting results.
 0:36ENMatthew Berman· 25 oct 2026Kimi K3.1 and a Rubik’s Cube Solver DemonstrationMatthew Berman · Forward FutureMatthew Berman shows a scrambled virtual cube being solved and gives the Kimi K3.1 test a favorable assessment.
 0:21ENMatthew Berman· 24 oct 2026An AI-Generated Kimi Benchmark Chart Used Invented ScoresMatthew Berman · Forward FutureMatthew Berman asks for a graph of Kimi K3.1 Pro benchmarks, then discovers that the displayed figures are illustrative placeholders.
 25:50ENMatthew Berman· 24 oct 2026Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.
 32:20ENMatthew Berman· 23 oct 2026Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.