En 30 segundos
Matthew Berman presents Anthropic’s Claude Opus 4 and Sonnet 4 launch, emphasizing extended thinking, parallel tools, file-based memory and Claude Code. He argues that the company is prioritizing coding-agent infrastructure, a strategic interpretation rather than a statement that the Claude chatbot ceased to exist. He reviews vendor-reported benchmarks, an example of a seven-hour task and launch-era API prices. The results depend on testing methods, tool access and selected tasks; a short initial personal trial is not a comprehensive assessment.
- 1Hybrid modelsBoth launch models offer near-instant and extended-thinking modes, with tool use during extended thinking.
- 2Long-running taskAnthropic reports a customer refactor that ran for seven hours; the video does not independently validate broader reliability.
- 3SWE-bench methodologyThe high-compute scores use multiple attempts, visible-test filtering and an internal selection model.
- 4File-based memoryAnthropic’s example relies on developer-granted file access to store notes for longer tasks.
- 5Claude CodeThe launch made Claude Code generally available and announced editor integrations, an SDK and a GitHub beta.
- 6Historical priceThe displayed Opus 4 API launch price was $15 per million input tokens and $75 per million output tokens.
Conclusiones
- Claude Opus 4 and Sonnet 4 launched with near-instant and extended-thinking modes and could use tools during extended thinking.
- Anthropic reported a customer refactor lasting seven hours, a selected example rather than a guarantee of reliable performance on all long tasks.
- SWE-bench Verified scores with parallel test-time compute used multiple attempts, filtering and a scoring model.
- Anthropic’s memory example depends on developer-provided local file access and does not imply automatic indefinite memory.
- Claude Code became generally available with editor integrations, an SDK and a GitHub beta.
- Berman’s claim that Anthropic had abandoned chatbot competition is his interpretation of its strategy.
Lee el texto editado por capítulos
Claude 4 and tool use
Berman introduces Opus 4 and Sonnet 4, hybrid reasoning modes and the launch’s agent features. He describes his limited initial use.
In May 2025, Matthew Berman reviews Anthropic’s announcement of Claude Opus 4 and Claude Sonnet 4. He emphasizes coding agents and longer tasks, citing Anthropic’s claim that Opus 4 is a leading coding model. Such claims and the examples shown are launch-era vendor reports, not a universal or current ranking.
Both models are hybrid systems with near-instant responses and an extended-thinking mode. Anthropic says they can use tools during extended thinking and call multiple tools in parallel. Berman says he reached his usage limit after only a few prompts and planned more extensive testing.
Berman shows the Claude interface and its search and tool options. He also highlights the Model Context Protocol and Claude Code, which became generally available alongside the models. He sees these integrations as supporting applications that work over longer periods.
Long tasks and developer infrastructure
Anthropic describes a customer’s long-running refactor and new API tools. Berman interprets the launch as a strategic emphasis on coding agents.
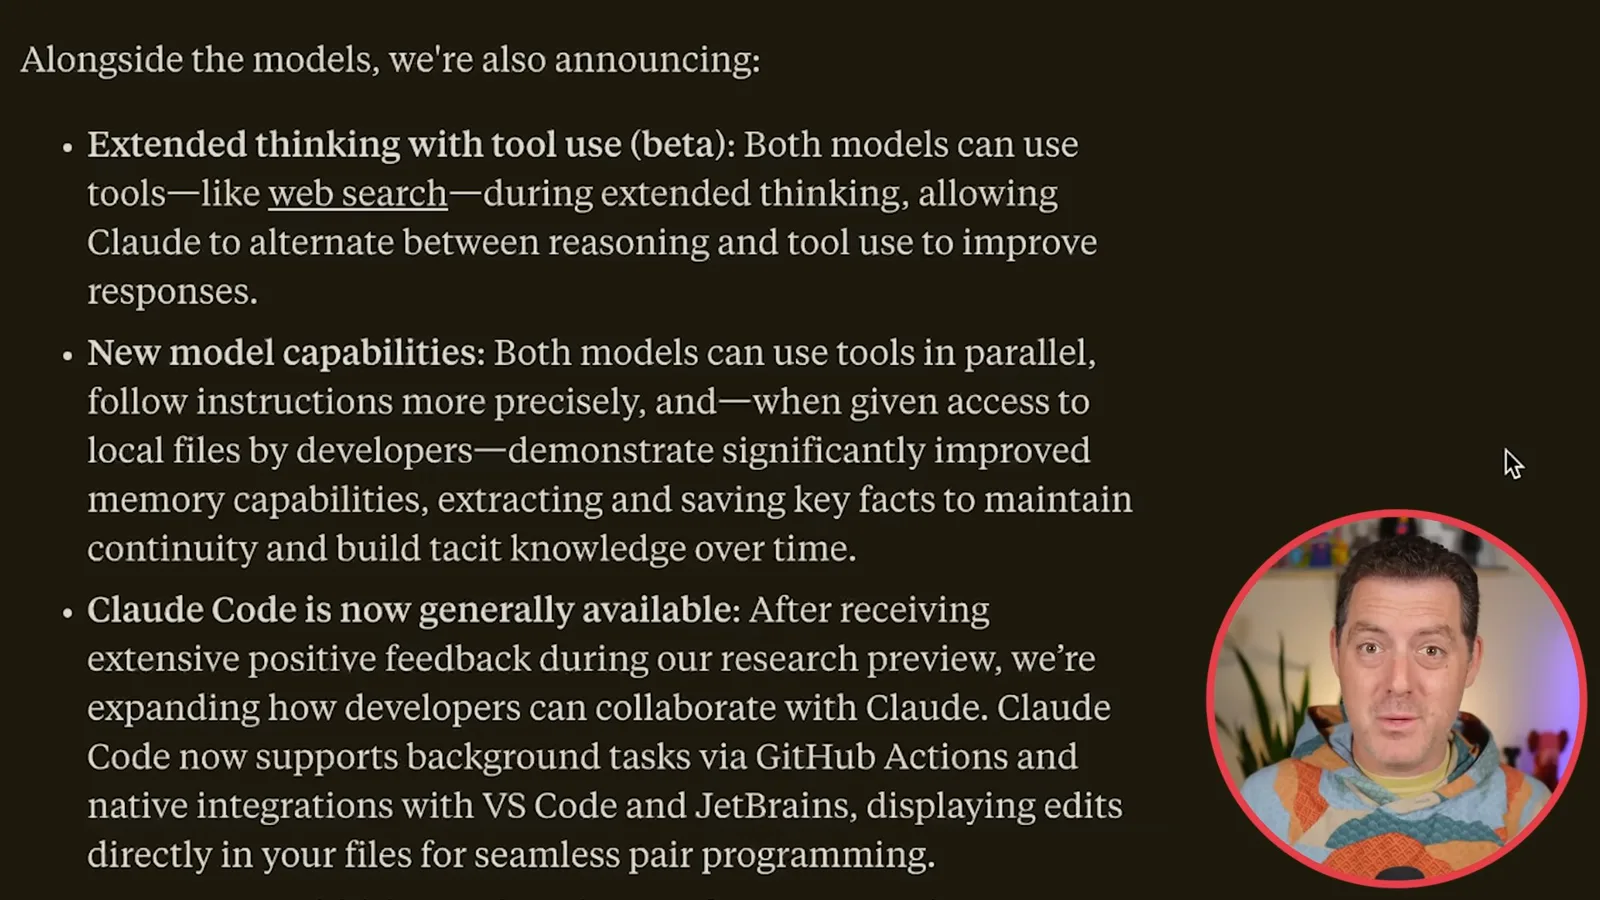
Anthropic cites a customer example of an open-source refactor sustained for seven hours. Its announcement also lists four API capabilities: code execution, an MCP connector, a Files API and prompt caching for up to one hour. This is a selected customer report rather than a guarantee that arbitrary tasks will run successfully for that long.
Berman explains the role of code execution, connecting tools, working with files and caching repeated prompt material. He argues that the collection points toward a strategy focused on infrastructure and coding agents, and characterizes Anthropic as having given up on the chatbot race. That is his interpretation; the launch also continued to offer the models in the Claude product.
He points to GitHub Copilot and other coding platforms integrating Claude models, citing partner claims of improved agentic performance. Berman treats tool use, memory and long-running tasks as a common theme. The video’s subsequent Box segment is a sponsorship.
Benchmarks, shortcuts and memory
Berman examines reported coding and reasoning results and a comparison with Sonnet 3.7. Anthropic’s shortcut and file-based memory claims apply to specified conditions.
Turning to benchmarks, Berman cautions that scores show only part of the picture. Anthropic’s SWE-bench Verified chart reports 72.5% for Opus 4 and 72.7% for Sonnet 4 under its standard setup, and 79.4% and 80.2% respectively with additional parallel test-time compute.
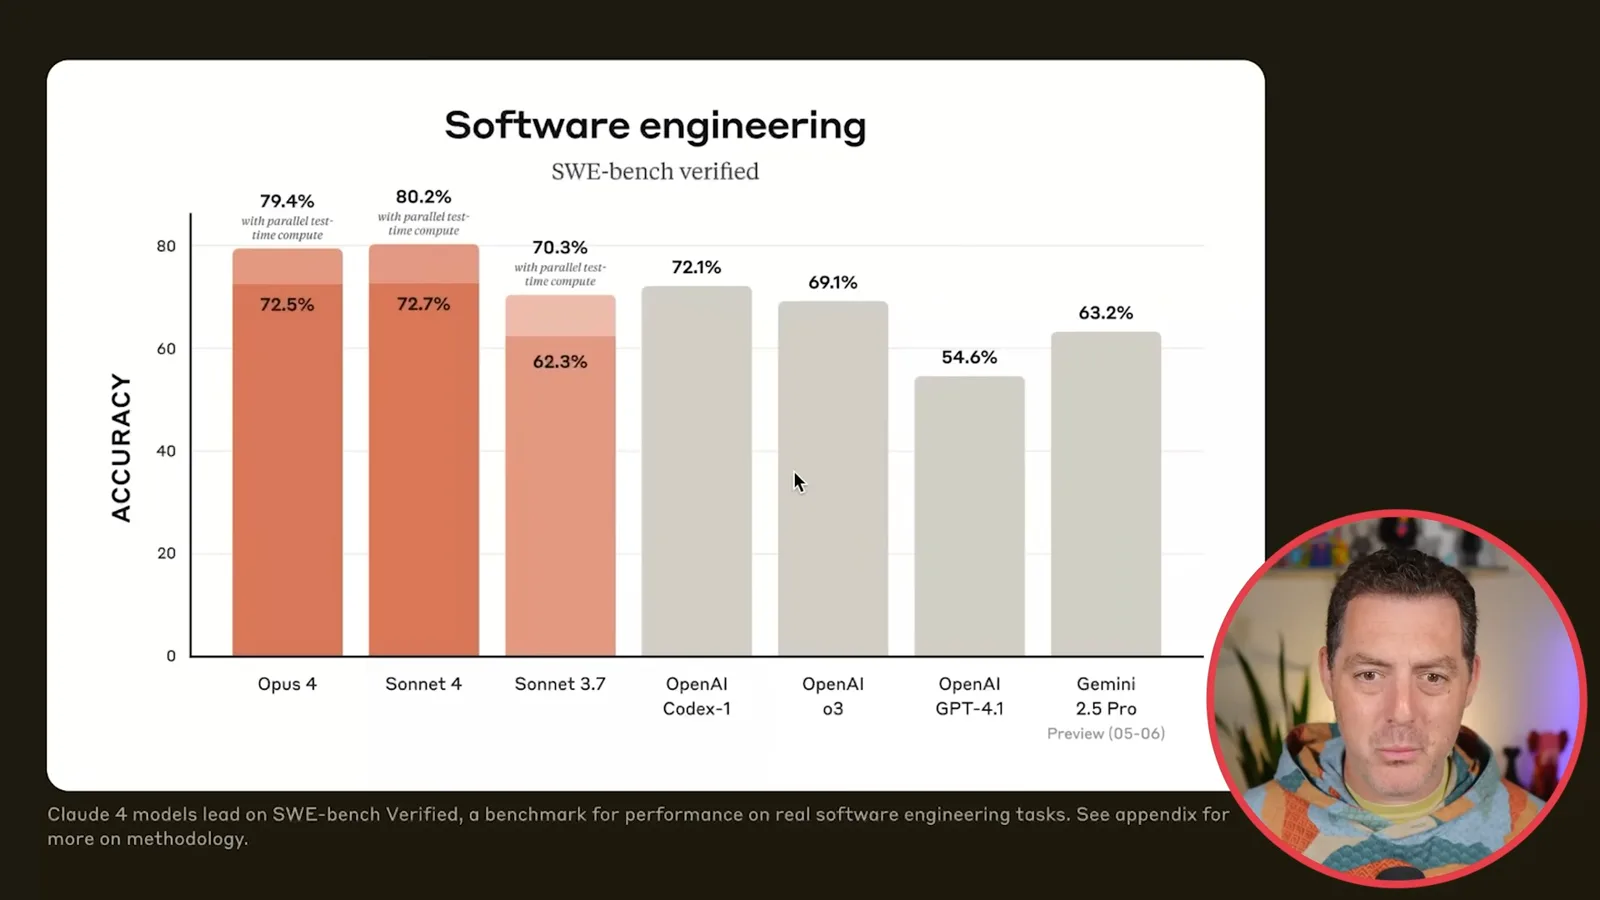
Anthropic’s high-compute method samples multiple attempts, filters patches that break visible regression tests, and uses an internal scoring model to select a remaining candidate. Berman notices that Sonnet scores slightly above Opus in this chart and says his own initial impression that Opus was faster is only anecdotal.
In the launch table, Opus 4 scores 43.2% on Terminal-bench and Sonnet 4 35.5%. Berman also reviews science reasoning, tool use, multilingual questions, visual reasoning and AIME mathematics. Comparisons need the individual evaluation conditions and agent scaffolds; the scores are not interchangeable measures of general capability.
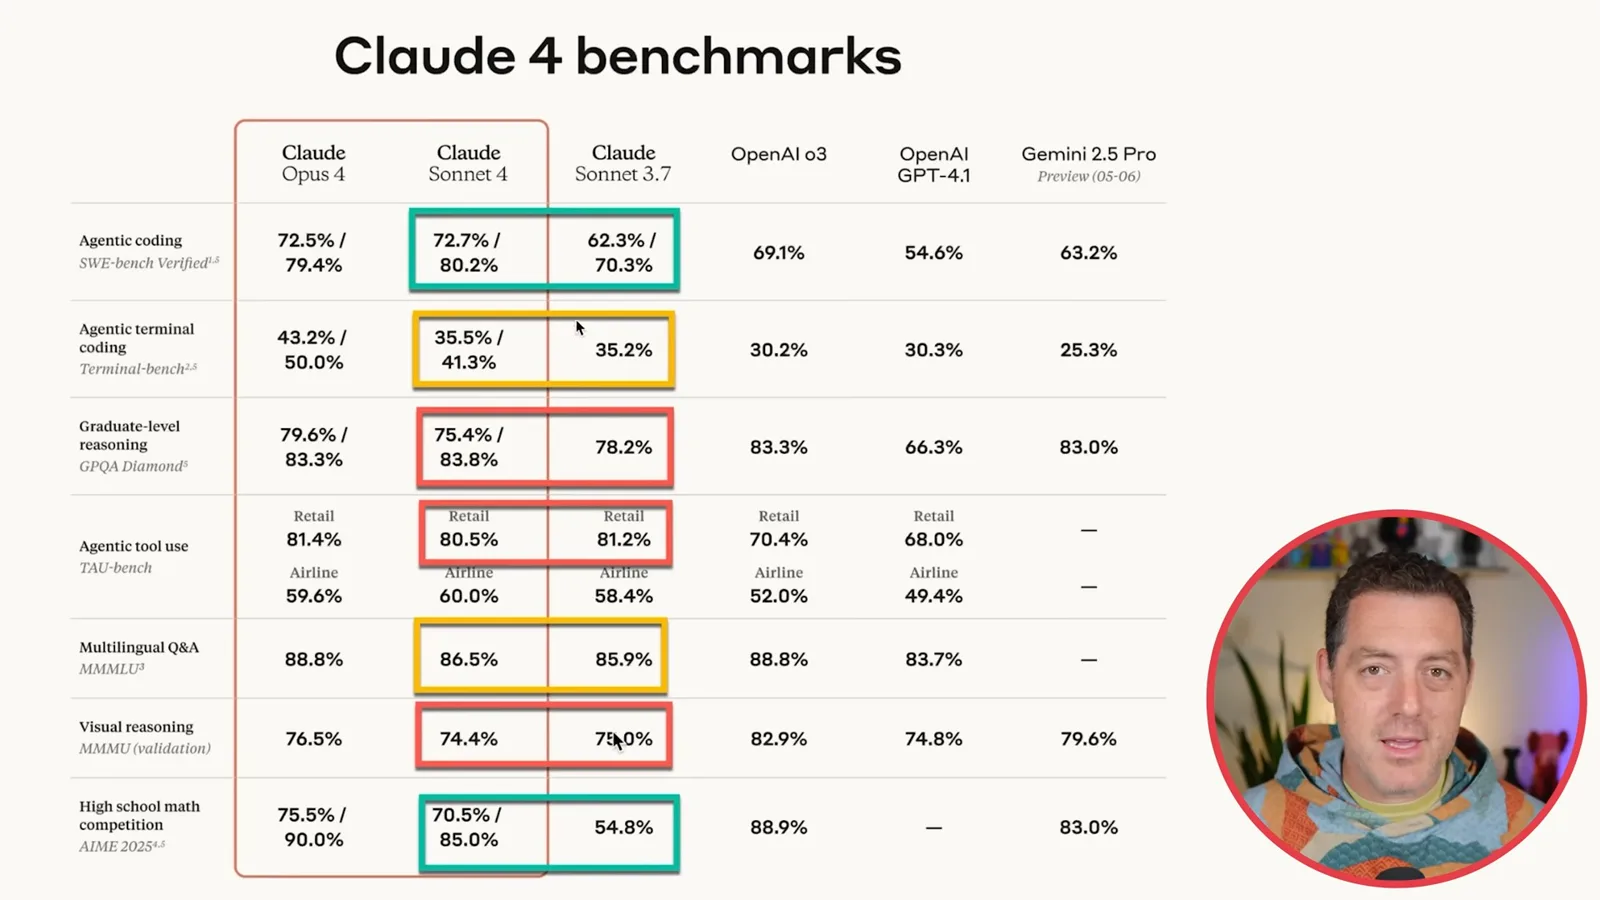
Berman shows an annotated comparison with Sonnet 3.7 and points out that some Sonnet 4 results are similar or lower, while others improve. He questions a blanket story of improvement. The direction and significance of any change depend on the benchmark, test configuration and uncertainty, rather than the color coding alone.
Anthropic reports that the new models were 65% less likely than Sonnet 3.7 to exploit shortcuts or loopholes on a selected set of agentic tasks susceptible to that behavior. Berman also reports the company’s claim of improved memory. These are targeted vendor measurements, not evidence that shortcuts or memory failures are eliminated.
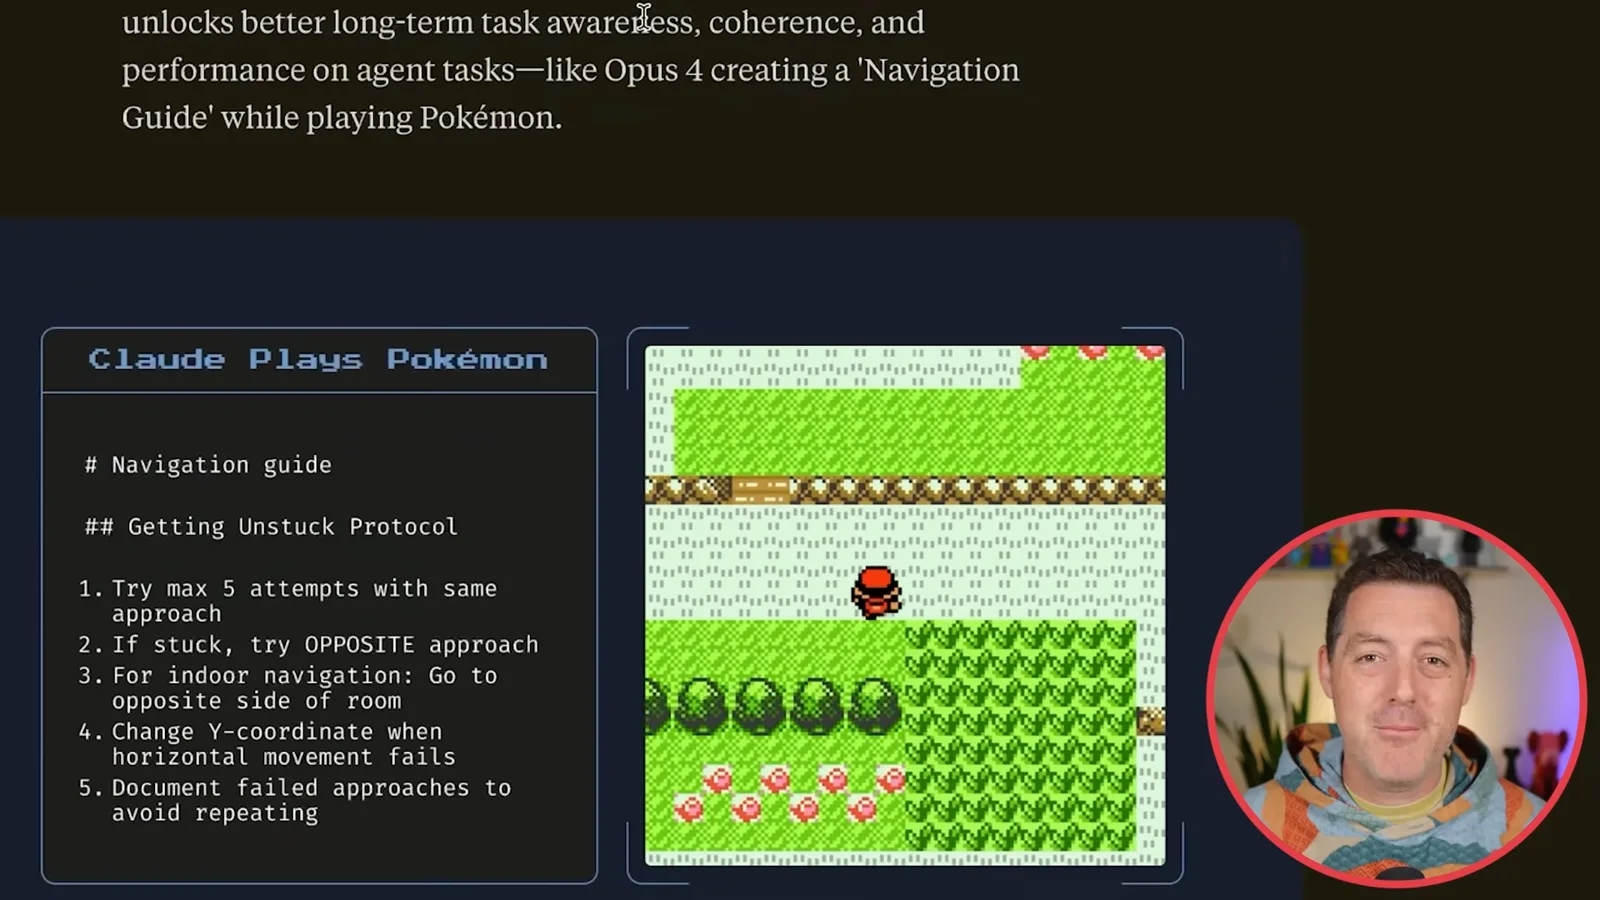
The memory example requires developers to provide access to local files: Anthropic says Opus 4 can write and maintain notes to preserve relevant information, illustrated by a Pokémon navigation guide. Berman imagines increasingly personalized agents, but the example does not establish that every conversation automatically learns or remembers indefinitely.
Claude Code and launch pricing
The announcement covers editor integrations, an SDK and a GitHub beta. Berman closes with his strategic interpretation and the historical Opus price.
Anthropic says lengthy thinking processes can be condensed into summaries by a smaller model and that users needing raw chains of thought can contact sales about Developer Mode. Berman comments on the availability of the detailed reasoning; the company says summarization was needed only for a minority of thinking processes in its launch description.
Claude Code became generally available, with beta VS Code and JetBrains integrations showing proposed edits in the editor. Anthropic also announced an SDK for building agents and a GitHub beta where a tagged agent can address review feedback, modify code or help with CI failures; the resulting work remains subject to review.
Berman cites a report quoting Anthropic chief scientist Jared Kaplan on a shift toward complex tasks, and reiterates his view that the company is prioritizing agentic infrastructure over the consumer chatbot race. That is his reading of the strategy, not proof that Anthropic ended its Claude chatbot offering.
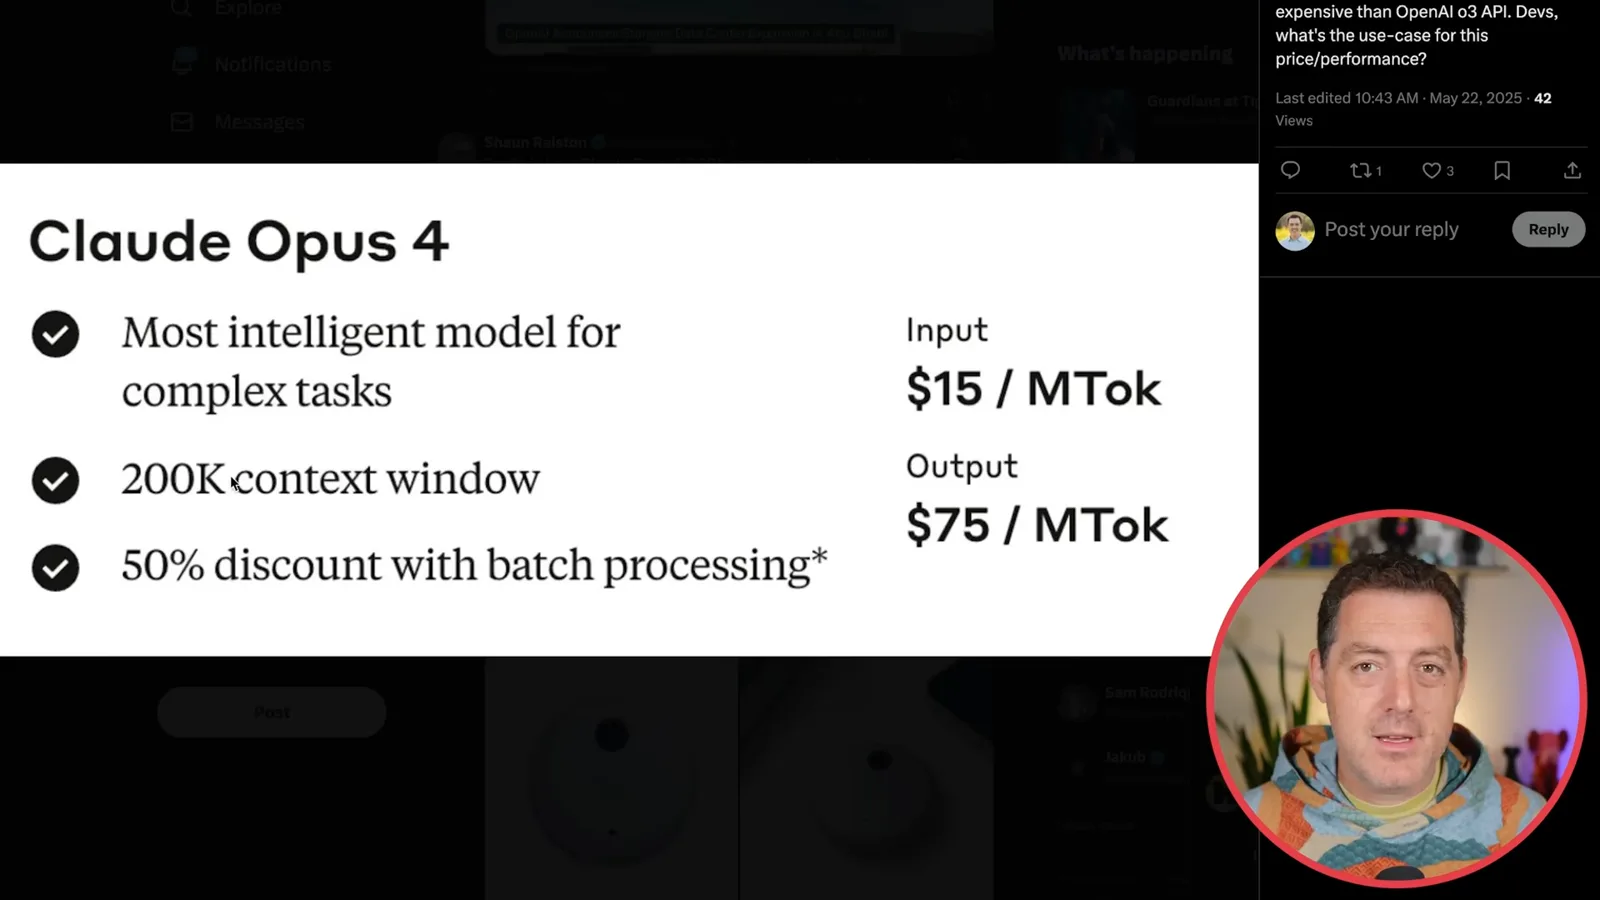
For the launch period, Berman lists Opus 4 with a 200,000-token context window and API prices of $15 per million input tokens and $75 per million output tokens, plus a stated batch discount. He closes by promising further tests. These are May 2025 details, not a current pricing guide.
Más de este canal
 34:21EN
 Matthew Berman· 27 oct 2026Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 0:36ENMatthew Berman· 25 oct 2026Kimi K3.1 and a Rubik’s Cube Solver DemonstrationMatthew Berman · Forward FutureMatthew Berman shows a scrambled virtual cube being solved and gives the Kimi K3.1 test a favorable assessment.
 25:50ENMatthew Berman· 24 oct 2026Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.
 32:20ENMatthew Berman· 23 oct 2026Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.
 1:03:37ENMatthew Berman· 23 oct 2026Matthew Berman’s Team Tests Kimi K3.1 on Animation, Games, and ChartsMatthew Berman, Alex, Brian · Forward FutureA live team AMA turns into an informal test of Kimi K3.1, from personal-agent workflows to motion graphics, a browser game, and a benchmark chart.
 0:53ENMatthew Berman· 22 oct 2026Sam Altman on AI and the Discovery of New KnowledgeSam Altman · OpenAIAltman expects progress in mathematical discovery to extend to biology, materials and energy.