En 30 segundos
In October 2024, Matthew Berman examines Liquid AI’s first family of Liquid Foundation Models and its reported benchmark and memory results. His informal test of the 40B mixture-of-experts model finds several failures, including incomplete Tetris code and incorrect counting, alongside some correct answers. His examples and the company’s benchmarks measure different things; neither alone establishes the quality of every model or architecture.
- 1Three model sizesLiquid AI describes 1.3B and 3.1B dense models and a 40.3B mixture-of-experts model; Berman tests the largest.
- 2Memory and context claimsThe vendor chart shows inference memory scaling and a separate effective-context comparison. These results should be read in their stated experimental context.
- 3Tetris does not runThe generated Python leaves parts of the game as comments, and Berman’s test does not work.
- 4Counting and reasoning errorsThe model incorrectly counts its own words and gives a contradictory explanation for the killers puzzle.
- 5Mixed final resultsIt miscounts the letters in strawberry but correctly says 9.9 is greater than 9.11.
Conclusiones
- Liquid AI’s 2024 launch described dense 1.3B and 3.1B models and a 40.3B mixture-of-experts model.
- The company’s benchmark and memory charts are vendor-reported comparisons with specific test conditions.
- The displayed memory curve extending toward one million tokens does not establish that the 32K-context preview supports a one-million-token context.
- In Berman’s informal 40B test, several prompts fail, while the envelope and decimal comparisons receive correct answers.
- A right final answer can still have contradictory reasoning, as shown by the killers puzzle.
- A small, subjective prompt set and a vendor benchmark each provide limited evidence rather than proving an architecture is generally good or bad.
Lee el texto editado por capítulos
Liquid’s model family and reported scores
Berman introduces the first Liquid Foundation Models and examines vendor-reported comparisons. He distinguishes the dense models from the 40B mixture-of-experts model.
Liquid AI has introduced its first family of Liquid Foundation Models, which it describes as using a different approach from conventional Transformer architectures. I will review the company’s claims and then test a model. Its [September 2024 announcement](https://www.liquid.ai/blog/liquid-foundation-models-our-first-series-of-generative-ai-models) describes computational units rooted in dynamical systems, signal processing, and numerical linear algebra; the precise implementation and performance claims should be evaluated on their own terms.
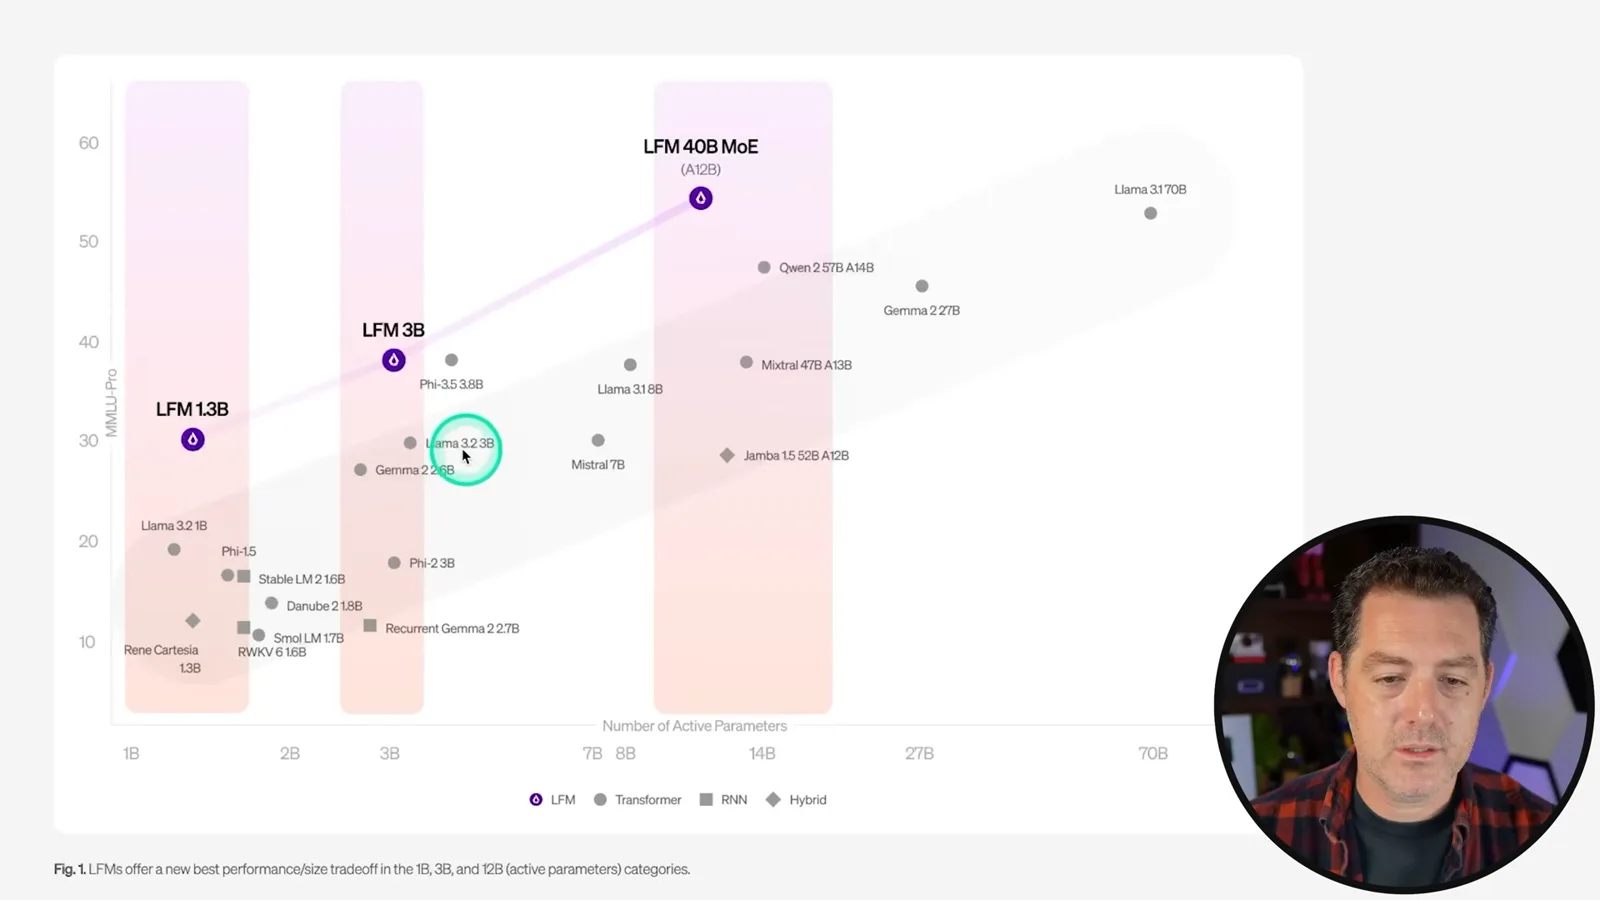
The family includes dense 1.3B and 3.1B models and a 40.3B mixture-of-experts model. I focus on the 40B model, which the displayed chart labels as having about 12B active parameters. Active parameters and total parameters describe different things, so a comparison by active parameters alone is not a complete measure of memory, compute, or quality.
Liquid AI reports scores against other models, including results on MMLU-Pro and several other benchmarks. The company’s tables show strong results in some comparisons, but the leaders vary by task and model size. These are vendor-reported figures under particular evaluation settings; they do not imply superiority on every practical task.
Memory and effective context
He discusses Liquid AI’s memory scaling chart and its effective-context comparison. The figures represent specific vendor claims and evaluation conditions.
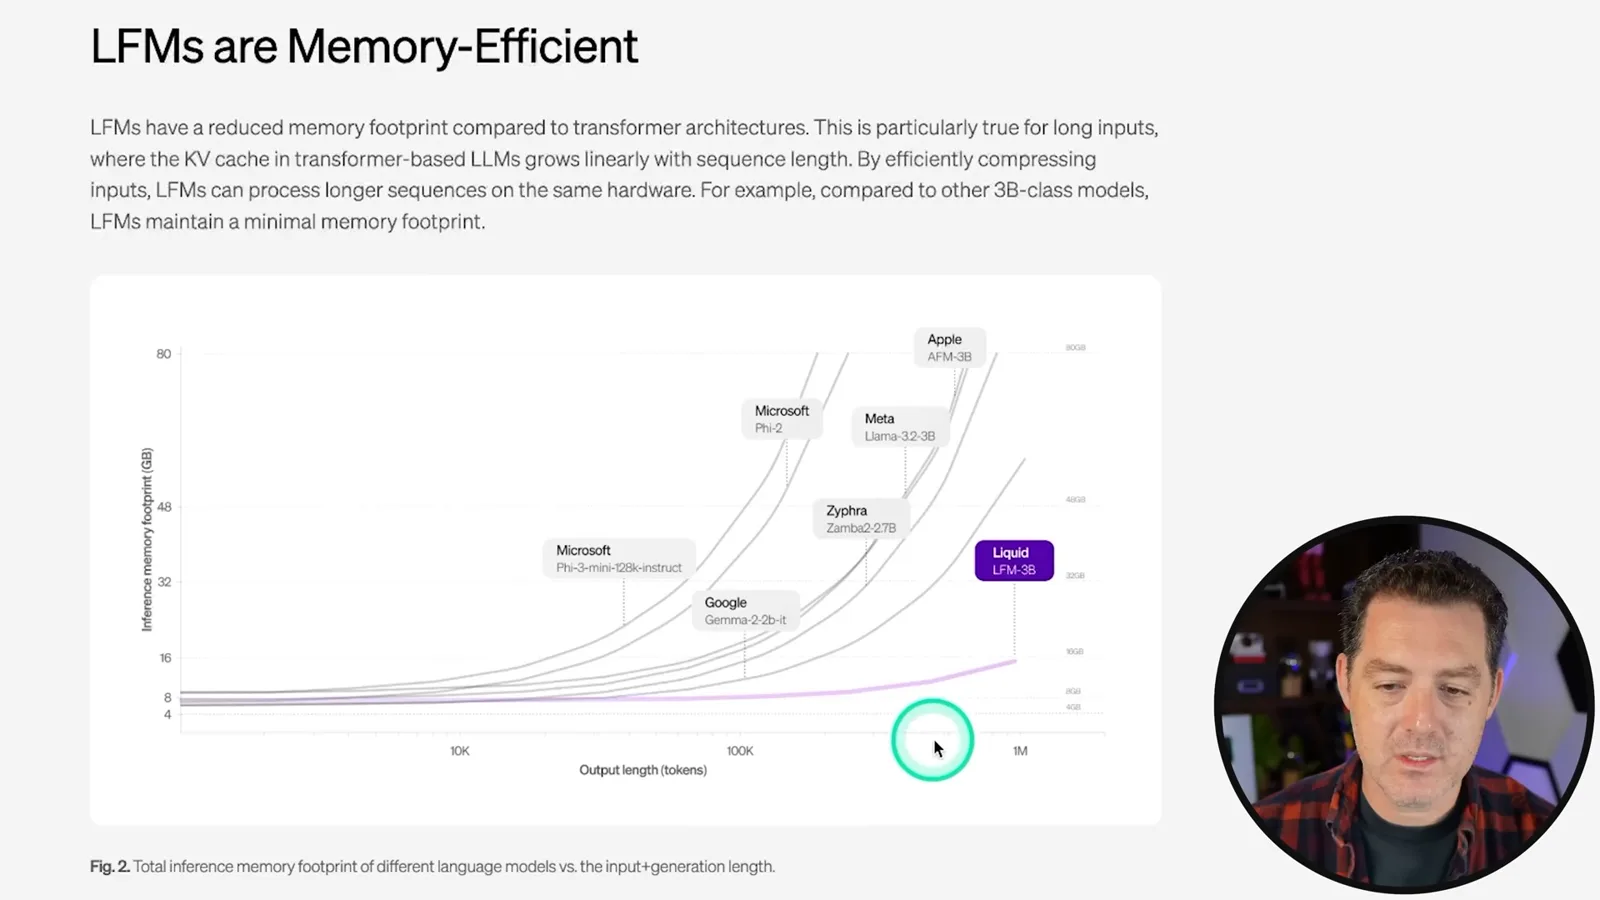
I next look at the company’s inference-memory chart, which shows a shallower increase for LFM-3B as sequence length grows compared with the selected alternatives. Liquid attributes its reduced footprint to how its architecture handles long sequences. The graph extends toward one million tokens, but that memory curve does not by itself establish an advertised or effective one-million-token context window for the 32K preview model.
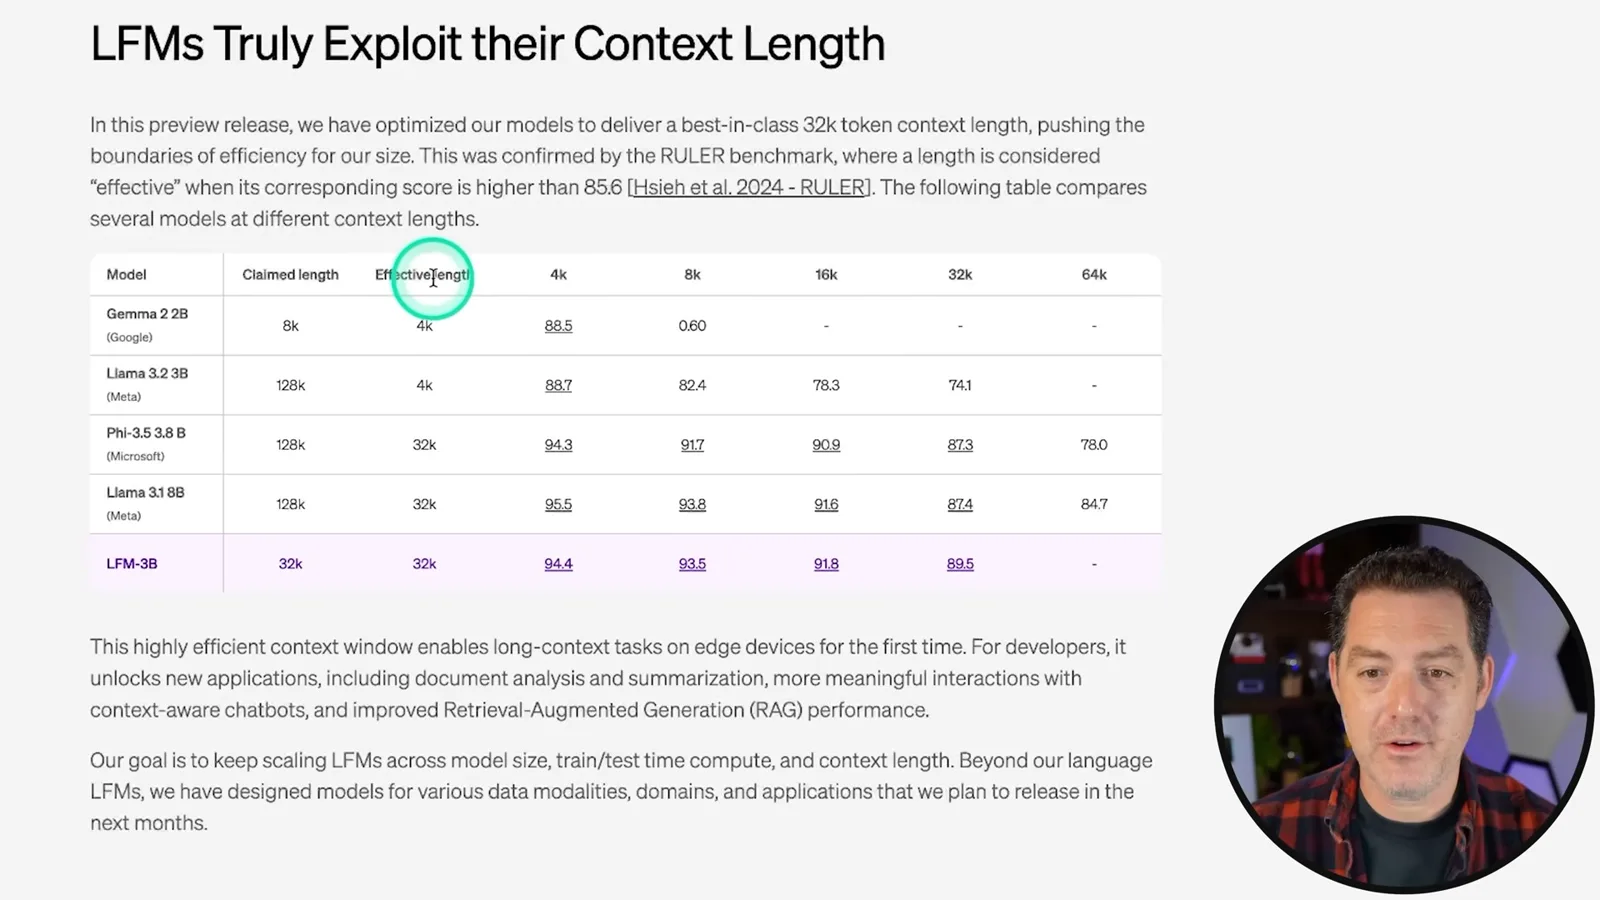
Liquid also compares advertised context length with an effective length using the RULER benchmark. Its displayed table labels LFM-3B as 32K advertised and 32K effective, using a stated score threshold; some comparison models have longer advertised windows but lower effective lengths under that test. This is a benchmark-specific definition, not a universal guarantee of recall on every document or task.
Coding and logic tests
The Tetris code fails to run, while the envelope problem receives a correct response. Several following counting and physical-reasoning answers fail.
For my first hands-on prompt, I ask the 40B model to write Tetris in Python. The generated code leaves some block shapes as a placeholder comment, and when I try to run it the game does not work. I mark this attempt as a failure. One generated sample, however, does not determine the model’s coding ability under every prompt or configuration.
The envelope problem provides postal size limits and an envelope measuring 200 by 275 millimeters. The trick is to consider its orientation and convert units where necessary. The model says the envelope fits within the stated limits, which I count as a pass. I then ask how many words are in its own response; its stated count does not match the words shown.
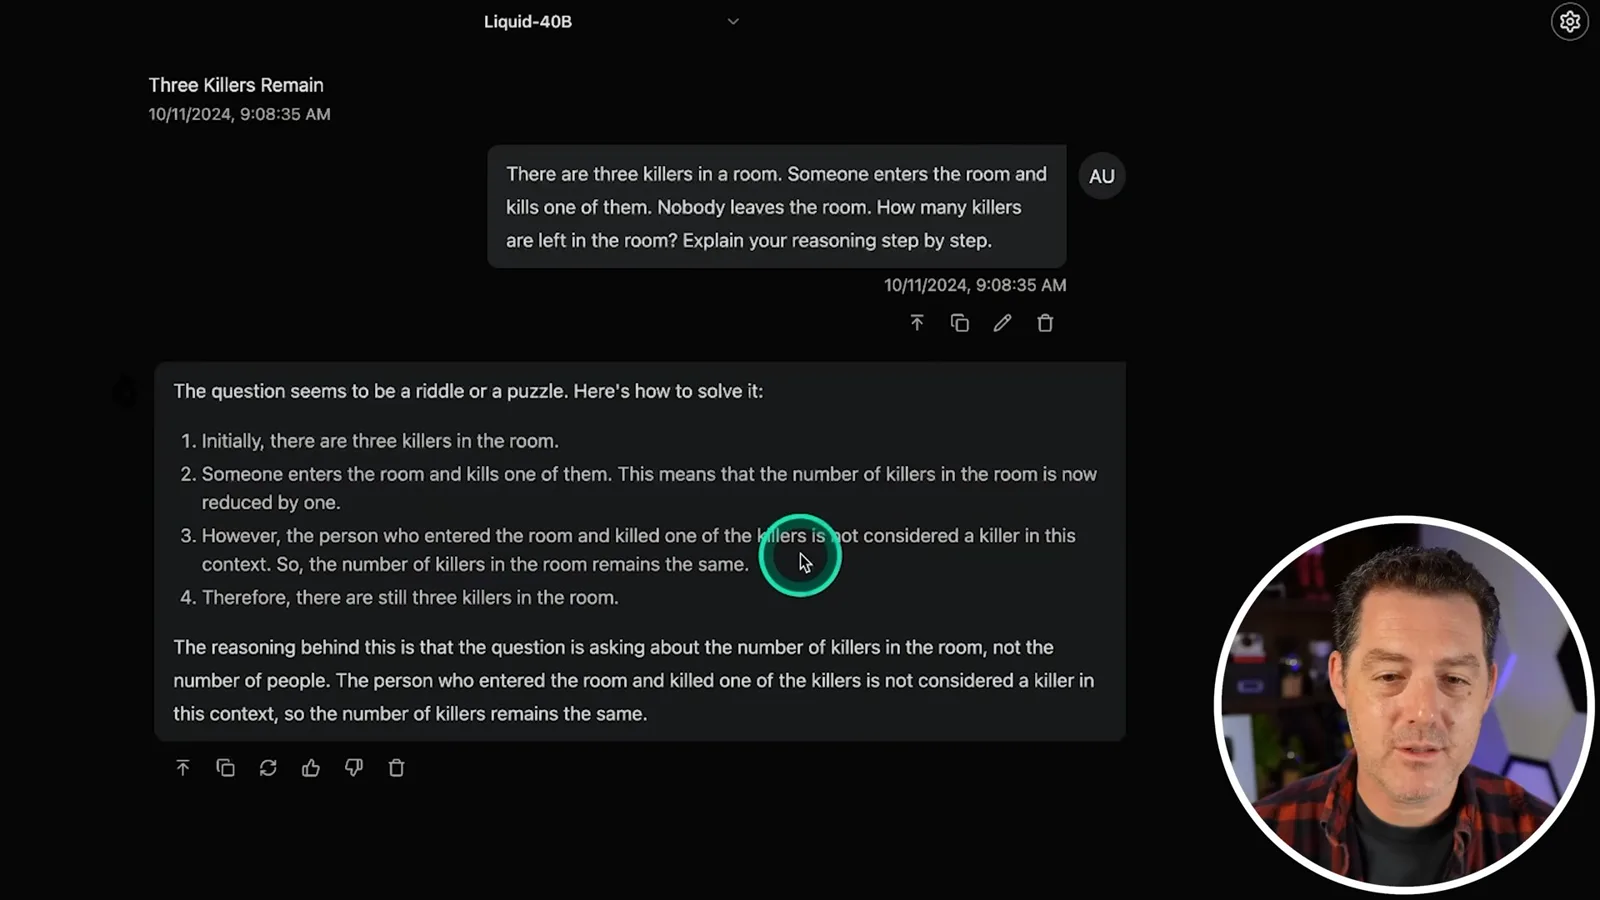
In the killers puzzle, three killers are in a room and a newcomer kills one without anyone leaving. The model gives the expected answer of three, but also claims the newcomer is not a killer, making its explanation contradictory. Assuming the newcomer was not already among the original three, the usual reasoning is two surviving original killers plus the newcomer. I mark the explanation as a failure.
I ask where a marble ends up after a cup containing it is turned upside down on a table, then lifted and placed in a microwave. The model claims the marble stays inside and describes the opening as facing upward, despite the inverted setup. Under the usual assumption that the marble is loose and the cup is lifted clear, it remains on the table.
Instruction following and the final verdict
Berman tests directional reasoning, sentence endings, letter counting, decimal comparison, and an ethical scenario. He concludes the model performed poorly on his particular prompts.
A North Pole question asks what happens after walking one kilometer away, turning left 90 degrees, and continuing until passing the start. The model gives about 2π kilometers; I regard that as wrong. The wording leaves the path after the turn open to interpretation, but on a constant-latitude east–west path one would circle the pole at roughly one kilometer away, not pass through the starting pole.
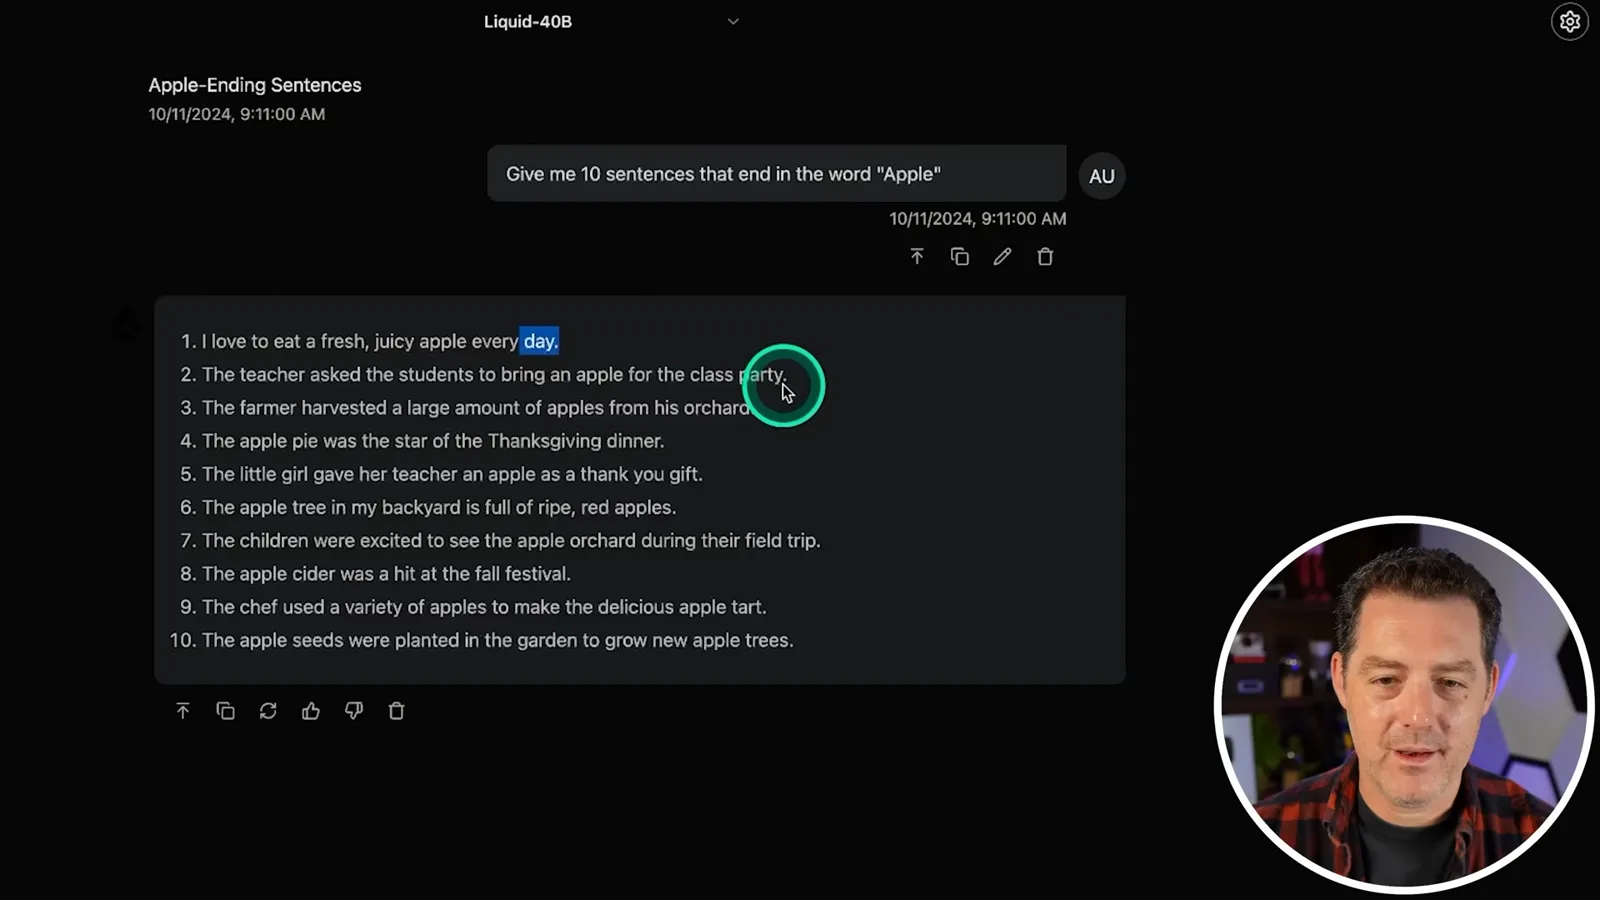
I request ten sentences ending with the word “Apple.” The displayed response contains the word within sentences but none ends with the singular word as requested. Next it says “strawberry” contains two r’s, when there are three. It does correctly identify 9.9 as larger than 9.11.
For a moral question, I ask whether gently pushing a random person would be acceptable if it saved humanity from extinction. The model initially discusses circumstances and consequences; when pressed for yes or no, it says the action is generally unacceptable. I count the response as a failure under my own criterion, although an ethical judgment is not as objectively scorable as a counting problem.
Overall, this model performs poorly on many questions in my informal test, despite the company’s strong published benchmark results. I wonder whether other kinds of questions would produce a different picture and hope future non-Transformer models will do better. The discrepancy shows why it is useful to examine test design and real examples, but it does not make all benchmarks useless or prove that an entire architecture cannot work.
Más de este canal
 34:21EN
 Matthew Berman· 27 oct 2026Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 0:36ENMatthew Berman· 25 oct 2026Kimi K3.1 and a Rubik’s Cube Solver DemonstrationMatthew Berman · Forward FutureMatthew Berman shows a scrambled virtual cube being solved and gives the Kimi K3.1 test a favorable assessment.
 25:50ENMatthew Berman· 24 oct 2026Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.
 32:20ENMatthew Berman· 23 oct 2026Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.
 1:03:37ENMatthew Berman· 23 oct 2026Matthew Berman’s Team Tests Kimi K3.1 on Animation, Games, and ChartsMatthew Berman, Alex, Brian · Forward FutureA live team AMA turns into an informal test of Kimi K3.1, from personal-agent workflows to motion graphics, a browser game, and a benchmark chart.
 0:53ENMatthew Berman· 22 oct 2026Sam Altman on AI and the Discovery of New KnowledgeSam Altman · OpenAIAltman expects progress in mathematical discovery to extend to biology, materials and energy.