En 30 segundos
Matthew Berman introduces LLM Colosseum, a project that connects language models to Street Fighter III and uses their chosen actions to control characters. The displayed match ends with a Mistral win; Berman says he has seen that result repeatedly in his own viewing. This is an illustrative game, not evidence that one model is generally superior or that its weights learned during the match. The video does not provide enough information to identify every model version or establish a statistical win rate.
- 1A fighting-game evaluationBerman presents Street Fighter III as an interactive way to compare language-model agents making decisions during a match.
- 2Observation to actionThe system forms a prompt from game information and a goal, asks an LLM for a move and applies the returned action in the game.
- 3A single displayed resultThe characters in the shown matchup are both Ken; the screen identifies OpenAI’s side and Mistral’s side. The victory screen reports Mistral won.
Conclusiones
- LLM Colosseum uses game observations and prompts to request actions from language models.
- The video presents one match between agents labeled OpenAI and Mistral, both using Ken.
- The displayed result is a Mistral win, which does not by itself establish general model superiority.
- The demonstration does not show that model weights were updated or that an agent learned during play.
Lee el texto editado por capítulos
A new game-based test
Berman introduces a Street Fighter III match between two language-model agents. He presents it as an alternative way to compare their decisions.
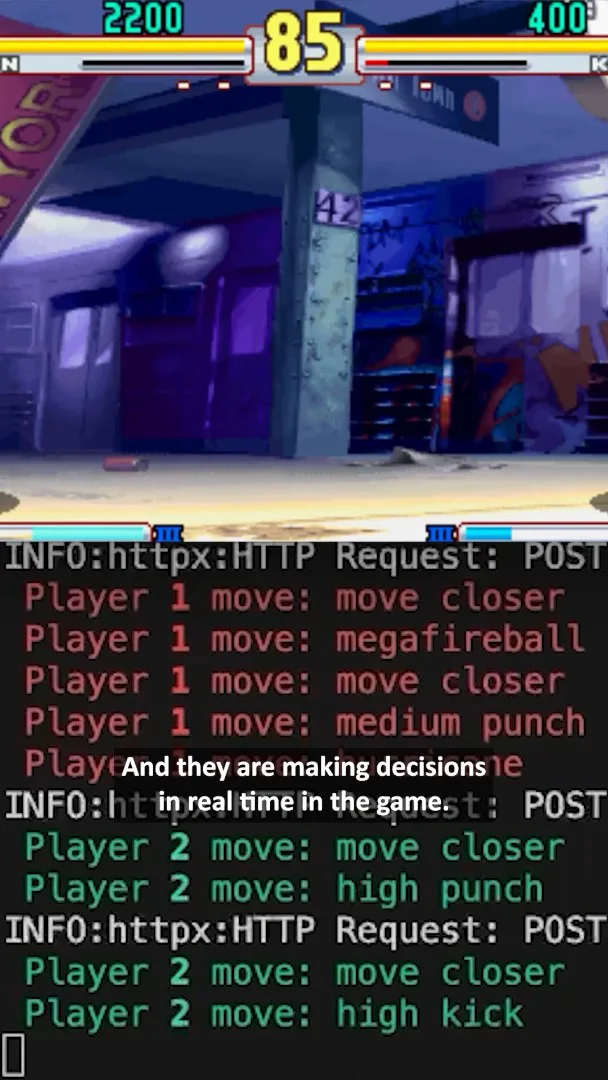
I am watching two language-model agents play Street Fighter III, a game I love. The project, [LLM Colosseum](https://github.com/OpenGenerativeAI/llm-colosseum), presents this as another way to compare models through decisions made during a game. A short match is an illustration of that setup, not a broad assessment of model quality.
How the loop works
Game observations and a goal are used to create a prompt. The model returns a move that the game executes.
The loop takes observations from the game and a goal, constructs a prompt and asks the language model for the next move. The selected action is then applied in the game. That describes an agent using a model to choose actions; the video does not show the model’s weights being trained or updated during play.
The match result
Both sides use Ken in the demonstrated match, which ends with a Mistral victory. Berman hopes to see more characters and games.
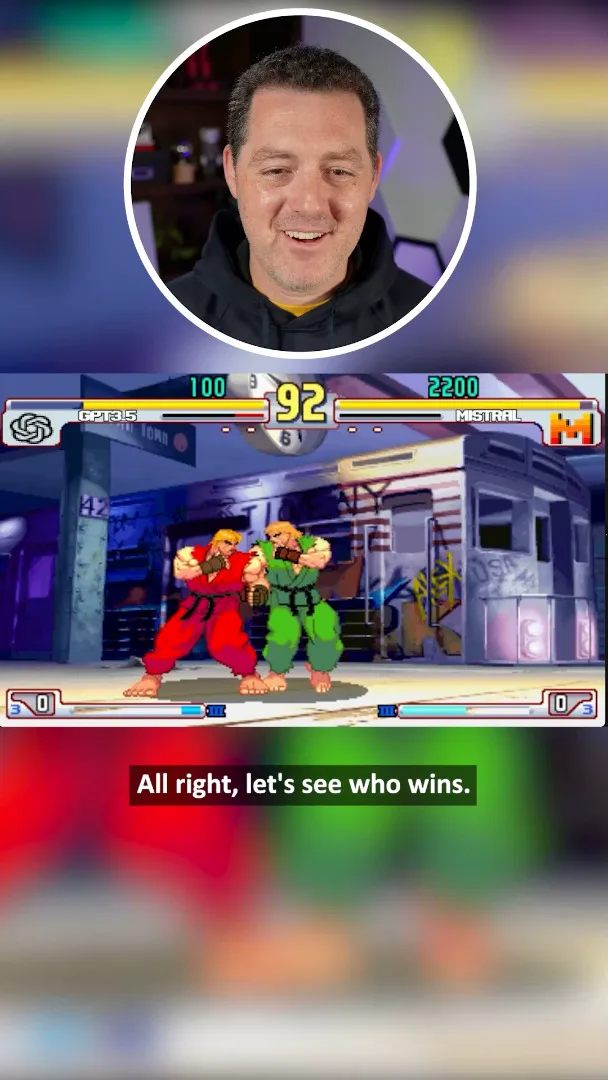
In the displayed matchup, I think the green Ken represents Mistral and the red Ken represents OpenAI; the game screen labels the sides. Both characters are Ken in this demo, and I hope the project adds more characters and games. The screen does not establish the exact version of the Mistral model.
After a brief pause at the end, the victory screen says Mistral won. I have seen this result repeatedly in my own viewing, but the short does not give a match count, controlled conditions or a statistical win rate. It is a fun demonstration, not proof that Mistral wins in general.
Más de este canal
 34:21EN
 Matthew Berman· 27 oct 2026Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 0:36ENMatthew Berman· 25 oct 2026Kimi K3.1 and a Rubik’s Cube Solver DemonstrationMatthew Berman · Forward FutureMatthew Berman shows a scrambled virtual cube being solved and gives the Kimi K3.1 test a favorable assessment.
 25:50ENMatthew Berman· 24 oct 2026Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.
 32:20ENMatthew Berman· 23 oct 2026Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.
 1:03:37ENMatthew Berman· 23 oct 2026Matthew Berman’s Team Tests Kimi K3.1 on Animation, Games, and ChartsMatthew Berman, Alex, Brian · Forward FutureA live team AMA turns into an informal test of Kimi K3.1, from personal-agent workflows to motion graphics, a browser game, and a benchmark chart.
 0:53ENMatthew Berman· 22 oct 2026Sam Altman on AI and the Discovery of New KnowledgeSam Altman · OpenAIAltman expects progress in mathematical discovery to extend to biology, materials and energy.