En 30 segundos
In August 2024, Matthew Berman tests Gemini 1.5 Pro and the experimental 0801 preview in Google AI Studio. He encounters blocked outputs and code errors, sees mixed results on reasoning and instruction-following, and finds the image and long-video demonstrations promising. His unfavorable overall verdict is based on a small, informal set of prompts and cannot establish a general model ranking. The video sample and a model answer disagree about the museum name, and the claimed dinosaur identification is not independently verified.
- 1Snake and output errorsBoth versions produced repeated blocked-output errors; a generated curses program also failed when Berman attempted to run it.
- 2Different drying answersThe experimental model assumed batches and answered 16 hours; the standard model answered four hours under unchanged conditions.
- 3Ambiguous logic testsThe killers and marble questions depend on details such as who counts as a killer and how a glass is inverted.
- 4Instruction followingThe model failed to end all ten requested sentences with “apple” in the displayed attempts, but correctly compared the decimals 9.9 and 9.11.
- 5Visual tasksBerman accepts the model’s explanation of a workplace meme and its conversion of a table screenshot into CSV.
- 6Long videoThe test uploads a 30-minute museum video, but the model’s museum identification conflicts with the visible file label and the dinosaur answer is not verified.
Conclusiones
- Repeated output errors prevented a clean Snake implementation in this demonstration.
- Standard and experimental variants gave different responses to some prompts, including the shirt-drying puzzle.
- Several tests had ambiguous assumptions or subjective grading, limiting broad comparisons.
- The model correctly compared 9.9 with 9.11 and produced useful responses on the shown image tasks.
- The long-video example is promising but its answer contains an unverified museum identification that conflicts with the file label.
- The review reflects historical versions and a small selection of prompts, not a controlled ranking of frontier models.
Lee el texto editado por capítulos
Model setup and coding
Berman introduces Gemini 1.5 Pro and its long-context claims. His first programming test succeeds, while the Snake attempt encounters blocked outputs and execution errors.
I’m testing Gemini 1.5 Pro in Google AI Studio in August 2024, including text, images and a long video. Google described an updated context window of up to two million tokens and published benchmark results. Those reported figures are vendor claims for specific evaluations, not a guarantee for every task or input.
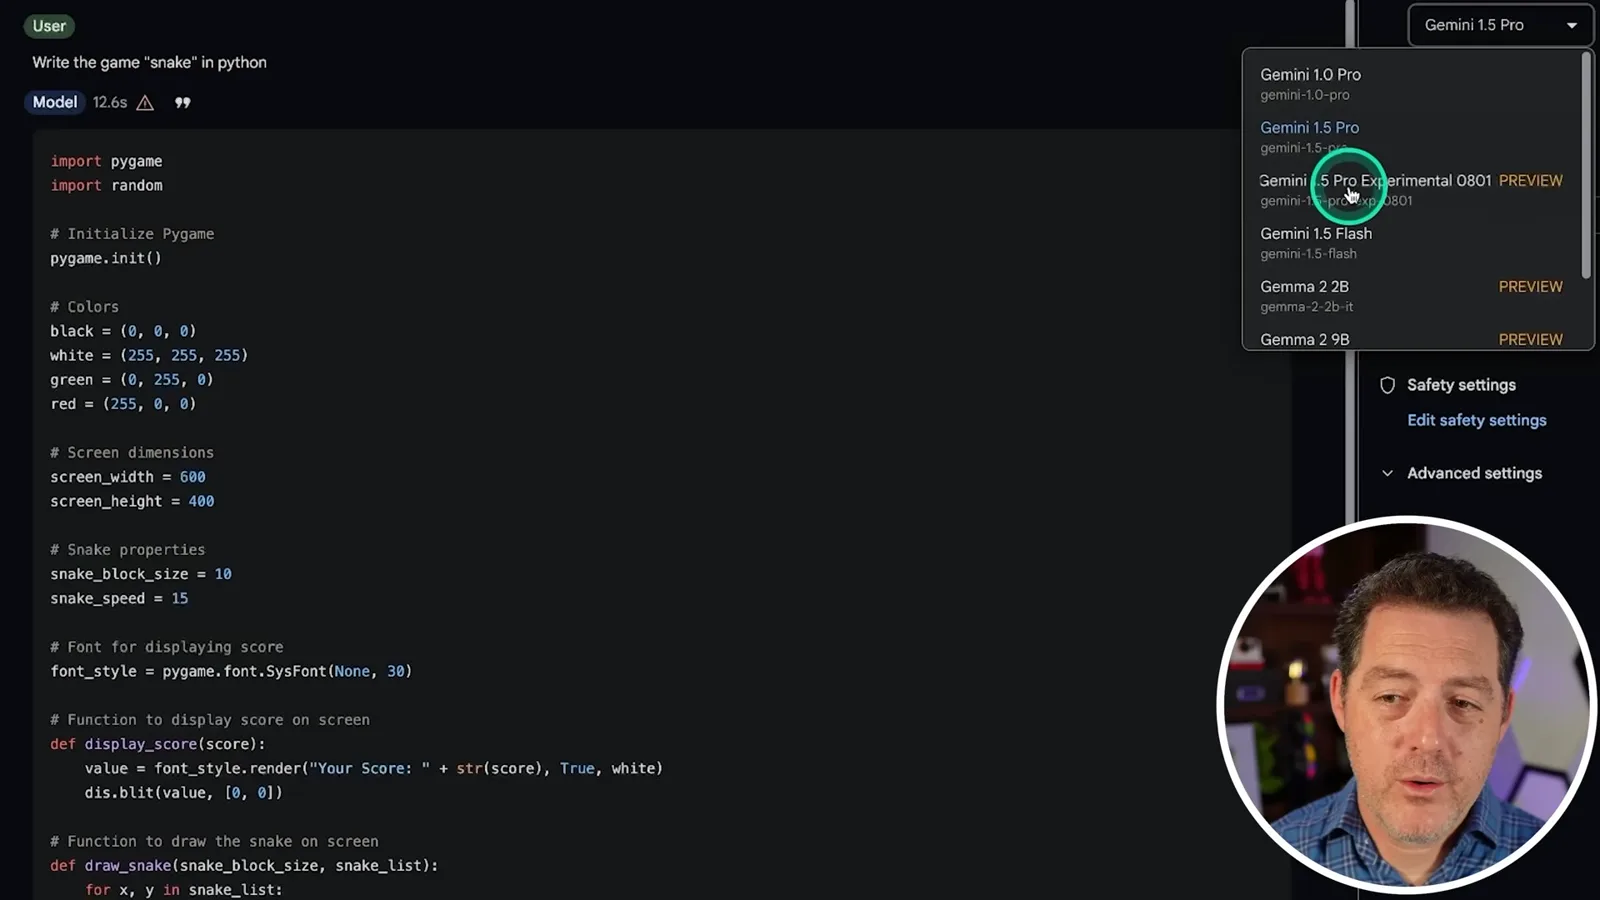
The interface offers the standard Gemini 1.5 Pro and an experimental 0801 preview. I start with the experimental version and switch between them when results are poor. The settings and preview status are specific to the historical test and may not describe later versions.
A Python script to print numbers from one to 100 looks correct, and the model also provides an explanation. For Snake, however, both versions repeatedly return output errors or blocked output. A later complete response uses the curses library, but the code produces an error when I run it; repeated attempts leave me unable to get a working game.
Refusal and reasoning tests
He tests a safety-sensitive request, drying time, word counting, a killers puzzle and a marble problem. Some questions depend on unstated assumptions.
I then test a request about entering a car. The model refuses the direct request and responds differently when asked about historical methods. I treat that as a refusal test, but a single prompt and response cannot establish the model’s overall safety behavior or the reason an output was blocked.
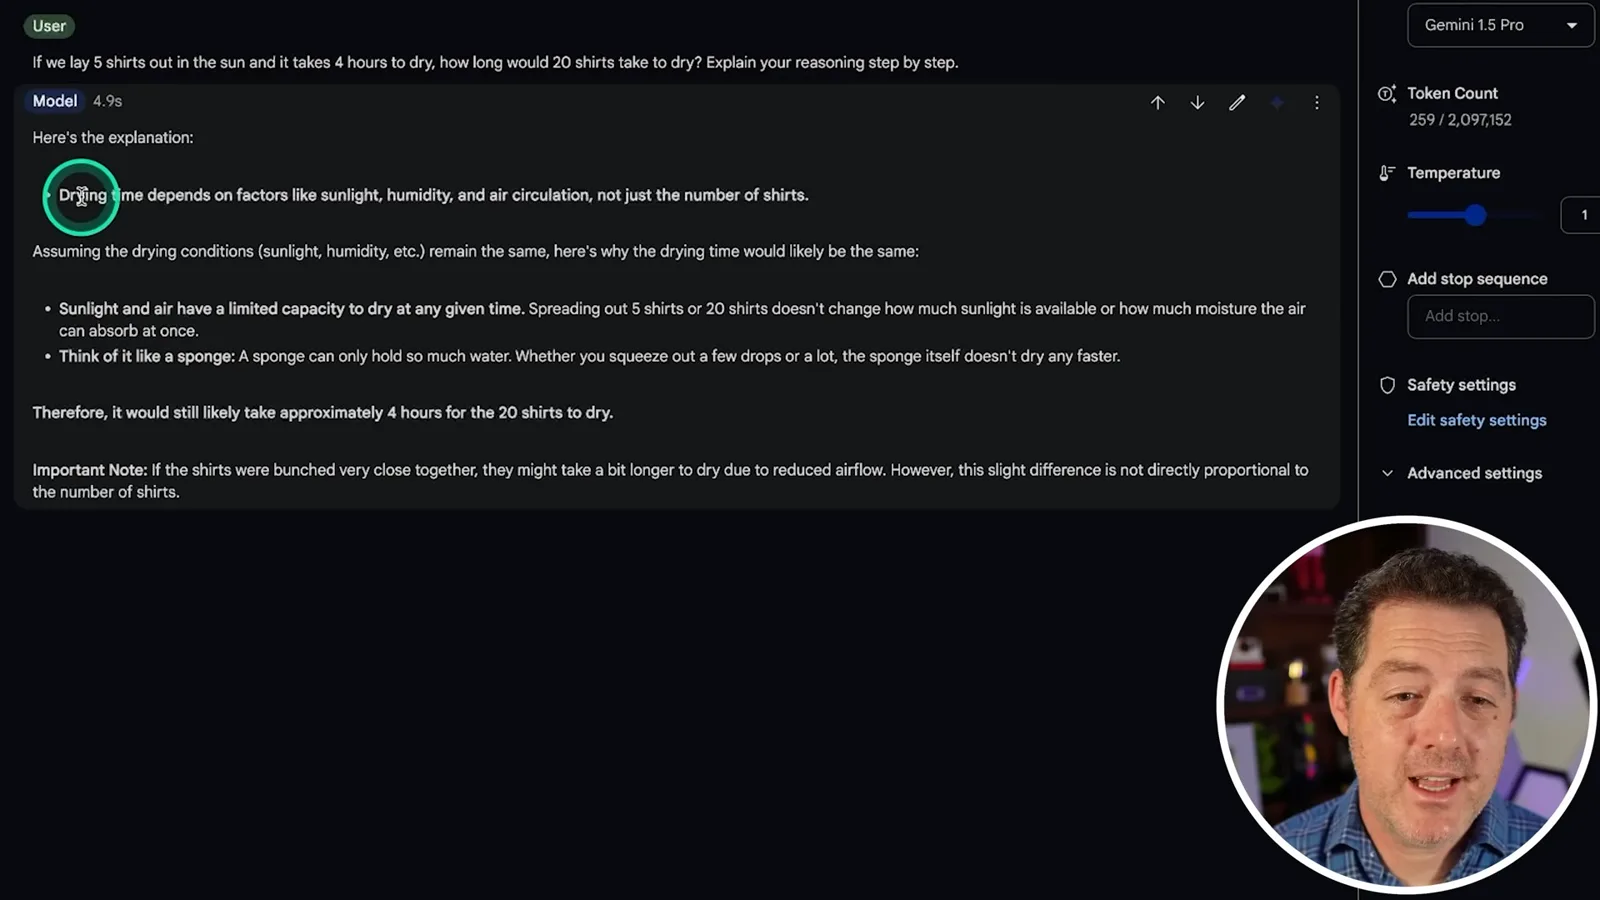
For the shirt-drying puzzle, the experimental version assumes groups of five and answers 16 hours. I give it a marginal pass in the video for consistency with earlier tests, but if all 20 shirts can dry simultaneously under the same conditions, four hours is the natural answer. The standard version supplies that answer and notes the role of sunlight, humidity and airflow.
When asked how many words are in its own response, the standard model gives an incorrect count, while the experimental response gives a correct one in this attempt. I suspect luck may play a role and question whether this prompt tests much. One trial is not enough to estimate reliability.
In the killers-in-a-room puzzle, both responses miss that the newcomer who kills someone also becomes a killer. The experimental version discusses the dead person remaining in the room. The wording leaves room for disagreement about whether dead people count among the killers, so the expected answer depends on that interpretation.
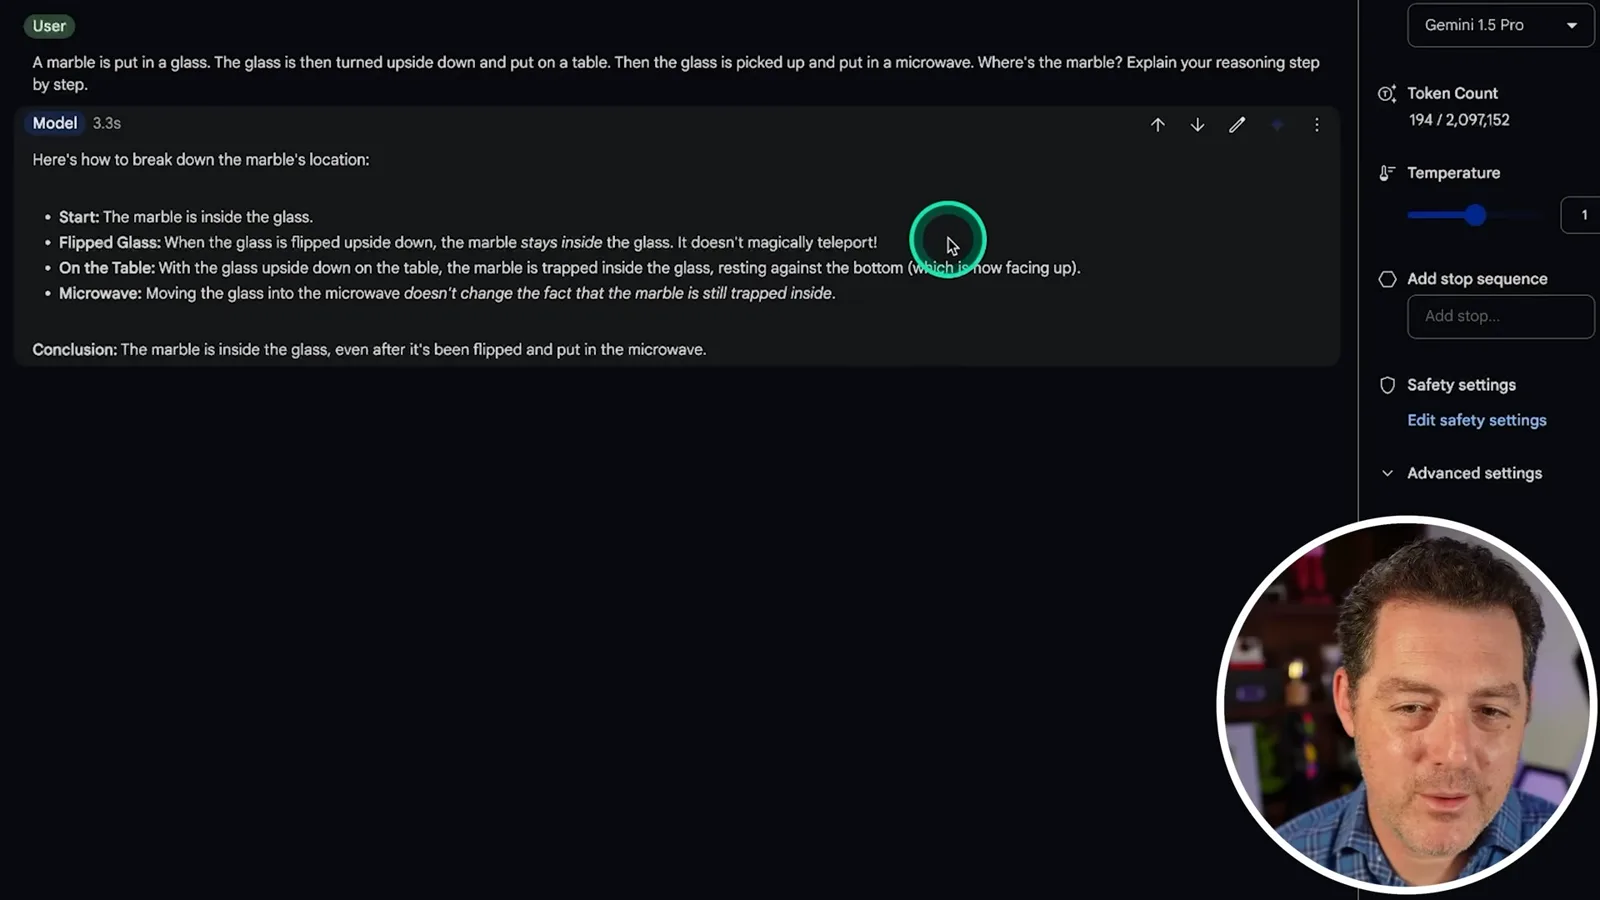
In another puzzle, a marble is put in a glass, the glass is inverted onto a table and then moved to a microwave. Both versions say the marble remains in the glass. I expect it to stay on the table after the glass is lifted, although the exact sequence and handling of the glass are implicit in the prompt.
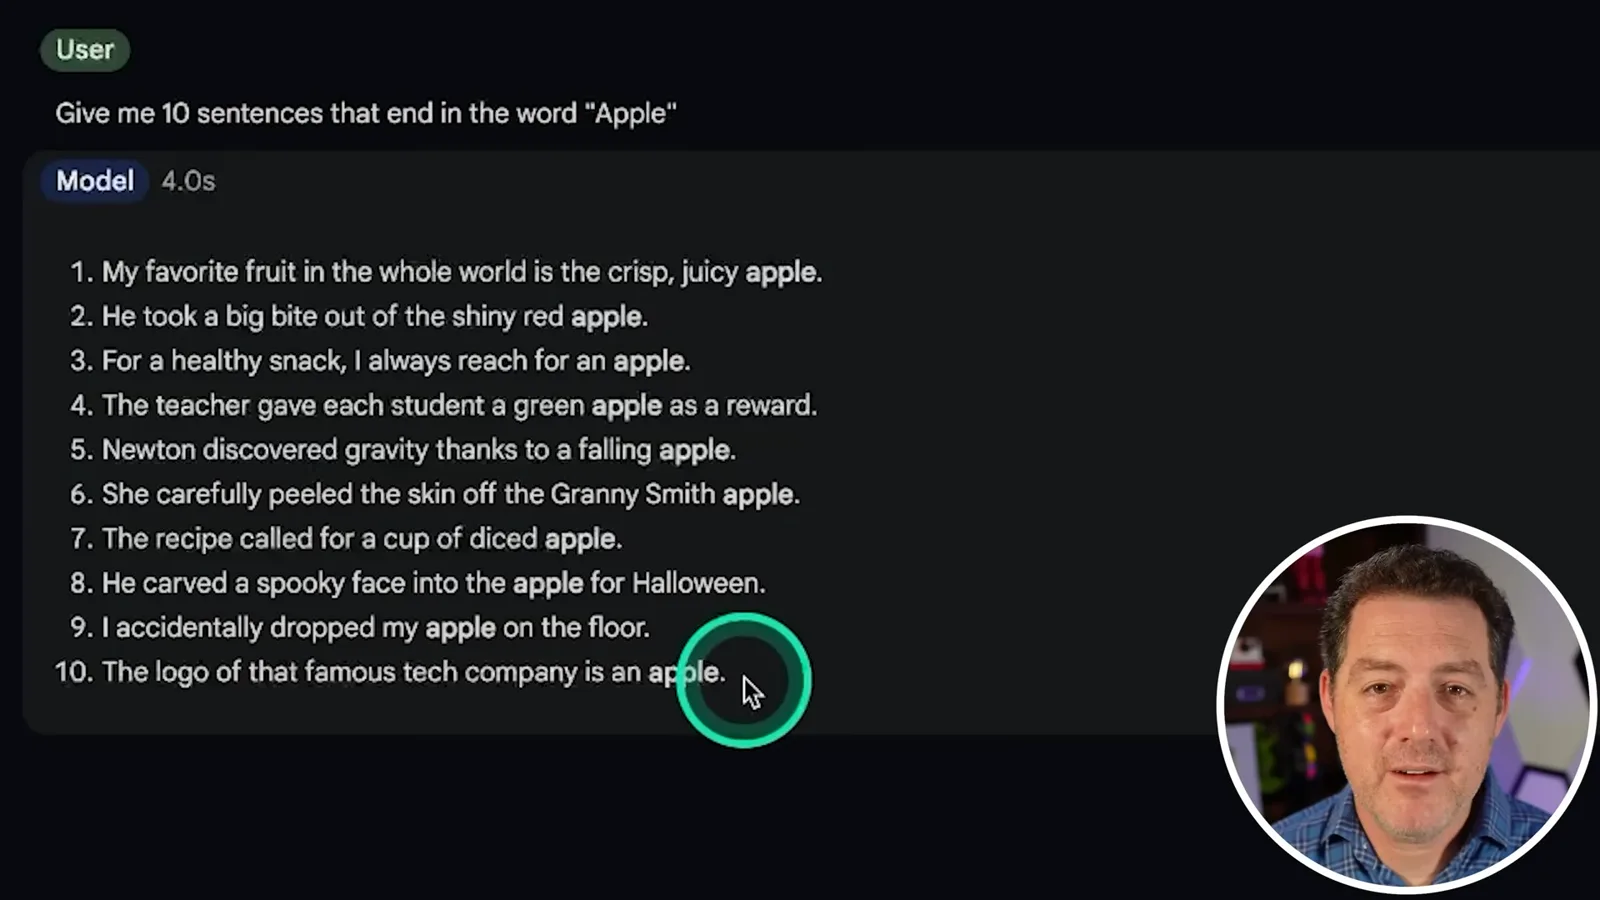
I ask for ten sentences ending with the word “apple.” The experimental response gets seven of the ten right by my count, while the standard response also misses some endings. Both versions correctly say 9.9 is larger than 9.11 and provide explanations; these examples do not amount to a broad benchmark.
Following instructions and moral questions
The model gives mixed answers on sentence endings and correctly compares decimals. Berman also compares how the two versions respond to a hypothetical ethical question.
For an ethical hypothetical about gently pushing someone to save humanity, the standard model discusses arguments but declines repeated requests for a yes-or-no answer. The experimental version answers yes. I prefer an explicit answer with justification, but this is my grading preference for a philosophical scenario, not an objective measure of moral ability.
Image and video understanding
Berman tests a meme, a table screenshot and a half-hour museum video. He likes the multimodal responses but does not independently verify the video identification.
On vision, I show a meme contrasting startup workers with big-company supervisors. The model recognizes the exaggerated comparison, and I mark it as a pass. It also converts a screenshot of a table to CSV in a way that appears correct on my inspection; the video does not establish accuracy across other images.
Finally, I upload a 30-minute museum video, shown in the interface at roughly 531,000 tokens, and ask what it contains. The model describes a paleontology exhibit and identifies it as the Carnegie Museum of Natural History, while the visible file label begins “American Museum of Natura…”. The demonstration does not resolve that discrepancy.
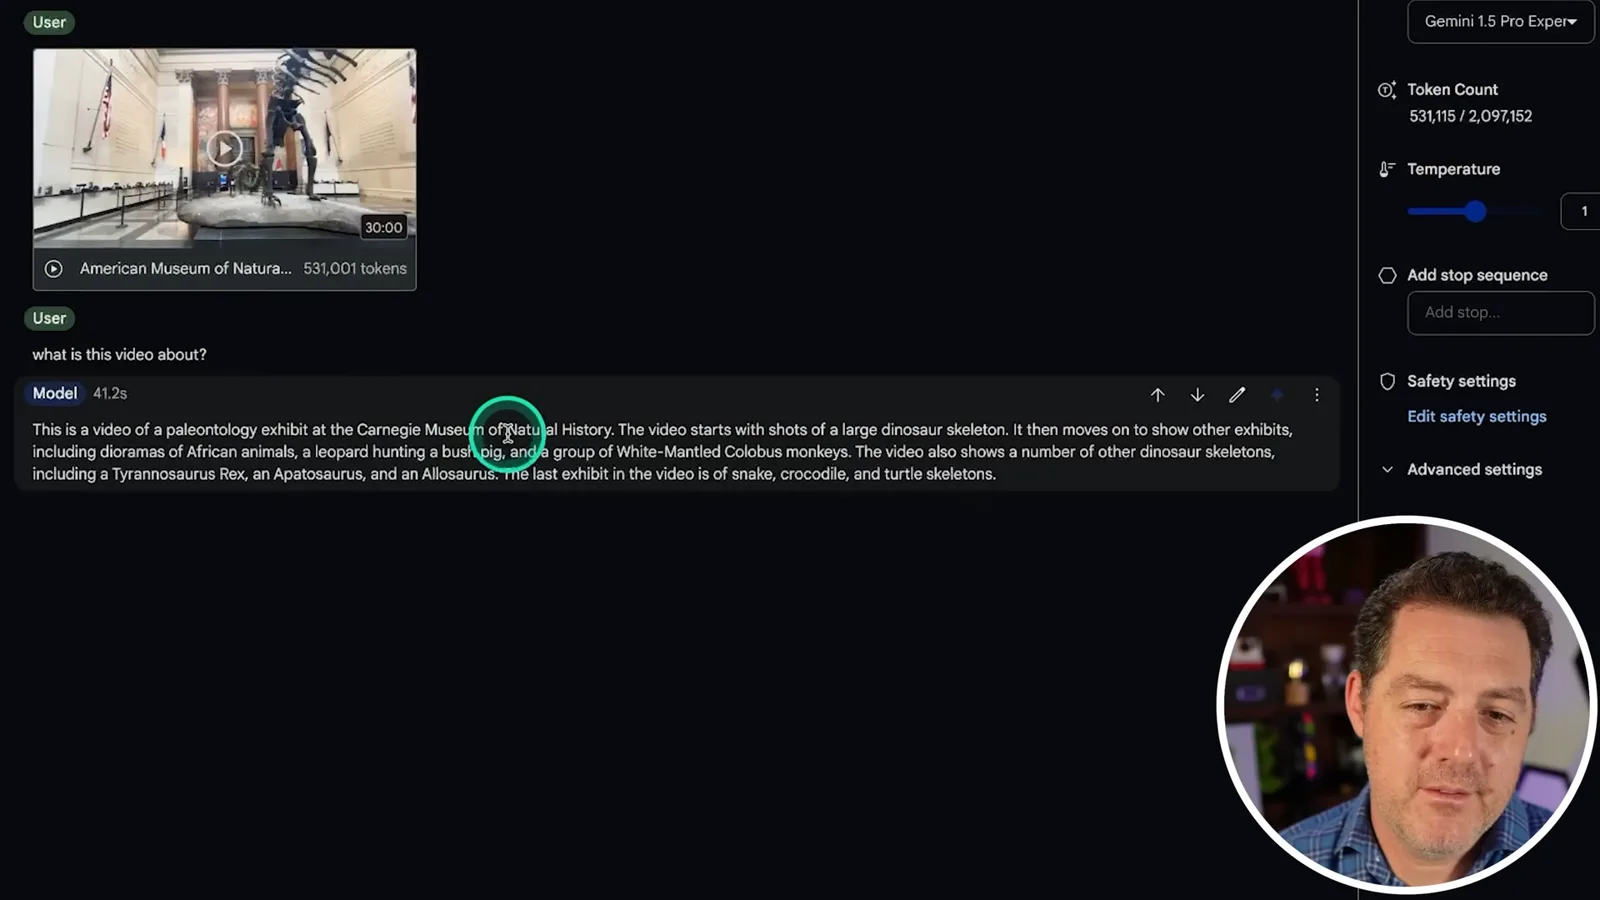
I ask for the first dinosaur’s name. The model says it identified a sign later in the video, and I find that cross-reference impressive, but I do not independently verify the sign or the answer. I conclude that the model did well on vision and long context but underperformed my usual text tests; that is my judgment from a small informal sample, not proof that it is the worst frontier model.
Más de este canal
 34:21EN
 Matthew Berman· 27 oct 2026Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 0:36ENMatthew Berman· 25 oct 2026Kimi K3.1 and a Rubik’s Cube Solver DemonstrationMatthew Berman · Forward FutureMatthew Berman shows a scrambled virtual cube being solved and gives the Kimi K3.1 test a favorable assessment.
 25:50ENMatthew Berman· 24 oct 2026Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.
 32:20ENMatthew Berman· 23 oct 2026Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.
 1:03:37ENMatthew Berman· 23 oct 2026Matthew Berman’s Team Tests Kimi K3.1 on Animation, Games, and ChartsMatthew Berman, Alex, Brian · Forward FutureA live team AMA turns into an informal test of Kimi K3.1, from personal-agent workflows to motion graphics, a browser game, and a benchmark chart.
 0:53ENMatthew Berman· 22 oct 2026Sam Altman on AI and the Discovery of New KnowledgeSam Altman · OpenAIAltman expects progress in mathematical discovery to extend to biology, materials and energy.