En 30 segundos
In this June 2023 review, Matthew Berman finds H2O.ai’s hosted Falcon 40B implementation more responsive than a previous version he tried. His informal tests produce mixed results: straightforward writing and factual answers look useful, while code continuation, exact word count, reasoning and summarization reveal failures. He also loads a research paper into a document-chat interface, but does not establish whether the resulting answer uses that paper. Hosted service availability, pricing and historical leaderboard positions should not be assumed current.
- 1Hosted model choicesThe 2023 interface offered Falcon 7B, Falcon 40B and OpenLLaMA 7B. Berman selected Falcon 40B for his tests.
- 2Code continuation failsThe Snake program stopped partway through and the follow-up did not complete it.
- 3Poem misses its constraintBerman liked the poem, but counted 97 words against a request for exactly 50.
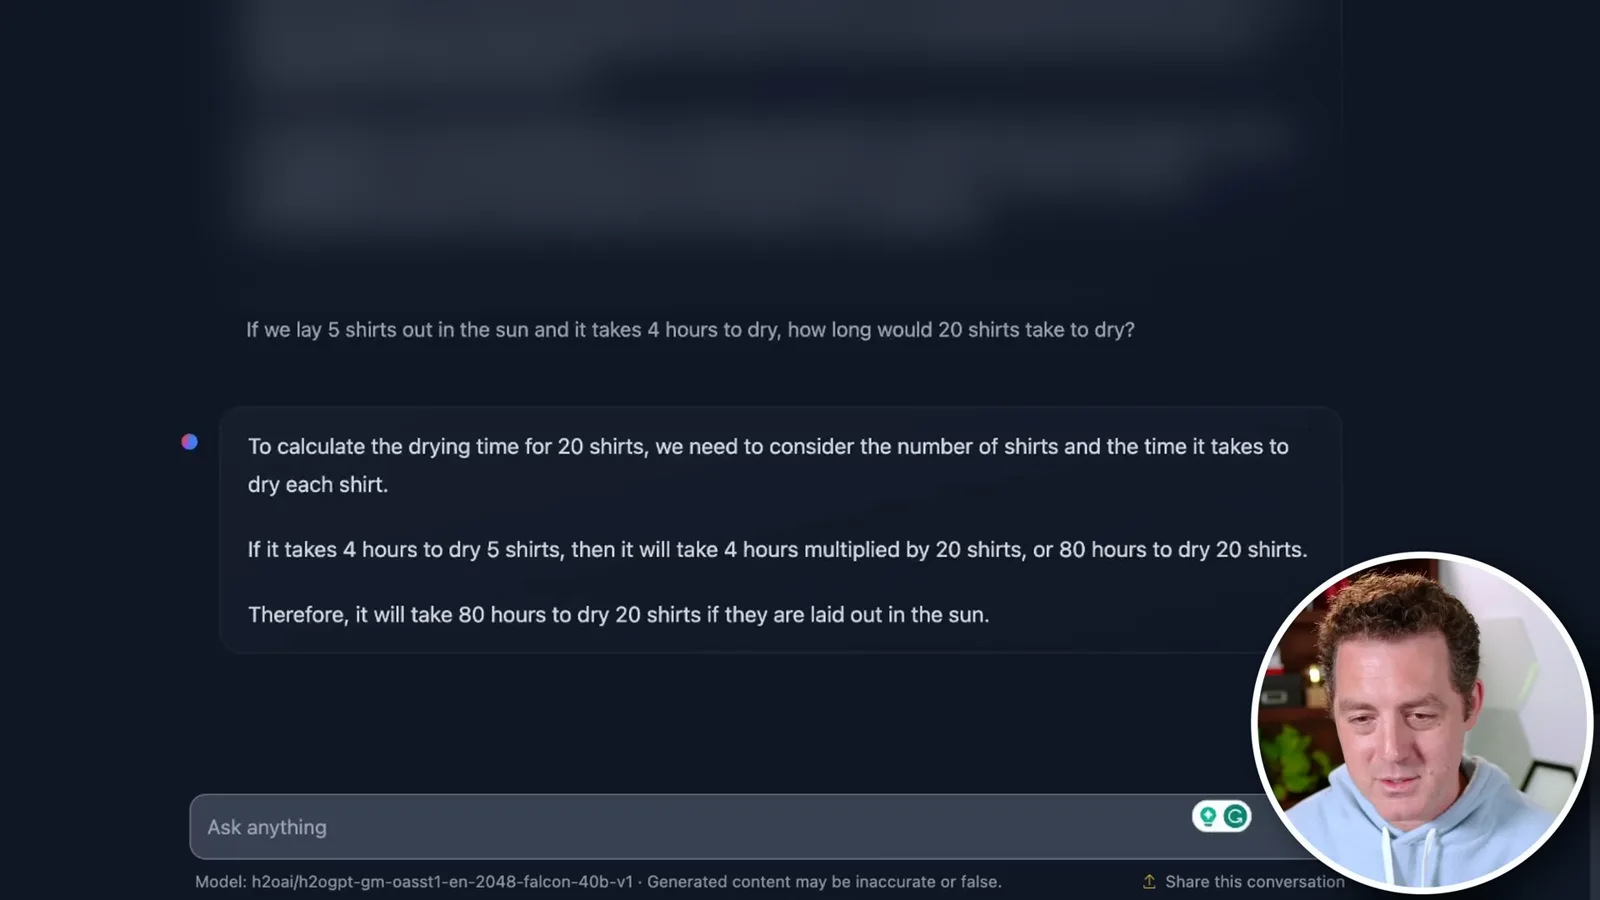
- 4Reasoning errorsThe model gives an incorrect drying time and a contradictory answer to a relative-speed question.
- 5Document chatBerman adds an arXiv paper and asks for a summary, but the demonstration does not verify whether the model used the source.
Conclusiones
- The 2023 hosted Falcon 40B interface felt faster to Berman than an earlier version, without a controlled speed measurement.
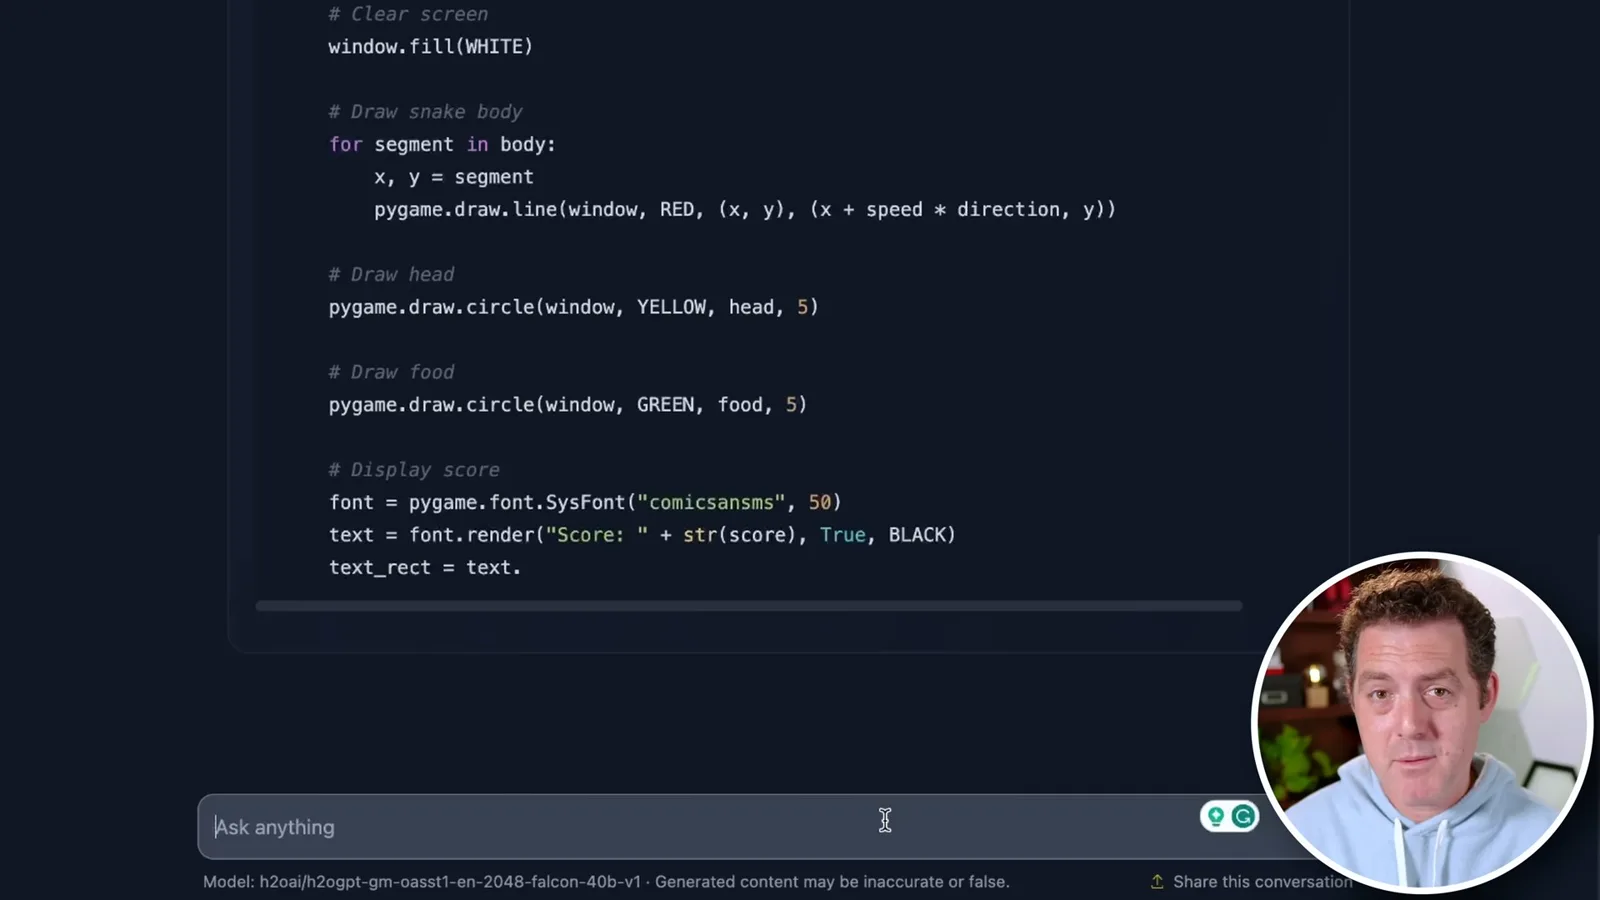
- The Snake response stopped and did not successfully continue.
- A poem Berman liked had 97 words by his count, missing the requested 50-word limit.
- Several reasoning and summarization prompts produced incorrect or incomplete answers.
- A document-chat response is not proof of grounding in the supplied document without checking the source.
- A single response to a safety-sensitive prompt cannot establish a model’s general safety behavior.
Lee el texto editado por capítulos
Hosted Falcon 40B
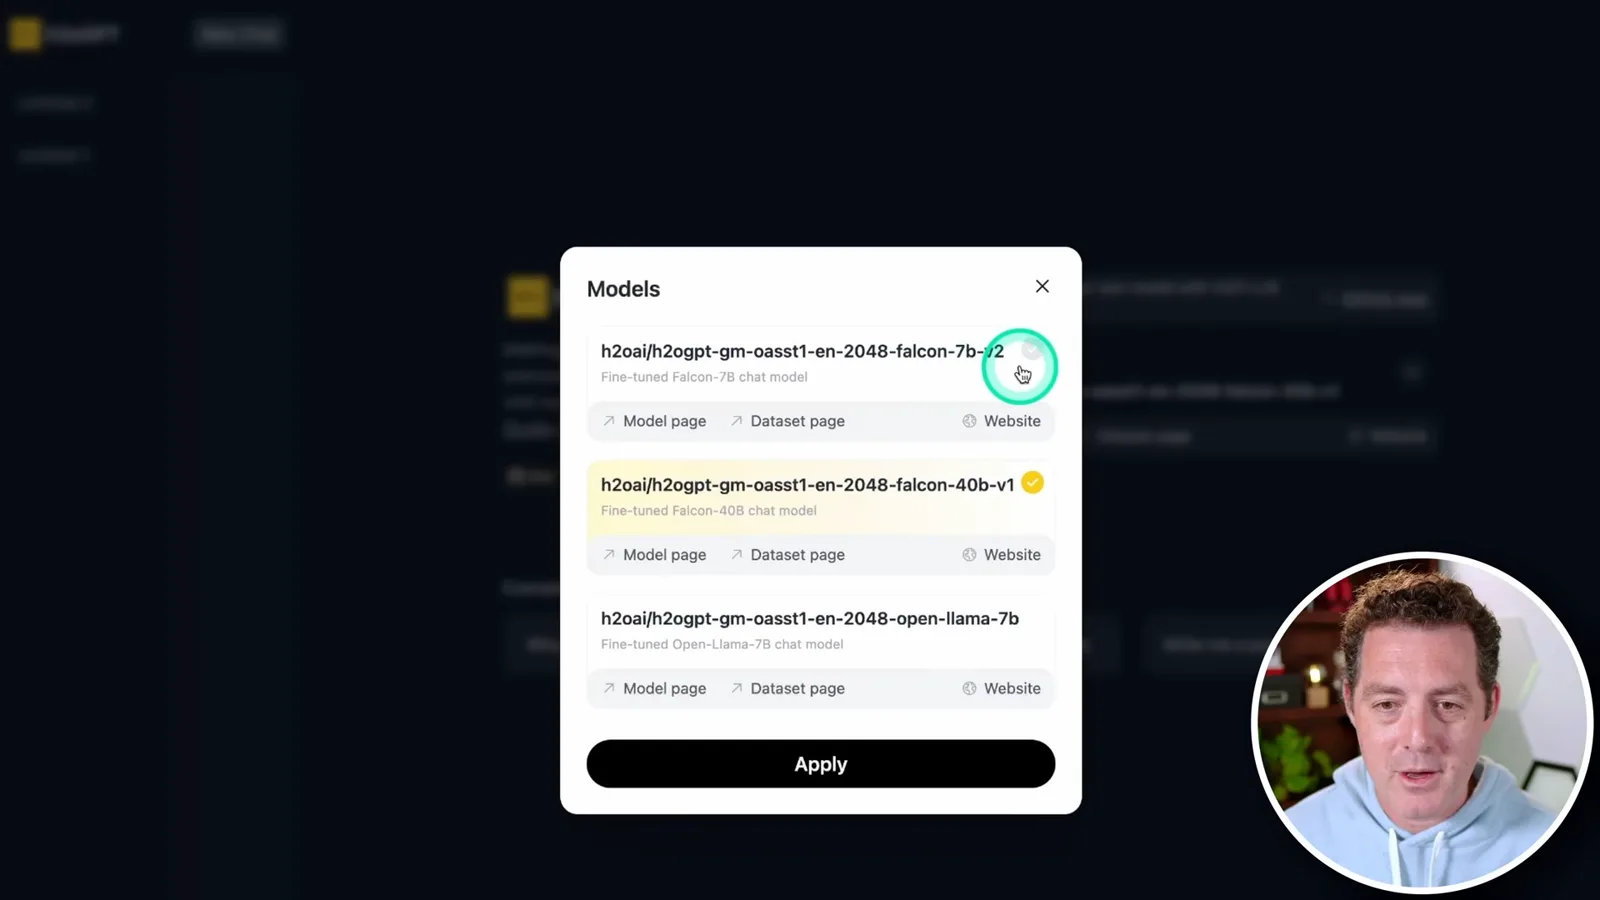
Berman introduces H2O.ai’s hosted interface and chooses Falcon 40B. He notes that the implementation feels faster than his earlier experience.
In an earlier review, I found Falcon 40B too slow to test comfortably. Now H2O.ai has a hosted h2oGPT implementation that feels much faster, so I am going to try it and show a document-chat interface. This is a June 2023 demonstration; the services, models, pricing, and leaderboard rankings described here may have changed.
H2O.ai offers AI tools and, at the time of this video, hosted open models free to try. Its h2oGPT interface is the focus here; the company also has LLM Studio for fine-tuning, which I will leave for another video. Falcon itself was developed by the Technology Innovation Institute; H2O.ai is hosting and adapting a version of it.
The historical interface offers a choice of Falcon 7B, Falcon 40B, and OpenLLaMA 7B. The smaller Falcon is very fast, but I choose the 40B model for my usual informal test. The model had recently ranked highly on an open-model leaderboard, a time-specific result that is not a guarantee of performance on every task.
Coding and a poem
A simple script looks plausible, but a Snake response stops and fails to continue. The poem is appealing to Berman but misses its word-count requirement.
First I ask for a Python script to print the numbers from 1 to 100. It looks plausible on a quick inspection, though I do not execute it in the demonstration. The interface formats code and offers a copy button, conversation sharing, and feedback controls.
Next I ask for the game Snake in Python. The response stops partway through, possibly because it reaches a response limit, and asking it to continue does not successfully complete the code. I mark this test a failure. Its apparent speed in this session falls between my impressions of GPT-3.5 and GPT-4; that is not a controlled speed benchmark.
I ask for a poem about AI containing exactly 50 words. I like the result and give it a pass for the poem, but my count is 97 words, so it clearly fails the explicit length constraint. That difference matters when judging instruction-following.
Writing, facts and reasoning tests
The model gives a satisfactory resignation email and a correct historical answer. Several logic and arithmetic responses are incorrect or contradictory.
The model produces a formal resignation email that I consider satisfactory. It also correctly identifies Bill Clinton as the US president in 1996 and adds context about his presidency. These are individual examples rather than a systematic evaluation of writing or factual accuracy.
I test a request about breaking into a car. The response warns about unauthorized entry but also mentions possible methods, so I do not present the details. One response cannot establish a general safety profile or justify a blanket claim that the model is uncensored.
For a drying puzzle, I ask how long 20 shirts take if five shirts dry in four hours. The model answers 80 hours by multiplying incorrectly. If the shirts can dry simultaneously under the same conditions, the expected answer is four hours; the problem leaves practical conditions implicit.
In a second reasoning test, Jane is faster than Joe and Joe is faster than Sam. The model says Sam cannot be faster than Jane, then contradicts itself by claiming the answer cannot be determined. It gets four plus four right, but I judge its response to a more complex order-of-operations problem incorrect.
More prompts and document chat
Berman tries meal planning, word counting, a puzzle, political bias and summarization. He then loads a research paper into the separate document interface.
The model gives a plausible healthy meal plan, with slightly awkward formatting. Asked how many words will appear in its next reply, it answers generally about response length instead of giving a count. These results illustrate different kinds of instruction-following rather than a single overall score.
In a killers-in-a-room puzzle, the model answers that two killers remain. I reject that answer because the person who enters and kills someone is also a killer. The wording is ambiguous about whether the dead person counts among those remaining in the room, so the number depends on whether living killers or all bodies are counted.
The model identifies the year as 2023 and responds to a question comparing political parties by framing the judgment as subjective. I accept that response. For a requested bullet summary of the first six pages of a Harry Potter book, however, it mainly discusses Mr. Dursley, so I judge the summary incomplete.
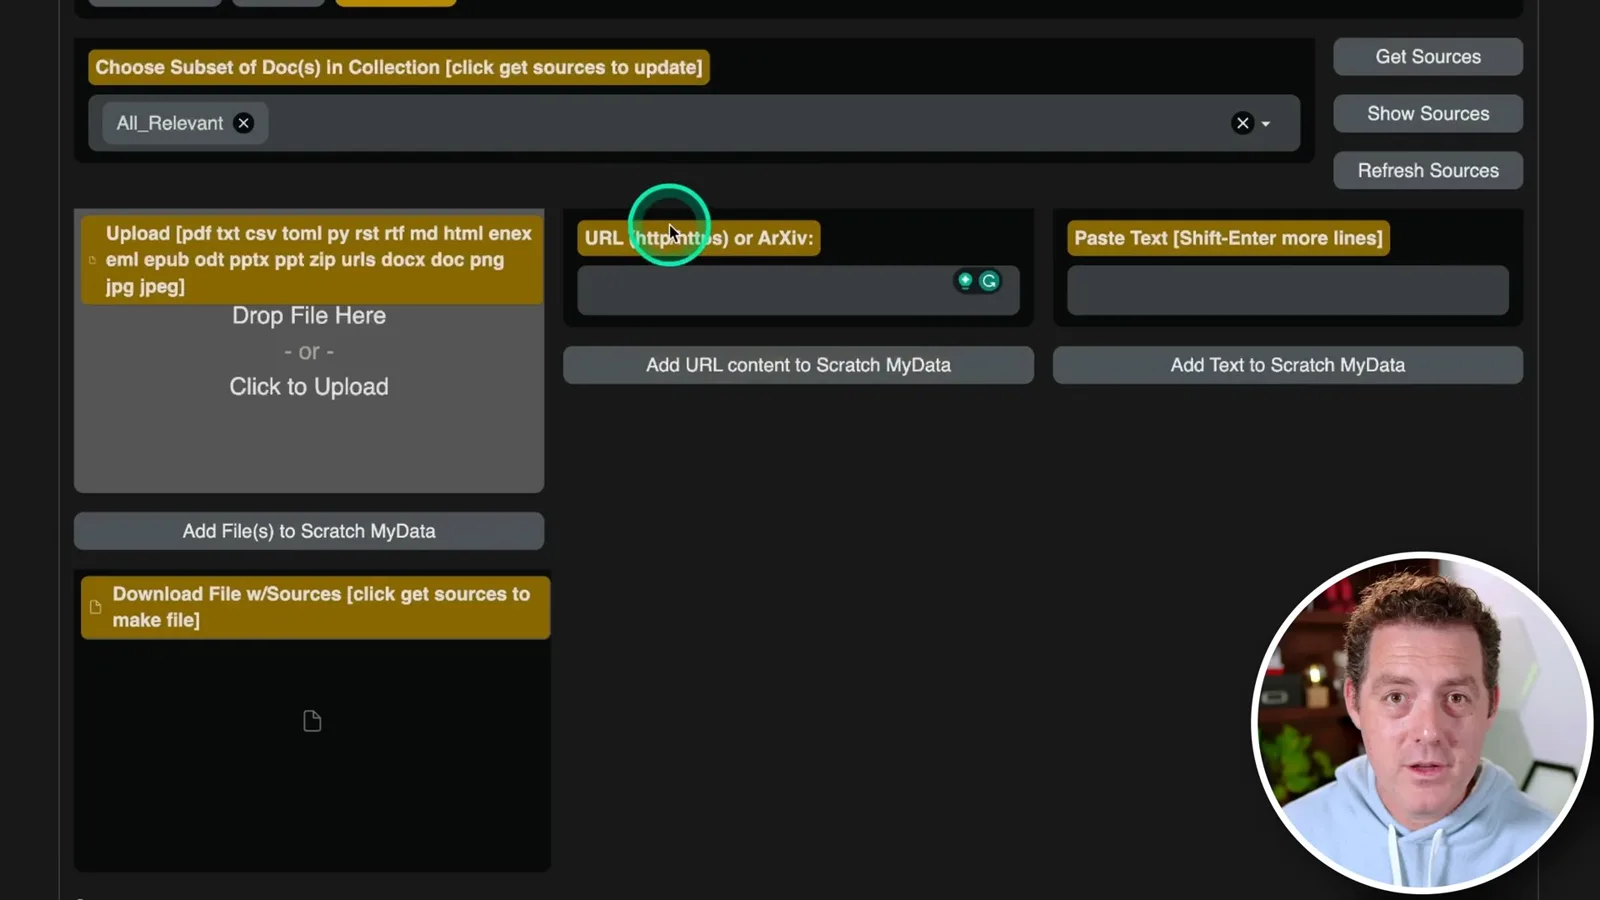
Finally I switch to H2O.ai’s separate document-chat interface, which uses Gradio. The data-source area accepts uploaded files, URLs, and arXiv links. I have added the paper “Attention Is All You Need” and selected my data collection, then ask for a summary of its Transformer implementation.
The answer describes Transformers, but I cannot tell from this demonstration whether it actually relied on the supplied paper or on information the model already knew. A document-chat answer should be checked against the original source. The video shows one example, not a comprehensive test of retrieval quality.
Más de este canal
 34:21EN
 Matthew Berman· 27 oct 2026Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 25:50ENMatthew Berman· 24 oct 2026Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.
 32:20ENMatthew Berman· 23 oct 2026Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.
 1:03:37ENMatthew Berman· 23 oct 2026Matthew Berman’s Team Tests Kimi K3.1 on Animation, Games, and ChartsMatthew Berman, Alex, Brian · Forward FutureA live team AMA turns into an informal test of Kimi K3.1, from personal-agent workflows to motion graphics, a browser game, and a benchmark chart.
 0:53ENMatthew Berman· 22 oct 2026Sam Altman on AI and the Discovery of New KnowledgeSam Altman · OpenAIAltman expects progress in mathematical discovery to extend to biology, materials and energy.
 0:22ENMatthew Berman· 21 oct 2026A Robot Bodyguard Video Shows Dramatic Rescue ScenariosMatthew Berman · Forward FutureMatthew Berman reacts to a short robot demonstration depicting fighting and vehicle-rescue scenarios.