En 30 segundos
Every’s Dan Shipper says Fable 5.2 is strongest when handed ambitious coding and creative projects, including a custom video editor and a toy-based racing game. Those gains come with a cost: one research documentary used 1.4 billion tokens, estimated at nearly $2,000 using Fable 5.1 API rates. For routine writing or interactive work, he often prefers another model or a lower effort setting.
- 1A custom editor took weeks and thousands of dollarsKieran Klaassen used Fable 5.2 to build EveryCut around the team’s video workflow.
- 2A toy photo became a playable racing gameShipper compares the Fable game with an Astra version on the same toy-room prompt.
- 3A research explanation became a documentaryMike Taylor used the model to turn footage about his research into a video.
- 4One video run consumed 1.4 billion tokensShipper estimates almost $2,000 at Fable 5.1 rates; Fable 5.2 pricing was unknown at recording.
- 5Writing remains weaker than coding in this reviewThe team found readable prose, but Shipper says it can bury the lead and become condescending.
Conclusiones
- Use the model for substantial work that justifies long runs and token expense.
- Estimate cost from token use, and distinguish proxy prices from actual model pricing.
- Try lower effort for interactive work and designs that become over-elaborate.
- Keep routine writing and email on a faster, cheaper model when its output is sufficient.
Lee el texto editado por capítulos
A model with uneven strengths
Every tested the model on its own work and found the biggest gains in coding.
I judge a new model by whether it makes me try things I would not otherwise attempt. Fable 5.2 does that for some tasks, but its strengths are uneven: for ordinary work, I might still choose Opus 5.5.
Every’s frontier team receives early access and free tokens from major labs. We test models on our own coding, writing, design and knowledge work, rather than relying only on public benchmarks or short demonstrations.
I rate the model especially highly for coding, including building games that are actually fun. For writing I give it a B or B-plus: it can bury the lead and its prose can be clunky. Design earns an A. Knowledge work can be excellent for the right user, but for routine tasks it can be slow and expensive.
Build professional tools and playable games
A custom editor and a toy-room racing game illustrate the team’s coding tests.
My colleague Kieran Klaassen built EveryCut, the video editor we now use, with Fable 5.2 through prompting. It combines the particular editing, transcription and recording features our team uses from several products into a tool fitted to our workflow.
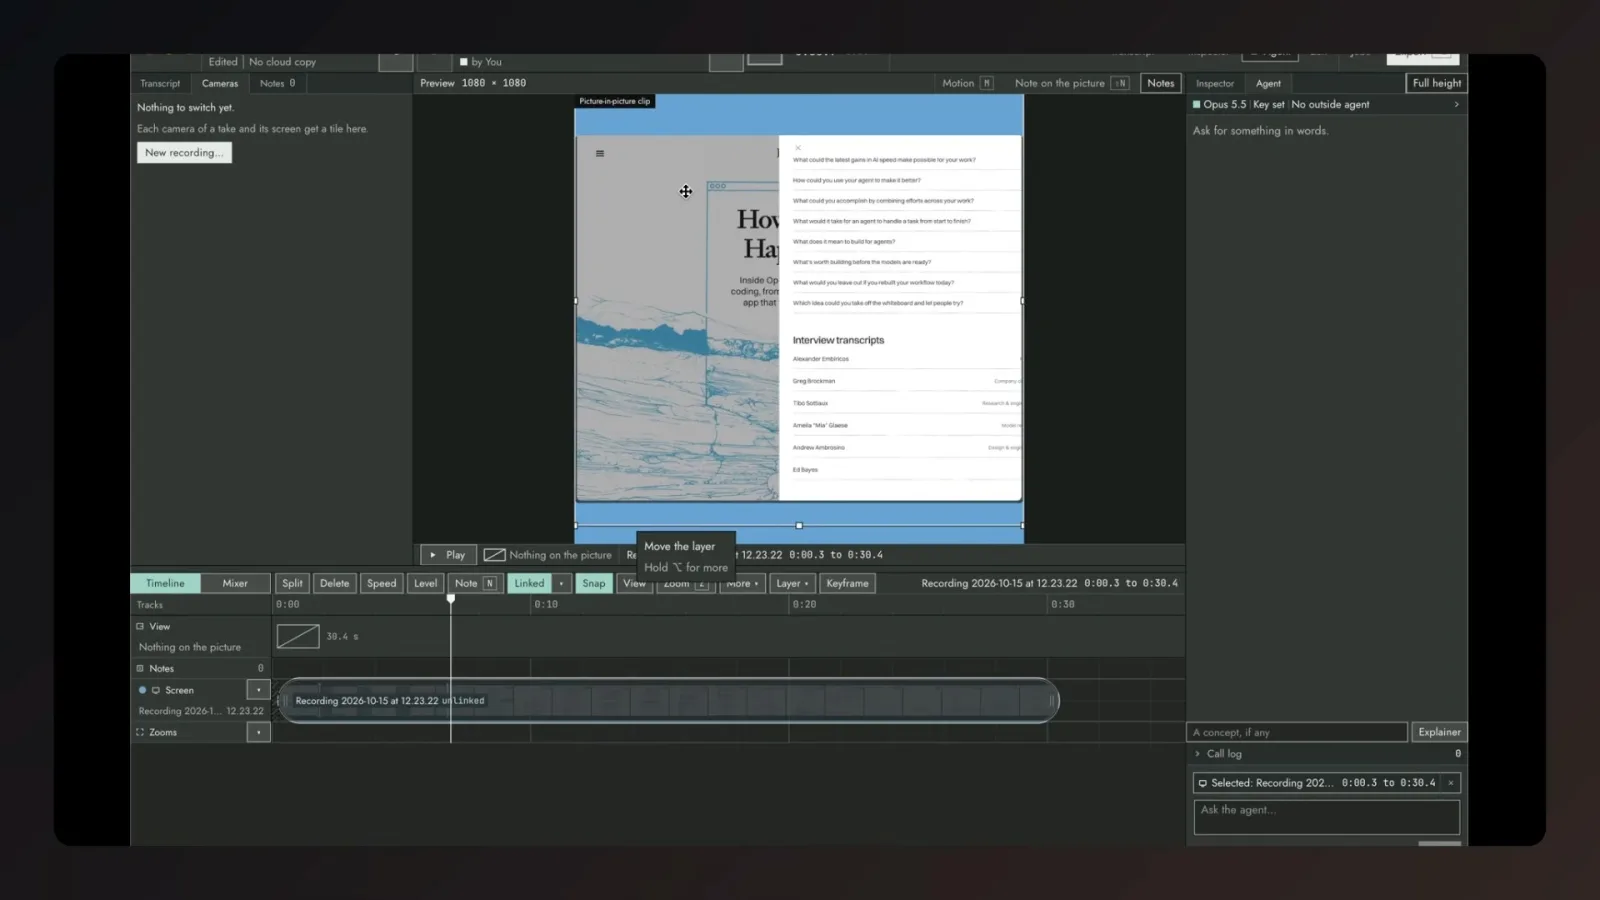
Klaassen sees this as a change in professional software: organizations can build tools around their specific workflows. This was not a two-hour project, however. I say the editor took weeks and thousands of dollars, which may still make sense for a serious creative team.
Tyler Nishida calls Fable an overnight model. I found it useful to send substantial work to a cloud computer, leave it running and return hours later. For interactive back-and-forth, lower effort settings or Opus may be a better fit.
The model can give an estimated completion time. In one example it warned Tyler to plug in his laptop because the task would outlast the battery. Klaassen prefers Opus 5.5 for thinking together and Fable for work he can hand off.
Klaassen also used the model on creative tools including a music application. He says its longer autonomous coding runs feel more trustworthy than earlier versions, which sometimes spent tokens on unnecessary work.
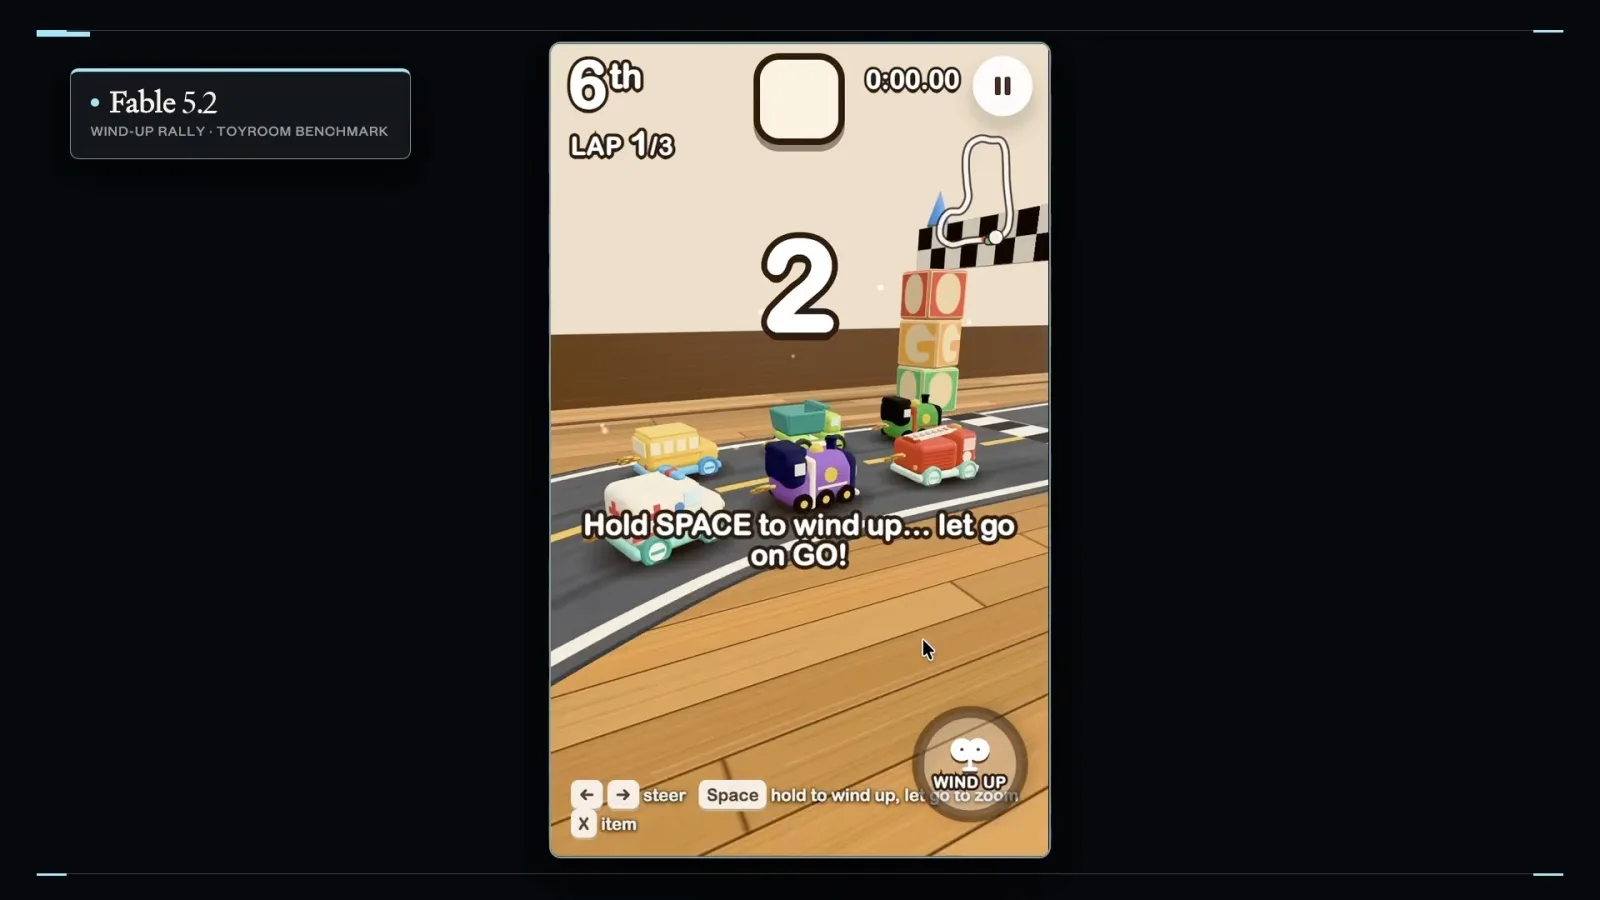
Our colleague Jack Cheng tests models by photographing toys in his children’s room and asking for a game. In the comparison shown, the Astra game has limited controls, while the Fable version uses the toys as racers and adds a track, items and more playable controls.
Turn research into a documentary
Parallel experiments and video creation expand the work a researcher can hand off, with substantial token costs.
For routine documents and email, I think the extra cost and power are unnecessary. But for people willing to change the form of their work, Fable can make a research result into something more than a document or slide deck.
Our head of evaluations, Mike Taylor, researched how to get AI to write like him. Instead of presenting only a document, he used the model to turn footage of his explanation into a short documentary about the process and findings.
Taylor described the three-week test as exceptionally productive. His work involves model experiments: he could give the model ideas to run in parallel, attend to other responsibilities and return to results later in the day.
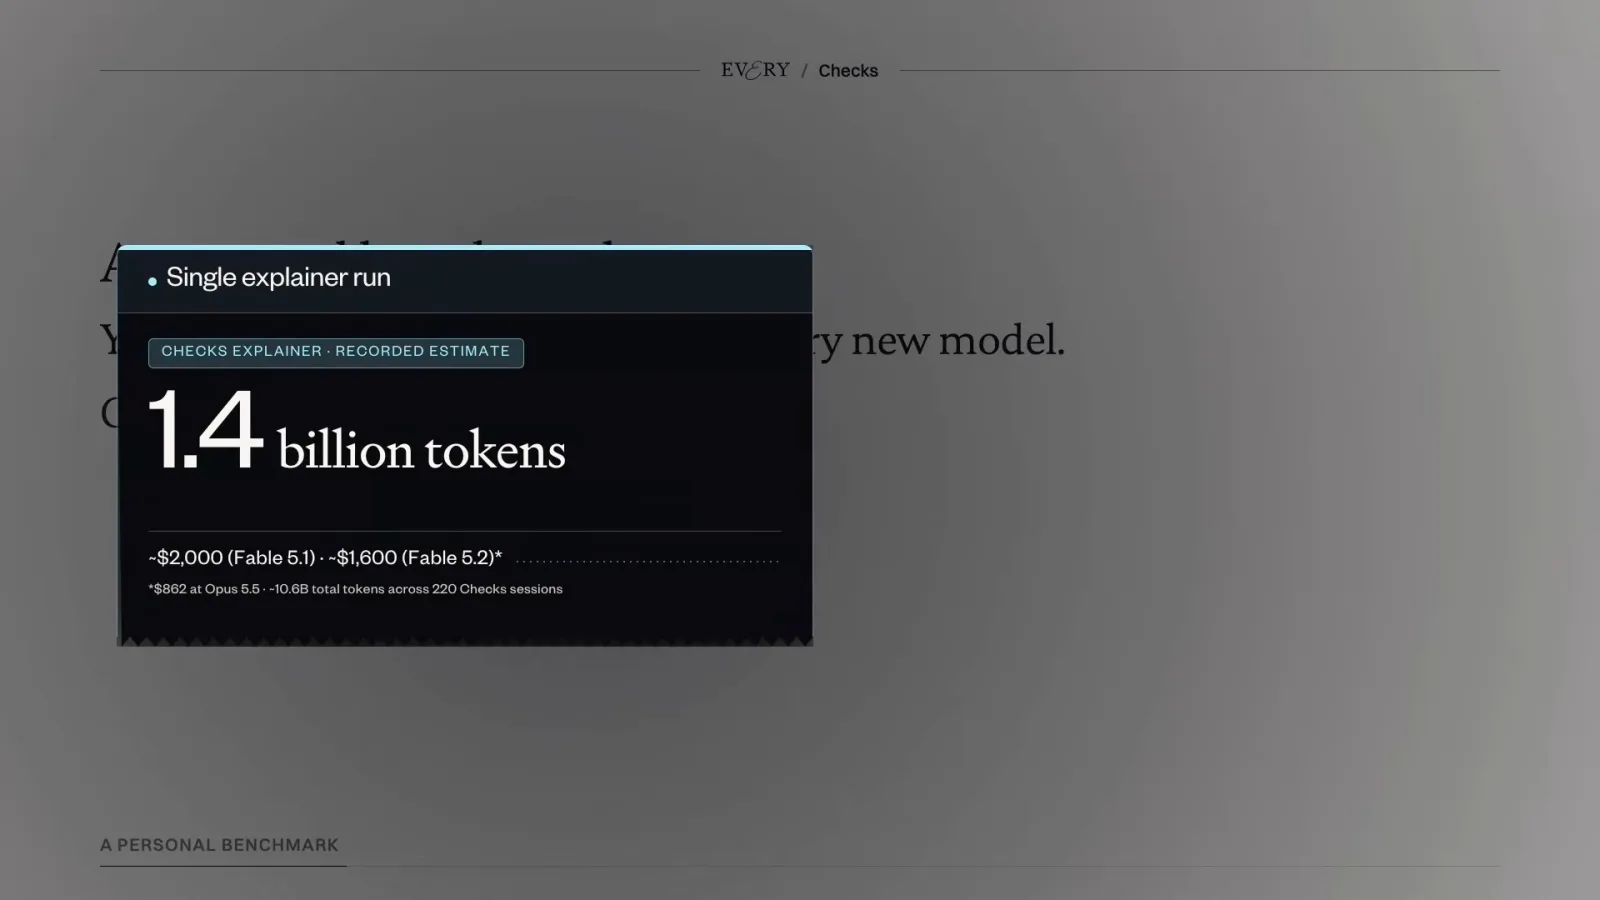
At recording time we did not know Fable 5.2’s exact price. The documentary example used about 1.4 billion tokens; we estimated almost $2,000 at Fable 5.1 API rates and $862 at Opus 5.5 rates. These are estimates using other models’ prices, not a bill or a confirmed Fable 5.2 price.
Writing, design and choosing the right effort
The reviewers found writing less compelling, while design benefited from careful effort settings.
For writing, our staff writer Katie found the prose easy to read, emotionally aware and funny, but also sometimes condescending or inclined to stop early at medium effort. I prefer Gemini 4 Argon for writing, with Astra close behind; in my tests Fable can bury the most interesting point.
For design, Tyler Nishida saw a new ceiling and found the model easy to steer. Higher effort sometimes produced too much, so he suggests trying lower effort settings. I recommend varying effort, not only switching between model tiers.
One detail stood out in my recurring task of making a film from Plato’s Protagoras: the model gave the younger Socrates a dark beard. Other models often defaulted to an older, gray-bearded depiction. I see it as an example of the model attending to details in a creative brief.
My conclusion is to reserve this model for ambitious coding and creative work where the potential result justifies the tokens. For ordinary tasks or some coding jobs, I found faster, more efficient alternatives such as Astra 6 could be preferable.
Más de este canal
 46:14EN
 Every· 4 nov 2026Pódcast · 2 vocesKevin Roose on Reporting AI History and Choosing What to DelegateInvitado: Kevin Roose · Presenta: Natalia QuinteroThe journalist discusses The AGI Chronicles, interviewing a secretive industry, AI-assisted research and his distinction between weightlifting and forklifting.
 50:51ENEvery· 29 oct 2026Pódcast · 3 vocesFred Graver on Using AI as a Writers’ Room, Not a GhostwriterInvitado: Fred Graver · Presenta: Dan Shipper, Natalia QuinteroThe writer and producer explains how he develops ideas and uses AI feedback.
 43:01ENEvery· 21 oct 2026Pódcast · 8 vocesHow Every’s Frontier Team Turns AI Experiments Into Useful WorkInvitado: Mike Taylor, Arielle Shipper, Jack Cheng, Katie Parrott, Jannik Jung, Kieran Klaassen · Presenta: Natalia Quintero, Dan ShipperEvery’s team explains how it tests models, organizes experiments and brings useful tools back to the rest of the company.
 51:02ENEvery· 14 oct 2026Pódcast · 2 vocesMatt Hartman on Hugging Face, Technical Founders and Product InsightInvitado: Matt Hartman · Presenta: Natalia QuinteroThe Factorial Capital investor discusses pivots, founder networks and what building his own AI app taught him about software.
 33:46ENEvery· 7 oct 2026Pódcast · 2 vocesHow Every Moved From Personal Bots to a Shared Company AgentInvitado: Willie Williams · Presenta: Dan ShipperDan Shipper and Willie Williams discuss agent experiments, management feeds and the boundary between work and personal tools.
 33:10ENEvery· 30 sept 2026Pódcast · 2 vocesSam Altman on Agents, Live Documents and Building with AIInvitado: Sam Altman · Presenta: Dan ShipperA conversation about personal workflows, developer opportunities and fast interaction.