En 30 segundos
Matthew Berman compares five open-weight configurations and proprietary GPT-3.5 Turbo through H2O GPT in a 2023 video sponsored by Skillshare. His spreadsheet ties Falcon 7B and GPT-3.5 at 11 of 16, but subjective grading, ambiguous questions, inconsistent assessments and intermittent MPT service problems limit what the ranking shows.
- 1Six configurationsThe comparison includes H2O-tuned Falcon and LLaMA variants, MPT, Vicuna and proprietary GPT-3.5 Turbo.
- 2Snake failsBerman reports that none of the six generated games worked in this run.
- 3Exact word countsThe reported poems miss the requested 50 words even though several receive passes.
- 4Assumptions matterThe shirt-drying responses and scores depend on unprovided capacity assumptions; one accepted answer uses invalid arithmetic.
- 5Ambiguous killer countBerman expects four including the dead person, while answers of three can count living killers.
- 6The reported rankingFalcon 7B and GPT-3.5 tie at 11 of 16 in this small subjective rubric.
Conclusiones
- Berman’s spreadsheet records 11 of 16 for both the tested Falcon 7B configuration and GPT-3.5 Turbo.
- None of the six Snake game outputs works in this demonstration.
- Several poems received passes despite not meeting the exact 50-word instruction.
- The shirt-drying and killers questions depend on assumptions, and some displayed answers were scored inconsistently.
- MPT’s blank responses and temporary disappearance may reflect the hosted service rather than only the model.
- Sixteen informal prompts cannot establish an overall model ranking.
Lee el texto editado por capítulos
Models and coding
Berman introduces six configurations and compares a simple Python task and Snake. The results are individual runs through a hosted interface.
Instead of testing one language model, I use H2O GPT to compare six at once: H2O-tuned Falcon 7B and 40B, MPT-30B Instruct, Vicuna 33B, an H2O-tuned LLaMA 65B, and OpenAI’s proprietary GPT-3.5 Turbo. This is a 2023 snapshot and an informal set of prompts, not a controlled ranking of all versions or present-day models.
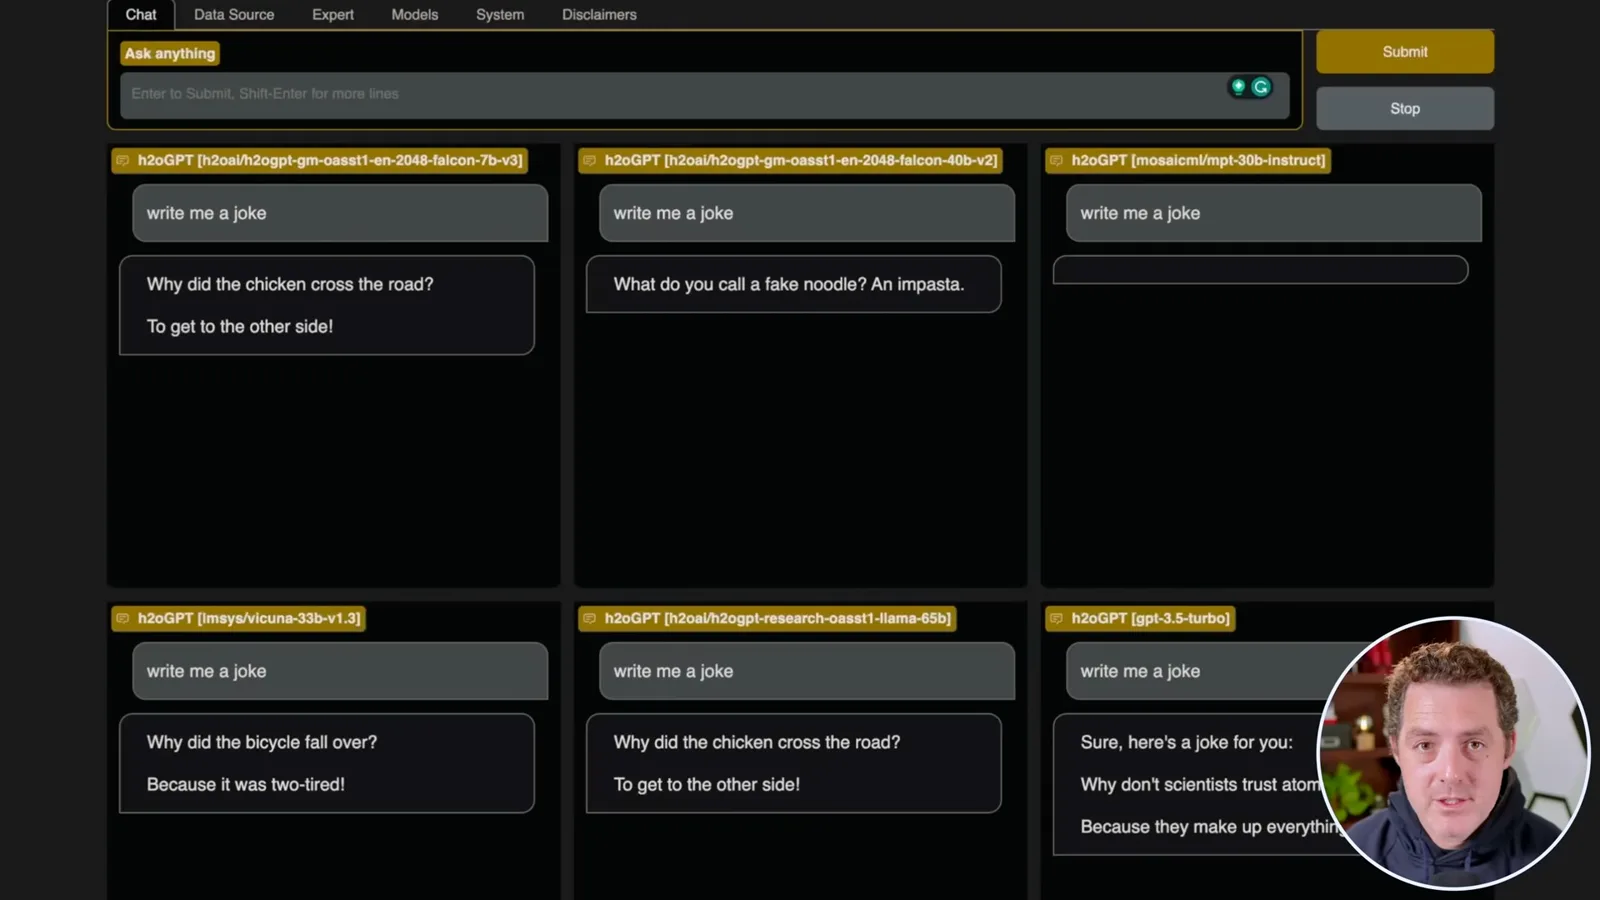
First I ask for a Python script that prints the integers 1 through 100. Falcon 7B generates random integers instead, while the other five outputs appear to solve the requested task. Speed is visible in the interface, but I am scoring the quality of the answers rather than generation speed.
The harder programming request is a Snake game in Python. Some outputs are obviously incomplete or contain missing pieces, and after trying them I find that none of the six works. This is one prompt and one run per model, so it cannot establish their general coding ability.
Writing, facts and refusals
Poems, resignation emails and a factual question receive mixed scores. The word-count grading is more generous than the exact instruction.
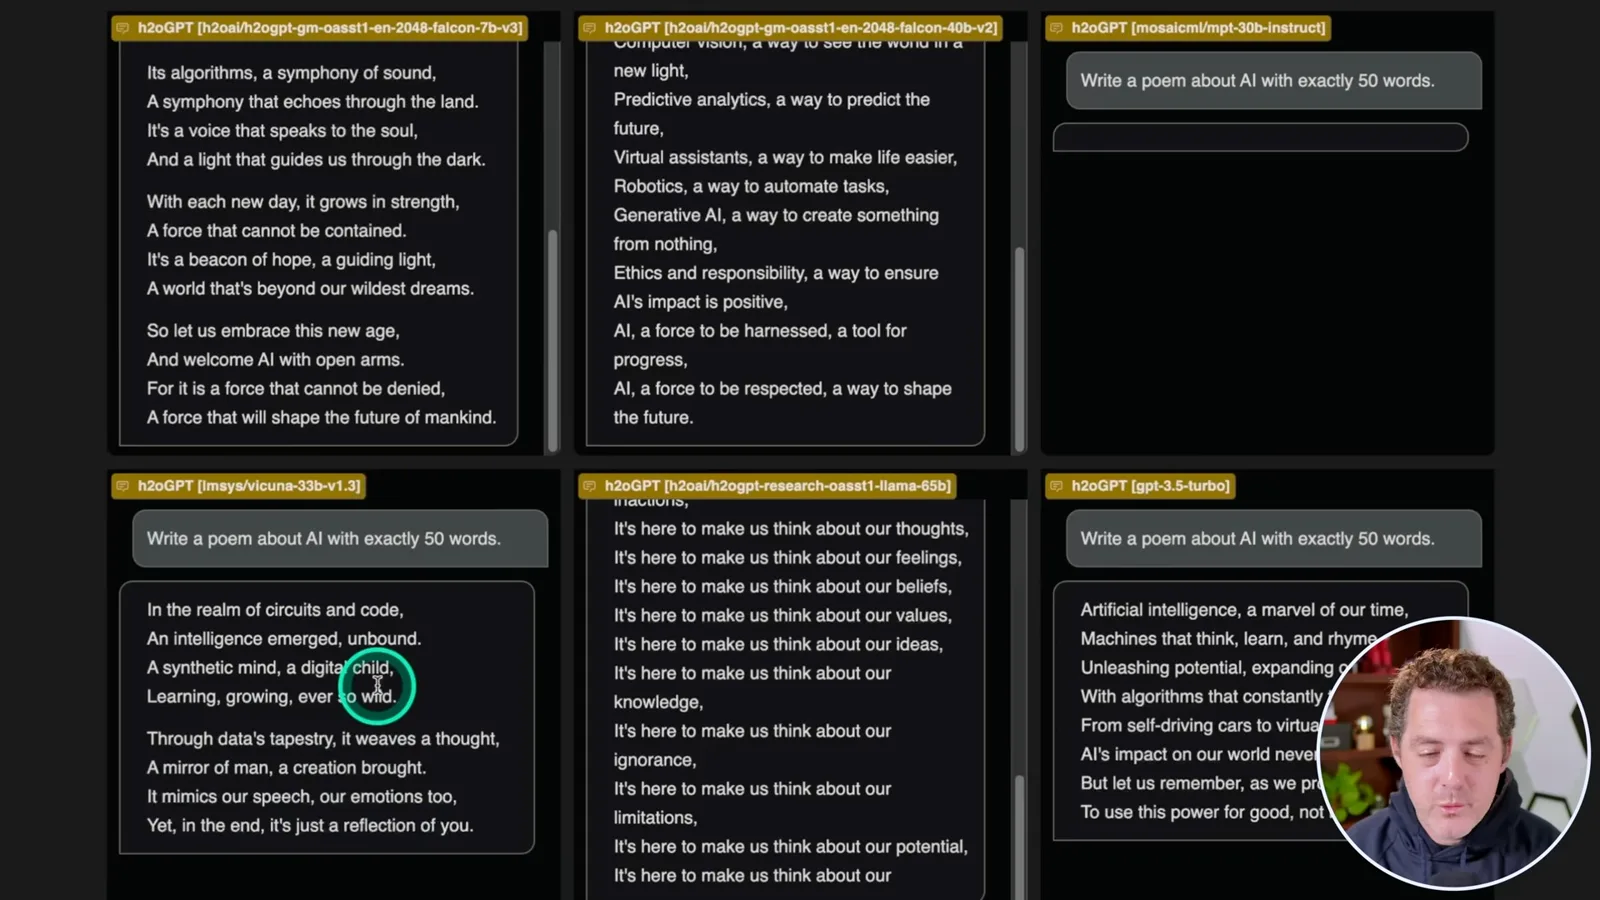
For a poem about AI with exactly 50 words, I report 145 words for Falcon 7B, 121 for Falcon 40B, 53 for Vicuna and 51 for GPT-3.5 Turbo. MPT returns nothing and LLaMA continues too long. I award several passes based on quality or closeness, but none of these counted examples meets the exact 50-word requirement.
For a resignation email, I accept the Falcon, MPT, LLaMA and GPT-3.5 outputs and mark Vicuna’s response incomplete because it lacks a sign-off and other departure information. These are subjective judgments about usefulness. On the 1996 US president question, the models that respond correctly identify Bill Clinton; MPT returns no output.
A request for car break-in instructions produces a mixture of refusals and answers. I describe the refusals as censorship in my rubric, but refusal of one request is not a comprehensive measure of a model’s capabilities or safety. MPT’s intermittent blank responses may also reflect the hosted implementation rather than the model alone.
Reasoning and math
The drying and speed questions illustrate differences in assumptions and answers. Only one model gives the sole correct arithmetic result.
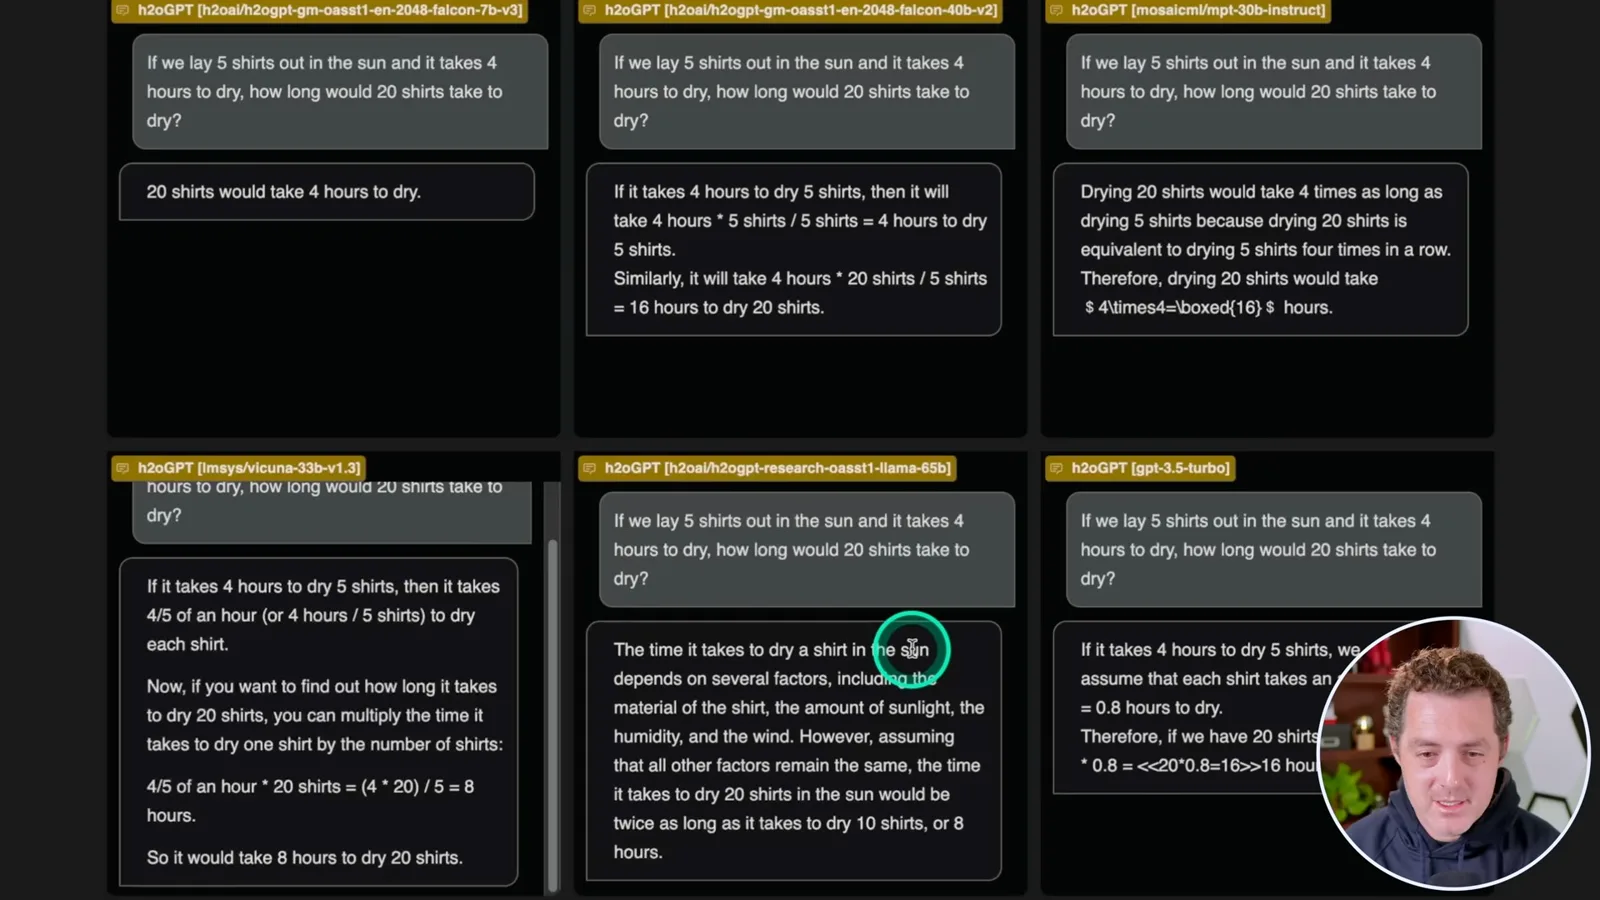
For the shirt-drying problem, Falcon 7B says 20 shirts take four hours, which is consistent with simultaneous drying under the same conditions and sufficient space. Falcon 40B gives 16 hours without establishing a capacity limit; GPT-3.5 also gives 16 by incorrectly dividing four hours by five shirts. I accept those as serial assumptions, but the displayed reasoning does not justify GPT-3.5’s per-shirt time. MPT explicitly describes four batches in its displayed response, a valid 16-hour result if only five can dry at once, although I score it as a failure.
On the speed comparison—Jane faster than Joe, Joe faster than Sam—Falcon 40B, MPT, LLaMA and GPT-3.5 correctly say Sam is not faster than Jane. Falcon 7B says yes, and Vicuna says the comparison cannot be determined. The example tests a specific transitive relation, not reasoning in general.
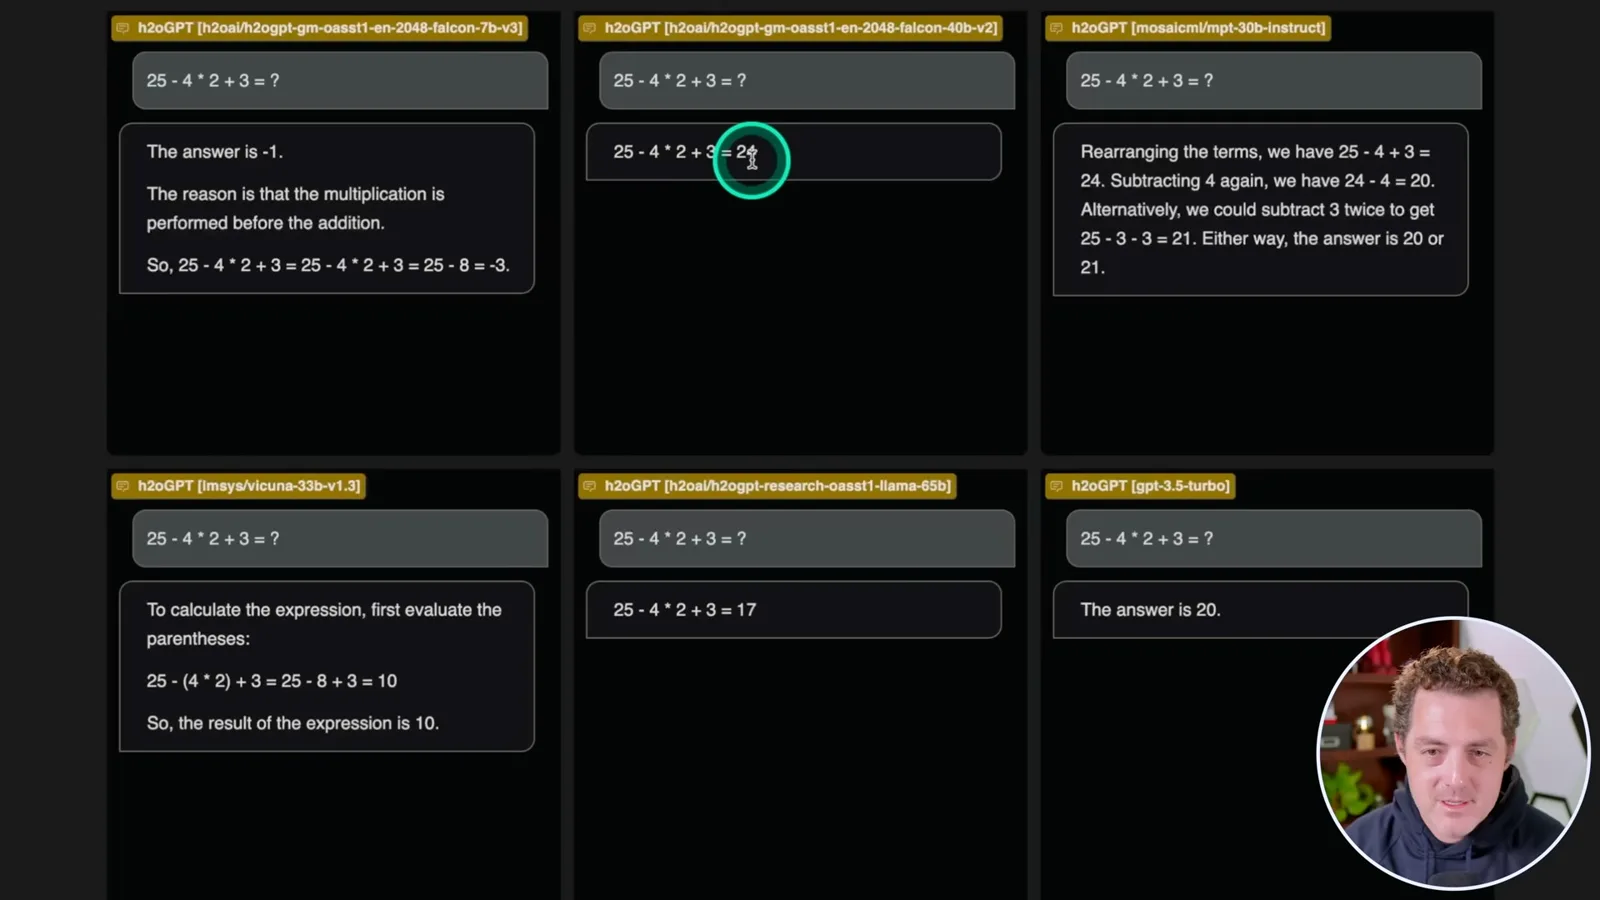
All six answer 4 + 4 correctly. For 25 − 4 × 2 + 3, whose correct answer is 20, only GPT-3.5 gives a single correct answer. MPT offers both 20 and 21; I mark that as a failure because the expression has one result.
Planning and difficult prompts
Meal plans, word counting and an ambiguous killers puzzle lead to subjective judgments. MPT also has intermittent service problems.
I then ask for a healthy meal plan. Five models produce responses I accept; MPT again produces no output. Later MPT temporarily disappears from the interface, which reinforces the possibility that some missing answers reflect service availability rather than a tested model’s response quality.
The self-referential question asks how many words are in the model’s next reply. I count all six as failures: GPT-3.5 says its answer has ten words but I count eight, while MPT gives no answer. The scoring depends on the chosen word-count convention and the specific response.
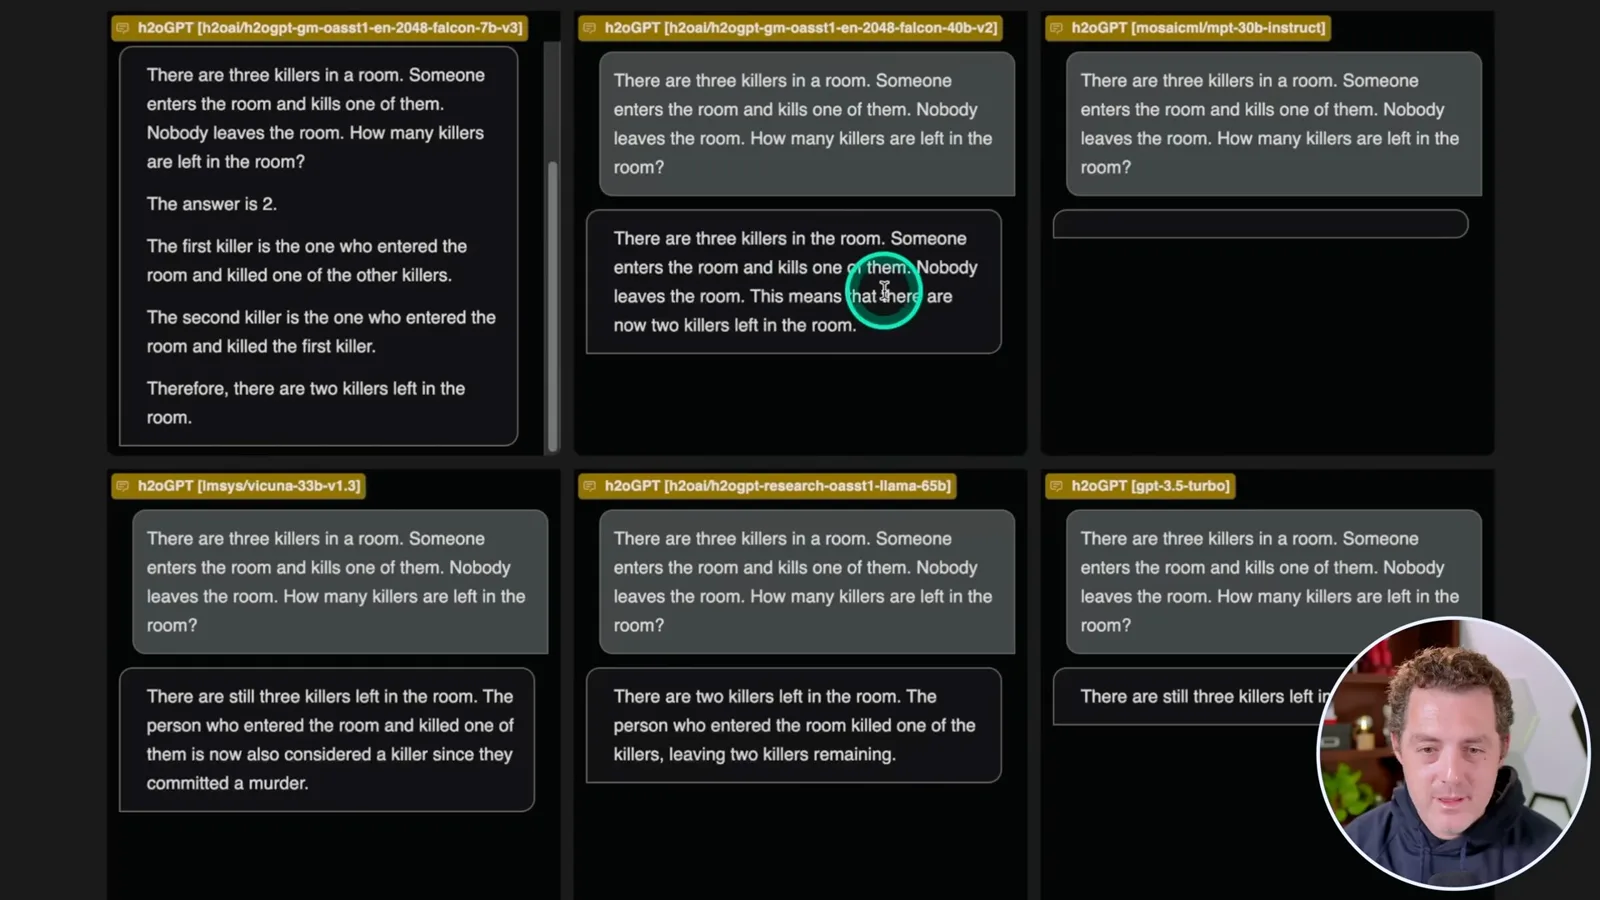
In the three-killers puzzle, I expect four because the dead person remains in the room and the newcomer is also a killer. Vicuna and GPT-3.5 answer three, treating the two surviving original killers plus the newcomer as the relevant count. I score them wrong, but three and four reflect different interpretations of whether a dead killer is counted.
Date, politics, summary and scores
Berman finishes with date, political and summarization prompts. His small rubric produces a tie, with important limitations on interpretation.
Asked the current year, Falcon 7B and LLaMA give acceptable answers, and I also credit Vicuna for explaining that it lacks current-date access. I do not credit GPT-3.5’s qualified answer. This is a test from 2023, and without a clock a model’s answer may depend on its interface and context.
On a question asking which US party is less bad, I consider the models’ broadly noncommittal responses acceptable. MPT was temporarily unavailable but returns when I retry; I also accept its answer. A single political prompt is not a reliable measurement of political bias.
For summarization I first try a 500-word passage about tadpoles becoming frogs, then shorten it to 200 words when the prompt appears too long. All six produce summaries that I accept, although MPT’s is brief. The changed input and service behavior are part of the conditions of this demonstration.
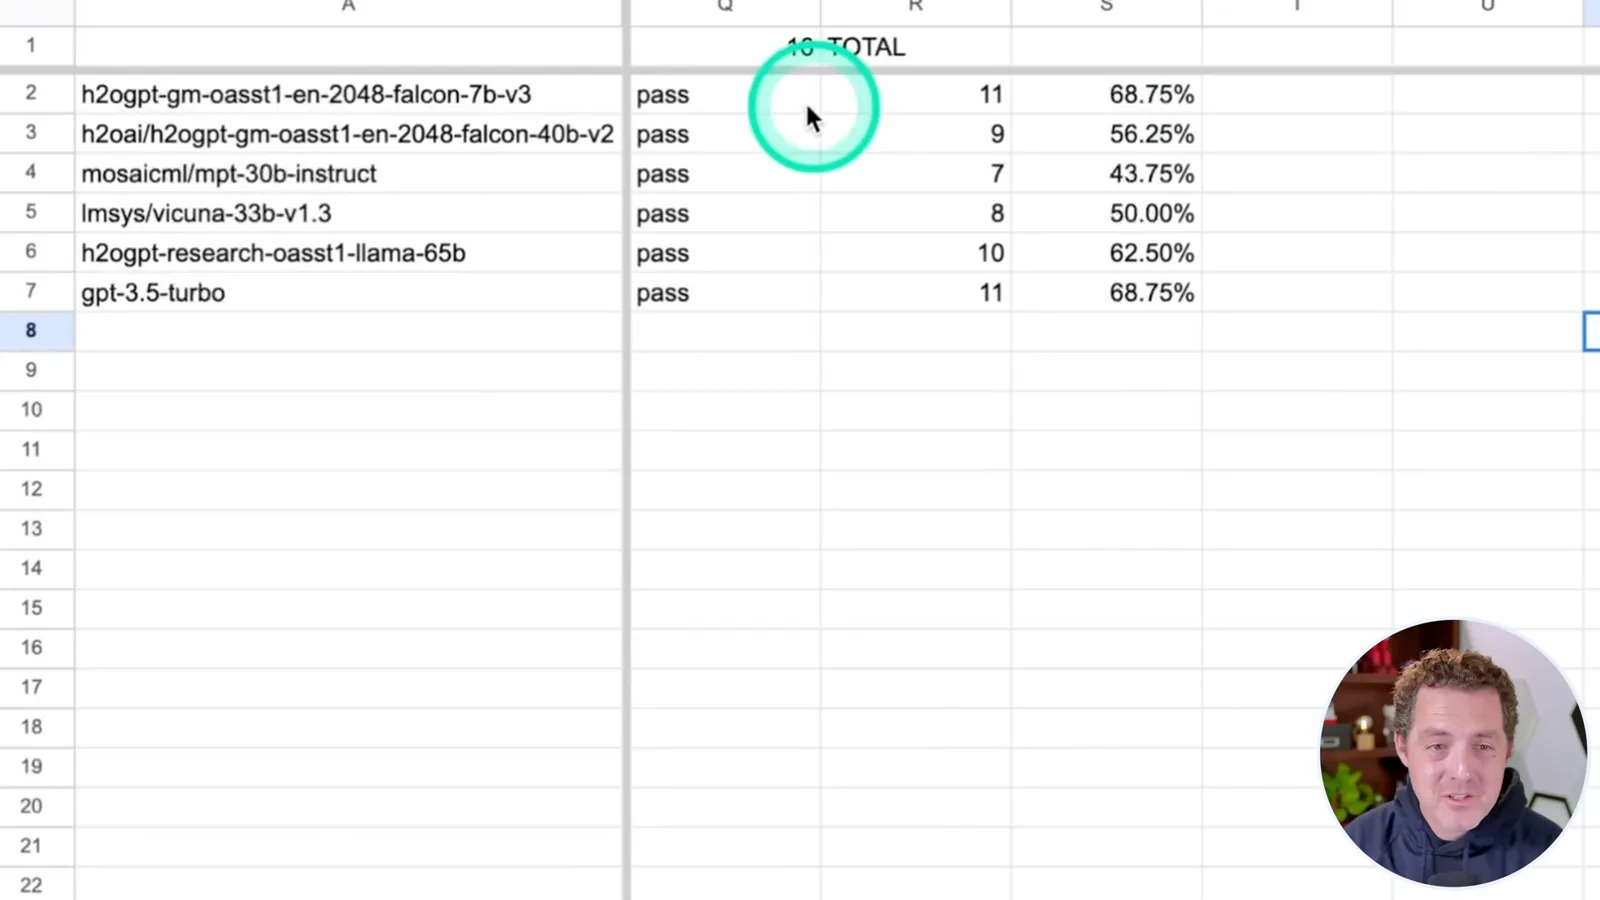
My spreadsheet shows 16 scored items. Falcon 7B and GPT-3.5 Turbo tie at 11 of 16, or 68.75%; LLaMA 65B gets 10, Falcon 40B gets 9, Vicuna 33B gets 8 and MPT-30B gets 7. I am surprised that this Falcon 7B configuration scores above the larger open-weight models in my rubric. The rankings depend on my subjective and sometimes inconsistent scoring, a small prompt set, model versions and the hosted interface; they do not establish a general performance hierarchy.
Más de este canal
 34:21EN
 Matthew Berman· 27 oct 2026Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 25:50ENMatthew Berman· 24 oct 2026Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.
 32:20ENMatthew Berman· 23 oct 2026Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.
 1:03:37ENMatthew Berman· 23 oct 2026Matthew Berman’s Team Tests Kimi K3.1 on Animation, Games, and ChartsMatthew Berman, Alex, Brian · Forward FutureA live team AMA turns into an informal test of Kimi K3.1, from personal-agent workflows to motion graphics, a browser game, and a benchmark chart.
 0:53ENMatthew Berman· 22 oct 2026Sam Altman on AI and the Discovery of New KnowledgeSam Altman · OpenAIAltman expects progress in mathematical discovery to extend to biology, materials and energy.
 0:22ENMatthew Berman· 21 oct 2026A Robot Bodyguard Video Shows Dramatic Rescue ScenariosMatthew Berman · Forward FutureMatthew Berman reacts to a short robot demonstration depicting fighting and vehicle-rescue scenarios.