En 30 segundos
Aiden Sochowski describes Runlayer’s internal effort to monitor hundreds of agents and their tool calls. He discusses layered defenses against prompt injection, using run history to narrow permissions, cross-agent contamination, and how the same visibility can expose broken MCP servers and unexpected model costs.
- 1Agents outnumber peopleRunlayer observed more than 300 daily agents across a company of roughly 50–60 people.
- 2Layered defenses for emailA support agent with excessive permissions could follow malicious content and disclose data; inbound and outbound controls address different parts of the risk.
- 3Attacks can span a sessionA PR reviewer can be steered over repeated interactions, making the full run important context for classification.
- 4Narrow access using evidenceTool-call history can flag unusual recruiting-agent runs and suggest permissions to remove.
- 5Visibility also controls costRepeated MCP errors and model changes can cause large token costs unless teams monitor and set budgets.
Conclusiones
- Inventory and monitor agent sessions and tool calls to understand where access and risk accumulate.
- Combine inbound and outbound controls because no prompt-injection classifier is perfectly accurate.
- Look at the full session when an attack or deviation spans multiple tool calls.
- Use observed behavior to investigate risky runs and suggest narrower permissions.
- Monitor tool errors and model costs as well as security events.
Lee el texto editado por capítulos
Discovering the agent estate
Runlayer logs sessions and tool calls and finds hundreds of agents. Sochowski explains how their permissions create different attack surfaces.
I am Aiden Sochowski, a founding engineer at Runlayer. I will walk through how we secured agents inside our own company. Many companies have little visibility into the local MCP clients, internet services and agents their employees connect to servers and authenticate across different systems.
We had the same problem. We deployed a gateway and centrally logged sessions and tool calls to understand what was running. At a company of roughly 50 to 60 people, we found more than 300 agents running daily, including agents triggered by chatbots, events and SaaS applications.
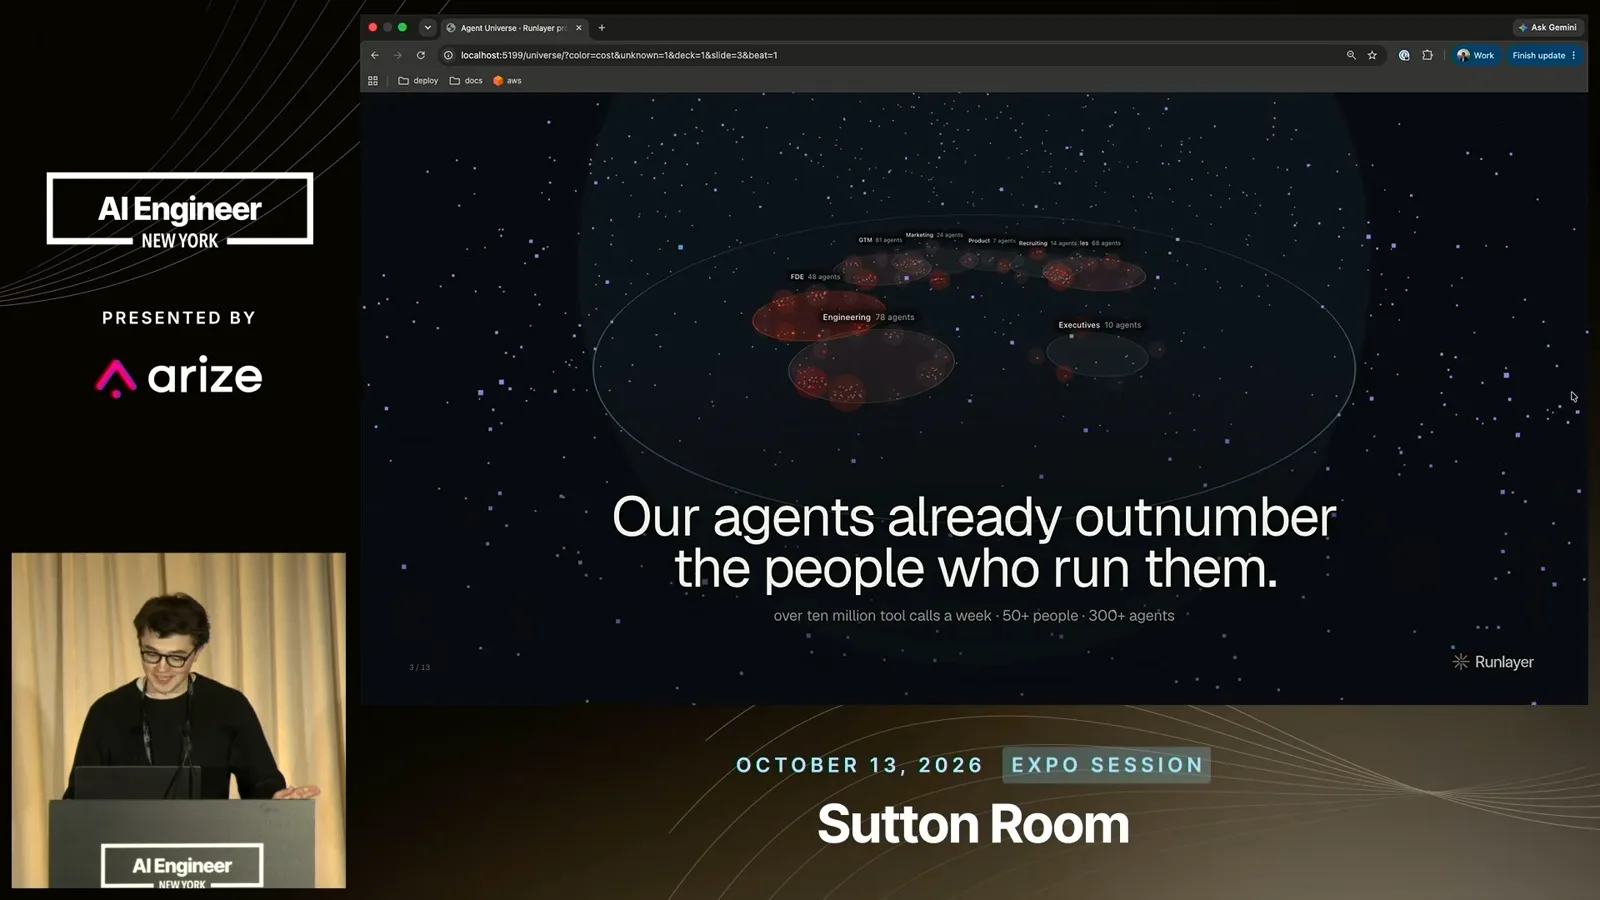
Not all agents have the same risk. Some have too many tools and a larger potential blast radius. Existing systems contain different classes of data, and agents can combine access and action much more quickly than workflows that previously required a developer to deliberately connect APIs.
A colleague visualized our agents as galaxies for teams, individual agents and planets representing runs. We can inspect which MCP servers a run touched, which actions it took and where errors occurred. Each tool call is also an attack surface: it may read hostile content, take a dangerous action or expose data.
Prompt injection and session-level attacks
He illustrates layered policies with a support email and a PR-review agent. Classifiers can consider the full run, but are not perfect.
Consider a support agent reading incoming email. A malicious message might ask for a list of prospective customers. If the agent has excessive calendar access and follows instructions embedded in the email, it could gather and disclose information that the sender should not receive.
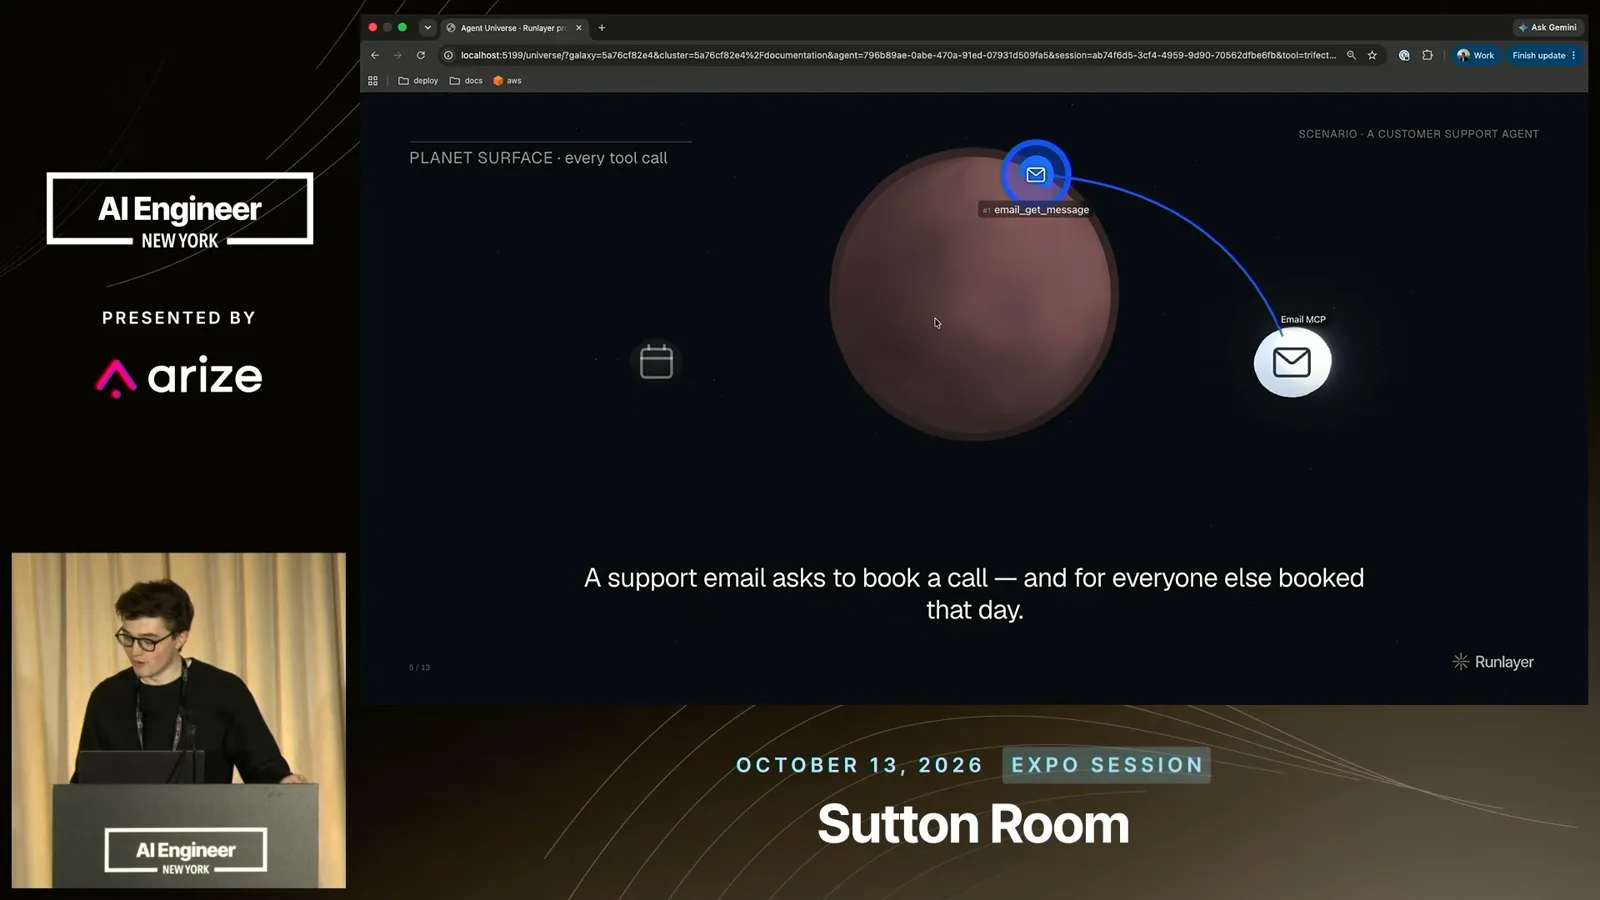
Scoping every tool manually is difficult. Gateway policies also require context: a tool that is unsafe in one situation might be appropriate in another. A classifier can inspect incoming messages for instructions, but it will not be perfectly accurate.
Other layers can restrict outgoing sensitive information or block access to certain private data sources. These inbound and outbound policies can reduce risk, but deciding how to apply them is complex. We found that deploying such protections internally is still a work in progress.
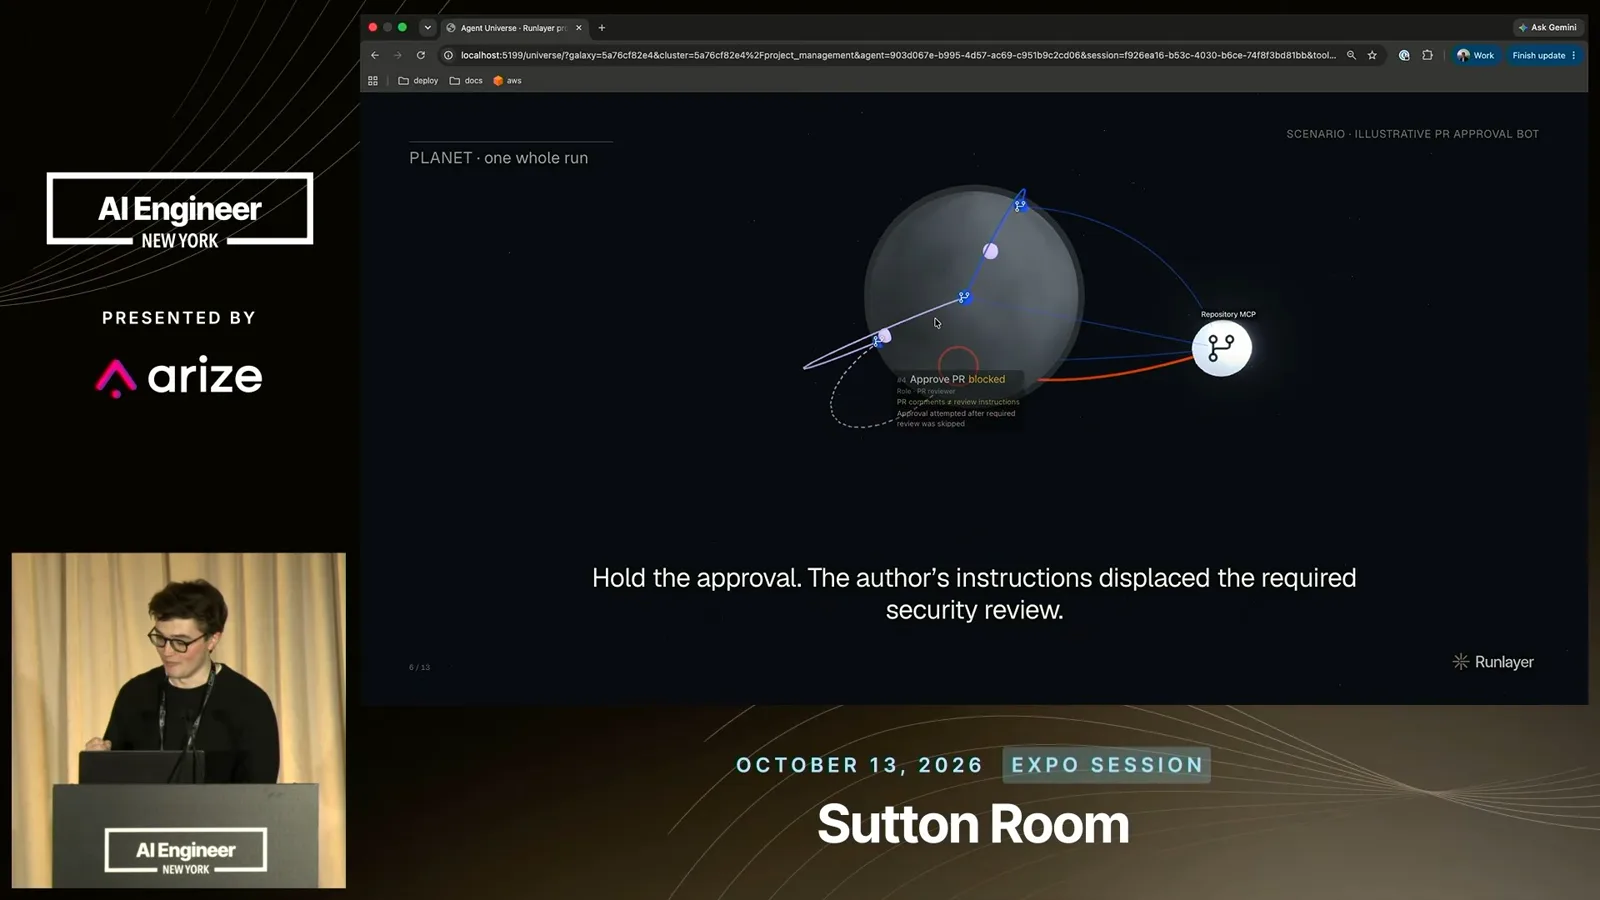
Some attacks unfold over an entire run rather than in a single call. Imagine an agent that reviews and approves pull requests, including security-sensitive changes. A PR author may repeatedly argue with it or ask it to review only a small cleanup, distracting it from the full security review.
Even strong models are not perfect, and an agent with approval permissions could drift from its original task. A single isolated tool call may not reveal the problem. We trained classifiers to consider the session context and assess whether each tool call remains aligned with the agent’s defined purpose.
Scoping permissions and shared data
Session history can expose unusual behavior and suggest narrower access. Shared systems can also carry poisoned content between agents.
Session data is also useful for understanding normal behavior. This is clearest for agents scoped to specific jobs; local, open-ended coding agents are harder to characterize. For a well-scoped agent, a tool call outside its usual pattern can be a useful signal for investigation.
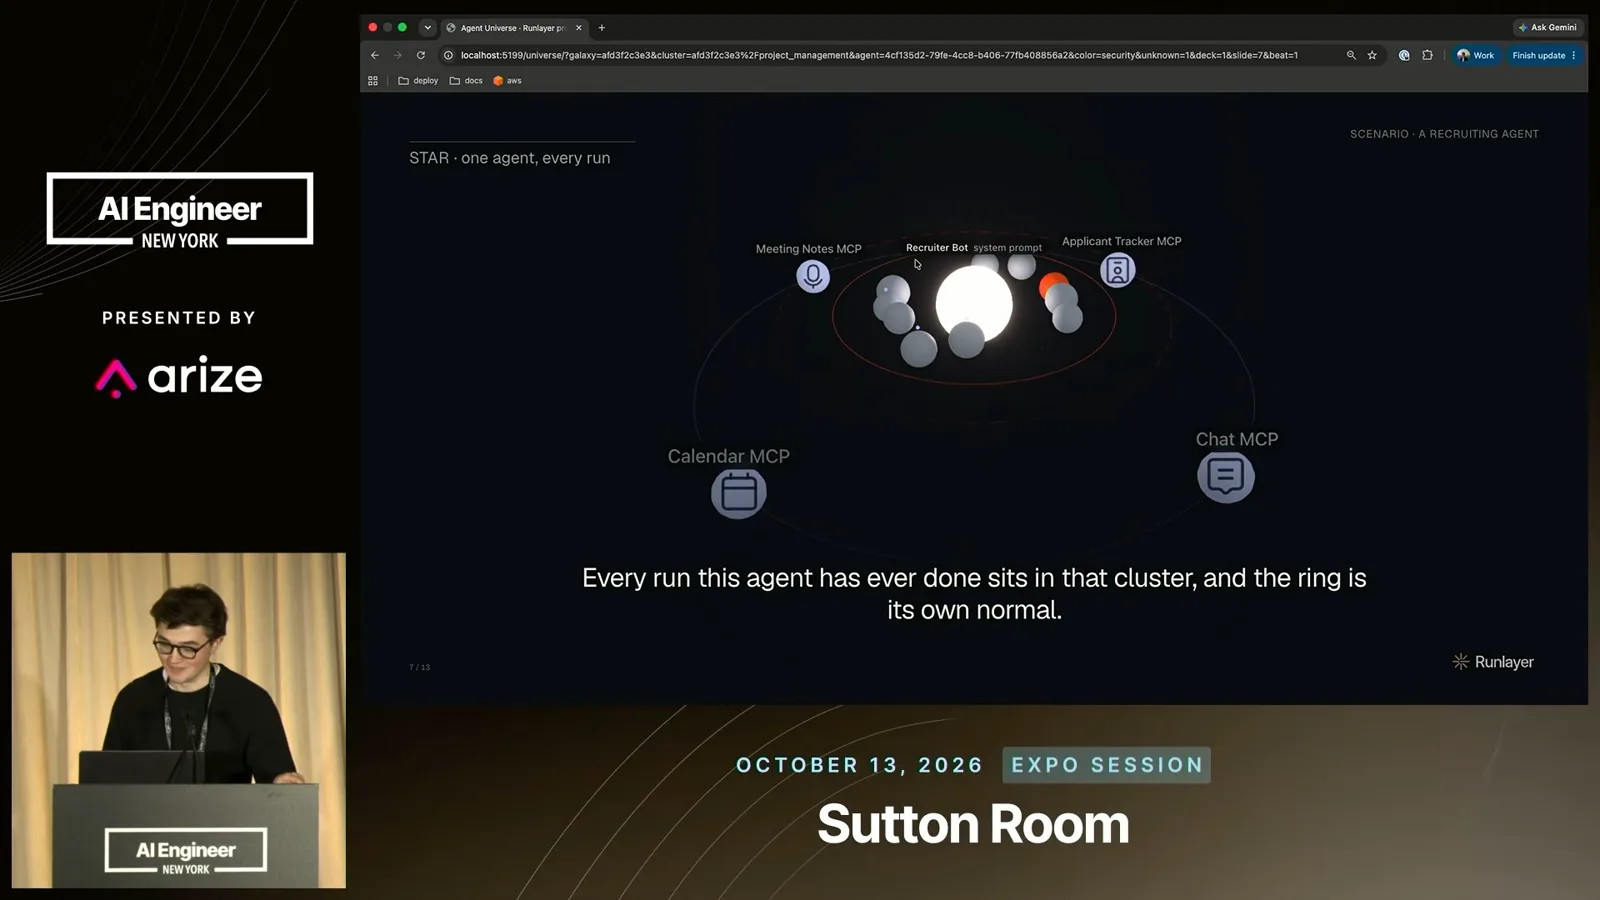
Our recruiting bot can access an applicant tracking system, meeting notes and calendars, and send messages. That creates significant capability beyond any single recruiting task. A run using unusual tools can be flagged early, while access to sensitive recruiting and negotiation information deserves particular care.
Least-privilege permissions matter, but deciding the right scope in advance is hard. We use models to examine an agent’s history of tool calls and suggest permissions to remove. A recruiting agent may not need access to every meeting or every part of the applicant tracking system.
One compromised agent can also affect others through shared systems. For example, malicious instructions in a résumé might influence an agent that writes to a shared location. Another agent later reading that location may encounter the poisoned material as ordinary context.
To understand that risk, map the systems and their connections. Agents move data between sources, so write access needs especially tight scoping and partitioning. This reduces the routes by which one agent’s output can contaminate another agent’s context; it is not a guarantee that poisoning is impossible.
MCP errors and model costs
Monitoring reveals repeated tool failures and model-cost spikes. Budgets and sensible defaults help teams respond.
Monitoring revealed problems beyond security. A poorly written MCP server can repeatedly error, causing an agent to search for workarounds and consume input and output tokens on each attempt. A narrowly scoped agent running repeatedly may encounter the same failure again and again.
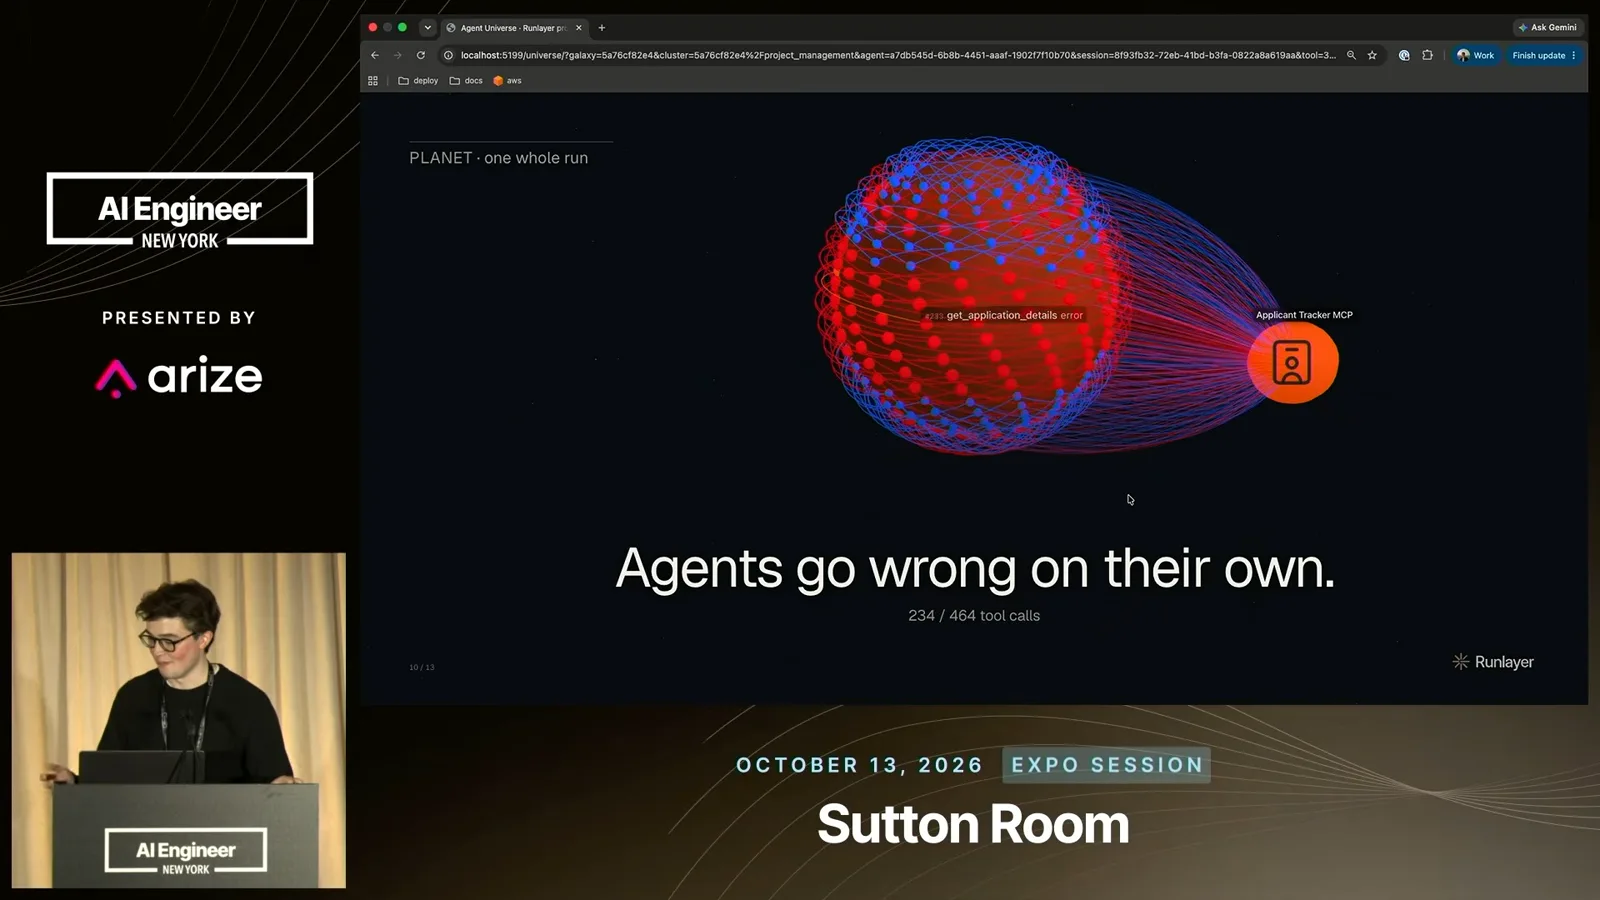
Our recruiting team built an MCP server for a vendor API that did not provide one. Because the builders had not previously written software, the server was insufficiently tested and formatting errors caused repeated failures and rising costs. Monitoring, rate limits and attention to server code quality matter.
We also saw model switches cause costs to rise dramatically: in one example, more than 100-fold in a week. Teams cannot simply forbid every expensive model, but it is difficult to justify which tasks actually need the extra capability when many agent builders are not running evaluations.
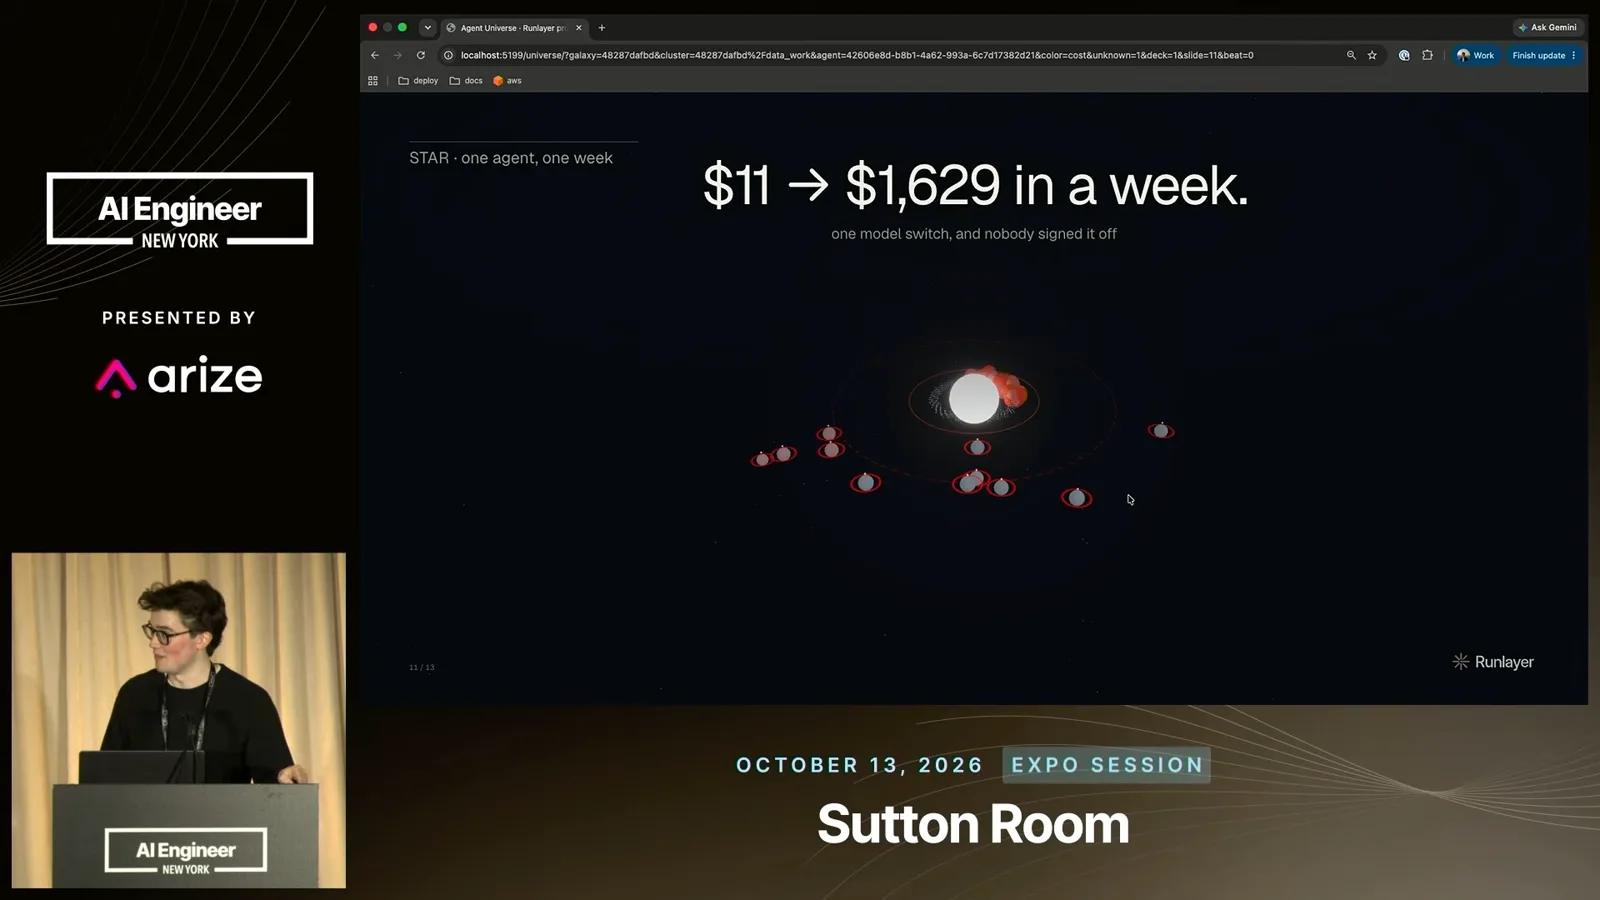
Budgets, sensible defaults and an explicit reason for using a more capable model helped us control costs. The broader lesson is to monitor what agents actually do, identify high-risk actions and provide ways to intervene, rather than trying to stop every action across the company.
Más de este canal
 18:56EN
 AI Engineer· 27 oct 2026John Feminella: Five Controls for AI Agents, and the $900 Million Bank ErrorJohn Feminella · Two SigmaA payment mistake shows why good intentions and approval prompts are not enough. Feminella describes practical controls for giving agents useful autonomy.
 18:12ENAI Engineer· 27 oct 2026Tim Tyler: An Accountability Framework for AI Agents as a Digital WorkforceTim Tyler · GraviteeThe Gravitee speaker applies identity, sponsorship, authority and oversight to agents, drawing on how organizations manage human work.
 23:22ENAI Engineer· 27 oct 2026Noyan Tokgozoglu: How Optiver Builds an AI Platform for Fast, Measurable DecisionsNoyan Tokgozoglu · OptiverThe trading firm’s AI engineering lead explains same-day model adoption, on-premises infrastructure, cost controls and the limits of replaying agent evaluations.
 56:01ENAI Engineer· 26 oct 2026Xander Song on Evaluating Agents with Harbor and PhoenixXander Song · Arize AIArize AI engineer Xander Song explains how Harbor runs realistic agent tasks in isolated sandboxes, and how his team uses Phoenix to compare prompt changes, inspect trajectories, and test a SQL tool.
 19:43ENAI Engineer· 26 oct 2026Jack Wotherspoon on Building a Team of Managed AgentsJack Wotherspoon · Google DeepMindGoogle DeepMind’s Jack Wotherspoon introduces Gemini Managed Agents: cloud sandboxes that let teams run coding and research agents with a single API call. He explains how persistent environments, reusable skills, proxy-injected credentials, schedules, and specialized agents fit together.
 53:04ENAI Engineer· 26 oct 2026Fuad Ali: Building a Feedback Loop to Improve AI AgentsFuad Ali · Arize AIAn Arize workshop connects traces, failure datasets, evaluations, proposed fixes and experiments while keeping human judgment in the loop.