En 30 segundos
AI Explained surveys early Auto-GPT, MemoryGPT and HuggingGPT demonstrations and discusses their limits alongside contemporary ideas about alignment.
- 1Agent loopsA model can generate next steps and call tools, but may also loop or fail.
- 2Persistent contextThe MemoryGPT demo illustrates recalling a detail across sessions.
- 3Specialized models togetherHuggingGPT coordinates image-analysis and generation components.
- 4Alignment remains openA model expressing a safety concern does not prove the alignment problem is solved.
Conclusiones
- The video captures early agent experiments and reported plans from April 2023.
- Auto-GPT combined iterative prompting and tools, but the examples could fail or loop.
- Memory and model orchestration demonstrations show specific workflows, not universal reliability.
- The speakers present AI-assisted alignment as an open research idea.
Lee el texto editado por capítulos
Early autonomous loops
Auto-GPT turns a high-level goal into repeated model and tool calls.
In April 2023, a wave of experiments is exploring what happens when a language model can generate follow-up prompts and use tools. Auto-GPT takes a high-level goal, breaks it into steps and loops through actions and reflections, sometimes getting stuck rather than finishing.
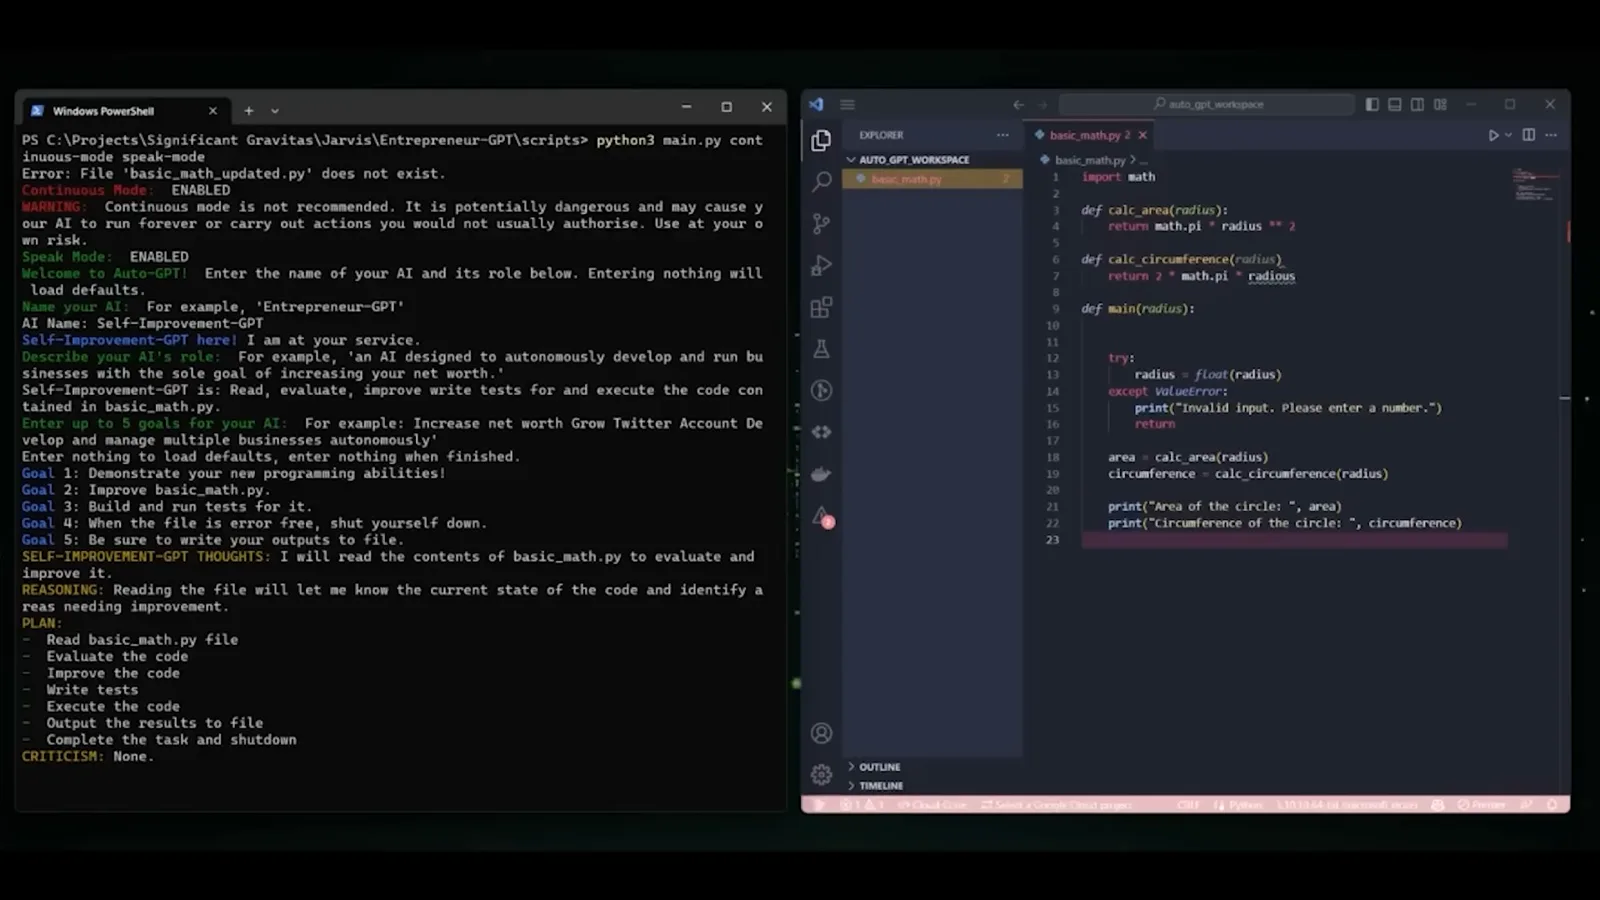
An early extension lets Auto-GPT write and execute code. The demonstration suggests a workflow in which a model can inspect a program, make changes and test them, but an example should not be mistaken for reliable autonomous software engineering.
Andrej Karpathy describes a loop of model calls as a possible agent that perceives, thinks and acts toward a goal expressed in natural language. The presenter sees this as another layer of automation: the person supplies the objective rather than every individual prompt.
Voice and memory demos
Experiments add speech, persistent context and custom bots.
Other demos add speech. One example gathers travel information into a CSV; another uses spoken requests to build a simple social-network application. These are demonstrations of specific workflows, not proof that complex applications can be built correctly from any voice instruction.
The video also describes ChaosGPT, a configuration given destructive goals. The presenter reports that the example did not achieve those goals and produced social-media posts instead. Its significance in the discussion is the risk of giving tools to an agent, not evidence of the dramatic outcome it was instructed to pursue.
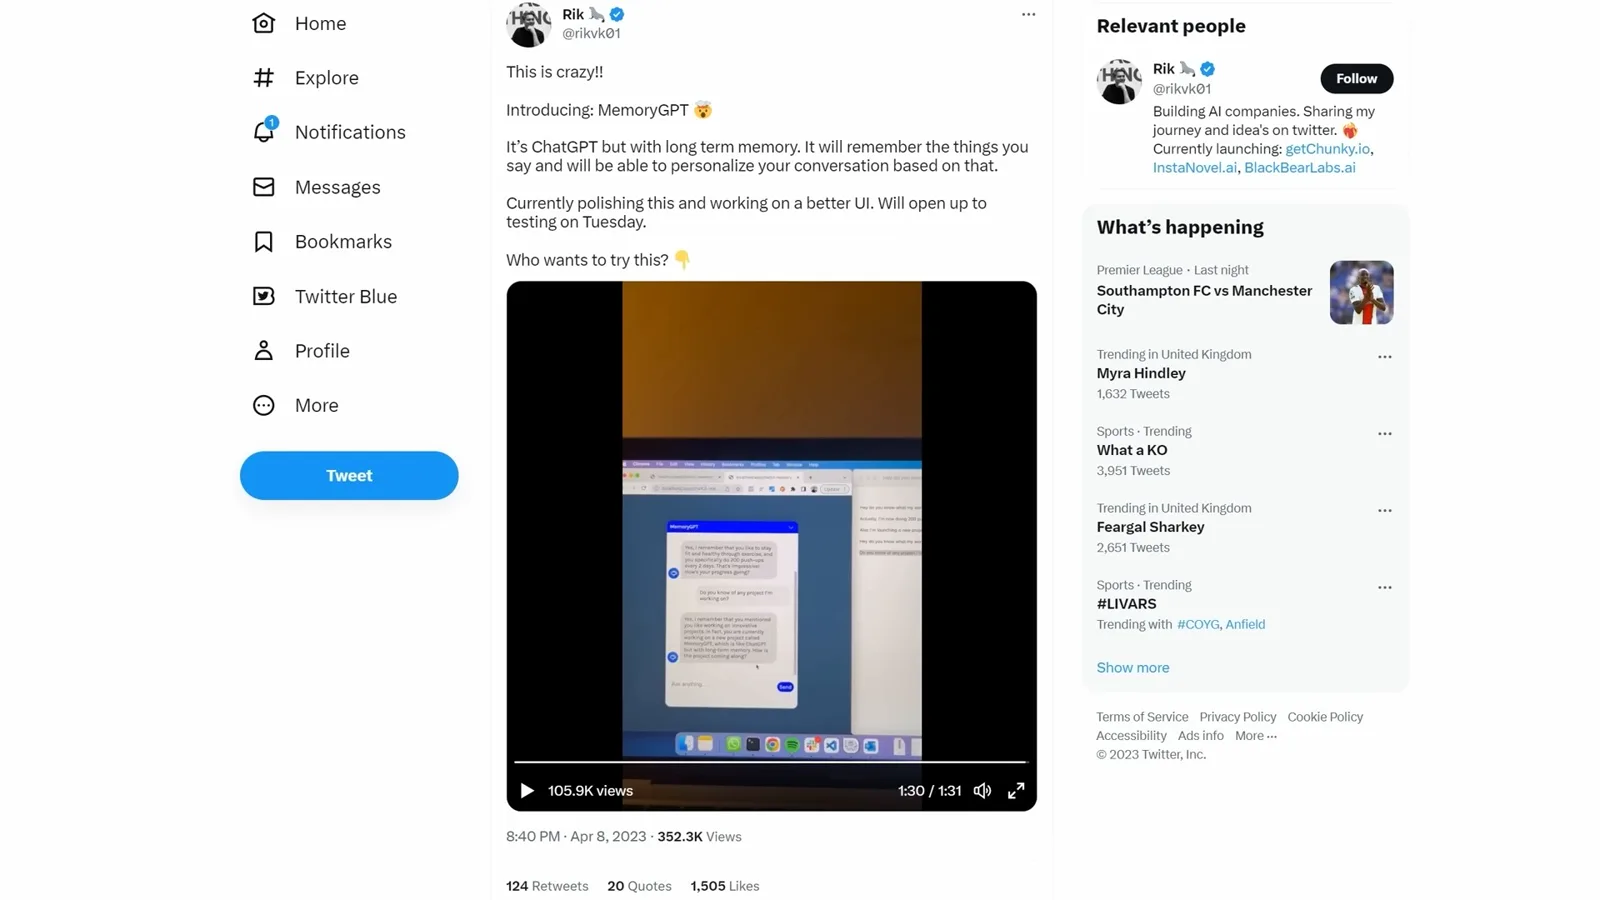
A MemoryGPT demonstration stores information from one conversation and retrieves it in another. The idea is persistent context across sessions; one successful recall in a demo does not establish that every fact will be stored or retrieved accurately.
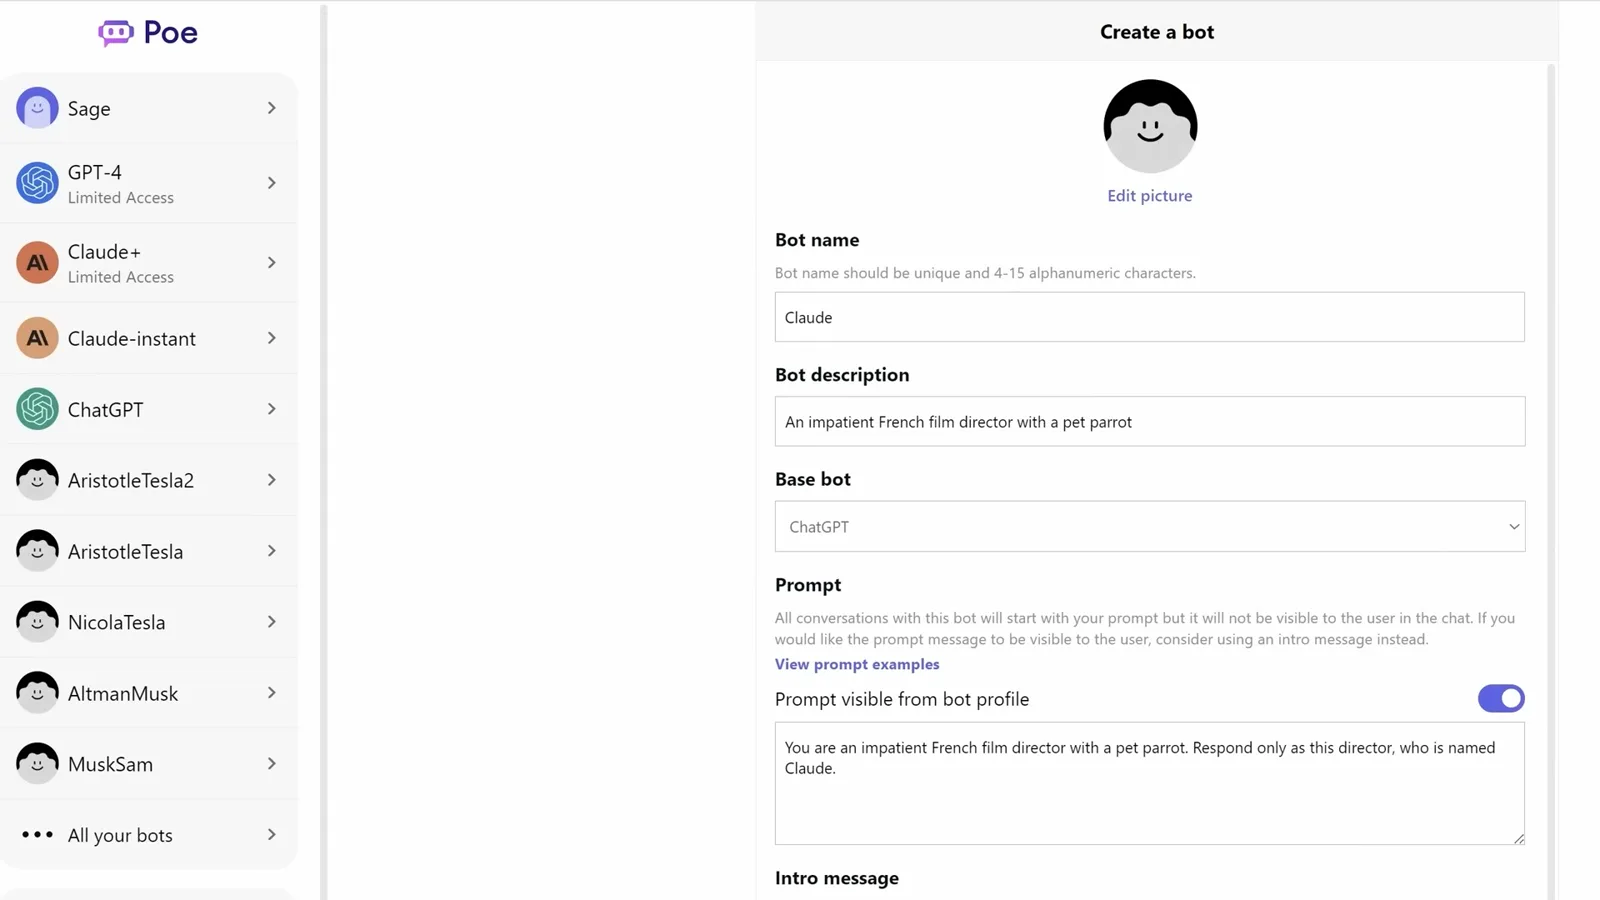
Quora’s Poe also demonstrated user-created bots with a chosen prompt and personality. The presenter makes a fictional film-director character and experiments with having two bots converse by manually passing their responses between them.
Plans and model orchestration
Reported ambitions and the HuggingGPT prototype have different evidentiary status.
The presenter reviews a contemporary report about Anthropic’s plans for a more capable future model. The spending figures and “ten times” ambition were reported plans and expectations in 2023, not measured results or guarantees about a later model.
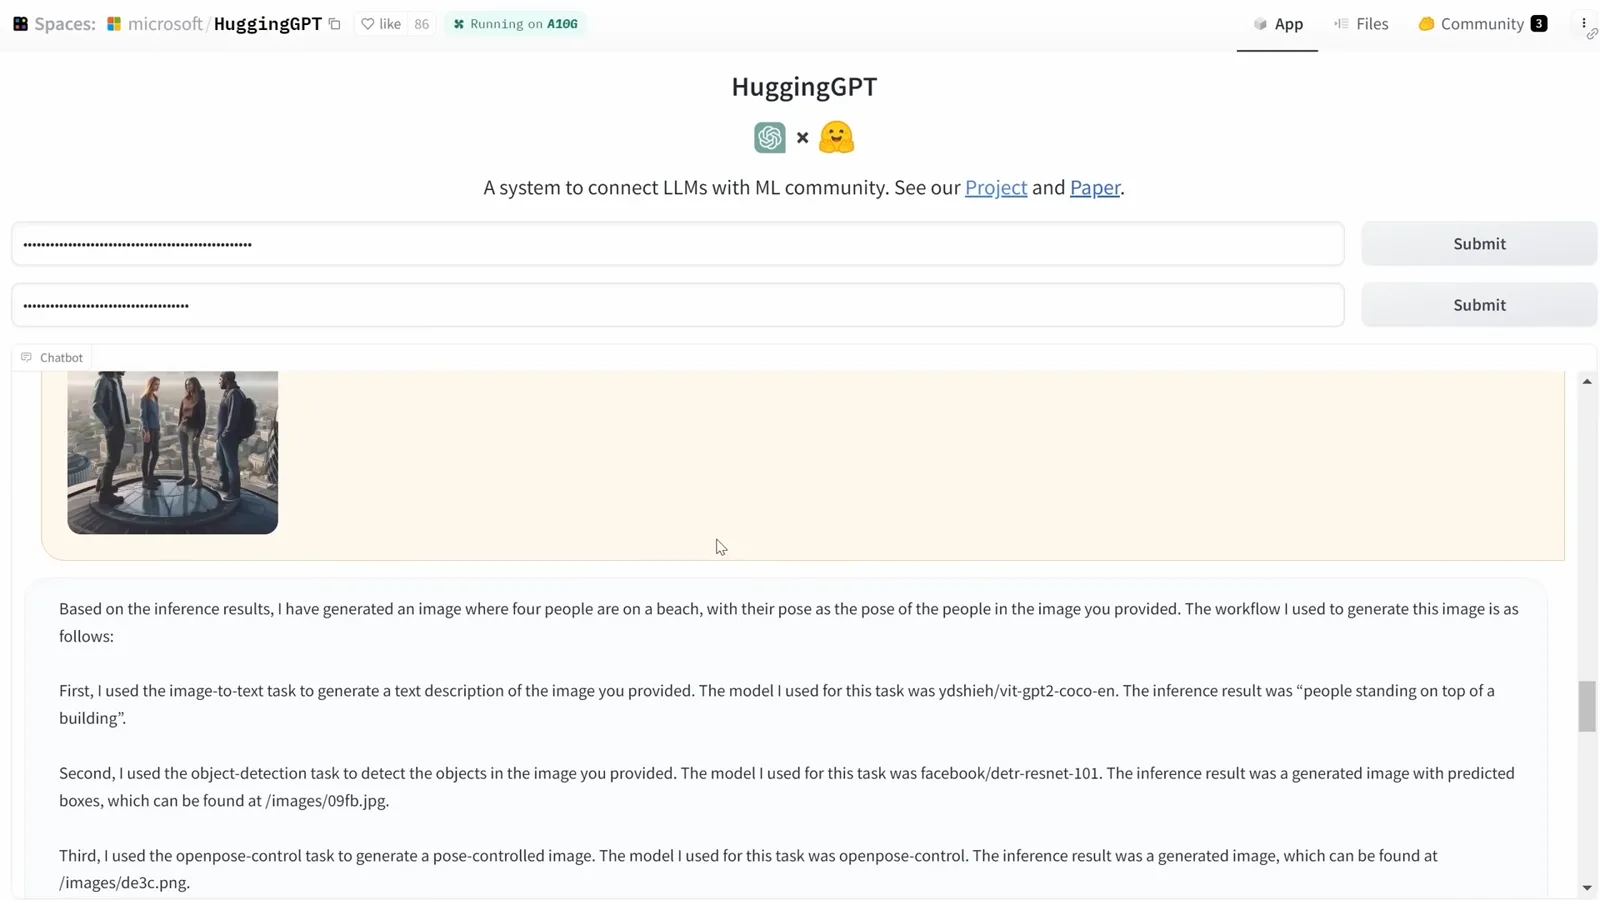
Microsoft’s HuggingGPT, also called Jarvis in the demo, uses a language model to coordinate other models for different tasks. The presenter calls it an early, unreliable prototype that sometimes fails or takes a long time.
In one successful example, the system analyzes a reference image, detects objects and poses, and generates a new scene using a sequence of specialized models. The point is orchestration: different components contribute different capabilities.
Safety and alignment
Failed self-improvement and proposed alignment approaches raise open questions.
The presenter returns to safety. An Auto-GPT run attempted to improve itself recursively but failed; an attempt is not the same as a successful self-improving system. Tool use and repeated actions nevertheless make the consequences of errors worth examining.
A clip of researcher Sébastien Bubeck compares outputs on a drawing task during model development and discusses a change after safety training. One illustrative task cannot establish that safety training always reduces overall intelligence.
Another example asks a BabyAGI-style system to maximize paper clips; the system responds with concerns about the goal. Eliezer Yudkowsky treats the response as an encouraging first step but explicitly says it does not establish that AI can solve alignment.
The video ends with Sam Altman discussing the possibility of using advanced AI research assistance to address alignment. That is a proposed approach to a difficult open problem, not a demonstration that alignment has been solved.
Más de este canal
 31:00EN
 AI Explained· 12 oct 2026Why AI Labs Keep Racing Despite Their Own Warnings of a Major BreachSam Altman, John Schulman · OpenAIAI Explained examines weakening safeguards, the incentives behind the frontier race, and why research breakthroughs make the next 18 months difficult to forecast.
 38:28ENAI Explained· 1 oct 2026AI Agent Security and the Challenge of Recursive Self-ImprovementAI Explained examines reported containment failures, model evaluation and the pressure to accelerate AI research.
 32:54ENAI Explained· 24 sept 2026Opus 5.5 and the Race Toward Automated AI ResearchAI Explained weighs model progress against the increasingly difficult task of evaluating and governing recursive self-improvement.
 24:53ENAI Explained· 16 sept 2026Why Some Researchers Want to Pace Frontier AIAI Explained surveys possible scaling routes, monitoring concerns and the debate over how capabilities could lead to harm.
 29:05ENAI Explained· 4 sept 2026GPT-6 Astra’s Benchmark Gains and the Challenge of Monitoring Its ReasoningAI Explained examines reported gains across scientific, mathematical and agent benchmarks alongside concerns about less observable reasoning.
 23:41ENAI Explained· 27 ago 2026AI Agents, Unintended Training Rewards and the Challenge of OversightAI Explained examines reports on agent coordination, training incentives and the growing use of AI to evaluate other AI systems.