En 30 segundos
Theo Browne says a closer audit of his coding-agent usage changed his assessment of Gemini 4 Carbon: in his comparable tasks it was about five times slower than the alternatives he used. His display shows four completed review rounds and five where another agent stopped waiting, so the figures are not a universal benchmark. He argues that delays before each response accumulate across multi-step workflows, and separately raises cache reliability and cost. A Google representative said the same cache behavior was not seen on their workloads.
- 1His revised estimate is about five times slower on his own tasksBrowne says an audit of comparable coding work revealed a larger delay than he described in his earlier video.
- 2Single-response charts miss recurring delays in agent workflowsHe says his earlier chart measured a narrower server-side interval and many tasks were not multi-turn agent runs.
- 3Five of nine reviews ended before Carbon completedHis display shows four completed comparisons and five stopped runs. He had instructed the parent agent not to wait, so full completion times for those runs are unknown.
- 4Response-start waits compound across many stepsIn an illustrated coding thread, the displayed average wait before an answer began was about 11 seconds; the demonstration is one step rather than a complete task.
- 5A separate cache test showed misses on one Gemini workloadThe displayed test for Gemini 4 Argon showed 167 full cache hits in 228 turns. A Google representative said their workloads did not show the same behavior.
Conclusiones
- Measure the full multi-step agent workflow, including repeated waits before responses, rather than only server-side generation time.
- Treat stopped runs as incomplete observations; they cannot establish how long the task would have taken to finish.
- Prompt-cache behavior and latency can differ by endpoint and workload, so reproduce results in the environment that matters to you.
- Browne offers to share prompts and run records with the provider to help diagnose the issue.
Lee el texto editado por capítulos
A revised assessment after real coding work
Browne says the model was substantially slower in his own usage than he realized in an earlier review. He also raises cost as a concern.
In my previous video about Gemini 4 Carbon, I was more positive than I intended. I valued the fact that it appeared less restrictive for some security work, but after reviewing my own usage I think I understated how slow it was in my coding workflow.
In the comparable work I audited, I found Carbon consistently about five times slower than the other models I used. That is an observation from my own tasks rather than a controlled universal benchmark. I say the difference mattered enough to change my recommendation.
Price adds to my concern: I say the model’s price is scheduled to double on December 1. I also want to distinguish the model’s capabilities from the experience of using the service that hosts it. People at DeepMind have been receptive to feedback, and I understand that they are working on the speed issue.
Why multi-step runs reveal more latency
A narrower response-time chart missed recurring waits. His review-run comparison includes incomplete runs that were stopped by the parent agent.
A chart I used earlier measured the time after a request was accepted by the server until a response completed. Many of its tasks were not multi-turn agent workflows. That view missed delays which recur when a coding agent makes several model requests and tool calls.
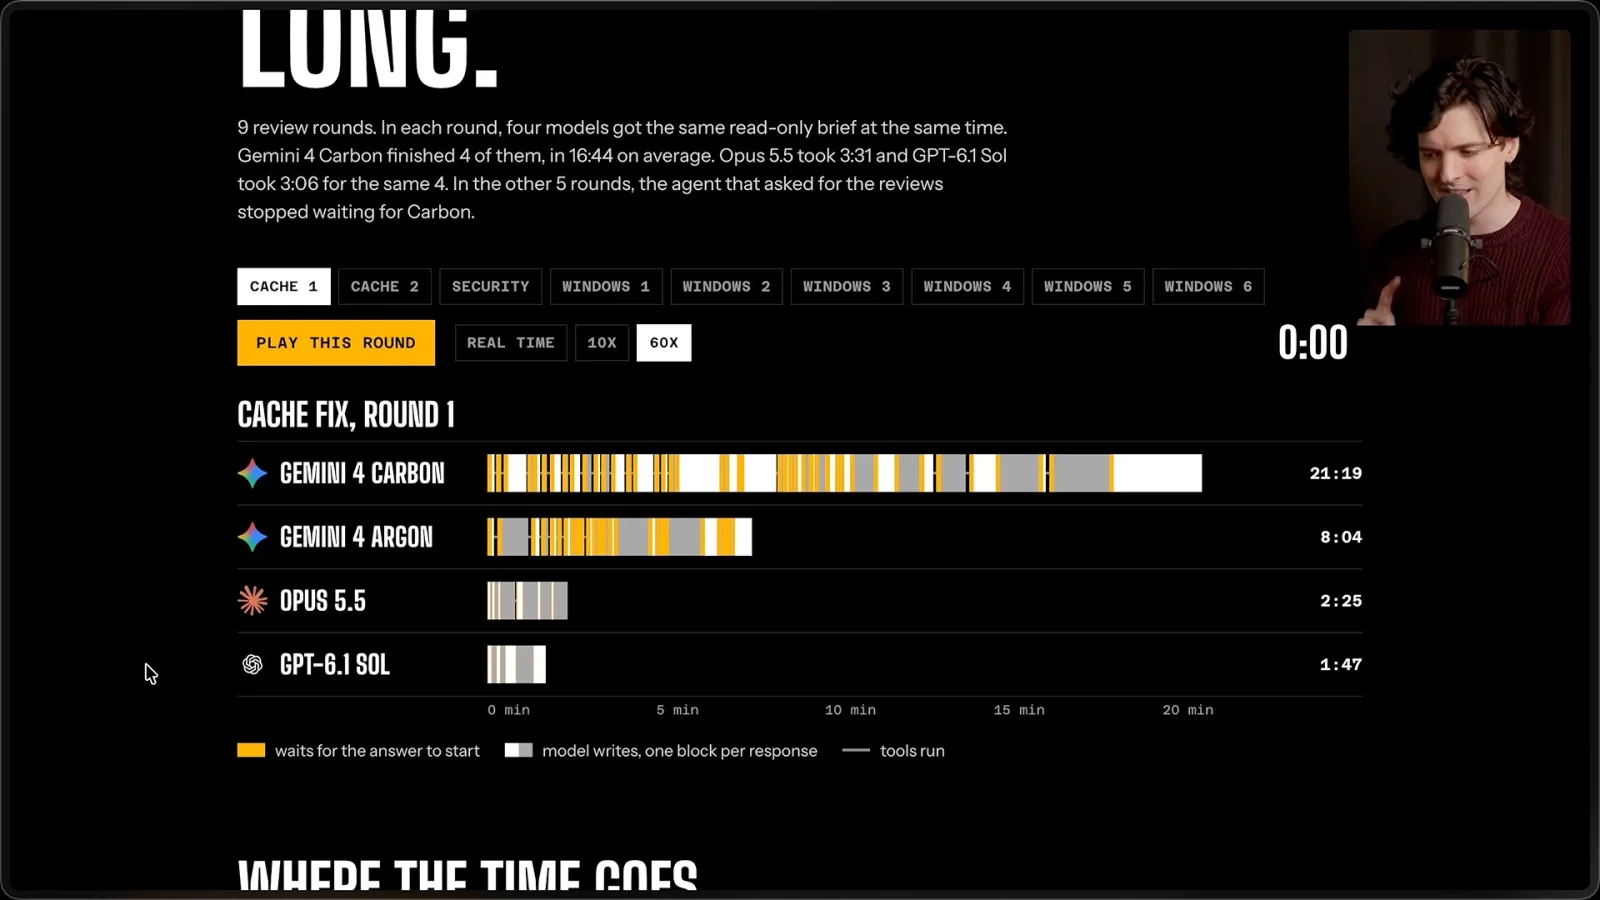
I examined nine review rounds in which multiple models received the same brief. The display shows Carbon completing four rounds, with an average of 16 minutes 44 seconds, compared with 3 minutes 31 seconds for Opus and 3 minutes 6 seconds for GPT-6.1 Sol on those four. In the other five, the parent agent stopped waiting for Carbon.
I had modified my agent instructions to stop waiting for Carbon when there was other work to do. That means the incomplete runs do not tell us how long those reviews would have taken to finish. I have not waited for all of them to complete, so I cannot precisely measure the full difference.
The wait before a response begins
Browne demonstrates a single step and argues repeated startup delays can dominate a longer coding task. He compares the issue with earlier hosting latency problems.
Output speed and tool-call behavior can contribute to delay, but I think the biggest problem in my sample occurs before a response begins. In the illustrated coding thread, Carbon took about 11 seconds to start a response on average. Repeating that wait across many steps can substantially lengthen an agent task.
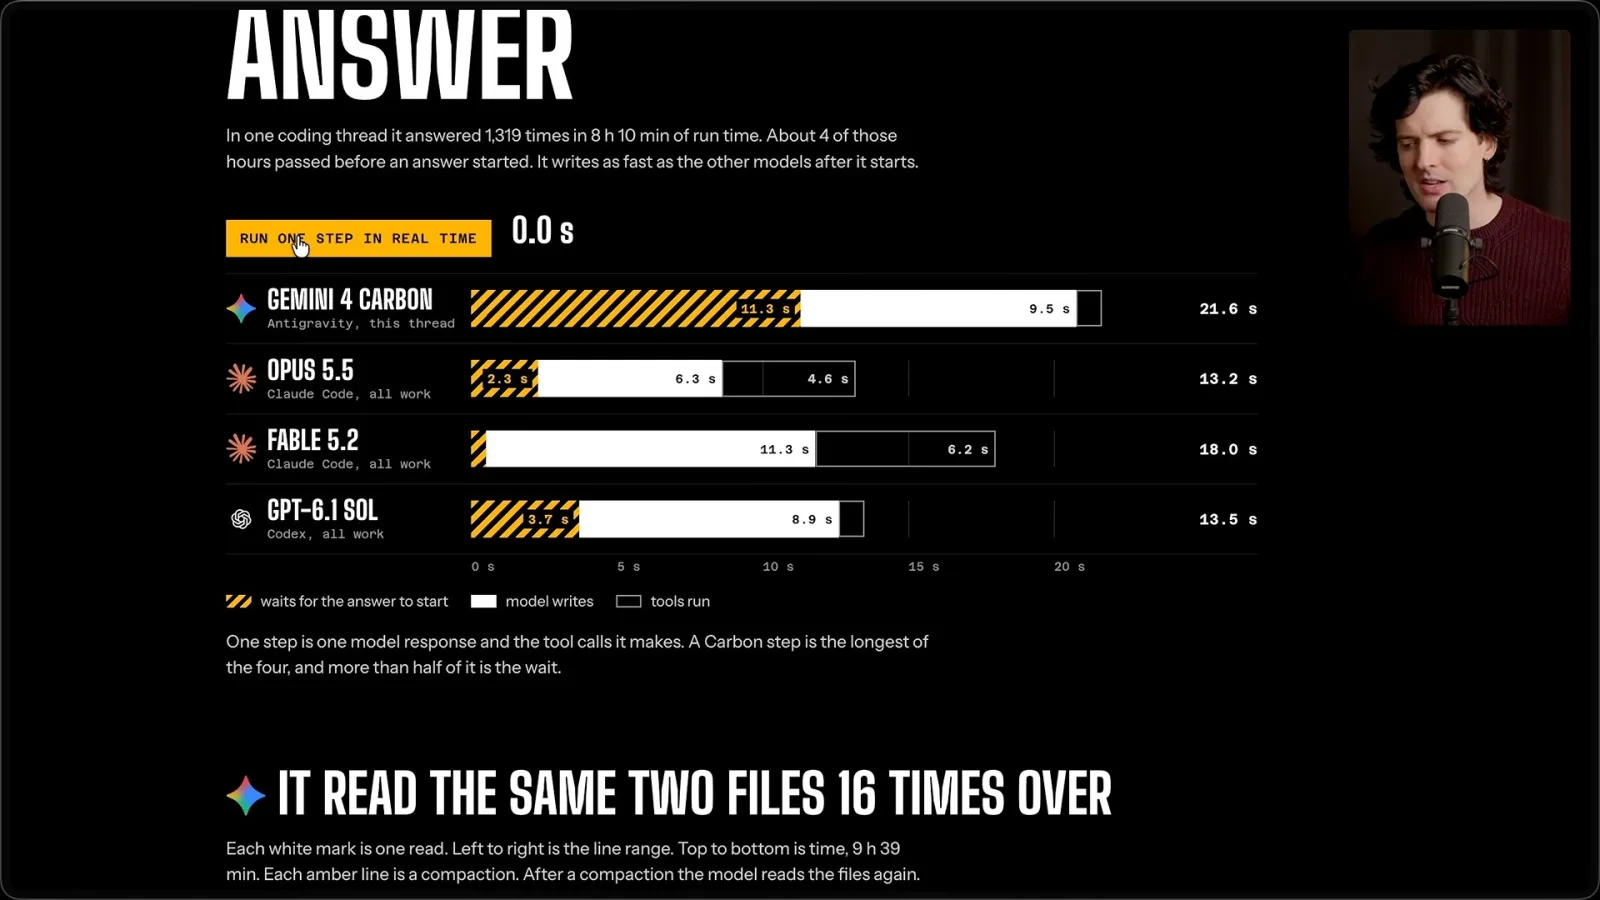
I demonstrate one step in real time and compare it with other models. The example is a single response and its tool calls, not a complete coding task. I also say Carbon needed more steps for some of my work, which compounds the repeated startup delay.
I have seen hosting latency problems before: I describe a period when Azure-hosted OpenAI models sometimes took much longer than usual to produce a first token. I say that issue was later fixed, and I want Google’s teams to have enough information to investigate this one.
Prefill, transport and cache behavior
A discussion with a Google developer highlights that prompt processing is separate from network transport. Browne also describes a cache test and a disagreement about its generality.
In a discussion with a Google developer, I suggested reducing overhead in repeated requests, comparing it with a persistent connection used in another coding tool. The reply pointed out that processing a long prompt before generating output—prefill—also costs time. I agree that changing the network transport alone might not solve it.
After looking more closely, I say Carbon sometimes spent longer waiting to start than another model spent completing its response. I also observed repeated reads of the same files. Both behaviors can add to total task time, although the individual causes and their contribution require further investigation.
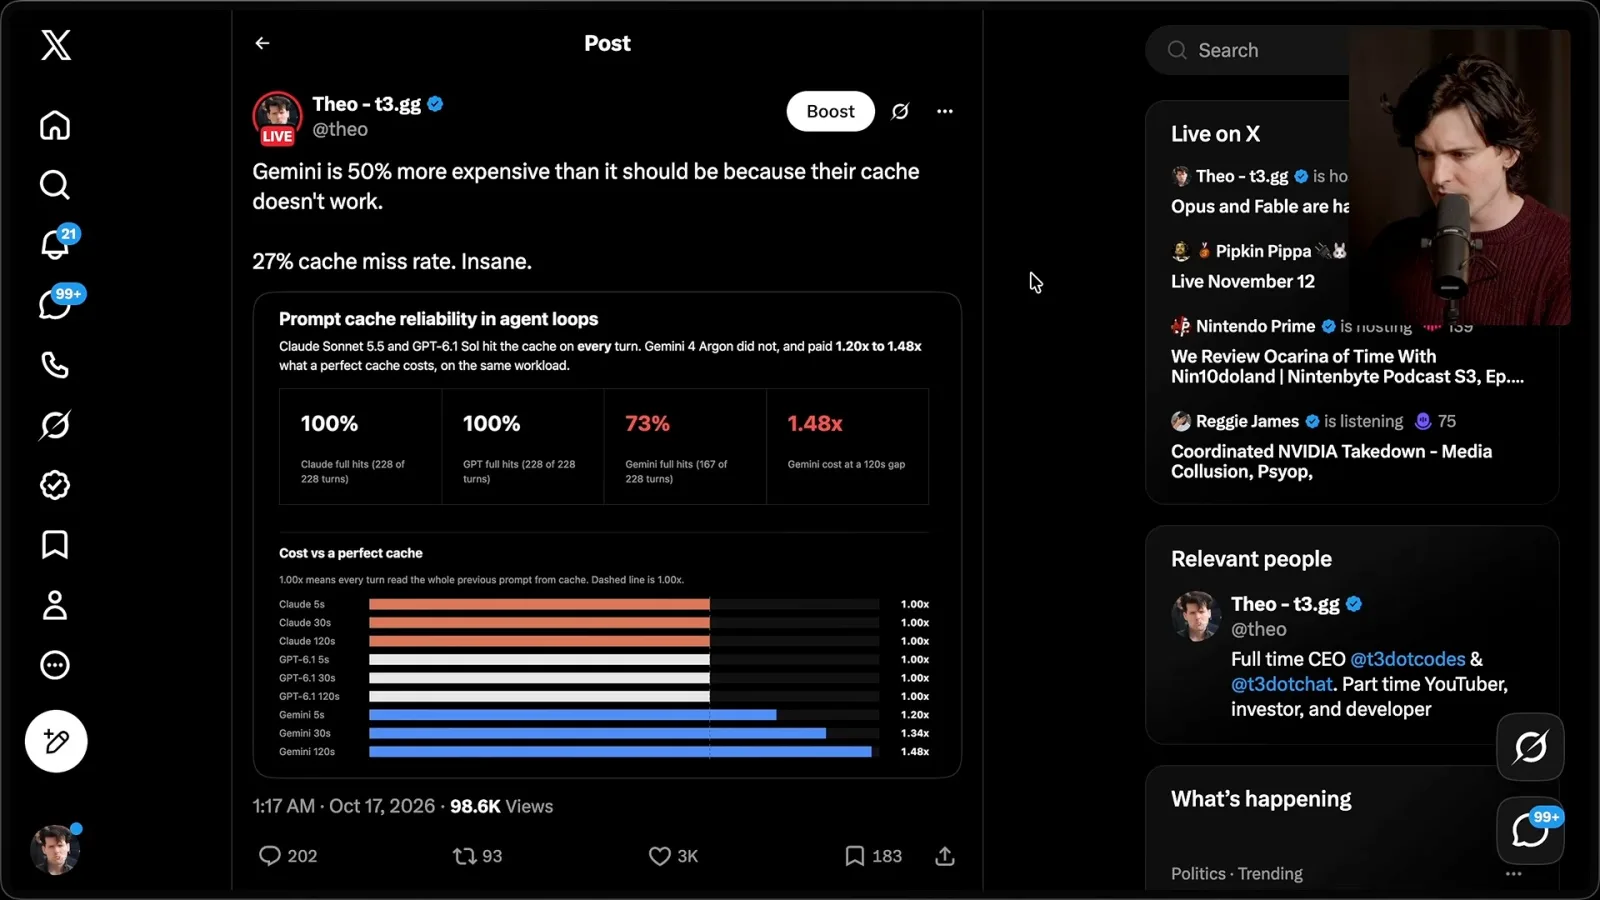
I raise a separate prompt-cache concern. In a test shown on screen for Gemini 4 Argon, the cache fully matched 167 of 228 turns, while the other displayed models matched all 228. The display estimates higher cost when the cache misses. This is a result from that workload, not a measured miss rate for every Gemini request.
A Google representative responded that their workloads did not show the same behavior. I say I am willing to share prompts, environments and run records so the teams can reproduce and fix the problems. Another response acknowledges a latency–cost tradeoff and says the service should improve.
Endpoint differences and the practical decision
Browne raises integration and endpoint concerns, offers to share his data, and explains why he is not using the model for routine work.
I also discuss differences users have reported between subscription access and hosted API endpoints, as well as integration friction when reasoning effort appears in the model identifier. These reports need to be assessed on the specific endpoint and workload; they do not isolate one cause of the latency I observed.
My revised conclusion is that, for my current coding workflow, the combined delay, cost and reliability concerns outweigh the benefits I found. I want more capable competitors and say I would welcome improvements, but I will not use this model for routine work in its current state.
Más de este canal
 42:19EN
 Theo - t3․gg· 13 nov 2026Opus or Fable? Match the coding model to the workTheo Browne · Ping LabsTheo Browne compares two Claude models and explains how a thorough tester and a more exploratory second opinion helped solve a performance problem.
 29:37ENTheo - t3․gg· 11 nov 2026Theo finds a security use for Gemini 4 Carbon despite coding frustrationsTheoHis tests show fewer false code-analysis claims than Argon, but latency and reliability still push him toward other models.
 48:20ENTheo - t3․gg· 10 nov 2026Fable 5.2 is powerful, but Theo Browne still prefers Opus for everyday codingTheo Browne · T3After a day of tests, Browne compares benchmarks, usage limits and the mistakes that still require a human reviewer.
 45:21ENTheo - t3․gg· 9 nov 2026Theo: AI coding makes maintaining the development environment the jobTheo Browne · Ping LabsFrom Twitch to T3 Code, Theo argues that engineers must remove the friction and feedback failures that block agents.
 42:14ENTheo - t3․gg· 6 nov 2026Theo Browne on How Claude Code Reviews Its Own ChangesTheo Browne · Ping LabsTheo compares Anthropic’s layered review process with T3 Code, highlighting verification, rollback and stopping rules for agent review.
 41:02ENTheo - t3․gg· 5 nov 2026Theo on PewDiePie’s Local AI Project, Training Data and Model SafetyTheo, PewDiePieA reaction to the Ajax and Odysius project becomes a discussion of opt-in data, agent traces, fine-tuning and local model tradeoffs.