In 30 seconds
Harvey’s Spectre platform has handled 10,000 agent-written pull requests, but Joey Wang says the hard failures came from the infrastructure around the agents. One alert storm launched 900 duplicate investigations; a later 950-task burst filled the cluster. The team deduplicated alerts and introduced a fair launch queue, yet a 60% rise in company-wide PR volume has left merging as an unresolved bottleneck.
- 1The follow-up loop continues after the agent writes codeIt checks a real stack, repairs CI failures and puts the PR through the shared review process.
- 2A callable interface grew to 6,500 terminal-started tasks a monthPeople and agents could use the same command-line actions without opening the web app.
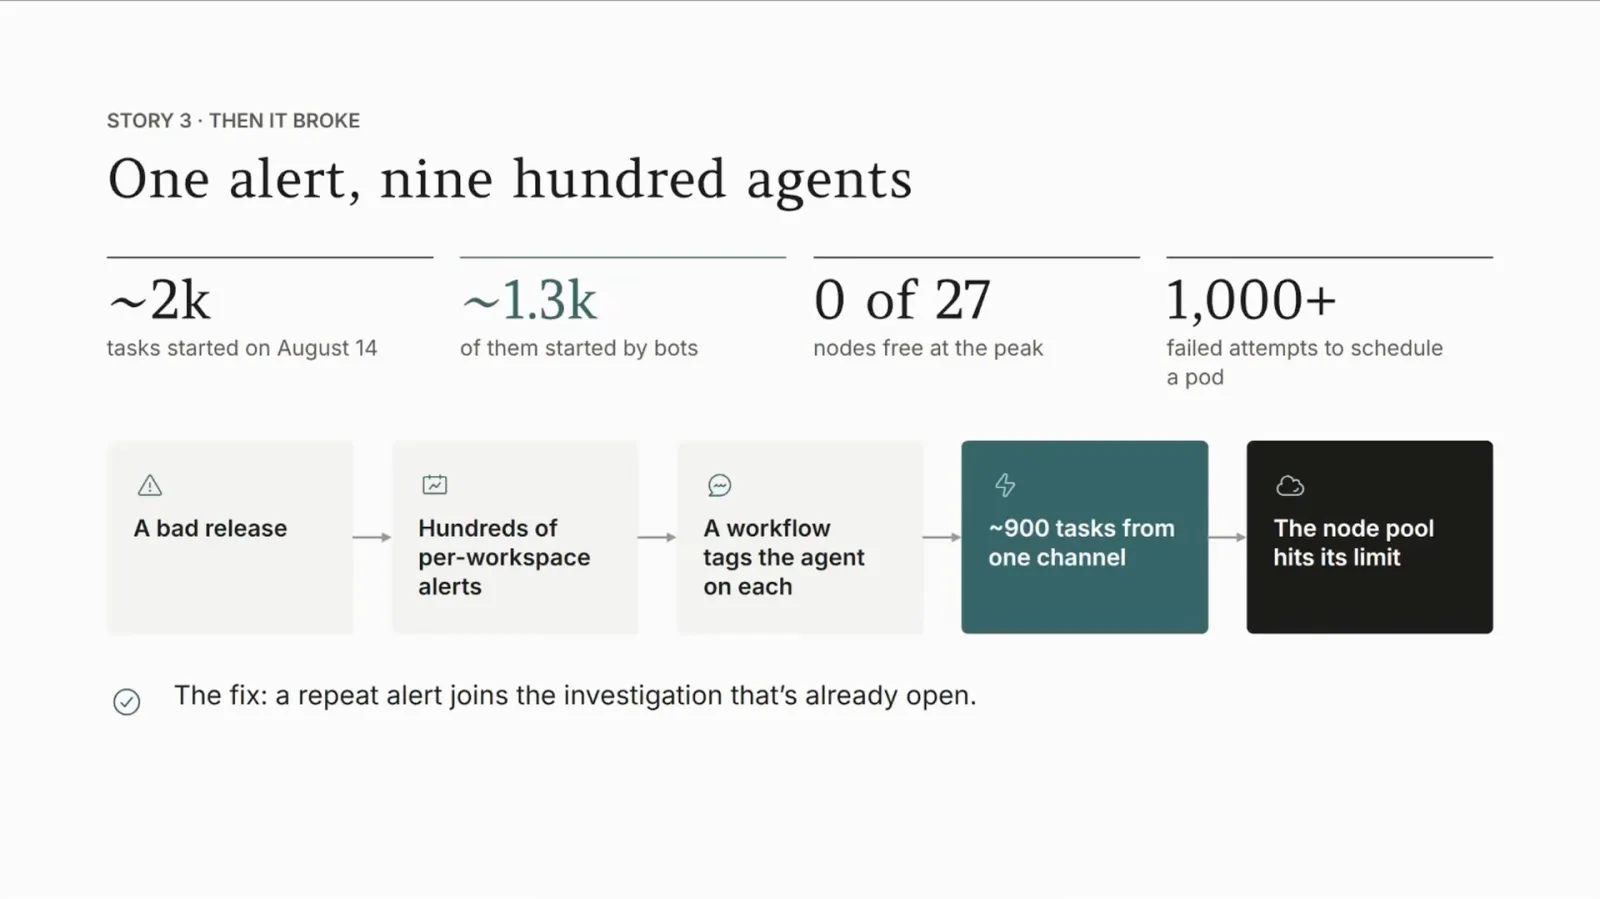
- 3One alert storm created 900 investigations for the same bugRepeated alerts now join an open investigation instead of starting another task.
- 4A single engineer’s 950 tasks filled the clusterA fair launch queue prioritized interactive users and limited contention; a 300-task synthetic test improved task-list p95 from 1.7 seconds to 71 milliseconds.
- 5The bottleneck moved to a merge queue the team has not solvedCompany-wide PR volume rose about 60% in a month and merge time grew from 15–30 minutes to over an hour.
Takeaways
- Deduplicate repeated alerts so they join an existing agent investigation.
- Queue and fairly share capacity before users or agents can fill the cluster.
- Build follow-up for failed CI, validation evidence, review and merging after code generation.
- Make platform actions callable by agents, but limit how much work any caller can start.
- Give unattended automations failure limits, budgets or expiry dates.
Read the edited text by chapter
The platform around agents became the hard part
Spectre runs existing agents with company context and a shared process. Usage expanded beyond coding.
More than one agent started on Harvey’s platform every minute on average in the preceding month, says Joey Wang. After 10,000 agent-written pull requests, his main lesson is that the difficult failures were in the surrounding platform: scheduling, testing, review and merging.
About 460 people at Harvey used the platform in the previous month. Its work expanded beyond coding: employees ask data questions in Slack, and one marketing colleague requested a storyboard for a product video from a prototype and a talk track.
Wang calls the internal cloud platform Spectre. It runs existing coding agents rather than competing to build a new one. In his view, cloud execution supplies the company’s secrets, real stack, alerts, tickets, shared rules and capacity that individual laptop tools do not provide on their own.
Finish the work after code generation
The platform validates changes, follows up on CI failures and sends PRs through a common review queue.
Instead of rebuilding the same integrations for each coding tool, engineers can use their preferred agent and call Spectre underneath. Work can start locally, move to the cloud and return. The shared platform handles the stages after the initial code is written.
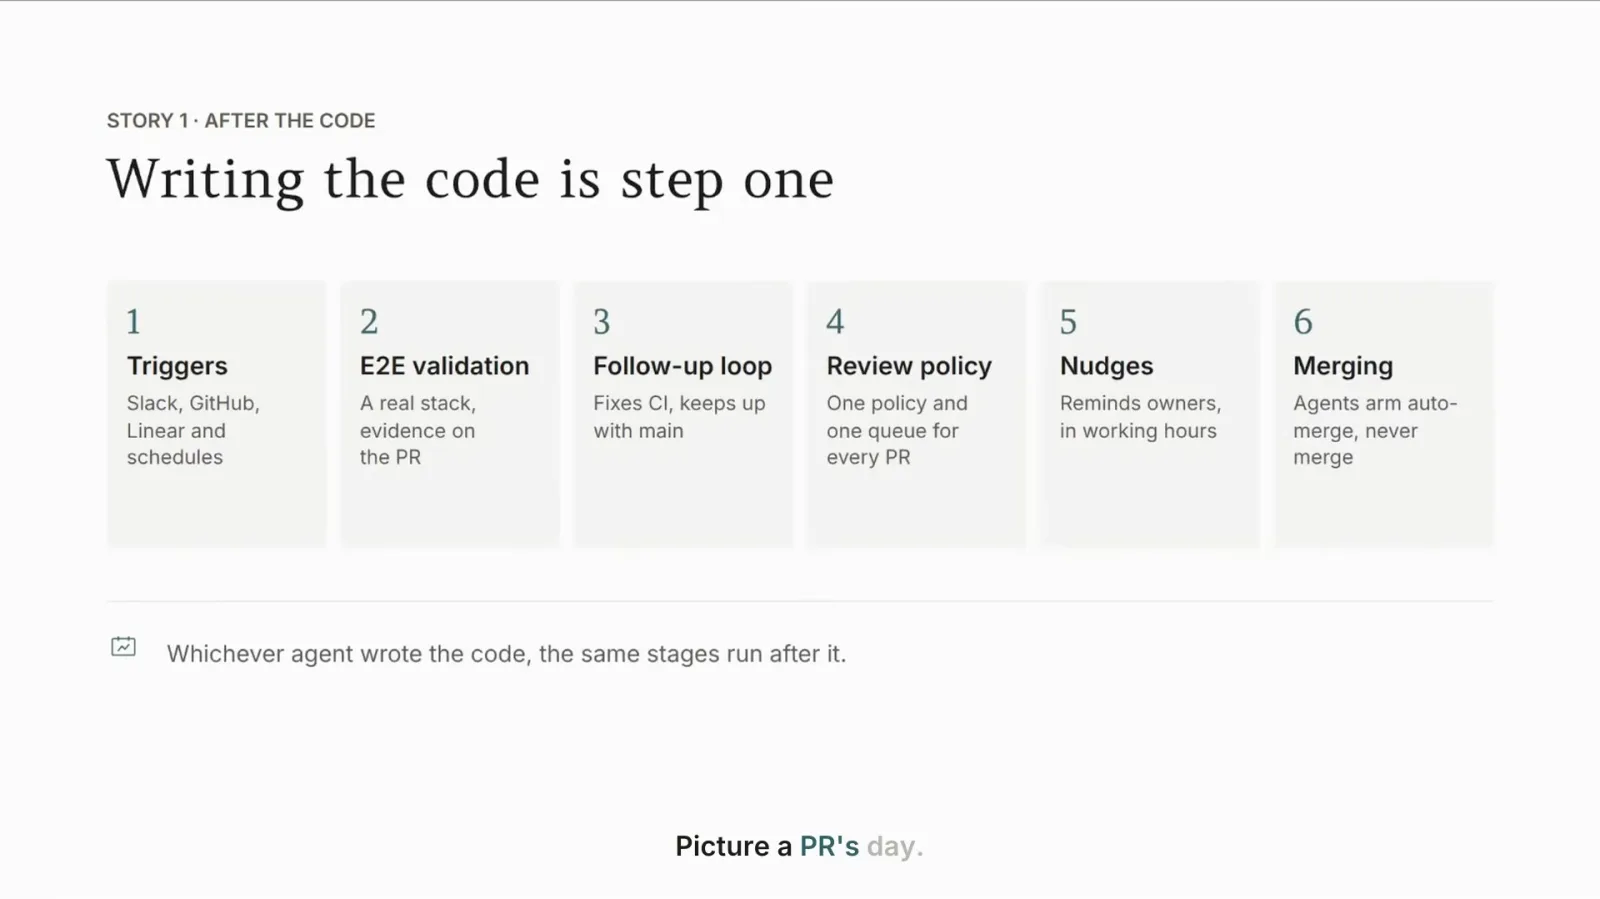
For an overnight alert, an agent can write a fix, start a real copy of the stack and attach evidence to a pull request. A follow-up loop reads CI failures and pushes fixes. The request enters the common review queue, its owner is nudged during working hours, and an agent can enable automerge after approval.
Wang says the follow-up loop was enabled for everyone in early October. That month, four out of five agent PRs that merged into the backend had gone through it. Teams also record project knowledge and trusted skills so agents share test instructions and an audit trail.
Let agents call every platform action
Command-line access lets local agents, sandboxed agents and CI start work. Usage grew to thousands of terminal-started tasks a month.
The next rule was: if a person can click an action, an agent should be able to call it. The command line can start tasks, enable follow-up or automerge, and publish a page. A laptop agent, a sandboxed agent or CI can use the same interface.
In May, only one task originated from the terminal; by October the command line started about 6,500 per month, while the web app continued to be used. Some people started hundreds of tasks a month without opening the app.
Wang used a local agent as a coordinator to split work into ten milestones and send hundreds of tasks to Spectre, each with an isolated environment for end-to-end validation. He also describes an assistant that lists questions waiting for his response and drafts answers for his approval.
The slowest task stage was not model inference but checking out repositories: copying every repository took more than a minute on average. The team kept a copy of each repository on each machine and allowed tasks to borrow it.
Two task storms filled the cluster
Duplicate alerts and a large legitimate batch exposed capacity limits. Deduplication and a fair launch queue addressed those failures.
In August, a faulty release triggered an alert per workspace. A workflow tagged the agent on every alert, producing around 900 tasks in four hours instead of the usual roughly 50. All chased the same bug until no node capacity remained. The fix joins repeated alerts to an existing investigation.
In October, an engineer sent roughly 950 legitimate tasks from the command line in about three hours. One laptop filled the cluster and other people’s work queued behind it. Wang treats this as a platform design problem, not misuse by the engineer.
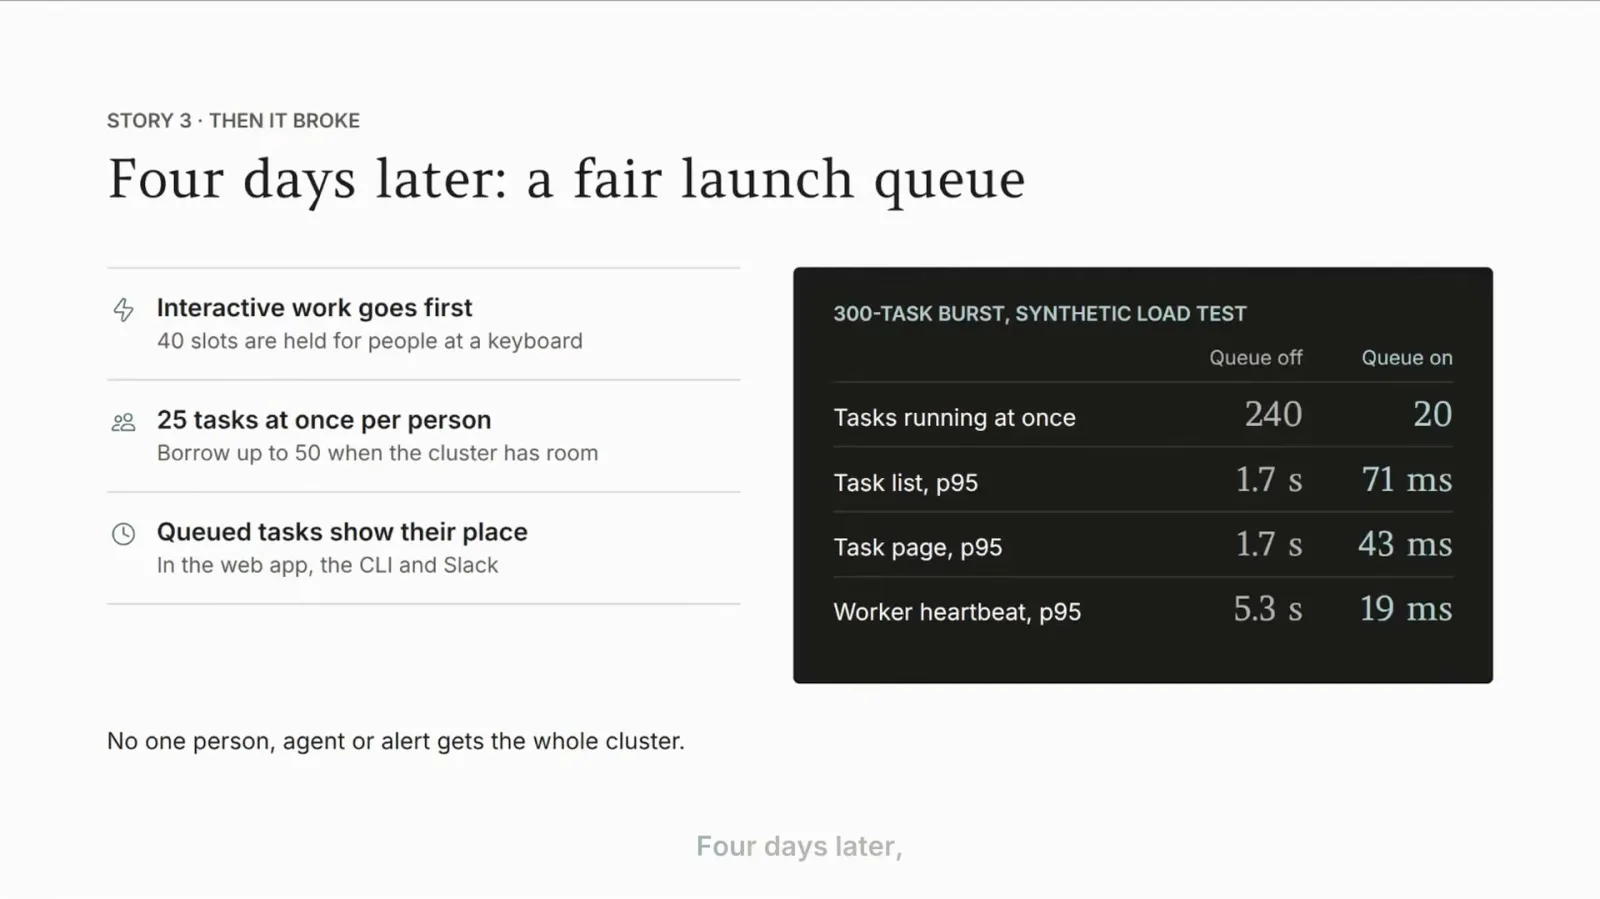
Four days later the team introduced a fair launch queue. Interactive users receive priority, users get a fair share and can borrow unused capacity, and queued tasks show their place in line. In a synthetic burst of 300 tasks, task-list p95 latency fell from 1.7 seconds to 71 milliseconds with the queue enabled.
Wang says a later busy day handled more than twice the task volume of an August peak with better completion. Several changes happened at once, so he cannot attribute the improvement to one fix. Larger bursts continued to arrive while the platform kept up.
Merging became the next unsolved bottleneck
A sharp rise in PRs overloaded the merge queue. Scheduled automations also need limits when nobody is watching.
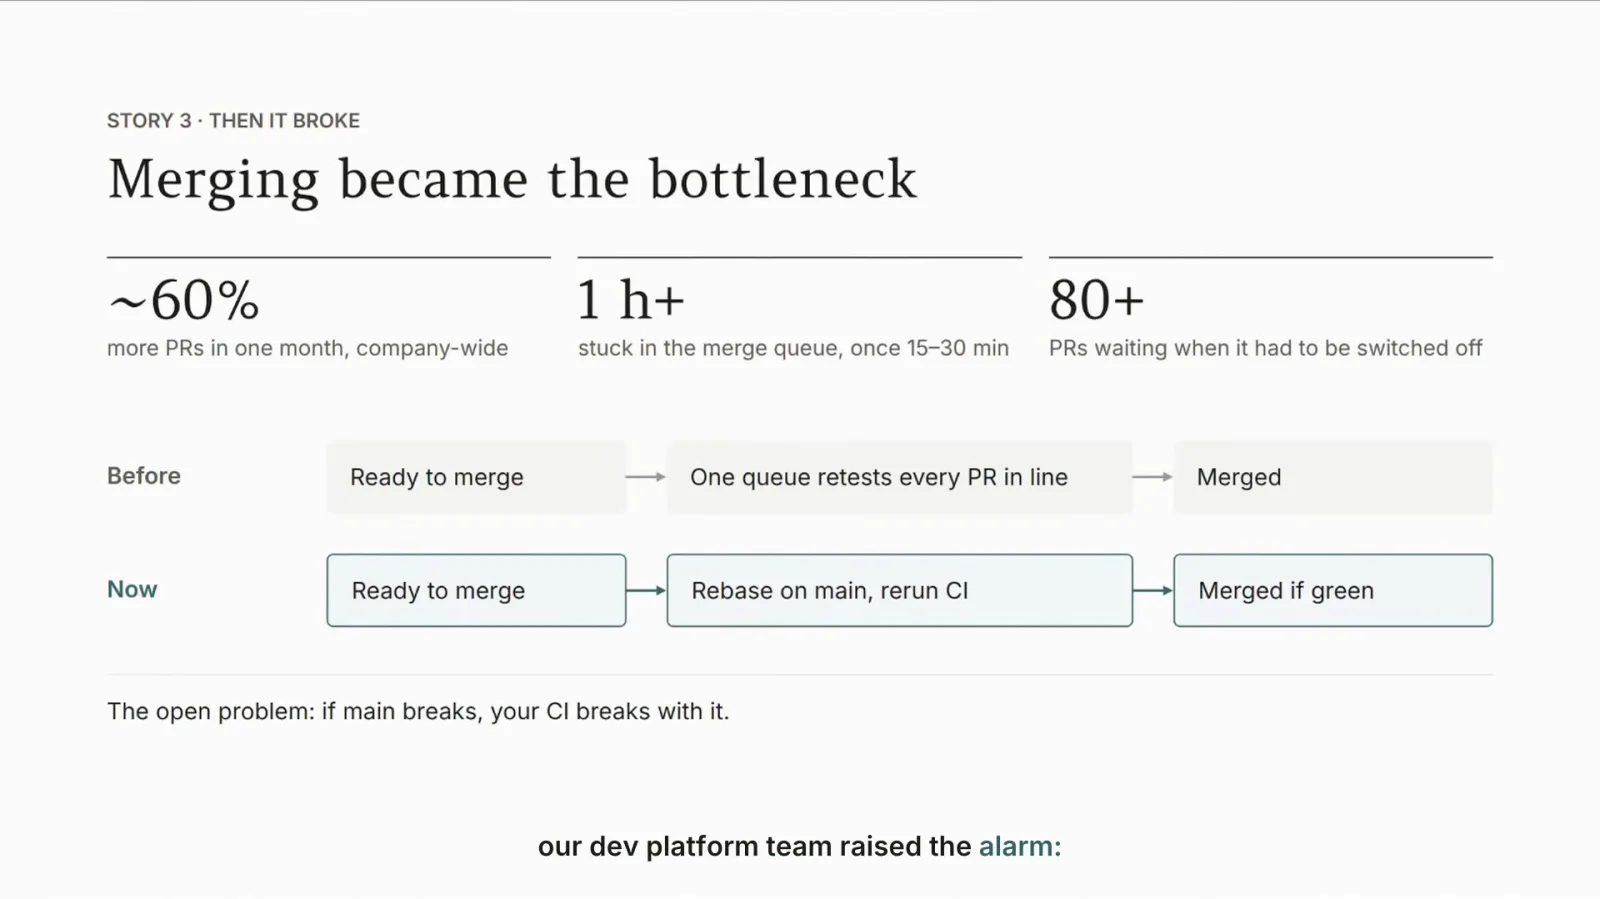
The bottleneck then moved to merging. Company-wide PR volume rose about 60% in one month, and a merge that once took 15–30 minutes exceeded an hour. The merge queue had to be switched off; PRs now rebase on main and rerun CI, leaving everyone exposed if main breaks. Wang says this problem remains unsolved.
Automations that start on a schedule or event are a fast-growing source of work. Around 110 people had an automation running in the previous month. A job switches itself off after five consecutive failures and can carry a budget or expiry date, limiting unattended task creation.
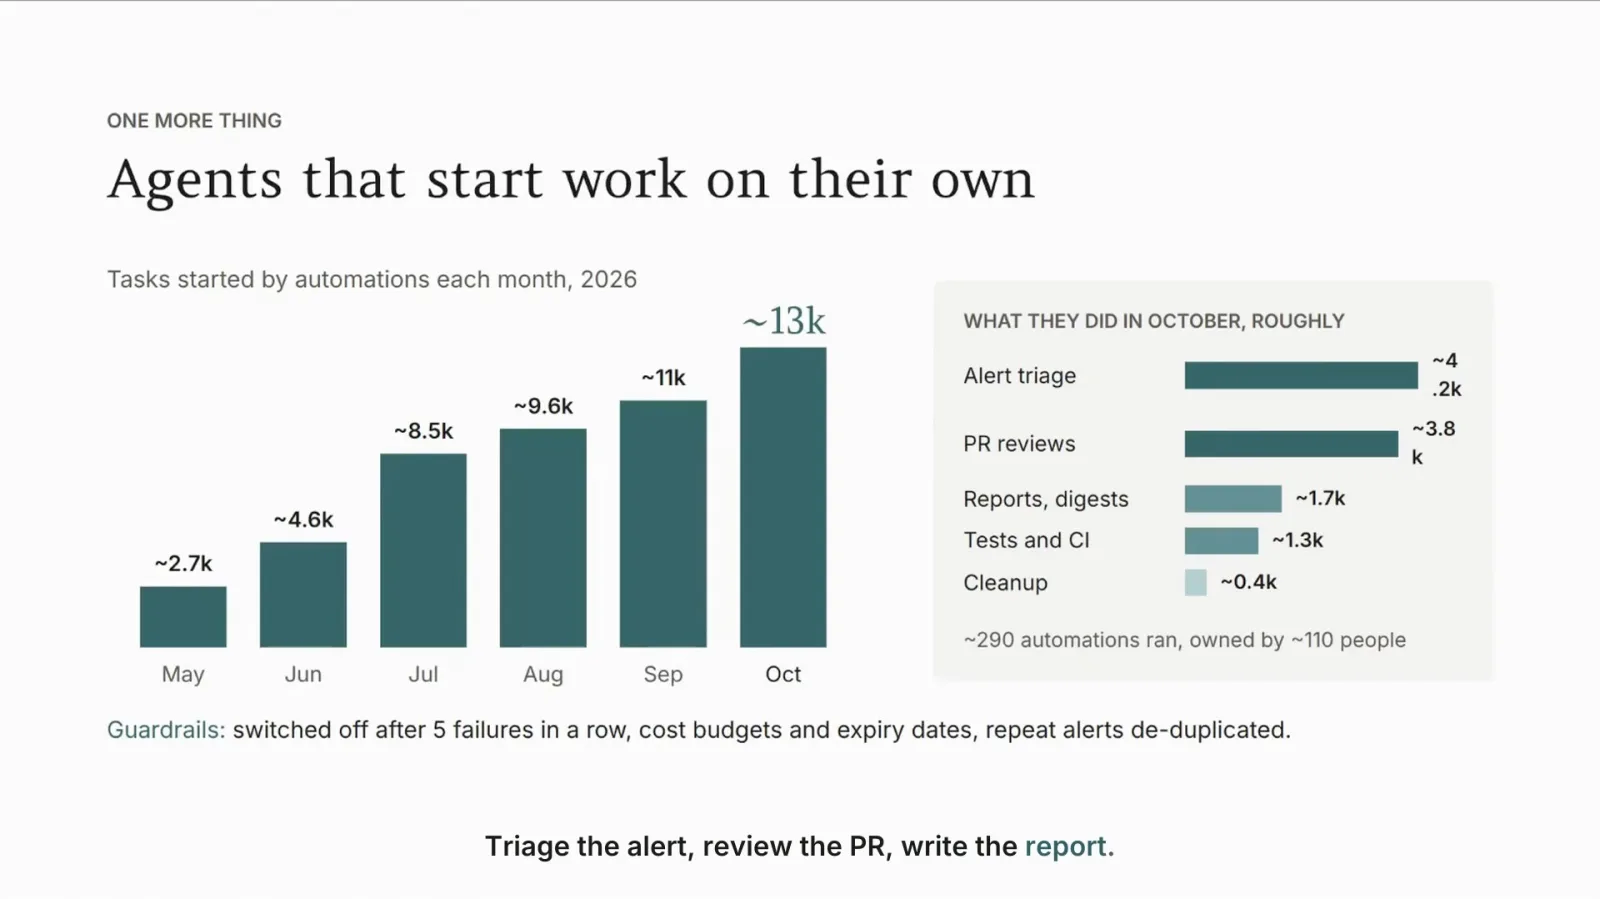
Wang is still asking how to run persistent channel agents, require evidence before a person reviews a PR, and merge when agents continuously open requests. Only about one merge in twenty currently carries that kind of proof, he says.
His advice is to own what happens after code is written, make actions callable by agents, and cap how much work an agent, person or alert can launch. Engineers can choose their preferred coding agent; the shared system still has to run, check and merge the work.
More from this channel
 38:50EN
 AI Engineer· Nov 10, 2026LinkedIn’s self-improving agent first had to fix its judgesZiwei Guo, Saloni Gandhi · LinkedInA prompt-optimization loop improved a career agent, but unreliable evaluators required human calibration first.
 28:00ENAI Engineer· Nov 10, 2026Robinhood’s AI reviewer merges 60% of data PRs without human reviewChetas Joshi · RobinhoodScripts verify live facts, an agent traces code risks, and people retain sensitive decisions.
 19:41ENAI Engineer· Nov 9, 2026A high-reliability automation starts by routing the hard cases awayMatthew Jewkes · Standard CyberneticsMatthew Jewkes describes separating critical errors, ambiguous decisions and unusual exceptions in a biopharma indexing workflow.
 52:08ENAI Engineer· Nov 9, 2026When coding agents overwhelm a self-hosted model, reject earlyHarshul Jain, Parv Khatri · AudibleAdmission control can protect GPU capacity, but benchmark it against every offered request—including the ones rejected.
 22:01ENAI Engineer· Nov 9, 2026Zach Lloyd: make the software factory measurable and editableZach Lloyd · WarpWarp’s CEO proposes recording agent runs, scoring failures and testing changes to the workflow on real tasks.
 27:35ENAI Engineer· Nov 9, 2026Uber traded an always-green trunk for faster AI-scale mergesPreetam Dwivedi, Manjari Akella · UberIts merge queue now relaxes some conflicts and validates the combined state after landing, with a verified-good fallback.