In 30 seconds
Hassan El Mghari and his father Omar tested whether an open model could construct a financial forecast around Costco’s 2024 membership-fee increase. Five of 16 generated models passed their engineering checks, and their average forecast was within 4.4% of the reported result. Omar’s accounting review found that an overstated geographic base and an understated executive-member share partly canceled each other, illustrating why output accuracy alone cannot validate a financial model. The speakers recommend involving domain experts and turning their checks into repeatable tests.
- 1Control what the model could already knowThe team selected models that did not answer their check about Costco’s 2024 fee increase and used filings available before the cutoff.
- 2Build a financial model from timestamped factsThey extracted roughly 3,000 facts from 214 public filings and asked the model to generate structured formulas and assumptions.
- 3Five of 16 generated models passed basic checksThe team retried failed checks and reports that the parallel model runs cost about 19 cents.
- 4Two wrong assumptions canceled outOmar found that the model applied the increase to too broad a membership base while understating the executive-tier share.
- 5Use expert judgment as another line of defenseThe speakers recommend reviewing assumptions and encoding domain checks alongside engineering validation.
Takeaways
- A historical forecasting test should control access to facts and model knowledge from after the cutoff.
- Structured formulas and assumptions are easier to inspect and test than an opaque numerical answer.
- Parallel generation and basic validation can find candidate models but do not ensure accounting correctness.
- Offsetting errors can make an inaccurate model appear accurate.
- A domain expert can challenge assumptions and help encode stronger checks.
Read the edited text by chapter
A father and son test an AI forecast
Hassan introduces the experiment and Omar describes his accounting background. Their initially promising result leads to a review of the assumptions.
Hassan El Mghari introduces a joint project with his father Omar: can a language model build a financial forecast for Costco using only public information available before a selected date? They focus on the effect of a membership-fee increase.
Hassan leads developer experience at Together AI and builds open-source AI applications. Omar brings experience in auditing, finance leadership and internal audit; he serves as the domain expert reviewing the engineering work.
Hassan previews the result: the forecasts were close to the reported outcome, with an average error of about 4.4%. Omar’s review revealed that the close result did not mean the underlying assumptions were sound.
Creating the Costco financial model
The team uses filings from before the membership-fee increase, generates formulas and tests multiple runs.
Costco sells large volumes of goods at relatively low margins, making membership fees important to operating profit. The speakers use the 2024 increase in standard and executive membership prices as the event to forecast.
The team chooses a cutoff before the announced change and gathers the information available up to that point. They ask how a fee increase would affect the financial model over the following two years.
Newer models already answered a check about the 2024 increase, suggesting that they had encountered the event. The team therefore selected older open models that did not answer that check; the check reduces, but cannot prove the absence of, knowledge leakage.
They collect 214 public filings and turn them into roughly 3,000 timestamped facts. Facts after the cutoff are filtered out before the model builds the forecast.
The language model generates structured assumptions and formulas rather than performing all the arithmetic in a single response. The resulting model is then evaluated separately, making its inputs and calculations easier to inspect.
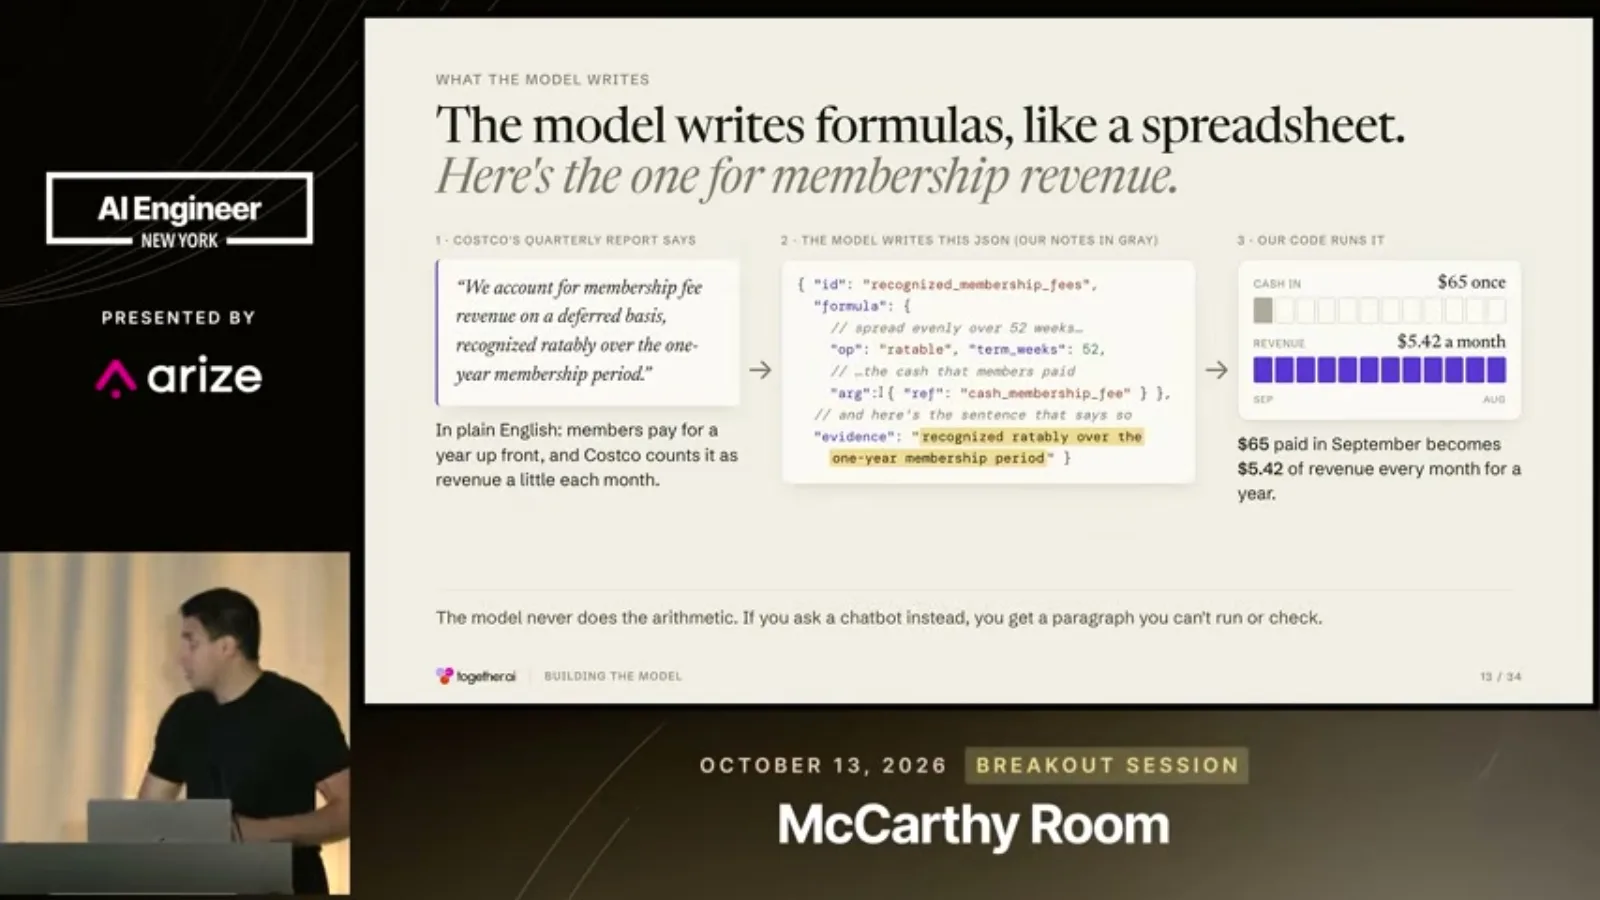
For example, the model represents the recognition of annual membership fees over the membership period. It also estimates unknown quantities such as executive-tier share and the proportion of members in affected geographies.
The resulting spreadsheet includes assumptions, 14 generated formulas and numbers from filings. The team tests properties such as avoiding circular dependencies and whether a fee increase raises revenue.
They run 16 independent attempts and return validation errors for up to two correction attempts. Five generated models pass the checks; Hassan says the 16 model runs cost about 19 cents.
A close forecast with offsetting errors
The model produces a forecast near the reported outcome. Omar shows how incorrect assumptions happened to cancel.
Hassan asks the resulting financial model to estimate the impact of the fee increase. One output projects approximately $560 million in additional profit over two years; the calculation runs quickly once the formulas are built.
The speakers compare the forecasts with reported results and say the average of the five builds was about 4.4% off. Hassan initially viewed that as encouraging, but a close numerical result does not by itself validate the model.
Omar starts his review with the assumptions. He notices that the executive-tier share moves the result substantially, while the US-and-Canada share appears to have no effect even though it should be relevant to the fee change.
The model used an executive-tier assumption of 15% and cited a statement about increased penetration without a supporting numeric value. Omar says the relevant filings already disclosed a figure of about 45%, which the model missed.
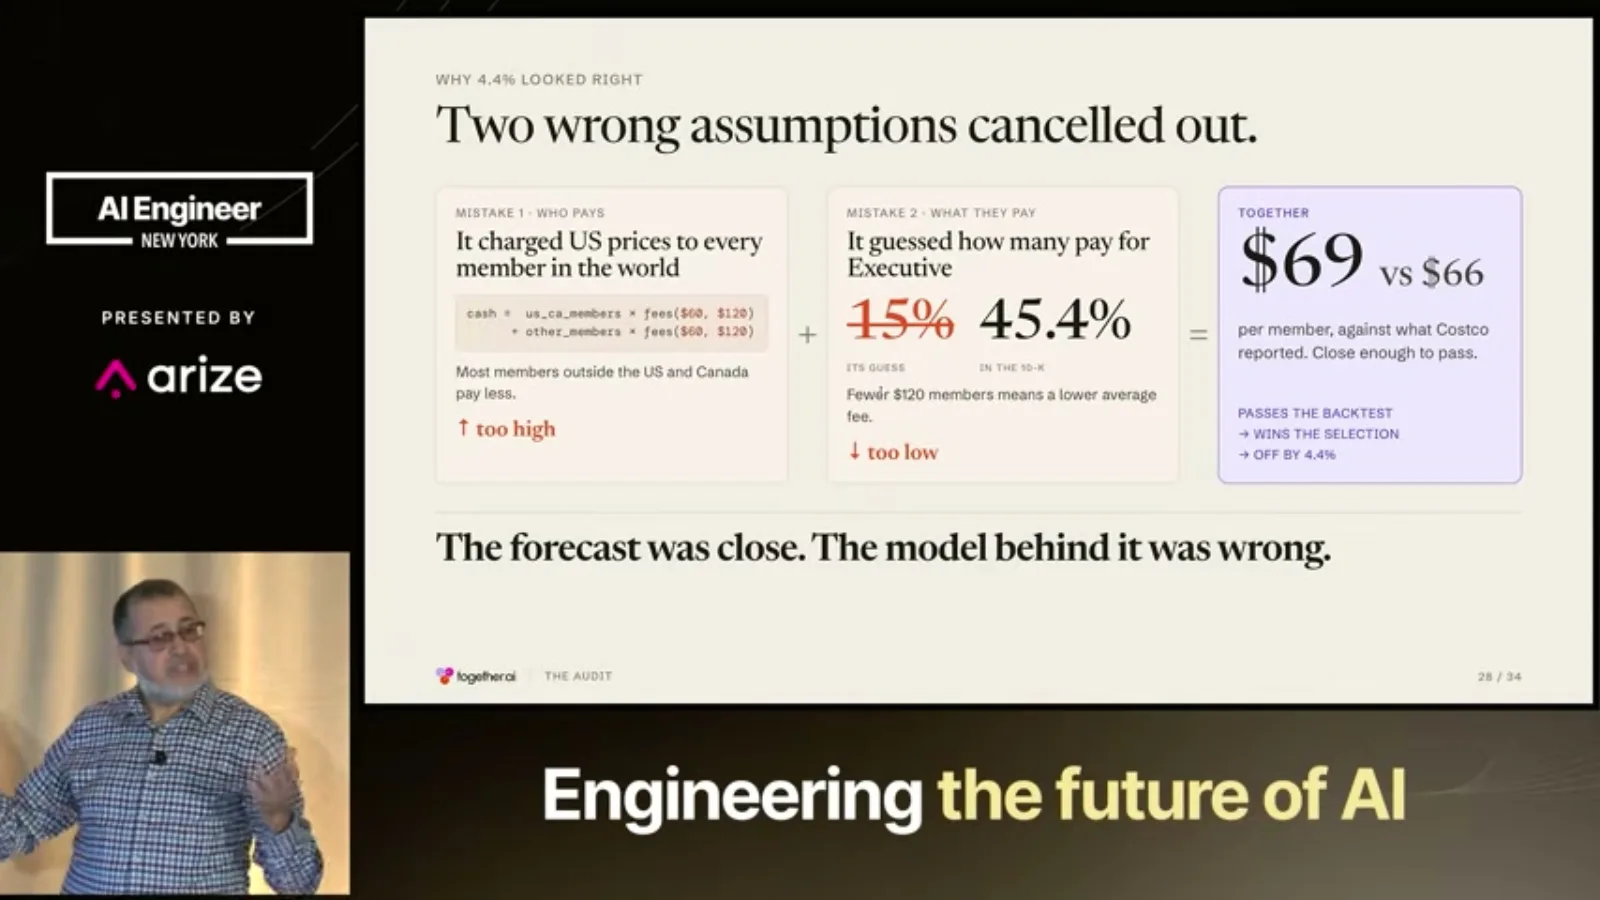
The team identifies two errors that partly offset each other. The model applies the increase to too broad a geographic membership base, overstating the affected population, while using too low an executive-tier share.
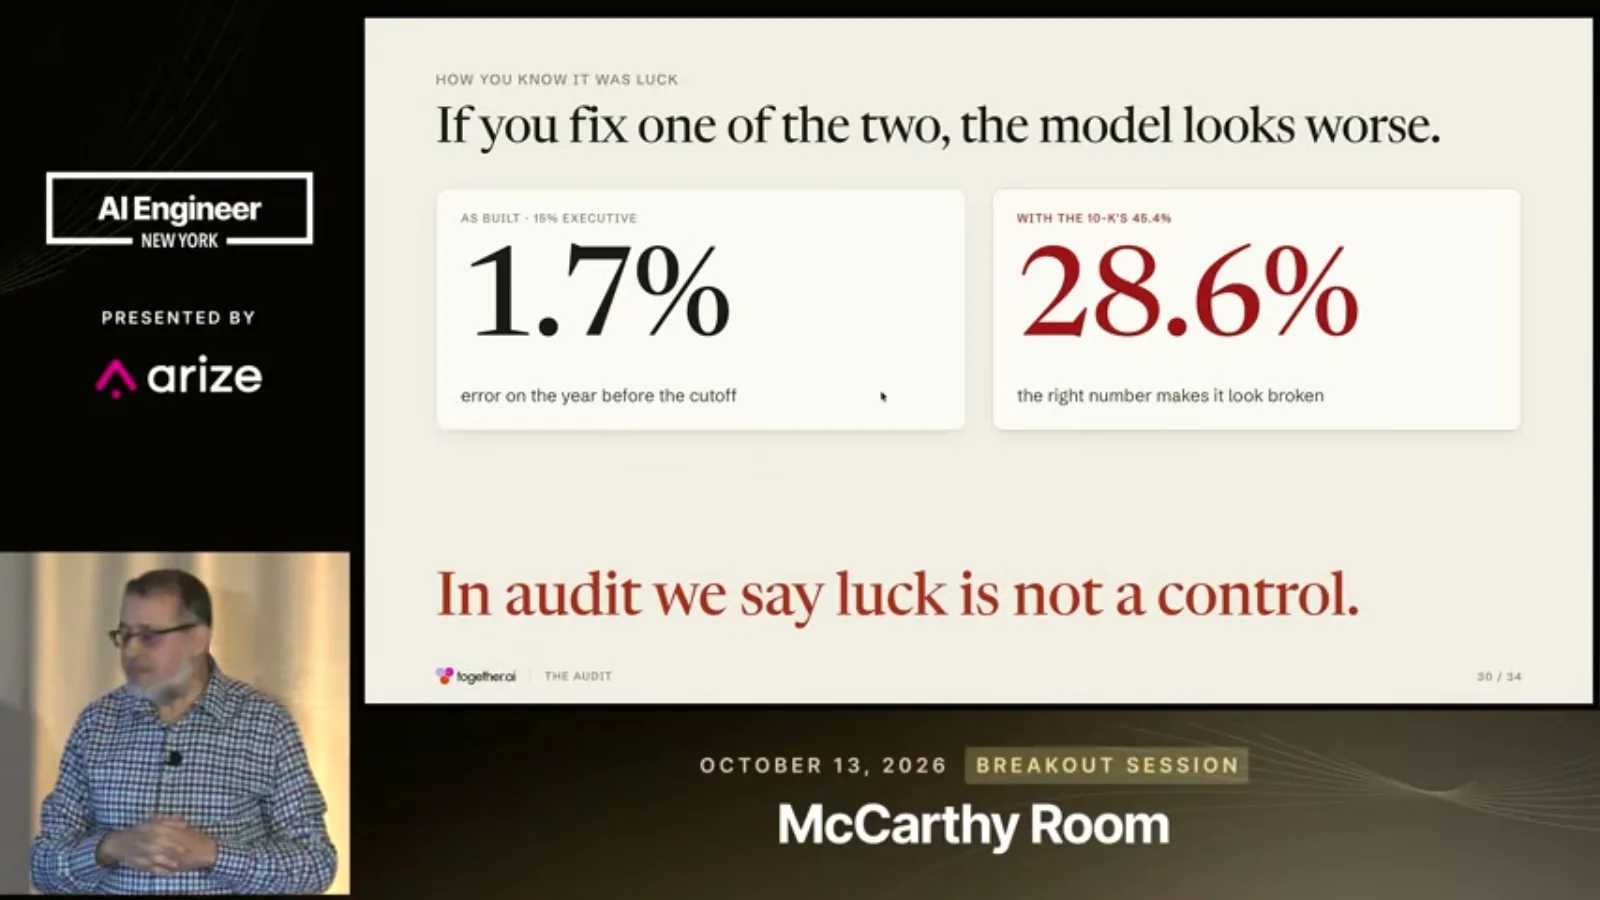
Omar describes a diagnostic technique: correct one assumption at a time and observe whether the result gets worse. In his example, replacing the 15% assumption with 45% exposes a much larger error rather than an improvement.
Add professional judgment and checks
The speakers compare engineering checks with internal and independent review. They argue that experts can help encode stronger validation.
He compares the engineering checks with three lines of defense in auditing: management controls, internal audit and independent external review. In this demonstration, he supplies professional judgment as an additional layer.
Hassan says some of Omar’s accounting checks can be converted into programmatic validation. The broader lesson is to ask a subject-matter expert to examine assumptions, inputs and outputs before treating a close forecast as reliable.
The speakers conclude that domain checks and human review complement automated tests. Their single retrospective case illustrates a failure mode, not evidence that this workflow will reliably forecast other companies or investment returns.
More from this channel
 19:41EN
 AI Engineer· Nov 9, 2026A high-reliability automation starts by routing the hard cases awayMatthew Jewkes · Standard CyberneticsMatthew Jewkes describes separating critical errors, ambiguous decisions and unusual exceptions in a biopharma indexing workflow.
 22:01ENAI Engineer· Nov 9, 2026Zach Lloyd: make the software factory measurable and editableZach Lloyd · WarpWarp’s CEO proposes recording agent runs, scoring failures and testing changes to the workflow on real tasks.
 27:35ENAI Engineer· Nov 9, 2026Uber traded an always-green trunk for faster AI-scale mergesPreetam Dwivedi, Manjari Akella · UberIts merge queue now relaxes some conflicts and validates the combined state after landing, with a verified-good fallback.
 14:38ENAI Engineer· Nov 9, 2026Jemima Abu: Give coding agents accessibility rules from the startJemima Abu · CAISA product engineer shows how semantic HTML, reusable components and explicit agent skills can help teams build more usable interfaces.
 21:12ENAI Engineer· Nov 9, 2026Tom Moor: Give coding agents the product context that code cannot showTom Moor · LinearLinear’s workflow carries customer requests, past decisions, review history and human feedback from intake through implementation and review.
 15:35ENAI Engineer· Nov 9, 2026Mislav Ivanda: Choose an execution boundary before an agent frameworkMislav Ivanda · DaytonaThe Daytona engineer compares local approvals, embedded runtimes and sandboxed machines for running agent-generated code.