In 30 seconds
In a video recorded largely before Fable’s June 2026 suspension, Theo questions access restrictions, fallback behavior and data retention. He criticizes an initially invisible safeguard for frontier model development, reports Anthropic’s move to visible safeguards, and distinguishes his own unverified theory from the evidence shown.
- 1Fallback and false positivesAnthropic described visible fallback to Opus for certain sensitive categories and acknowledged harmless requests could be caught.
- 2Retention and exceptionsThe announced 30-day retention policy raised questions for customers expecting zero retention; Theo’s legal interpretation remains uncertain.
- 3Invisible interventionAn earlier system card described undisclosed measures to limit assistance with frontier model development.
- 4A correction and policy updateTheo finds a changelog and corrects himself; Anthropic says it is moving to visible safeguards.
- 5What the research chart showsThe 64% result concerns selected cases where a researcher’s next step had room for improvement, not average superiority.
- 6An unproven theoryTheo’s hypothesis about proprietary information in model weights is speculation, not a demonstrated cause of the safeguards.
Takeaways
- Anthropic described Fable 5 and Mythos 5 as the same underlying model with different safeguards.
- Visible fallback and false positives can complicate users’ experience and benchmark interpretation.
- The announced retention policy included a 30-day baseline and exceptions, raising questions for some business customers.
- Theo corrected his initial assertion that the updated system card lacked a changelog.
- Anthropic said it was replacing the invisible frontier-development safeguard with visible fallback; Theo’s proposed explanation for its original choice is speculative.
Read the edited text by chapter
A powerful model with restrictions
Theo introduces his concerns about access, fallback and evaluation. A later insert notes the government-related suspension.
Fable is an impressive model, but I am concerned about Anthropic’s restrictions: who can access it, when requests fall back to another model and how those interventions affect evaluation. Strong benchmark results can include an Opus 4.8 fallback, and a reported ProgramBench run saw the model refuse all 200 tasks.
A later insert provides context: while I was recording, news arrived that the US government had asked Anthropic to restrict the models. The main discussion was recorded before that suspension and examines the safeguards Anthropic had already introduced.
Models, fallback and retention
He explains the model offerings, safety classifiers and potential false positives. He then questions the business data-retention policy.
Anthropic describes Fable 5 and Mythos 5 as the same underlying model, with some safeguards lifted for trusted Mythos users. I compare them to two doors into the same place, one with additional checks. My idea that additional reinforcement learning separated the earlier Mythos preview from the later model is an assumption.
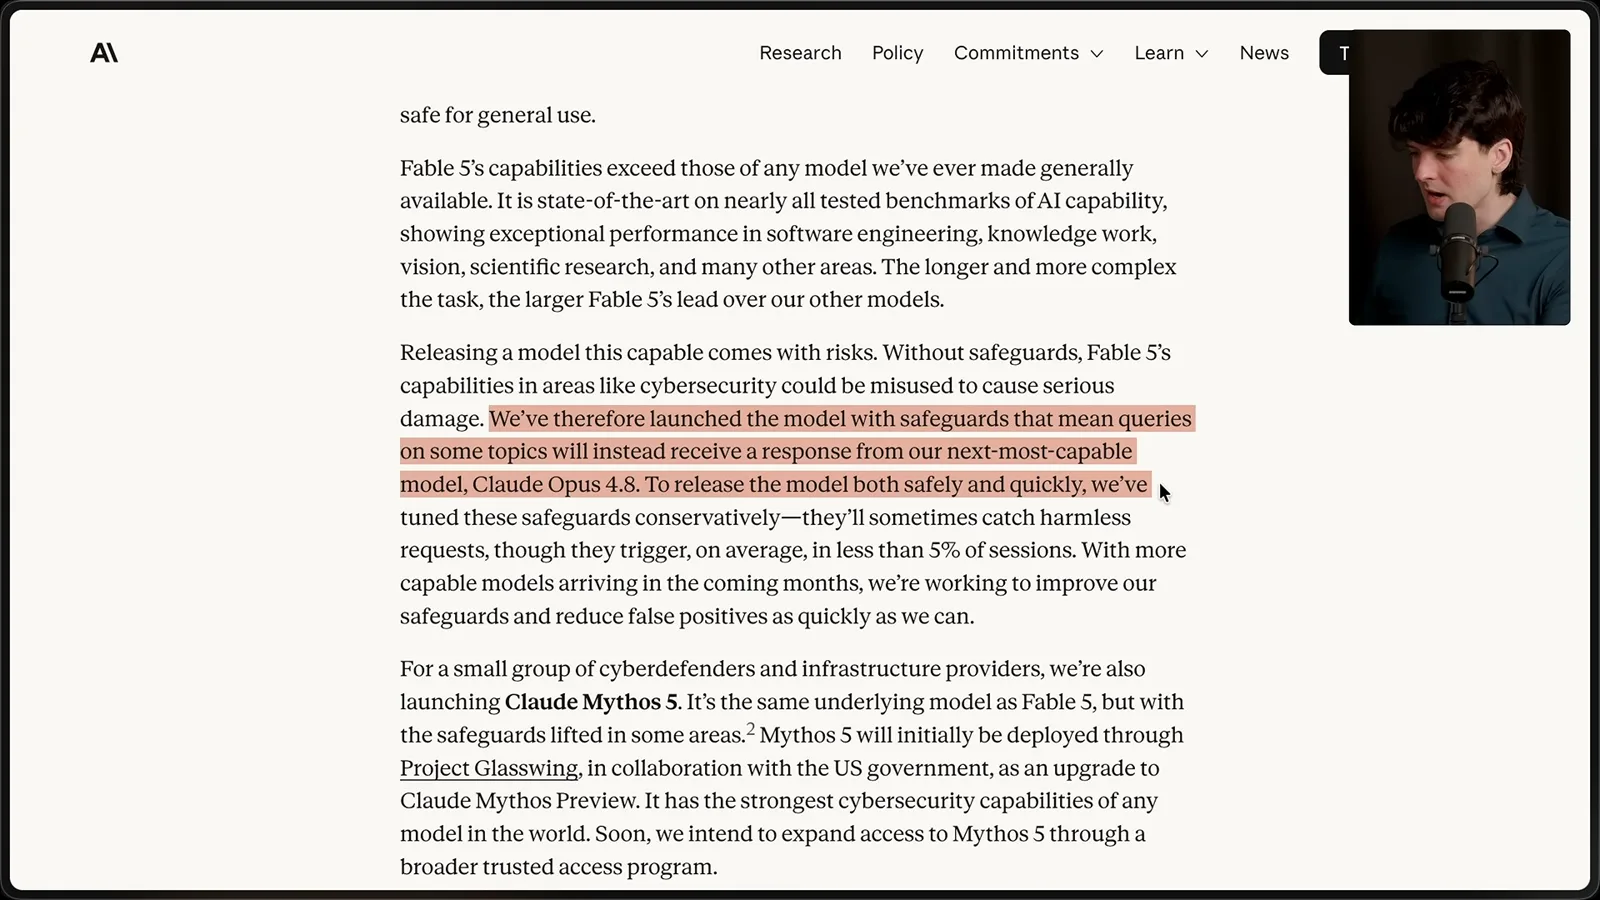
Anthropic said some requests would be routed to Opus 4.8 because of risks in areas such as cybersecurity. It said the safeguards were conservatively tuned, could catch harmless requests and triggered in fewer than 5% of sessions on average. In my experience, rerouting did sometimes happen on benign work.
For example, I asked for help with a cryptographic puzzle and saw a fallback followed by a response that stopped. I find that frustrating: a benign request can be rerouted and then fail under the fallback model’s restrictions too. Anthropic acknowledged that false positives were possible and said it intended to improve the classifiers.
The company described separate classifiers for potential misuse, including cybersecurity, biology, chemistry and model distillation. For the visible fallback categories it said users would be informed and billed for the model handling the request. I would prefer an explicit choice before an unexpected fallback incurs a different charge.
Restrictions can also change the meaning of a benchmark: a low result on a security evaluation may reflect safeguards or refusals rather than the underlying model’s raw capability. Some areas involve serious dual-use risks, so both the safety purpose and the measurement limitation deserve attention.
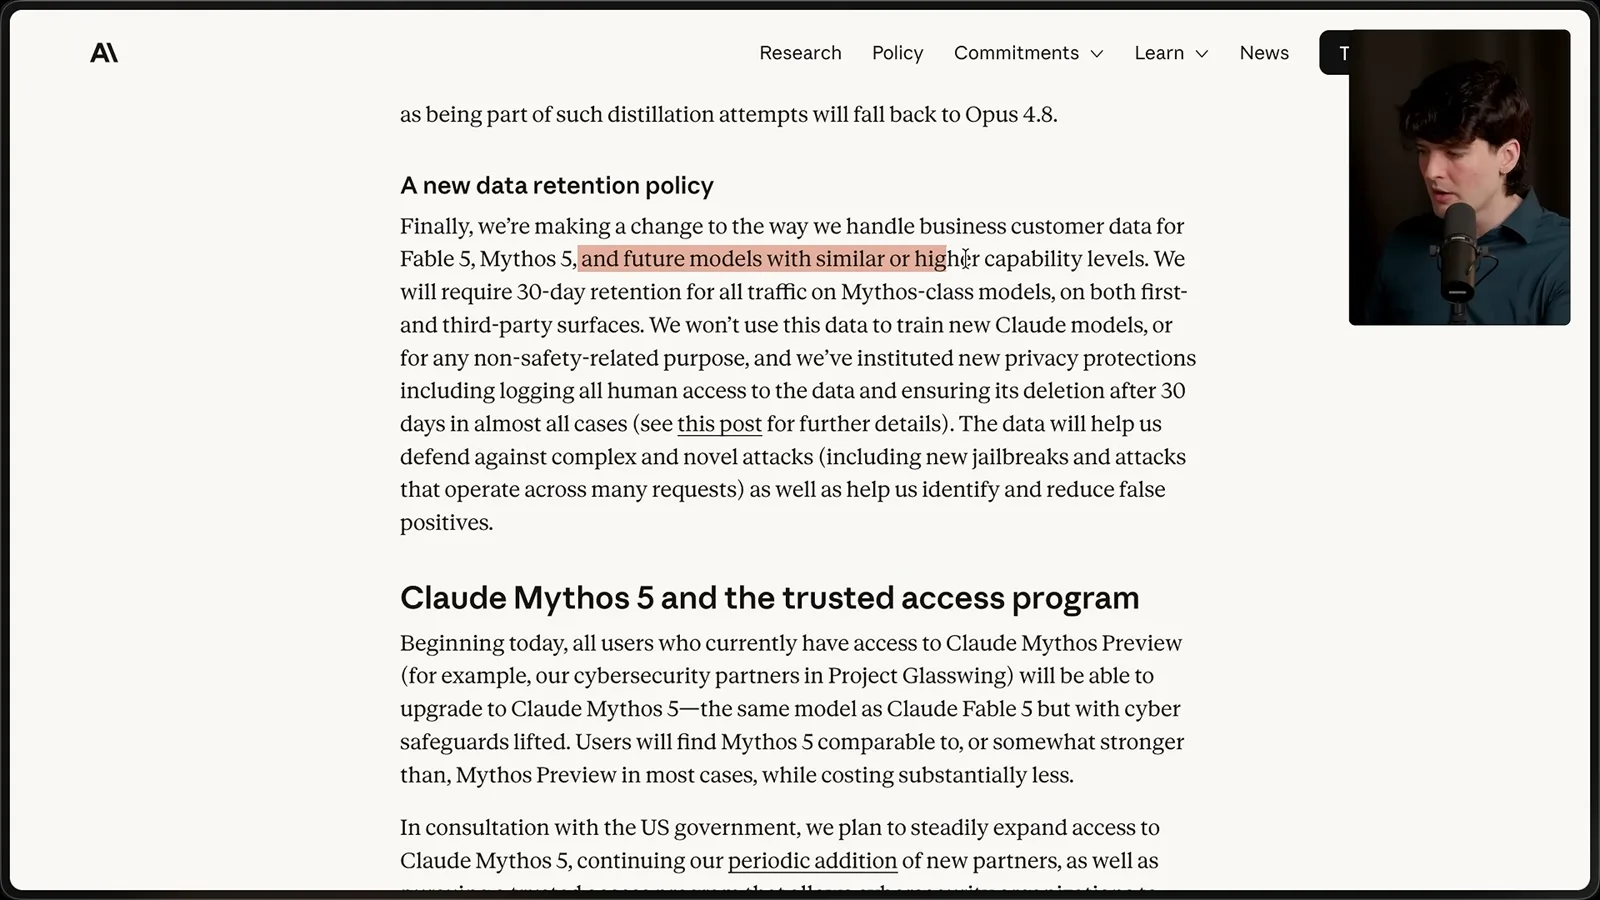
A separate issue is data retention. Anthropic said business traffic on Mythos-class models would require 30-day retention on first- and third-party surfaces, even where customers might otherwise expect zero data retention. It said the data would not be used to train new Claude models or for non-safety purposes, and would normally be deleted after 30 days.
The company also described exceptions for safety investigations or legal obligations. I worry about the longer retention periods mentioned for flagged material and what they mean for customers with sensitive data. My interpretation of how different policies interact, including whether any training exception applies, is uncertain and should not be treated as a legal conclusion.
Invisible safeguards and the correction
Theo compares system-card versions and criticizes hidden interventions. He later corrects his claim that the update had no changelog.
I found that the system card I had downloaded differed from the version online. Initially I accused the company of changing the document without noting it; later in the video I corrected myself after finding a changelog. The substantive change still matters to my criticism, but the initial claim about an absent changelog was wrong.
The earlier system card described invisible safeguards for requests targeting frontier language-model development. It listed methods such as prompt modification, steering vectors or parameter-efficient fine-tuning to limit effectiveness, and estimated that about 0.03% of traffic would be affected. Those were the document’s described interventions and estimates.
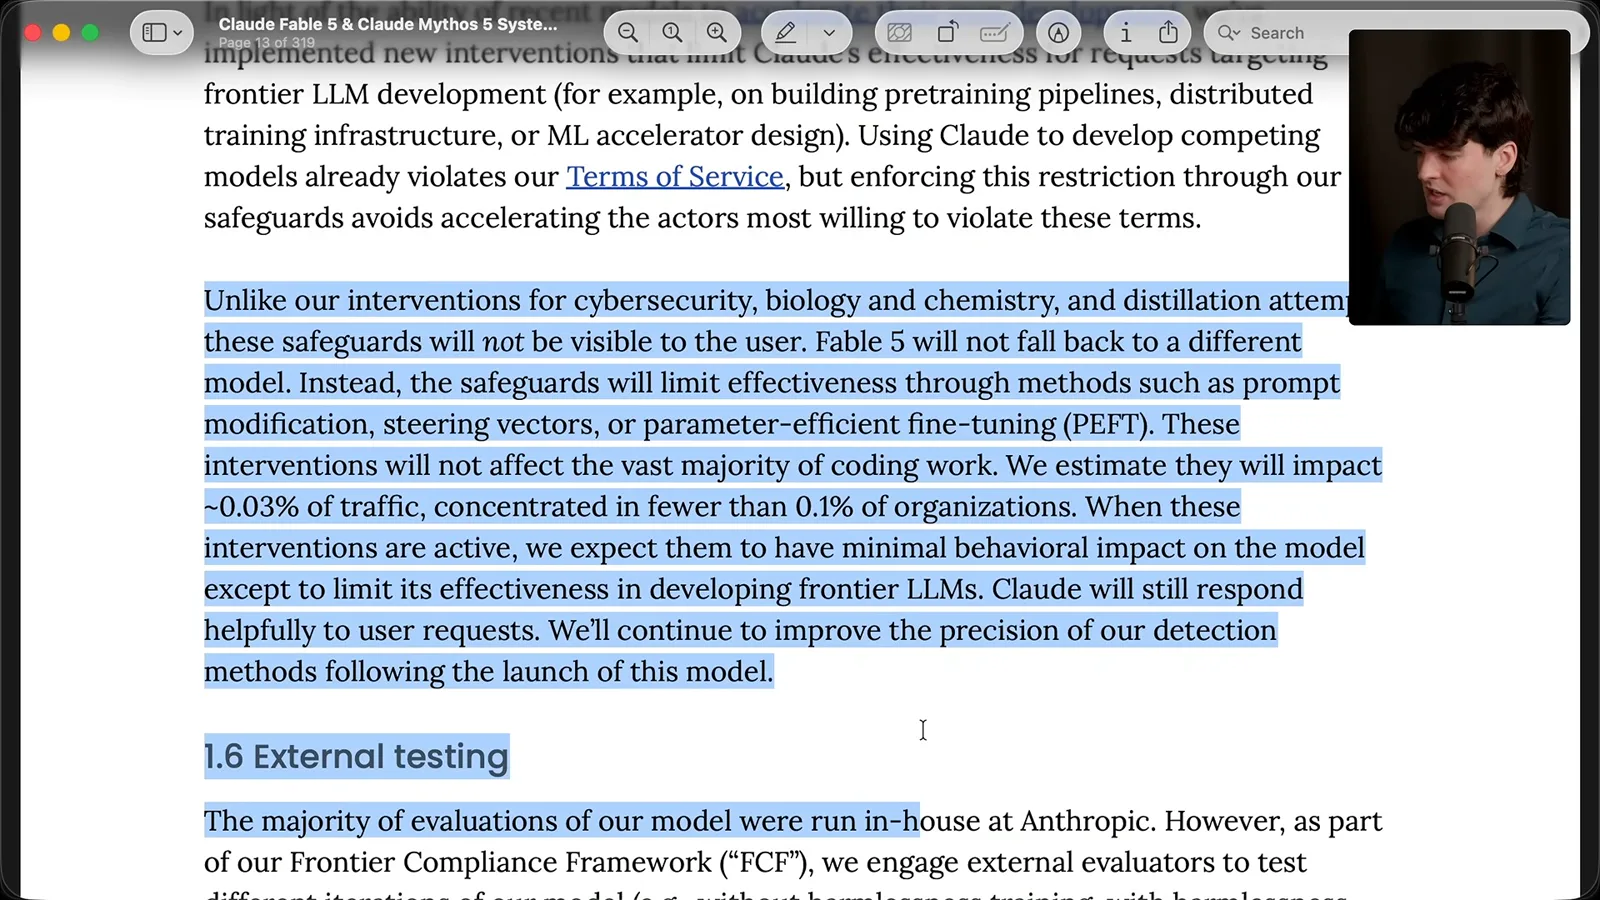
I interpreted that as a serious trust problem: a user could pay for an answer without knowing an intervention had affected it. My example of a prompt being rewritten to deliberately make code worse was hypothetical; the text I show does not establish that this exact rewrite occurred.
Researchers raised a related evaluation concern: if an intervention is invisible, an evaluator may not know whether a failure reflects the model’s capability or a safeguard. I share that concern, particularly where legitimate research resembles a restricted category. That uncertainty is different from proving a particular answer was deliberately sabotaged.
I discuss criticism from Redis creator Salvatore Sanfilippo and other researchers, who objected to restricting useful research and to the implications for openness. These are their arguments and mine; reasonable people can disagree about how to balance competitive, safety and transparency concerns.
Visible safeguards and speculation
Anthropic announces a change to visible fallback. Theo considers the research chart and offers an explicitly unverified theory about the earlier decision.
I then found Anthropic’s update and corrected my earlier statement about the missing changelog. The company said it was changing frontier-model-development safeguards to be visible: flagged requests would fall back to Opus 4.8, and API users would receive a refusal reason, with server-side fallback to follow.
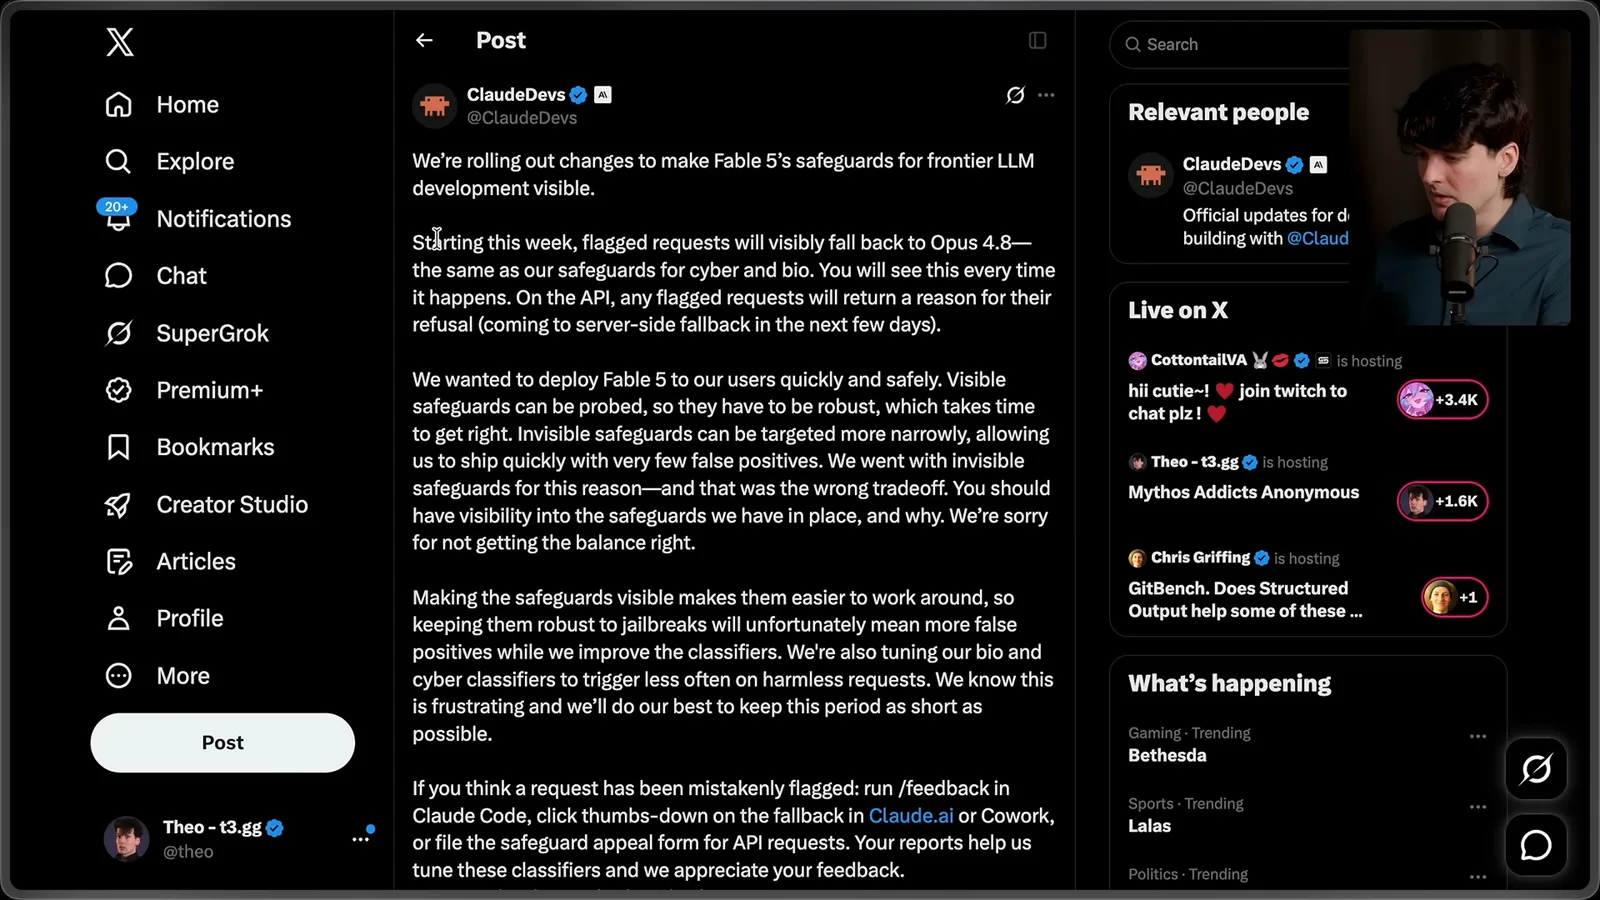
Anthropic said invisible safeguards were initially chosen because they could be narrowly targeted while the company worked on robustness, but acknowledged that this was the wrong transparency tradeoff. It warned that making safeguards visible could lead to more false positives and said it was tuning cyber and bio classifiers.
I welcome the reversal but remain unhappy with the earlier hidden intervention and think affected customers deserve compensation. Anthropic also described feedback and appeal paths for requests people believe were mistakenly flagged. This discussion records the rollout as described at the time, not a statement of current product behavior.
Why did Anthropic choose this approach? I offer a theory based on its research into models assisting AI researchers. It is speculation, not an established explanation from Anthropic. The company’s stated rationale was the safety and transparency tradeoff described in its update.
The research chart examined 129 internal sessions at points where a researcher’s next step had room for improvement. Mythos Preview’s alternative was judged better in 64% of those selected cases. This does not mean the model was better than researchers on average; the cases were chosen because the human direction was already improvable.
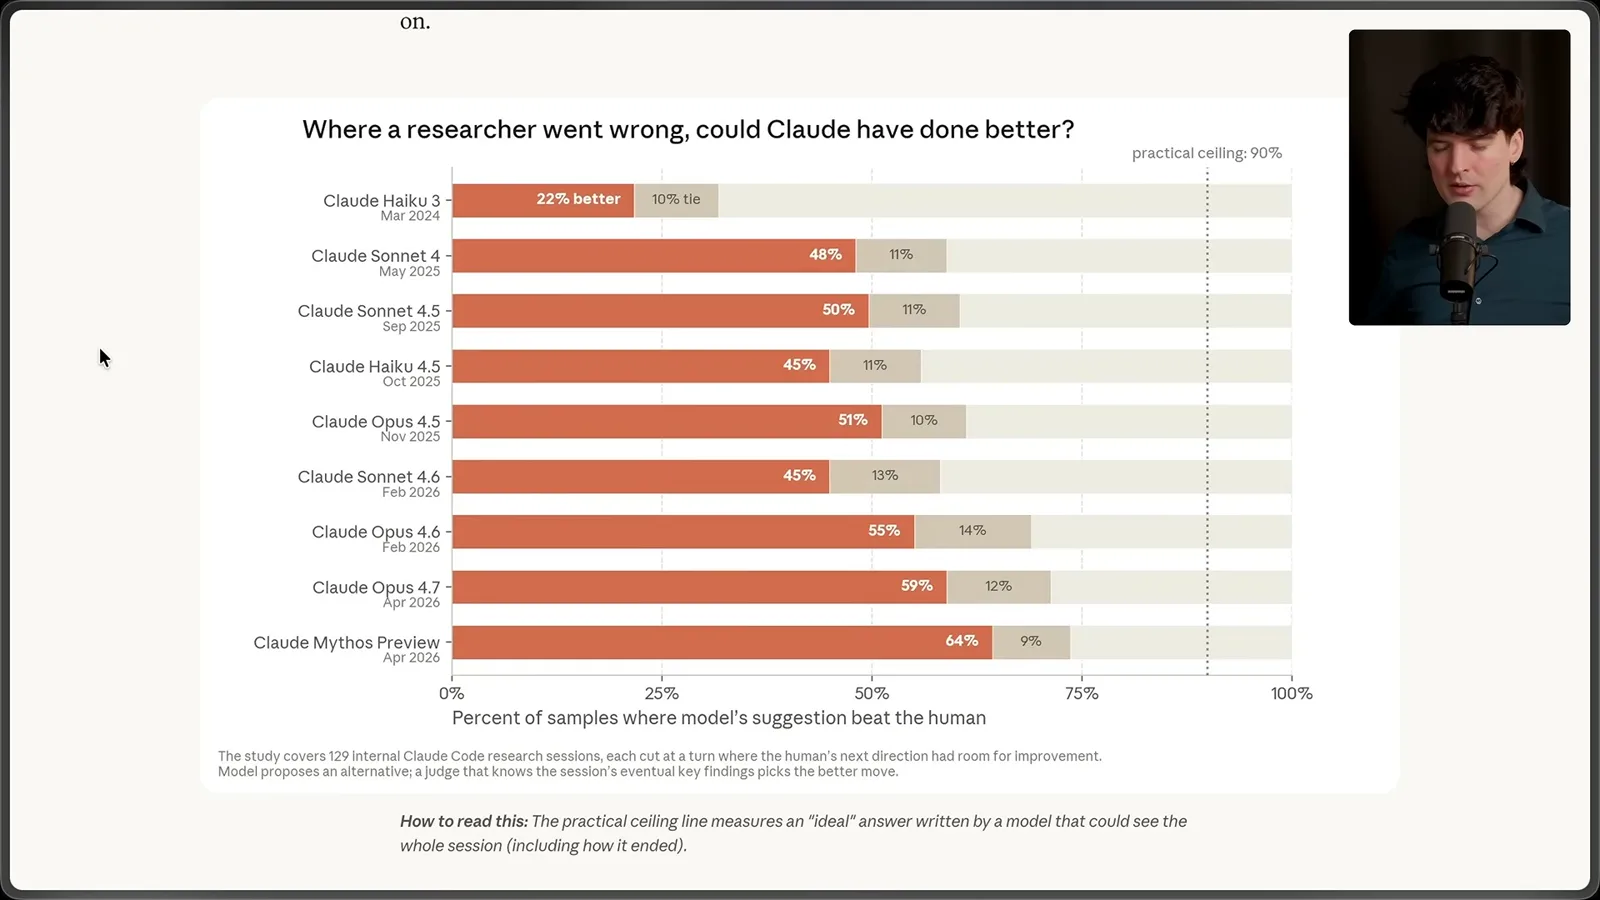
I speculate that proprietary research information may have entered the model and influenced the company’s decision. I do not provide evidence proving that happened, that the information can be extracted, or that it caused the safeguards. Those are conjectures rather than findings of the chart.
John Ready’s article frames invisible degradation as a supply-chain concern: as more ordinary software work involves AI models, developers may not know why an answer was poor. I agree that undisclosed interventions can make evaluation and trust harder. I am glad the specific approach was changed, but remain concerned about the precedent.
More from this channel
 38:47EN
 Theo - t3․gg· Oct 28, 2026Theo’s Long-Running Agent Experiments: Verification, Compute and CostTheo Browne · Ping LabsA skateboard game and two compiler projects show how repeated checks and flexible compute can sustain agent work—and how expensive those loops can become.
 36:07ENTheo - t3․gg· Oct 27, 2026Theo on Token Costs, Coding Agents, and the Price of AI CapabilityTheo Browne · Ping LabsA viral estimate of Lauren's AI spending prompts a closer look at cache pricing, benchmarks, and the changing work of coding agents.
 30:37ENTheo - t3․gg· Oct 26, 2026Theo’s Three Skills for Reviewing and Shipping with Coding AgentsTheo Browne · Ping LabsHow sol-loop, full-send and full-stop encode review, verification and different levels of merge authority.
 0:43ENTheo - t3․gg· Oct 23, 2026Theo Distinguishes Security Vulnerabilities from Active AttacksTheo Browne · Ping LabsA short explanation of why disclosed software flaws and reported attacks are different kinds of security news.
 29:22ENTheo - t3․gg· Oct 22, 2026Theo on Security Vulnerabilities, Stolen API Keys and AITheo Browne · Ping LabsA look at the gap between vulnerability disclosure and patching, and a speculative account of why stolen inference keys may be valuable.
 31:13ENTheo - t3․gg· Oct 20, 2026Theo on Why Smarter Models Help More Than DevelopersTheo Browne · Ping LabsFrom game modifications to compiler experiments, Theo revisits his assumptions about who benefits from more capable AI.