In 30 seconds
Nacho Martinez explains the components around a model that make up an agent harness, including storage, memory, context assembly and tool execution. His workshop uses synthetic banking transactions to illustrate how an agent can surface potential anti-money-laundering cases for people to review. He discusses file and database tradeoffs, retrieval, bounded loops and reusable skills. The demonstration is not evidence of production accuracy, and flags are not proof of wrongdoing.
- 1The agent stackThe workshop focuses on data, memory, tools and orchestration around the model.
- 2Shared stateFiles and transactional databases have different concurrency tradeoffs.
- 3Memory categoriesMartinez distinguishes episodic, procedural and semantic information.
- 4A bounded agent loopThe example assembles context, calls a model and dispatches tools within limits.
- 5Retrieve skills on demandA skillbox searches for relevant capabilities instead of loading everything.
- 6Human reviewThe simulated AML system flags activity rather than automatically blocking accounts.
Takeaways
- A harness controls the context, tools and memory around a model.
- Choose files or transactional storage according to the concurrency and data needs.
- Retrieve relevant memory and capabilities rather than assuming everything fits in context.
- Bound agent loops and enforce approval for consequential actions.
- Use synthetic AML flags as investigation prompts, not automatic conclusions.
- Evaluate retrieval and safeguards in the actual application.
Read the edited text by chapter
The workshop and agent stack
Martinez introduces the simulated bank and harness components.
Nacho Martinez introduces a hands-on workshop on agent harnesses. The example is a simulated bank whose agent examines transactions and flags cases for human review.
Martinez is an AI developer advocate and data scientist. He plans to cover the agent stack, memory, context engineering and how a harness surrounds a model.
He uses anti-money-laundering as a motivating problem. A bank may encounter large numbers of transactions that require investigation; a flag should prompt review, not be treated as proof of wrongdoing.
Long-running agents need more than a model call: the application must manage context, tools and stored information. Martinez argues that these surrounding components are a useful place for engineers to experiment.
His fictional example includes several suspicious transaction patterns. The aim is to surface possible issues to bank staff, who can then investigate them.
He divides the agent stack into an application, data, model, infrastructure and compute. This workshop focuses on the data and orchestration components that application builders can control.
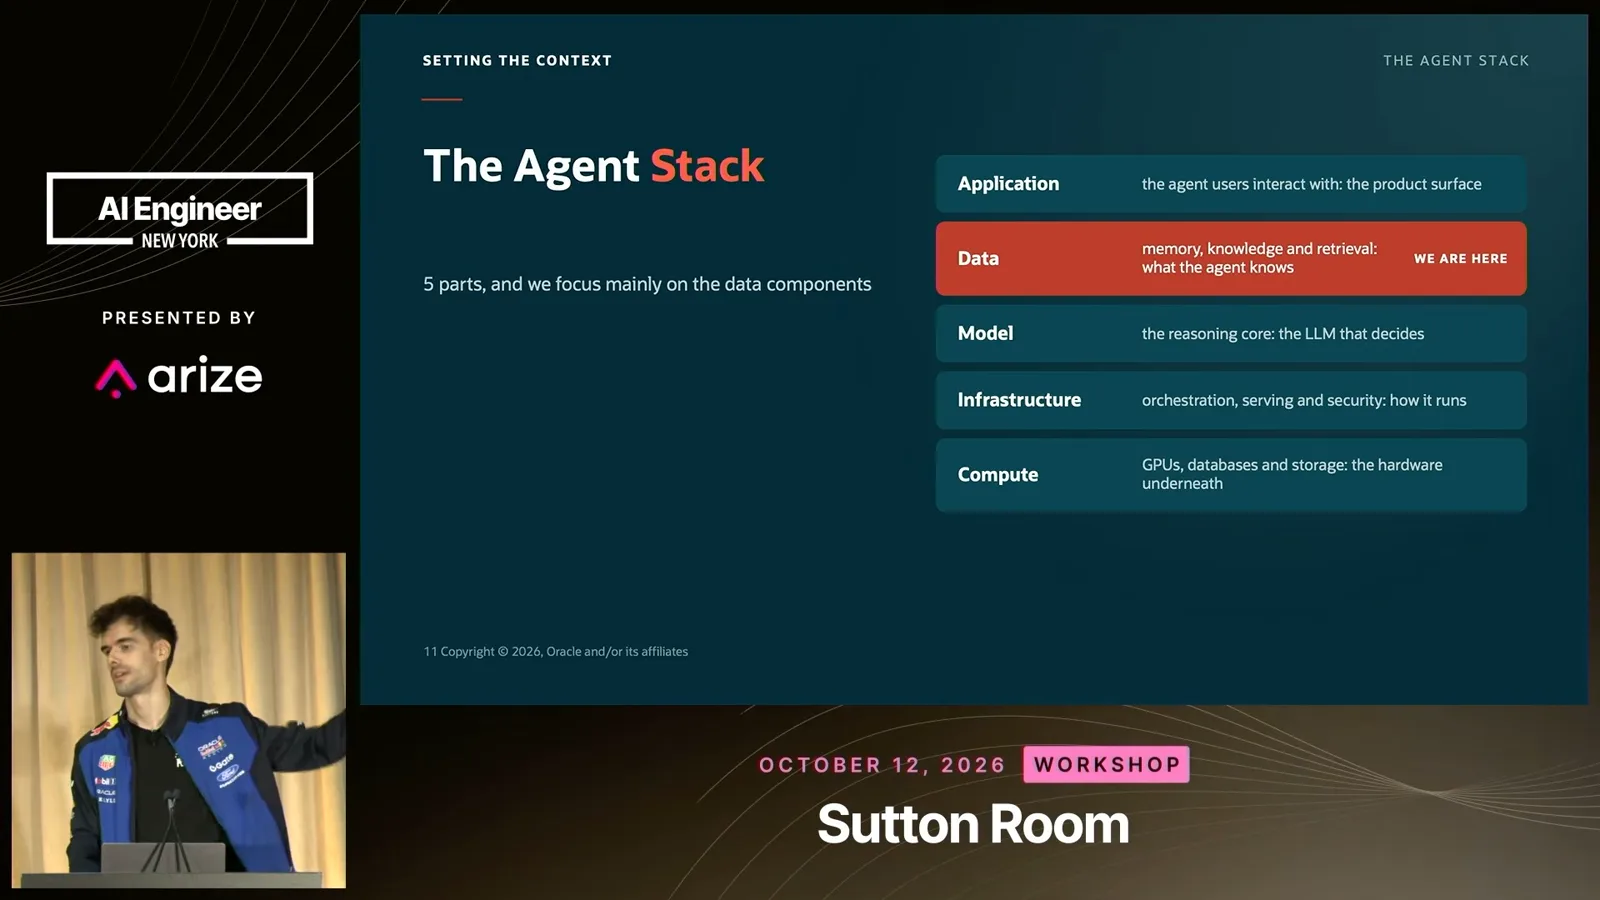
The data layer includes an agent loop, connections to external sources, memory, context management, tools and skills. These components decide what information and capabilities are available at each step.
Martinez distinguishes chatbots, retrieval applications, fixed workflows and agents. He describes modern agentic systems as often combining automation with a degree of autonomy.
He uses a human analogy: a model performs reasoning, tools let the system act, and stored information supports recall. The analogy is a way to organize the components, not a claim that the system thinks like a person.
He calls the surrounding scaffolding the harness. Different choices for memory, inputs and tools can change how the same model performs on a task, so the surrounding system should be evaluated too.
Design choices include storage, retrieval, memory categories, the agent loop and context assembly. The right arrangement depends on what the application has to do and what evidence it must retain.
Storage, memory and context
He compares files and databases and describes memory categories.
On files versus databases, Martinez recommends choosing according to the problem. Files are useful for unstructured material; databases can provide transactions and concurrency controls for shared state.
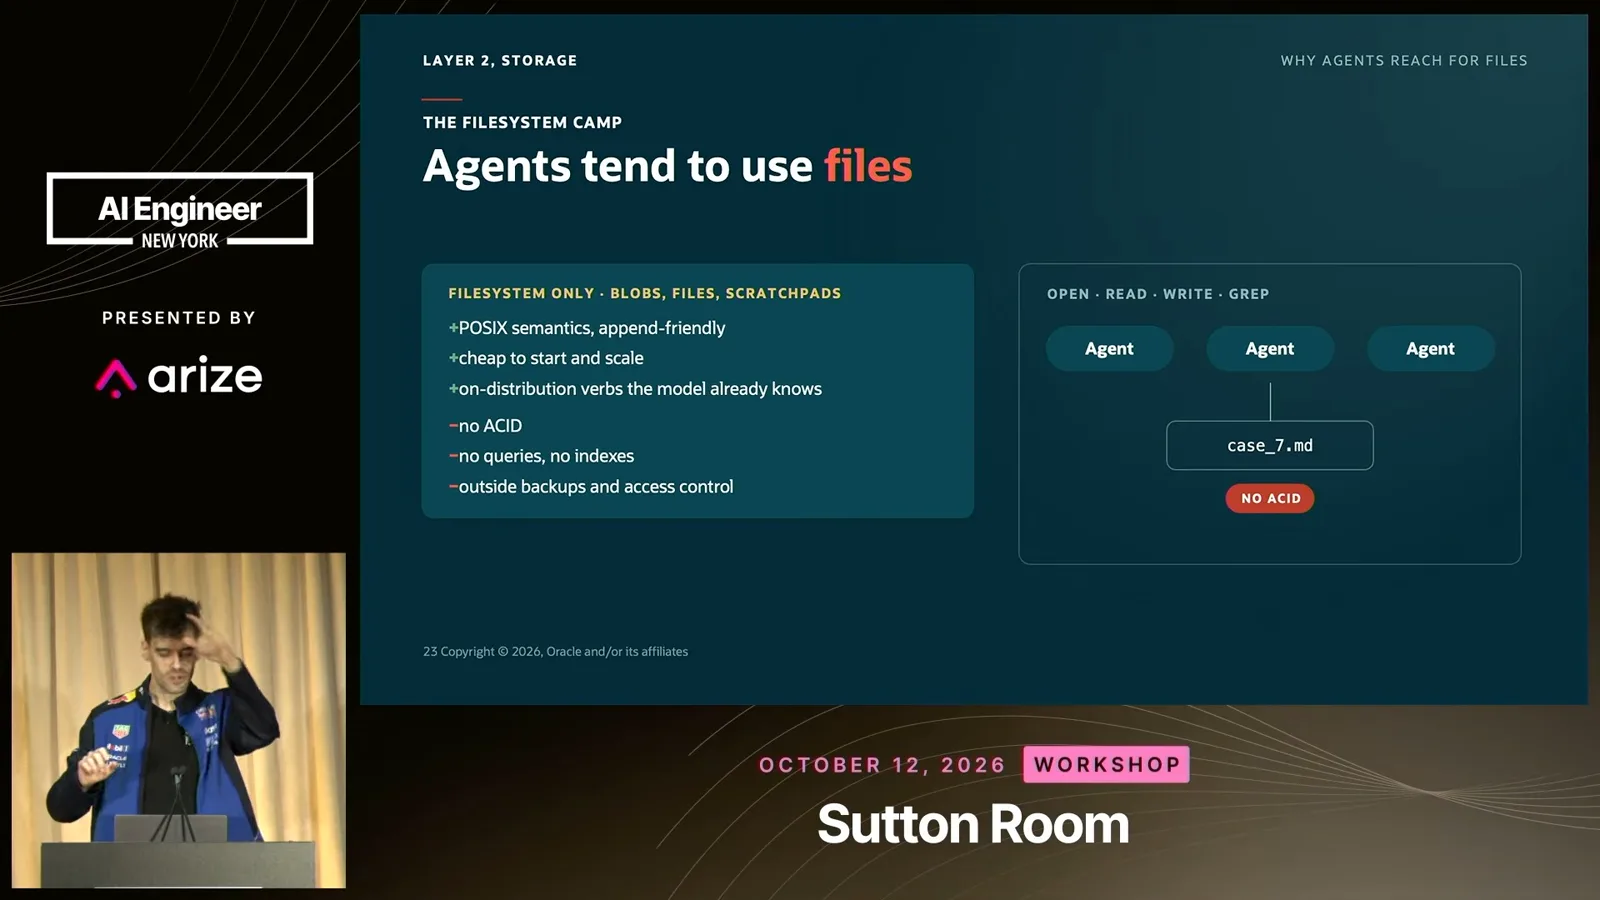
Several agents writing the same file can encounter conflicting updates. Worktrees isolate changes in some development workflows, while transactional storage offers another way to coordinate shared writes.
Memory design includes deciding what to save, how to refine it and when to retrieve it. Martinez distinguishes short-term context from information retained beyond a single conversation.
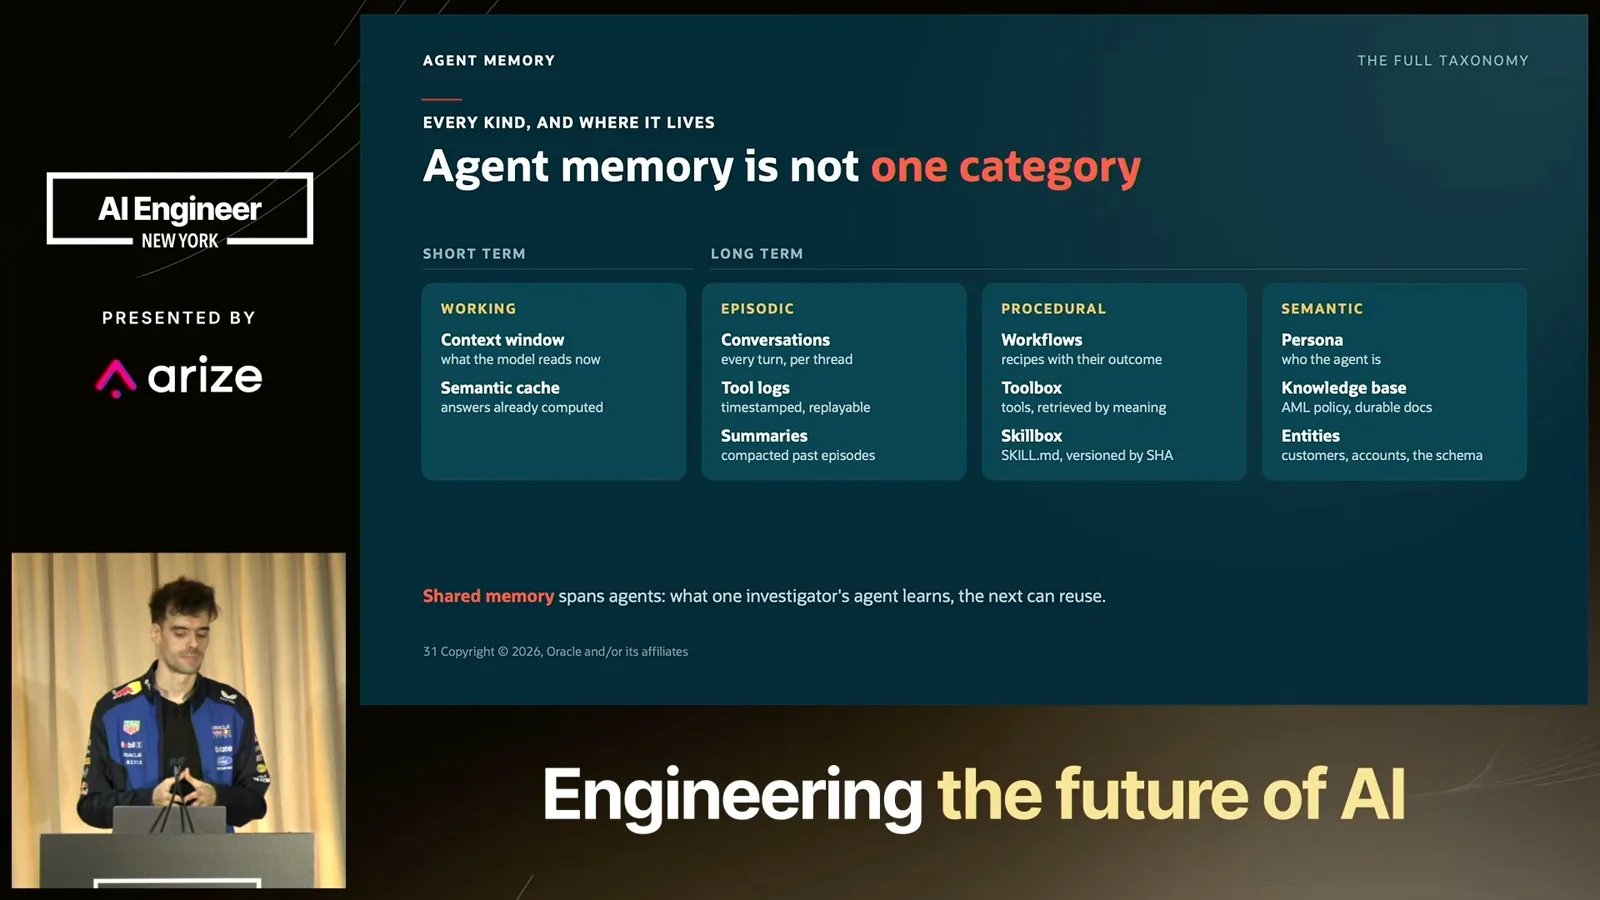
His proposed long-term categories include episodic history such as conversations and tool logs, procedural memory such as skills and workflows, and semantic information such as preferences and domain knowledge.
Context windows have limits, and relevant information can be harder to use amid long histories. The effect varies by model and task; a shorter context is not automatically better if it omits necessary evidence.
Summarization can condense a conversation before a later turn. Another approach stores material outside the immediate context and retrieves it when needed; both approaches can lose or fail to retrieve important details.
Agent loops and skills
He discusses bounded execution and retrieval of relevant capabilities.
The agent loop assembles context from conversations, files, databases, tools and skills, calls the model, dispatches actions and incorporates results. The workshop's loop has bounded iterations and time.
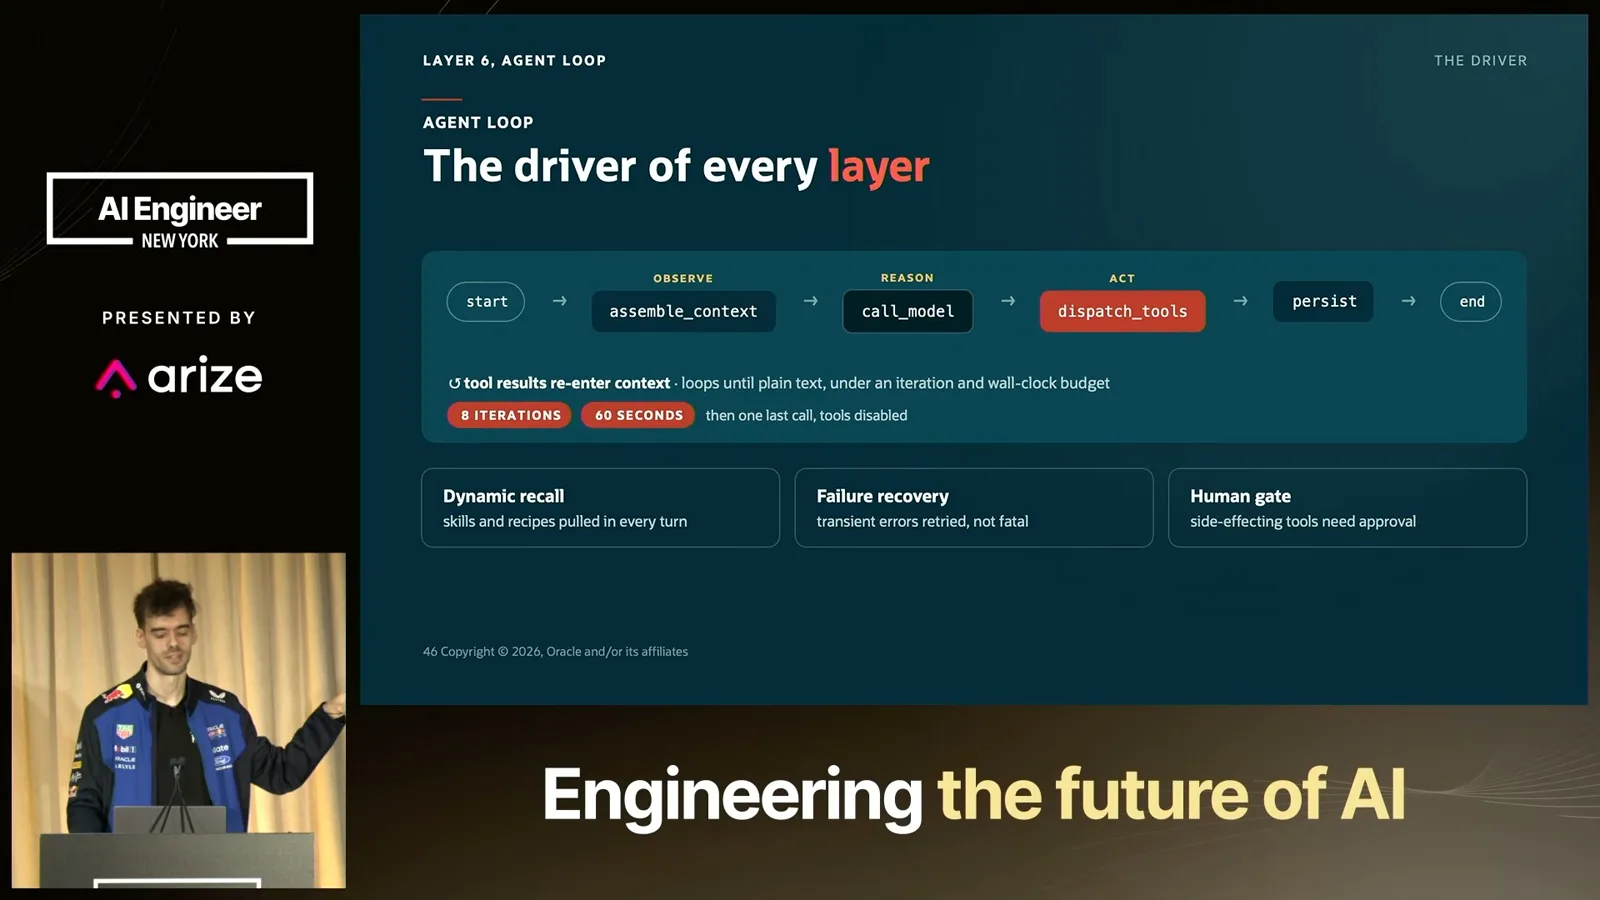
The example uses a maximum of eight iterations and a time budget. The slide also shows a human approval gate for tools with side effects; actual controls need to be enforced by the application.
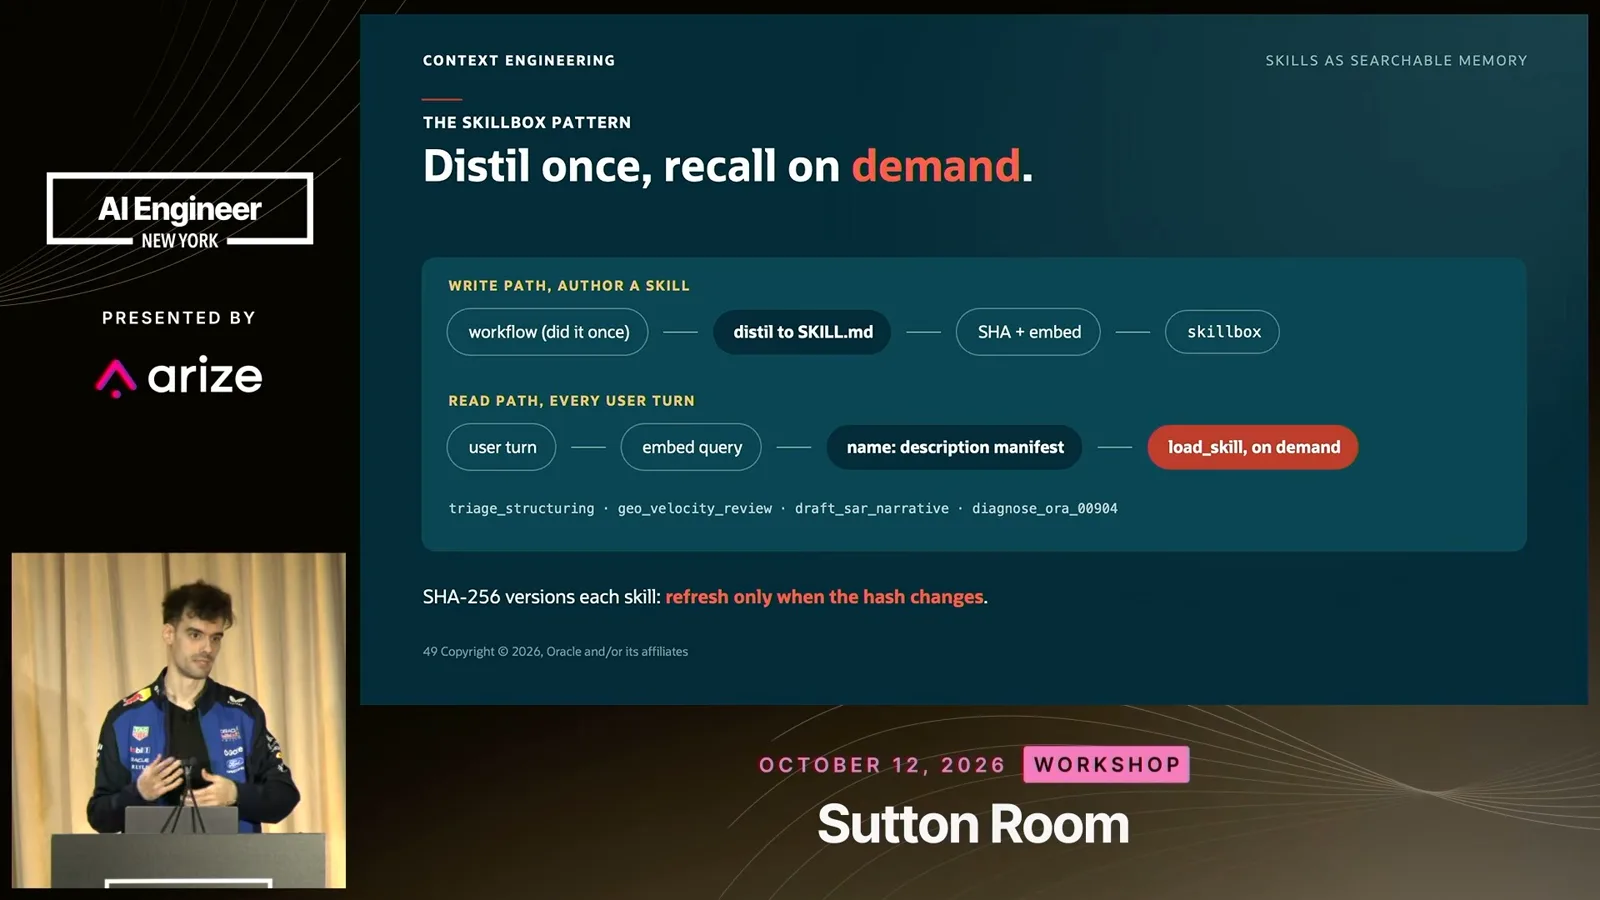
Loading every available skill and tool into every request can consume substantial context. Martinez proposes a toolbox and skillbox: index descriptions and retrieve relevant items for the current task.
Vector similarity can help find candidate tools or skills, after which the agent loads the selected material. Retrieval is imperfect, so the choice and results need testing for the application.
He calls turning successful runs into reusable instructions skill distillation. For example, a team can record a frontend workflow and its preferences in a skill file for later use.
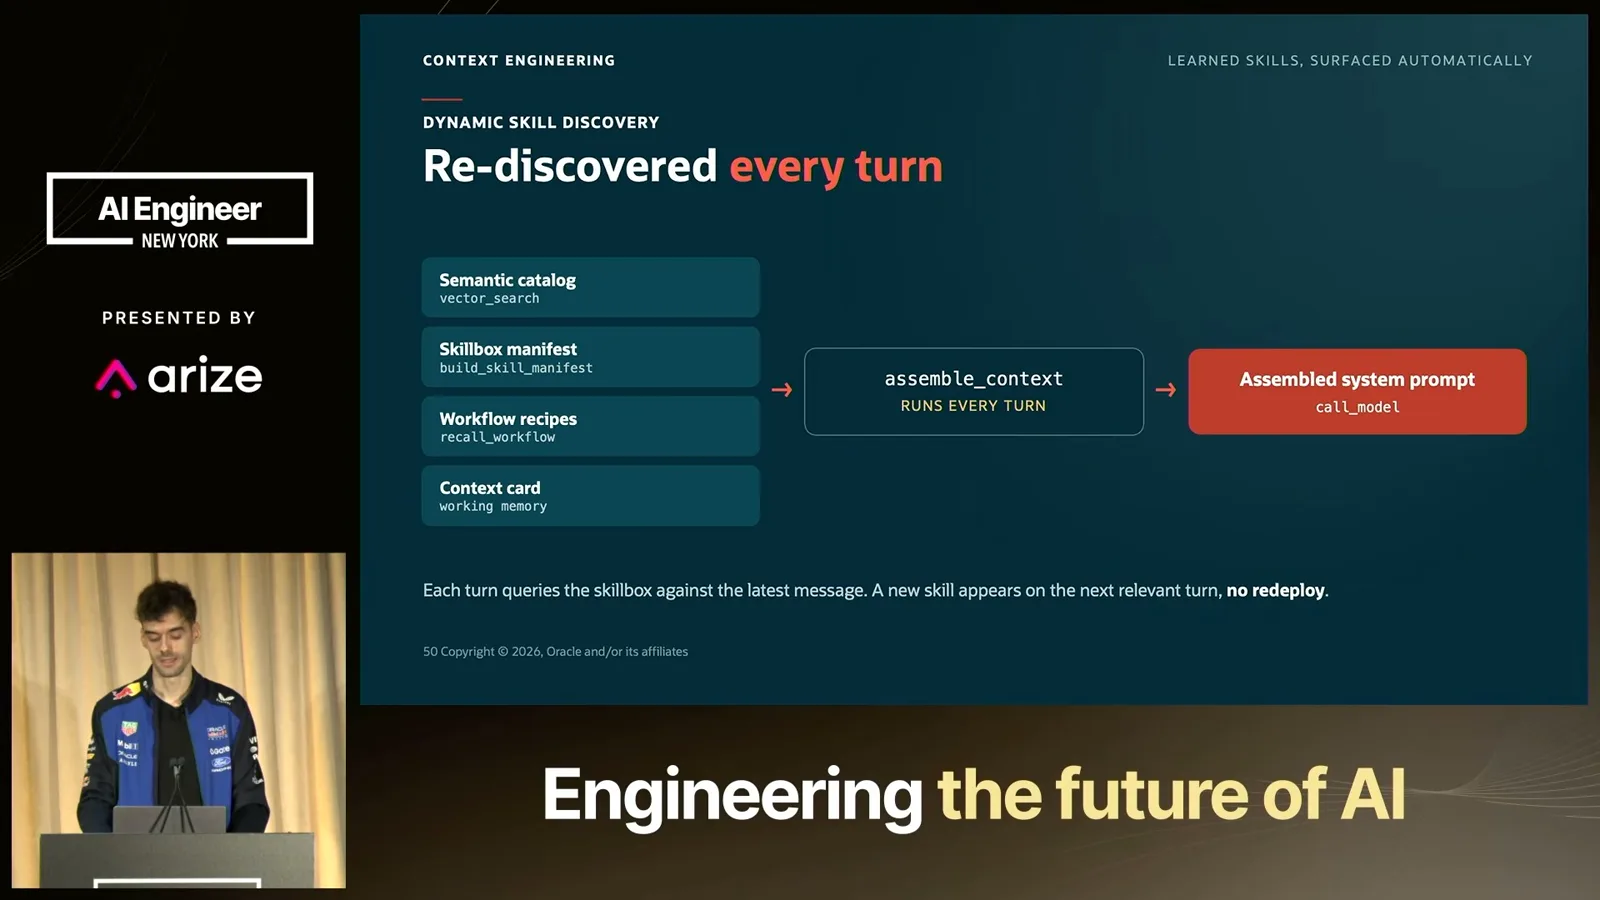
Dynamic discovery can retrieve that skill when a related request arrives. This changes the information supplied to the model; it does not by itself change the model's weights.
Martinez contrasts external memory and retrieval with changing model parameters or embeddings. He focuses the workshop on the external-data approach and notes that the other techniques are separate choices.
He discusses instruction hierarchy as another part of context design: system and application instructions, user requests, and tool or retrieved content play different roles. Exact behavior depends on the model and platform.
The simulated AML application
The demo flags synthetic transactions for human review.
The AML demo is designed to flag activity for later human inspection. Martinez stresses that it should not simply block accounts based on an automated suspicion, because an incorrect action could seriously affect a person.
The application displays a stream of synthetic transactions, some ordinary and some flagged, together with a view of the agent's context and stored data. The workshop is a demonstration, not evidence of production effectiveness.
The agent searches available knowledge and uses tools to assemble evidence for a suspicious-activity analysis. A real deployment would need validation, access controls and human review appropriate to its setting.
In the notebook, participants inspect the components and complete exercises. Martinez shows a model connection and database setup, then invites questions about the memory architecture.
Questions on retrieval and design
He answers questions about memory, tools, hybrid search and custom harnesses.
Asked whether episodic memory could confuse an agent with old conversations, he says architecture and retrieval determine what is recalled. Separation helps organize information but does not eliminate conflicts automatically.
He discusses indexing third-party skills or tools by embedding their descriptions, so the loop can select candidates without loading every item. Access and trust still need to be considered for external capabilities.
He also discusses context and caching costs. Exact request sizes and caching behavior vary by provider, configuration and workload, so the numbers in his illustration should not be treated as universal.
In this workshop, context assembly retrieves a limited number of relevant tools and skills from separate vector stores. The example uses a default of three candidates.
A reranker could further order the candidates or help select fewer items when only one is needed. Martinez presents it as an optional refinement rather than a component already used in the demo.
For memory, he recommends starting simply: keep current context and a long-term store, then promote selected information when it is worth retaining. More elaborate categories can be added when justified.
The loop can retrieve stored memories before reasoning, using relevance or a similarity threshold. A threshold and index need evaluation because relevant context may be missed or irrelevant content returned.
He discusses database access through MCP and prebuilt queries as one way to expose known operations. Restricting the available operations can help, but does not remove the need for authorization and input validation.
Keyword and semantic retrieval have different strengths. Martinez describes hybrid search and combining rankings; its actual quality depends on the data, queries and evaluation.
He says a custom harness need not reproduce a full general-purpose coding agent. A smaller harness can be designed around the specific data, tools and constraints of a domain.
Different problems need different budgets and memory strategies. An unattended long-running research task might need context management, while this demonstration limits its loop to eight steps.
Martinez encourages participants to work through the notebook and ask questions. He says the workshop environment can also be explored after the event, subject to its actual availability and terms.
More from this channel
 21:32EN
 AI Engineer· Oct 29, 2026Shy Ruparel on AI agent reliability and recovery after failuresShy Ruparel · TemporalTemporal’s survey finds a gap between frequent agent use and dependable deployment. Ruparel demonstrates a synthetic payout workflow that resumes after workers stop.
 14:50ENAI Engineer· Oct 29, 2026Cole Gannaway on code review, cross-repository risk and AI software factoriesCole Gannaway · QodoA one-line rename can pass local checks while affecting distant clients. Qodo’s Cole Gannaway explains how review context, shared rules and independent agents can expose those risks.
 11:47ENAI Engineer· Oct 29, 2026Revolut’s David Abitbol on self-hosting AI coding models at scaleDavid Abitbol · RevolutAbitbol shares engineering delivery trends, GPU-serving costs and latency tuning, then describes controls for operating the tools in a regulated bank.
 21:47ENAI Engineer· Oct 28, 2026Patrick Smyth on Open-Source Supply Chain Security in the AI EraPatrick Smyth · ChainguardChainguard’s Patrick Smyth discusses faster exploitation, malware in dependencies, zero-days and the expanding attack surface around developer workflows.
 14:09ENAI Engineer· Oct 28, 2026Taylor Luttrell-Williams on Finding Logic Vulnerabilities with SonarQube Hunter AgentTaylor Luttrell-Williams · SonarSonar’s Taylor Luttrell-Williams explains how a security agent maps a codebase, investigates logic flaws and presents validated findings alongside conventional scans.
 16:29ENAI Engineer· Oct 28, 2026Chris Vela on Benchmarking vLLM Configurations with Runpod BenchPodChris Vela · RunpodRunpod’s Chris Vela demonstrates a dashboard for comparing LLM serving configurations and choosing performance settings with workload-specific data.