In 30 seconds
Theo draws on his own coding workflow to compare Claude Fable 5 and GPT-5.6 Sol. He favors Fable’s judgment and design ideas, but frequently starts with Sol for cost, persistence and practical execution. His examples are observations rather than controlled comparisons, and the pricing and access discussion reflects July 2026.
- 1Usage is not a controlled comparisonThe estimates cover different models and workloads, including one unusually expensive rewrite.
- 2Compare quality, token use and costThe charts show different task scores and spending at particular benchmark settings.
- 3Design versus diligenceTheo prefers Fable for visual exploration and often favors Sol for persistent execution.
- 4Agent actions need controlsAnecdotes about destructive actions illustrate the need for permissions, backups and review.
- 5Make requirements reviewableExplicit constraints and multiple mockups helped Theo iterate on a sidebar design.
- 6Choose by taskTheo combines Fable for judgment and planning with Sol for routine or long-running work.
Takeaways
- Benchmark scores, reasoning effort, task cost and elapsed time measure different parts of the trade-off.
- Theo prefers Fable for interpreting intent, visual exploration and changes that need careful judgment.
- He often starts with Sol for routine fixes, computer use and long-running tasks because of its diligence and cost.
- Explicit requirements, review and recoverable backups remain important with either model.
- Evaluate models and subscription plans on representative tasks and current provider terms.
Read the edited text by chapter
Two capable models, different trade-offs
Theo introduces his personal comparison and explains why preference and usage need not match.
I like Fable 5 more than GPT-5.6 Sol, but I use Sol more often. That sounds contradictory until you account for price, speed and the kinds of jobs I hand to each model. Other heavy users have reached different conclusions, so this is a comparison of my experience, not a universal ranking.
Both are exceptionally capable coding models, yet their strengths feel different. I want to compare the quality of their work, how they follow instructions, their costs and where those differences matter in a real workflow.
My perspective comes from extensive use rather than an identical controlled test. The examples are useful for understanding my choices, but they cannot establish that one model will win for every team or task.
Cost, benchmarks and speed
Usage reports and benchmark charts illustrate the trade-offs, with important limits on comparisons.
First, cost. My usage report for the first 15 days of July shows an estimated $10,775 in inference, about $6,175 through Codex and $4,547 through Claude. Those are estimated usage values in my tooling, not a claim that I paid those amounts as a single API bill.
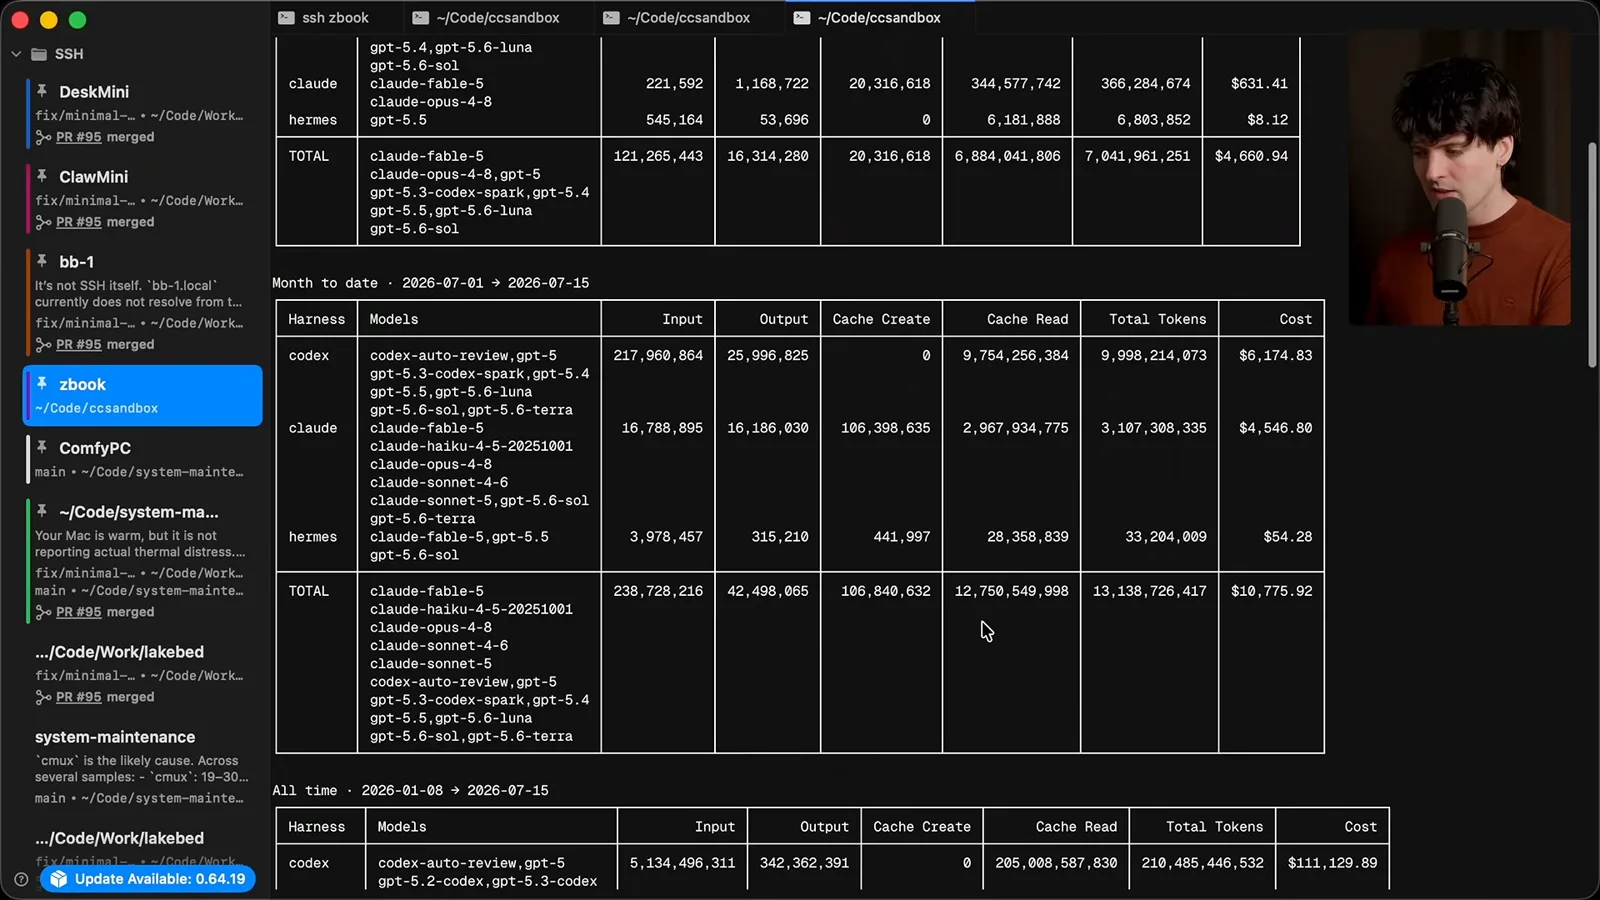
The totals also cover multiple models and different workloads. A particularly long experiment rewriting a TypeScript project in Rust used roughly $4,000 of estimated inference by itself. You cannot divide those totals and call the result a fair model comparison.
I use subscriptions as well as metered services, and the economics affect which model I start with. Subscription prices, included usage, supported tools and provider rules change; my setup and the amounts in this recording are a snapshot, not a promise of unlimited access.
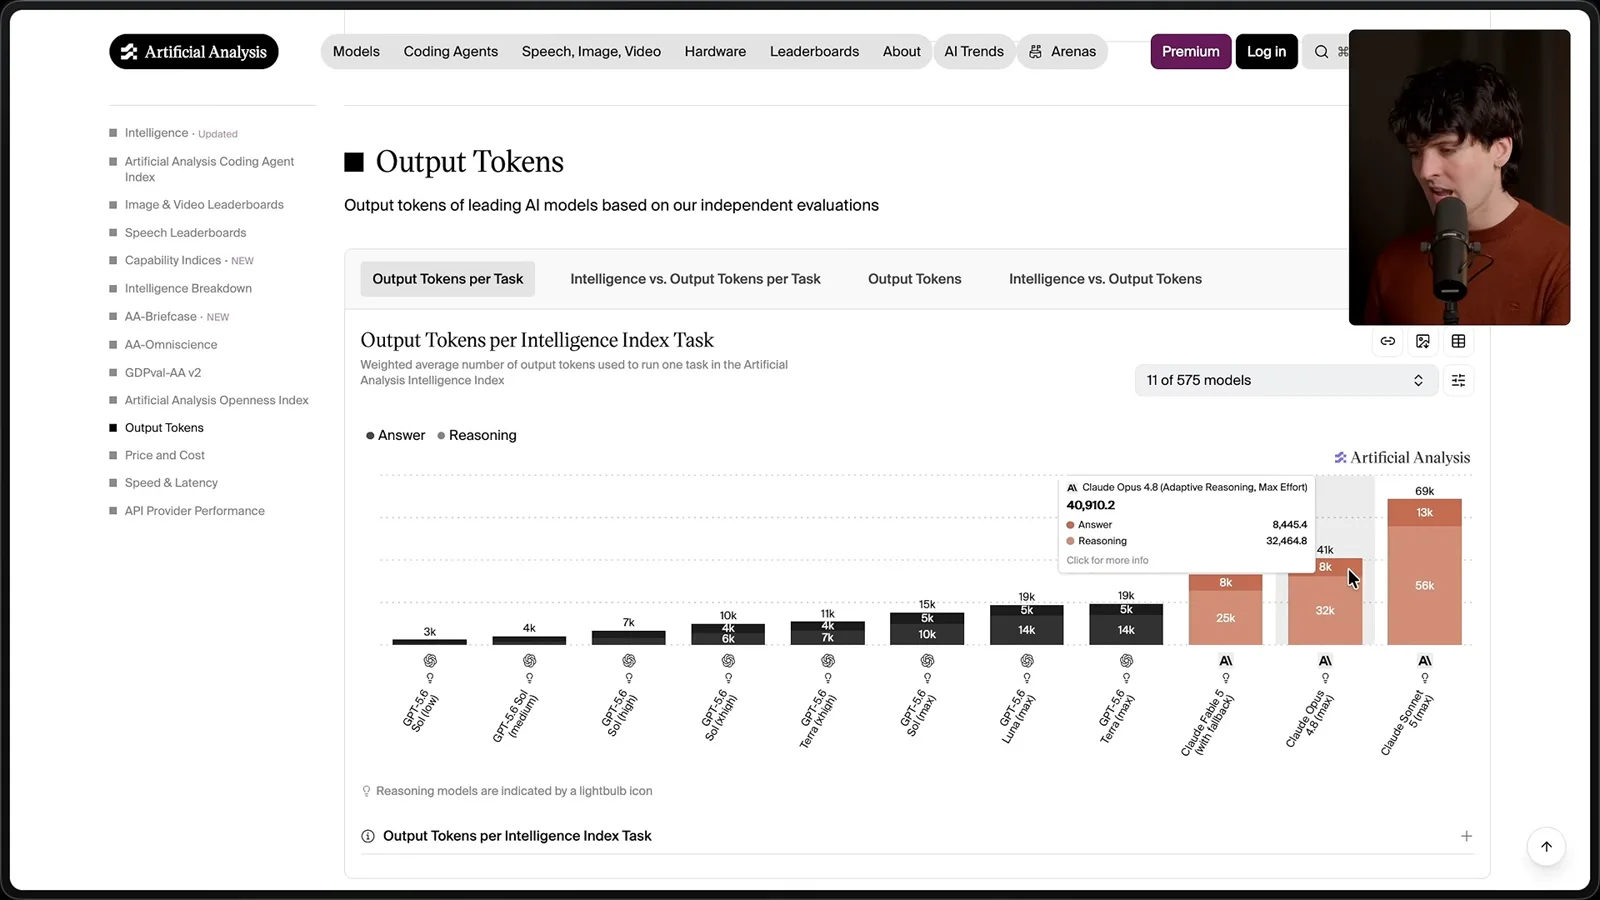
Artificial Analysis illustrates another cost driver: how many output tokens a model spends on a task. In the chart I show, Fable uses around 33,000 on the intelligence-index task, while Sol at maximum effort uses about 15,000; lower effort settings use fewer. More thinking has both a time and a cost.
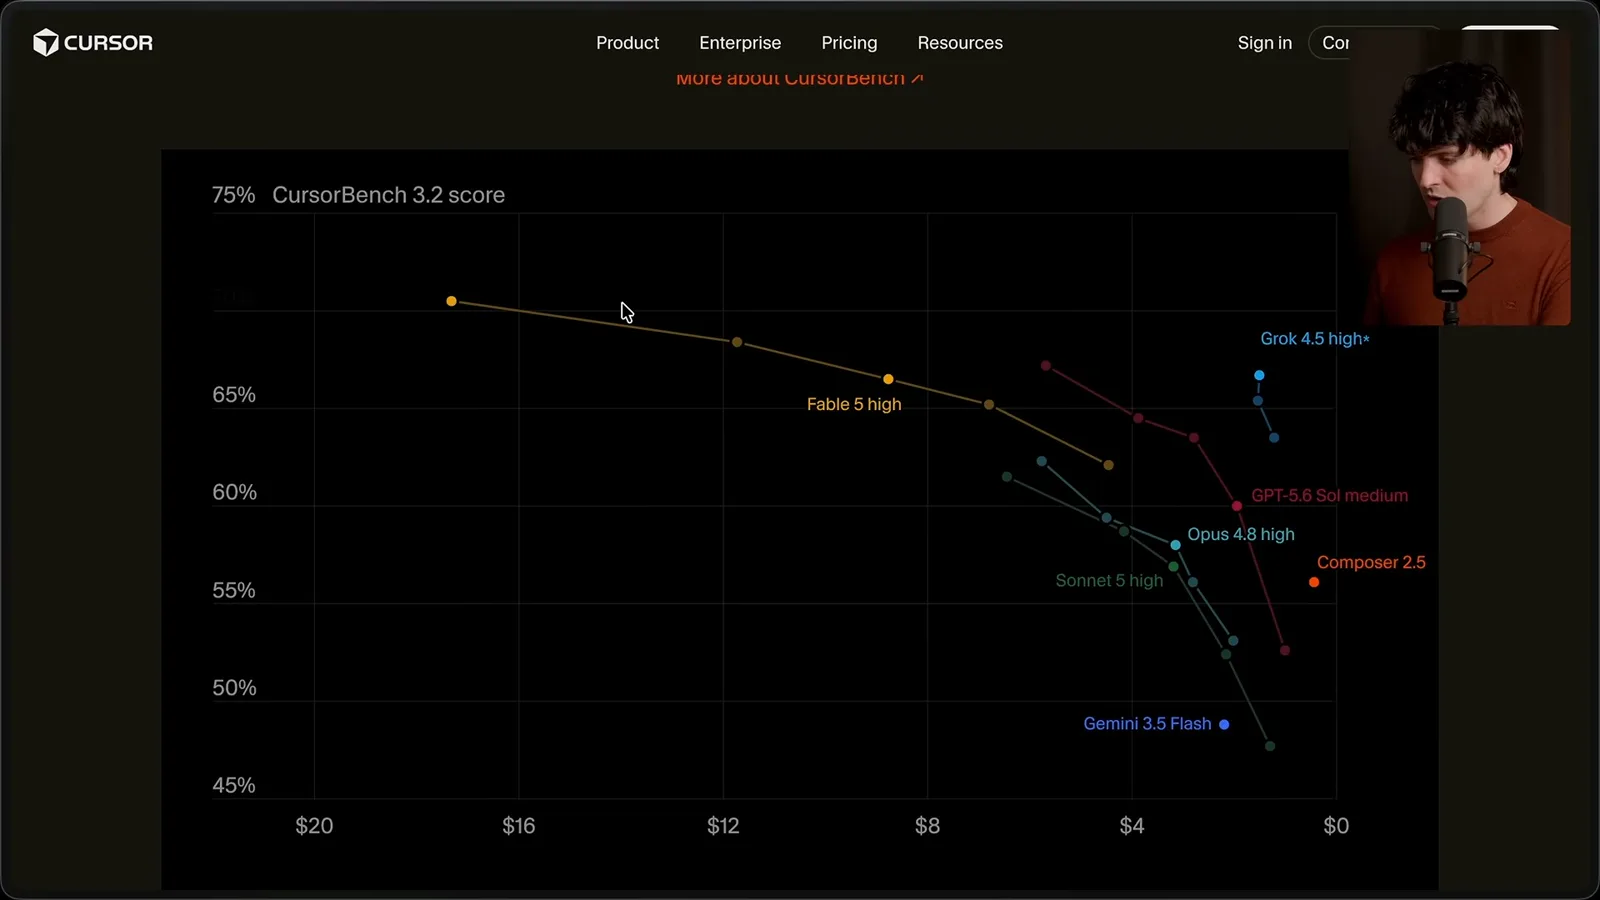
CursorBench plots a different trade-off. The displayed Fable point reaches about 70.5% at roughly $17 per task, while a Sol point is around 67% at roughly $5. These are results for that benchmark and configuration, not a guaranteed price or success rate for your own work.
The benchmark also shows output volume changing with effort. A model can spend substantially more tokens to gain a few points. Whether that extra work is worthwhile depends on the cost of failure and whether the task resembles the benchmark.
Speed is more than tokens per second. The model's reasoning length, tool calls, harness and network connection all contribute to elapsed time. A fast stream does not automatically mean a task finishes first if the model has much more to generate.
I mention a very fast Cerebras offering, but at the time of recording I have not tested it. Advertised throughput is interesting, not evidence of how it performs in my own end-to-end workflow.
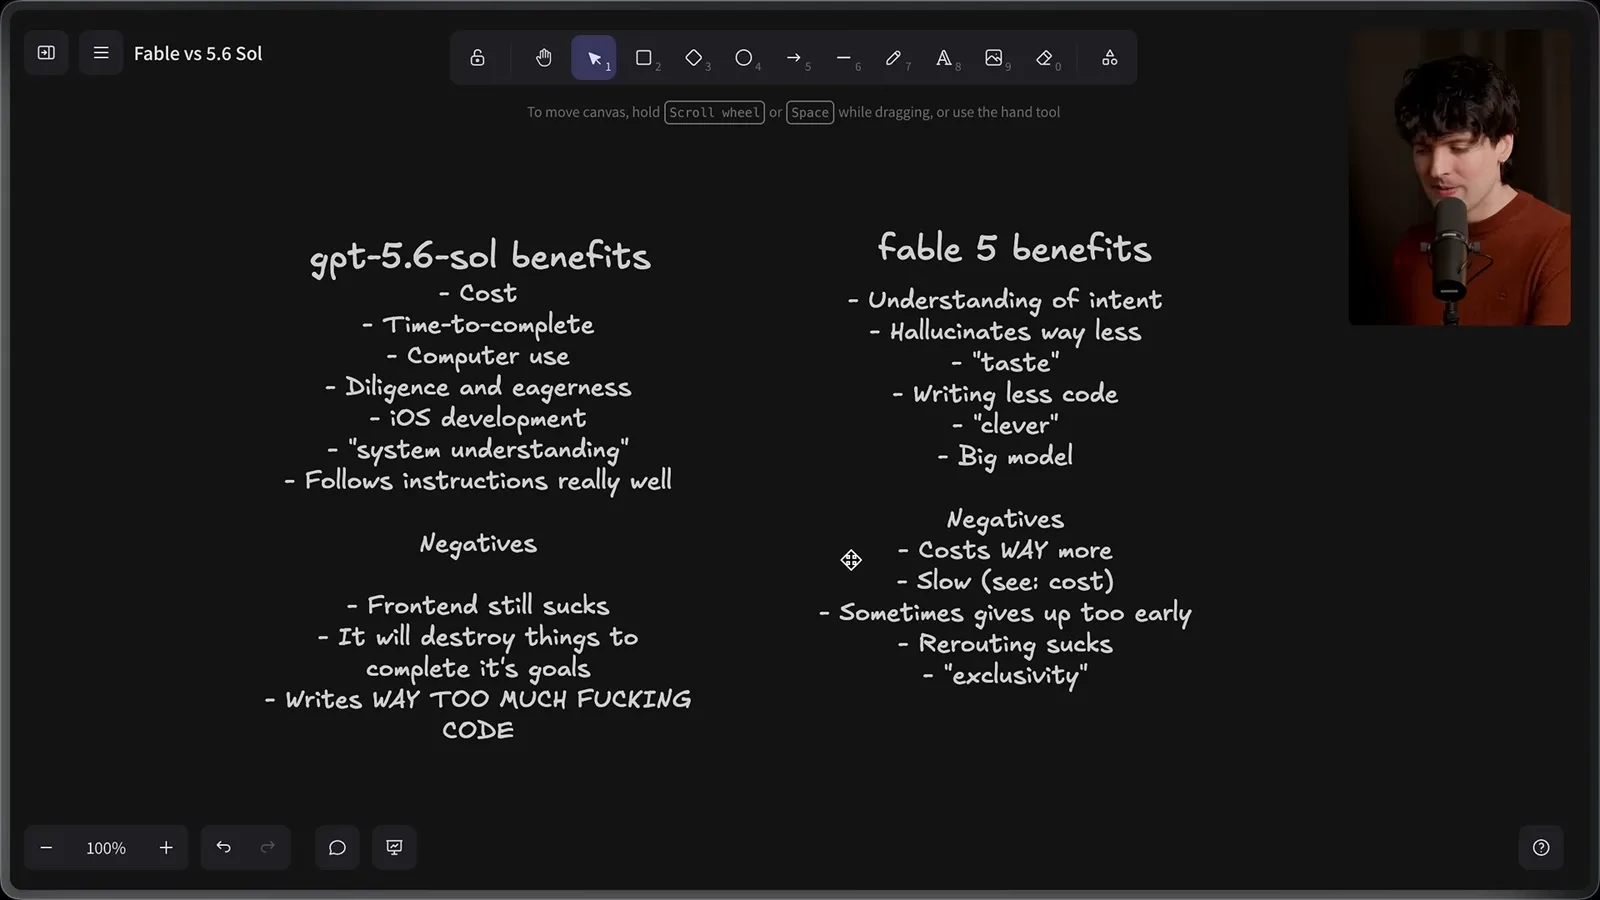
Sol has been particularly useful to me for iOS development and system maintenance. Its lower-effort settings can handle many routine jobs quickly and cheaply, which changes the economics of keeping an agent working throughout the day.
For small jobs, I care about the time until a usable result, not simply how smart the answer sounds. Choosing an effort level and giving the model an appropriate task can matter as much as choosing its name.
Those strengths don't eliminate judgment calls. A faster or cheaper attempt can still require another round of correction, and the right comparison includes the time a person spends inspecting and fixing the output.
Design, persistence and safety
Theo compares frontend work, iOS development and instruction following, including risks from agent actions.
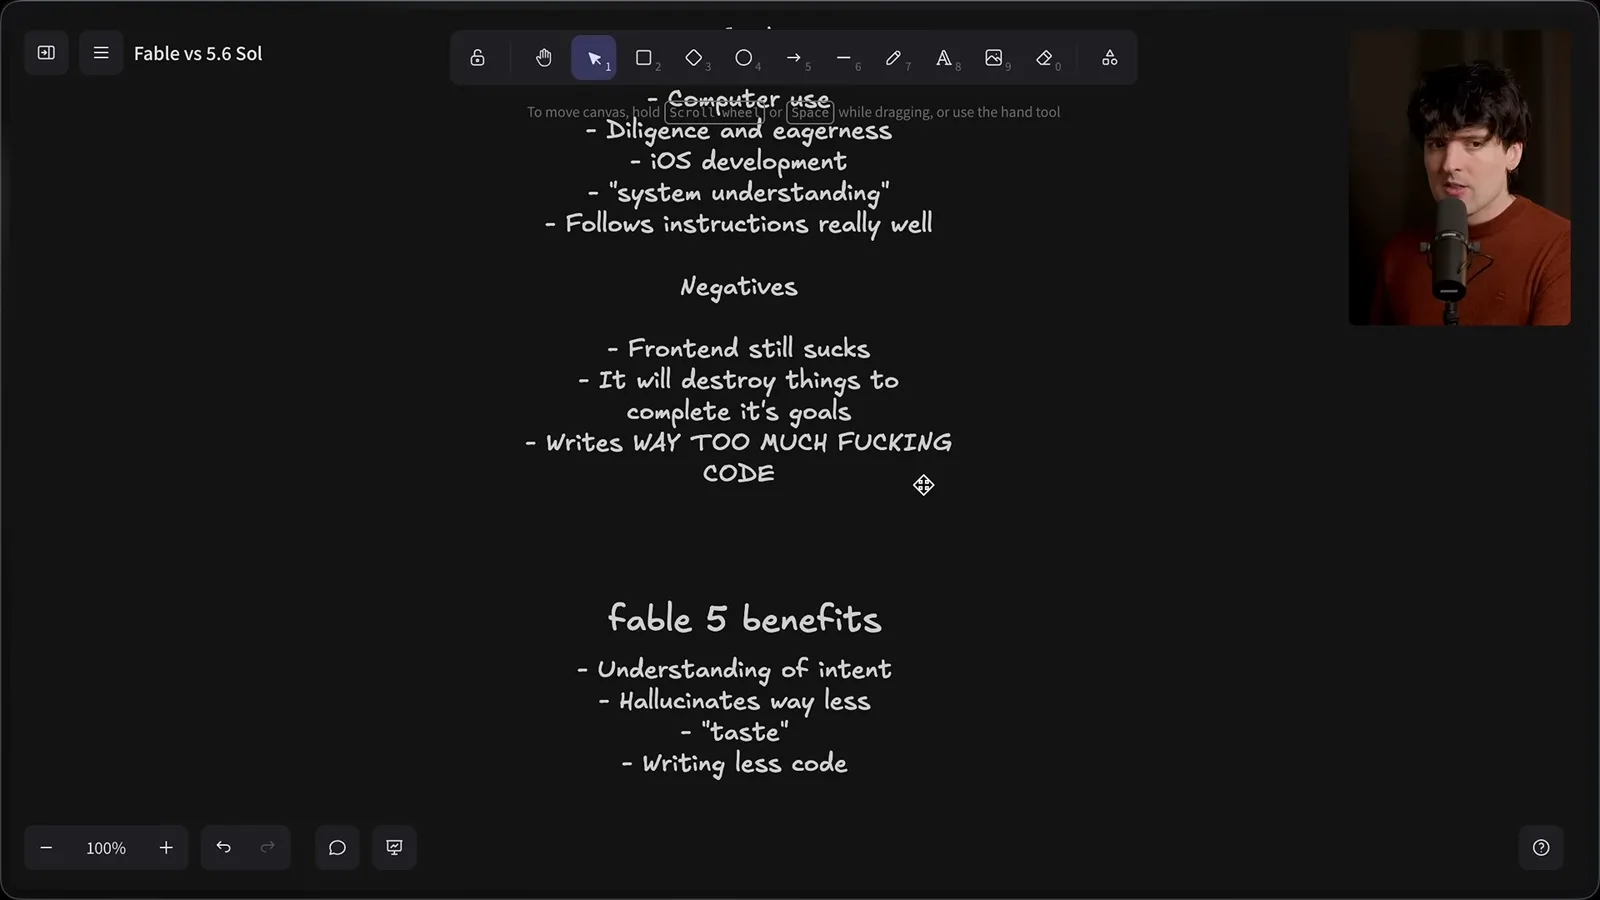
Frontend design is where Fable stands out to me. When I ask it to explore a design from scratch, it more often produces something I find interesting. Sol can follow an established design system well, but its first visual ideas have been less compelling in my experience.
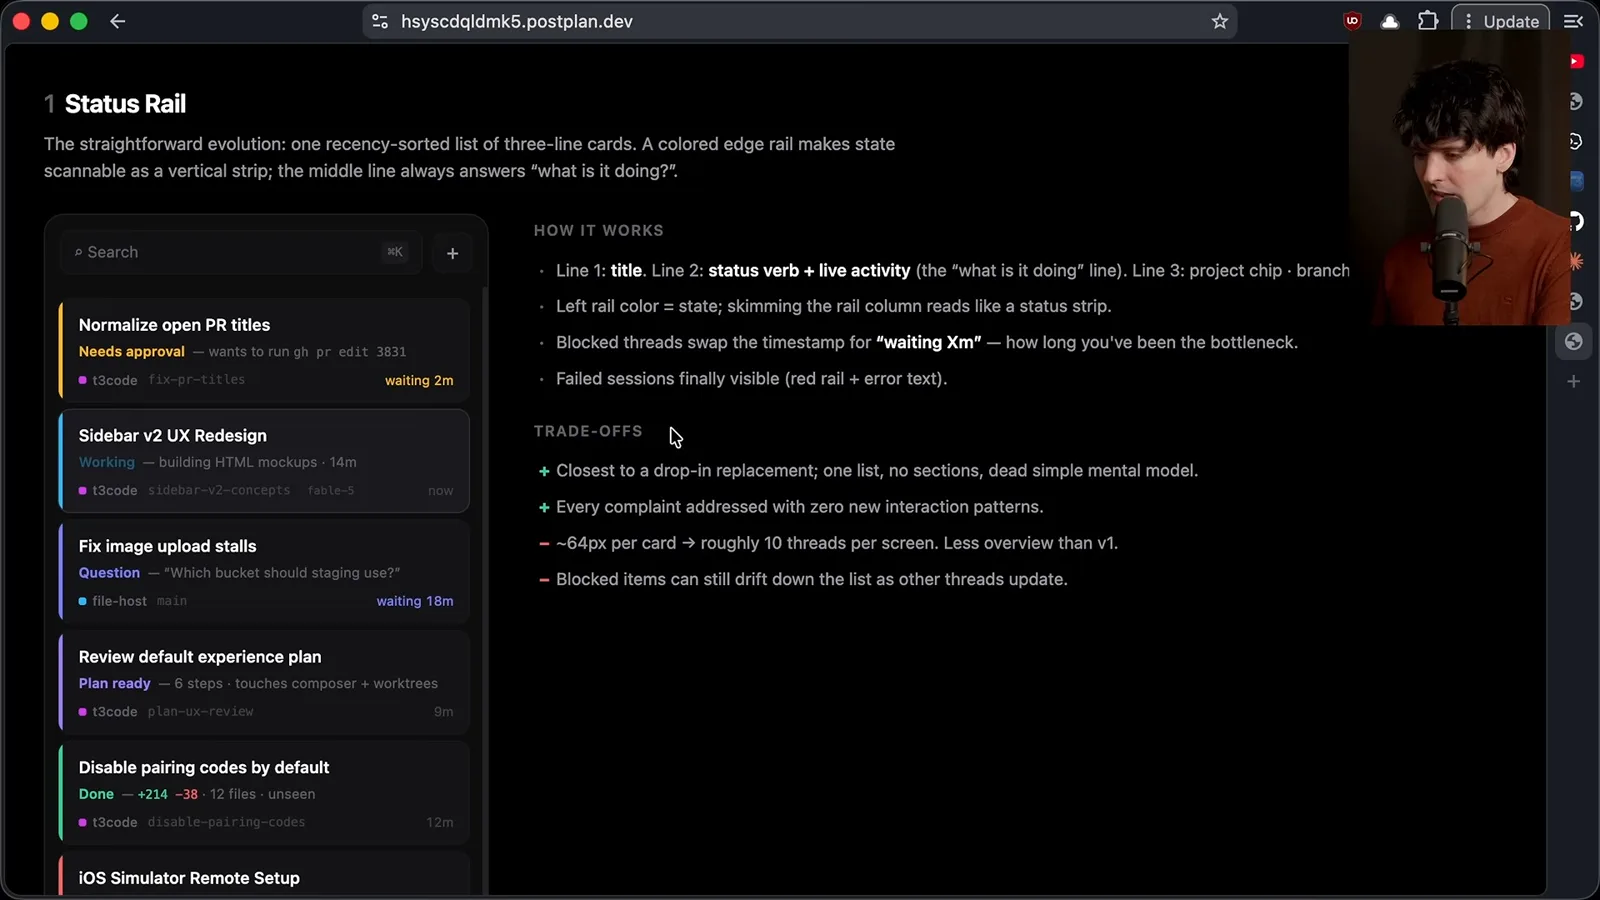
For the T3 Code sidebar, I asked for multiple mockups rather than committing immediately to a single design. Fable produced options and described their trade-offs, giving me concrete alternatives to react to and refine.
The same model is not necessarily my favorite in every interface task. In my iOS work, I have had better results with Sol. That distinction is important: a judgment about visual ideation is not a blanket assessment of all frontend or application work.
Sol is very diligent about instructions. Give it a list and it tends to keep working through the items. I value that persistence when I know exactly what needs to happen, especially for long-running work that involves many small steps.
Persistence can also go wrong. I discuss reports of an agent deleting files while trying to complete a task, including a post alleging extensive local data loss. These are anecdotes, not independently verified comparative safety measurements, but they illustrate why permissions and supervision matter.
An agent can optimize for the immediate instruction while missing the surrounding consequences. Restrict access, keep recoverable backups and review consequential actions regardless of which model is running; a model preference is not a substitute for those controls.
Intent, taste and code quality
He discusses judgment, reviewability, hallucinations and the limits of test-only evaluations.
Fable's strongest advantage, in my experience, is understanding intent. It often infers what I am actually trying to accomplish and produces an answer that fits that goal instead of merely following the literal wording.
I also find that it invents fewer details and is more likely to question an assumption or test an idea. That is my observation from particular tasks, not a measured hallucination rate or a guarantee that its output is correct.
Taste is hard to put on a leaderboard. To me it includes choosing a sensible direction, noticing what makes an interface awkward, and making changes that feel coherent with the product. Those qualities still need a human to evaluate them in context.
Code size is another difference I notice. Sol sometimes writes much more code than I want, while Fable often produces a smaller change. Fewer lines are not automatically better, but a focused diff can be easier to understand and review.
Passing tests is not the same as producing a change a maintainer will merge. I point to work such as FrontierCode that tries to look at mergeability. A useful evaluation should consider the resulting change and review burden, not only whether a test suite turns green.
Fable can be especially helpful as a planner or orchestrator: it helps clarify an ambiguous request, breaks down a problem and suggests a direction. That does not mean every implementation should be delegated to the same model.
Weaknesses and access
Fable can stop early or follow unproductive paths, while price and access shape real workflows.
There are weaknesses on the Fable side too. Sometimes it stops before I think the work is finished; at other times it follows an unproductive line of investigation. A good initial insight is not the same as reliably carrying every task to completion.
Rerouting and access are practical frustrations as well. The model, the provider's subscription rules and the tool or harness through which it is available are separate pieces of the decision; a configuration that works with one service may not be offered by another.
I discuss the subscription restrictions and prices as they stood when I recorded this. They affect my willingness to use the models in different environments, but plans and terms can change. Check the provider's current conditions before deciding how to use a subscription.
The cost difference can push a workflow toward Sol even when I prefer Fable's answer. If the work runs for hours or involves many attempts, the total economics matter more than the price of one isolated response.
Sidebar case study and cross-review
Another developer’s comparison leads into a concrete design iteration and the value of reviewing outputs.
I read Peter Gostev's comparison, which likens Fable to a thoughtful owl and Sol to a dog that keeps hold of a problem. It is a vivid description of his impressions, not a scientific classification of the models.
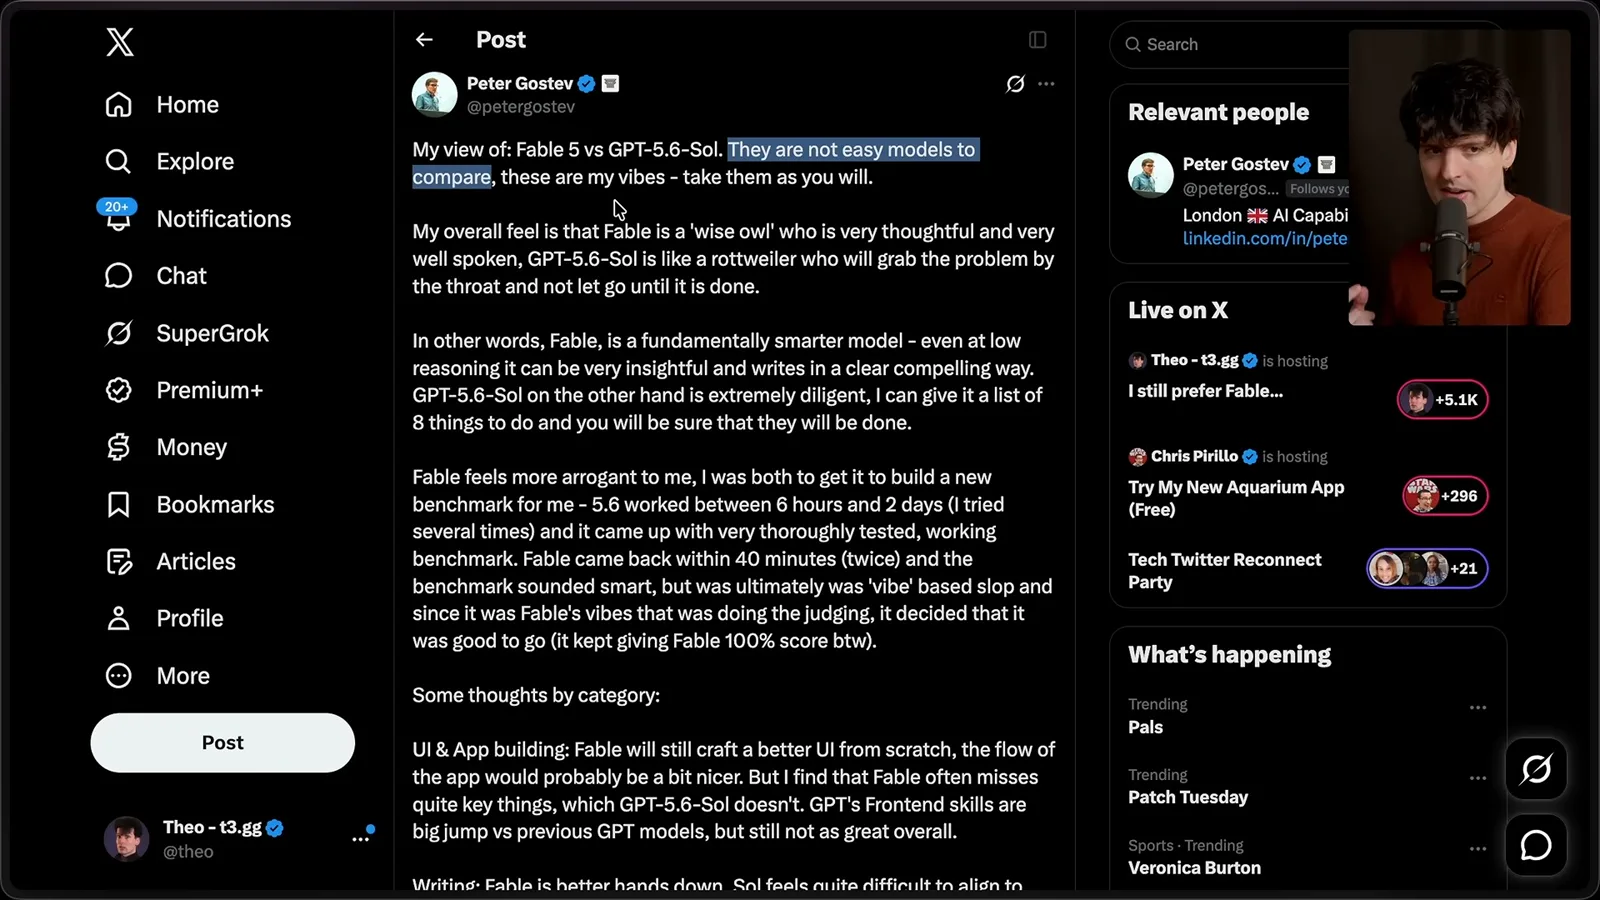
In his example, he asked the models to build a benchmark. He reports that Sol spent longer and produced a more thoroughly tested result, whereas Fable returned quickly with a benchmark that gave itself excellent scores. Self-grading is not independent evidence of quality.
That example resonates with a problem I encountered on the T3 Code sidebar. Fable kept missing a basic requirement even while producing visually appealing designs: I needed the project associated with a thread to remain visible.
I rewrote my instructions as four explicit constraints: indicate the project in the sidebar and in the open thread, use favicons where available, and do not group the sidebar by project. Making the requirements concrete gave me a better basis for judging the next attempt.
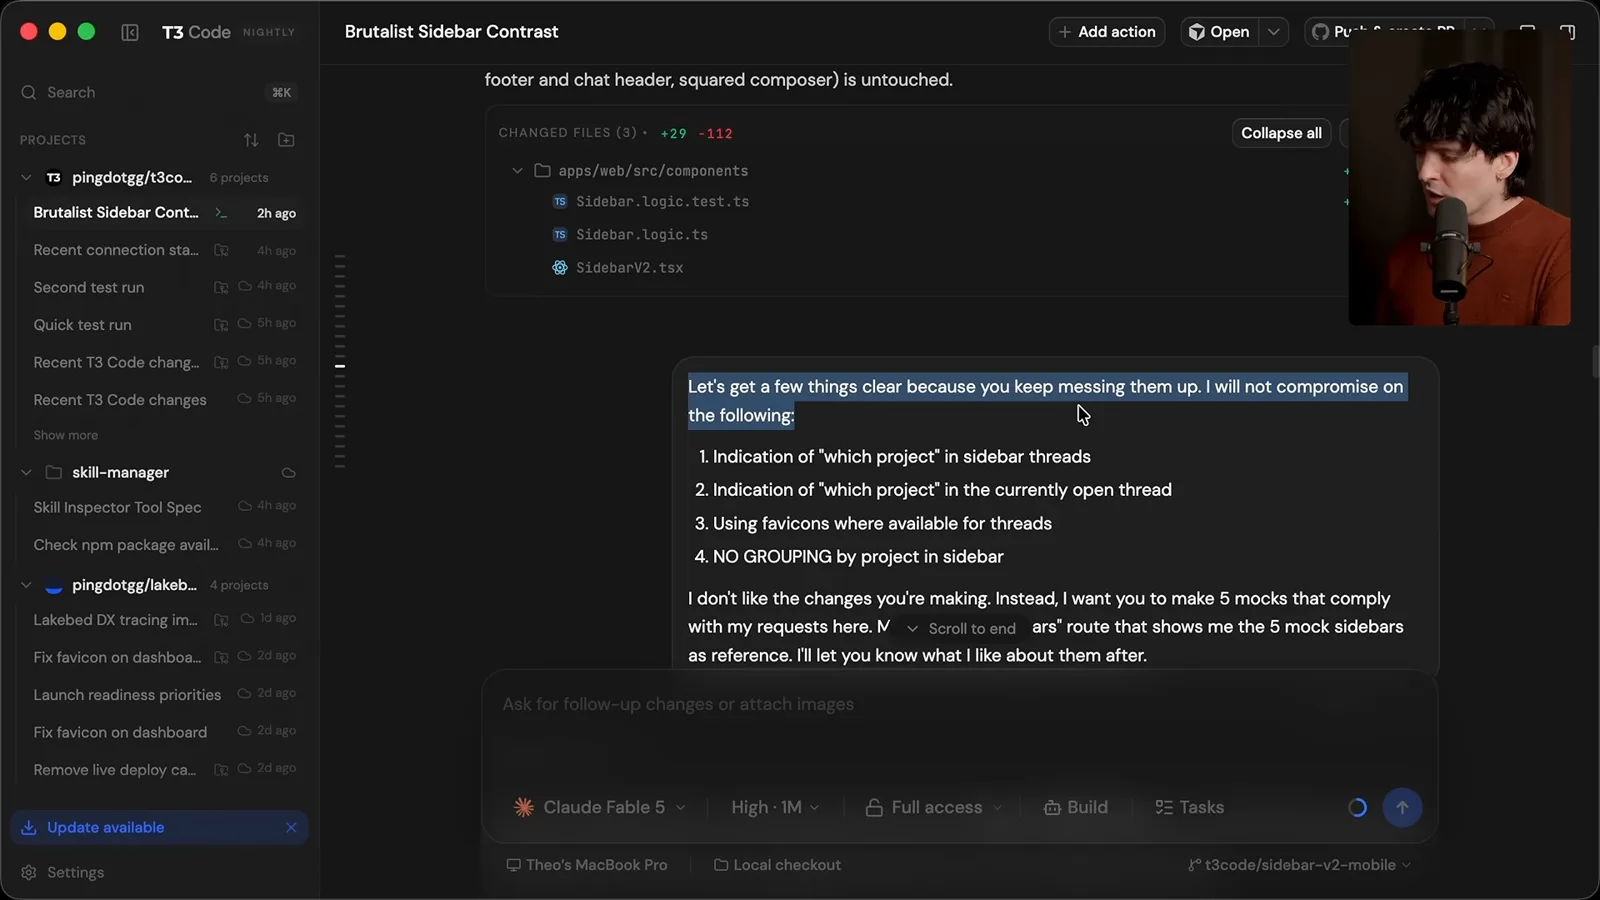
Instead of asking the model to make another final implementation, I requested five mockups. I could compare the options, choose the second one and give further feedback. The interaction turned an unclear disagreement about taste into a reviewable set of choices.
The example cuts both ways: Fable produced designs I liked, yet it repeatedly overlooked requirements. Sol's diligence can help with that kind of checklist, although I often want it to simplify the amount of code it writes.
I use models to review one another's output. One can generate or implement a change, and another can look for mistakes or simplify it. That is a way to get another perspective, not proof that either reviewer will catch every problem.
Computer use is another area where Sol has been valuable to me. In tasks involving applications and existing workflows, it can follow established patterns and keep working through a sequence. It still needs checks, especially when the application can modify valuable files.
A video editor is a useful example of why the stakes differ: an agent might appear to make progress while damaging a project or its source files. Automated interaction needs a way to verify the result and recover from mistakes.
Long-running work and choosing a model
Usage data, task allocation and subscription considerations lead to Theo’s personal conclusion.
Sol's ability to keep going through context compaction has helped on work lasting several days. I have not run an equivalent Fable comparison for the same duration and workload, partly because of cost, so the experience should not be mistaken for a controlled endurance test.
I also look at reports generated from my own model usage. They are useful for seeing where tokens and money went, but the workload mix matters. One unusually large rewrite can dominate the figures and make a simple model-to-model comparison misleading.
Availability and the tools I used were different too. The reports describe my behavior, not a quality-adjusted experiment: they do not tell us how well both models would perform on the same set of tasks at the same settings.
My practical split is to reach for Fable when I particularly care about landing a good change, finding a design, understanding a difficult problem or deciding what I actually want. It is also useful as a second set of eyes to verify and simplify a result.
I tend to start with Sol for long-running work, computer use, quick fixes and tasks where cost matters. I can also ask Fable to think through a problem and then delegate parts of the execution to Sol. The combination exploits the strengths I see in each.
This is a personal allocation, not a law. Your application, tolerance for rework, access to each tool and budget can shift the answer. Even among people working closely together, preferences differ because their daily tasks differ.
My colleague Julius, for example, weighs the choice differently. If the central question is which single model to have rather than which to use first for a particular job, the balance between quality and practical access changes.
I turn to the subscription question, but my recommendation reflects the products and prices available in July 2026. The right plan depends on your workload and the provider's current limits, so compare current offerings and test the tasks you actually perform.
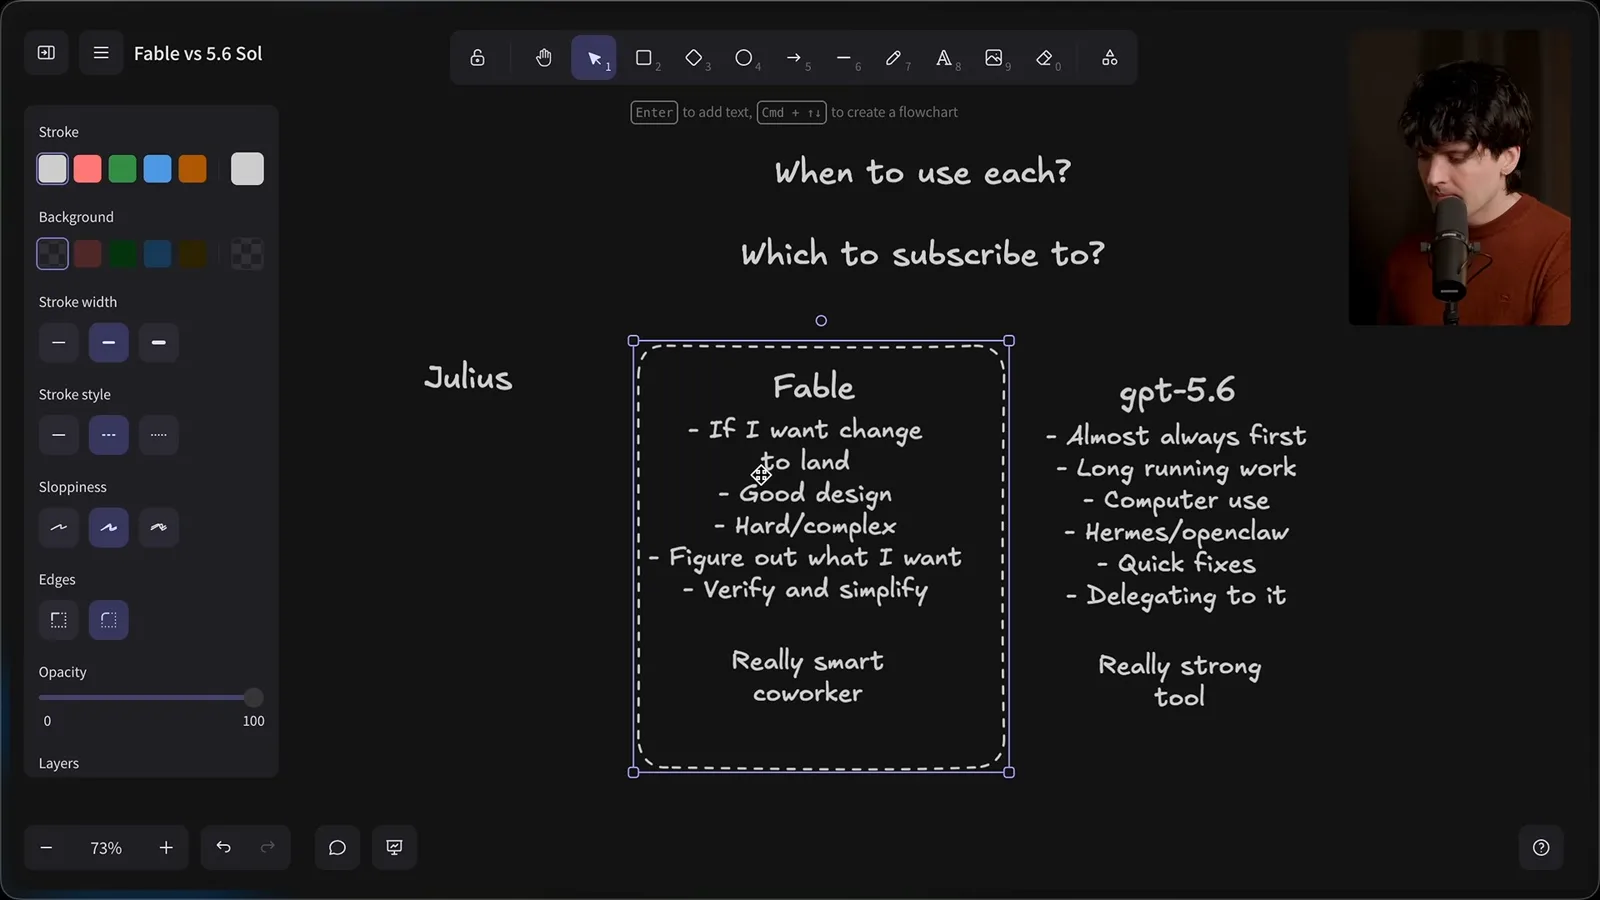
A stronger model can justify a higher cost when its judgment saves repeated work or prevents a bad implementation. For routine jobs, a lower-cost model may deliver better overall value. Neither conclusion follows solely from the advertised model ranking.
Try representative jobs instead of copying my exact setup. Look at the whole loop: the prompt, execution time, output, review, corrections and the conditions under which you are allowed to use the service.
My conclusion remains that Fable often shows the stronger judgment for the work I value most, while Sol is the model I start with for much of my daily work. That is why liking one model best and using the other more can both be true.
The model landscape will keep changing, and your experience may differ from mine. Use these examples as hypotheses, compare them on your own work, and keep the human review needed for changes that matter.
More from this channel
 38:47EN
 Theo - t3․gg· Oct 28, 2026Theo’s Long-Running Agent Experiments: Verification, Compute and CostTheo Browne · Ping LabsA skateboard game and two compiler projects show how repeated checks and flexible compute can sustain agent work—and how expensive those loops can become.
 36:07ENTheo - t3․gg· Oct 27, 2026Theo on Token Costs, Coding Agents, and the Price of AI CapabilityTheo Browne · Ping LabsA viral estimate of Lauren's AI spending prompts a closer look at cache pricing, benchmarks, and the changing work of coding agents.
 30:37ENTheo - t3․gg· Oct 26, 2026Theo’s Three Skills for Reviewing and Shipping with Coding AgentsTheo Browne · Ping LabsHow sol-loop, full-send and full-stop encode review, verification and different levels of merge authority.
 0:43ENTheo - t3․gg· Oct 23, 2026Theo Distinguishes Security Vulnerabilities from Active AttacksTheo Browne · Ping LabsA short explanation of why disclosed software flaws and reported attacks are different kinds of security news.
 29:22ENTheo - t3․gg· Oct 22, 2026Theo on Security Vulnerabilities, Stolen API Keys and AITheo Browne · Ping LabsA look at the gap between vulnerability disclosure and patching, and a speculative account of why stolen inference keys may be valuable.
 31:13ENTheo - t3․gg· Oct 20, 2026Theo on Why Smarter Models Help More Than DevelopersTheo Browne · Ping LabsFrom game modifications to compiler experiments, Theo revisits his assumptions about who benefits from more capable AI.