In 30 seconds
Matthew Berman introduces seven coding-agent loops: page-load optimization, documentation review, architecture refactoring, logging coverage, production error triage, search visibility and full product evaluation. He demonstrates how a goal or scheduled automation can drive repeated work toward a stopping condition. The examples range from measurable checks to subjective model judgments. Berman cautions that open-ended goals can run for days and consume substantial tokens; the illustrated performance investigation does not establish that all production pages reached 50 milliseconds.
- 1Triggers and goalsA person, schedule or event starts the loop; a measurable check or model judgment determines when it stops.
- 2A page-load targetThe example measures pages after significant changes against the same under-50-millisecond goal.
- 3Overnight documentationA scheduled sweep compares docs with the code and opens a pull request for review.
- 4Production error sweepAn agent can trace actionable errors, verify proposed fixes and report the resulting pull request.
- 5Product evaluationThe workflow defines scenarios and criteria, records evidence, fixes failures and reruns checks.
- 6Practical limitsSubjective goals may be brittle and long-running loops can consume considerable time and tokens.
Takeaways
- A loop combines a trigger with a goal that guides repeated agent work.
- Repeatable measurements make a performance target more assessable, but the result is limited to its test conditions.
- Documentation, architecture and logging goals often require judgment rather than a simple deterministic check.
- A production error sweep can investigate, verify and propose fixes for review.
- Open-ended feature goals and long-running loops can be hard to control and expensive.
Read the edited text by chapter
What makes an agent loop
Berman distinguishes triggers from goals and explains measurable checks and model judgment. He introduces a library of reusable examples.
A loop lets an AI coding agent work repeatedly toward a specified goal. I find loops useful because the agent can continue iterating without a person manually prompting every step. That autonomy does not mean the result is automatically correct or that the work needs no oversight.
I describe two parts of a loop: a trigger and a goal. The trigger may be a person starting it, a schedule, or an event such as opening a pull request. A recurring trigger is useful for maintenance; a manual trigger is useful when the work should begin only on request.
A goal can be checked against a concrete condition or judged by a language model. For example, coverage can be measured numerically, while “refactor until satisfied” leaves the model to assess a subjective outcome. Even a measurable metric such as coverage does not by itself establish that tests are meaningful.
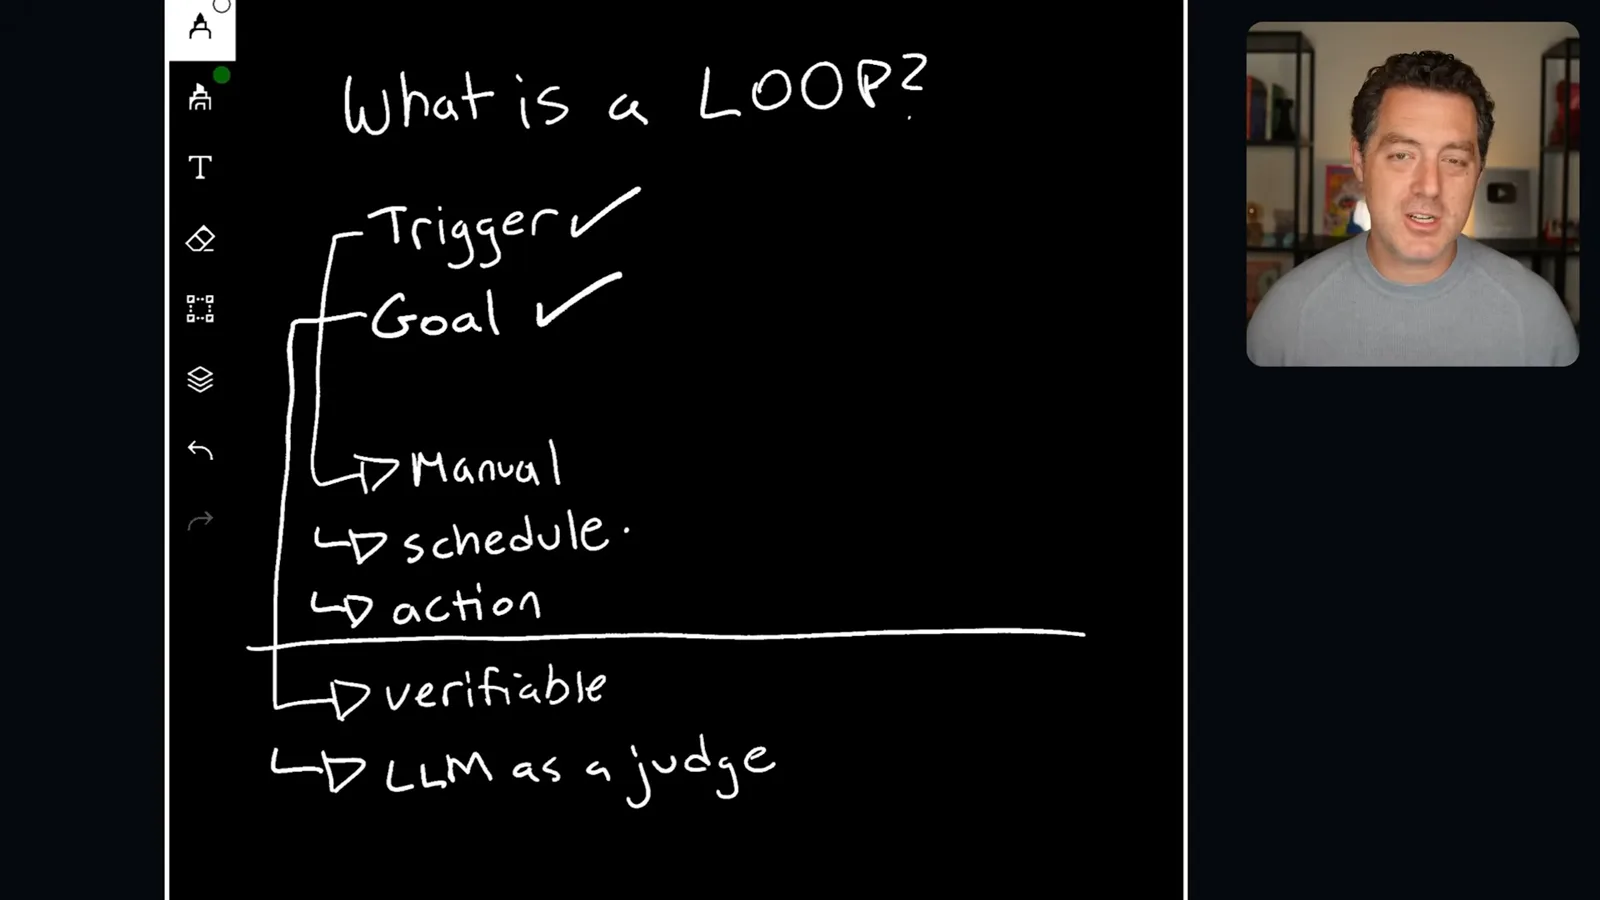
I have collected examples in a free Loop Library so people can copy prompts or adapt them. The examples below show different triggers and stopping conditions; they are starting points that need to be tailored to a project and its constraints.
Performance and documentation loops
A page-load goal uses repeatable measurements, while a nightly documentation sweep relies partly on judgment. Berman demonstrates starting a goal and scheduling an automation.
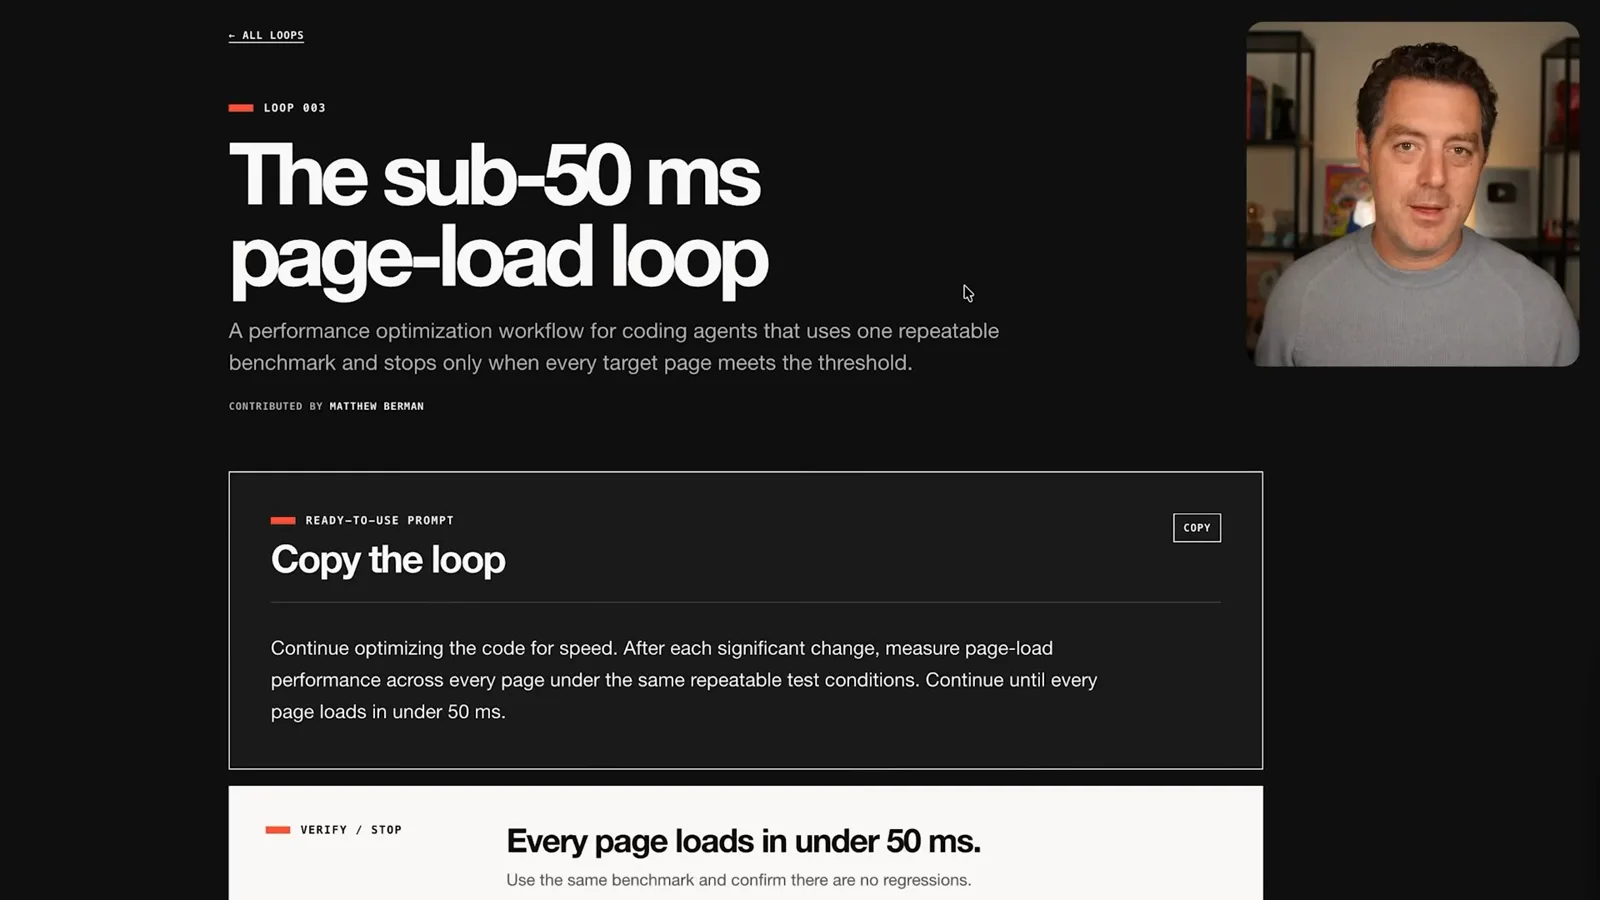
The first is a page-load optimization loop. After each significant change, the agent measures every target page under the same repeatable conditions and continues until each meets a sub-50-millisecond threshold. Defining the measurement and test conditions is essential: a result measured in one environment does not establish the same experience for all users.
This loop can be started manually, scheduled or triggered by a pull request. I demonstrate copying the prompt into Codex and setting it as a goal. I say the agent may work for minutes or hours, so users with limited token budgets need to watch usage and set appropriate bounds.
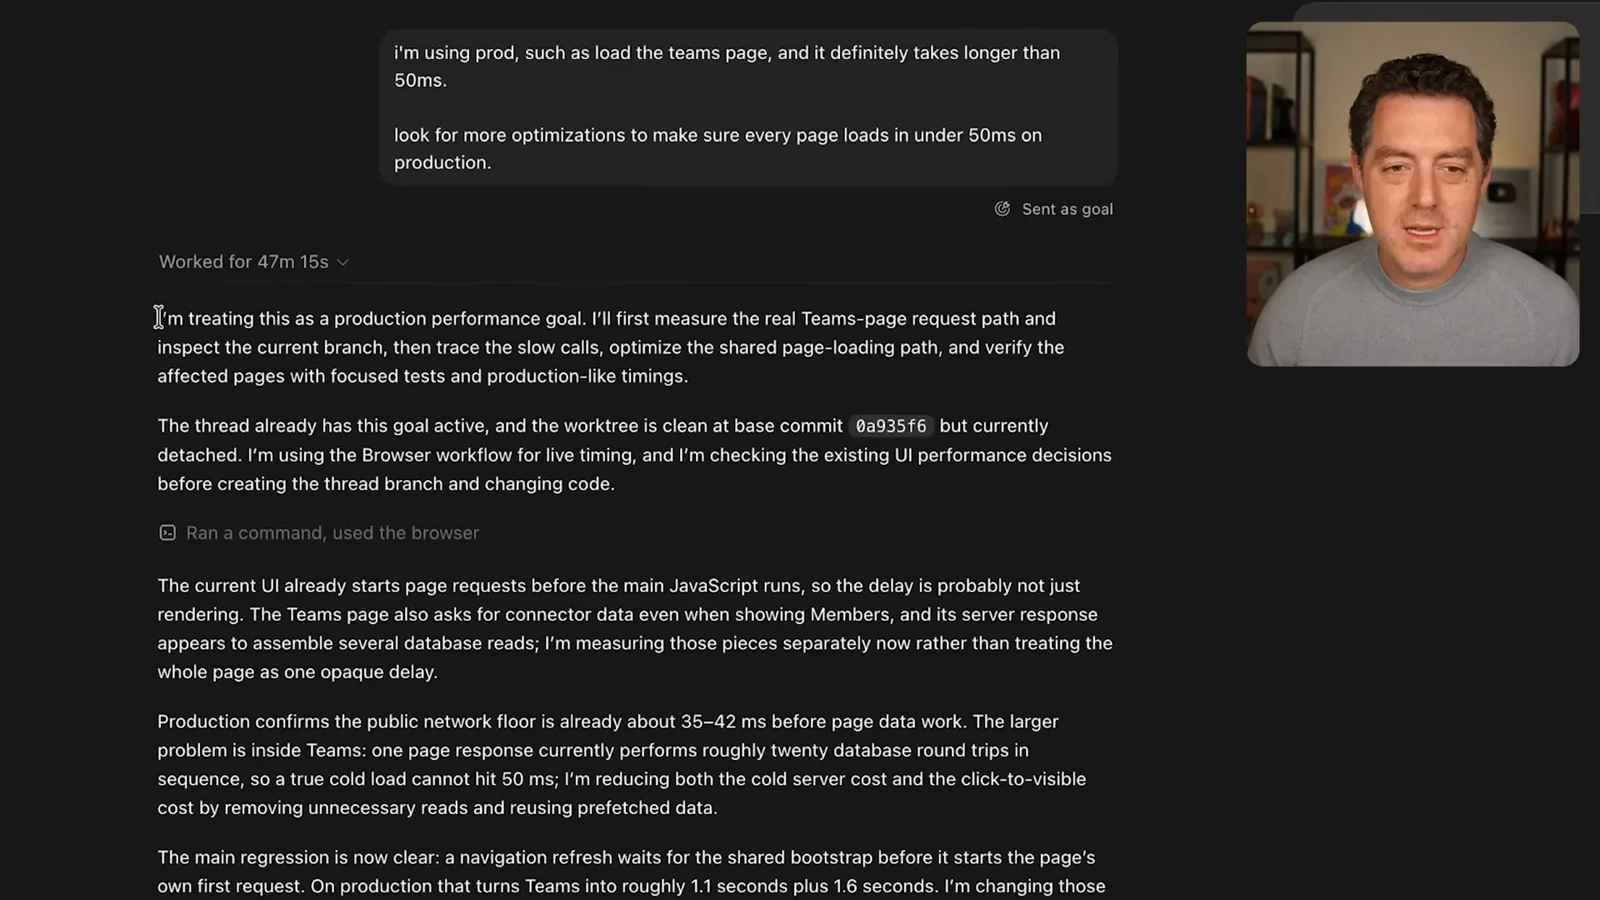
I show a run that worked for nearly 50 minutes on a production performance goal. The visible agent output identifies a network latency floor and database round trips, and says a true cold load cannot reach 50 milliseconds under the conditions described. The clip illustrates an investigation, not independent proof that every production page achieved the target.
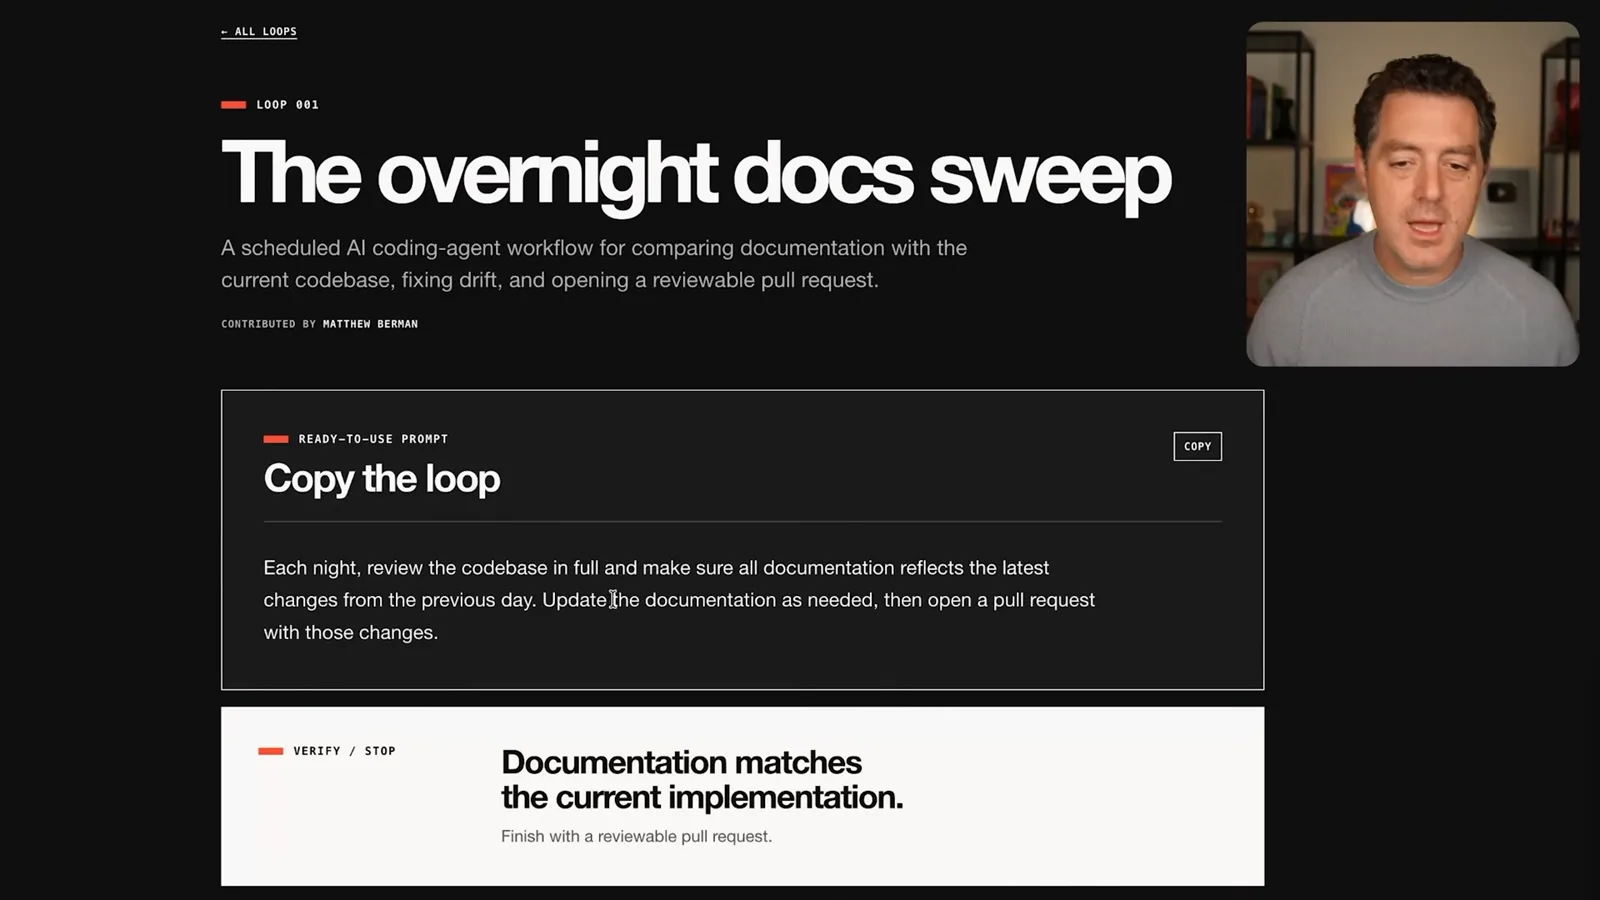
The overnight docs sweep asks an agent each night to review the codebase, update documentation to reflect recent changes and open a pull request. The objective is to keep implementation and documentation aligned while producing changes a person can review.
This is partly an LLM-as-judge task: deciding whether the documentation is complete involves judgment, even if specific coverage checks can be automated. I demonstrate creating a recurring Codex automation with the copied prompt. A scheduled review is a proposal for a workflow, not proof that every document will always be correct.
Architecture, logging and production errors
Three examples address refactoring, useful logs and actionable production errors. Each uses an explicit condition and a way to review its work.
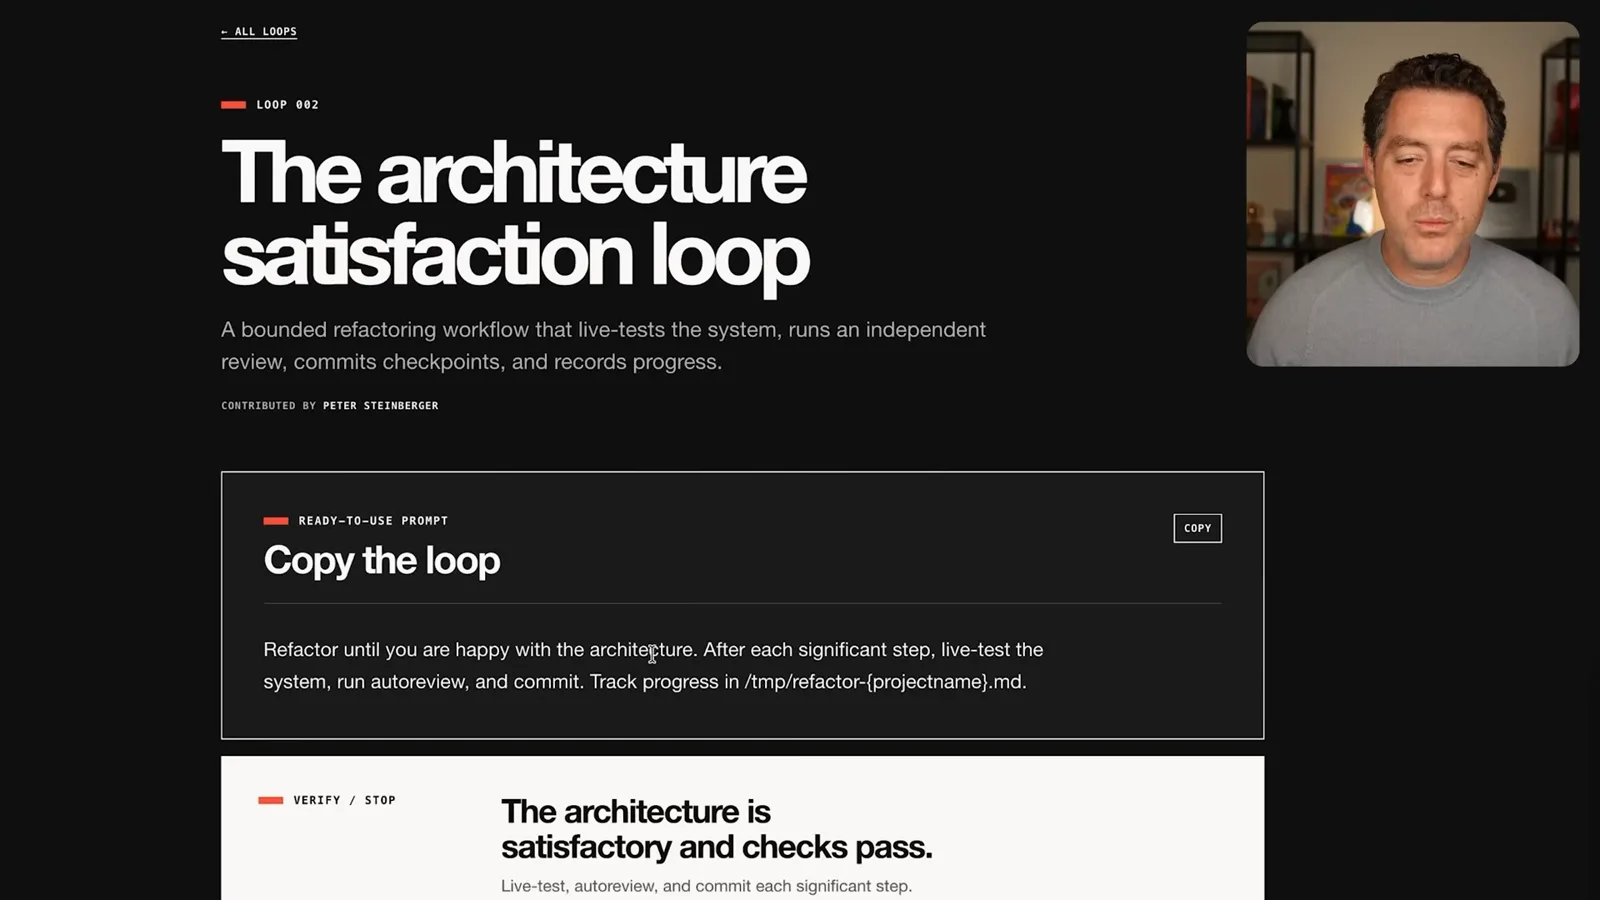
Peter Steinberger’s architecture satisfaction loop asks the agent to refactor until it is satisfied with the architecture. The prompt adds structure: after each significant step, live-test the system, run an automated review, commit a checkpoint and track progress in a Markdown file.
Because satisfaction is subjective, I suggest providing additional guidance such as favoring simplicity or reducing duplication. The agent’s judgment can still differ from the team’s architectural goals, so the tests, review and recorded checkpoints matter.
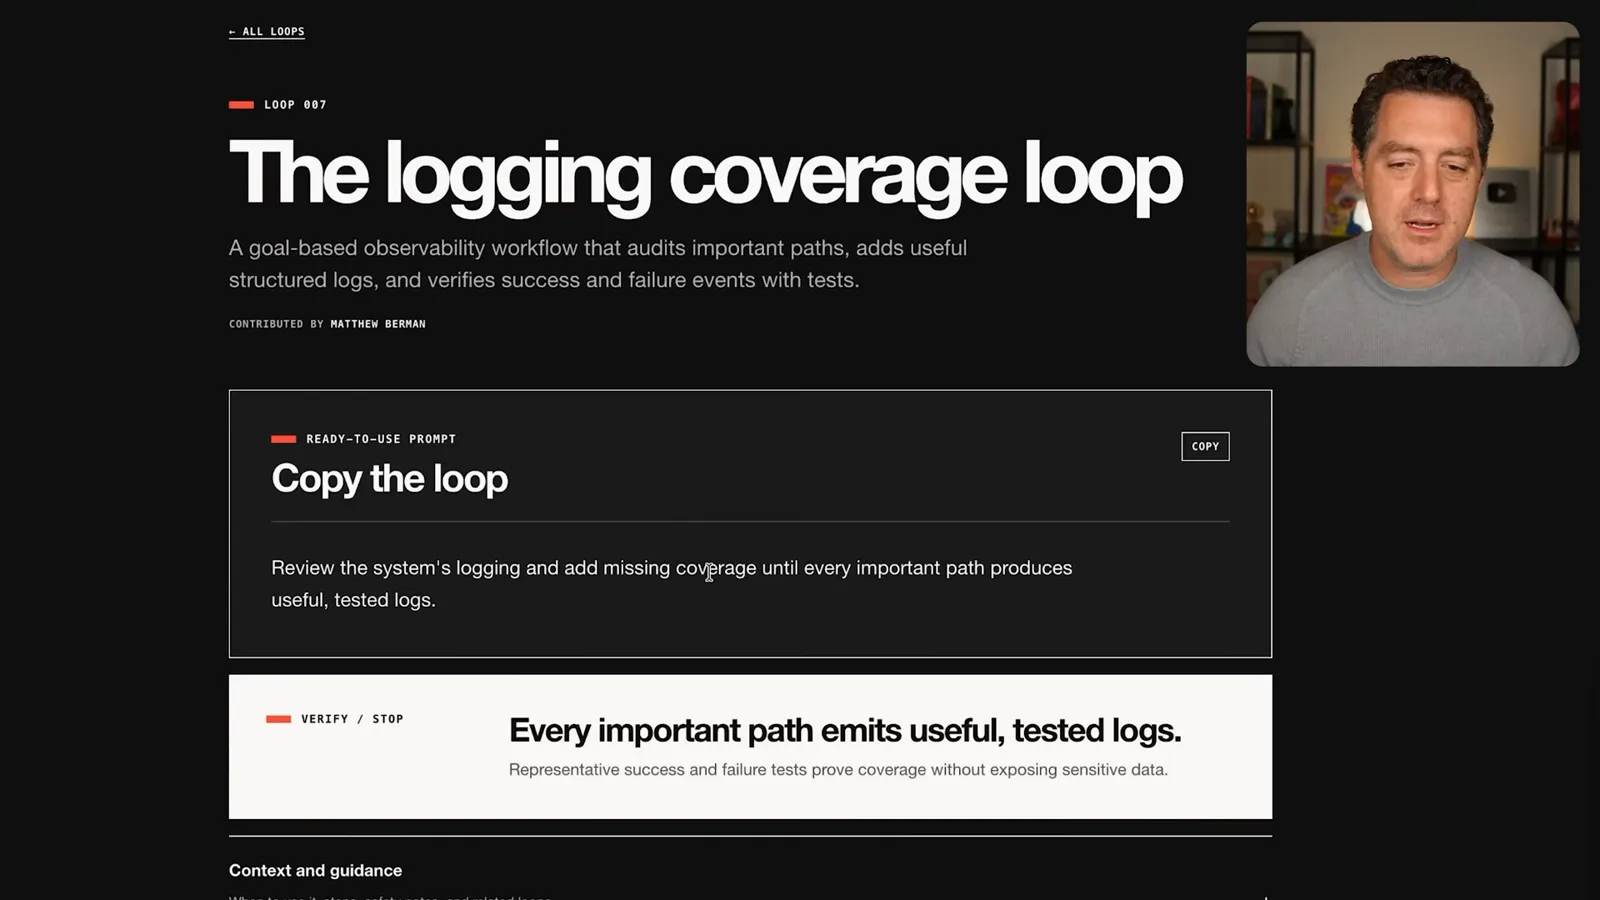
The logging coverage loop reviews the system and adds missing logs until important paths produce useful, tested events. The word “important” makes the stopping condition partly subjective: the agent must decide which paths matter. This loop also sets up a later workflow that uses the resulting logs.
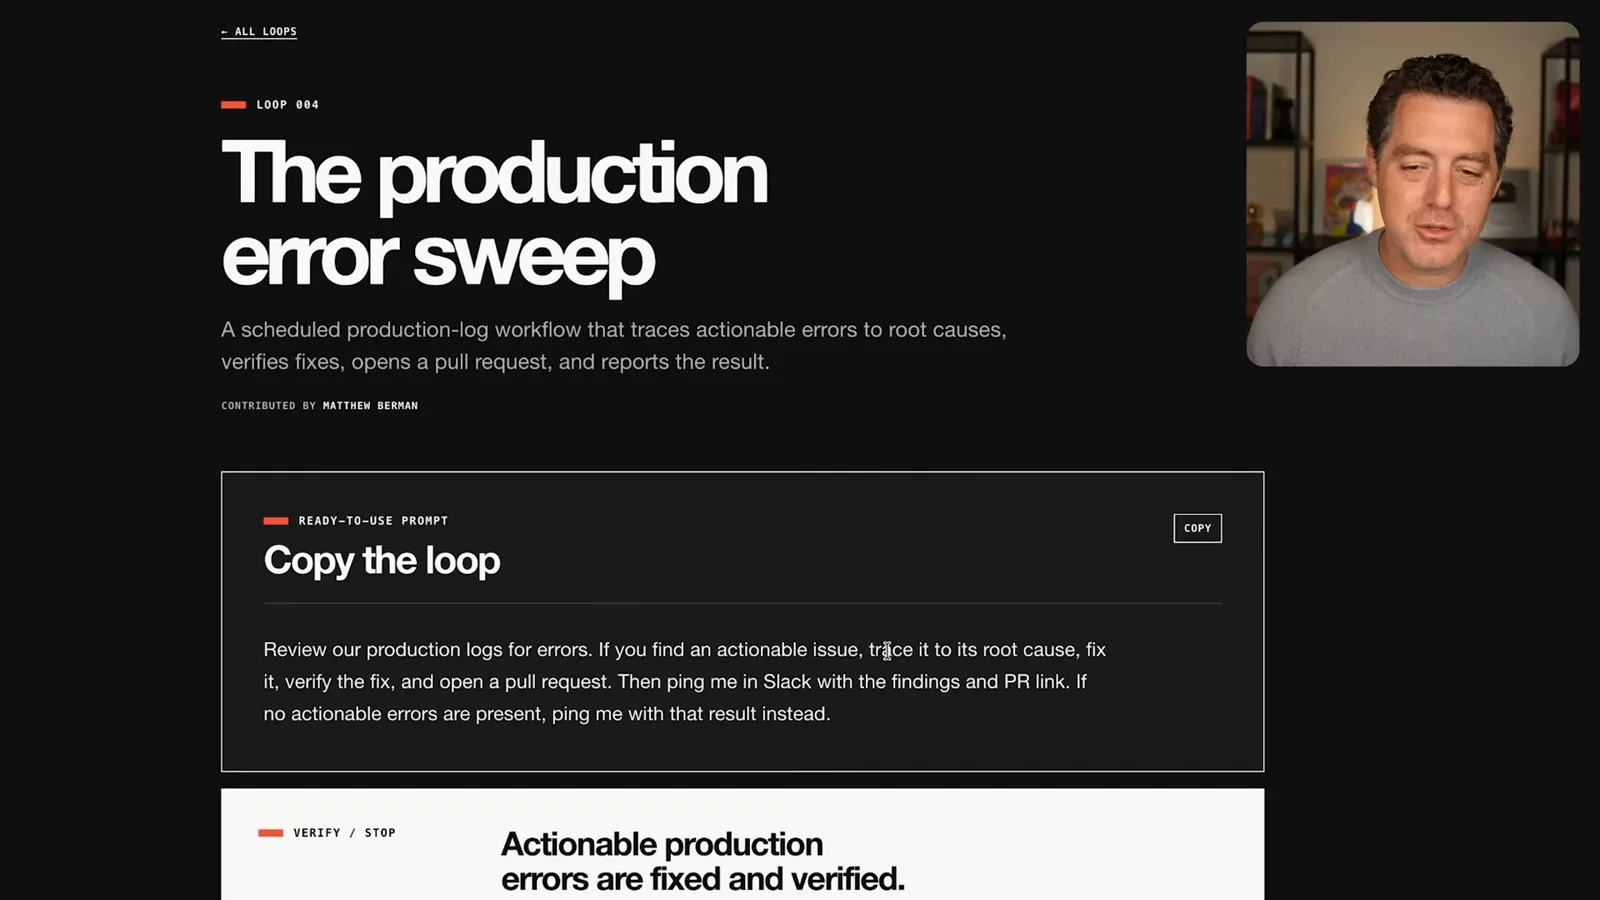
The production error sweep runs on a schedule and reviews production logs. When it finds an actionable issue, the prompt asks the agent to trace the cause, fix it, verify the fix and open a pull request, then report the findings and link in Slack. If there are no actionable errors, it reports that result instead.
Visibility and product evaluation
The remaining examples audit search visibility and test realistic product scenarios. Both iterate on findings and repeat their checks.
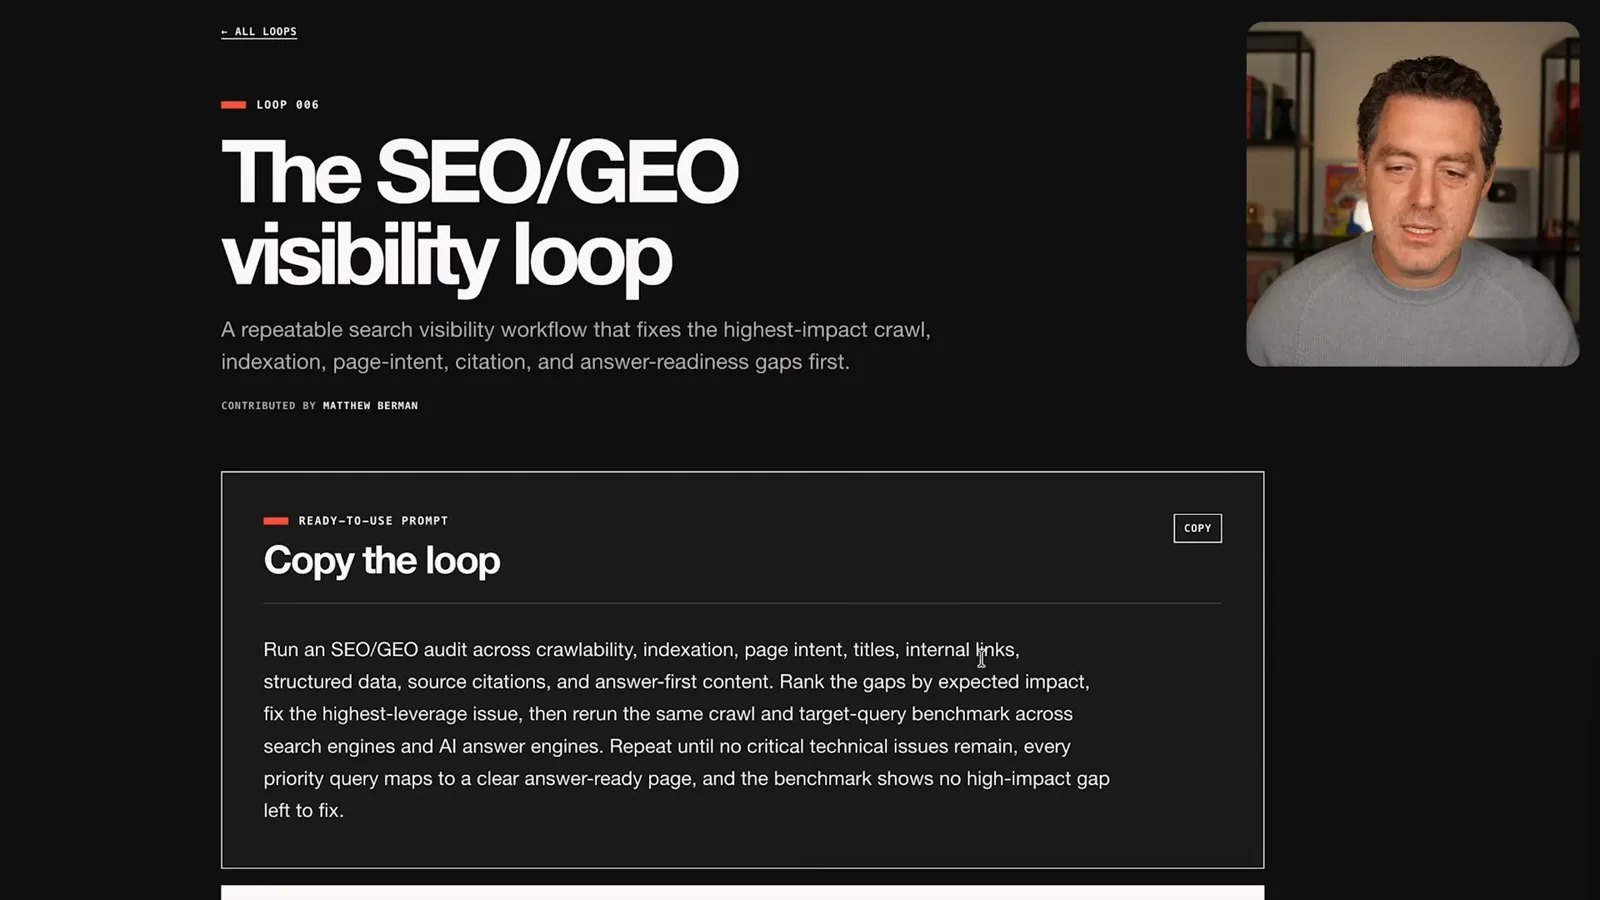
The SEO/GEO visibility loop audits crawlability, indexation, page intent, titles, internal links, structured data, citations and answer-first content. It ranks gaps, fixes the highest-impact issue, reruns the same crawl and benchmark, and repeats until its specified critical gaps are addressed.
The full product evaluation loop starts by creating realistic scenarios across major capabilities. Before testing, it defines success criteria and a consistent method, such as pass/fail checks or a scoring rubric. It runs scenarios under the same conditions and records evidence for each outcome.
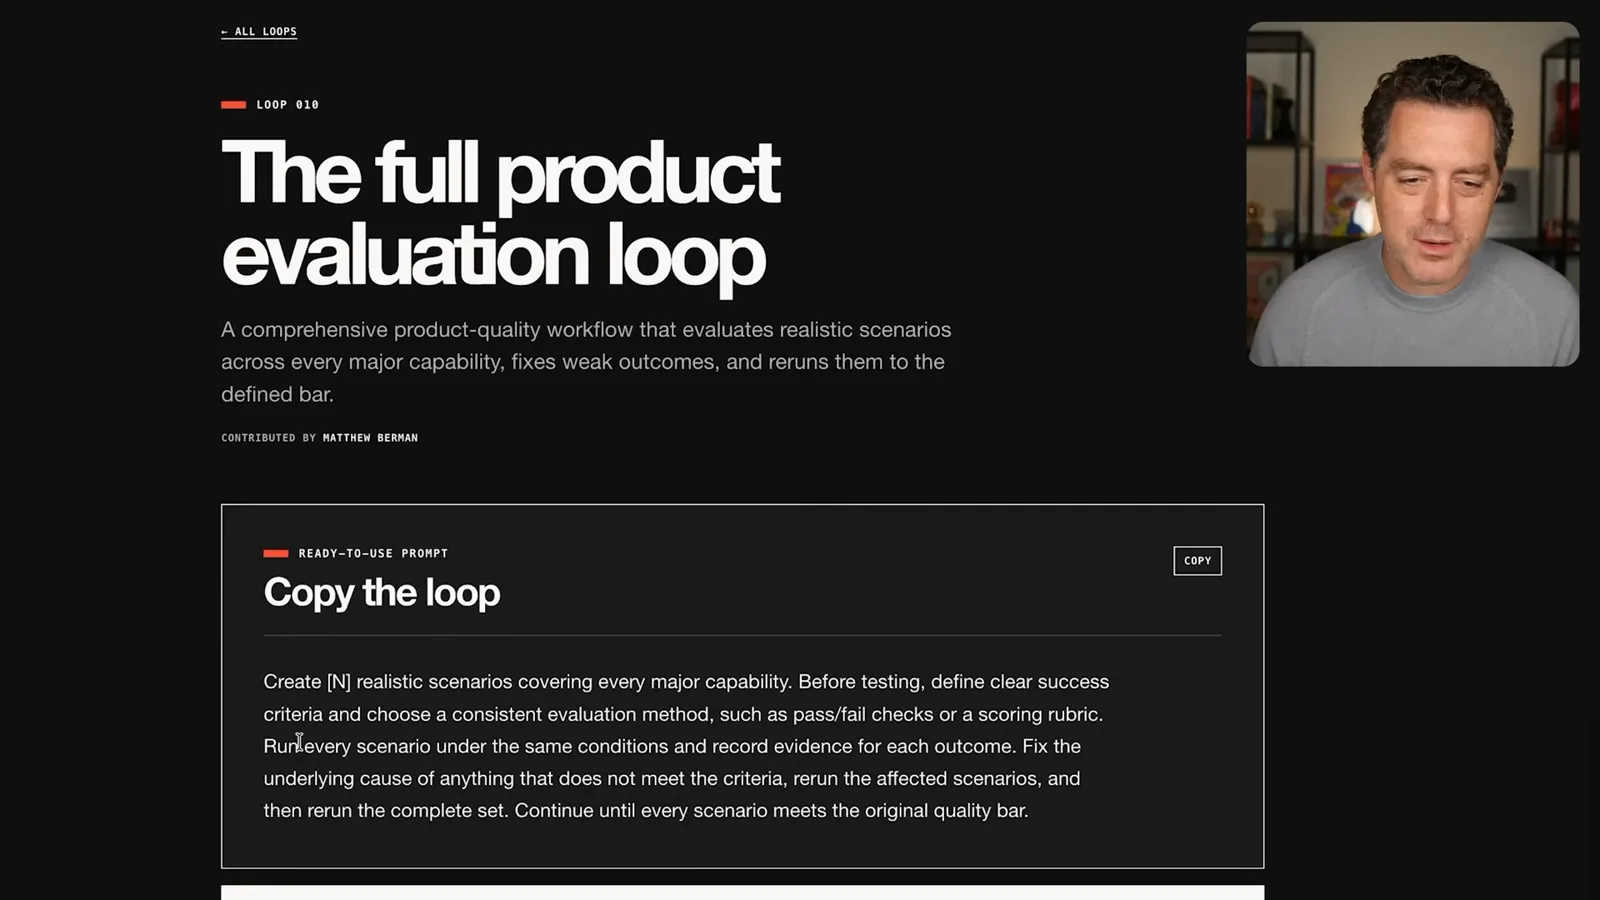
For outcomes that fail, the agent investigates the underlying cause, makes changes, reruns affected scenarios and then reruns the complete set. I describe this as more than a conventional deterministic test suite because some judgments about quality can be made by a model.
I say this loop can take twelve hours or more, and offer an example of a question-answering product that must provide accurate, sourced responses. The agent can create a wide range of test questions, judge the results and iterate, but its judgment and chosen scenarios still need scrutiny.
Limits and cost
Berman cautions that subjective goals and open-ended feature creation are difficult to bound. Long-running loops can also consume substantial resources.
There are two major caveats. First, designing a useful stopping condition is difficult, and loops are not appropriate for every problem. A concrete, verifiable target is easier to assess than a subjective one where the model must decide whether its own work is good enough.
Feature development is especially hard to leave open-ended. Asking an agent to build a complete permissions system without specifying the desired behavior gives it too much freedom to choose what matters and when to stop. I prefer not to use such a loop for an unspecified feature from day zero.
I once asked an agent to clone Excel to feature parity. It used computer control to inspect Excel, but the task ran for days before I stopped it. I do not recommend that approach: an expansive goal can keep producing work without a practical endpoint.
Second, loops can be expensive. Agents consume tokens as they work, and a run can last minutes, hours or days. Consider the budget and the value of the task before allowing an autonomous loop to keep going.
More from this channel
 34:21EN
 Matthew Berman· Oct 27, 2026Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 25:50ENMatthew Berman· Oct 24, 2026Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.
 32:20ENMatthew Berman· Oct 23, 2026Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.
 1:03:37ENMatthew Berman· Oct 23, 2026Matthew Berman’s Team Tests Kimi K3.1 on Animation, Games, and ChartsMatthew Berman, Alex, Brian · Forward FutureA live team AMA turns into an informal test of Kimi K3.1, from personal-agent workflows to motion graphics, a browser game, and a benchmark chart.
 0:53ENMatthew Berman· Oct 22, 2026Sam Altman on AI and the Discovery of New KnowledgeSam Altman · OpenAIAltman expects progress in mathematical discovery to extend to biology, materials and energy.
 0:22ENMatthew Berman· Oct 21, 2026A Robot Bodyguard Video Shows Dramatic Rescue ScenariosMatthew Berman · Forward FutureMatthew Berman reacts to a short robot demonstration depicting fighting and vehicle-rescue scenarios.