In 30 seconds
Matthew Berman covers anticipated Llama releases, robot hands, Sora videos, Mistral models, GPT-4o mini, tool-calling models and AI education. He also examines reporting on YouTube subtitle data, a power-line-charging drone and a historical example of inconsistent model safeguards. Predictions and benchmark comparisons reflect July 2024 rather than current rankings.
- 1Anticipated Llama releaseBerman discusses July 2024 reports about an upcoming 400B-class Llama model. Release timing, license and benchmark predictions were unconfirmed at the time of recording.
- 2Three Mistral releasesHe reviews Mathstral 7B, Codestral Mamba and 12B Mistral NeMo, emphasizing specialization, efficiency and the published comparisons.
- 3YouTube subtitle concernsReporting identified subtitles in a dataset used by some organizations; consent and whether a particular model used the data must be assessed separately.
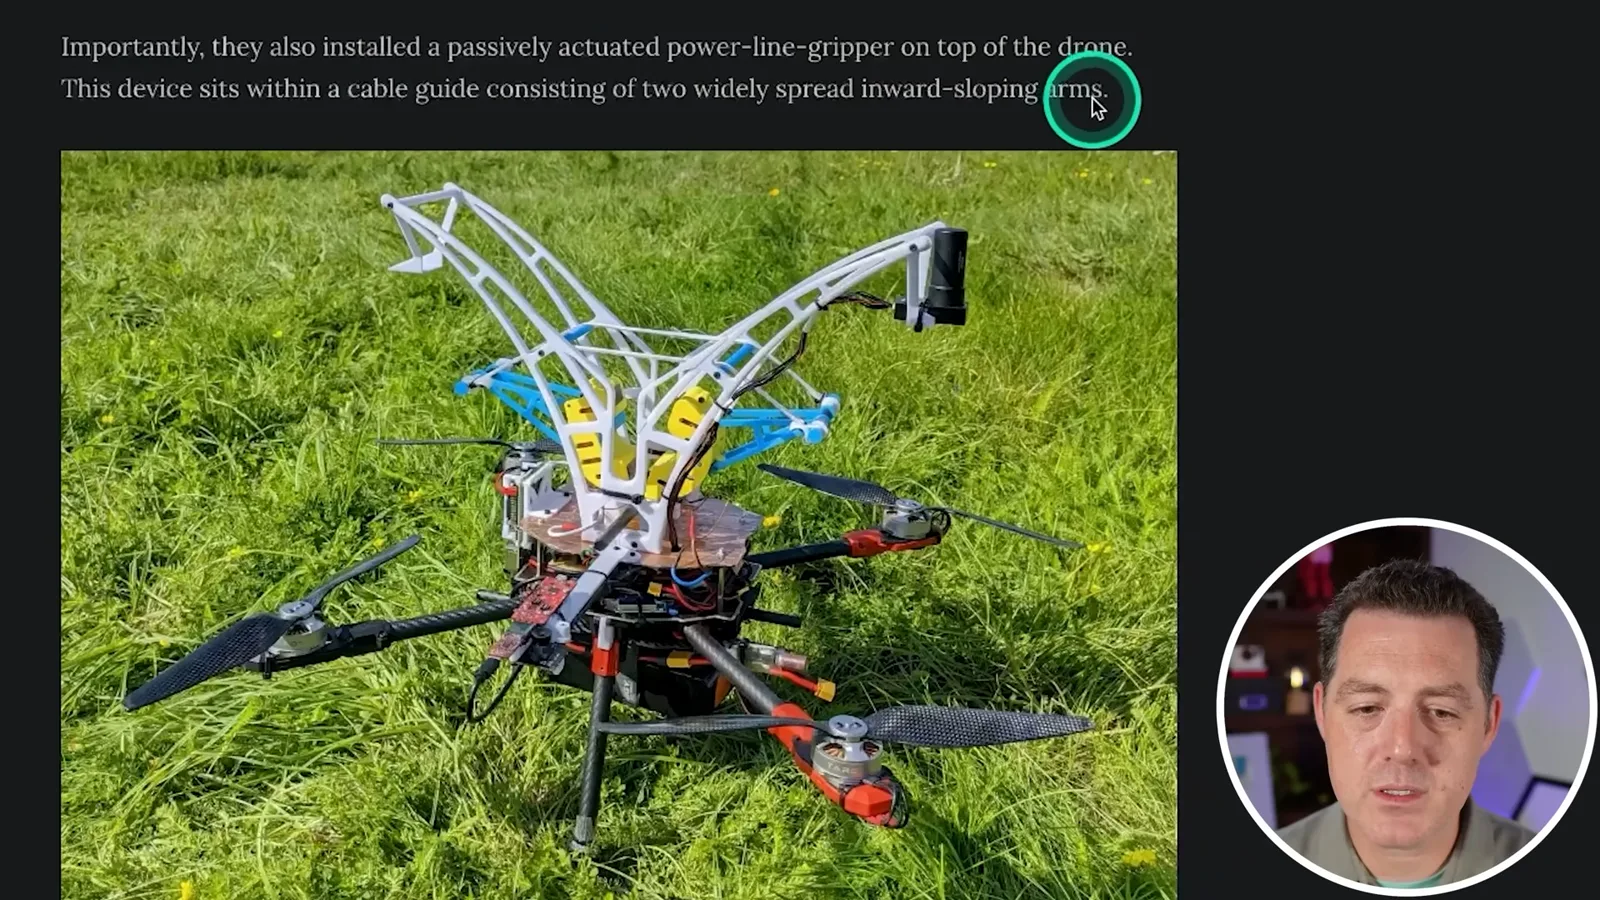
- 4A drone that recharges on linesThe prototype uses a gripper and an inductive charger to draw power while perched. Berman raises a possible misuse concern.
- 5Safeguards can failBerman demonstrates a historical example of inconsistent responses to reworded prompts. His broader claim that jailbreaks are inevitable is an opinion, not a demonstrated theorem.
Takeaways
- A robotic hand demonstration illustrates dexterity, but does not establish autonomous surgical capability.
- Mathstral, Codestral Mamba and Mistral NeMo explored different model sizes and architectures with reported results on selected benchmarks.
- Mamba’s theoretical sequence properties do not mean unlimited effective context in a practical deployment.
- Reporting about YouTube subtitle data raised consent and training-data questions; describing the material as legally stolen is a contested characterization.
- A research drone demonstrated power-line recharging, not indefinite operation under all conditions.
- A single jailbreak demonstration illustrates a safeguard failure but does not prove all defenses must always fail.
Read the edited text by chapter
Llama, robot hands and Sora
Berman discusses reports about a forthcoming Llama model and shows a robotic hand demonstration. He reviews new Sora-generated clips and their visual imperfections.
This week brings a broad range of AI news. Reports suggest Meta may soon release a 400B-class Llama 3 model. At the time of this July 19, 2024 video, its timing, final capabilities and release terms are still reported expectations, so I look forward to testing it when it is available rather than treating those details as confirmed.
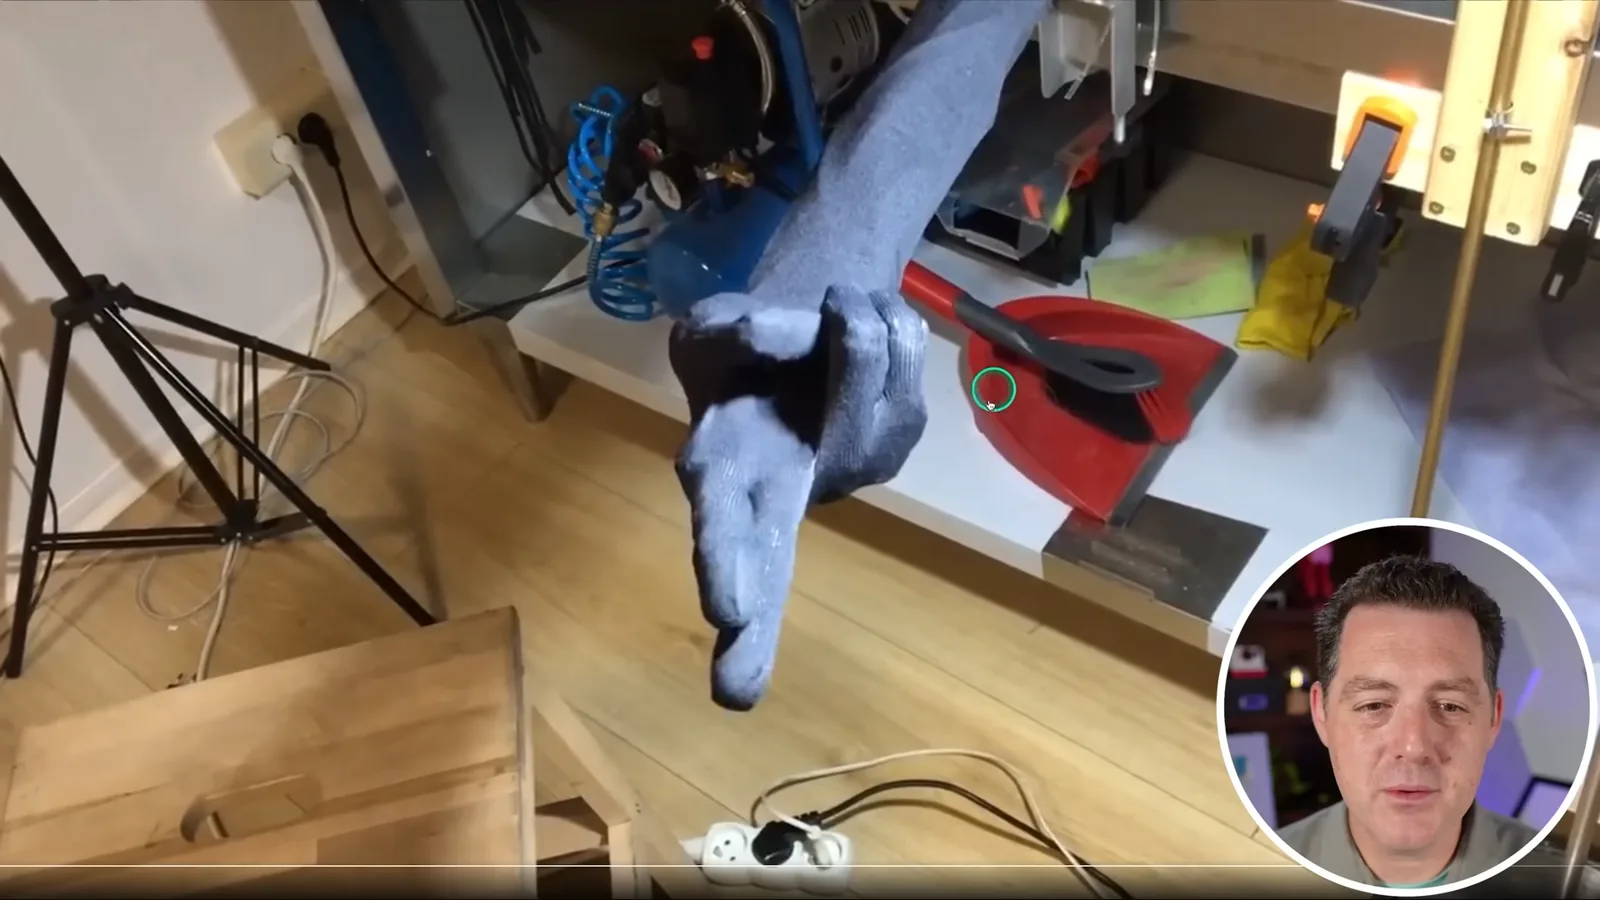
Clone Robotics shows a hand and arm designed to mimic musculoskeletal motion. The demo includes rotation and handling tools such as a drill and scissors. I find the coordination impressive and imagine future medical applications, but a demonstration of grasping tools is not evidence that the system can perform autonomous surgery.
OpenAI has shared more Sora examples, including surreal animals, a pianist and interior scenes. Some look convincing, though I notice rigid motion, imperfect hands and odd hair. Another clip impresses me with its apparent fluid motion, even while the car movement has visible issues; a realistic-looking frame does not establish physically accurate simulation.
Game creation and Mistral models
A game-engine demonstration is followed by Mathstral, Codestral Mamba and Mistral NeMo. Berman discusses architecture, context and reported benchmark results.
A Buildbox 4 demonstration shows a game environment being changed through prompts, such as adding fog or making a space shooter. I imagine a future where people can create more personalized games in this way. The demo shows a particular tool and workflow, not a guarantee that any game can already be generated on demand.
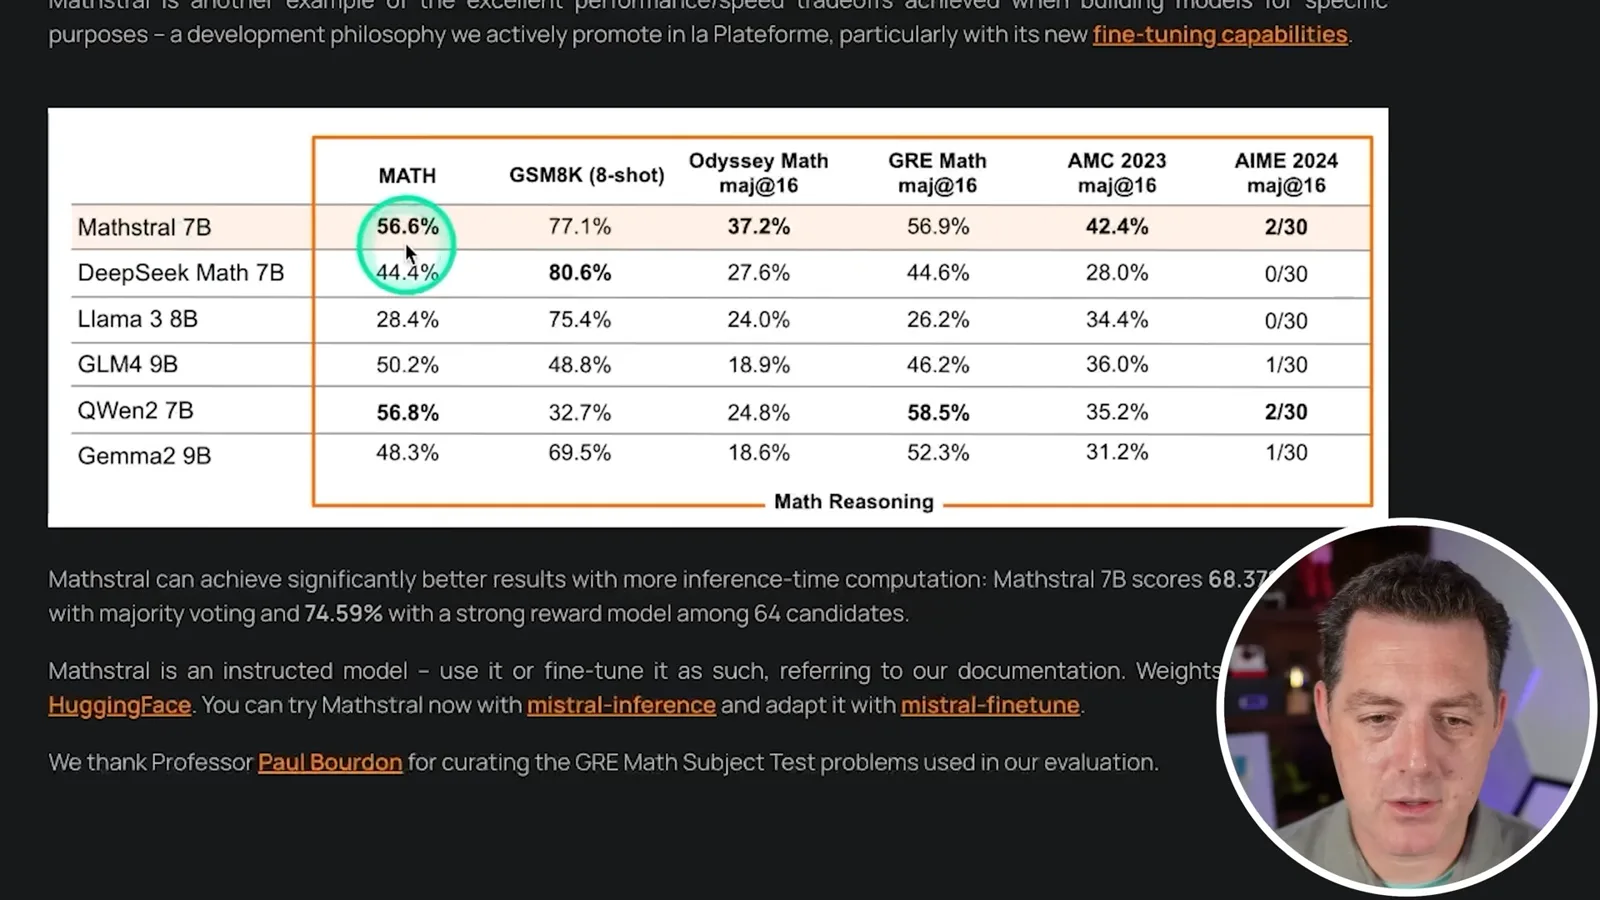
Mistral has released Mathstral 7B, a model aimed at mathematics, with a stated 32K context and Apache 2.0 license. The displayed table compares it with other small models on several math benchmarks. Those numbers are useful for the tested tasks, but they do not establish uniform superiority in every mathematical application.
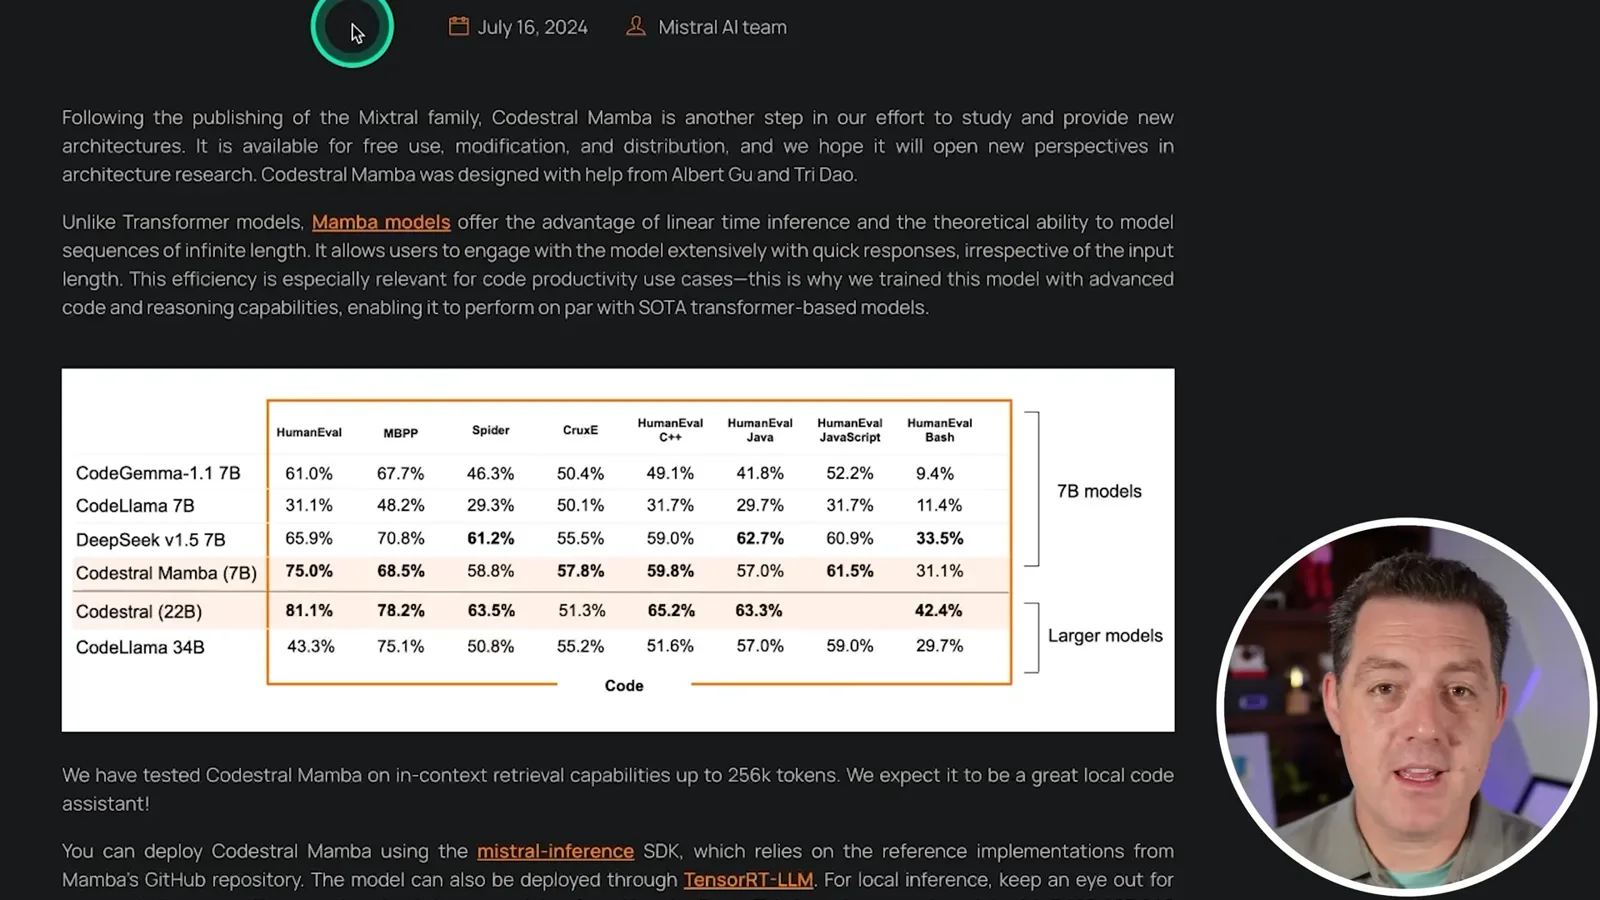
Codestral Mamba is a code model based on the Mamba architecture rather than a conventional Transformer. Mistral describes favorable inference scaling and the theoretical ability to model long sequences. The theoretical claim does not mean that practical context, memory or accuracy is unlimited; the shown benchmarks compare specific models and tasks.
Mistral NeMo, developed with Nvidia, is a 12B model with a stated 128K context window and Apache 2.0 license. Mistral presents comparisons against smaller models including Llama 3 8B and Gemma 2 9B and highlights multilingual performance. I am interested in smaller models that might eventually run on more personal devices, though practical deployment still depends on hardware and workload.
Training data, apps and education
The video discusses reporting on YouTube subtitles in a training dataset, the Claude Android app and Karpathy’s education venture. Consent and specific model usage require separate examination.
An investigation raised concerns about YouTube subtitles included in the Pile, a dataset associated with EleutherAI. Berman describes the collection as unauthorized and calls it stolen; that legal characterization is contested. The presence of subtitles in a dataset, a company’s use of that dataset and the training data of a particular model are separate claims that need individual evidence.
Anthropic has released a Claude app for Android, which I am happy to see as an Android user. I regard Claude 3.5 Sonnet highly at the time, though calling any model the best depends on the tasks and period considered. This is a July 2024 snapshot, not a present-day ranking.
Andrej Karpathy has announced Eureka Labs, an education company envisioning high-quality human-designed course materials supported by an AI teaching assistant. The idea is to make patient, accessible guidance available to more learners. The proposed first course, LLM101n, would guide students through building a small AI model.
Tool use, charging drones and GPT-4o mini
Berman reviews Groq’s tool-use fine-tunes and a drone that can recharge on a power line. He compares historical GPT-4o mini pricing and benchmark results.
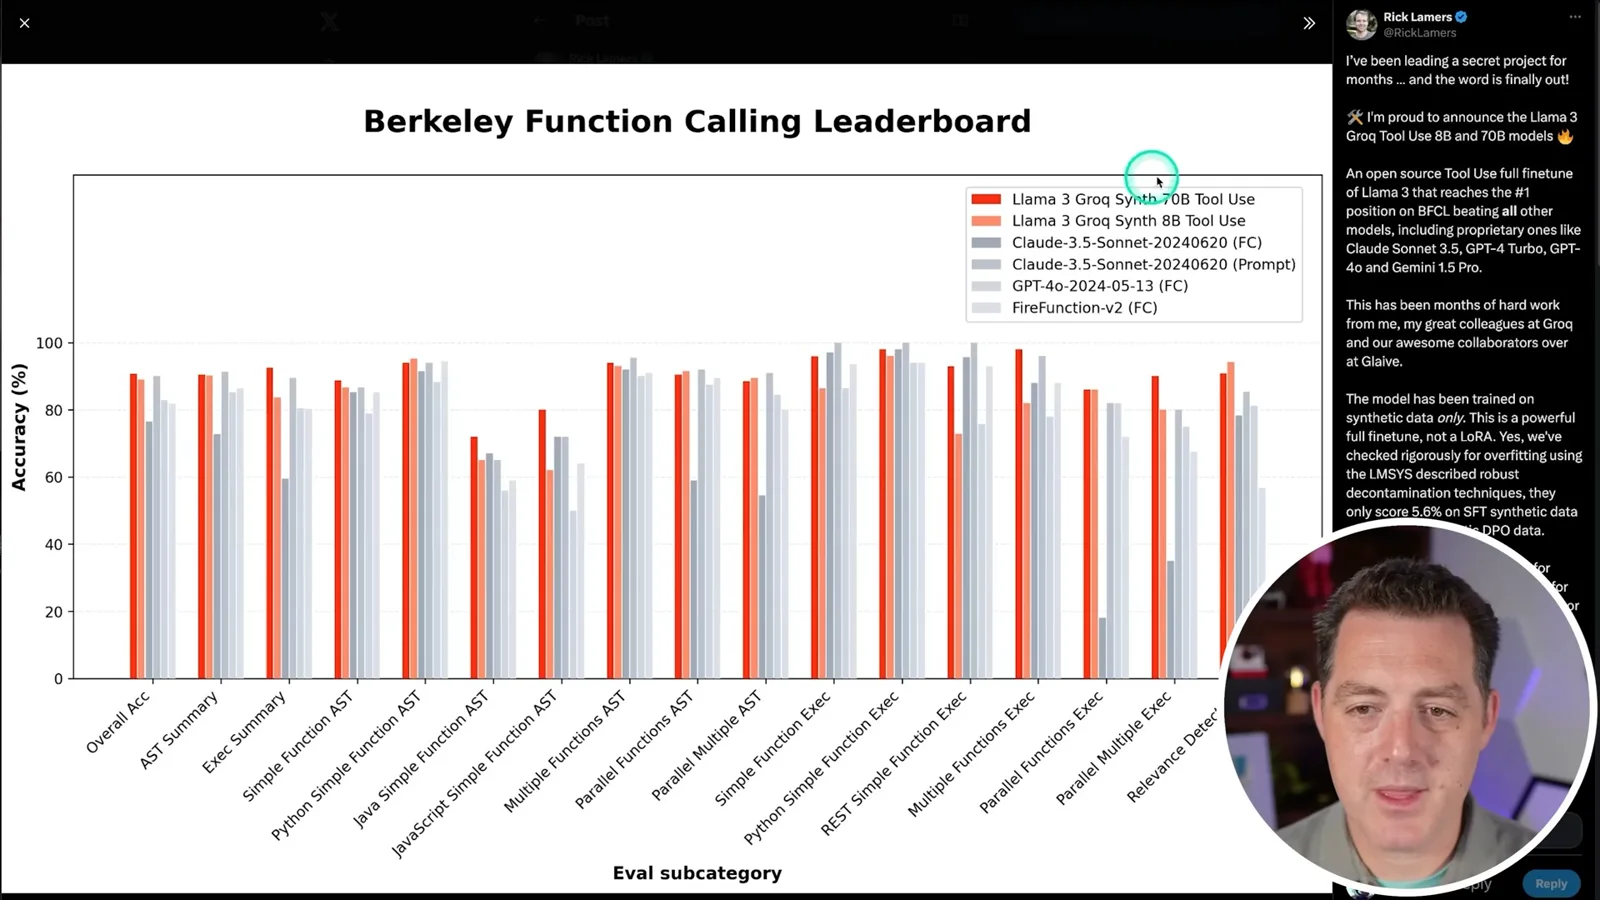
Groq announces Llama 3 tool-use fine-tunes in 8B and 70B sizes. The team says they were fully fine-tuned on synthetic data and checked for overfitting; the displayed Berkeley Function Calling Leaderboard compares them on particular categories. Groq also reports high inference speeds, which depend on the serving setup and measurement conditions.
Researchers at the University of Southern Denmark have demonstrated a drone that can perch on a power line and recharge. A cable guide helps position a passive gripper, while onboard sensing assists the approach and an inductive charger draws energy. I wonder about possible unauthorized power use, but a prototype does not establish unlimited flight or general deployment.
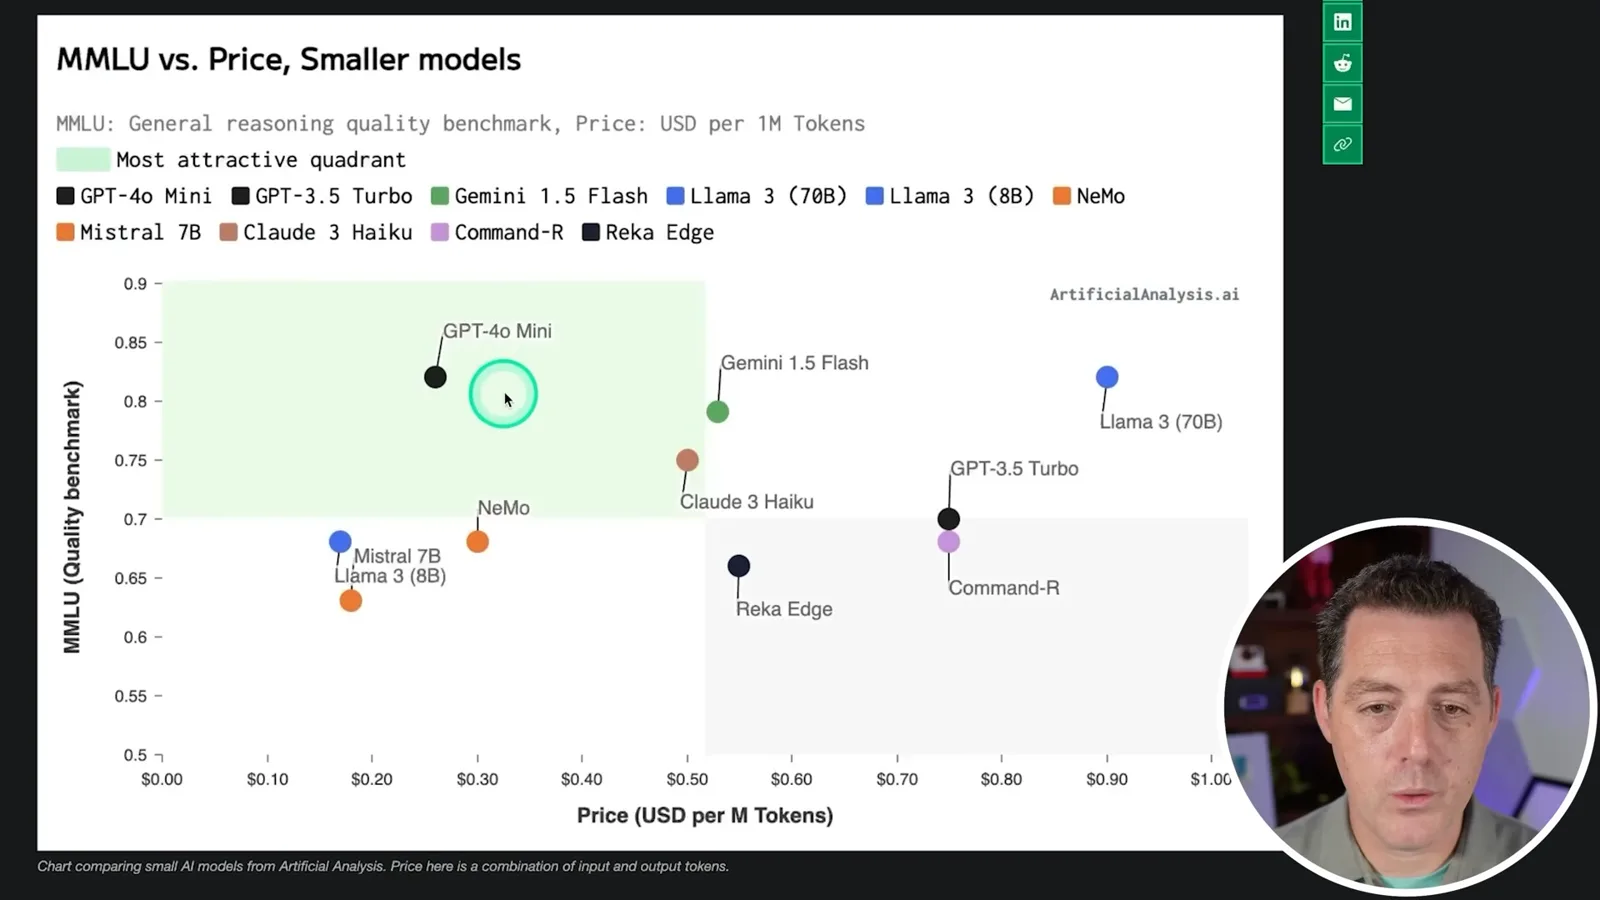
OpenAI has introduced GPT-4o mini as a smaller, lower-cost hosted model. A historical chart compares MMLU scores with prices for selected models, including Llama and Mistral. The result is one benchmark and a time-specific price comparison; users also need to consider task quality, privacy, serving costs and whether local deployment matters.
A historical safeguard demonstration
Berman shows how different wording produced inconsistent model responses in one test. He closes with his opinion about the continuing challenge of jailbreaks.
Finally, I show a 2024 example in which changing the framing of a prompt led to different safety responses. I do not need to reproduce the dangerous requested content to explain the issue: inconsistent safeguards can allow unsafe answers. My belief that jailbreaks will always exist is a judgment about an ongoing security challenge, not something established by one experiment or by randomness alone.
More from this channel
 34:21EN
 Matthew Berman· Oct 27, 2026Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 25:50ENMatthew Berman· Oct 24, 2026Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.
 32:20ENMatthew Berman· Oct 23, 2026Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.
 1:03:37ENMatthew Berman· Oct 23, 2026Matthew Berman’s Team Tests Kimi K3.1 on Animation, Games, and ChartsMatthew Berman, Alex, Brian · Forward FutureA live team AMA turns into an informal test of Kimi K3.1, from personal-agent workflows to motion graphics, a browser game, and a benchmark chart.
 0:53ENMatthew Berman· Oct 22, 2026Sam Altman on AI and the Discovery of New KnowledgeSam Altman · OpenAIAltman expects progress in mathematical discovery to extend to biology, materials and energy.
 0:22ENMatthew Berman· Oct 21, 2026A Robot Bodyguard Video Shows Dramatic Rescue ScenariosMatthew Berman · Forward FutureMatthew Berman reacts to a short robot demonstration depicting fighting and vehicle-rescue scenarios.