In 30 seconds
OpenAI's spring 2024 event presented GPT-4o, a model designed to work across text, audio and images, alongside a desktop interface and voice demonstrations. Matthew Berman walks through the launch, from emotional voice synthesis and interruption to live math help, code analysis and translation. The demos show a compelling interface but also include moments where the assistant appears to respond before seeing the right image; the video ends with Berman's hope for assistants that can actually carry out tasks.
- 1A new interface for an existing model familyThe launch emphasizes the desktop experience and GPT-4o, whose 'o' stands for omni. Berman stresses that the event is not a GPT-5 reveal.
- 2A faster voice loopOpenAI contrasts previous speech-to-text, text-model and text-to-speech stages with a model designed to work natively across modalities, aiming for a more responsive conversation.
- 3Voice as an interfaceA live demonstration uses the assistant to help with a presenter's nerves, then shows that a user can interrupt and redirect its response.
- 4Expressive outputThe assistant retells a bedtime story with changes in delivery and tone. Expressive speech is a demonstration of generated audio, not evidence that the system experiences emotion.
- 5Tutoring and codeA phone-camera math exercise and a desktop code explanation show how voice and visual context can support learning, while a premature camera response illustrates a limitation.
- 6Translation and visual contextThe team demonstrates conversational translation and asks about a selfie; a camera-view mix-up shows that the model's descriptions depend on the image it actually receives.
- 7Beyond the demoBerman hopes that future assistants will go beyond answering and take useful actions, while treating launch-stage demonstrations as a starting point.
Takeaways
- GPT-4o was presented as a GPT-4-class multimodal model, not a GPT-5 announcement.
- A more integrated audio pipeline aims to reduce delays and make interruption and expressive voice interaction feel more natural.
- The launch demos include tutoring, code explanation, translation and interpreting a camera image.
- Some camera demos reveal mistakes or premature responses, illustrating why polished demonstrations are not proof of reliability.
- Berman sees task execution and agent capabilities as an important next step beyond conversation.
Read the edited text by chapter
Introducing GPT-4o
Berman frames OpenAI's launch and the new desktop and multimodal experience.
Matthew Berman reviews OpenAI's May 2024 spring event, which he sees as a significant step toward more natural interaction with AI.
The event introduces a desktop app and GPT-4o. The name refers to its multimodal design; Berman notes that this is a GPT-4-class release rather than GPT-5.
OpenAI executives describe a goal of making advanced AI useful through a more accessible interface. Availability and rollout statements in the video refer to the launch period.
Native audio and responsiveness
The presentation explains the intended difference between earlier voice pipelines and GPT-4o's multimodal processing.
The presentation contrasts earlier voice interactions, which passed through separate transcription, language and speech-generation stages, with a model built to process multiple kinds of input and output.
Lower latency matters because a conversation feels more natural when the assistant can respond quickly and a person can interrupt it.
Berman highlights the implications for day-to-day use: voice, images and text can become parts of the same interaction rather than isolated features.
Live voice demonstrations
Presenters test coaching, interruption and expressive storytelling.
In a live demonstration, the presenters ask the assistant to help one of them relax before appearing on stage.
They interrupt the assistant and redirect it, demonstrating an interaction pattern that is difficult in a rigid turn-by-turn voice interface.
The assistant changes its delivery in response to requests. Berman is struck by how conversational and expressive the generated voice sounds.
A bedtime-story demonstration asks for changes in dramatic tone. The demonstration concerns voice output; it does not establish that the assistant feels the emotions it portrays.
Math, code and translation
The assistant is shown responding to camera and desktop context and translating speech.
For a math example, the camera is directed at an equation and the assistant is asked to help with the reasoning instead of simply delivering an answer.
The assistant appears to describe an equation before the intended image is shown. That mistake is a useful reminder that live visual understanding can fail.
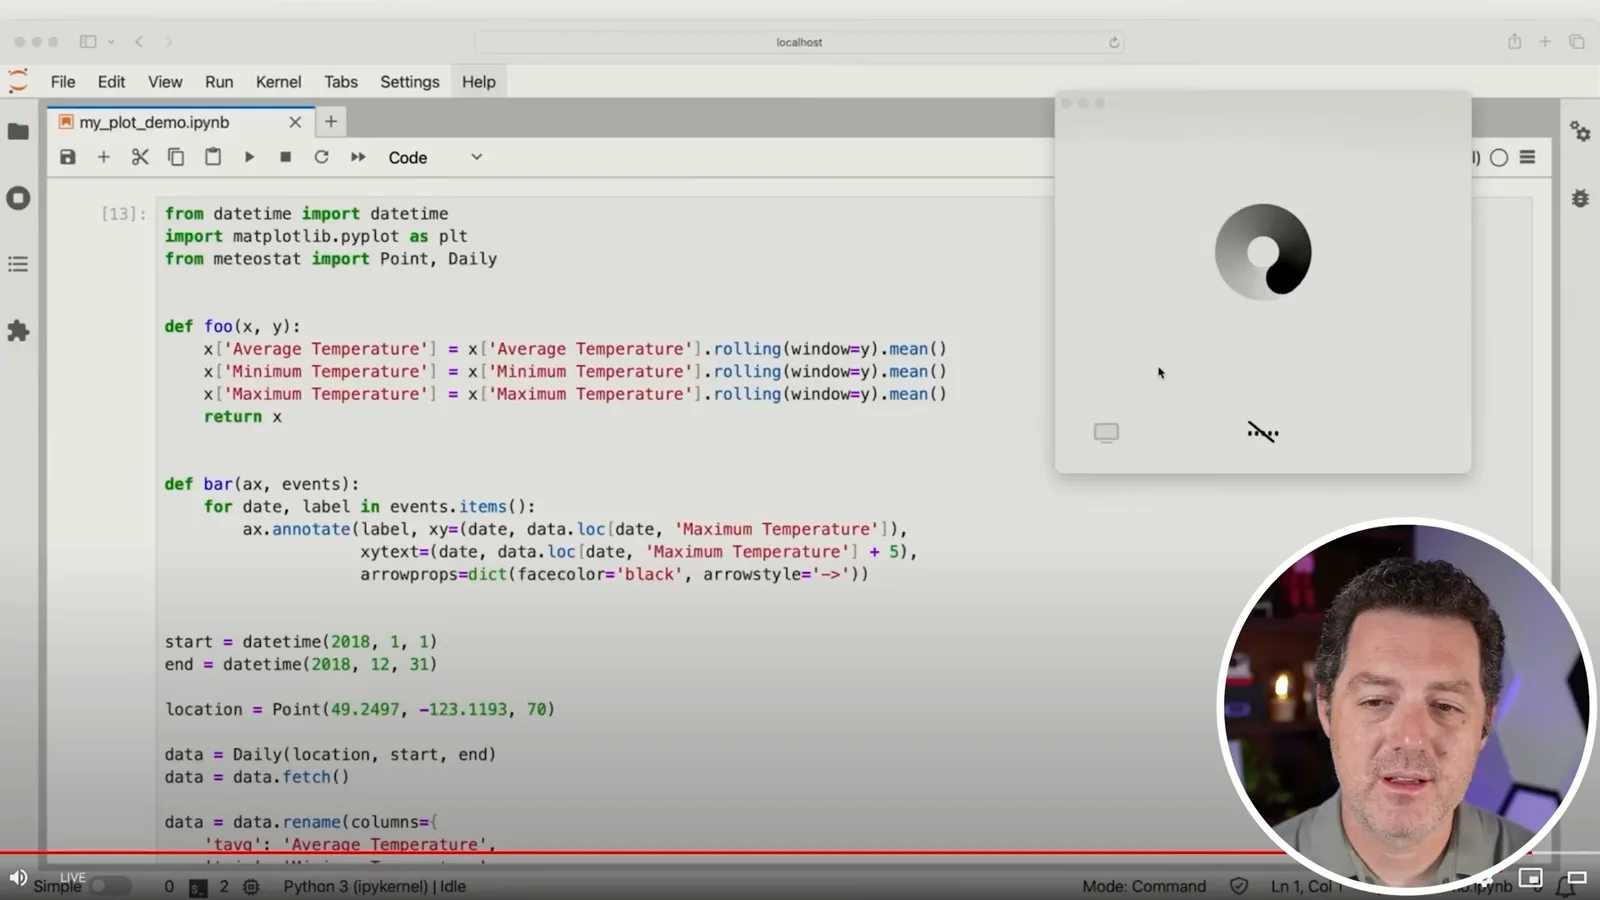
On a desktop, the team shares code from a notebook and asks the assistant to explain it and discuss a plotted result.
Another demonstration uses the assistant as an interpreter between English and Italian, illustrating a possible real-time translation workflow.
Camera limitations and what's next
The selfie demonstration exposes a camera mix-up, and Berman reflects on future agent capabilities.
A selfie demonstration asks the assistant to comment on a person's expression. It first describes the wrong camera view and must be corrected; a face alone cannot reliably establish someone's emotional state.
The event closes with OpenAI's view of future AI interaction. Berman adds that he wants assistants that can perform useful tasks on a user's behalf, not just hold a conversation.
More from this channel
 25:50EN
 32:20EN
 0:22EN
 45:08EN
 0:32EN
 1:02EN