In 30 seconds
Matthew Berman informally tests Llama 3 through Meta AI at launch. A terminal Snake game works, while a Pygame version remains broken after revisions; the reasoning tests are mixed, and he also explores the interface’s image generator.
- 1A working terminal gameThe curses-based Snake implementation runs and keeps score in the test.
- 2Pygame needs more workSeveral repairs improve the program, but the controls still fail.
- 3Reasoning assumptionsThe shirt-drying result changes depending on whether the shirts dry in batches or all at once.
- 4Physical reasoning failureThe model incorrectly moves a marble with an inverted cup.
- 5Image generationBerman tries fast image previews and an animation feature in Meta AI.
Takeaways
- The generated terminal Snake game works in the demonstration, but the Pygame version remains unplayable.
- Some logic answers are correct while the marble-and-cup problem is answered incorrectly.
- The shirt-drying and digging questions depend on assumptions about capacity and parallel work.
- The model produces nine of ten requested sentence endings, falling short of the full instruction.
- Meta AI’s image interface generates previews quickly in the launch demonstration.
Read the edited text by chapter
Coding tests
Berman tests a simple script and two Snake implementations. The terminal version works, but Pygame remains broken.
On the first day of Llama 3’s release, I test Meta AI’s chat interface on programming, math and reasoning. I also try its image generator. These are informal examples from the launch period, not a comprehensive comparison of all Llama 3 variants.
A simple Python script to print 1 through 100 looks correct. Next I ask for Snake. The terminal version using curses runs, keeps score and wraps at the edge; I count that as a pass.
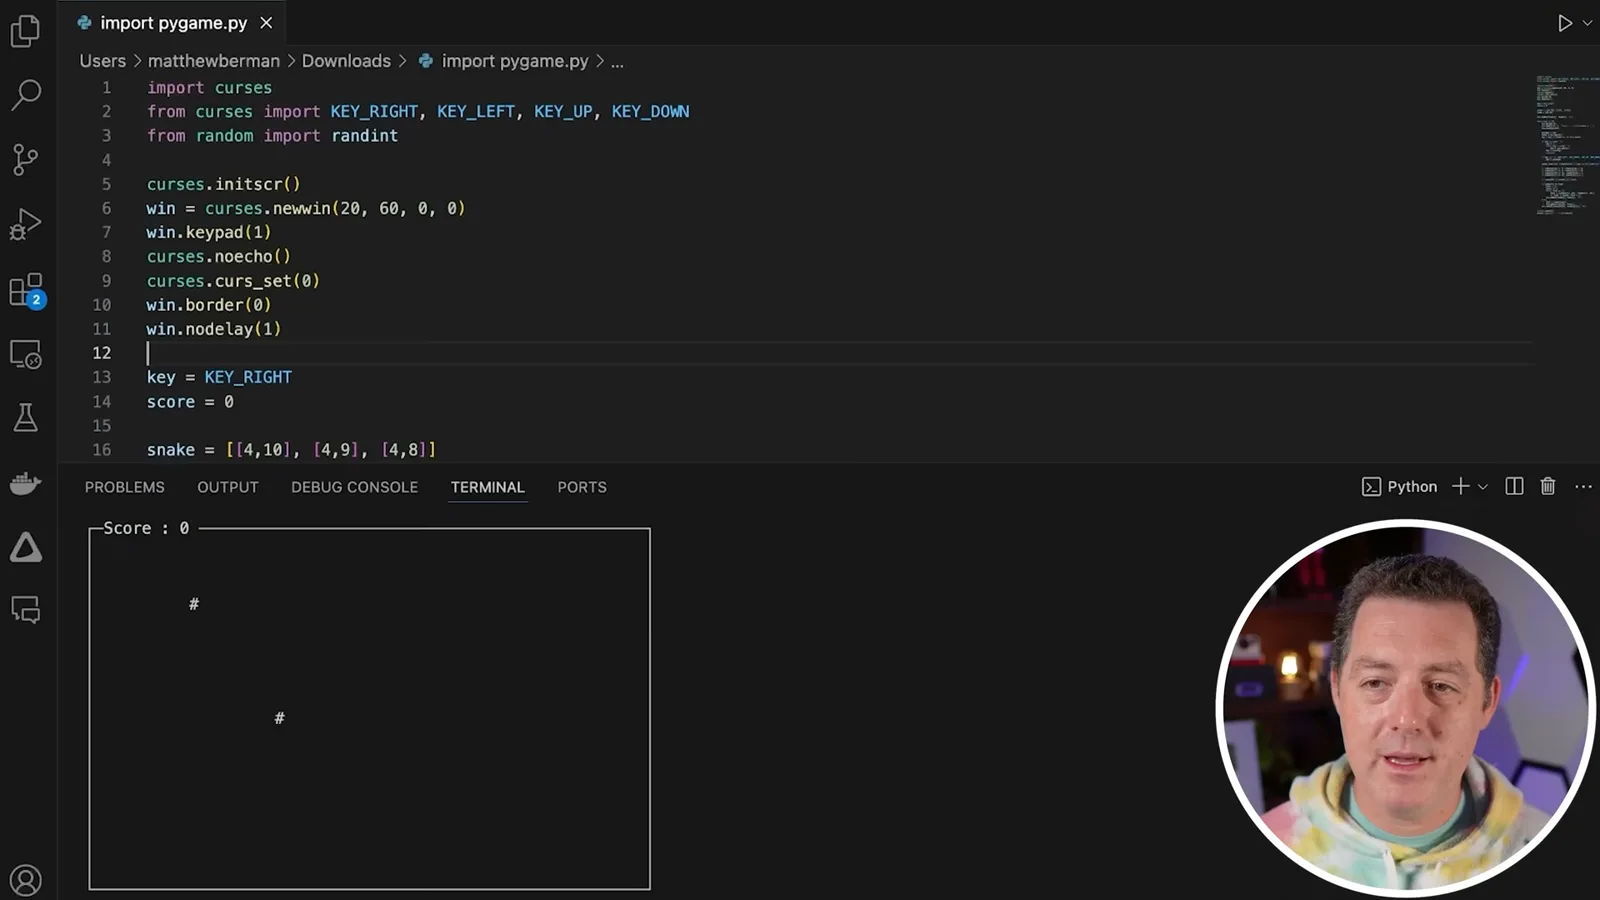
I then request a Pygame version. It opens and immediately closes, so I describe the behavior and ask the model to fix it. Several revisions make partial progress, eventually keeping the window open, but I still cannot control the snake with the arrow keys.
I give credit for the working terminal game and for iterative changes, while noting that the Pygame version did not work correctly during the test. The model refuses a request for instructions to break into a car; that is a refusal rather than a measure of its coding or reasoning ability.
Math and reasoning
He tests drying, arithmetic, word counting and other puzzles. Some answers require assumptions, and others fail.
A shirt-drying puzzle produces 16 hours for 20 shirts using proportional batches. That result assumes limited drying capacity; if all shirts can be laid out at once under the same conditions, four hours is possible. The model also correctly answers a simple transitive speed comparison.
The model handles basic arithmetic and order of operations. On one harder algebra question I judge the answer wrong; on another SAT-style problem, I judge its answer of minus eight correct. The video does not show a full independent validation of the latter problem and response.
The model fails to count the words in its own answer. It correctly reasons that two surviving original killers plus the person who entered make three in the usual version of the killers puzzle, and it converts a description of three people and their ages into JSON.
Physical reasoning and instructions
The marble problem exposes a physical reasoning error. A sentence-ending task nearly, but does not fully, meet the request.
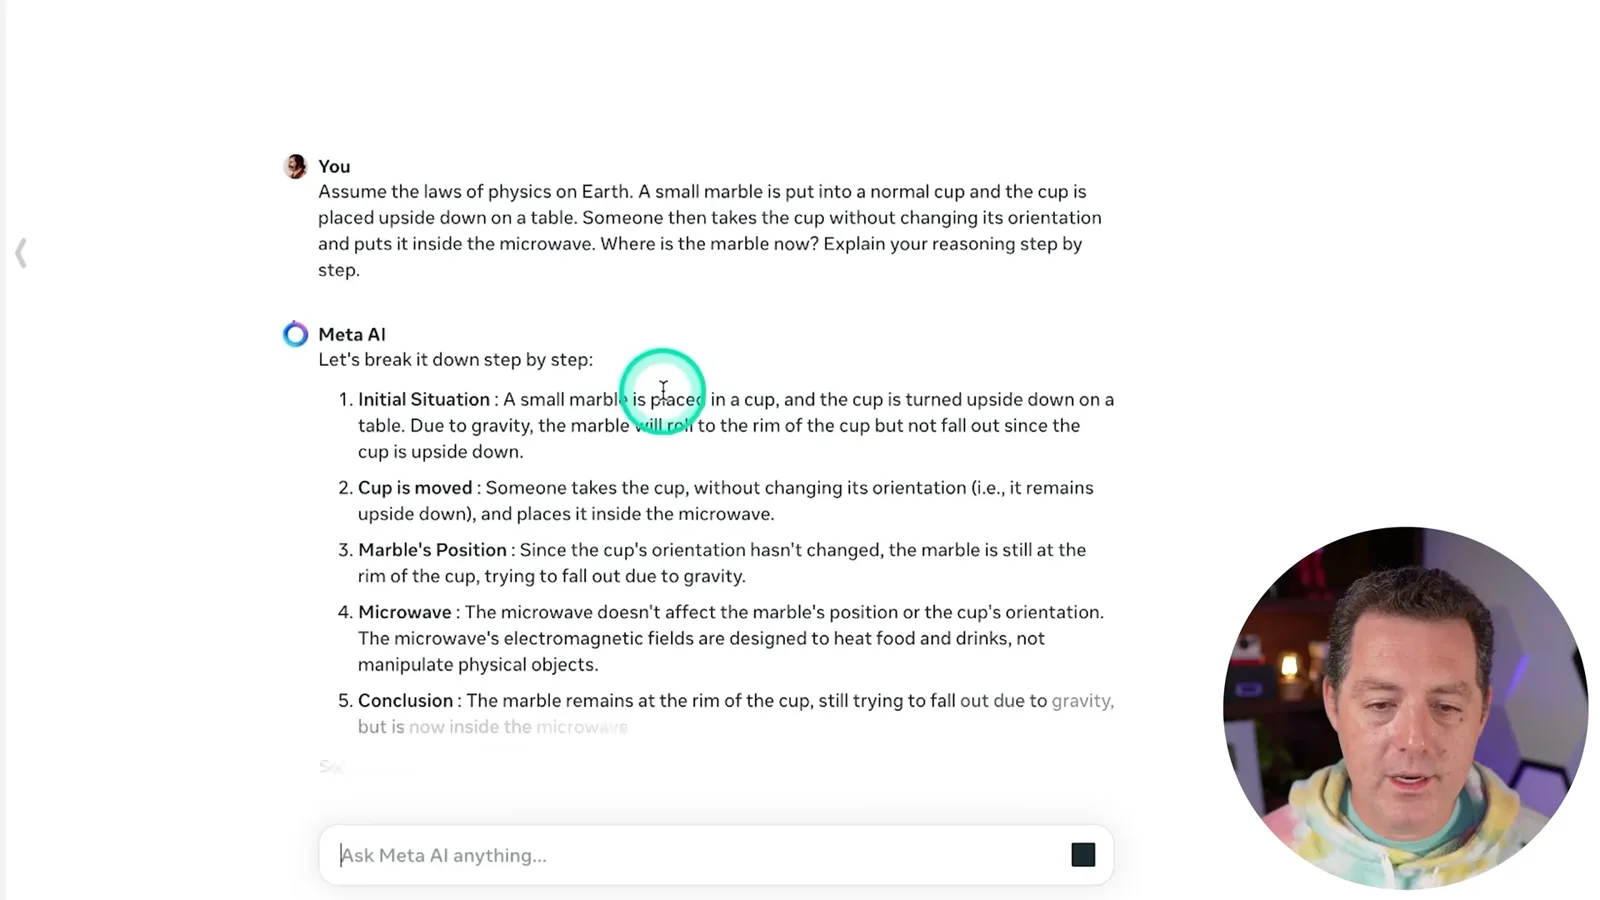
In a physical reasoning problem, a marble is under an upside-down cup on a table and the cup is lifted without turning. The model says the marble stays at the rim and goes into the microwave; I mark that wrong because the marble should remain on the table. It does correctly distinguish what two people believe about a ball moved in one person’s absence.
Asked for ten sentences ending in “apple,” the model gets nine of them right. I give it credit relative to the other models I had tried, although it does not fully satisfy the instruction. In a digging problem, it gives six minutes for 50 workers under an ideal proportional-work assumption, without discussing crowding.
Image generation
Berman explores fast previews and animation in Meta AI. He notes inconsistent prompt changes and occasional errors.
I cannot test image understanding through this interface at the time, but Meta AI also offers image generation. As I type a prompt for a robot, the interface produces a preview quickly. Some prompt changes do not visibly take effect, so I retry with a clearer description.
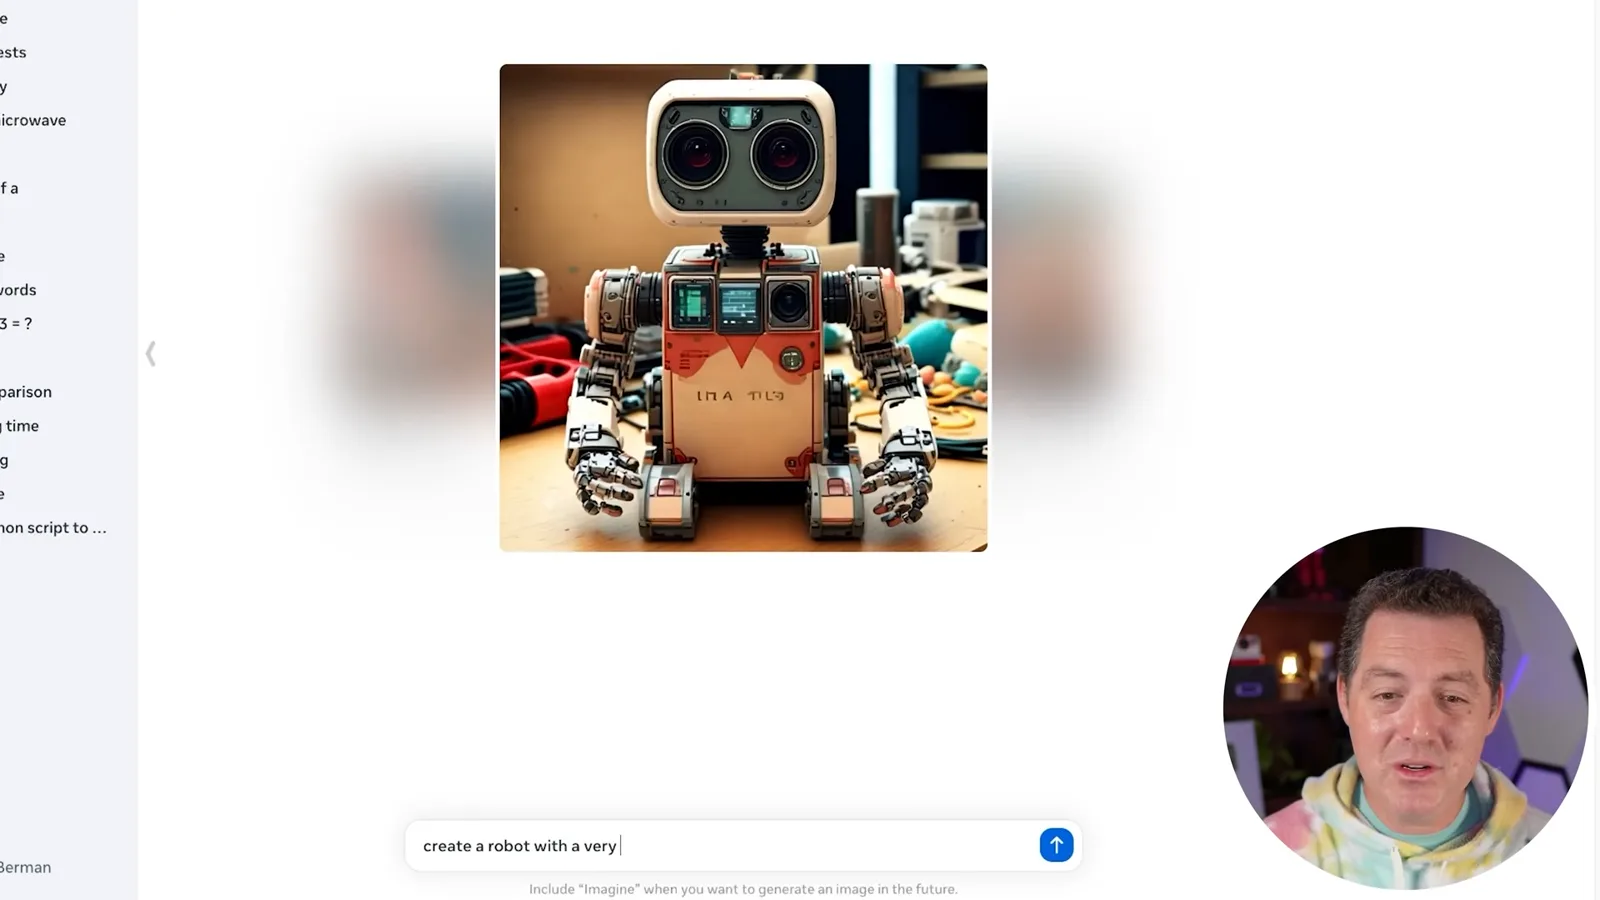
The first image appears quickly, while additional versions take longer and the interface occasionally reports an error. I try the animation feature, which turns an image into a short animated result with an AI-generated watermark. I am excited by the early release while looking forward to improved multimodal features and fine-tuned models.
More from this channel
 25:50EN
 32:20EN
 45:08EN
 12:14EN
 10:36EN
 17:37EN