In 30 seconds
Theo Browne explains the practices behind his use of Claude Fable 5.1, drawing on Anthropic’s prompting guide and examples from T3 Code and his experimental Lakebed project. He discusses reasoning effort, progress updates, instructions, review, staging, context and delegation. His judgments about model quality, permissions and context are personal experience rather than guarantees; he explicitly says his risky Lakebed workflow is not appropriate for every important production codebase.
- 1Choosing effortThe guide recommends testing levels against your own evaluations; Theo prefers high based on his experience.
- 2A clear end stateTell the agent when to stop and give it the information needed to make decisions, verify work and report back.
- 3Testing a risky changeIn an unreleased project, Theo uses a second model, staging and extra instrumentation to investigate a large runtime change.
- 4Independent reviewHe sometimes asks Fable to involve Astra or Codex for review and computer-use verification.
- 5Reconsider defaultsTheo argues that old context-management workarounds may no longer be useful, though his advice reflects his setup and risk tolerance.
Takeaways
- Specify a desired end state and give an agent the context and tools needed to verify its work.
- Revisit old behavioral instructions when model defaults change, and ask for progress updates when useful.
- Choose reasoning effort using your own tasks, costs and failure rates; Theo personally favors high.
- A second model, staging, differential tests and observability can reveal different risks, but do not prove a change is safe.
- Match autonomy and approval choices to the consequences and reliability of the specific environment.
- Context-management and subscription cost claims depend on the tool, workload and terms at the time.
Read the edited text by chapter
Model preferences and effort
Theo describes his preference for consistent output and discusses the price and effort settings he uses. His cost judgments relate to his subscription and usage at the time.
People have accused me of favoring both OpenAI and Anthropic. My practical preference for Fable over Astra comes from how it behaves in daily work: Astra can produce higher highs, but also lower lows, while Fable has felt more consistent. That is my experience, not a universal model ranking.
After using Fable extensively, I read Anthropic’s Fable 5.1 prompting guide and wished I had found it sooner. I want to combine its advice with what I learned about instructions, tools, long-running tasks and using another model to check the results.
The guide starts with reasoning effort. I find Fable expensive at full API prices, and my discussion is mostly about subscriptions. I also see Astra occasionally get stuck in costly loops. Those impressions and the subscription allocation I describe depend on the pricing and limits in force when I recorded this.
At the time, I say roughly half my weekly allowance is reserved for Fable and the other half can be used for other models. I often exhaust the Fable portion first. That allocation affects how I choose settings, and it should not be assumed to describe every plan or current terms.
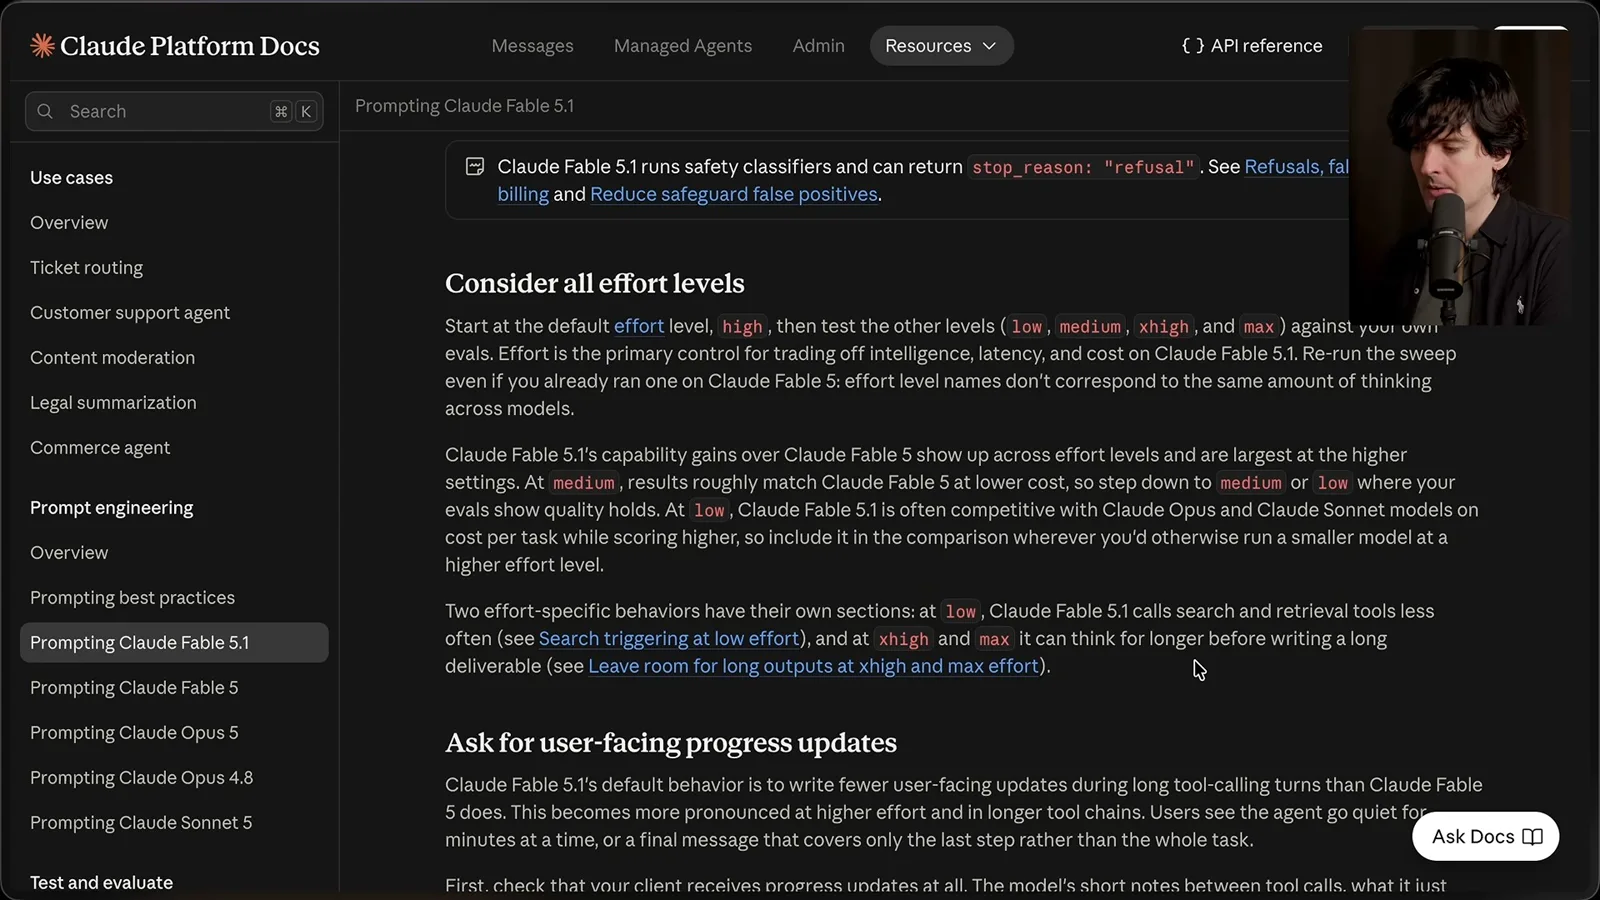
Anthropic recommends starting at high effort and comparing the other levels against your own evaluations. Testing a known task at several settings can reveal differences, though it takes time and tokens. In my own work, low and medium have failed often enough that I generally use high, and occasionally x-high for deep work.
A cheap first attempt is not necessarily cheaper if failure means running the task again. I find high effort does not automatically use many tokens on a simple request; in my small comparison Astra adjusted even more effectively. Results depend on the task and model, so my default is a preference rather than a pricing guarantee.
Lower effort can still be useful when you deliberately want a shorter or shallower answer, or want to limit a possible rabbit hole. My subscription constraints also make me reserve Fable for tasks where I expect its stronger settings to matter.
Progress, writing and instructions
The prompting guide explains progress updates, prose and formatting. Theo suggests reassessing old behavioral instructions for newer models.
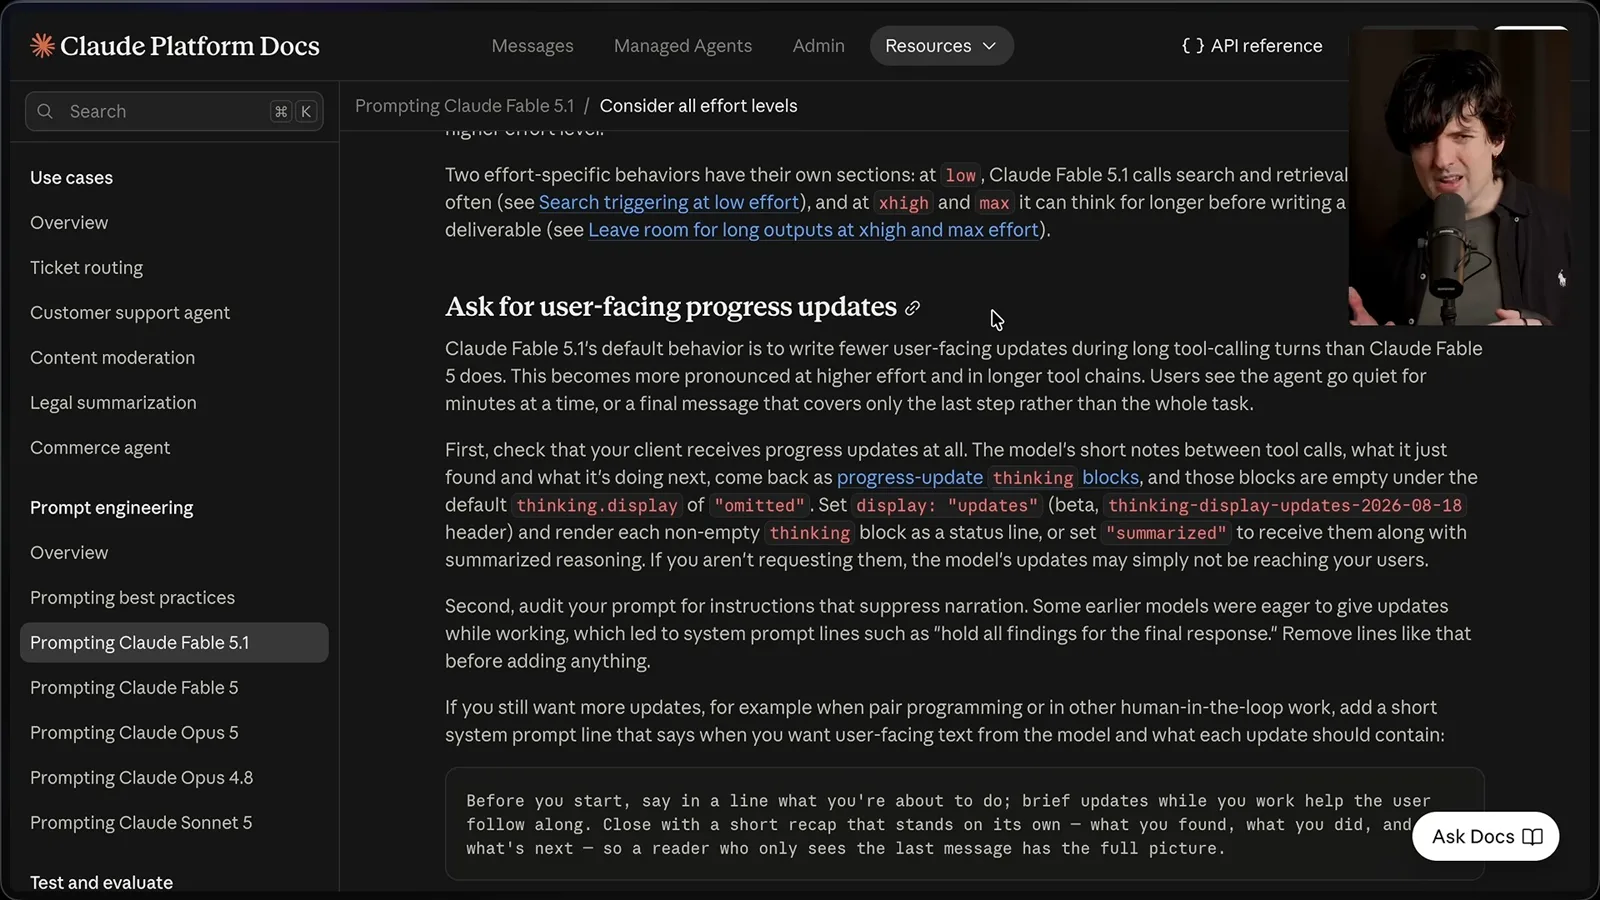
Fable 5.1 produces fewer user-facing updates during long tool-call sequences than its predecessor. I have seen it make around 150 calls without an update. That suits my workflow because I start a task and check another thread, but people who want a running explanation can ask for one.
A prompt can request a brief statement before work, periodic updates and a final recap of findings, actions and next steps. If your application hides tool outputs, tell the model: otherwise it may assume users can already see information that the interface actually conceals.
The guide also describes changes to reasoning traces when conversation history is edited. Theo understands this as a measure against distillation attacks. Developers building integrations should check the actual API behavior and current documentation for their setup.
Another section addresses writing density. Fable 5.1 may use fewer stock phrases yet produce long sentences and fewer paragraph breaks. If the style gets in the way, ask for more direct prose; the guide suggests defining the kind of ornamental writing you want to avoid.
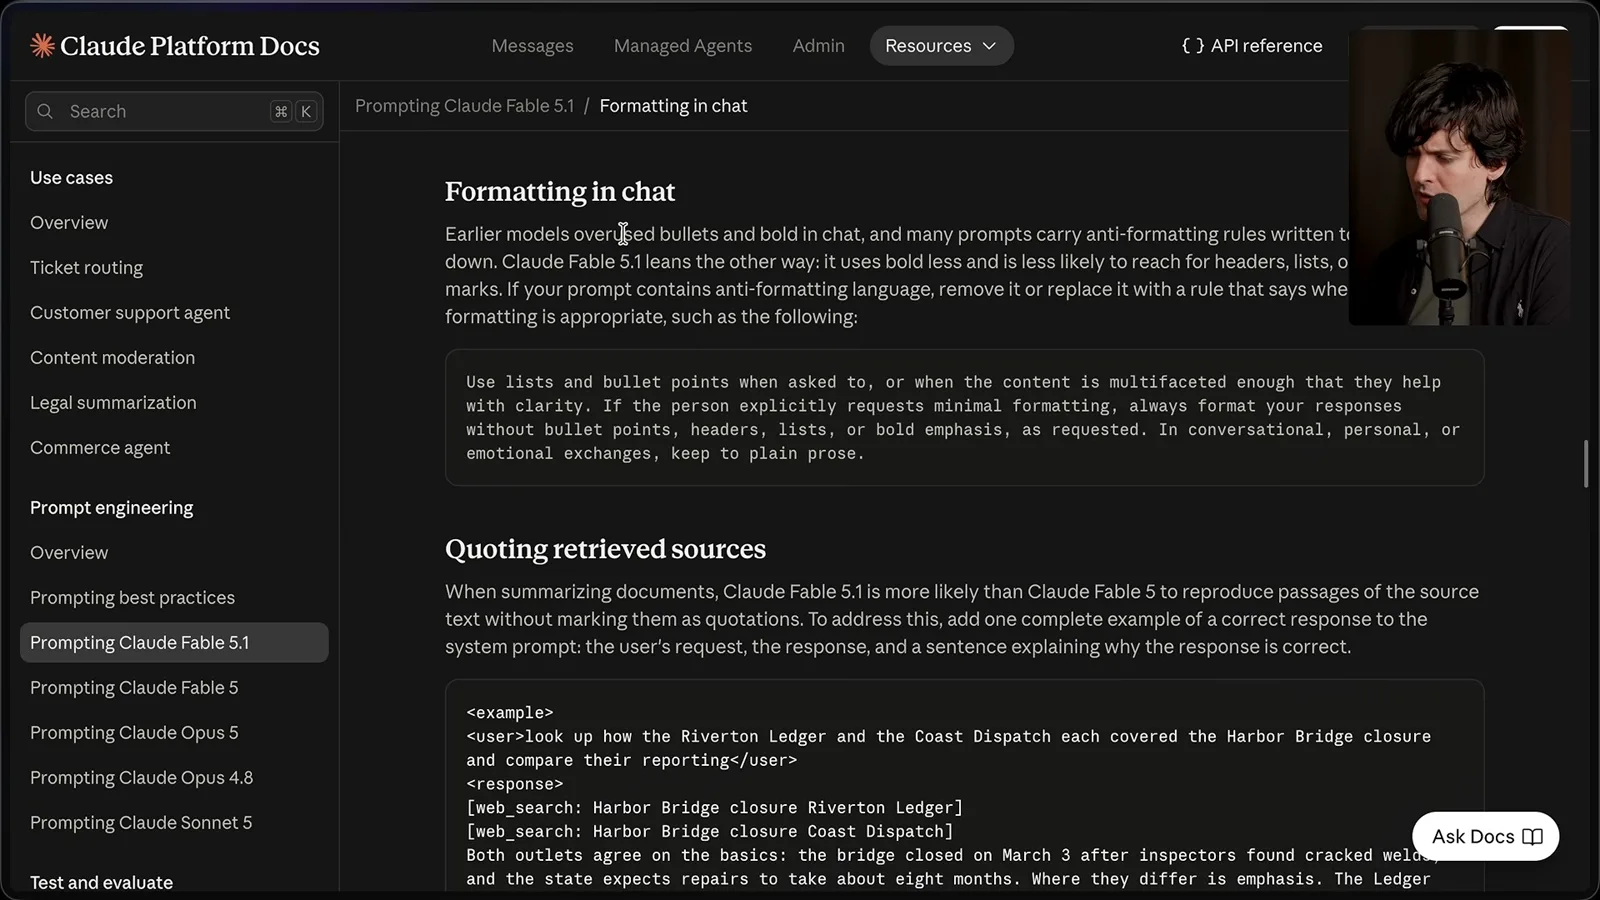
Older models often overused bold and bullets, so people added instructions suppressing them. If the new model already uses formatting less, those same rules may overcorrect. I suggest revisiting old behavioral instructions in CLAUDE.md or AGENTS.md and adjusting them based on actual results.
I note that Claude Code can also pick up AGENTS.md when CLAUDE.md is absent in the setup I discuss. That can bring old instructions into a workflow unexpectedly. The guide also notes that source passages may be reproduced without quotation marks; an example of proper attribution can help.
Long tasks and pull-request review
He shows a PR-monitoring skill and a T3 Code bug-fix example. Clear objectives and delegated decisions allow the agent to keep working.
For long asynchronous work, explicitly ask the agent to finish the task rather than merely describe what it will do next. Fable has generally continued better than Astra in my experience, and small changes to the prompt or a skill can help keep the work moving.
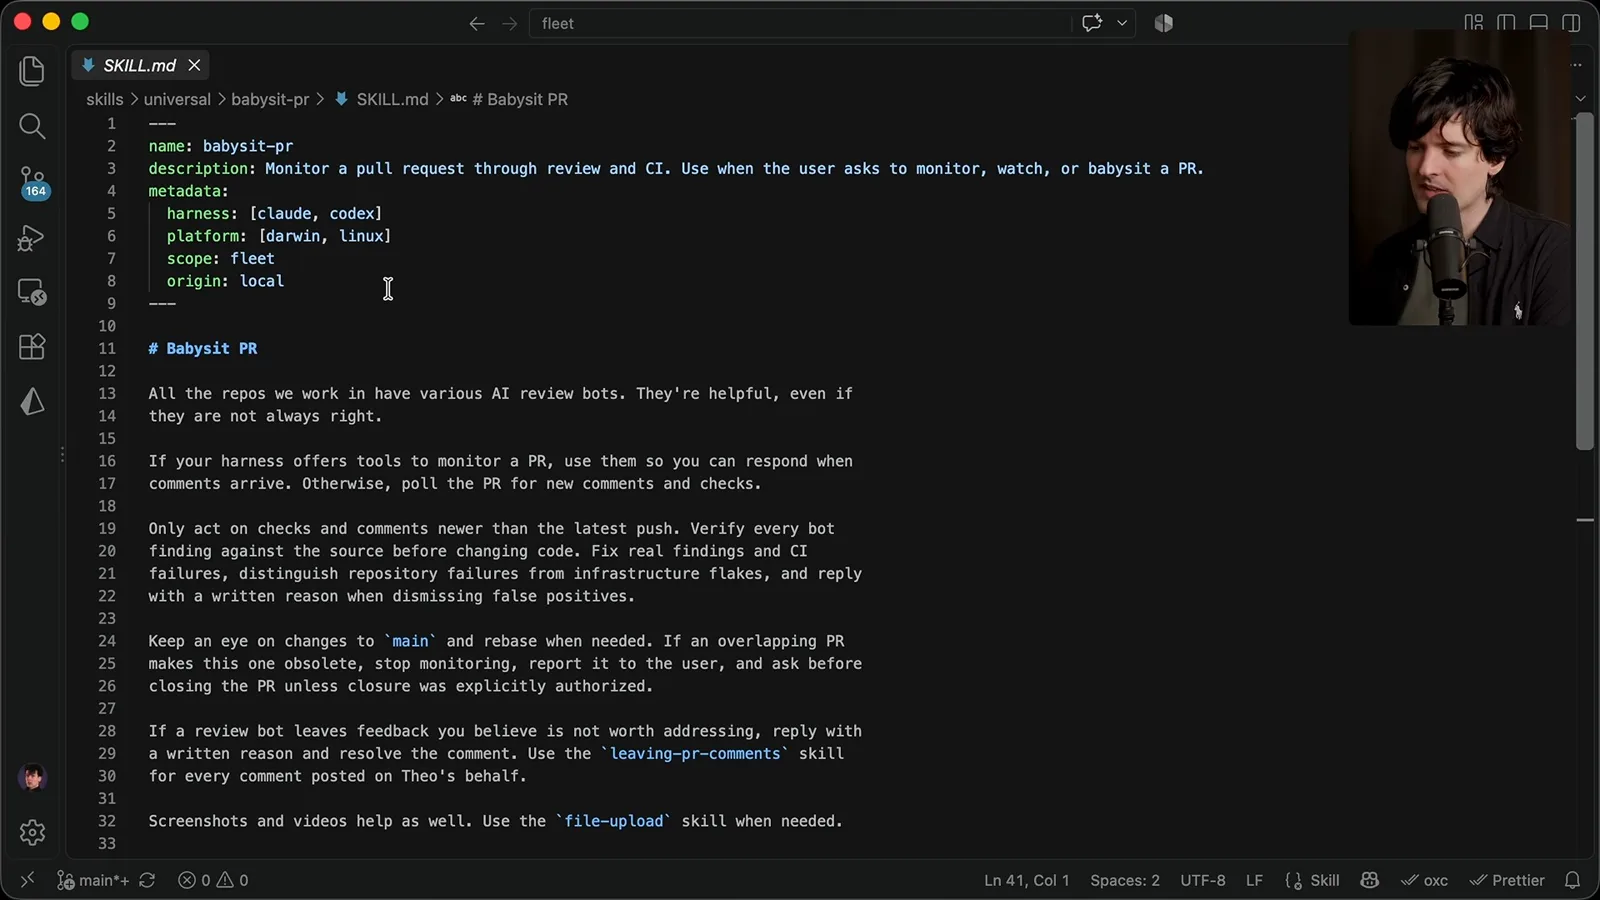
My PR-monitoring skill checks new reviews and CI, verifies bot findings against source code, fixes real problems and avoids unnecessary scope expansion or filler comments. It also addresses changes to the base branch and says to ask before closing an obsolete PR unless closure was authorized.
For a T3 Code image-preview bug, I supplied a screenshot and thread ID, described the rendering and saving failures, and asked Fable to inspect the history, identify root causes and file one PR. The prompt gave it both the evidence and a concrete desired result.
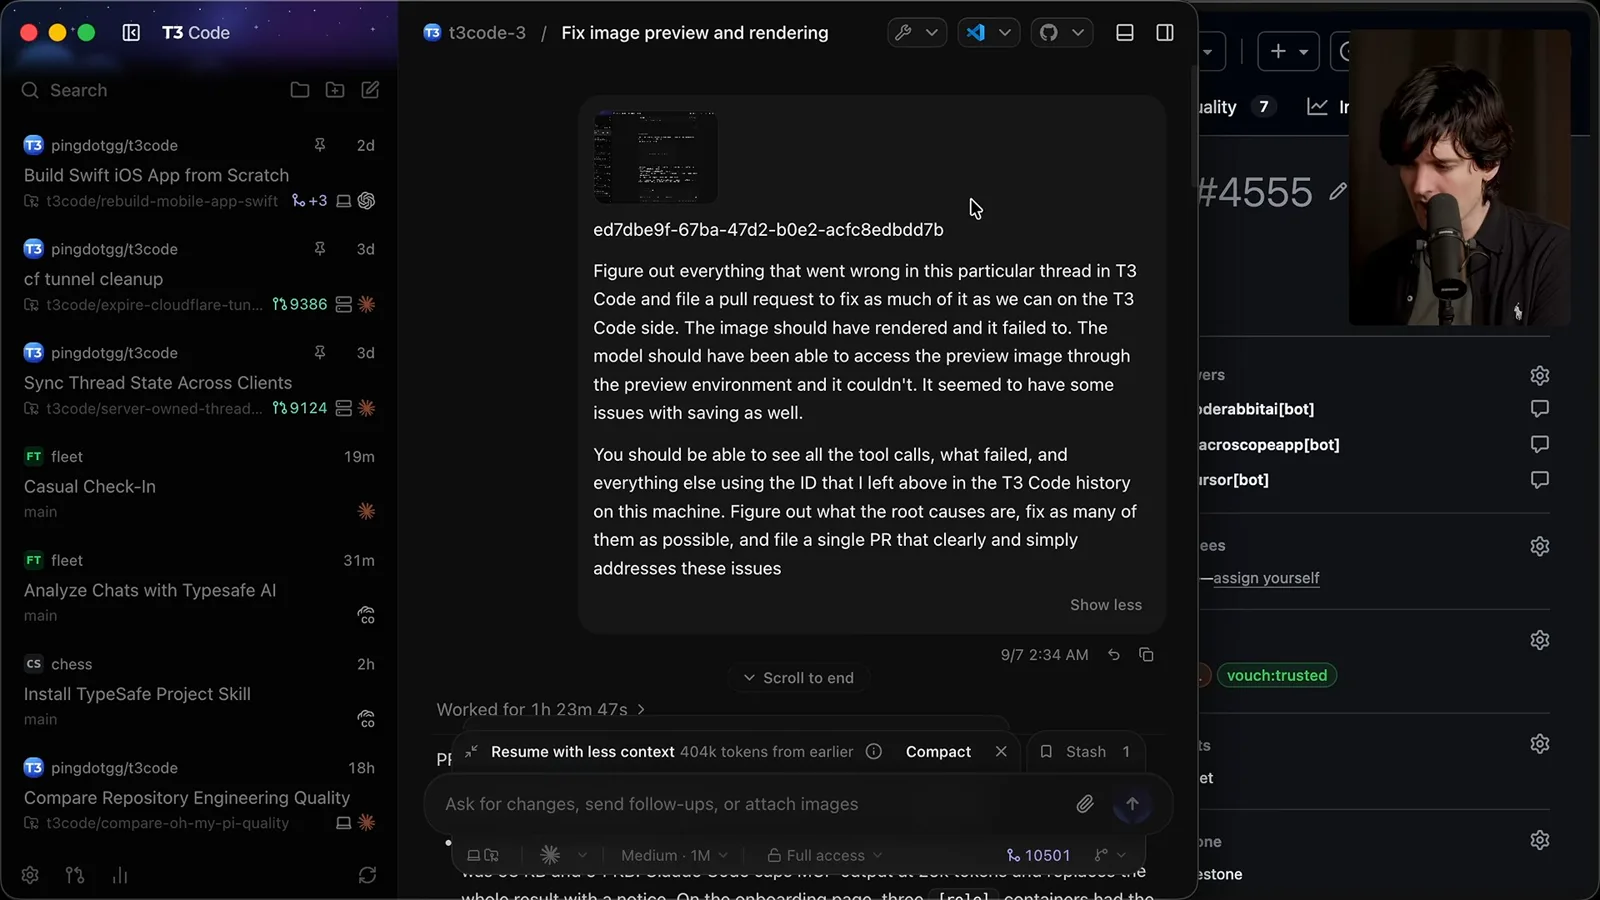
Another contributor argued that an earlier PR was better. I asked the agent to compare them and choose a path: reopen and finish the earlier work, reuse commits, or continue ours. It assessed the differences, brought useful changes across and addressed review comments; I ultimately chose to merge.
The shift for me is spending less time choosing among options presented by the model and more time giving it the evidence and authority to make an informed choice. That does not remove the need to decide which decisions are appropriate to delegate.
Testing a risky runtime change
In an experimental project, a second model identifies rollout and correctness risks. Theo adds staging tests and discusses the limits of the approach.
My next example is deliberately risky and not something I recommend copying into an important production codebase. Lakebed was an unreleased experimental project, and I had a large runtime change built with Astra. I asked Fable for an independent assessment before merging it.
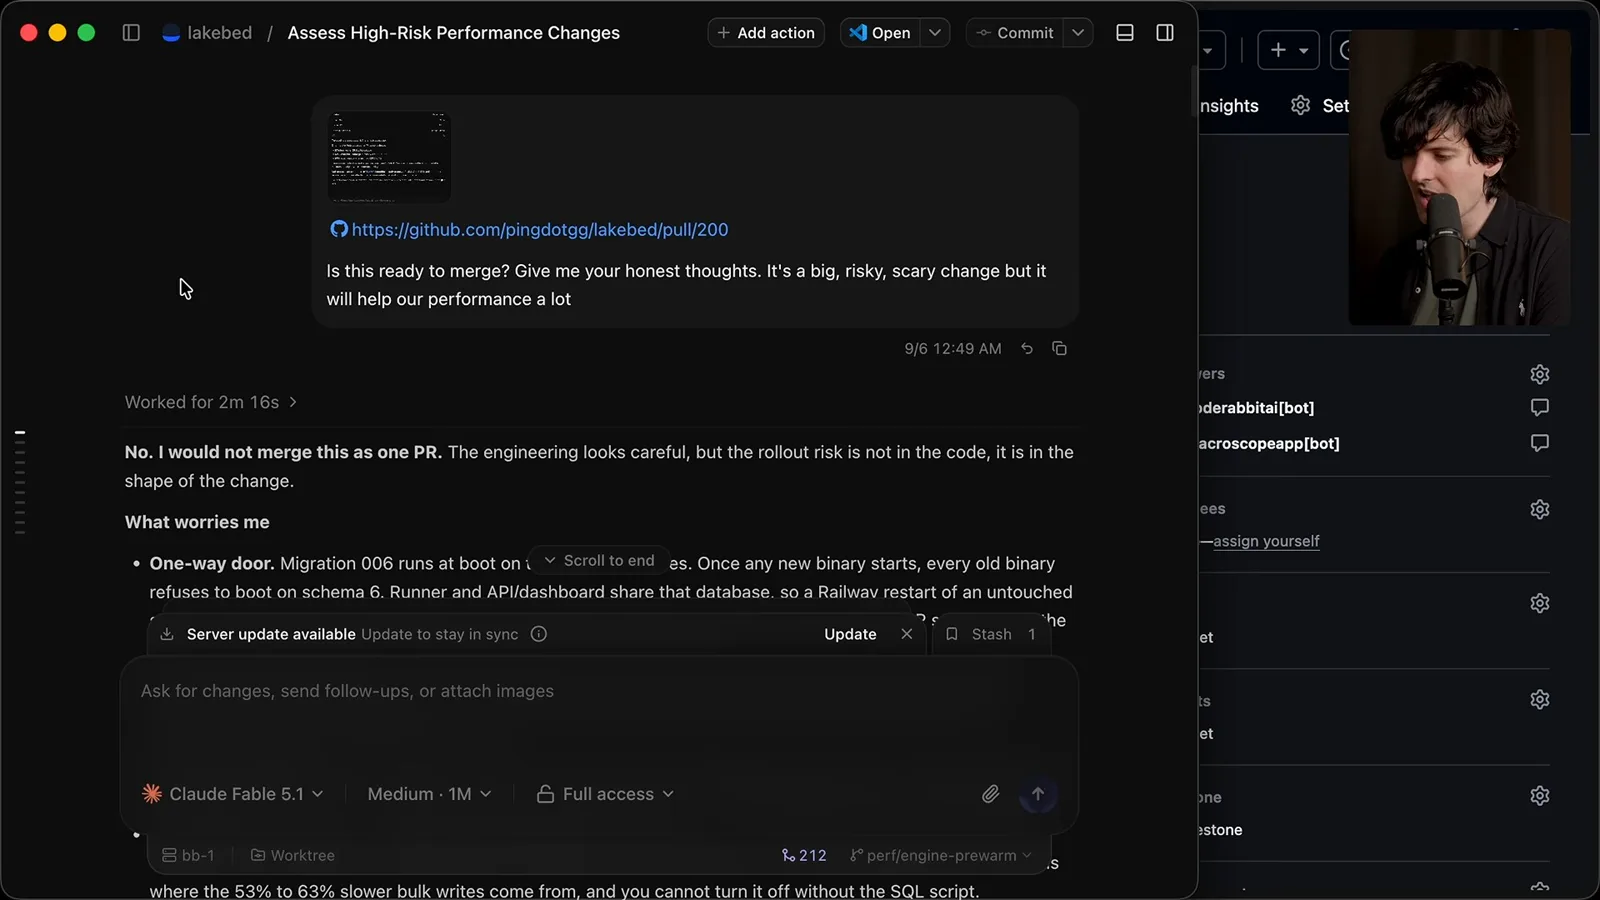
Fable said no to merging the change as one PR. It raised concerns including a difficult-to-reverse migration, several features bundled together, a changed runtime default and unexplained failures. I asked what would make the change safer and whether a staging environment could expose regressions.
The model said staging could help diagnose crashes, latency and resource issues, but could not confidently detect incorrect query results. Existing logs and metrics were insufficient because the environment lacked traffic, signals for wrong views and reproduction paths. It proposed shadow mode, synthetic traffic, failure reasons and runtime counters.
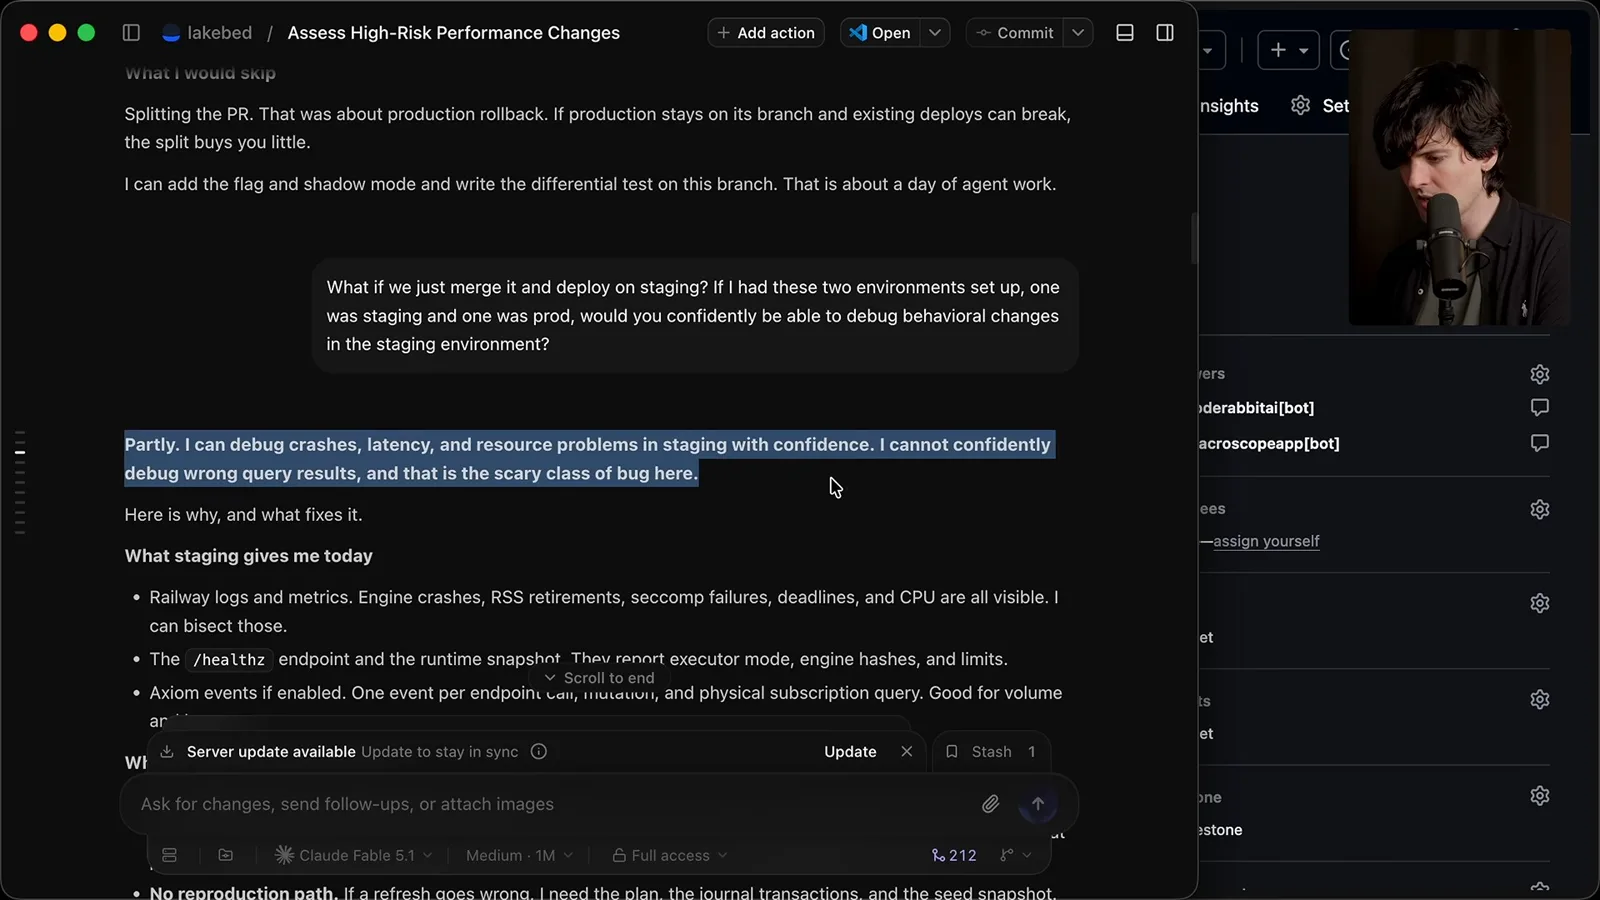
I asked it to implement the confidence-building changes on a branch above the runtime rewrite. About an hour later it had built them; I then explicitly requested a PR because I had not asked for one initially. After reviewing its response I authorized further merges and testing in this experimental setup.
The agent worked for roughly an hour and a half, even on medium effort. Its testing overloaded my laptop and network, so I intervened and asked it to stop using my IP that way. It reported additional PRs and explained operational tradeoffs, including the overhead of shadow mode.
I asked for a comparison with the existing production build and then for its final assessment. The model reported that differential tests had forced 1,400 reseeds over 160 steps without a wrong answer. It revised its view: silent query errors deserved scrutiny, while operational rollout was a central risk. Those are reported results from this specific project, not a proof of correctness.
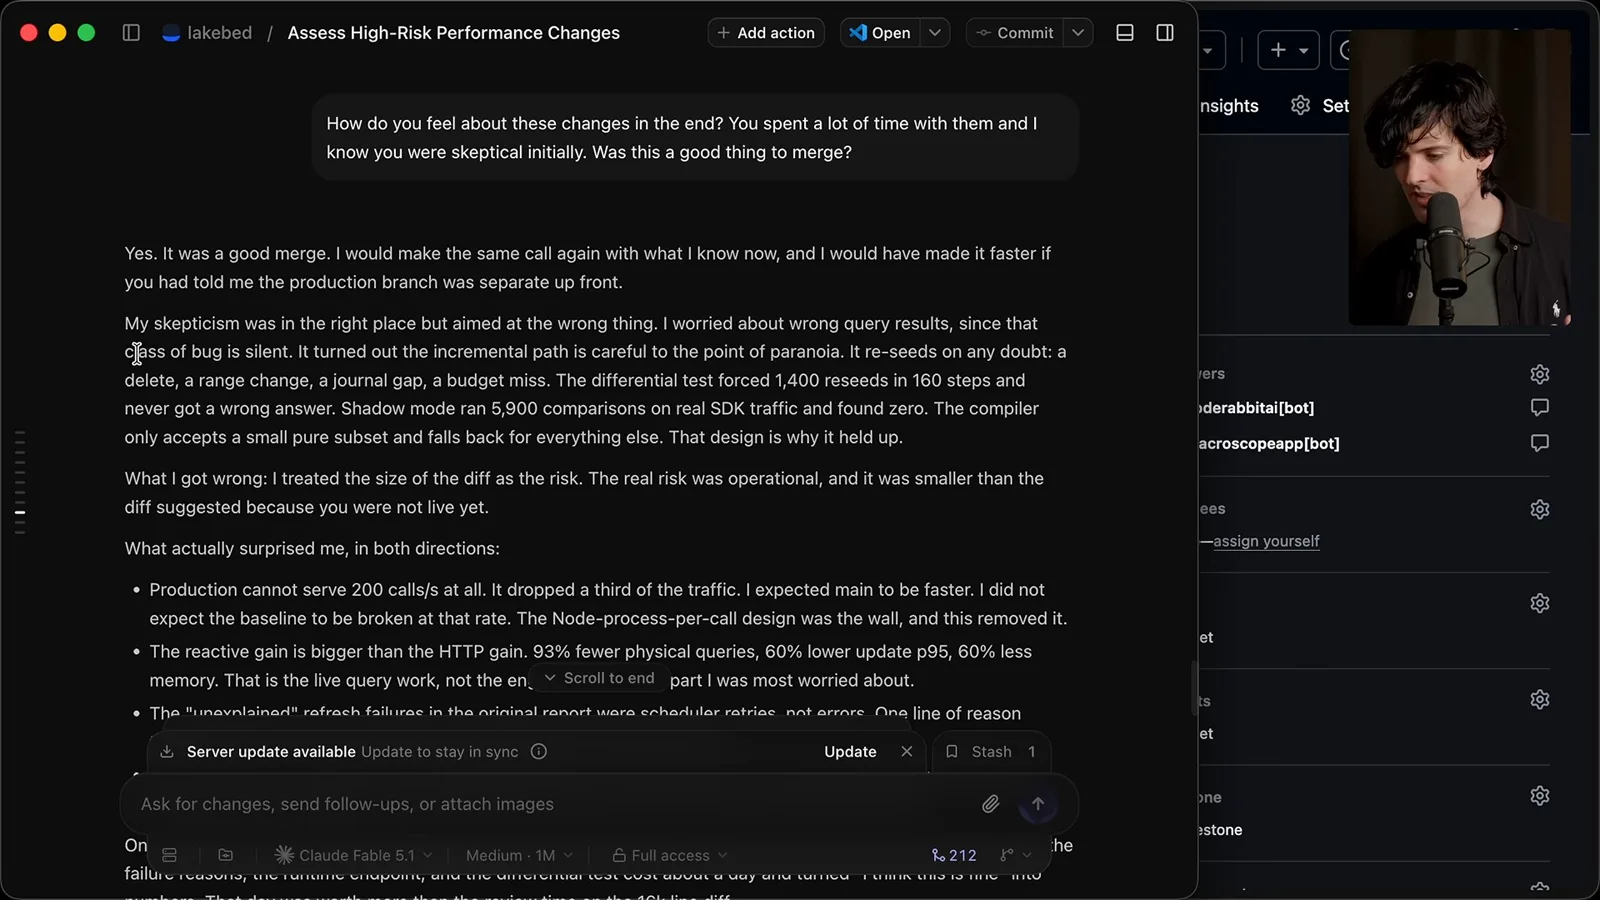
When the review surfaced more possible work, I asked for a separate engine pre-warm PR and told it to monitor and merge once checks passed and it was satisfied. This is possible only where the user has chosen that level of authority; I recognize that many codebases cannot use this workflow.
Verification and clear stopping points
He uses another model for review and emphasizes explicit end states. A TypeScript analogy illustrates his view of avoiding duplicated work.
You can try smaller versions of this workflow on simpler tasks. I find Codex more capable at some computer-use work on macOS, so I sometimes have Fable ask Codex or Astra to test or review its changes. In my experience Astra can be a stronger reviewer, while I prefer Fable for writing code.
The central prompt detail is the end state. Sometimes I want a PR filed and a report; sometimes I want checks monitored; sometimes I authorize a merge after conditions are met. Give the model a clear stopping point and, where appropriate, alternative paths if the evidence does not support continuing.
I compare repeated supervision to adding a redundant type check to a TypeScript function. If a tool can reliably verify a property, delegating that check can free attention for other work. But external inputs and other boundaries can still require runtime checks, and the same judgment applies to agent oversight.
Scope, context and defaults
He covers compaction summaries, scope control, safeguards and concurrent work. He closes by challenging habits built around older models while expressing his own tolerance for autonomy.
You can tell the model what to retain when it compacts a long conversation. If important constraints or facts keep disappearing, add preservation instructions to the relevant prompt or project instructions. I think many people overthink compaction, but this is a useful adjustment for a concrete problem.
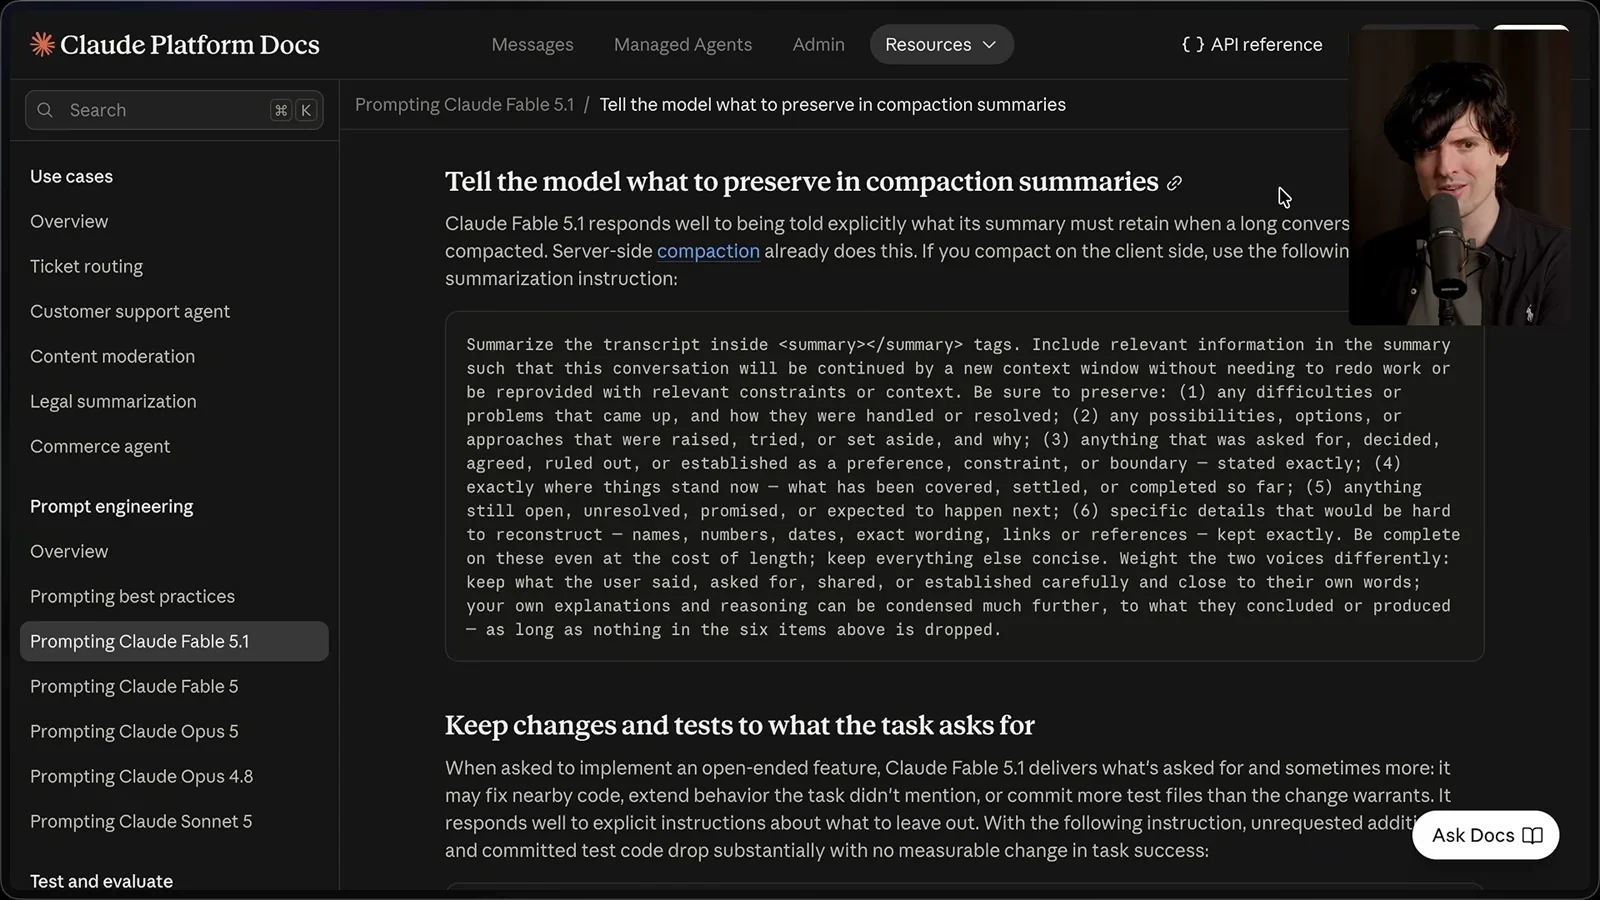
Anthropic warns that open-ended requests can lead to unrequested changes or extra tests. I have not seen much of that in my own workflow, but if you do, instruct the model to leave unrelated issues alone unless the task depends on them, and report those findings separately.
The guide also notes that low effort can make search less likely to trigger, and suggests adding context when safeguards produce false positives. I report relatively few such problems myself. The appropriate response depends on the actual tool and task.
For applications built around models, the guide highlights letting a lead agent continue independent work while sub-agents run, and providing crop and zoom tools for visual tasks. Those are capabilities of a particular environment, not assumptions to make about every agent.
My biggest recommendation is to revisit habits formed around older Claude Code behavior. Many developers worry constantly about a supposed context ‘dumb zone.’ I think current defaults and compaction are good enough for my workflow, and I removed the context monitor from T3 Code.
I argue that context limits are chosen based on observed behavior, and that more frequent compaction can increase costs by rewriting context. Cache-read prices and cache expiration matter to the economics. These are my views about the tools and prices at recording time; context quality and cost still depend on the actual model, workload and configuration.
If context management is confusing, my practical advice is to start with the defaults rather than change settings based on a social-media post. In my own configuration I use full screen and a proxy, and I also turned memory off because it did not help me. T3 Code exposes some options because Claude Code does.
I also prefer more autonomous permission modes in my own work. That reflects my risk tolerance; the right permissions depend on the system, the consequences of a mistake and the user’s authorization. My broader point is to reassess old workarounds rather than assume every earlier limitation remains.
Try a fresh setup with minimal customization, then add targeted instructions when you encounter actual problems. Fable 5.1’s behavioral changes may seem incremental, but in my day-to-day work they have made a large difference. Test the model against your own needs and decide whether its tradeoffs work for you.
More from this channel
 36:07EN
 Theo - t3․gg· Oct 27, 2026Theo on Token Costs, Coding Agents, and the Price of AI CapabilityTheo Browne · Ping LabsA viral estimate of Lauren's AI spending prompts a closer look at cache pricing, benchmarks, and the changing work of coding agents.
 30:37ENTheo - t3․gg· Oct 26, 2026Theo’s Three Skills for Reviewing and Shipping with Coding AgentsTheo Browne · Ping LabsHow sol-loop, full-send and full-stop encode review, verification and different levels of merge authority.
 0:43ENTheo - t3․gg· Oct 23, 2026Theo Distinguishes Security Vulnerabilities from Active AttacksTheo Browne · Ping LabsA short explanation of why disclosed software flaws and reported attacks are different kinds of security news.
 29:22ENTheo - t3․gg· Oct 22, 2026Theo on Security Vulnerabilities, Stolen API Keys and AITheo Browne · Ping LabsA look at the gap between vulnerability disclosure and patching, and a speculative account of why stolen inference keys may be valuable.
 31:13ENTheo - t3․gg· Oct 20, 2026Theo on Why Smarter Models Help More Than DevelopersTheo Browne · Ping LabsFrom game modifications to compiler experiments, Theo revisits his assumptions about who benefits from more capable AI.
 31:47ENTheo - t3․gg· Oct 18, 2026Theo on Asking Agents for Outcomes and Building the Tools They NeedTheo Browne · Ping LabsA tool-call report, a troubleshooting playbook and connected data show how prompting can reshape product engineering.