








Results
52 articlesSort
 25:50EN
 Matthew Berman· Oct 24, 2026Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.
 32:20ENMatthew Berman· Oct 23, 2026Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.
 1:03:37ENMatthew Berman· Oct 23, 2026Matthew Berman’s Team Tests Kimi K3.1 on Animation, Games, and ChartsMatthew Berman, Alex, Brian · Forward FutureA live team AMA turns into an informal test of Kimi K3.1, from personal-agent workflows to motion graphics, a browser game, and a benchmark chart.
 21:29ENMatthew Berman· Oct 7, 2026Mistral Large 4 Preview: European Open Weights, Cyber Benchmarks and Setup FrictionMatthew Berman · Forward FutureMatthew Berman reviews the model’s reported specifications and benchmarks, then tests it in an agent coding workflow.
 20:46ENMatthew Berman· Aug 26, 2026Open-Weight AI Models: Token Share, Spending and Strategic TradeoffsMatthew Berman · Forward FutureMatthew Berman examines a Vercel AI Gateway snapshot and argues that model usage and spending can tell very different stories.
 13:09ENMatthew Berman· Aug 14, 2026AI News: Ultrafast Inference, Claude Watermarks and New ModelsMatthew Berman · Forward FutureMatthew Berman reviews an ultrafast coding preview, text watermarking, Grok Bot, open-weight models and Computer History.
 15:37ENMatthew Berman· Aug 4, 2026Matthew Berman on Qwen3.8-Max, AI Costs and Open-Weight CompetitionMatthew Berman · Forward FutureA 2026 review of reported benchmark results and research demonstrations leads to questions about deployment economics and geopolitical dependence.
 52:29ENMatthew Berman· Jul 24, 2026Claude Opus 5: Benchmarks, Cost per Task, and Early ImpressionsMatthew Berman · Forward FutureMatthew Berman reacts to the model launch, examines reported benchmark and pricing data, and explains why the cost of completing a task matters more than token price alone.
 27:13ENMatthew Berman· Jul 21, 2026Kimi K3 and the Debate Over Open-Weight AIMatthew Berman · Forward FutureMatthew Berman examines model economics, competition and security arguments after Moonshot AI’s Kimi K3 announcement.
 1:00:47ENMatthew Berman· Jul 15, 2026AI News Live: A Codex Keyboard, Open Models and Agent Safety ResearchMatthew Berman, Alex, Brian · Forward FutureMatthew Berman, Alex and Brian discuss new tools, model costs and a research report, separating initial impressions from verified results.
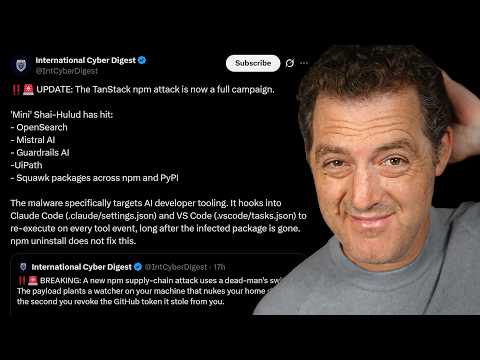 1:42:54ENMatthew Berman· May 12, 2026AI and Cybersecurity: Matthew Berman’s Warnings, Predictions and Open QuestionsMatthew Berman · Forward FutureA livestream reviews reported AI-assisted threats and debates whether stronger defensive models can keep pace with attackers.
 9:47ENMatthew Berman· Apr 3, 2026Gemma 4: Smaller Open-Weight Models for Local AIMatthew Berman · Forward FutureMatthew Berman reviews Google’s model sizes, multimodal features and reported benchmarks, with an eye toward local agents.
 18:09ENMatthew Berman· Dec 15, 2025Training a GPT-OSS 2048 Strategy With Verifiable RewardsMatthew Berman · Forward FutureMatthew Berman walks through a local Unsloth notebook, reward checks and one 2048 training run on an RTX 5090.
 7:49ENMatthew Berman· Dec 2, 2025DeepSeek V3.2: Reasoning, Sparse Attention and Agent TrainingMatthew Berman · Forward FutureMatthew Berman examines DeepSeek’s December 2025 model release, its benchmark results and the techniques used to improve long-context efficiency and tool use.
 1:52:38ENMatthew Berman· Nov 22, 2025Open Models, AI Infrastructure, and Search: Four PerspectivesMatthew Berman, Nick Wentz, Himanshu Tyagi, Misha Laskin, Bryan Catanzaro, Robby Stein · Forward FutureForward Future speaks with leaders from Sentient, Reflection AI, NVIDIA, and Google about openness, scaling, safety, and AI-powered search.
 17:51ENMatthew Berman· Aug 28, 2025AI News in August 2025: Claude for Chrome, New Models and AI InfrastructureMatthew Berman · Forward FutureMatthew Berman reviews a browser-agent preview, model releases, reported Apple discussions and research on inference and weather.
 1:43:51ENMatthew Berman· Aug 8, 2025GPT-5, Cline and SWE-bench: How to Judge AI Coding AgentsMatthew Berman, Matt Wolfe, Ray Fernando, Saoud Razwan, Nick, Ofir, Carlos, John, Kilian · Forward FutureMatthew Berman and guests discuss early GPT-5 impressions, the economics of Cline, and why coding benchmark results depend on the evaluation setup.
 1:01ENMatthew Berman· Aug 5, 2025OpenAI’s gpt-oss Release and a Coding BenchmarkMatthew Berman · Forward FutureMatthew Berman introduces two open-weight models and reviews a Codeforces comparison from the launch.
 15:30ENMatthew Berman· Jul 31, 2025Qwen3 Tested: Coding Demos, Long Context and Response BehaviorMatthew Berman · Forward FutureMatthew Berman tests generated simulations, political and safety prompts, hand tracking and word puzzles using a hosted Qwen3 model.
 33:18ENMatthew Berman· May 1, 2025Zuckerberg and Nadella on AI Coding, Agents and the Next Software StackMatthew Berman, Mark Zuckerberg, Satya Nadella · Forward FutureMatthew Berman examines their 2025 LlamaCon conversation about AI-assisted development, open models and changing workflows.
 7:41ENMatthew Berman· Jan 30, 2025CES 2025 and Running DeepSeek R1 Distills on an RTX 5090Matthew Berman · Forward FutureMatthew Berman tours AI demonstrations at CES and runs two quantized DeepSeek R1 distilled models locally on an NVIDIA GPU.
 5:27ENMatthew Berman· Jan 29, 2025Ways to Try DeepSeek R1: Hosted and Local Distilled ModelsMatthew Berman · Forward FutureMatthew Berman demonstrates DeepSeek chat, Groq’s hosted distill and a local model in LM Studio.
 0:28ENMatthew Berman· Nov 6, 2024Comparing Three Local Coding ModelsMatthew Berman · Forward FutureMatthew Berman introduces a sponsored comparison of DeepSeek Coder V2, Yi-Coder and Qwen Coder running on a workstation.
 9:15ENMatthew Berman· Sep 25, 2024Llama 3.2 Adds Vision and Smaller On-Device ModelsMatthew Berman · Forward FutureIn a Meta-partnered 2024 video, Matthew Berman reviews the model family, its tooling and a brief hosted 1B demonstration.
Load moreShowing 24 of 52