In 30 Sekunden
In July 2026, Theo Browne tested Codex Ultra and investigated its multi-agent behavior. He reports rapid usage consumption, critiques the interface and compares it with code-defined workflows in Claude Code. His descriptions reflect the versions and configuration he examined and may not describe current products.
- 1Effort versus orchestrationTheo says the tested Ultra mode combined a reasoning setting with instructions for multi-agent work.
- 2A costly personal runHe reports exhausting a five-hour allowance quickly with fast mode and increased concurrency.
- 3Two sub-agent designsA model-generated analysis compares a dispatcher with named, nested agents.
- 4Context is a trade-offSharing more history can aid context but also increase input use and carry irrelevant assumptions.
- 5Workflows make stages explicitA code-defined example runs parallel reviews and synthesizes their structured output.
- 6Separate the controlsTheo prefers an orchestration switch distinct from model reasoning effort.
Das Wichtigste
- Reasoning effort and multi-agent orchestration are distinct choices even when an interface presents them together.
- Concurrent high-effort agents can consume substantial resources; actual usage depends on configuration and task.
- Context sharing, messaging, nesting and concurrency affect coordination and cost.
- Explicit workflow stages can clarify data flow and stopping conditions but still require safeguards.
- Product interfaces, limits and implementations should be checked against current documentation.
Den bearbeiteten Text nach Kapiteln lesen
What Ultra meant in the tested version
Theo distinguishes reasoning effort from orchestration and explains his concerns about labeling.
When GPT-5.6 arrived, Codex also presented Max and Ultra alongside its reasoning-effort choices. I found Ultra confusing: in the version I tested, it did more than raise the model's reasoning effort. It also encouraged a multi-agent workflow, with consequences for usage and control.
My criticism reflects the implementation and my experience in July 2026. Interfaces, defaults, model routing and subscription limits change, so the details here should not be read as instructions or a description of every later version.
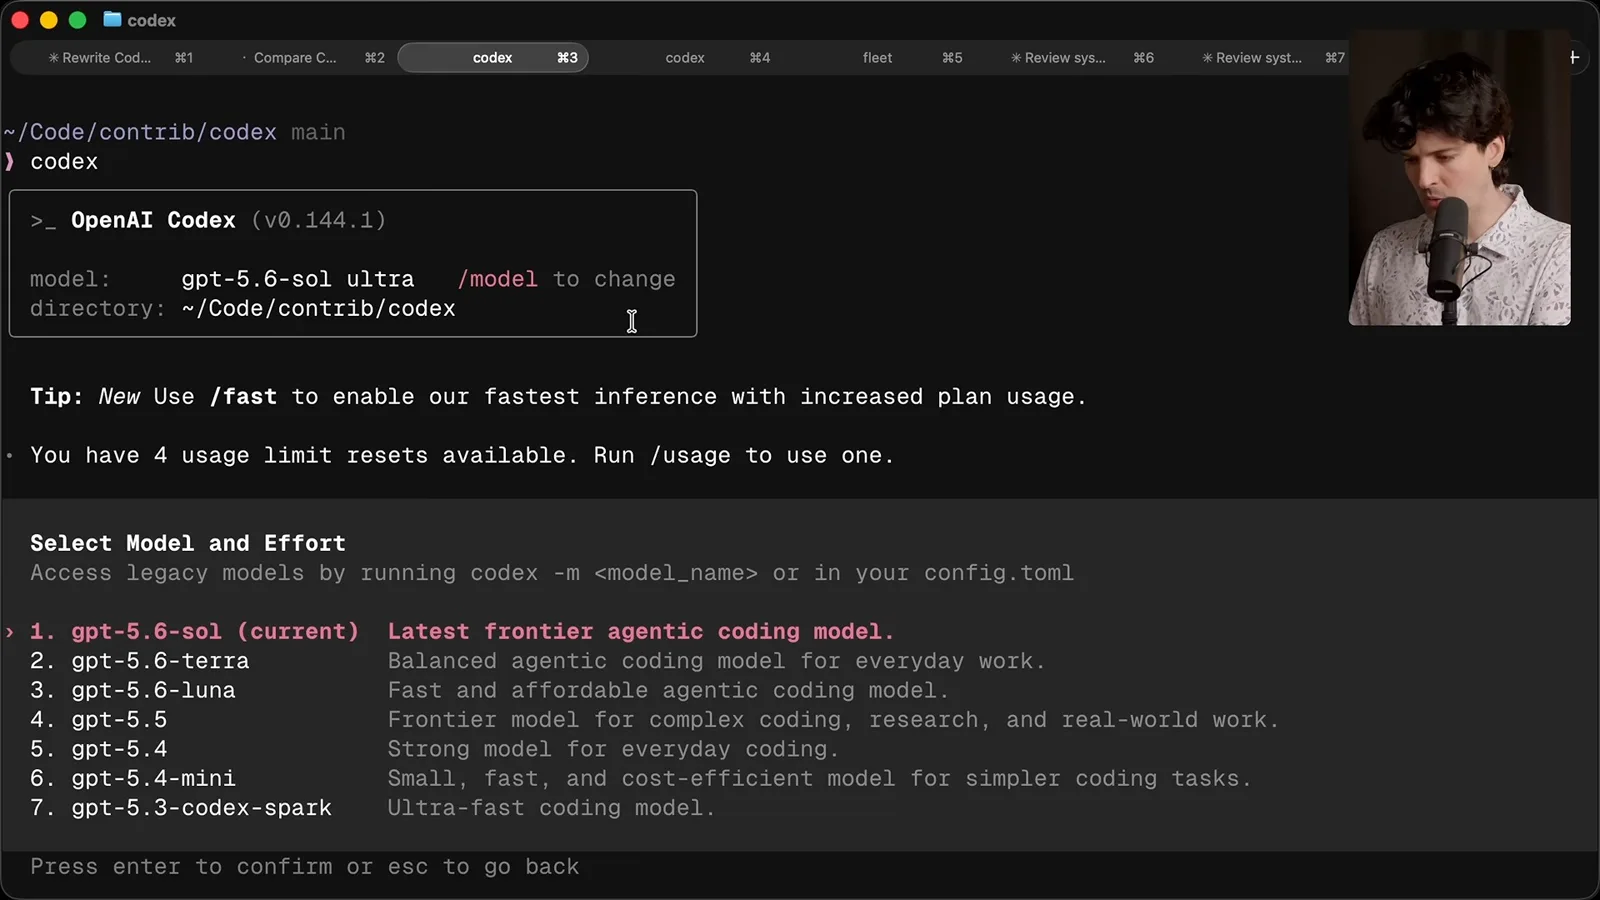
The CLI presented Ultra in the same menu as low through max reasoning. In the desktop interface I observed changes during recording: Ultra moved out of the main slider into an advanced effort menu. My concern is that this presentation can hide the difference between more thinking and more delegated work.
For comparison, the Claude Code interface I show labels Ultra Code as extra-high effort plus workflows. Selecting it activates workflow behavior rather than simply selecting a higher reasoning level. I think both products should make that distinction clear.
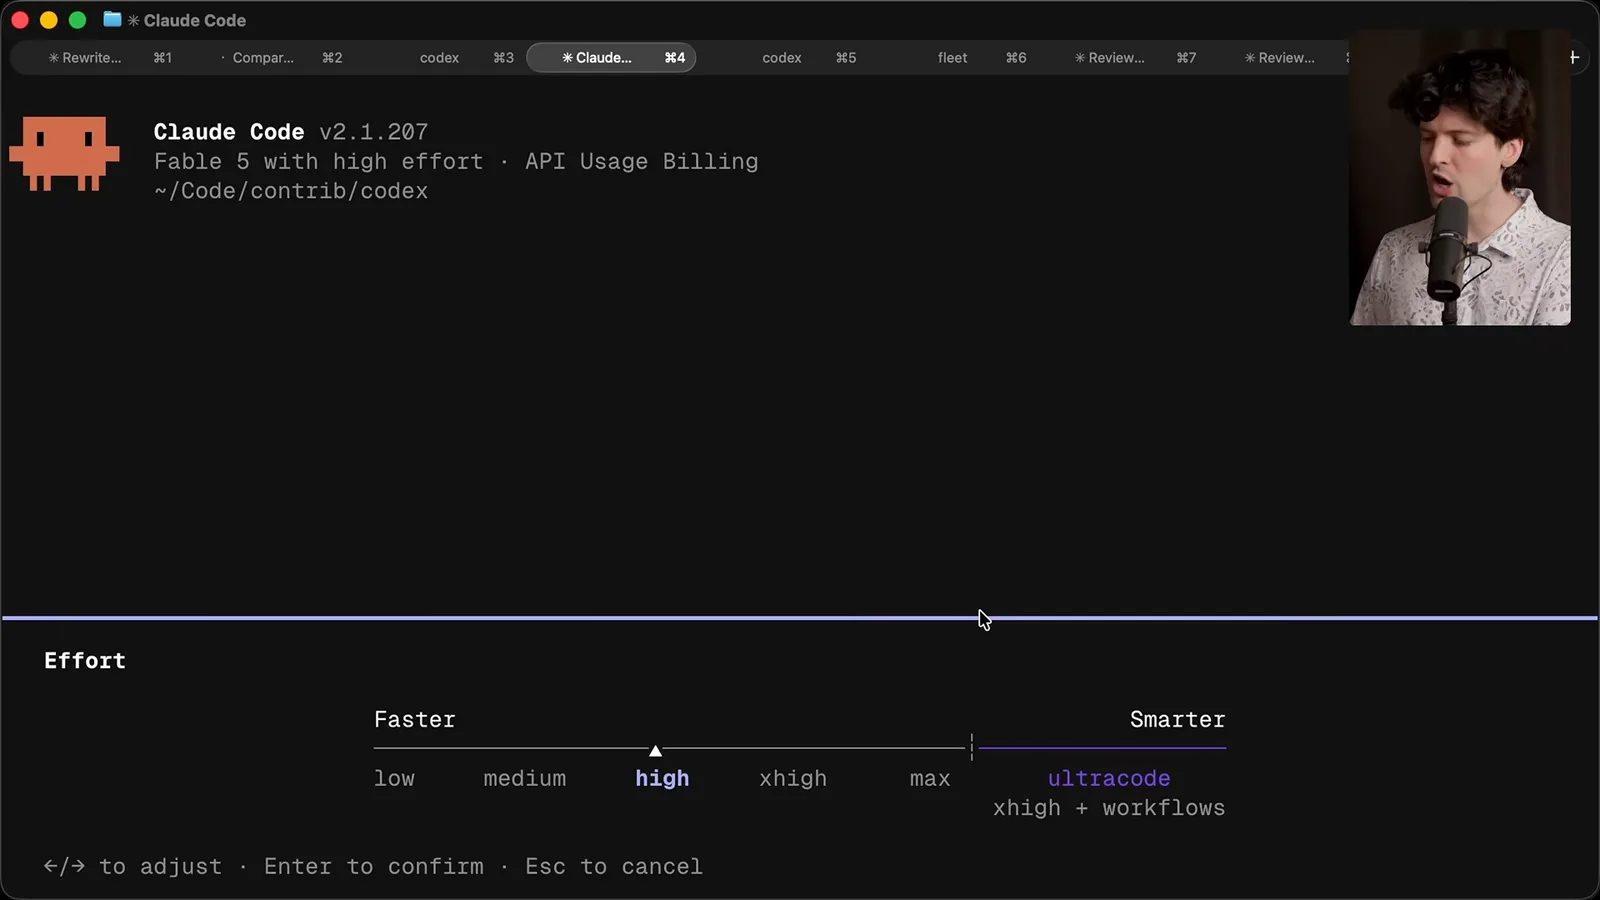
I describe Ultra as a mode that adds instructions encouraging sub-agent use. The model still needs a reasoning setting, and orchestration also depends on the harness. My explanation is based on the version and implementation I inspected, rather than a promise about future behavior.
Usage and effort
His personal limit experience illustrates how high effort and multiple agents can compound consumption.
In my comparison, Claude Code's Ultra Code selected extra-high effort with workflows, while the Codex Ultra setup used maximum reasoning. Combining a high-effort parent with multiple high-effort helpers can multiply usage, especially if agents continue spawning further work.
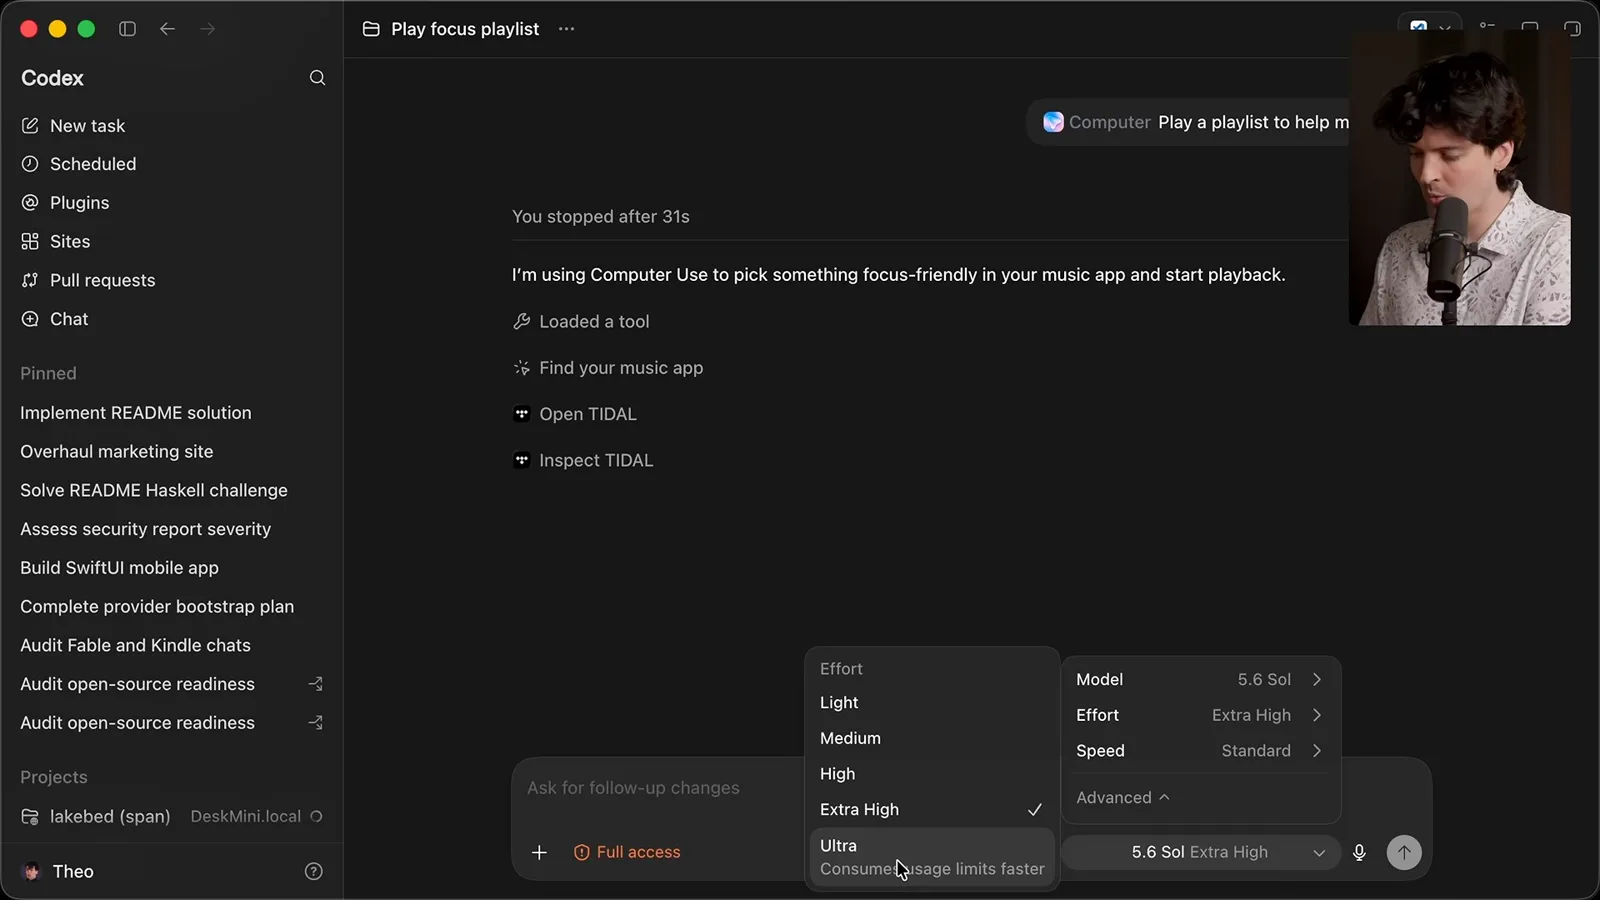
I cite benchmark observations in which max used more than twice the tokens for a relatively small score gain. That is a trade-off from particular tests, not a universal ratio: the value of extra reasoning depends on the task, settings and cost of failure.
In the setup I tested, I could not easily set a lower reasoning effort for the child agents through the available sub-agent interface. I wanted a separate control so that the parent could delegate cheaper work without every helper inheriting the most expensive setting.
One Ultra run in fast mode exhausted my five-hour allowance in about 20 minutes; after a manual reset, I hit it again in about 40 minutes. I had also increased the agent concurrency limit. This is my particular experience, not a prediction of another account's consumption.
I was concerned that temporarily changing a short-window limit could make it easier to consume a weekly allowance quickly. Plan limits and safeguards vary and change, so anyone evaluating a run should check current usage and settings rather than rely on these historical figures.
Sub-agent implementations
Theo examines model-generated explanations of V1 and V2, context sharing, messaging and concurrency.
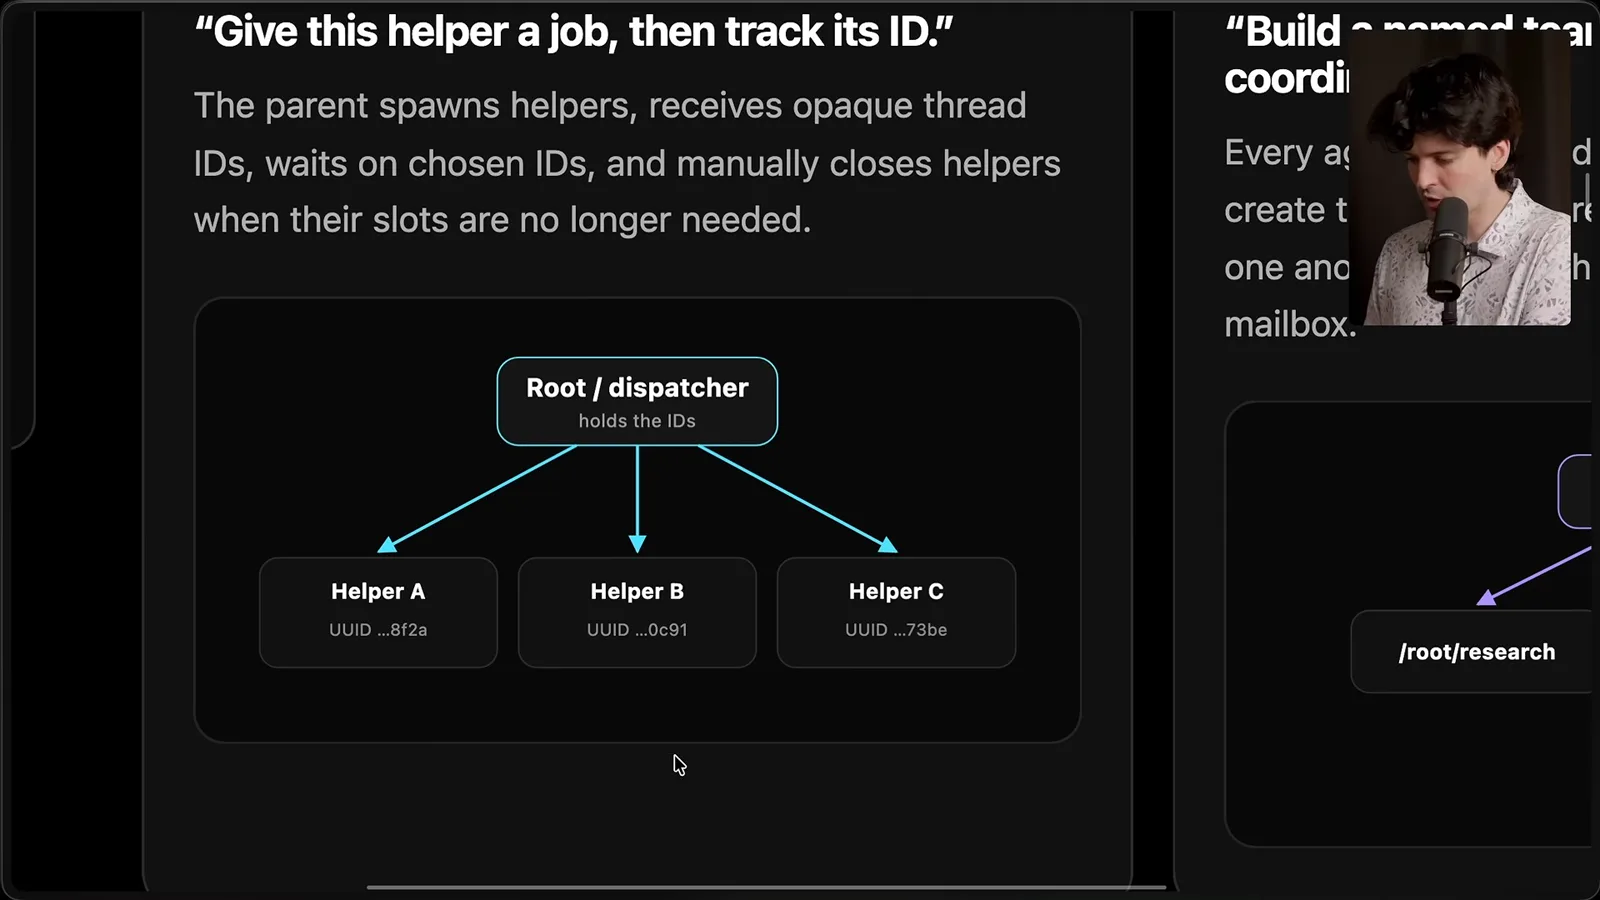
To understand the behavior, I had models inspect two Codex sub-agent implementations, which I call V1 and V2. V1 resembles a dispatcher assigning work to temporary helpers; V2 organizes named agents in a tree with messaging. The page shown is model-generated analysis and should be checked against the relevant source version.
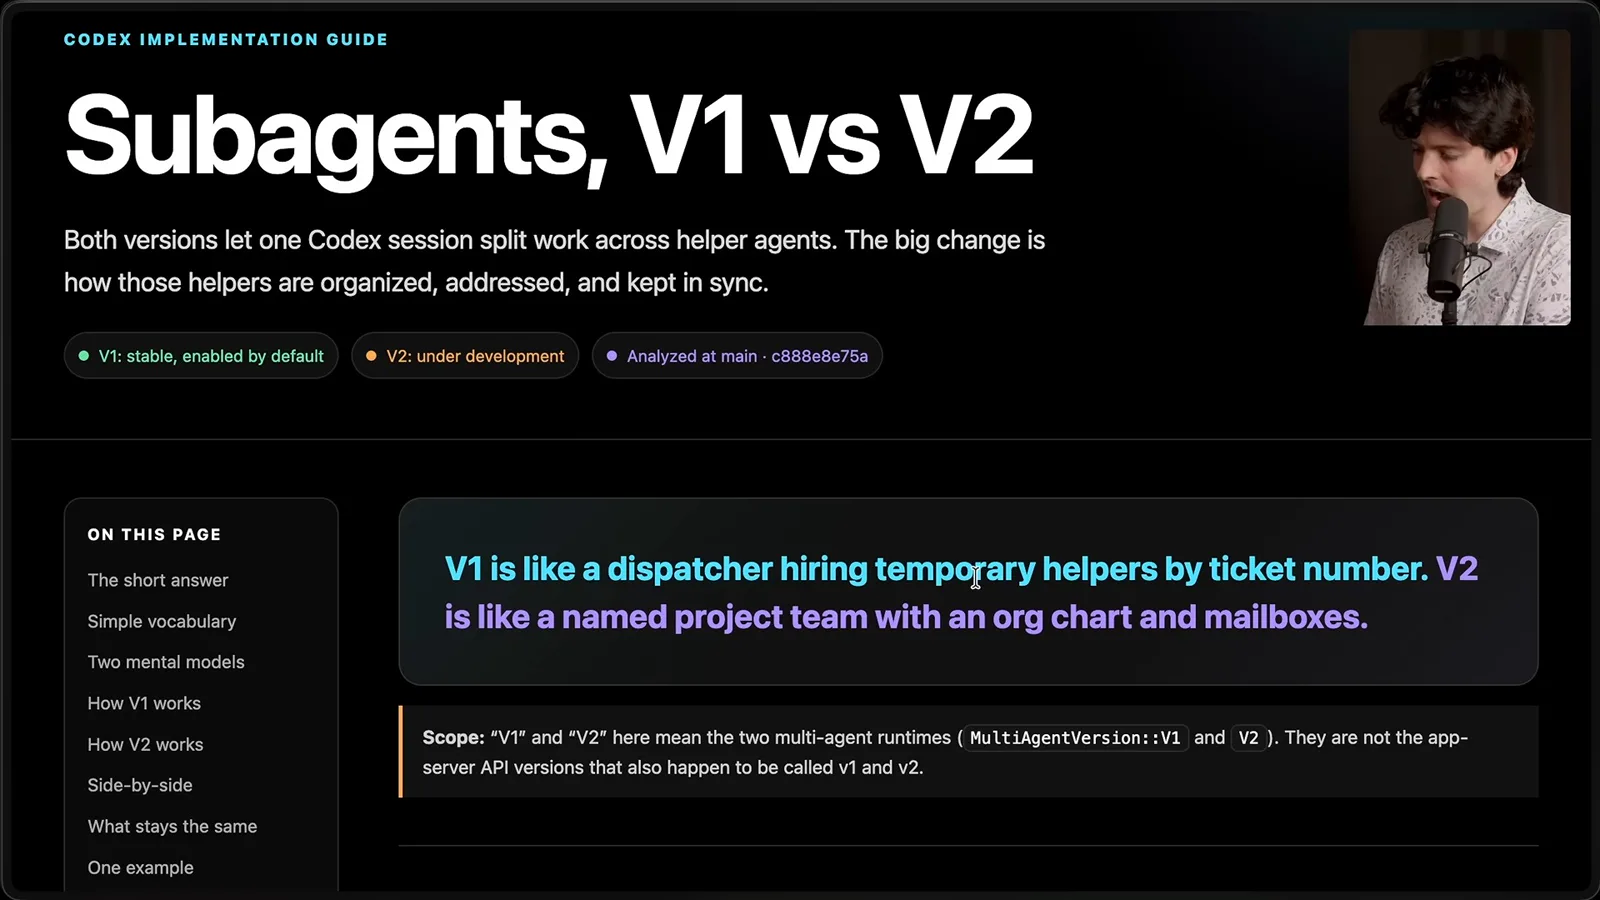
In the simple example, a parent can delegate three pull-request reviews to three helpers, wait for their results and synthesize them. Each helper has its own context and a defined task. That kind of division can be valuable without making every assignment a large agent hierarchy.
The V2 design described in the video adds named task paths, nested agents and messages. Theo says it was under development and that the models he tested were routed to it through configuration. Those are observations about that release, not current product documentation.
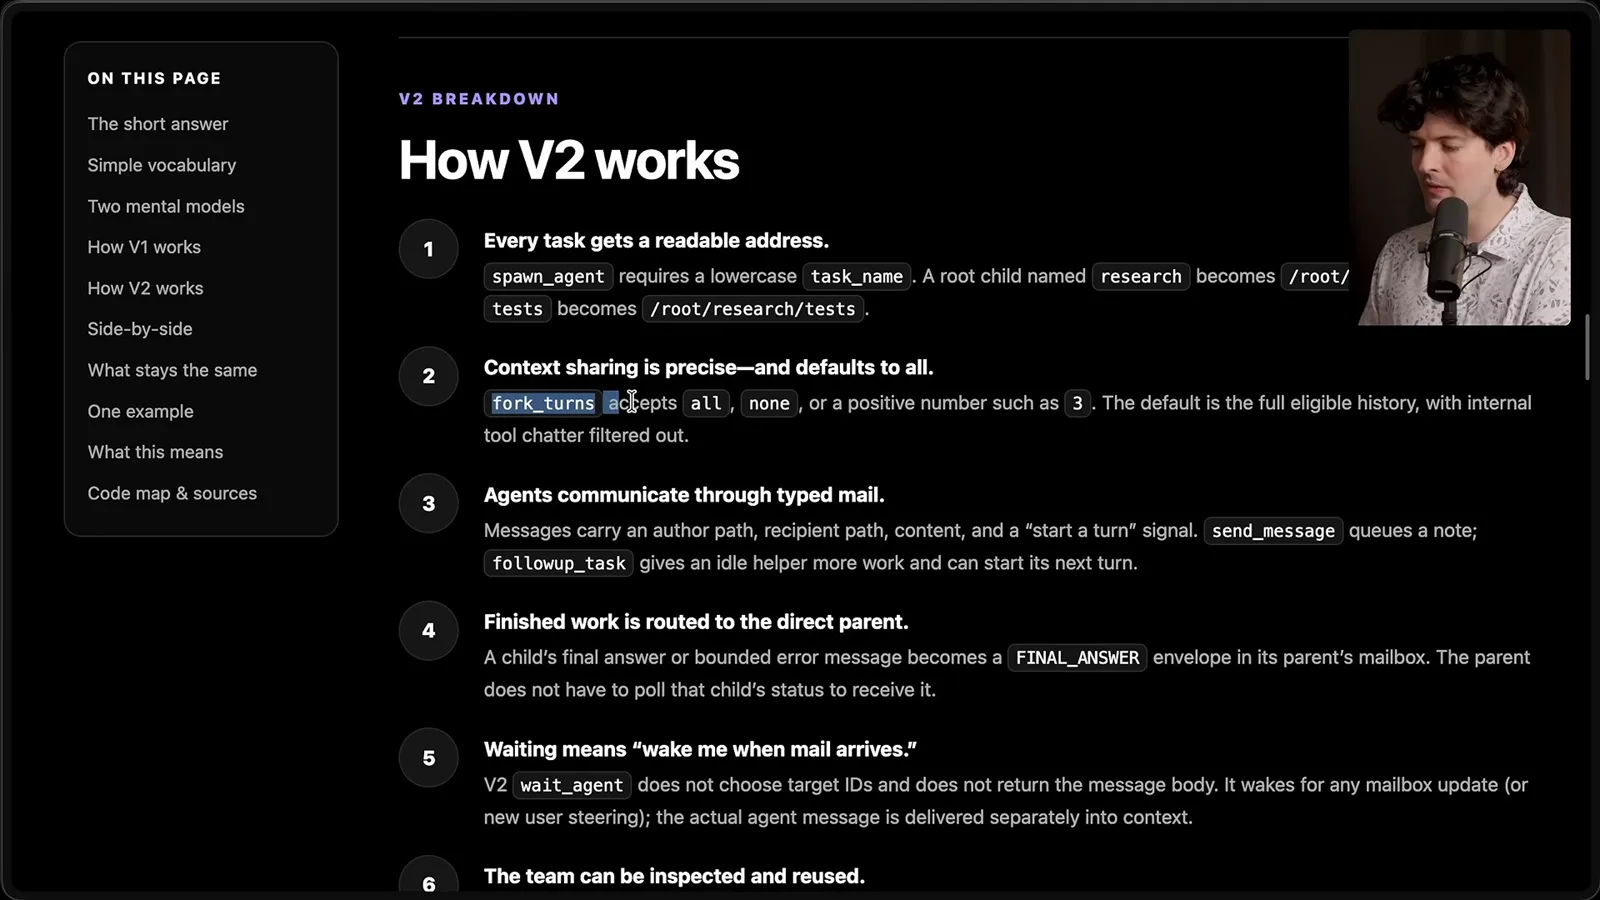
The context-sharing default concerns me most. The analysis says eligible parent conversation history is shared by default, with options for less context. More history may help a helper understand the task, but it can also increase input use and carry irrelevant assumptions into its work.
I speculate about whether caching motivated the default, but I am not certain how all prompt differences affect cache hits. The practical point is to measure real usage: shared context, cache behavior, number of agents and model effort all affect cost.
Messages allow agents to send notes or assign follow-up work to existing helpers. Results travel to a direct parent; a wait can wake on a mailbox event instead of meaning that all work is finished. This makes coordination flexible, but I found it noisier in practice.
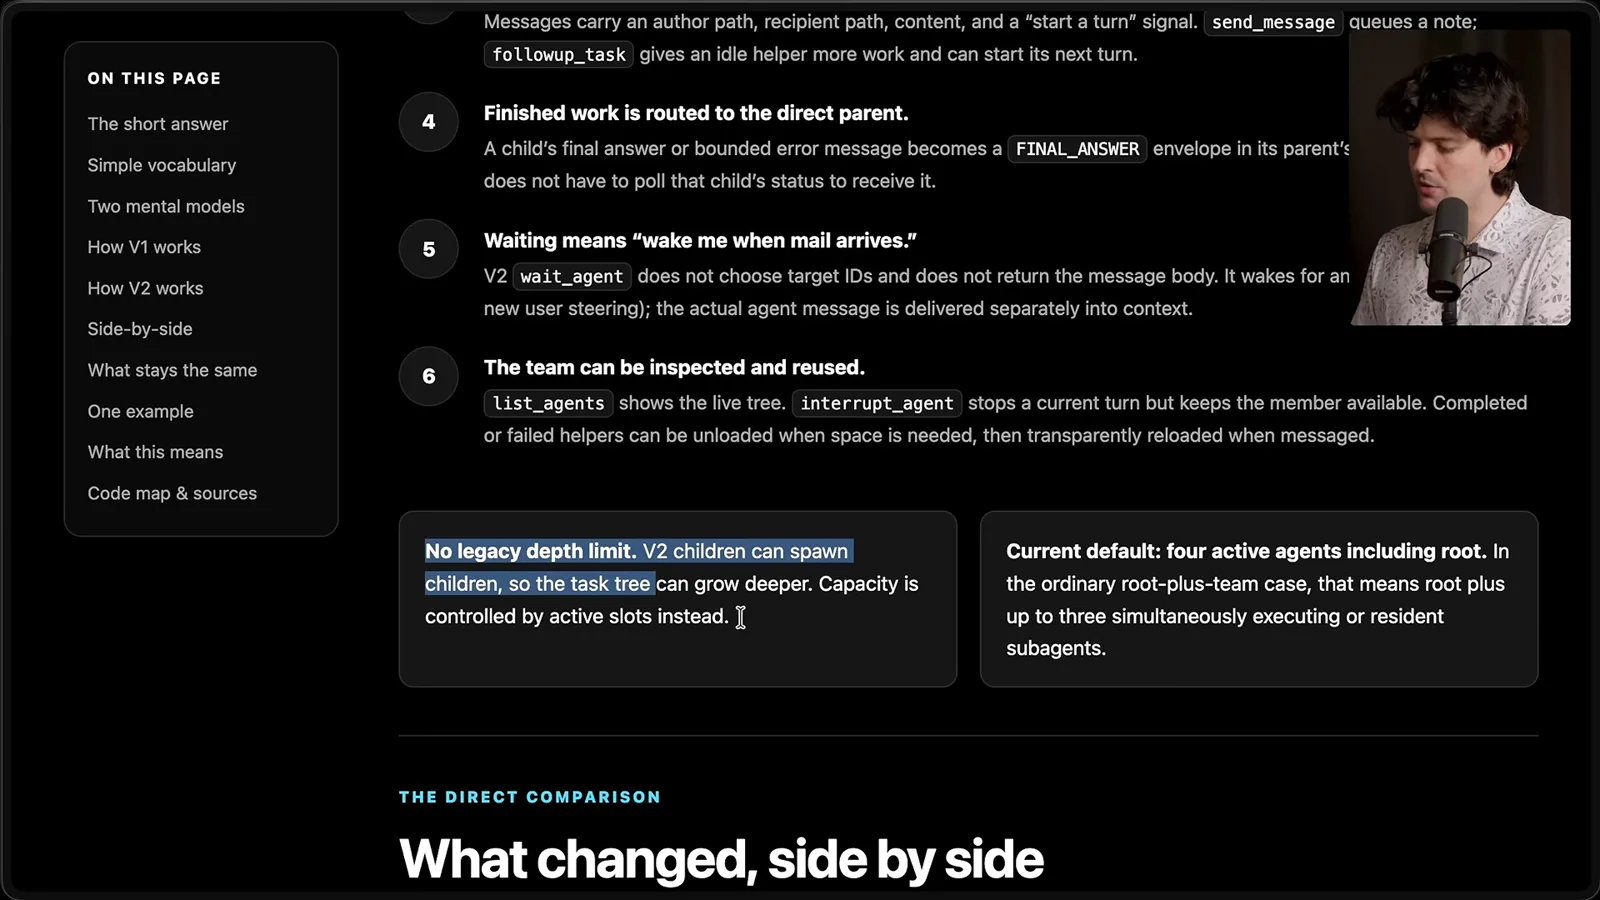
The report describes nested children without the old depth limit, while the default in that version was four active agents including the root. I had changed my concurrency setting, which contributed to my high usage. A concurrency limit and a depth limit control different things.
I did not use V2 extensively during early testing, so I could not establish a reliable quality comparison then. In later use I saw longer, noisier runs and more token consumption without results that impressed me enough to justify them. That is a subjective assessment, not a controlled benchmark.
A workflow alternative
He describes staged, code-defined orchestration and argues for clearer controls.
For people who feel pressure to master every new setting immediately, my advice is to slow down. Defaults can be useful, implementations change quickly and there is no need to reproduce my elaborate setup to benefit from the tools.
What I want instead is clearer separation between reasoning effort and orchestration, plus more control over how helpers are configured. I prefer the workflow approach I used in Claude Code, where the model can write a program defining stages, prompts and expected outputs.
In the example, the workflow defines metadata, output schemas and a review phase. It launches different model reviewers in parallel, waits for their structured results, and passes those results to a synthesis phase. The structure is explicit and can be inspected as code.
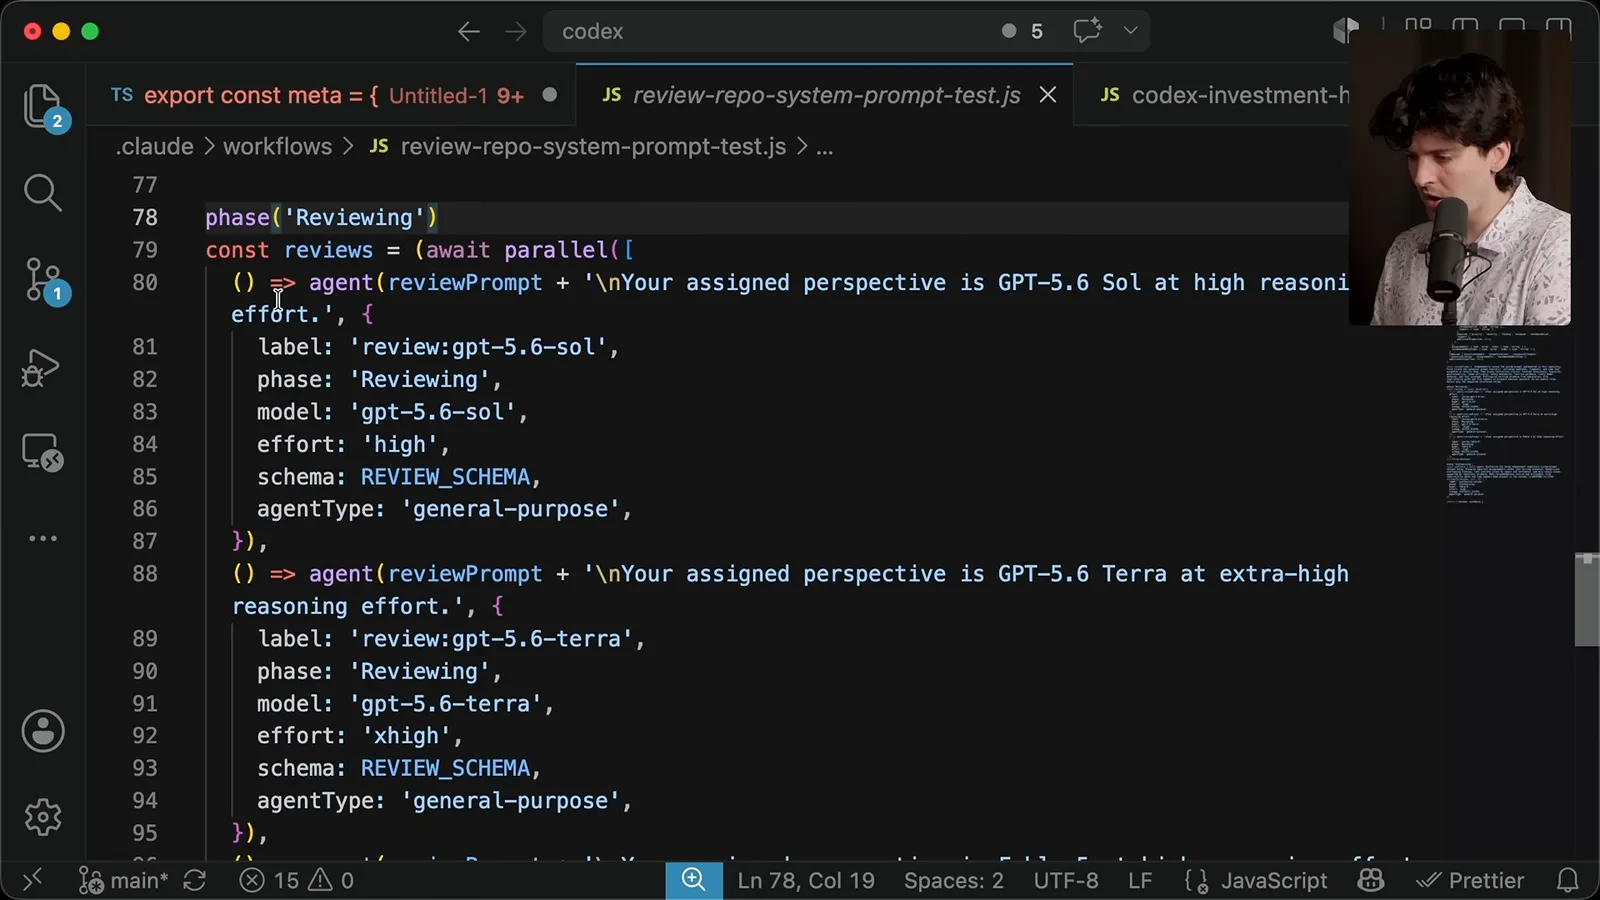
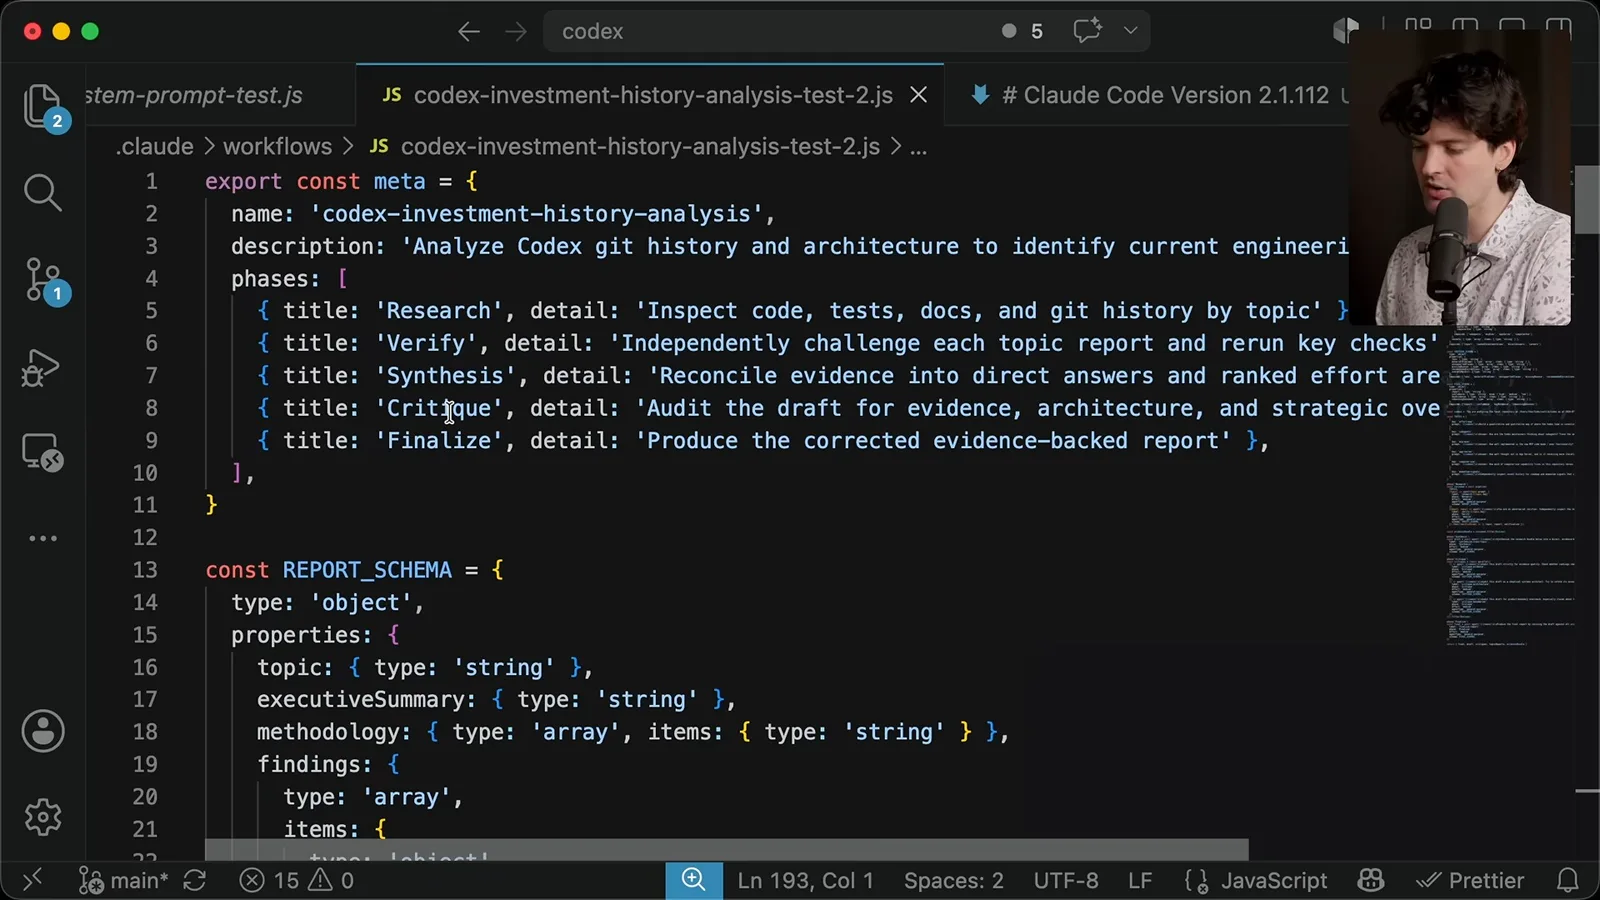
A larger example has research, verification, synthesis, critique and finalization phases. Code can filter missing responses or decide whether another review is needed. This lets the workflow route results according to the actual output instead of relying only on repeated conversational tool calls.
I see workflows as a middle ground between fixed predefined helper roles and entirely ad hoc delegation. A model can generate the specific roles and flow for the task while a program handles the sequencing. The generated workflow still needs review, limits and appropriate permissions.
A bounded sequence can make the stopping condition clearer than an open-ended agent conversation. It is not an automatic guarantee: loops, retries or a large fan-out can still consume significant time and resources. The important distinction is making those limits explicit.
I think the interface copied the misleading part of the competing experience while missing what I value in the workflow implementation. My preference is a model selector with a separate, clearly labeled orchestration switch rather than presenting everything as one effort scale.
I close by showing Maria's mockup of that separation and advising caution with the Ultra version I tested. This is a July 2026 assessment; users should look at the current interface, documentation and limits when deciding what to enable.
Mehr aus diesem Kanal
 38:47EN
 Theo - t3․gg· 28. Okt. 2026Theo’s Long-Running Agent Experiments: Verification, Compute and CostTheo Browne · Ping LabsA skateboard game and two compiler projects show how repeated checks and flexible compute can sustain agent work—and how expensive those loops can become.
 36:07ENTheo - t3․gg· 27. Okt. 2026Theo on Token Costs, Coding Agents, and the Price of AI CapabilityTheo Browne · Ping LabsA viral estimate of Lauren's AI spending prompts a closer look at cache pricing, benchmarks, and the changing work of coding agents.
 30:37ENTheo - t3․gg· 26. Okt. 2026Theo’s Three Skills for Reviewing and Shipping with Coding AgentsTheo Browne · Ping LabsHow sol-loop, full-send and full-stop encode review, verification and different levels of merge authority.
 0:43ENTheo - t3․gg· 23. Okt. 2026Theo Distinguishes Security Vulnerabilities from Active AttacksTheo Browne · Ping LabsA short explanation of why disclosed software flaws and reported attacks are different kinds of security news.
 29:22ENTheo - t3․gg· 22. Okt. 2026Theo on Security Vulnerabilities, Stolen API Keys and AITheo Browne · Ping LabsA look at the gap between vulnerability disclosure and patching, and a speculative account of why stolen inference keys may be valuable.
 31:13ENTheo - t3․gg· 20. Okt. 2026Theo on Why Smarter Models Help More Than DevelopersTheo Browne · Ping LabsFrom game modifications to compiler experiments, Theo revisits his assumptions about who benefits from more capable AI.