In 30 Sekunden
Nathan Lambert translates policy gradients into language-model code, then explains PPO, GRPO and asynchronous training infrastructure. He discusses reward placement, value estimation, numerical failure modes and how loss aggregation changes length weighting.
- 1Log probabilities and masksShift predictions, gather token log probabilities and select completion tokens.
- 2PPO training loopGeneration, reward shaping, advantage estimation and policy/value updates form a cycle.
- 3GRPO simplificationGroup-relative rewards replace the value model and GAE in the common implementation.
- 4Asynchronous trainingSeparate actors and learners overlap generation and updates.
- 5Loss aggregationSequence-level and token-level normalization imply different length weighting.
Das Wichtigste
- Token log probabilities and masks connect language-model outputs to policy-gradient losses.
- PPO reuses sampled data with clipping and often trains a value model.
- GRPO uses group-relative advantages and removes the value model in its common form.
- Asynchronous actors and learners improve throughput but require weight synchronization.
- Per-sequence and per-token loss aggregation weight response lengths differently.
Den bearbeiteten Text nach Kapiteln lesen
Policy gradients in code
Lambert connects token log probabilities, masks and advantages to REINFORCE and leave-one-out baselines.
This lecture moves from the policy-gradient derivation to implementing reinforcement learning for language models. I cover PPO, GRPO, infrastructure and loss aggregation. Many scaling and data corner cases depend on the specific codebase, but the common building blocks are worth understanding.
I use state–action notation, although prompt–completion notation is also common. The practical question is how the policy-gradient objective becomes code that computes log probabilities, advantages and parameter updates.
The objective maximizes expected trajectory reward. Its gradient contains a sum of log-policy gradients weighted by an advantage or related signal. In an implementation, the loss combines log probabilities and advantages, and automatic differentiation performs the backward pass.
For a batch of token IDs, a model returns logits with batch, sequence and vocabulary dimensions. Shift positions to align each prediction with the next token, apply log-softmax and gather the probability of the selected token.
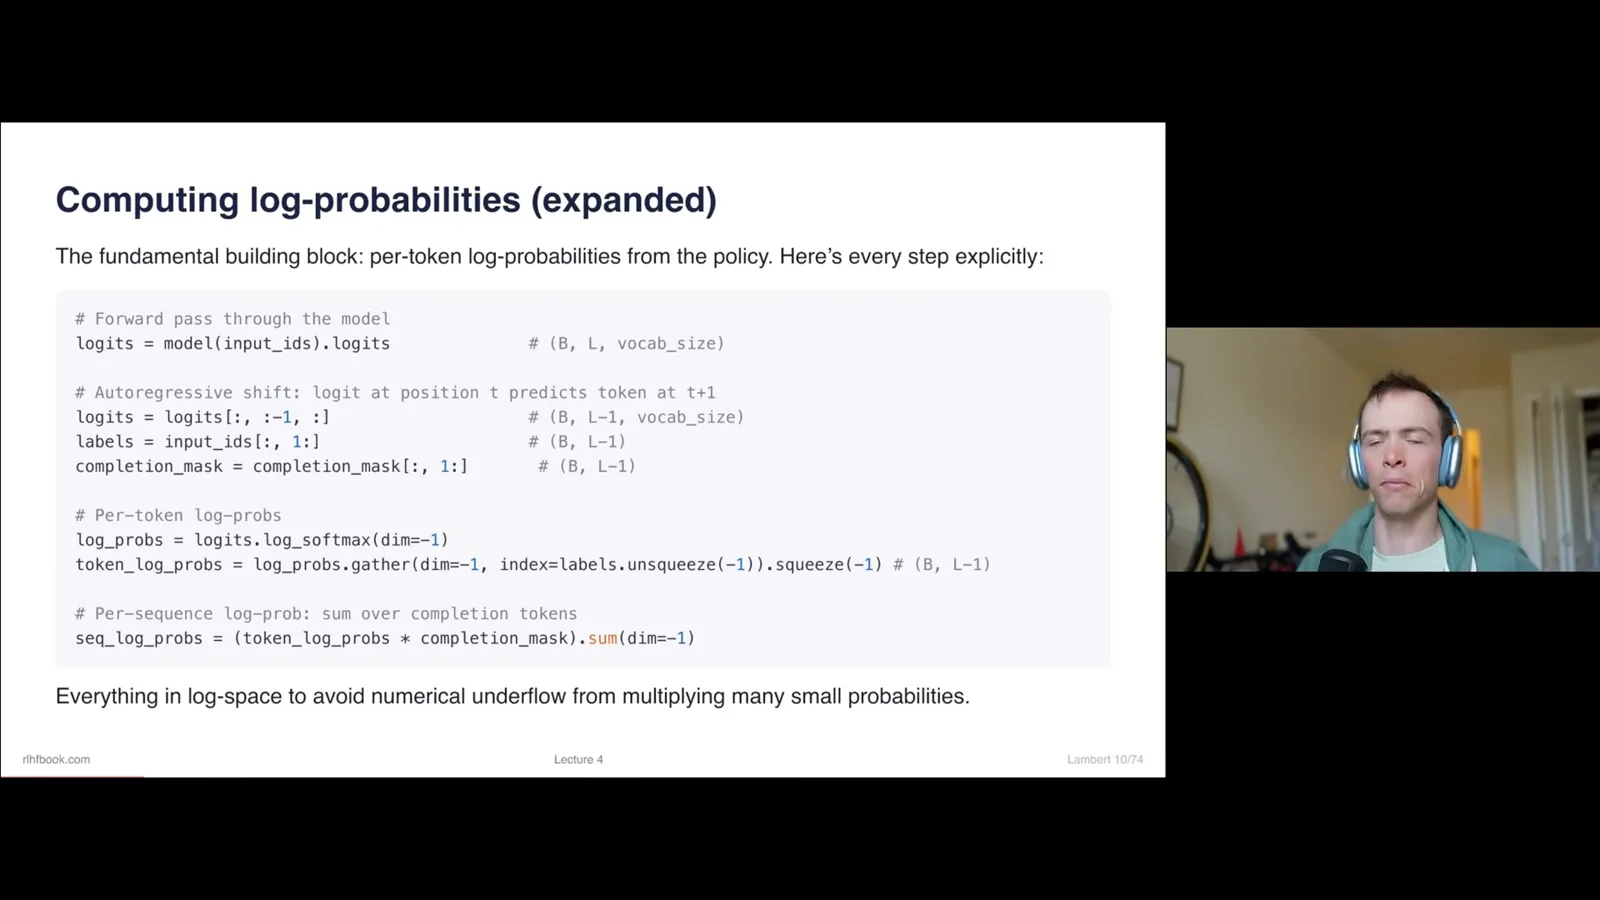
A completion mask excludes prompt tokens from the training loss. Other masks handle padding or packed sequences. Computing in log space avoids numerical underflow from multiplying many small probabilities, and the calculation is usually packaged in a reusable helper.
REINFORCE uses a reward minus a baseline to form an advantage, then weights sequence log probability by that advantage. A negative sign appears because the RL objective is maximized while the implementation minimizes a loss.
REINFORCE leave-one-out generates multiple answers for each prompt and uses the mean reward of the other answers as the baseline. One implementation sums group rewards, subtracts the current answer’s reward and divides by the remaining count.
PPO implementation
The lecture walks through reward shaping, GAE, clipped policy and value losses, stability and debugging.
PPO adds a clipped surrogate objective and commonly uses a value model with generalized advantage estimation. This allows several updates on collected data while controlling large changes, at the cost of more models, hyperparameters and code complexity.
A simplified PPO loop samples prompts, generates responses, scores them, computes a reference-policy KL penalty, shapes rewards and estimates advantages. It then updates the policy and value model over minibatches before collecting more data.
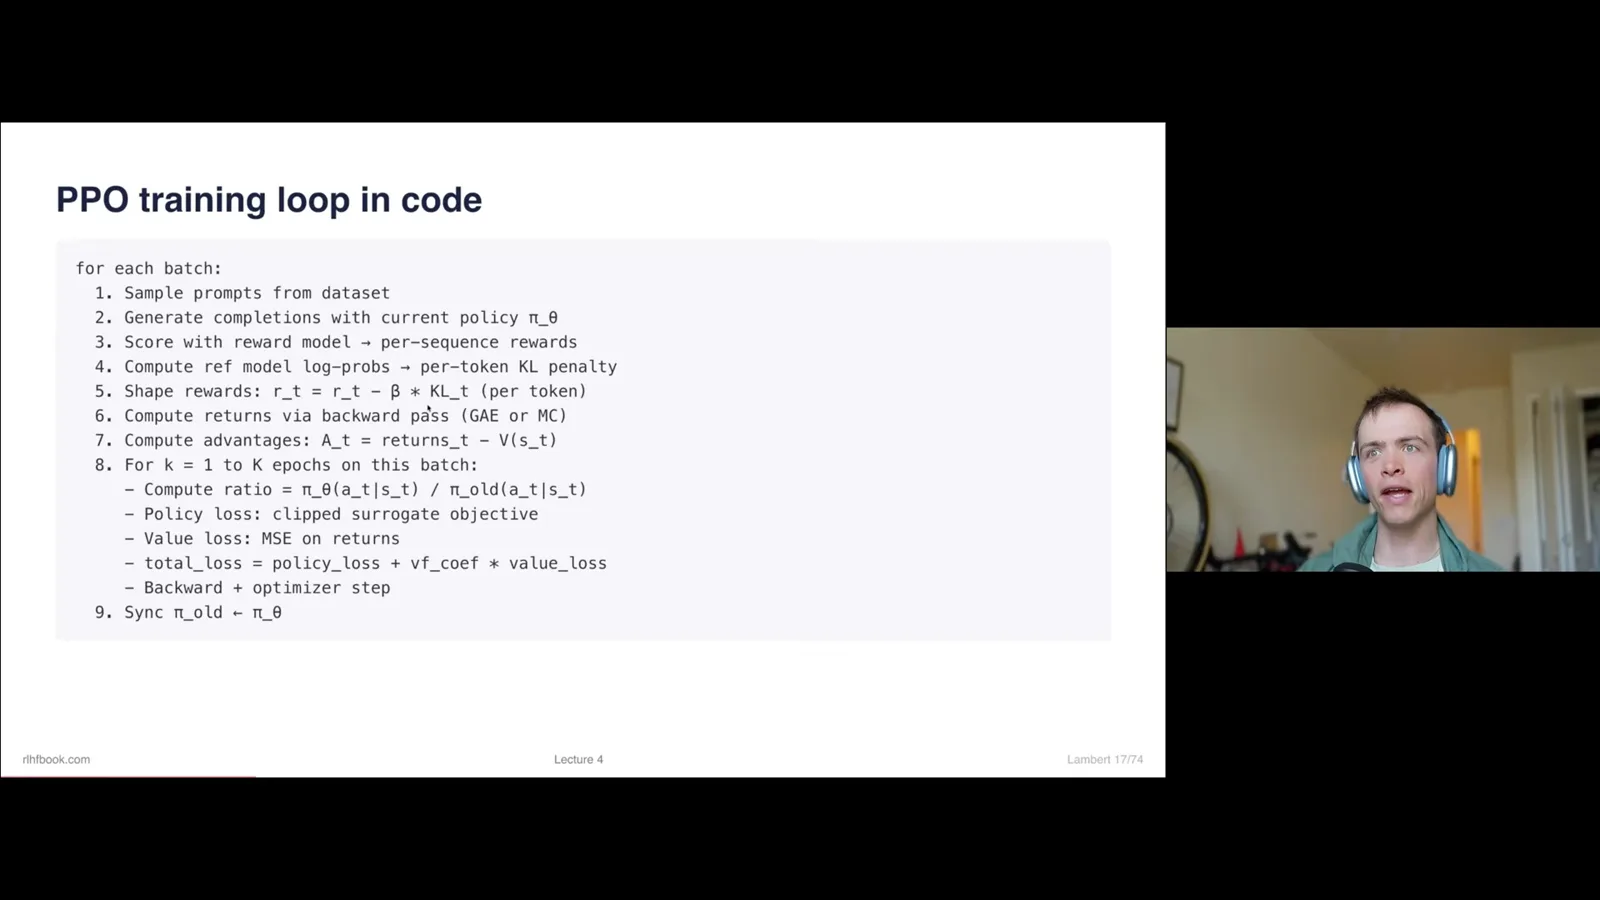
Reward placement depends on the algorithm. In the RLHF setup shown, a reward-model score is placed at the final token while per-token KL terms shape earlier rewards; GAE assigns credit backward. Some GRPO-style RLVR implementations instead broadcast an outcome-based advantage across completion tokens.
A PPO batch needs token IDs, completion masks, old log probabilities, old value estimates and possibly reference-model probabilities and rewards. The old policy is the policy at the start of the current batch; the reference policy is typically fixed from the start of the RL run.
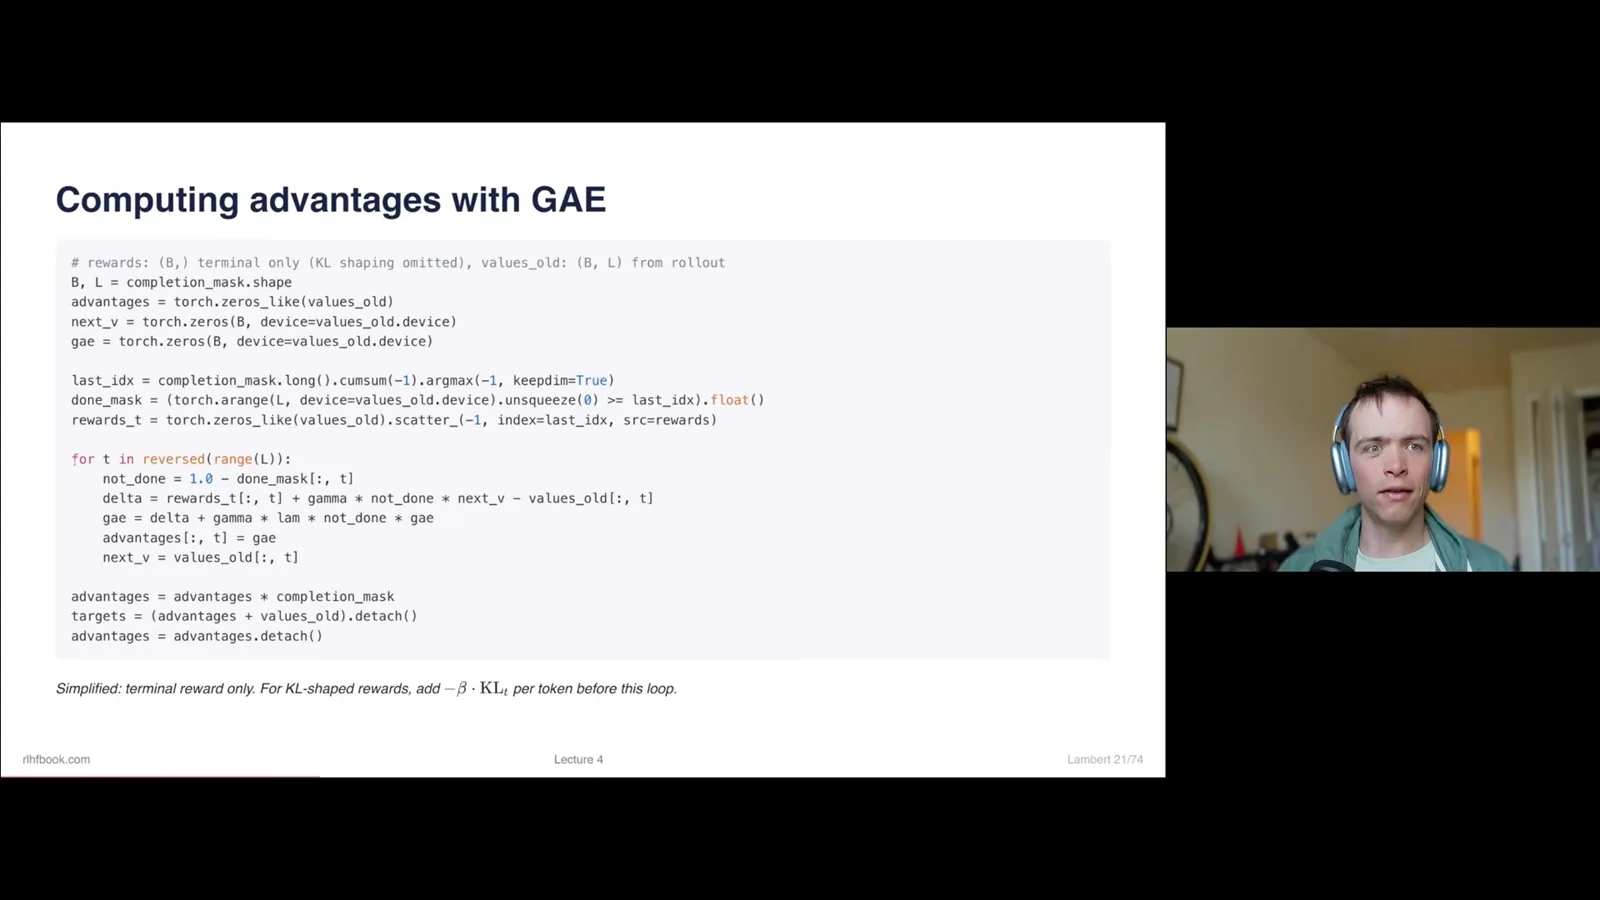
GAE works backward from each sequence’s final token to estimate per-token advantages. End-of-sequence and done masks matter because sequences in a batch have different lengths. A value target is formed from the old value estimate and advantage, then detached from the gradient.
The PPO ratio is computed stably by subtracting old log probabilities from new ones and exponentiating the difference. The policy loss compares unclipped and clipped forms, then selects the more conservative negative loss with a maximum.
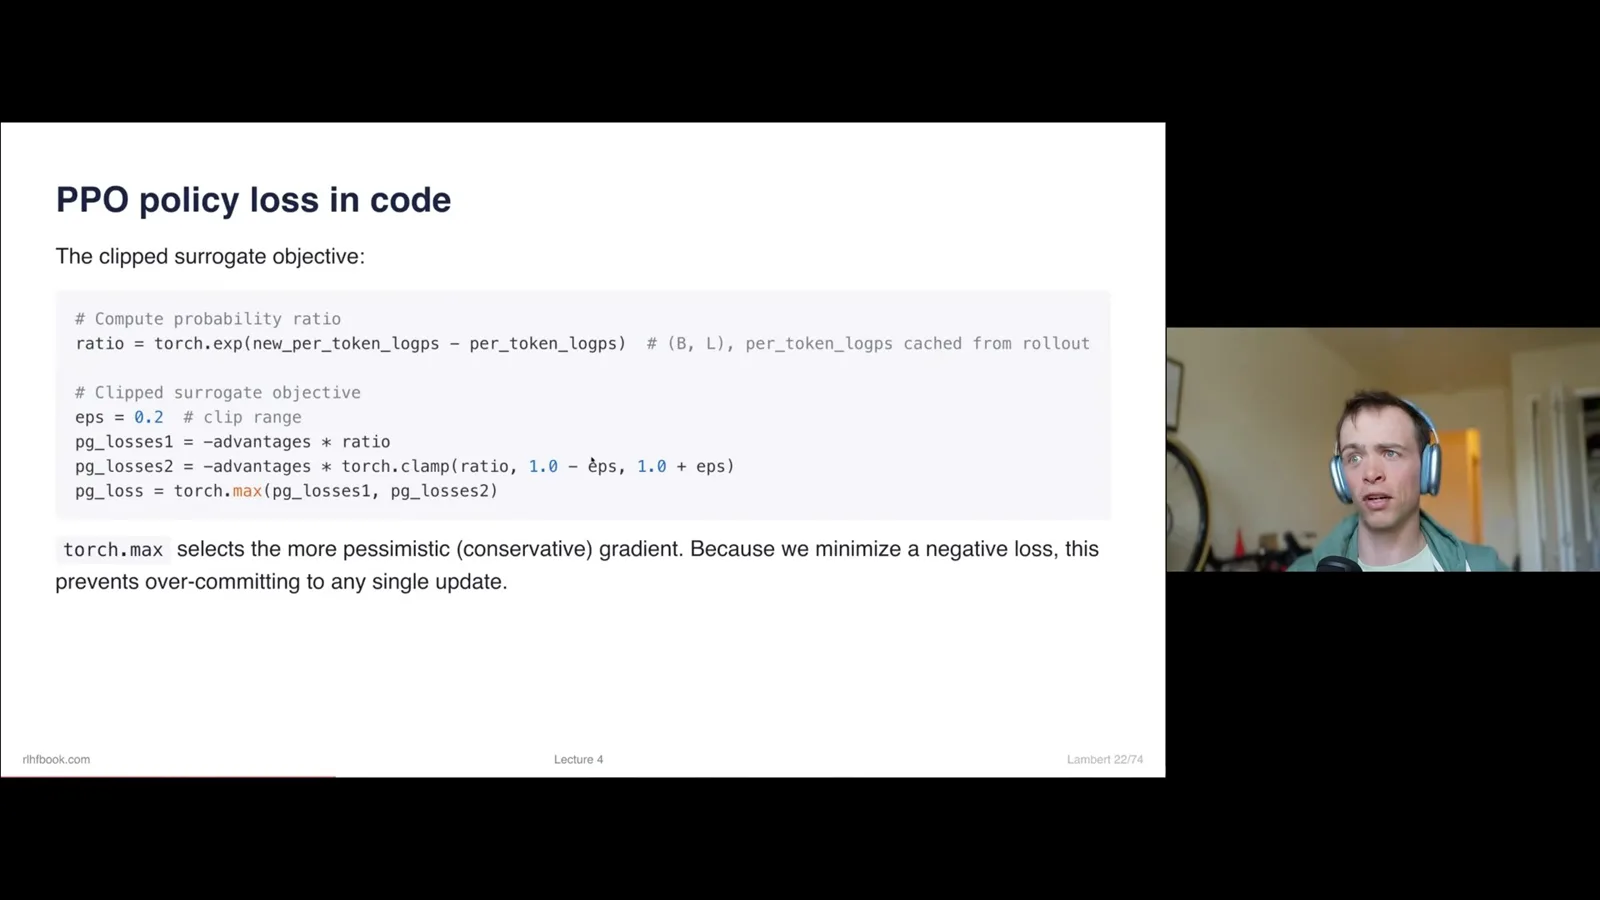
If the current and old policies are identical at the first update, the ratio starts at one and clipping does not activate. Multiple updates on the same collected batch can make the difference grow. Lambert distinguishes minibatch processing and repeated passes when discussing these mechanics.
The value model predicts future return. Targets based on observed returns and old value estimates should be treated as fixed during the value update. Some implementations use a clipped value loss as well as a clipped policy loss, and weight the two losses.
Advantages are often normalized within a batch to make update scales more predictable. This does not solve every stability problem, but reduces sensitivity to large changes in advantage scale.
Initializing a value model for a pretrained language model is difficult. A common approach attaches a value head to a strong model and warms it up on reward data before policy updates, because initial value predictions may be poor.
PPO has many interacting settings: clipping, GAE, value-loss weight, KL coefficient, batch size, learning rate and update count. Lambert recommends starting from a stable recipe and changing one factor at a time.
Large batches can reduce variance in sampled policy-gradient estimates, although they require more resources. Lambert points to examples from games and autonomous-driving research as well as language-model training.
Monitor clipping fraction, advantage behavior, value loss and KL divergence. Excessive clipping can suppress learning signal; a value loss that fails to improve can indicate critic trouble; rapidly exploding KL can indicate instability.
Implementation mistakes include training on prompt tokens, incorrect reward indexing and confusing old and reference policies. PPO can also require several large models in memory, in addition to optimizer states and activations.
GRPO and related algorithms
Group-relative advantages simplify the training loop. Lambert compares KL handling, leave-one-out baselines and other variants.
GRPO replaces the value model and GAE with advantages computed from multiple sampled responses to the same prompt. This substantially reduces moving parts while retaining a PPO-like clipped loss in the common formulation.
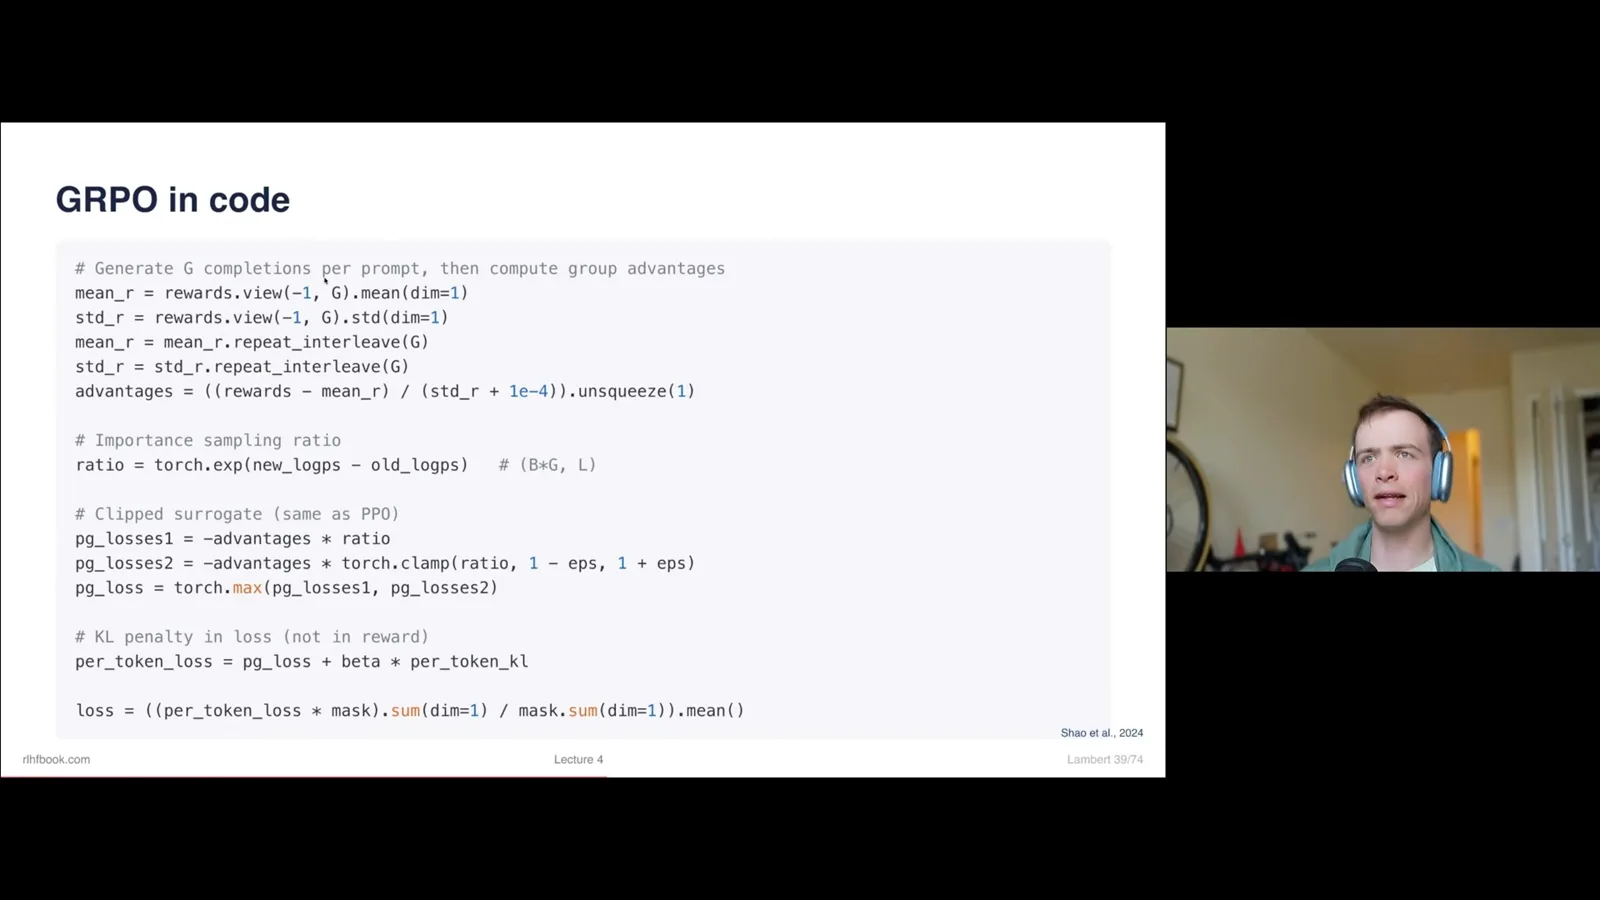
In the examples Lambert compares, PPO for RLHF shapes rewards with KL, whereas GRPO applies KL directly in a per-token loss. These are implementation choices rather than immutable definitions; the advantage in GRPO can be broadcast across a completion.
REINFORCE leave-one-out and GRPO share a group-based intuition, but use different baselines or normalization and different losses. Related algorithms such as GSPO and CISPO modify ratio or clipping calculations to improve large-scale stability.
Infrastructure and engineering
Asynchronous actors and learners overlap generation with training. Numerical precision, masks and detached targets require care.
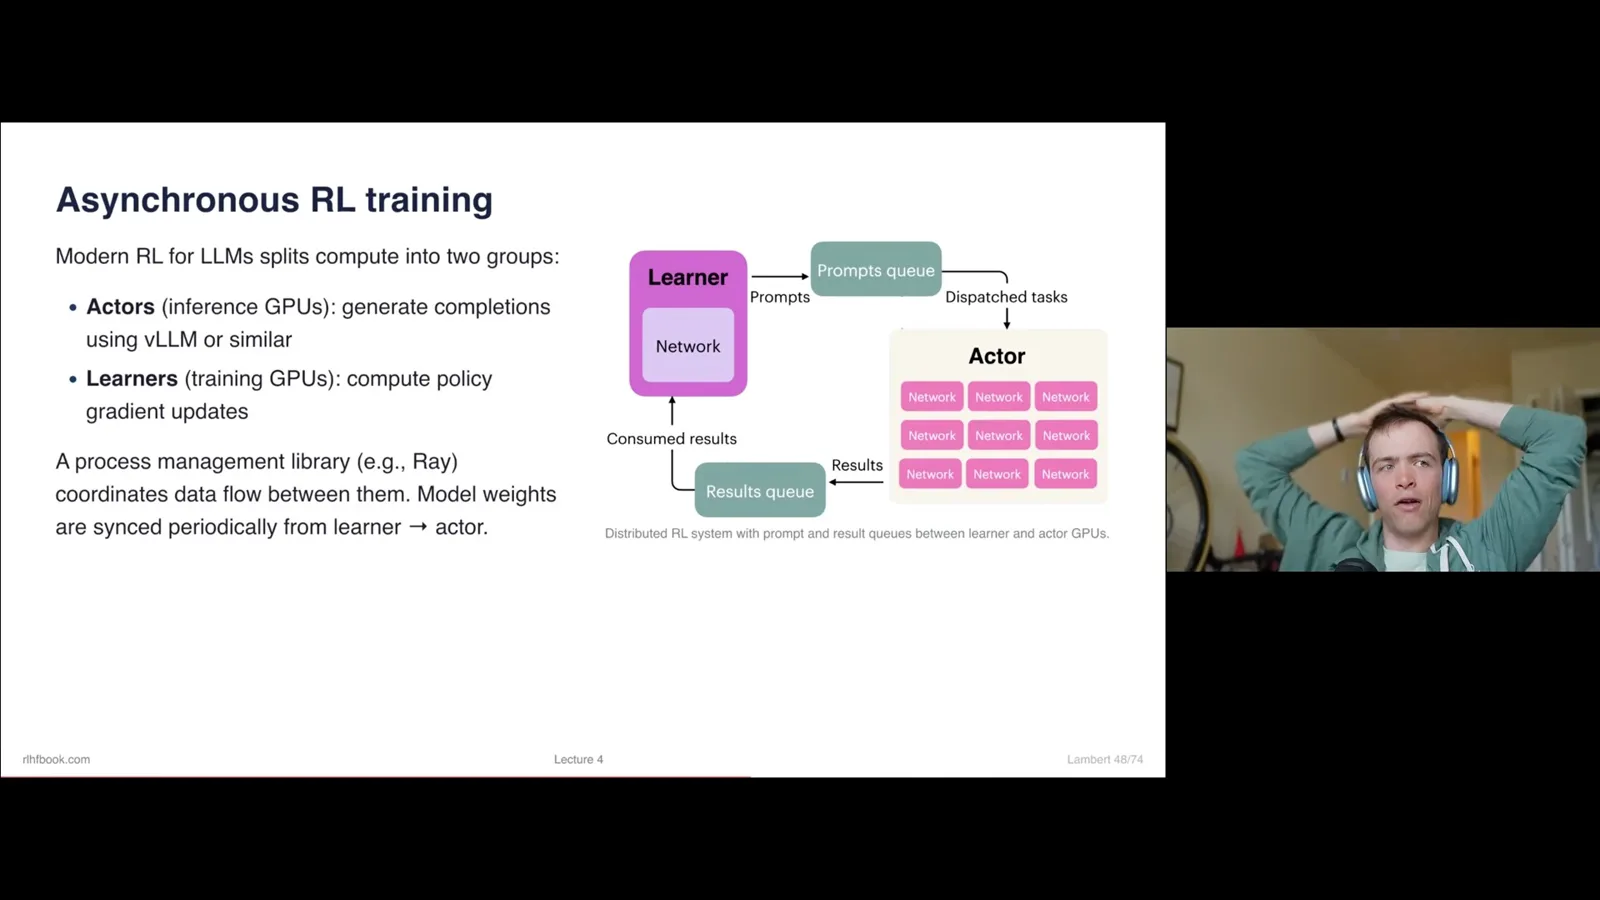
Strictly alternating generation and updates can leave accelerators idle. At scale, separate actor GPUs generate completions while learner GPUs train, allowing the two stages to overlap. The practical system trades exact synchrony for throughput and must manage stale weights.
A prompt queue dispatches work to actors; a result queue returns trajectories to learners. Learner weights are synchronized to actors periodically. Lambert points to Open Instruct, TRL and other open frameworks for implementation details.
Numerical and data errors can silently break training: compute log probabilities stably, align EOS and padding masks, detach targets and intermediate quantities where appropriate, and guard divisions against zero. These details often determine whether a run works at all.
Loss aggregation and monitoring
Normalizing by sequence or by token changes length weighting. Lambert reviews monitoring and reward exploitation.
How per-token losses are aggregated changes training dynamics. Language-model RL often has a single outcome reward per completion but a token-level loss, mixing a bandit-like outcome with a sequence of model actions.
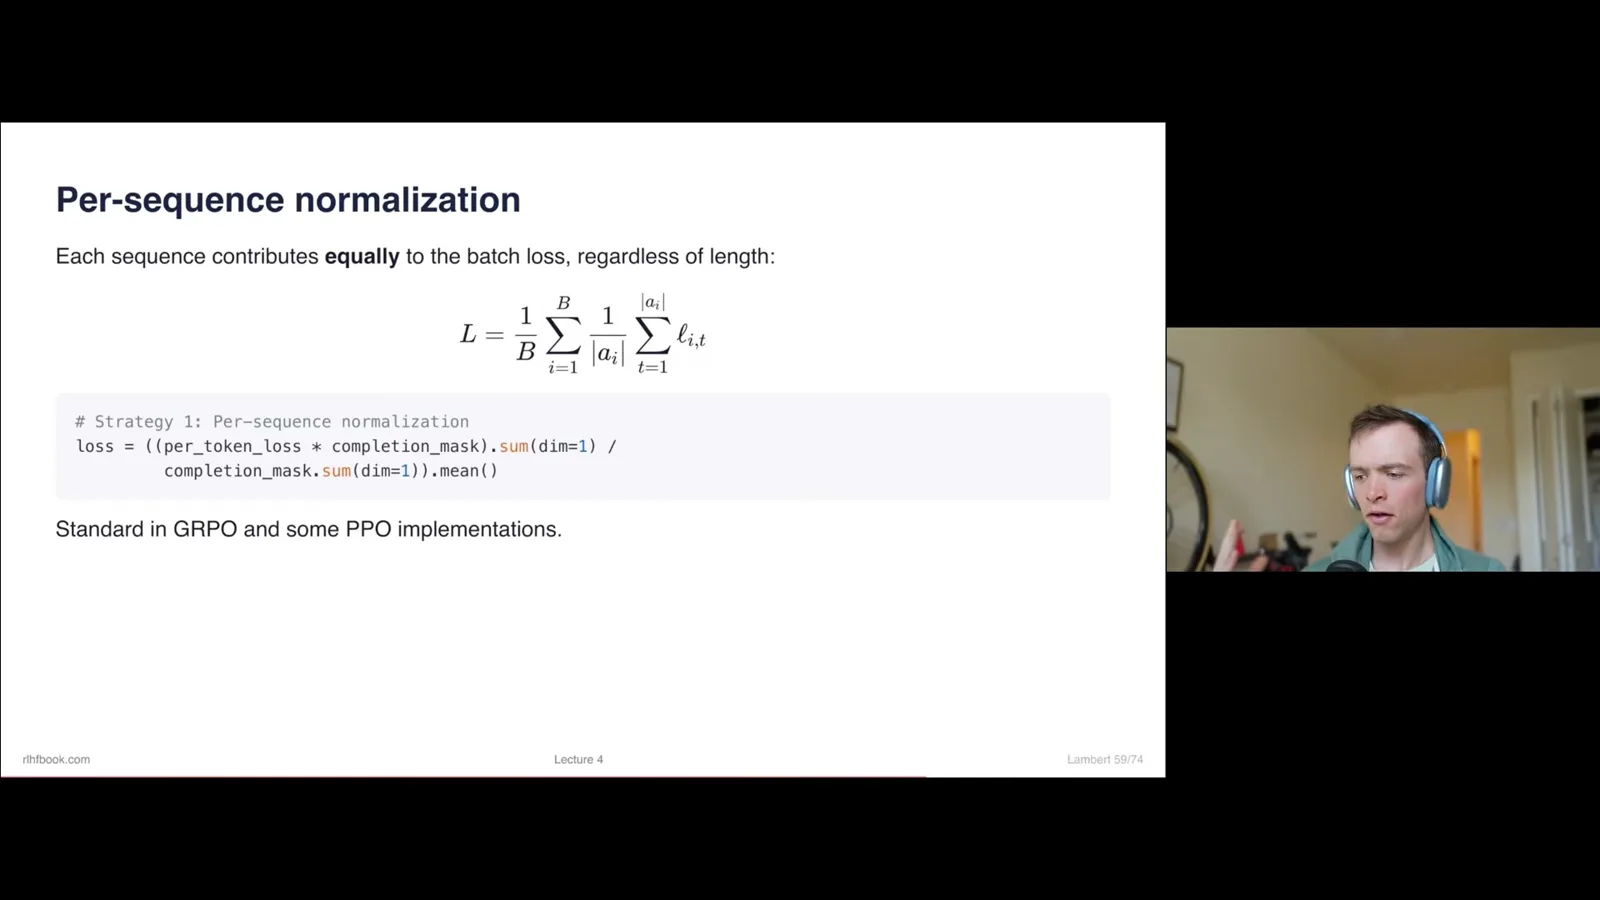
Per-sequence normalization averages within each completion and then across the batch, giving each sequence equal total weight. When two answers have different lengths, tokens in the shorter answer receive greater weight individually.
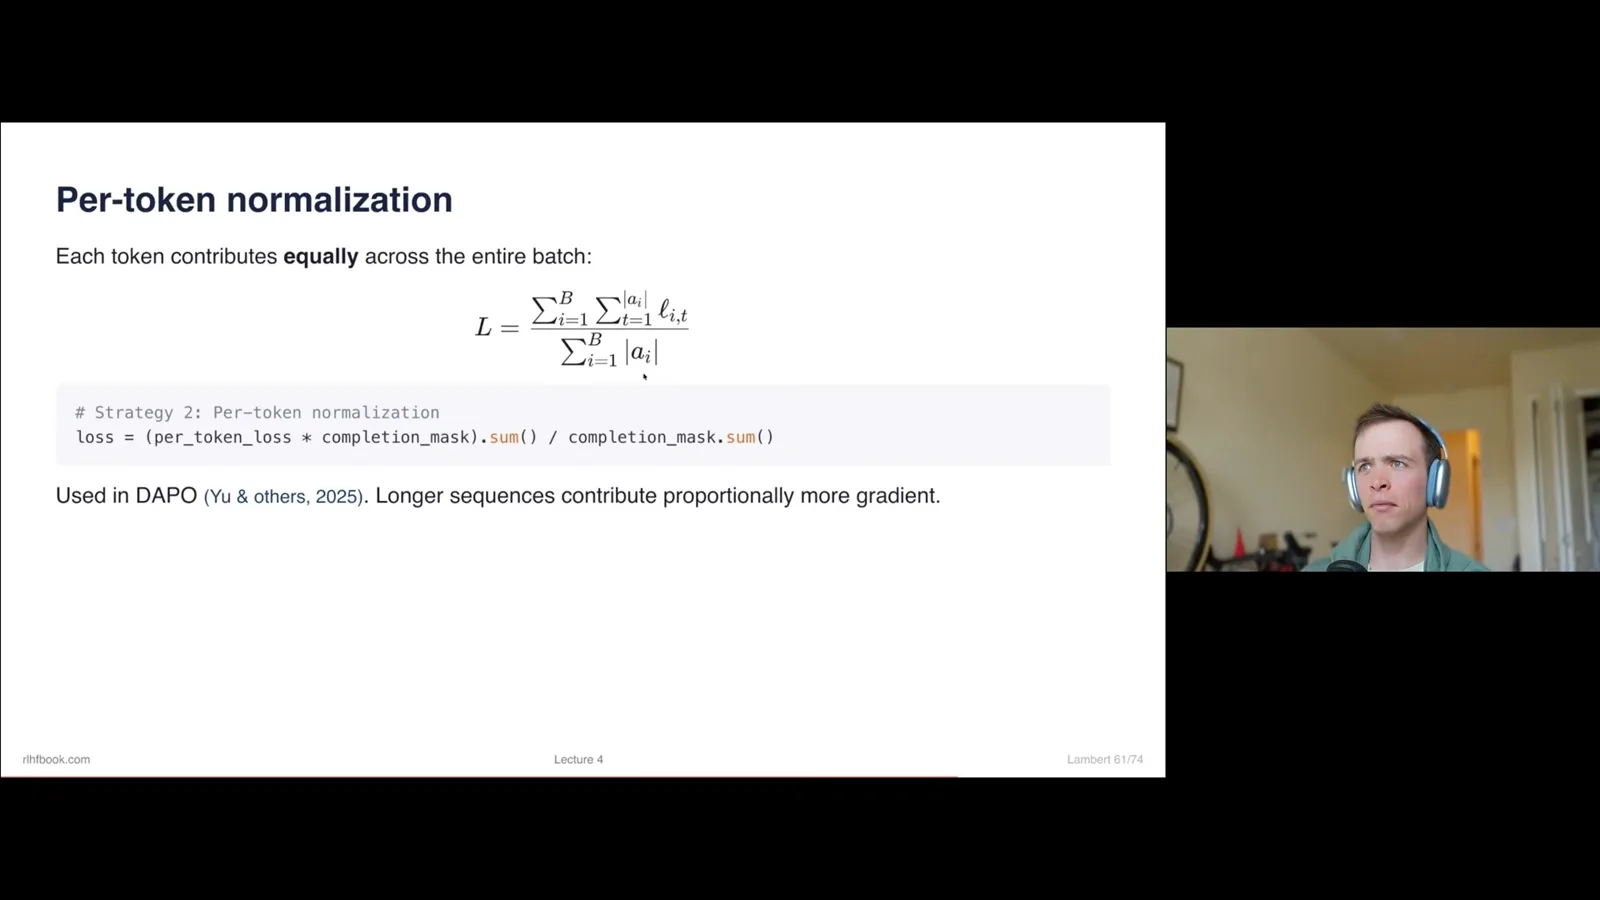
Per-token normalization instead gives each valid token equal weight across the batch, so longer sequences contribute proportionally more. DAPO popularized this choice for reasoning training; it changes the length bias rather than eliminating every possible bias.
Fixed-length normalization, discussed in Dr. GRPO, is another scaling choice. Lambert notes that its relation to per-token normalization can involve a loss-scale factor, which interacts with learning-rate choices and training dynamics.
During training, inspect rewards, KL, clipping, loss spikes, generation lengths and policy entropy. Even verifiable rewards can be exploited: a faulty checker may reward an unintended shortcut. Stable metrics and correctly specified evaluations are both necessary.
The lecture closes with references to the book, code and related papers. Lambert invites questions about confusing implementation details and plans later lessons on reasoning and direct preference optimization.
Mehr aus diesem Kanal
 16:48EN
 Nathan Lambert· 2. Nov. 2026Nathan Lambert on How Open Models Can Compete With Frontier LabsNathan Lambert · Allen Institute for AIOpen models are gaining use and closing capability gaps, but their builders need a sustainable economy and advantages beyond price.
 48:04ENNathan Lambert· 26. Okt. 2026Nathan Lambert on Open Language Models: History, Competition and RiskNathan Lambert · Allen Institute for AIA tour of open weights, research infrastructure, distillation, adoption and the choices facing model developers.
 46:42ENNathan Lambert· 25. Okt. 2026Nathan Lambert and Florian Brand on Kimi K3.1, Cyber Risk and AI AgentsNathan Lambert, Florian Brand · Allen Institute for AIThe Interconnects hosts discuss mixed model evaluations, a wave of security disclosures, and what a personal agent can do in everyday life.
 5:42ENNathan Lambert· 12. Aug. 2026Why the Shoggoth Became a Mascot for AI Post-TrainingNathan Lambert · Allen Institute for AINathan Lambert traces a creature from Lovecraft to a visual metaphor for language models, fine-tuning, and RLHF.
 32:56ENNathan Lambert· 6. Aug. 2026Nathan Lambert: An Introduction to AI Character TrainingNathan Lambert · Allen Institute for AIHow post-training shapes a model’s behavior, from constitutions and model specs to experiments with personality and activation steering.
 32:11ENNathan Lambert· 5. Aug. 2026Nathan Lambert on How Language Model Evaluation Has EvolvedNathan Lambert · Allen Institute for AIFrom few-shot prompts and pass@k to agent sandboxes, noisy scores and benchmark contamination.