In 30 Sekunden
After attending Google I/O in May 2025, Matthew Berman reviews Google’s AI announcements and demonstrations, including personal assistants, model updates, creative tools and Android XR glasses. He is especially interested in context-aware assistants and video generation. The keynote mixed available products, experiments and future plans; benchmark figures, pricing and release claims are historical and attributed to Google.
- 1A 50-fold token increaseGoogle reported growth from 9.7 trillion to over 480 trillion tokens per month across its products and APIs. This does not directly measure individual usage.
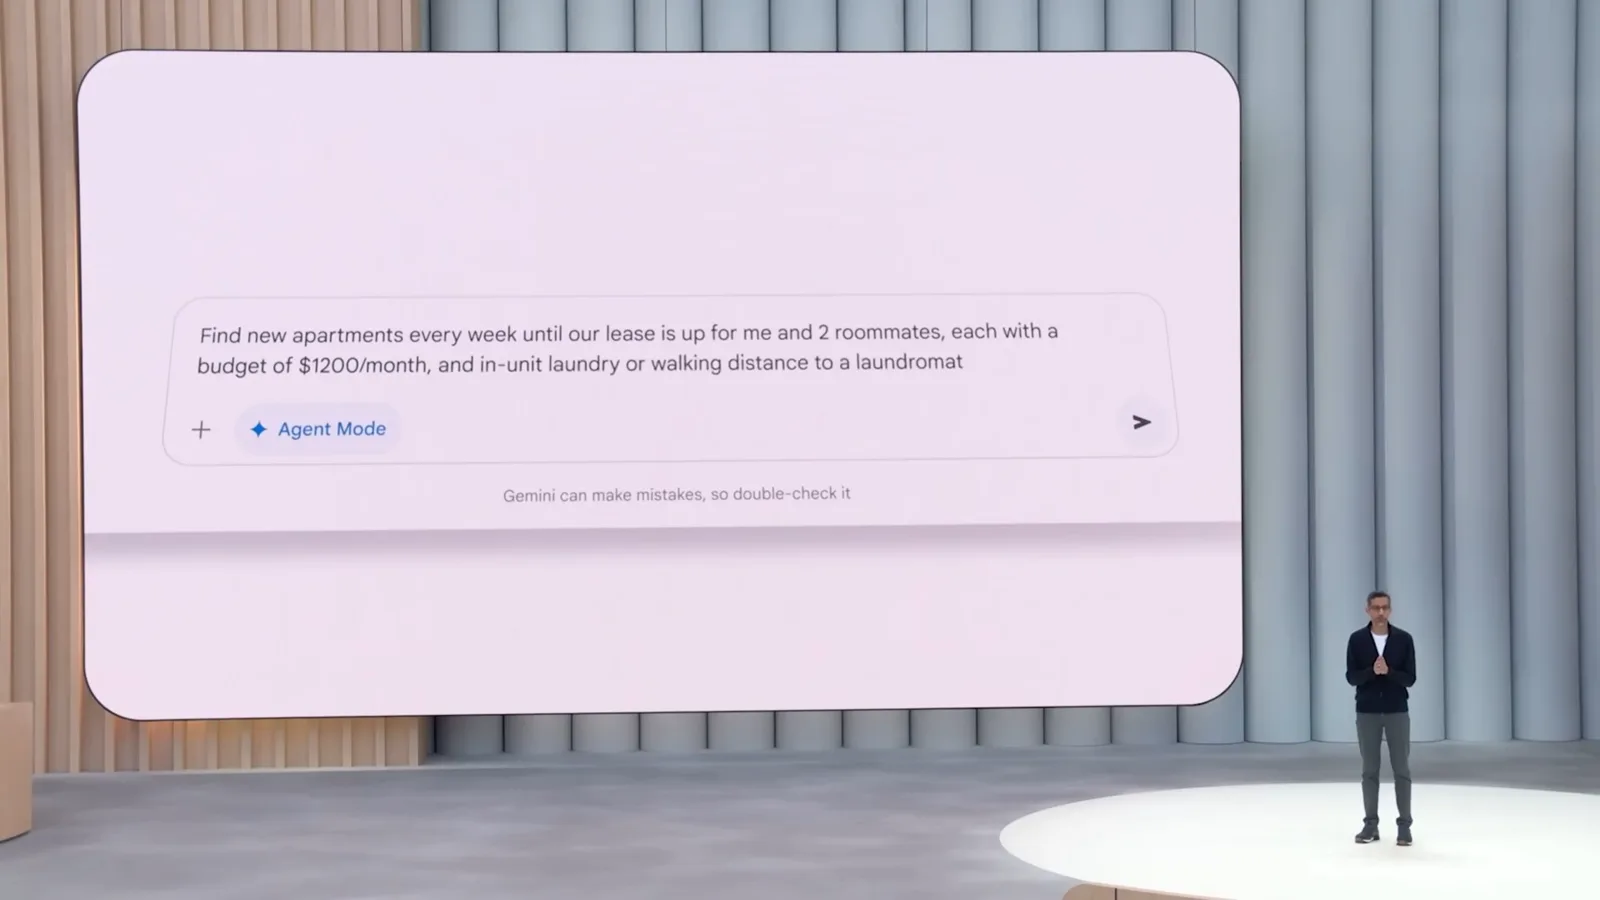
- 2Agentic web tasksMariner and a proposed Gemini agent mode illustrate filtering apartment listings and scheduling a tour. These are early demonstrations.
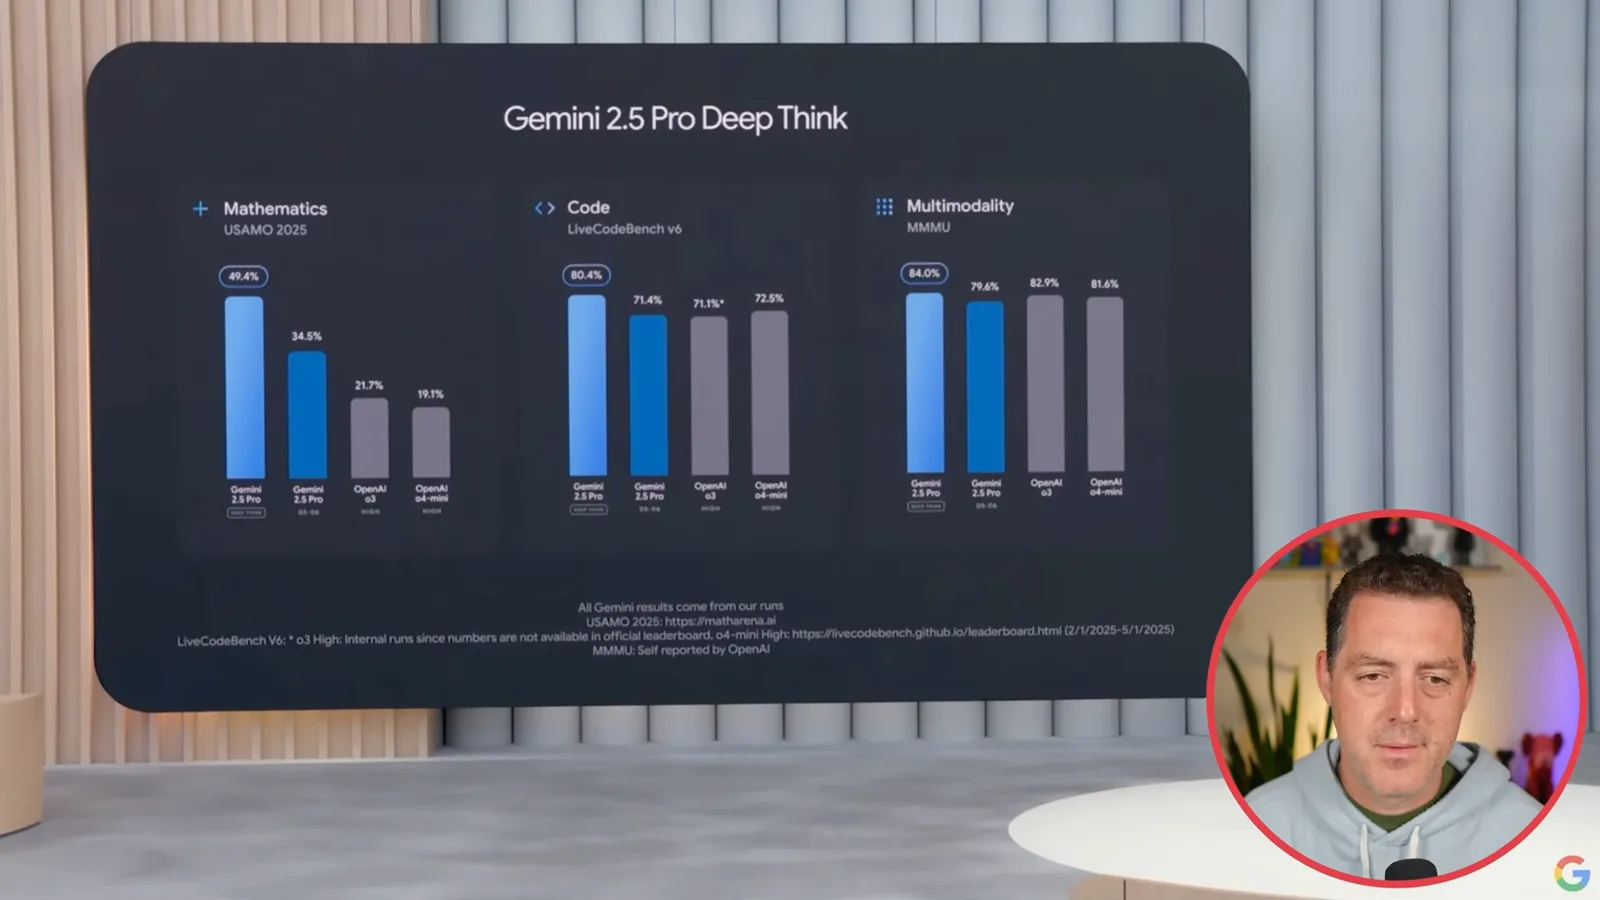
- 3Deep Think benchmarksGoogle’s chart reported 49.4% USAMO 2025, 80.4% LiveCodeBench v6 and 84.0% MMMU. The figures are benchmark- and setup-specific.
- 4Image and video generationImagen 4 and Veo 3 were shown alongside Flow. The promised up-to-tenfold speedup applied to a forthcoming Imagen 4 Fast variant versus Imagen 3.
- 5Prototype XR glassesThe live demonstration showed messages and map overlays, with visible jitter whose cause was not established.
Das Wichtigste
- Google reported more than 480 trillion monthly tokens across its products and APIs in 2025, an aggregate usage metric.
- Project Mariner and the proposed agent mode illustrated web-task automation, while Gemini Live brought camera-based interaction to more users.
- Google reported Deep Think benchmark results on USAMO, LiveCodeBench v6 and MMMU under specific evaluation conditions.
- Veo 3 added generated audio, while Flow demonstrated composition and editing of generated clips.
- Google’s Android XR glasses were a prototype; the keynote demo did not establish everyday reliability.
Den bearbeiteten Text nach Kapiteln lesen
Google’s AI momentum and Beam
Berman reviews the change in Google’s AI releases and its reported token volume. He describes trying the three-dimensional Beam communication system.
I just returned from Google I/O 2025, where Google showed a wide range of AI products. I also interviewed CEO Sundar Pichai about world models, search and an intelligence explosion, and plan to share that conversation separately.
A year earlier, many people doubted Google’s AI strategy. Since then, it has announced or released AlphaFold 3, Imagen 3, Gemma 2, Project Mariner, Gemini 2.5, Gemma 3 and AlphaEvolve. My impression of this event is that Google is moving research into products at a rapid pace.
One striking company metric is monthly tokens processed across Google products and APIs: 9.7 trillion a year earlier versus more than 480 trillion in 2025, roughly 50 times as many. That is Google’s aggregate measure, not a direct measurement of individual users or time saved. Model usage, product integration and longer reasoning outputs can all contribute.
Project Starline has become Google Beam, a three-dimensional video communications platform. Pichai says the goal is to make distant participants feel as though they are in the same room. Google showed it as an enterprise-oriented system rather than an ordinary consumer screen.
I tried Beam in person. Multiple cameras capture the other person and the display produces a depth effect reminiscent of a Nintendo 3DS. My eyes needed a moment to adjust; when someone held up an apple, it felt close enough to reach. That is my impression of a demonstration, not a test of every deployment.
Visual assistants and web agents
Gemini Live and Project Mariner illustrate camera-based interaction and browser automation. A proposed agent mode searches apartment listings and schedules a tour.
Project Astra’s capabilities are also reaching Gemini Live: a phone camera can let users converse about what they are seeing and ask questions about the scene. Google’s comic demonstration has a user mistake a garbage truck for a convertible, a streetlight for a building and a shadow for a follower. Camera and screen-sharing rollout details varied by platform and region.
Project Mariner is Google’s web-interaction agent. The announced multitasking feature points toward a workflow in which an agent handles one task while a user starts another; computer use, tools and memory come together. These are early systems, and a demonstration is not proof that long tasks reliably succeed without oversight.
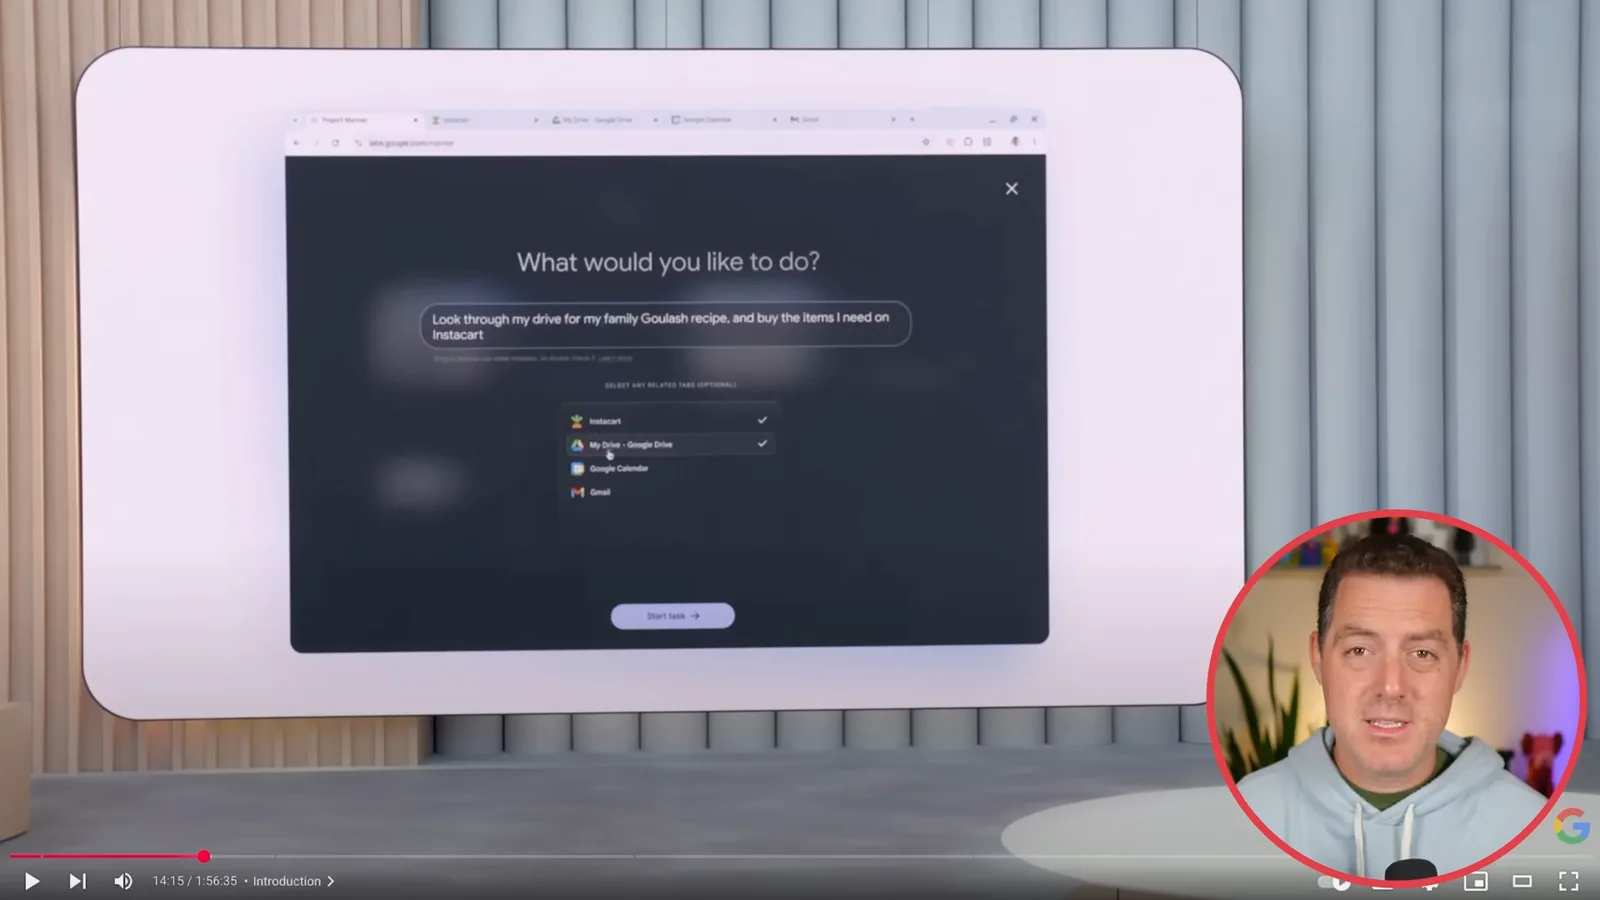
Google also described agent capabilities for Chrome, Search and the Gemini app. In a keynote example, Pichai asks for an Austin apartment for three roommates with a $1,200 monthly budget each and laundry access. The planned agent searches listings, uses Mariner for filters and can use MCP-connected tools to arrange a tour; this is a demonstration of a proposed workflow.
Personal context and model research
Berman discusses personalized replies, Gemini updates, diffusion-based text generation and Deep Think. He also reviews Google’s world-model and robotics ambitions.
What excites me most is a personal assistant that can use context from services such as Gmail, Calendar and YouTube, alongside memory from earlier interactions. I would like to open my inbox and find draft replies tailored to my history with each contact, ready for me to review and send. Personalized smart replies move partway toward that vision, but are not the full workflow I imagine.
I was also pleased that Google referenced my work with Gemini and a Rubik’s Cube demo during the presentation. The company introduced model updates including thinking budgets, faster performance and summaries. Thinking budgets offer a way to trade off reasoning-token use, latency and cost in supported configurations.
Google introduced Gemini Diffusion, a research model that iteratively refines text or code from noise. I find the speed of the demonstration striking, though model quality and latency depend on the specific system and measurement; diffusion is not automatically faster or less accurate than every autoregressive transformer. Google presented it as research, not a broadly proven replacement.
Gemini 2.5 Pro Deep Think was introduced as an experimental enhanced-reasoning mode using techniques including parallel approaches. In Google’s keynote chart, the company reported 49.4% on USAMO 2025, 80.4% on LiveCodeBench v6 and 84.0% on MMMU, a multimodal benchmark. These are reported scores for specific setups and competitors, not a universal ranking; the third benchmark is MMMU, not MMLU.
Google also spoke about moving toward world models. Demis Hassabis points to representations of nature, Veo’s video examples and Gemini Robotics as steps toward systems that can handle the physical world. The examples are demonstrations and the broader goal remains a research ambition, not proof of comprehensive physical understanding.
Generative media and subscriptions
Imagen 4, Veo 3, Lyria 2 and Flow were featured at the event. Berman reviews creative examples and the 2025 Ultra subscription price.
Imagen 4 generated detailed examples including a dress, paper-style bird, flowers and a cat. Google announced an Imagen 4 Fast version planned to be up to ten times faster than Imagen 3; the figure is a company claim about that specific forthcoming variant, not a measured speedup for every Imagen 4 request.
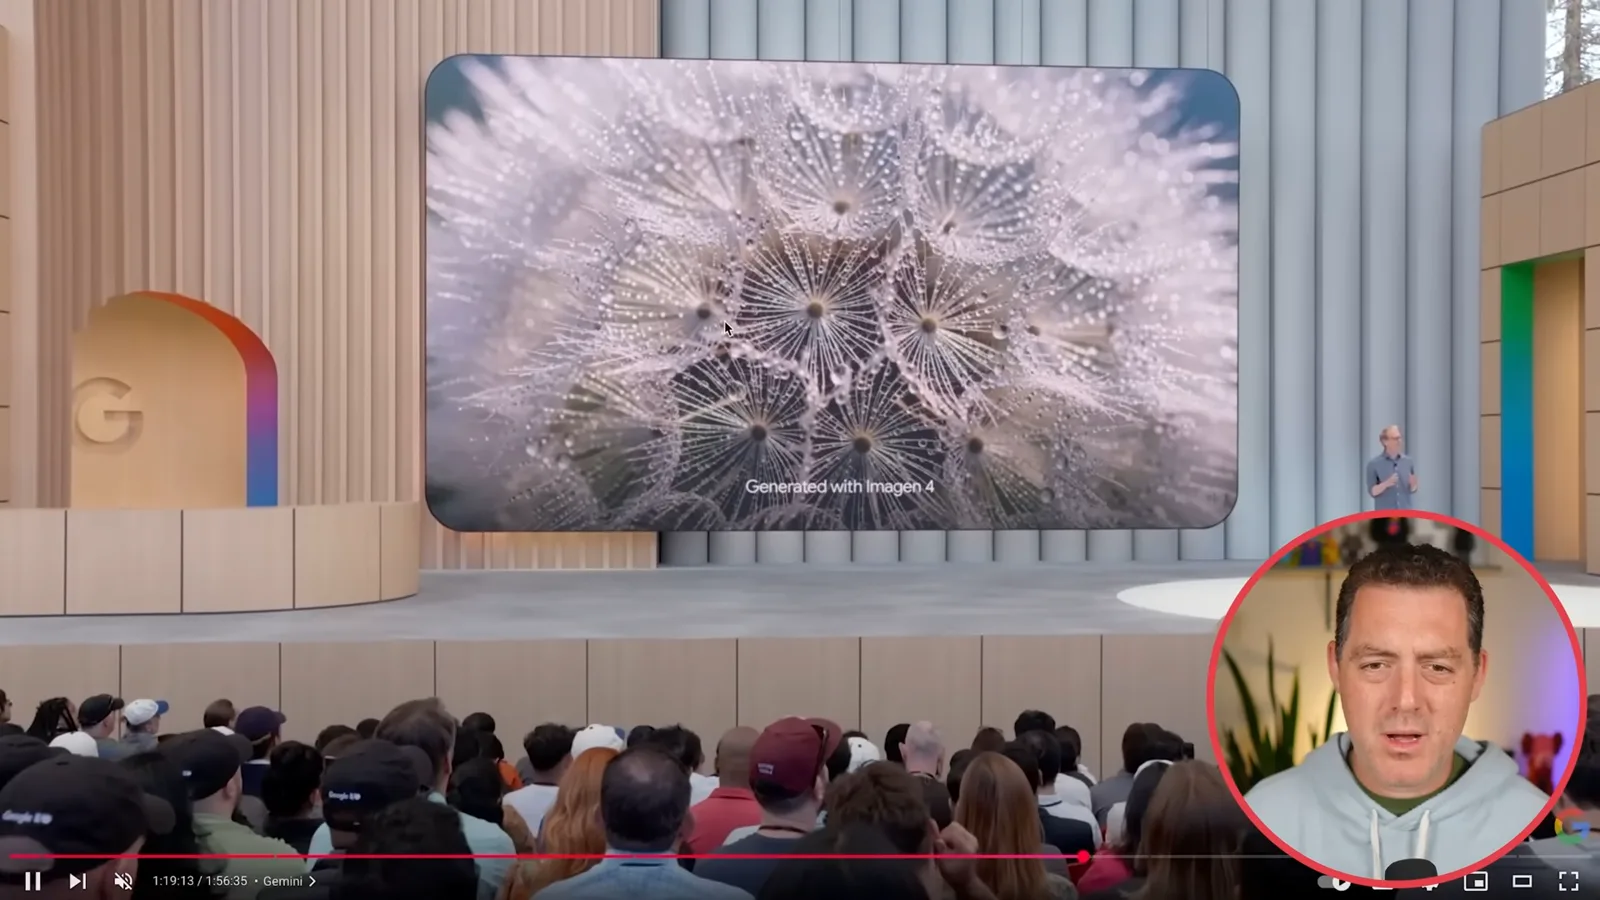
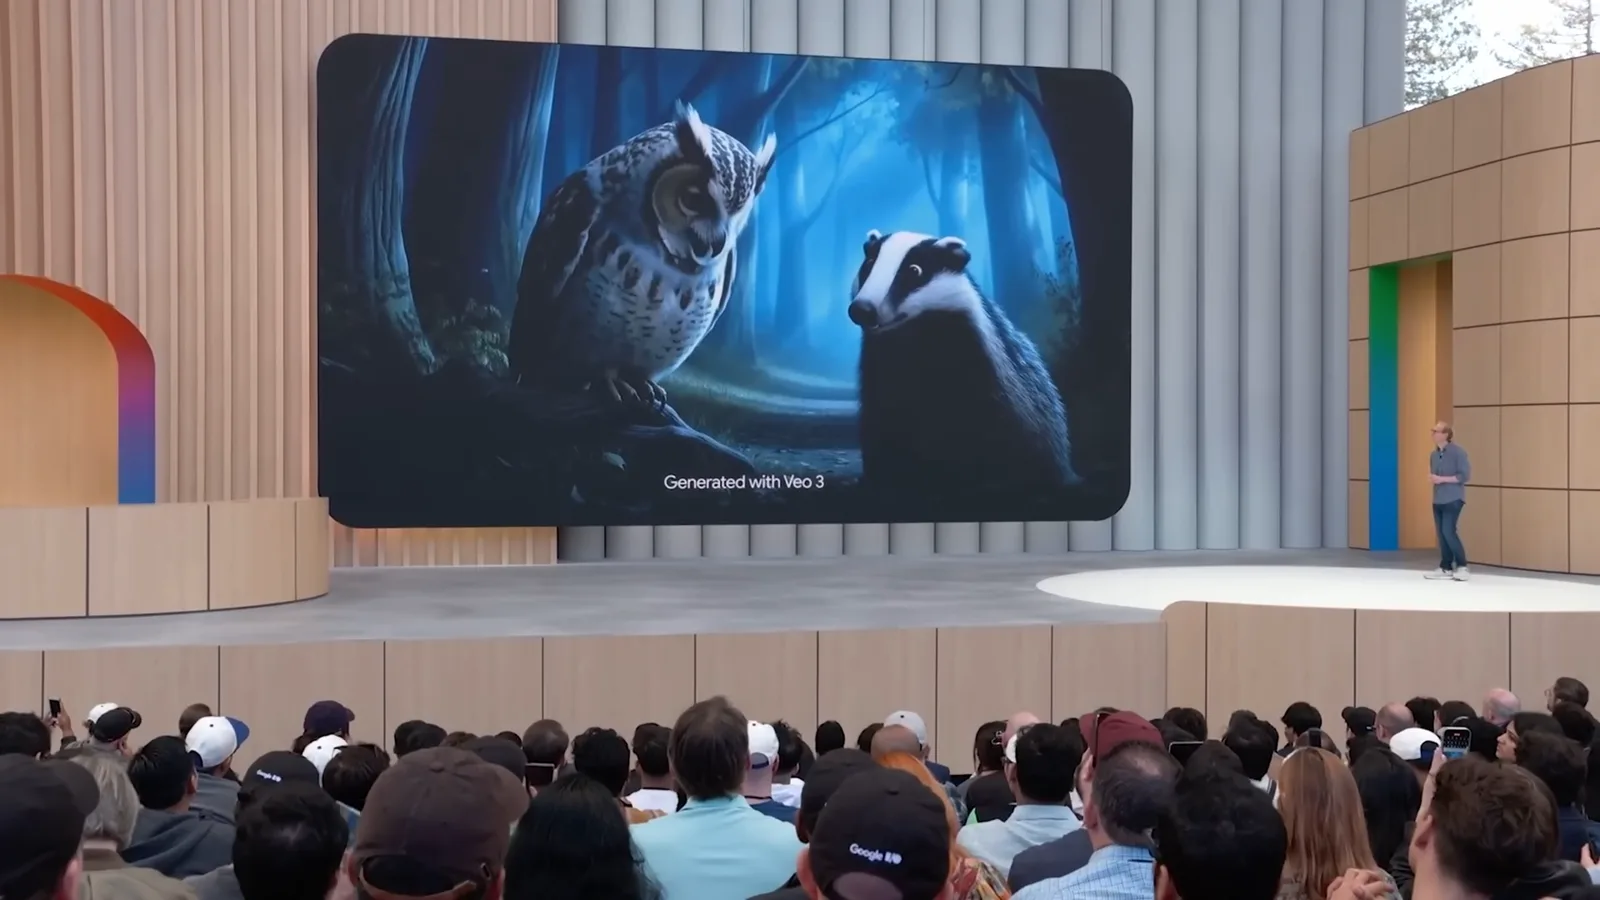
Veo 3 generates video with audio, including dialogue and sound effects, as shown in clips of animals and the ocean. Google also introduced the music model Lyria 2. I plan to test the tools myself; polished examples selected for a keynote do not independently establish typical output quality.
At the event Google AI Ultra was announced in the US at $249.99 per month, with a first-time three-month discount and higher limits and early access to features. I consider it expensive but plan to subscribe and report back. That is the 2025 launch price and availability, not a current price quote.
Flow combines Google’s generative media models into a filmmaking tool. In the demo, a creator generates ingredients such as a chicken-shaped gearshift, supplies a camera-angle prompt and combines images to create a clip. The interface can arrange and extend clips, giving creators more control than a single prompt alone.
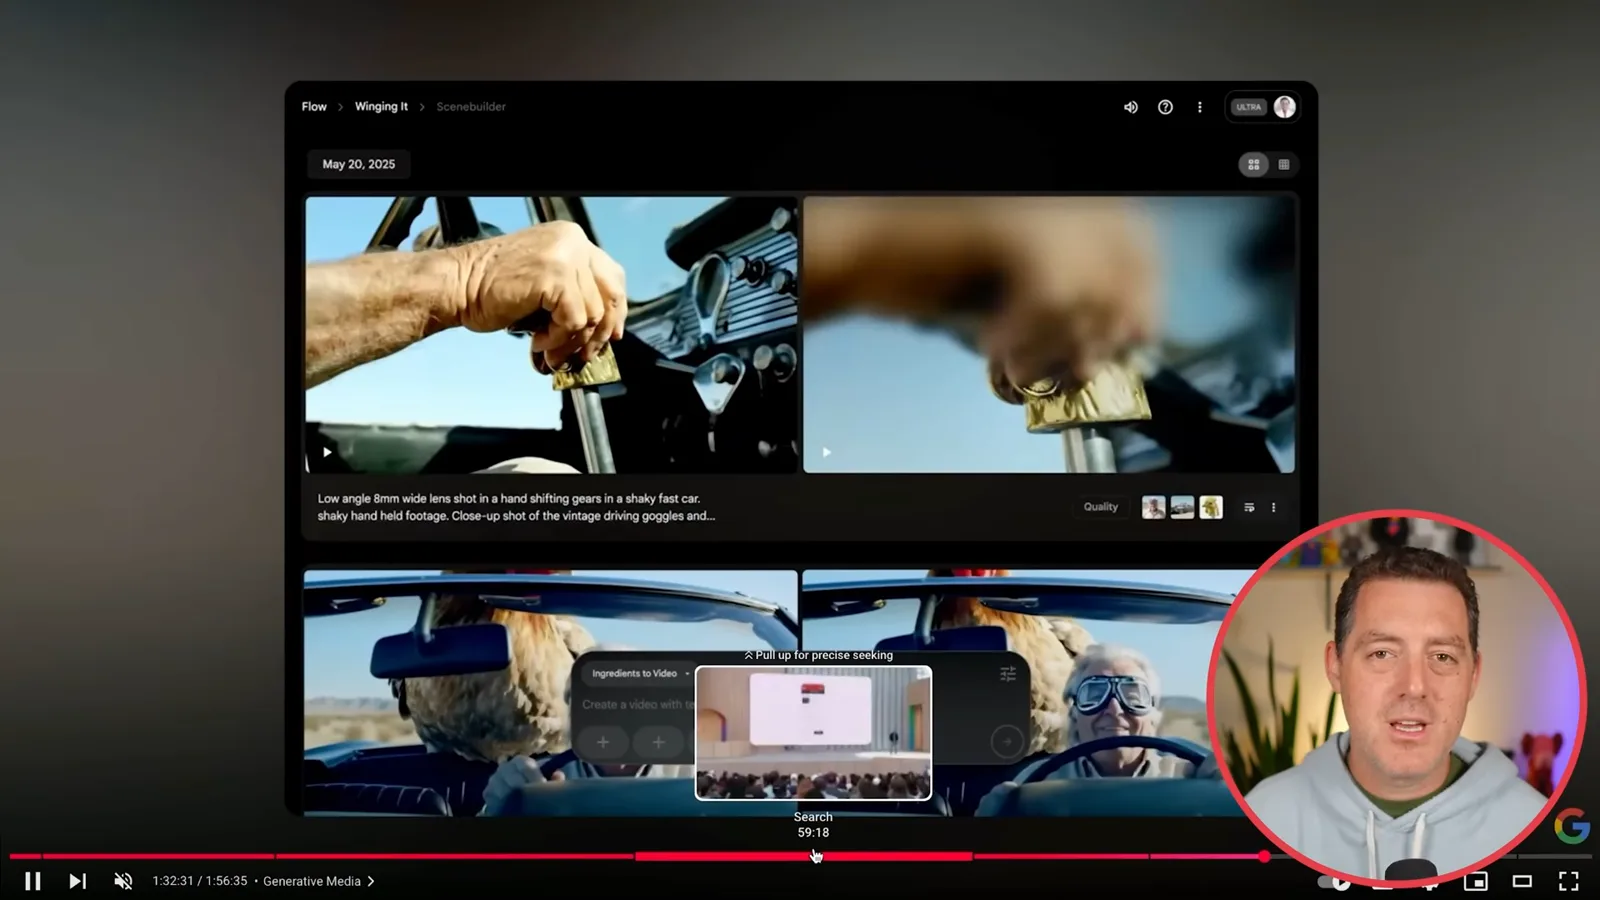
The resulting sequence combines generated visuals and sound. I compare Flow with Sora’s scene-building tools and express my preference for Veo 3’s video quality; that comparison is my judgment, not an independent benchmark. I intend to do a more extensive test later.
Android XR glasses
A prototype live demo showed information and navigation overlays. Berman reflects on when he would want to wear glasses.
Finally, Google showed prototype Android XR glasses with information displayed in the lens. A live demonstration showed a backstage wearer receiving a message, checking the weather and looking at navigation. There was some visible jitter; I suspect network conditions, but the video does not establish the cause.
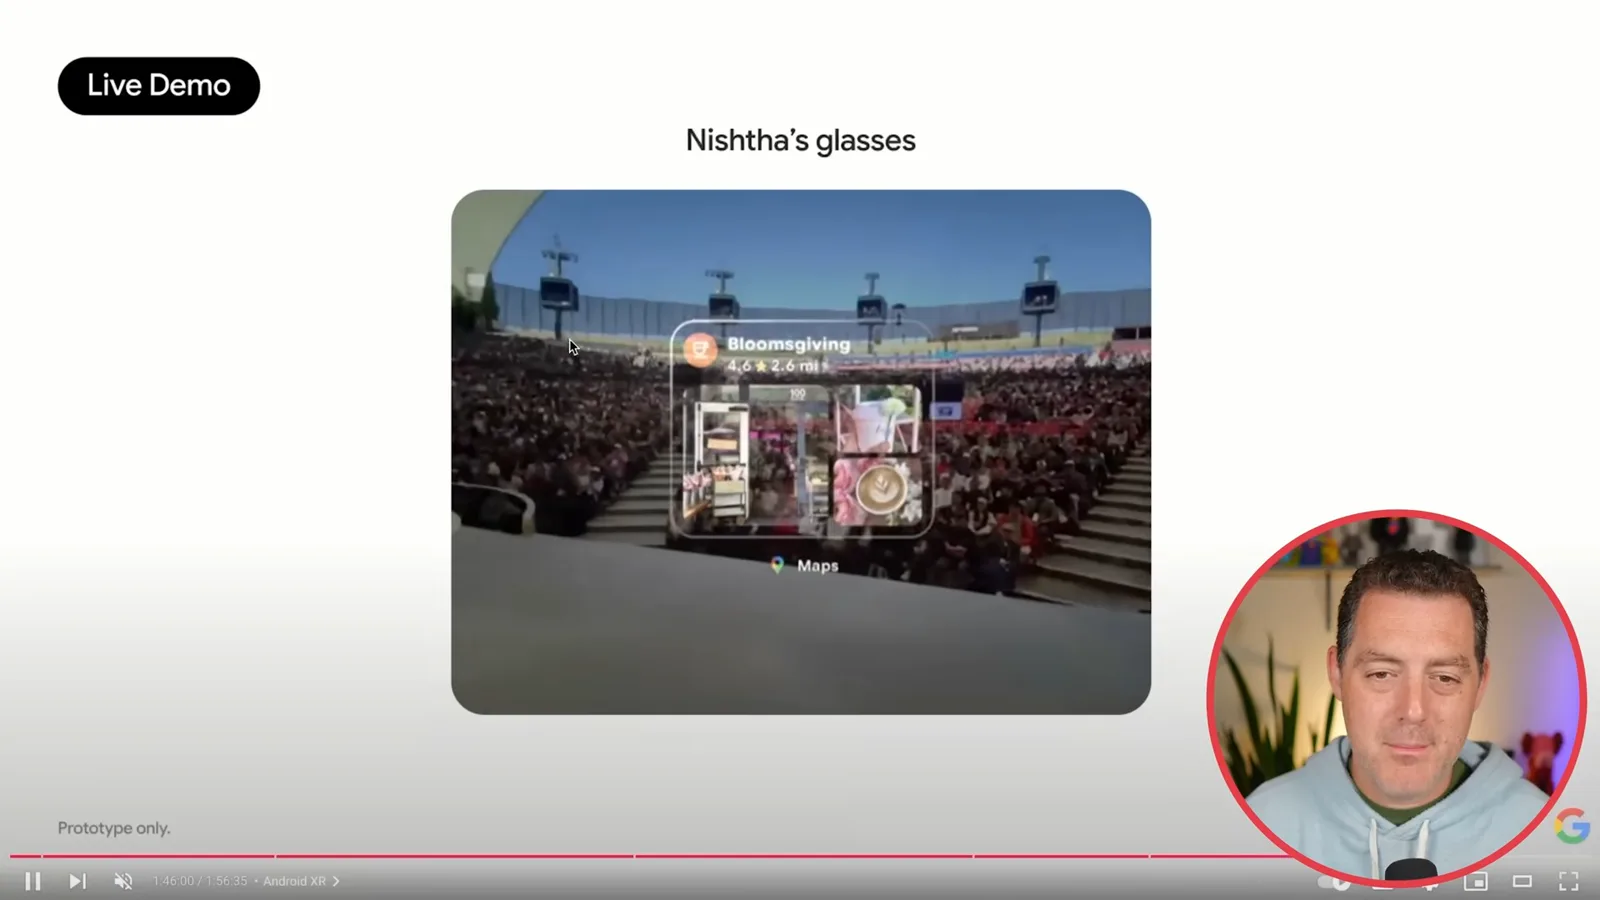
The demo shows a maps recommendation and directions over the wearer’s view. I have been skeptical that glasses are the ultimate AI form factor: I would wear them outdoors but do not want to wear them all day indoors. The prototype is a demonstration, not a guarantee of a released product or everyday performance.
Mehr aus diesem Kanal
 34:21EN
 Matthew Berman· 27. Okt. 2026Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 0:26ENMatthew Berman· 25. Okt. 2026Sam Altman on Human Values and Problem-Solving in an AI WorldSam Altman · OpenAIIn a short interview excerpt, Altman considers the enjoyment of solving hard problems and the human role in interpreting results.
 0:36ENMatthew Berman· 25. Okt. 2026Kimi K3.1 and a Rubik’s Cube Solver DemonstrationMatthew Berman · Forward FutureMatthew Berman shows a scrambled virtual cube being solved and gives the Kimi K3.1 test a favorable assessment.
 0:21ENMatthew Berman· 24. Okt. 2026An AI-Generated Kimi Benchmark Chart Used Invented ScoresMatthew Berman · Forward FutureMatthew Berman asks for a graph of Kimi K3.1 Pro benchmarks, then discovers that the displayed figures are illustrative placeholders.
 25:50ENMatthew Berman· 24. Okt. 2026Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.
 32:20ENMatthew Berman· 23. Okt. 2026Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.