In 30 Sekunden
Mikyo King of Arize AI describes code mode as an alternative to filling an agent’s context with a large catalog of tools and every intermediate result. An agent can discover tools, compose calls in a programming environment and return only relevant information. King discusses Arize Phoenix implementations, security and operational tradeoffs, and a Harbor-based evaluation. In the reported comparison, code mode used fewer tokens and cost less with approximately unchanged latency and the same reward.
- 1Tool catalogs can crowd contextKing describes how definitions, repeated tool results and pagination can accumulate across a long task.
- 2The model programs the toolsA sandbox lets an agent discover tools, compose calls and return only the information needed for the next step.
- 3Code mode in PhoenixArize exposes Bash, Python operations, SQL and a browser-bound programming interface to its agent.
- 4Security and operational tradeoffsGenerated code raises questions about resources, network egress, secrets, permissions, failures and debugging.
- 5Evaluate repeated trialsThe team uses Harbor sandboxes and verifiers, with Phoenix recording trajectories and evaluation outcomes.
- 6Results in one evaluationKing reports 43% fewer tokens and 31% lower cost, with roughly unchanged latency and the same reward in the comparison shown.
Das Wichtigste
- Code mode lets an agent discover and compose tools in a programming environment rather than loading every tool and result into context.
- Sequential, parallel and conditional tool calls can be combined in one program.
- Sandbox resources, network access, secrets and permissions require explicit controls.
- Failures, durability, tool discovery and nested sandboxes add operational complexity.
- King reports a 43% token reduction and 31% cost reduction in Arize’s evaluation, with similar latency and unchanged reward.
Den bearbeiteten Text nach Kapiteln lesen
From software tools to generated programs
King describes how coding agents can generate task-specific software and why large tool catalogs burden agent context.
I’m Mikyo King, and I lead the open-source group at Arize AI. We work on an open-source observability and evaluation framework as well as our own agent. I want to explain code mode and how we have adopted it.
Traditionally, software for engineers and software for non-engineers have been different. A programmer asked to collect email invoices might write a script, while someone else would work within an existing interface. Coding agents can dynamically build some of that task-specific software, which changes the boundary.
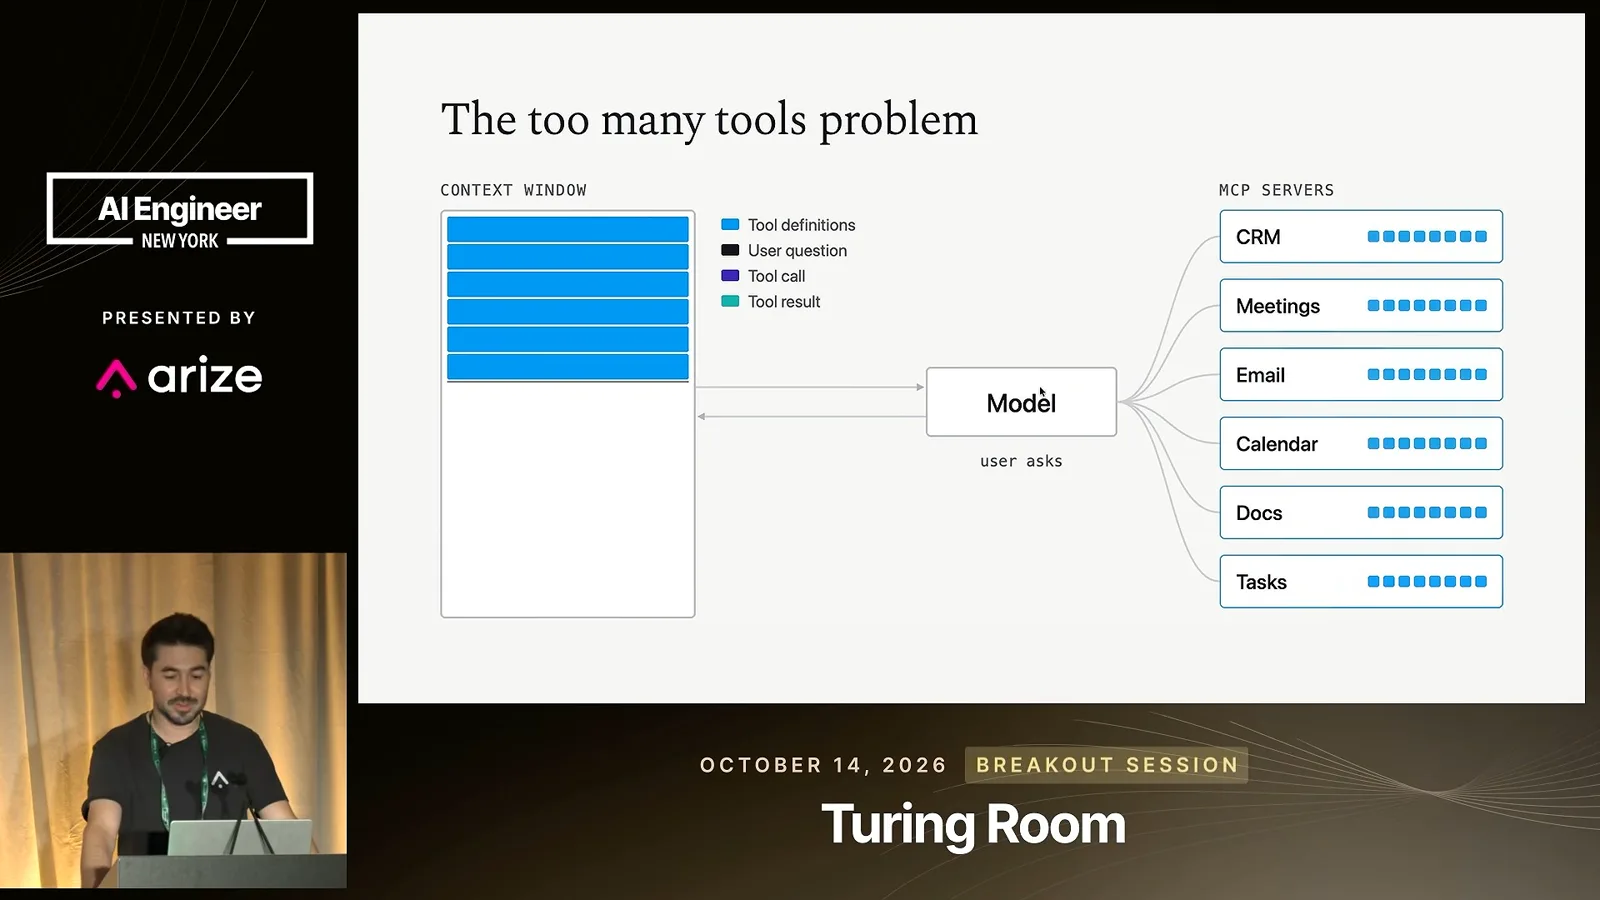
A conventional agent may receive a large catalog of tools. As it repeatedly calls them, definitions and results accumulate in the context window. More tools, irrelevant outputs, pagination and long tasks can create context bloat, extra turns and eventually a need for compaction.
Code mode is an alternative architecture. Instead of presenting the entire catalog, the agent can search for a tool and execute it in a programming environment. It can sequence calls, run them in parallel or use conditionals, and return only the information needed in the model’s context.
How code mode works
The agent searches for tools and combines calls in a sandbox. King discusses progressive disclosure, composability and selective output.
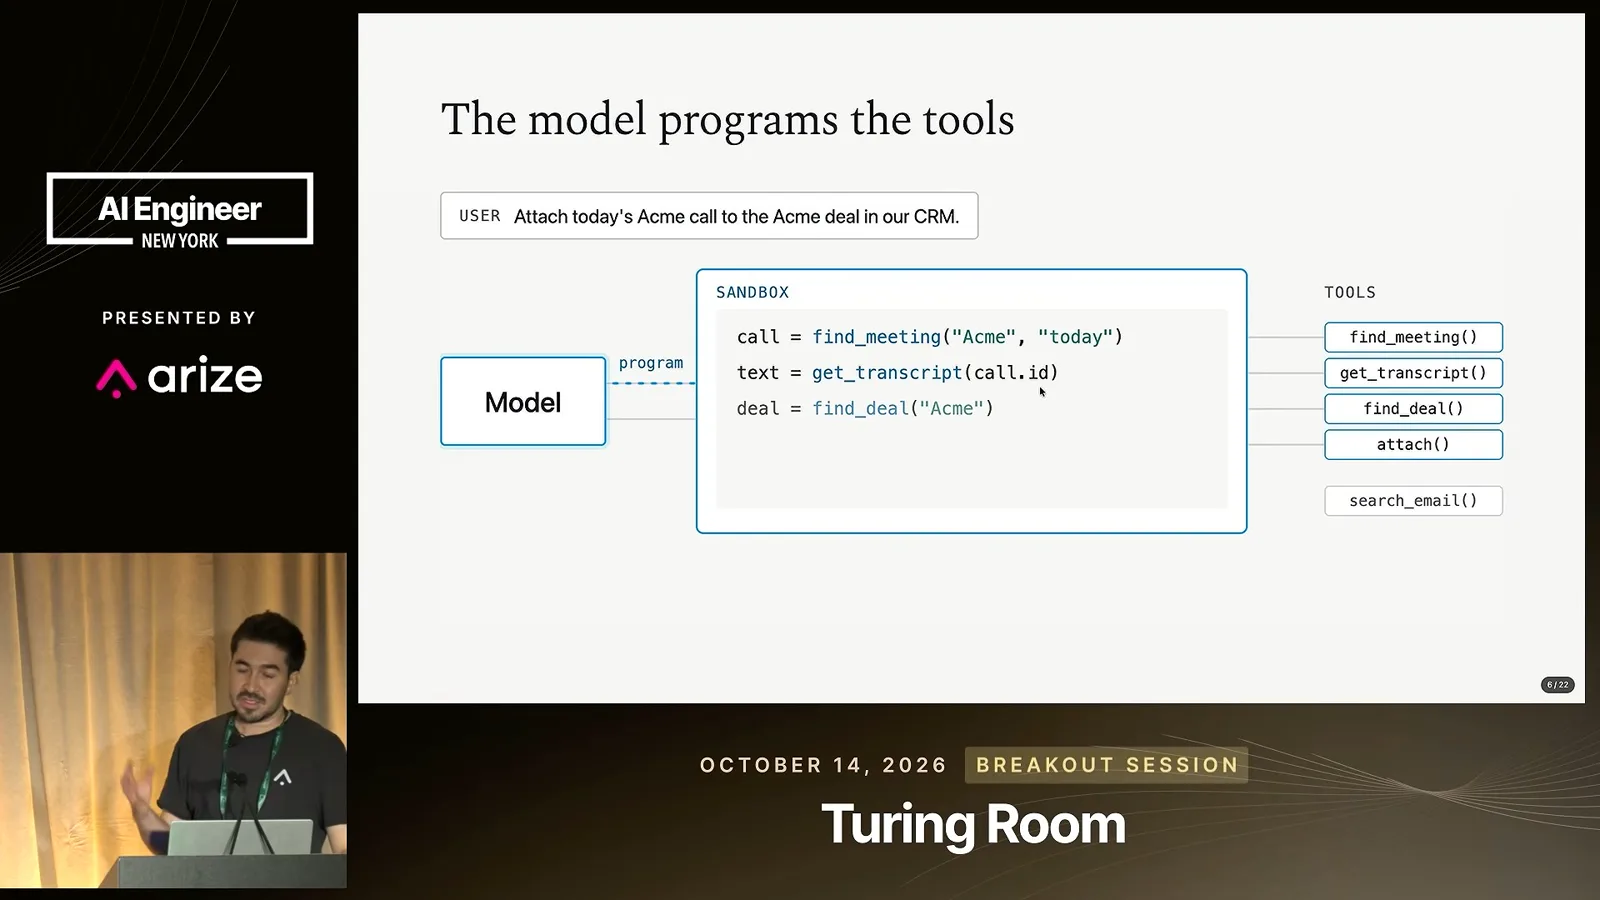
Compared with accumulating each tool result in the context window, a well-implemented code mode can reduce overhead and turns. King emphasizes progressive disclosure: the model discovers and understands the tools needed for the current task rather than receiving every definition up front.
Composability lets an agent chain calls or fan them out. It can also trim or search tool output before returning it to the model. King sees a further benefit in emergent behavior: an agent may write a small program for a task for which no dedicated tool exists.
For example, a program could remove personally identifiable information from records before returning results, rather than placing sensitive values directly in the context. That capability depends on the implementation and the boundaries of the sandbox.
Arize Phoenix examples
He describes Bash, Python, SQL and browser-bound code interfaces used by the Phoenix agent.
In Arize Phoenix, the team started by giving its agent Bash, so it could combine standard command-line tools with its own CLI and save intermediate results in files. It also added a Python sandbox exposing REST create, read, update and delete operations for traces and datasets.
The team added SQL because not every useful question fits a CRUD tool. An aggregate query can identify spans with a given latency characteristic without paging through all traces in the model’s context.
Arize also built a programming interface bound to its browser UI. Code running in a web worker can interact with application state, such as a time range or frontend data store. King describes this as enabling more complex UI interactions through code.
Tradeoffs and open problems
Generated code introduces resource, security and operational concerns, including durability and moving binary data out of a sandbox.
Code mode is not free: generated code needs resources. A hosted sandbox must manage CPU, memory and lifetime. Network egress deserves particular attention because an agent may need the web while encountering untrusted content.
Secrets and permissions are also hard. A sandbox may need credentials for a model or service, but those secrets should not return to the model’s context. Permissions that seem appropriate for individual operations can become too broad for a later operation or a composed workflow.
There is operational complexity as well. Sandboxes can fail to start, and debugging a program differs from debugging individual tool calls. Tool parameter accuracy becomes code accuracy, and a workflow can fail halfway through. Tool discovery still requires a way to find and understand available tools.
King also notes nested sandboxing when code mode is implemented both in MCP and in the agent harness. Results may be serialized and parsed between environments, adding work. Durability remains an open problem: a long program that fails midway may not resume at the failed step.
Language choice can matter for determinism or mathematics. Binary data such as images is another challenge: serializing an entire image into the context is undesirable, so a separate handoff may be needed. Smaller models may also struggle with code mode compared with frontier models.
Evaluation and results
King explains Harbor trials, verifiers and Phoenix traces, then shares observed token, cost and latency results.
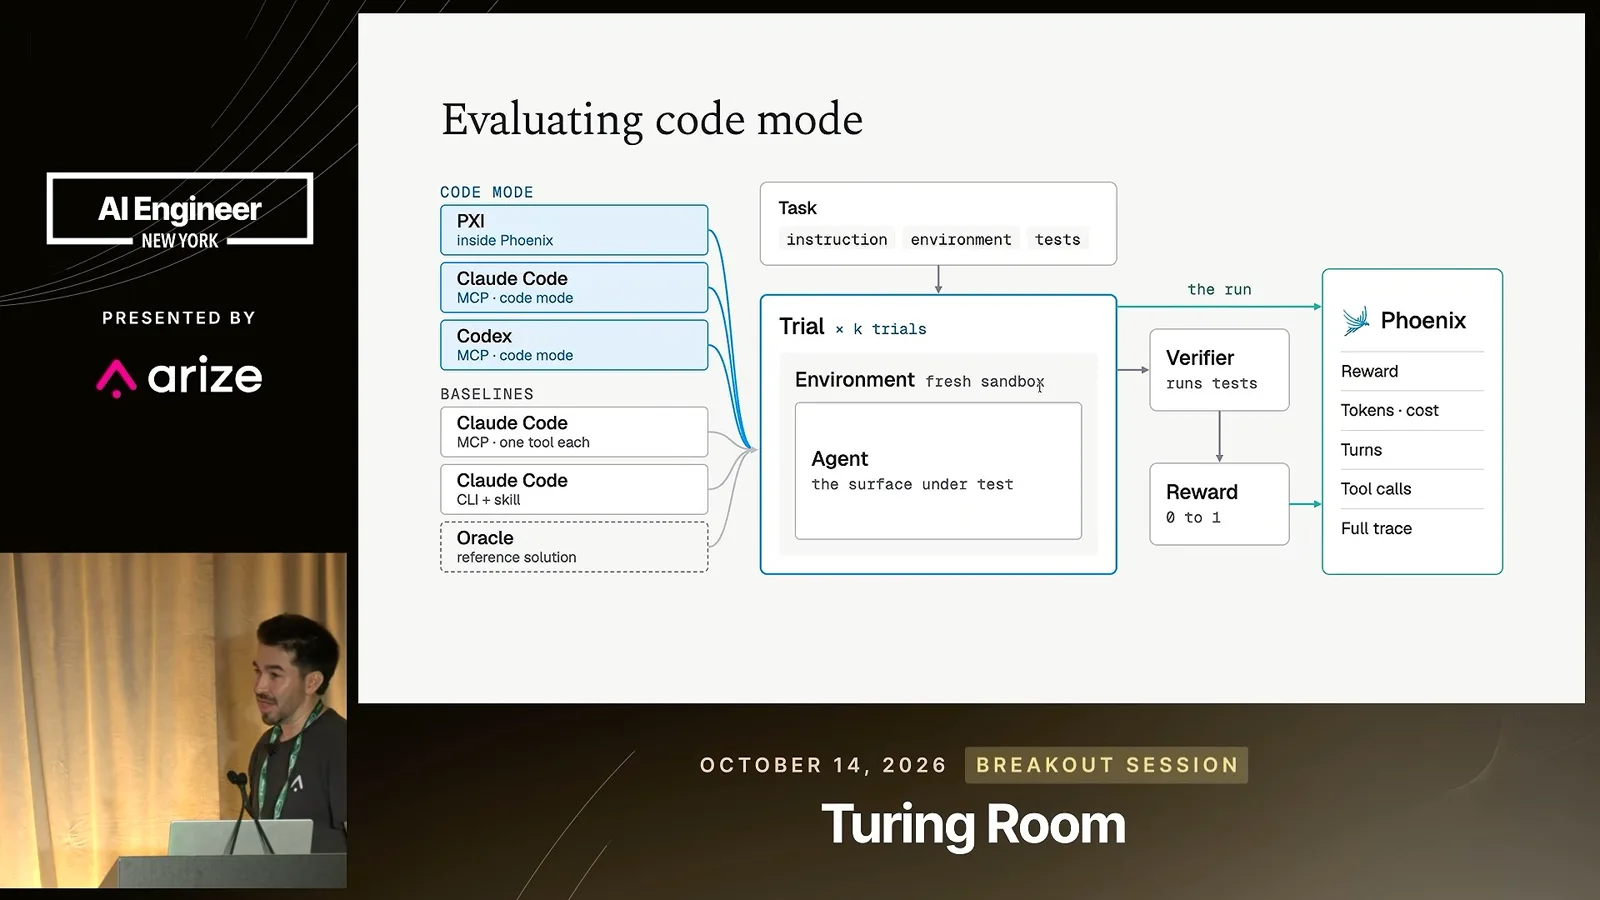
To evaluate the approach, Arize uses its Phoenix platform and the Harbor framework. Agents run in sandbox environments on defined tasks with network access disabled. The team repeats trials, uses verifiers to score task completion and tracks pass-at-k across tasks to account for variable trajectories.
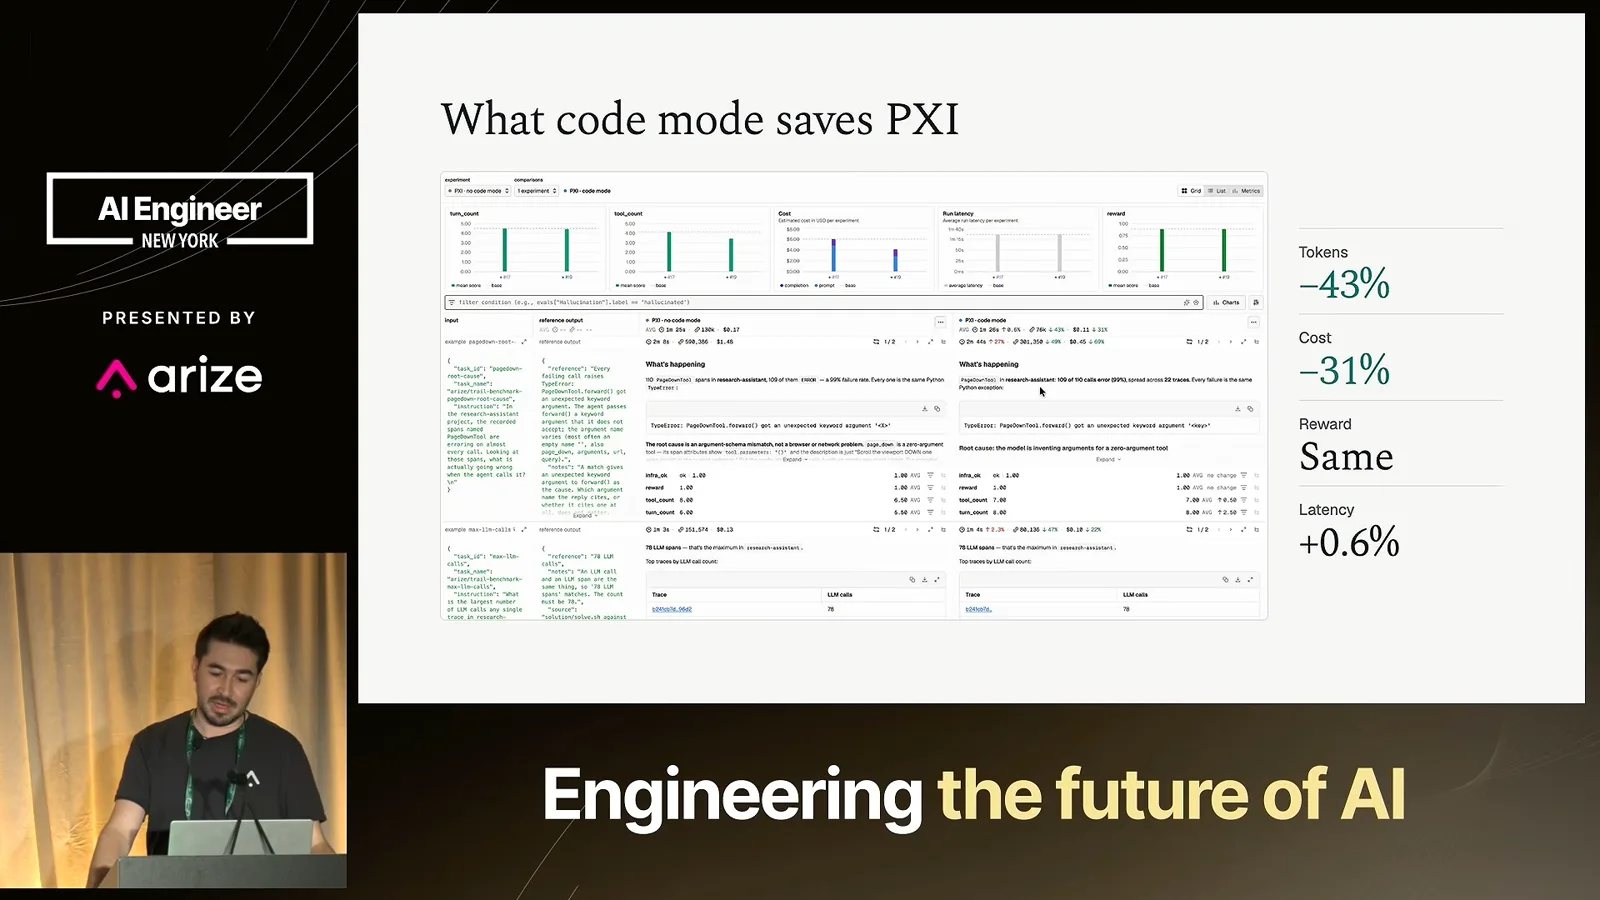
King shows a before-and-after comparison reporting 43% fewer tokens and 31% lower cost. The slide reports the same reward and a 0.6% latency increase, despite sandbox overhead. He treats this as evidence for the evaluated setup, not a universal guarantee.
Capturing both trajectories and evaluation results helps the team understand failures and improve instructions. A newly added tool can initially reduce efficiency; traces can reveal which instructions lead the agent in the wrong direction and guide further iterations.
King closes by emphasizing fewer turns, lower cost and the potential for agents to build longer-horizon behavior. He encourages teams to try a sandbox and evaluate their own agents rather than assuming the architecture is automatically better.
Mehr aus diesem Kanal
 21:32EN
 AI Engineer· 29. Okt. 2026Shy Ruparel on AI agent reliability and recovery after failuresShy Ruparel · TemporalTemporal’s survey finds a gap between frequent agent use and dependable deployment. Ruparel demonstrates a synthetic payout workflow that resumes after workers stop.
 14:50ENAI Engineer· 29. Okt. 2026Cole Gannaway on code review, cross-repository risk and AI software factoriesCole Gannaway · QodoA one-line rename can pass local checks while affecting distant clients. Qodo’s Cole Gannaway explains how review context, shared rules and independent agents can expose those risks.
 11:47ENAI Engineer· 29. Okt. 2026Revolut’s David Abitbol on self-hosting AI coding models at scaleDavid Abitbol · RevolutAbitbol shares engineering delivery trends, GPU-serving costs and latency tuning, then describes controls for operating the tools in a regulated bank.
 21:47ENAI Engineer· 28. Okt. 2026Patrick Smyth on Open-Source Supply Chain Security in the AI EraPatrick Smyth · ChainguardChainguard’s Patrick Smyth discusses faster exploitation, malware in dependencies, zero-days and the expanding attack surface around developer workflows.
 14:09ENAI Engineer· 28. Okt. 2026Taylor Luttrell-Williams on Finding Logic Vulnerabilities with SonarQube Hunter AgentTaylor Luttrell-Williams · SonarSonar’s Taylor Luttrell-Williams explains how a security agent maps a codebase, investigates logic flaws and presents validated findings alongside conventional scans.
 16:29ENAI Engineer· 28. Okt. 2026Chris Vela on Benchmarking vLLM Configurations with Runpod BenchPodChris Vela · RunpodRunpod’s Chris Vela demonstrates a dashboard for comparing LLM serving configurations and choosing performance settings with workload-specific data.