In 30 Sekunden
In this July 2024 sponsored introduction, Matthew Berman explains how retrieval can add selected external material to a language-model prompt. He uses a vector database workflow, a vehicle manual and a multi-step agent example to show the idea. RAG does not require a particular vendor or vector database and does not guarantee accuracy; Pinecone sponsored the video and was his exclusive channel partner.
- 1Retrieval and fine-tuningBerman distinguishes adding external context from altering model behavior, though fine-tuning has broader uses than tone alone.
- 2The context budgetA model has a limited token budget; historical model examples illustrate why repeatedly inserting entire collections can be costly.
- 3Relevant passagesA recent earnings report can be indexed and relevant passages retrieved for a question, rather than included in full each time.
- 4Embeddings and retrievalA model converts text into numerical vectors; a query can be embedded and matched to indexed passages.
- 5Multi-step searchAn illustrative agent searches for Apple Remote and then Front Row to answer a multi-hop question.
- 6Vendor and alternativesPinecone offers vector storage and search, but search can also use lexical or structured methods, with performance depending on implementation.
Das Wichtigste
- RAG retrieves external information and supplies selected context to a model at generation time rather than necessarily changing its weights.
- Context limits and repeated input costs can make including a complete document collection in every prompt impractical.
- Embeddings and vector similarity are one retrieval strategy; keyword, structured and hybrid search are also possible.
- Fine-tuning can change style or task behavior and can encode knowledge, but it is not a reliable substitute for a maintained external source.
- Retrieved material can be irrelevant, outdated or misused, so RAG can reduce hallucinations without eliminating them.
- Pinecone is a sponsor and one vector database option, not a requirement for RAG.
Den bearbeiteten Text nach Kapiteln lesen
What RAG adds
Berman contrasts external retrieval with fine-tuning and discusses limited context windows. He discloses Pinecone’s sponsorship.
I want to explain retrieval-augmented generation, or RAG, and why it helps applications use external information. Pinecone sponsors this video and is my exclusive channel partner; its vector database is one product used in the workflow I describe, not a prerequisite for RAG.
People often assume fine-tuning is the straightforward way to add documents to a model. I suggest retrieval is frequently a better fit for supplying changing information. My “nine out of ten” estimate is a personal rule of thumb, not a measured result; fine-tuning can do more than change tone and can also affect knowledge and task performance.
RAG retrieves relevant outside material and adds it to the context used to answer a question. It can give an application access to stored information or conversation history, although the model’s weights are not automatically updated and reliable long-term memory requires an actual storage and retrieval design.
A model cannot automatically know everything that happened after its training cutoff. You can put new information directly in a prompt, but sending a large collection repeatedly can be inefficient; retrieval is one way to choose a smaller set of relevant material.
The context window is a token budget for a model’s input and output, with exact limits and accounting depending on the model and interface. I cite roughly 8,000 tokens for the original Llama 3 and 128,000 for GPT-4o as examples from 2024, not current limits or limits for every variant.
Even when the window is large, repeatedly sending extensive context may incur cost and latency. Retrieval also has indexing and search costs, so whether it saves money or time depends on the workload and implementation.
Conversation history and company documents
He considers customer-service memory, private documents and recent financial reports. Retrieval selects passages to add to a prompt.
Imagine a customer-service assistant that needs to use previous conversations. Sending the entire history on every turn would eventually consume much of the available context, while only some previous exchanges may matter for the current question. A retrieval system can select relevant records, subject to privacy, retention and access controls.
The same issue arises with private company documents. A general model may not have been trained on them, and putting every document into every prompt is impractical at scale. An authorized retrieval layer can find relevant passages without sending the full collection each time.
Consider a new Tesla earnings report that postdates a model’s training information. The application can index the report, retrieve passages relevant to a question and include them with the question in the prompt. The document must actually be available and indexed; for a quarterly report, the relevant filing may be a 10-Q rather than the annual 10-K mentioned in the example.
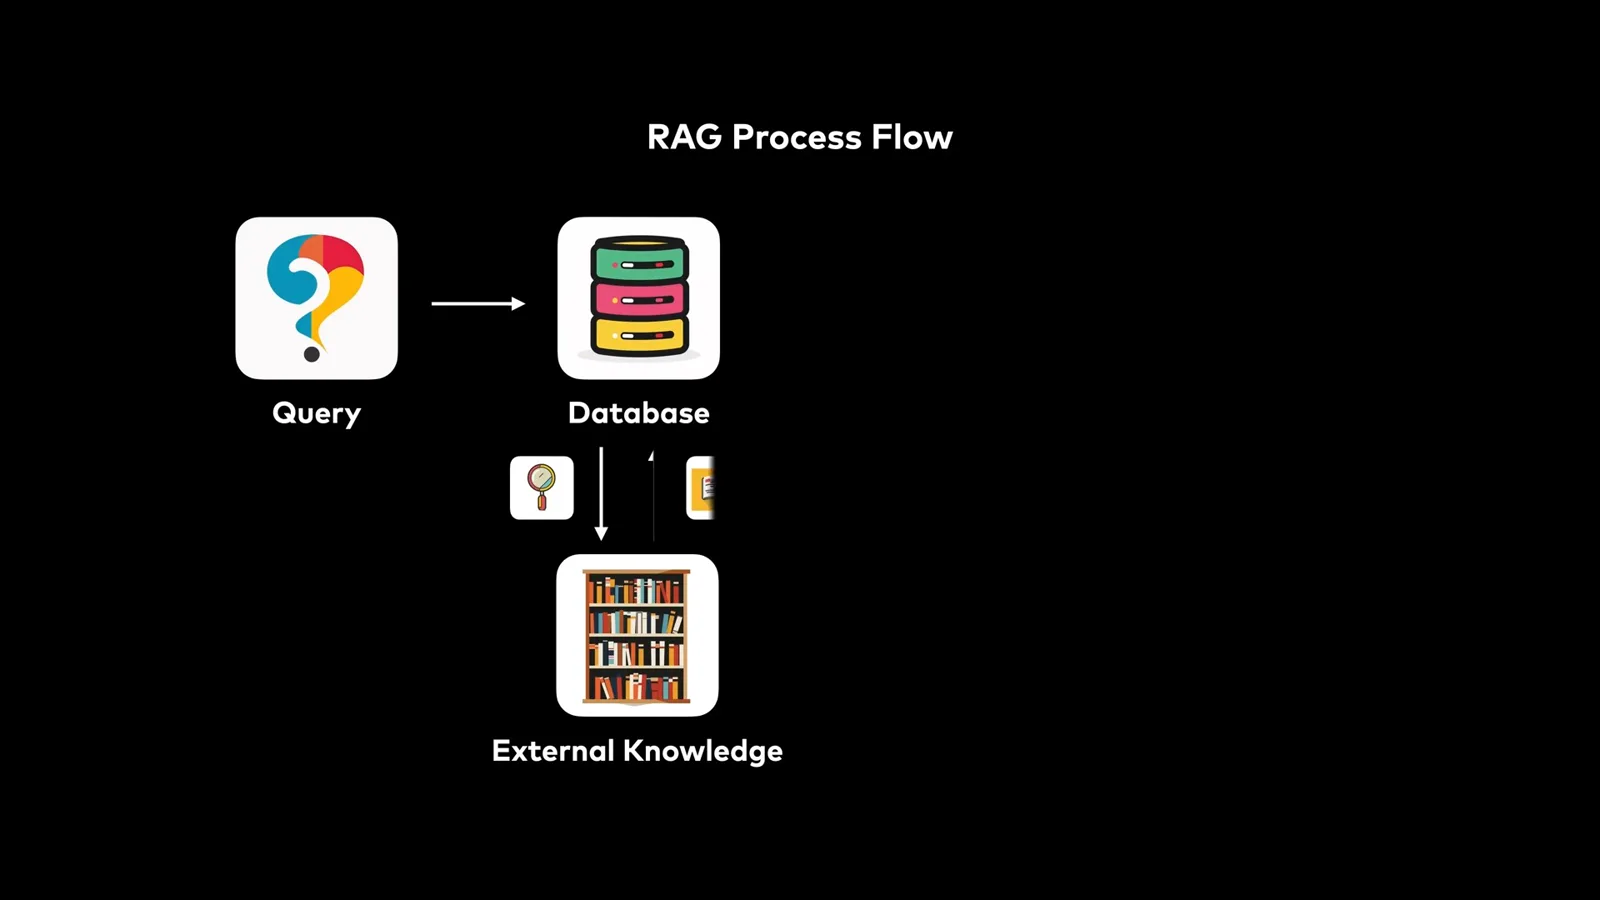
With reports from many companies, retrieval aims to select information about the company and period requested rather than repeatedly adding every filing. Retrieval quality and document freshness matter: the closest-looking passage is not always the right or most recent source.
From manuals to vector search
A vehicle-manual example illustrates indexing, embeddings and query-time retrieval. Grounding does not guarantee correctness.
I show Pinecone’s example of a question about a Volvo XC60 manual. The illustration contrasts an unsupported answer with one generated using retrieved documentation. An unsupported response may hallucinate, but it need not always do so; consult the manual for the exact vehicle and model year when dealing with a safety-related feature.
To prepare the illustrated system, documents are sent through an embedding model and stored with metadata in a vector database. In practical implementations, documents are often divided into passages, and the original text or a reference to it must remain available for inclusion in the prompt.
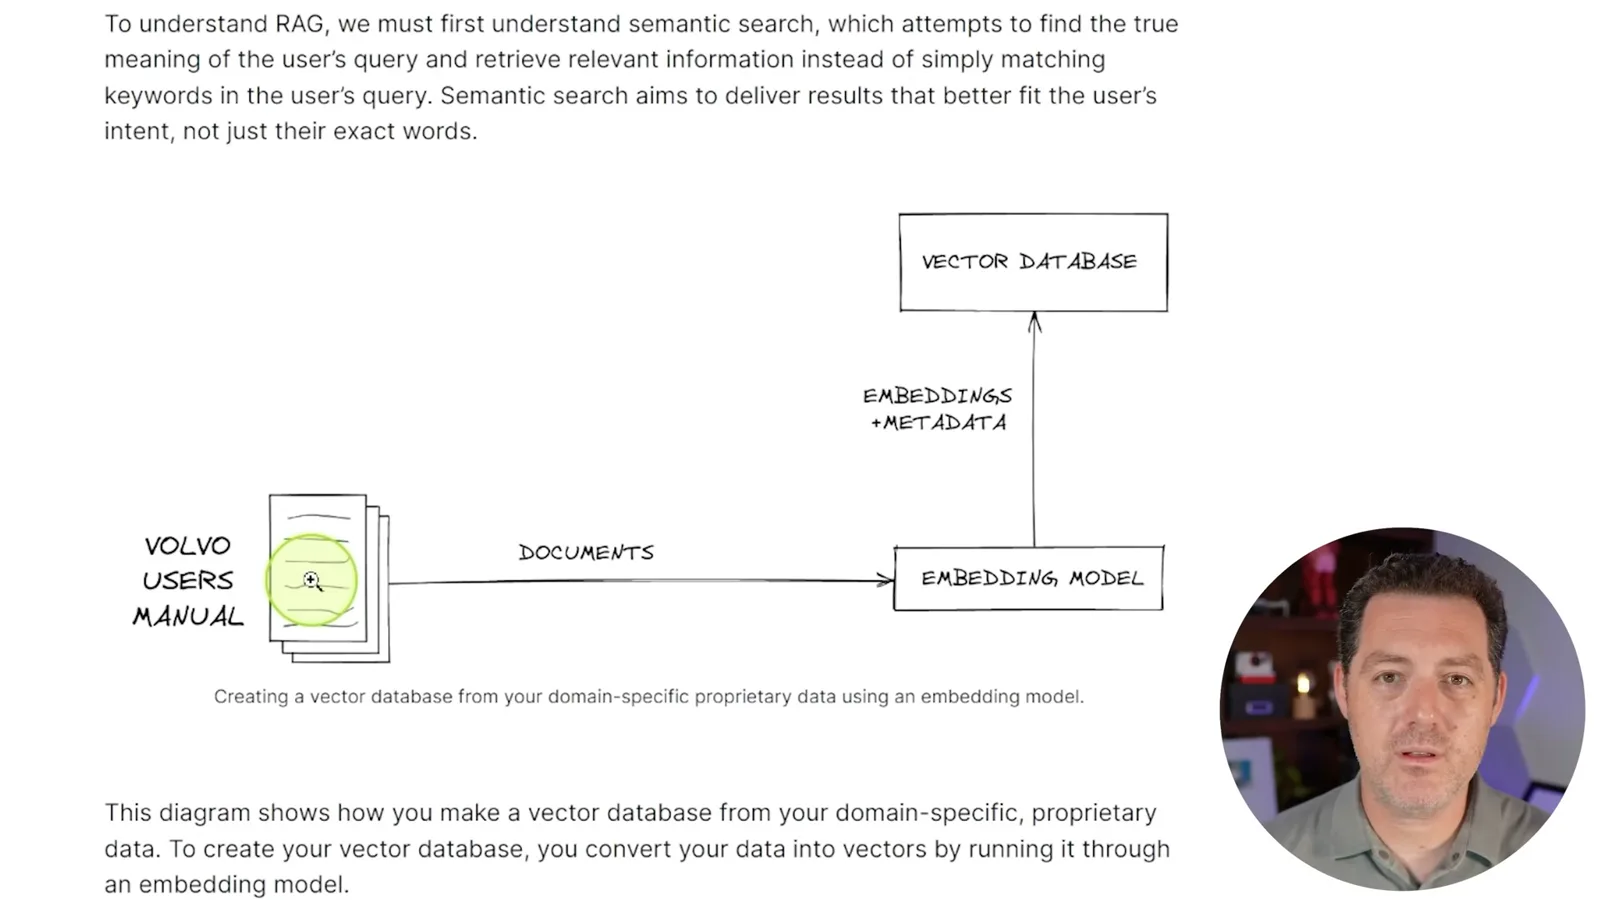
An embedding is a numerical vector representing text. The two-dimensional diagram is a simplification of a higher-dimensional space; an embedding model and similarity metric determine what counts as nearby, and closeness is an imperfect proxy for relevance or truth.
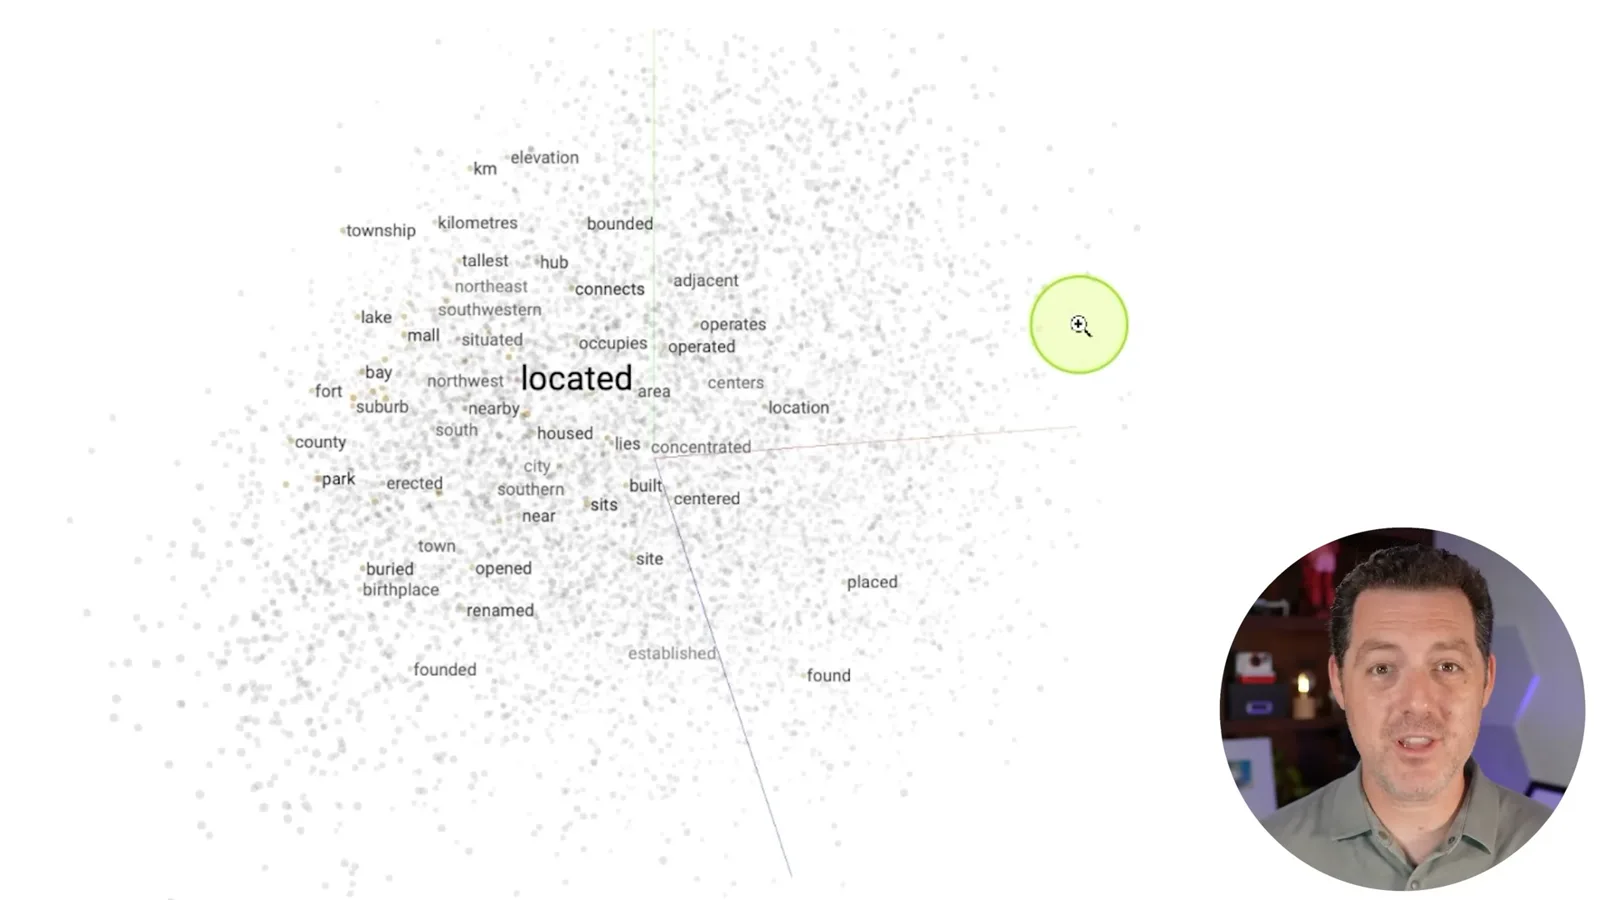
At query time, the system embeds the user’s question, searches for similar indexed passages and sends the selected context with the original question to the language model. The model can then use the passages to formulate an answer, though the retriever or generator can still make mistakes.
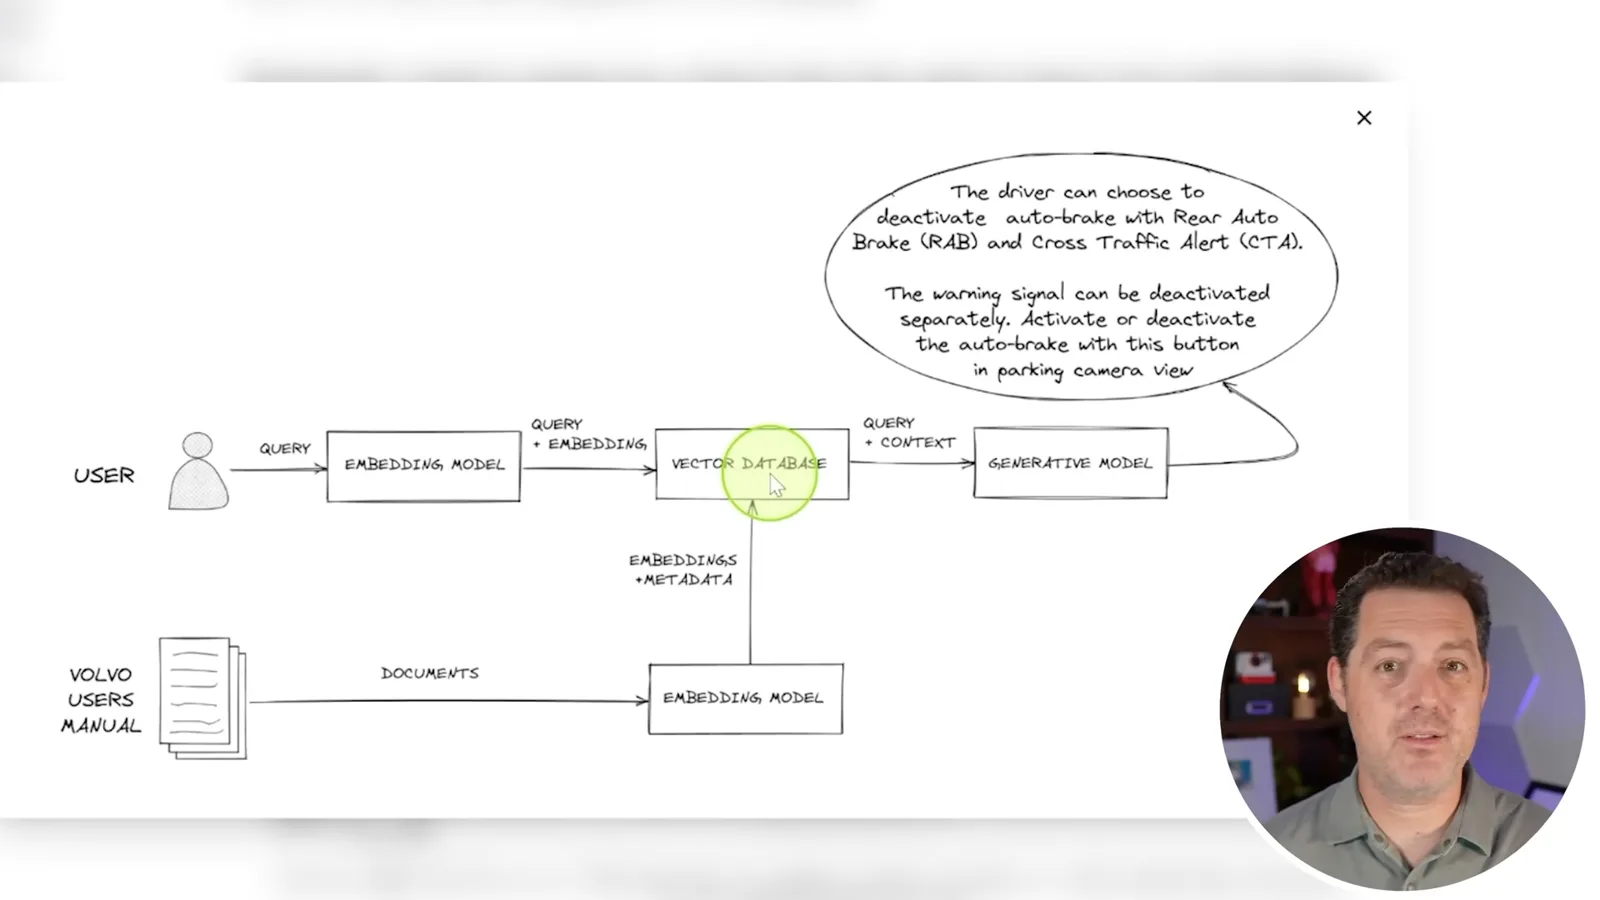
The manual example illustrates how grounding might reduce unsupported responses; it does not prove RAG eliminates hallucination or guarantees accurate instructions. Retrieved passages may be incomplete, misleading or outdated, and the model can misinterpret them.
Agents and implementation
A multi-step search example and a vector-database overview show how retrieval can support applications. The presenter highlights sponsor Pinecone.
I then show a multi-step example involving Apple Remote. A direct model answer in the illustration is iPod, while the search-based workflow looks up the remote, identifies Front Row and searches for another control method, arriving at keyboard function keys. The steps illustrate a particular example, not a guarantee of general agent reliability.
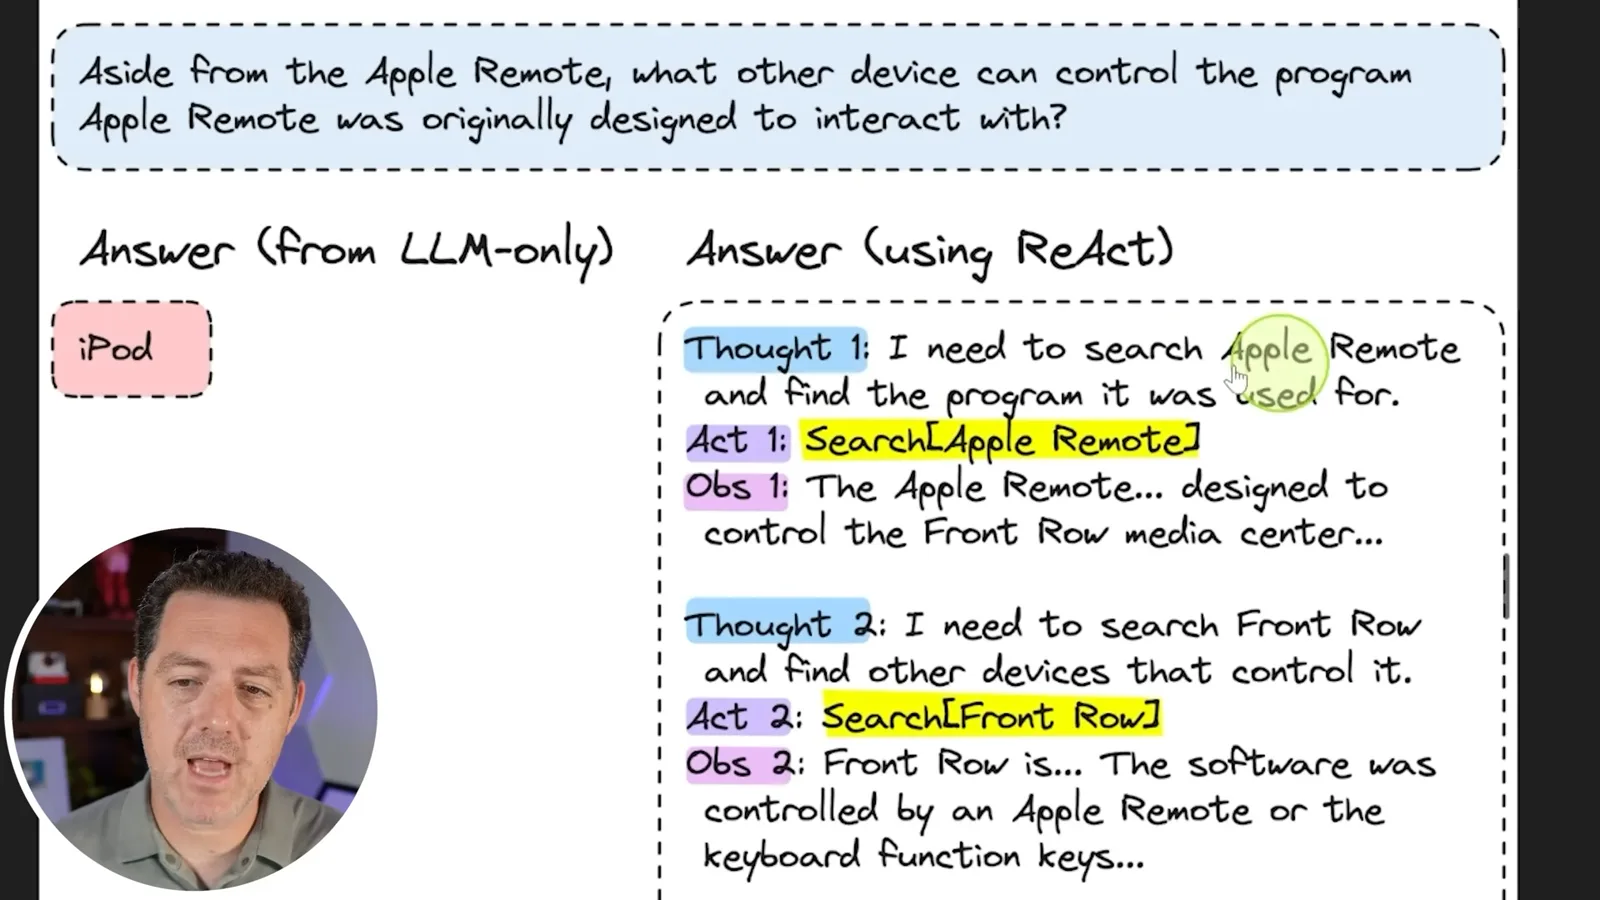
The reasoning and search steps can be organized in different ways, including one agent making multiple tool calls; each step need not be a separate agent. Such workflows can retrieve and combine sources iteratively, while still requiring verification of the result.
Pinecone stores and searches high-dimensional vectors at scale, and I describe it as fast. Those are sponsor-related product claims: actual latency, cost and capacity depend on configuration and workload. A vector database is one option rather than a requirement for RAG.
I compare vector similarity search with ordinary search. Many search systems use lexical matching, structured queries or hybrid methods as well as embeddings; proximity in vector space is not how all search works and does not itself guarantee relevance.
A basic implementation creates embeddings for documents, stores them with the relevant data, embeds a query and retrieves matching context. Pinecone offers one hosted implementation; teams still need to choose models, handle document updates and permissions, and evaluate retrieval and answers for their use case.
I close by offering to make a more detailed tutorial on preparing documents, embeddings and a Pinecone account, and thank Pinecone for sponsoring the video. The lesson is the retrieval-and-generation workflow, with its actual quality dependent on sources and evaluation.
Mehr aus diesem Kanal
 34:21EN
 Matthew Berman· 27. Okt. 2026Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 0:26ENMatthew Berman· 25. Okt. 2026Sam Altman on Human Values and Problem-Solving in an AI WorldSam Altman · OpenAIIn a short interview excerpt, Altman considers the enjoyment of solving hard problems and the human role in interpreting results.
 0:36ENMatthew Berman· 25. Okt. 2026Kimi K3.1 and a Rubik’s Cube Solver DemonstrationMatthew Berman · Forward FutureMatthew Berman shows a scrambled virtual cube being solved and gives the Kimi K3.1 test a favorable assessment.
 0:21ENMatthew Berman· 24. Okt. 2026An AI-Generated Kimi Benchmark Chart Used Invented ScoresMatthew Berman · Forward FutureMatthew Berman asks for a graph of Kimi K3.1 Pro benchmarks, then discovers that the displayed figures are illustrative placeholders.
 25:50ENMatthew Berman· 24. Okt. 2026Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.
 32:20ENMatthew Berman· 23. Okt. 2026Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.