In 30 Sekunden
After xAI released Grok-1 base weights in March 2024, Matthew Berman tested the hosted Grok service on X because he could not run the checkpoint locally. His informal prompts show successes and failures; the hosted product and search tools are distinct from a test of the raw base model.
- 1Hosted service versus base weightsBerman used Grok on X; xAI’s open release was an unfine-tuned base checkpoint.
- 2Snake game failsThe initial game and a proposed revision both failed during the demonstration.
- 3A misleading drying answerThe model’s 16-hour answer uses unjustified per-shirt reasoning; batch and parallel cases depend on capacity.
- 4A physical reasoning exampleThe model says the marble moves with an inverted cup, contrary to the usual interpretation of lifting the cup alone.
Das Wichtigste
- xAI released a 314B mixture-of-experts base checkpoint under Apache 2.0 in March 2024; it was not dialogue fine-tuned.
- The hosted Grok service on X was tested, not the released raw weights locally.
- The generated Snake game failed twice, while simple arithmetic and a JSON example worked.
- The shirt-drying and hole-digging problems require explicit assumptions; a coincidental number does not validate flawed reasoning.
- A few prompts do not establish overall model capability or safety.
Den bearbeiteten Text nach Kapiteln lesen
Grok-1 release and hosted coding tests
Berman explains the open weight release and tests the product on X. Simple code succeeds while the Snake game fails.
In March 2024 xAI released the weights and architecture of Grok-1, a 314-billion-parameter mixture-of-experts base model under Apache 2.0. The released checkpoint was not fine-tuned for dialogue. I could not run it locally, so I test the Grok service on X instead; that hosted product and its search tools are not a controlled test of the newly released raw checkpoint.
The X interface can surface recent information from the platform. My first coding prompt, printing the numbers one through 100, produces a correct Python loop. A request for Snake appears to use search and returns relevant posts with code, so the product's tool access is part of the observed result.
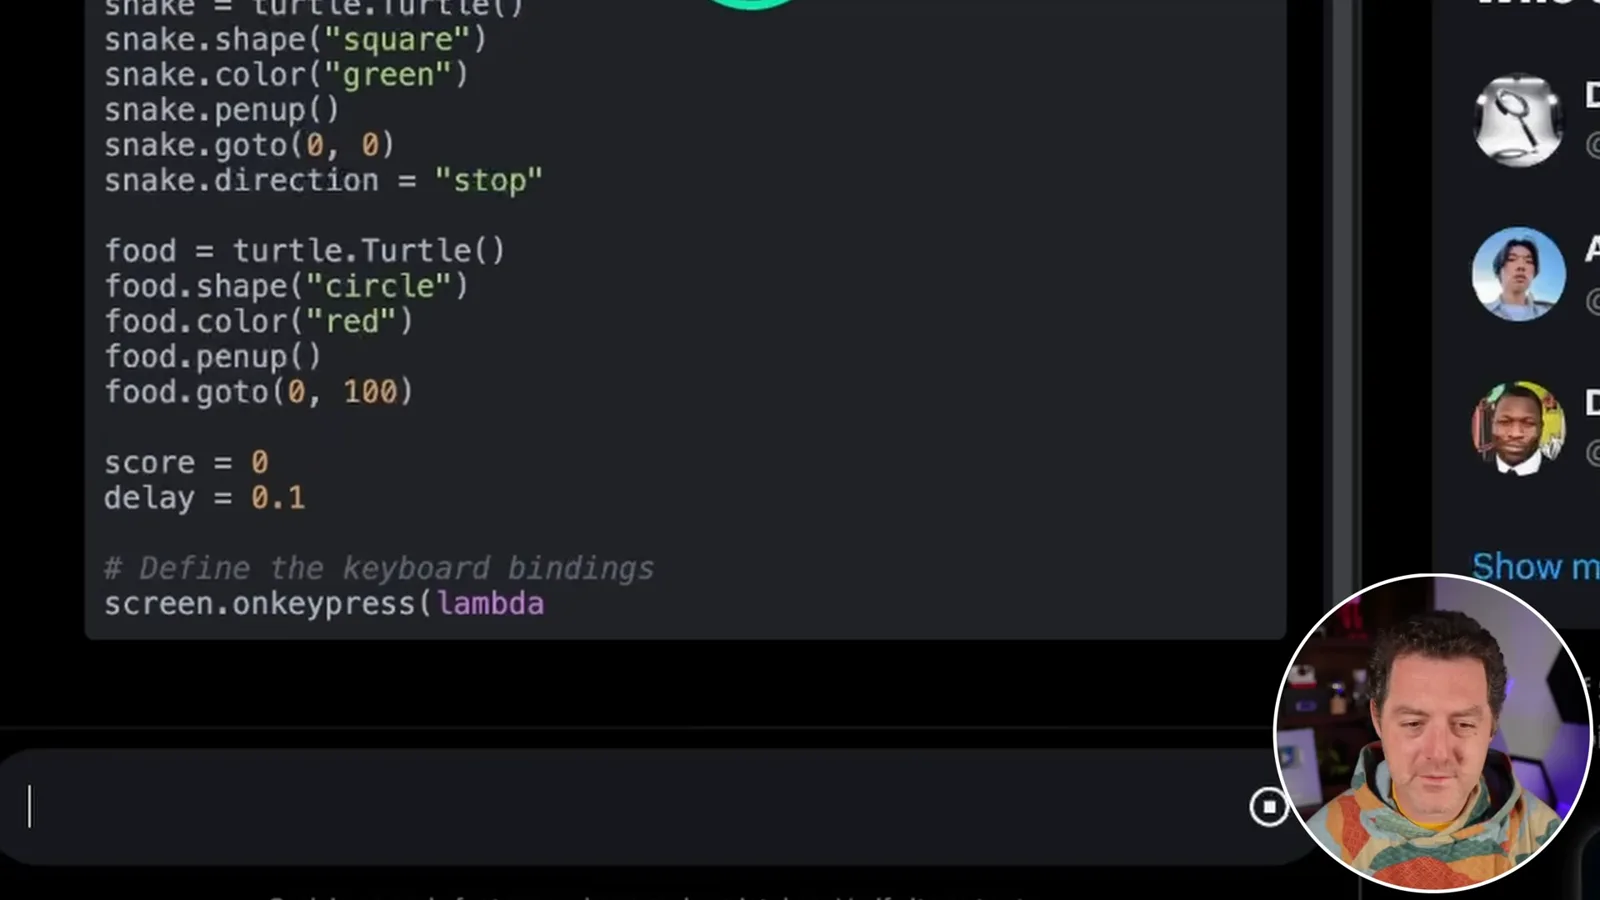
The generated Snake game starts but immediately crashes with a variable error. I paste the error back and try the revised code; it runs briefly and fails again with another error. I mark this as a failure for my no-manual-debugging test. It does not establish that the model could never produce a working game under other conditions.
Moderation and reasoning prompts
He probes the hosted interface with a harmful request, then tests arithmetic and logic. Several questions need explicit assumptions.
I also probe the hosted product with a potentially harmful request and observe that it responds rather than refusing. That single prompt cannot establish a general moderation policy or overall safety, and refusing harmful assistance would not itself be an ordinary task failure.
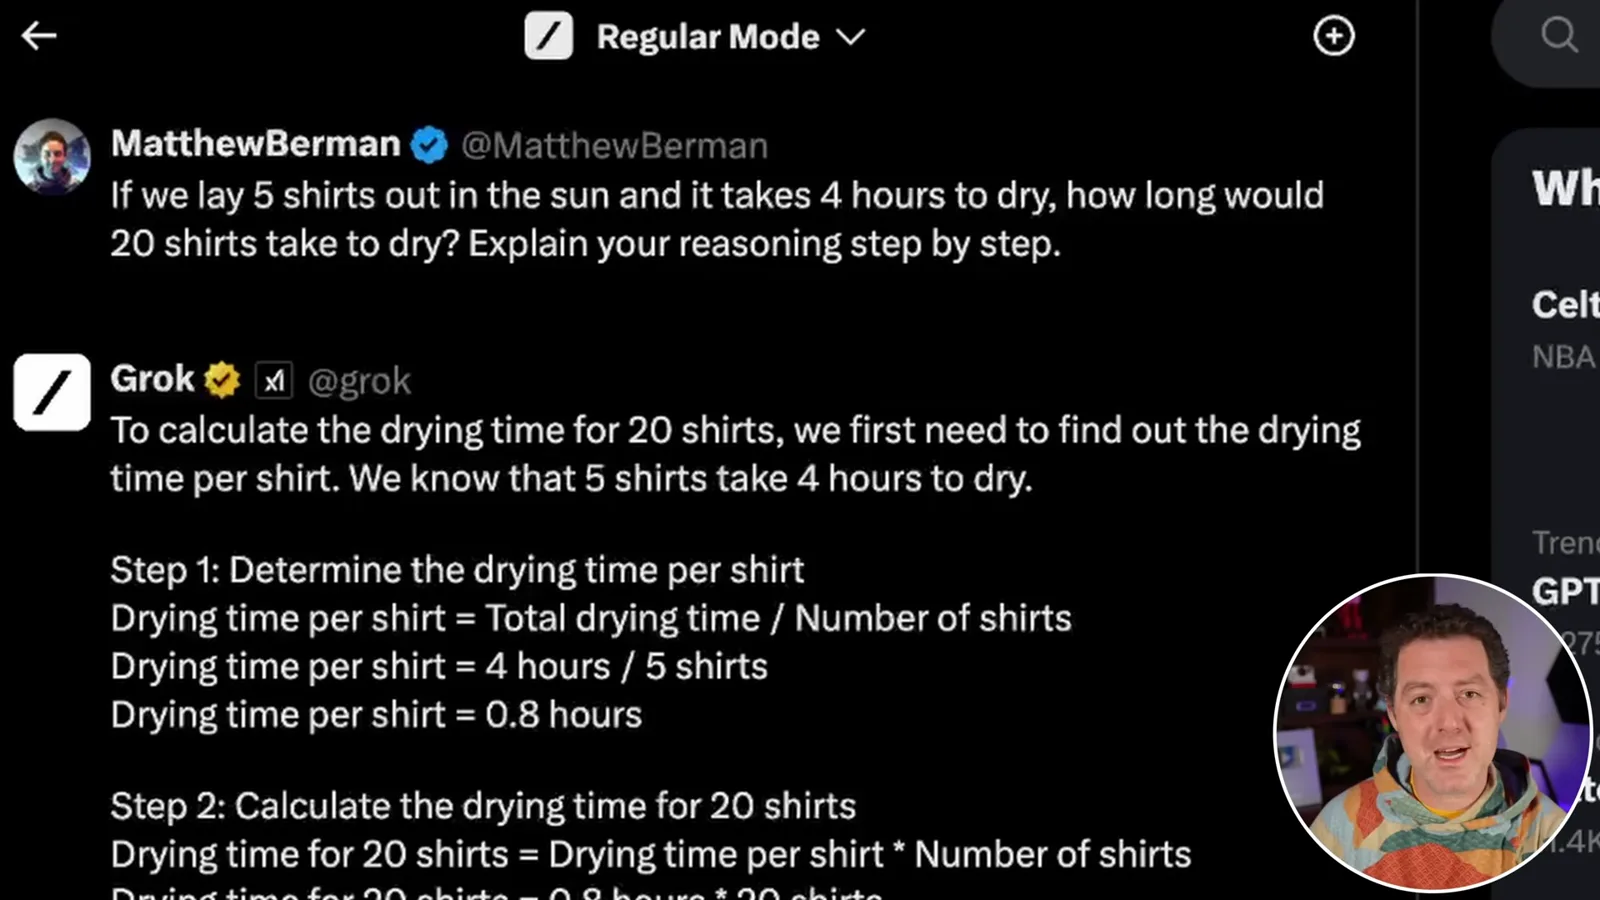
On the shirt-drying problem, Grok divides four hours by five shirts and multiplies by 20, producing 16 hours. I give it a pass in the video, but its per-shirt calculation is not justified by the question: simultaneous drying with sufficient space takes four hours, while four sequential batches of five take 16. The prompt does not specify capacity, so the answer requires an explicit assumption.
In the speed-order puzzle, the response says Jane is faster than Sam but begins with 'yes' even though I asked whether Sam is faster than Jane. I treat the explanation as a pass, but the direct yes/no answer conflicts with the stated ordering. Simple addition and the arithmetic expression 25 − 4 × 2 + 3 are answered correctly.
The model claims a self-referential reply contains 12 words; I count ten and mark it wrong. In the killers-in-a-room puzzle it counts two surviving original killers and the entrant, giving three. That is the intended answer if the question counts living people; including the deceased person would be a different interpretation.
Structured output and further puzzles
JSON, a marble puzzle, belief tracking and output constraints yield mixed results. Berman closes with his initial assessment.
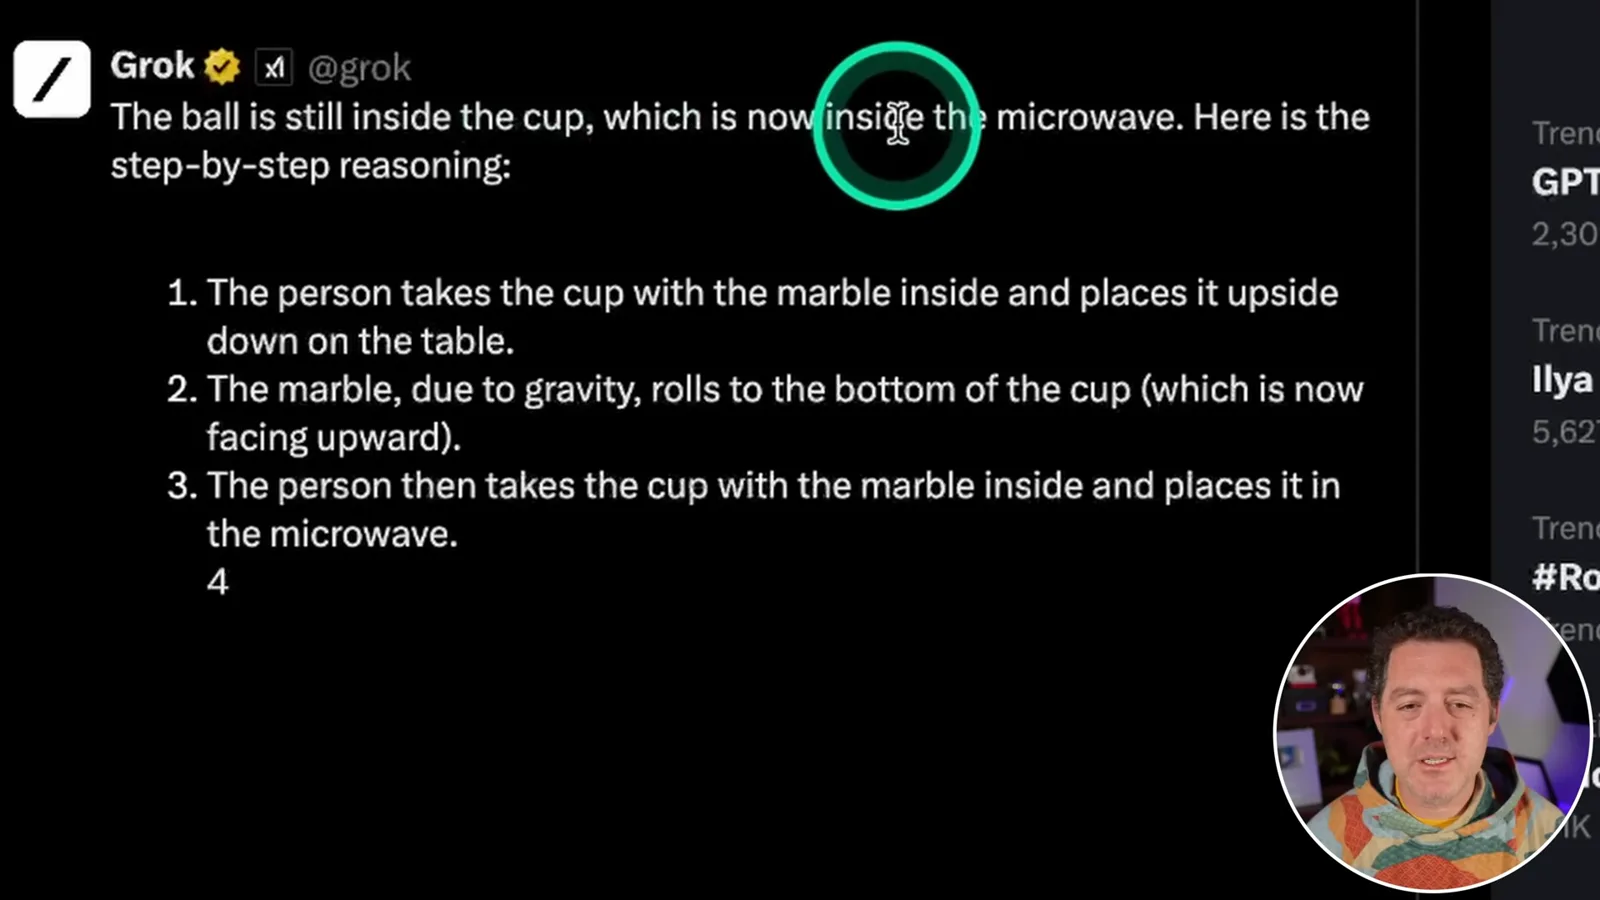
A structured-data prompt yields a JSON object for three described people. In the cup-and-marble puzzle, the model says the marble travels with the inverted cup into a microwave, even after I clarify that the cup stays inverted. Under the usual assumption that the cup alone is lifted from the table, the marble remains on the table; the wording and handling assumptions matter.
For a belief-tracking question, Grok says John thinks a ball is in the box and Mark thinks it is in the basket, matching where each last left it and what each knows. A request for ten sentences ending in 'Apple' fails after the first sentence, illustrating that an apparently simple output constraint can be missed.
Finally, the model estimates that five people could dig a hole in one hour if they work simultaneously at a constant combined rate. I accept the answer with that assumption, while noting real work may not scale linearly. Overall I find the session promising, but the mixed results come from a few prompts in a search-enabled hosted interface and do not establish a general ranking or the raw checkpoint's behavior.
Mehr aus diesem Kanal
 34:21EN
 Matthew Berman· 27. Okt. 2026Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 0:36ENMatthew Berman· 25. Okt. 2026Kimi K3.1 and a Rubik’s Cube Solver DemonstrationMatthew Berman · Forward FutureMatthew Berman shows a scrambled virtual cube being solved and gives the Kimi K3.1 test a favorable assessment.
 25:50ENMatthew Berman· 24. Okt. 2026Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.
 32:20ENMatthew Berman· 23. Okt. 2026Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.
 1:03:37ENMatthew Berman· 23. Okt. 2026Matthew Berman’s Team Tests Kimi K3.1 on Animation, Games, and ChartsMatthew Berman, Alex, Brian · Forward FutureA live team AMA turns into an informal test of Kimi K3.1, from personal-agent workflows to motion graphics, a browser game, and a benchmark chart.
 0:53ENMatthew Berman· 22. Okt. 2026Sam Altman on AI and the Discovery of New KnowledgeSam Altman · OpenAIAltman expects progress in mathematical discovery to extend to biology, materials and energy.