In 30 Sekunden
Theo Browne reviews Kimi K3 using launch materials, third-party evaluations and his own experiments. He finds strong coding and visual capabilities alongside usability, infrastructure and security concerns. Prices, availability and the planned weights release reflect the July 2026 recording.
- 1A large model with visionMoonshot announced 2.8 trillion parameters and a one-million-token context, subject to access limits.
- 2Benchmarks vary by taskK3 approaches leading proprietary models on some displayed coding evaluations but trails them on others.
- 3Long runs meet practical limitsTheo’s migration reached a context limit despite considerable progress.
- 4Visual iteration in a 3D gameA playable Fish Slap prototype emerged while the agent was still working.
- 5Security is dual-useA defensive audit impressed Theo, who also raises concerns about malicious applications and missing launch-era safety details.
- 6Access and costs changeThe video’s prices, subscription limits and planned weight release are historical snapshots.
Das Wichtigste
- K3 showed strong results on selected coding and visual tasks, though benchmark outcomes vary by test.
- A very large open-weight model can require substantial hardware even when its computation is sparse.
- Context limits, harness behavior and clear final reports matter in long agent workflows.
- The same security capabilities can support defense or misuse, and model-generated findings still need verification.
- API prices, provider terms and subscription limits should be checked at the time of use.
Den bearbeiteten Text nach Kapiteln lesen
K3 arrives
Theo introduces his impressions and the questions he wants to test.
Kimi K3 looks like a substantial jump for open-weight models. I had found earlier open models far behind the best proprietary systems on complex coding and long agent runs. After spending a day pushing K3, I think it can approach the frontier on some tasks, though it has rough edges.
Benchmarks are only part of the picture, so I tried real projects as well: a long migration, UI redesigns, a 3D game and a security audit. I also want to discuss the cost, availability and security implications of eventually releasing a model this capable.
Scale, benchmarks and pricing
Moonshot’s launch details and task-level benchmarks frame the size and cost trade-offs.
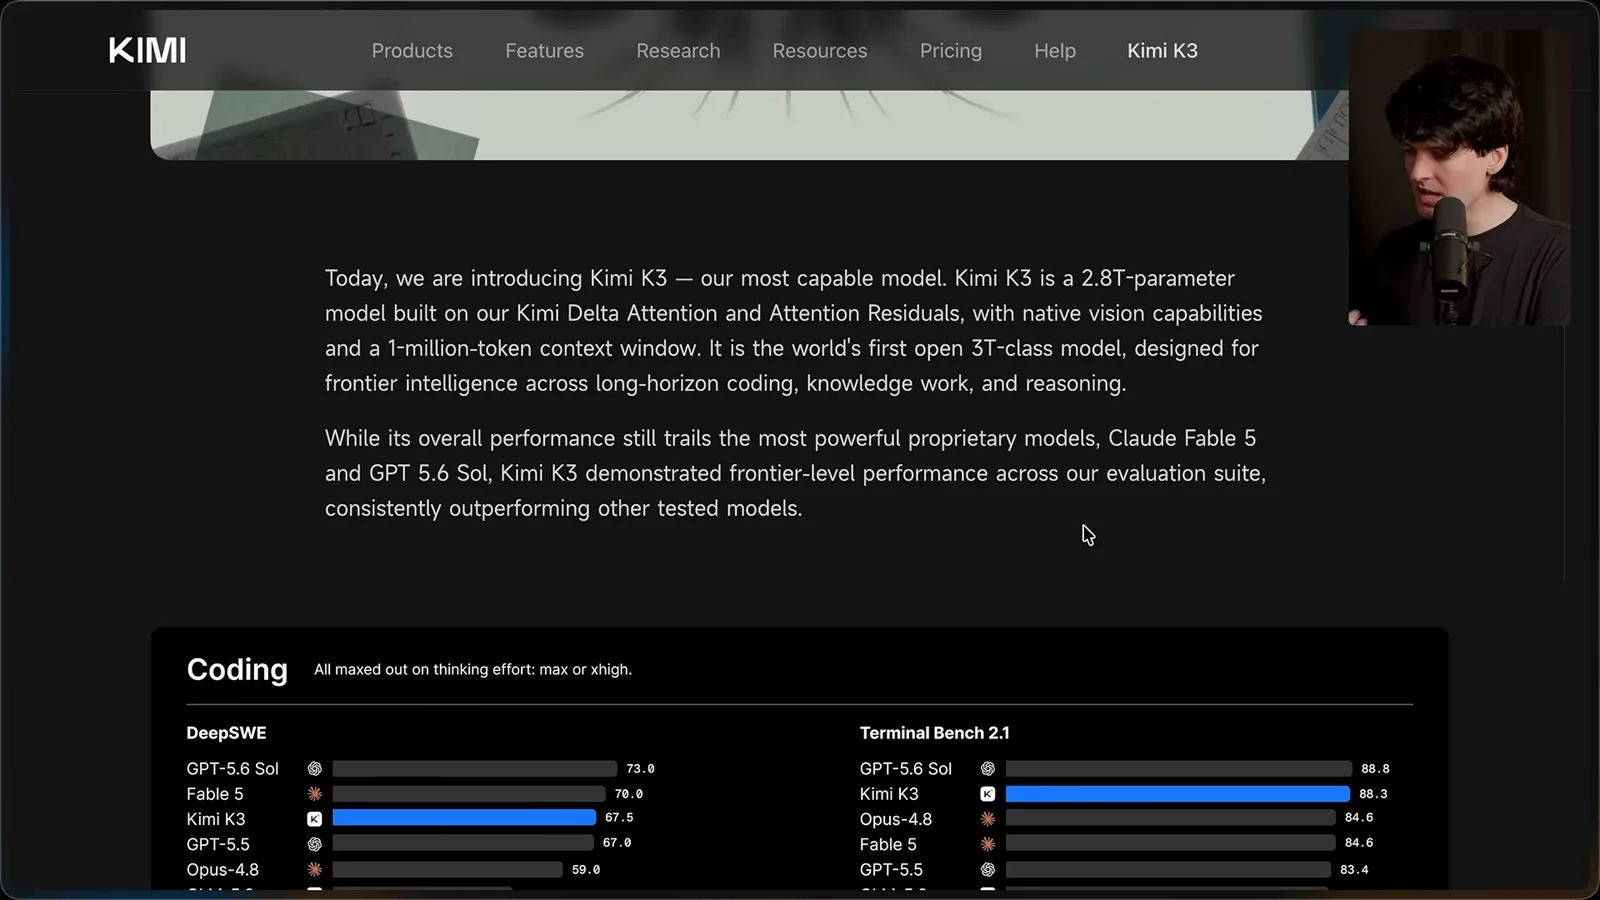
Moonshot describes K3 as a 2.8-trillion-parameter model with native vision and a one-million-token context window. Both are useful additions, but the full window was not available through every subscription configuration I tried. These are launch-era details and availability can change.
The model's size makes local hosting a very different proposition from downloading a small model. Even at four bits per parameter, the weights alone are roughly 1.4 TB before overhead. At the time of the video Moonshot planned to release the weights on July 27; they were not yet available.
Until weights and alternative deployments are available, using a hosted API means sending data to the provider. Decide whether that is appropriate for your code and data based on the provider's actual terms, retention policy and security controls.
Moonshot's launch charts put K3 at 67.5 on DeepSWE, behind GPT-5.6 Sol at 73 and Fable 5 at 70. On FrontierSWE, the displayed score places K3 between Fable and Sol. These are benchmark results under specific conditions, not a guarantee about every repository.
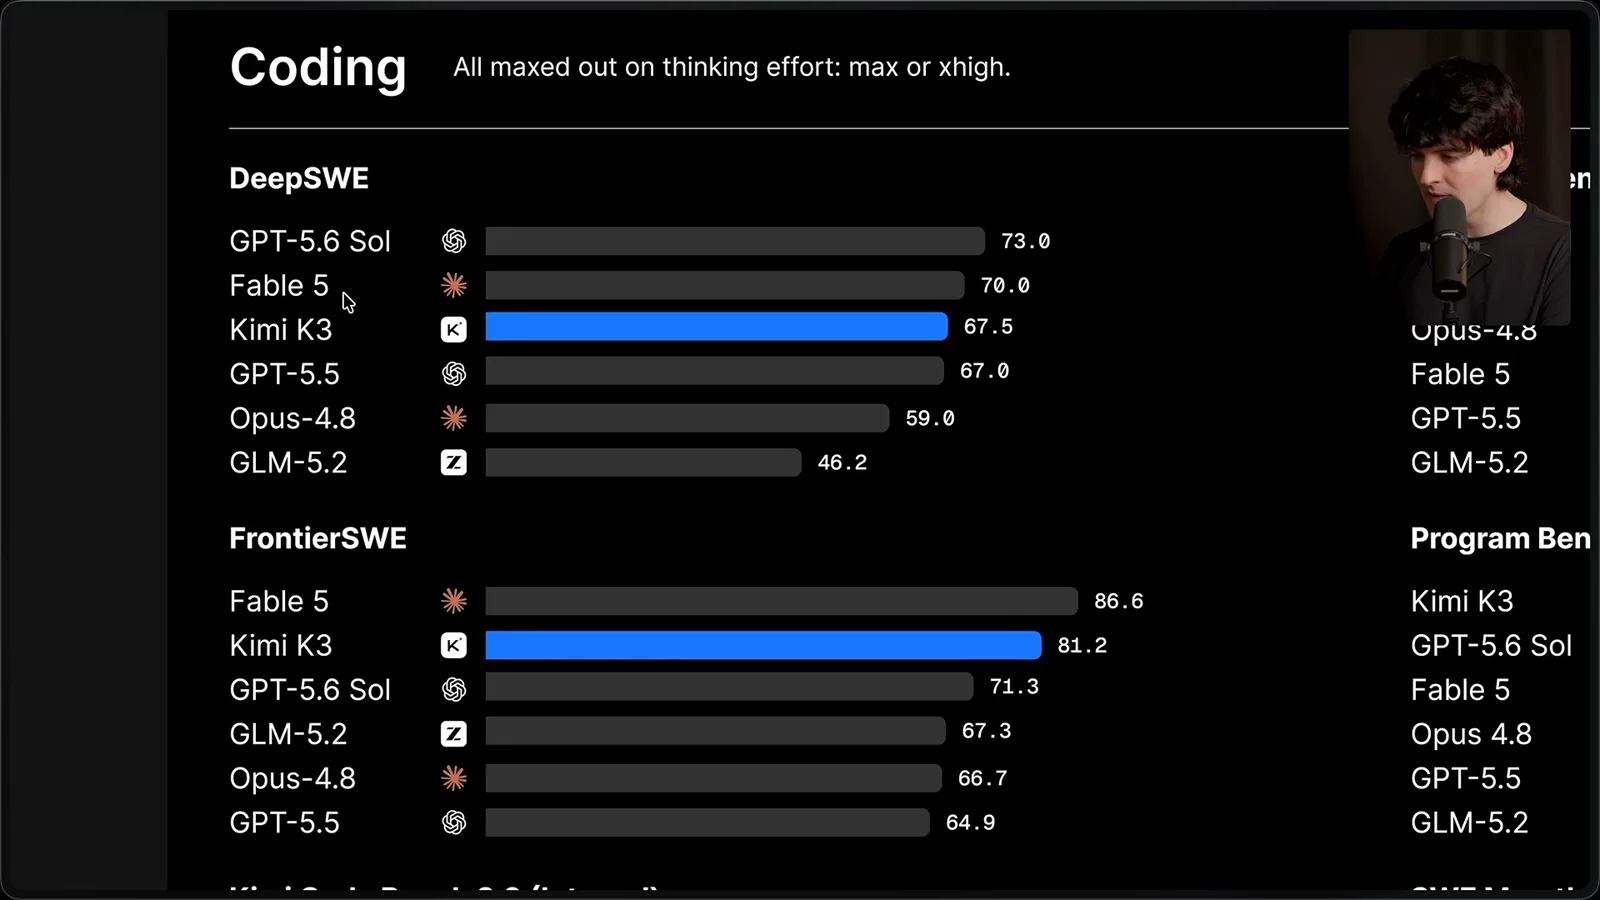
I like FrontierSWE because it tries to capture whether a change is suitable to merge, not just whether it solves the immediate problem. K3's result suggests better-looking, more reviewable code, although I would not assume the numerical gap will transfer directly to my projects.
The release also shows strong results on Terminal Bench, Program Bench and SWE Marathon, plus agent and spreadsheet evaluations. I am especially interested in BrowseComp: good browser and computer use could eventually be useful in a private deployment, if the necessary hardware is affordable.
Moonshot's BrowseComp chart compares score with cost per task and puts K3 near Sol on cost. Token prices alone are not the whole story: the number of tokens a model uses to finish a task also determines the bill and elapsed time.
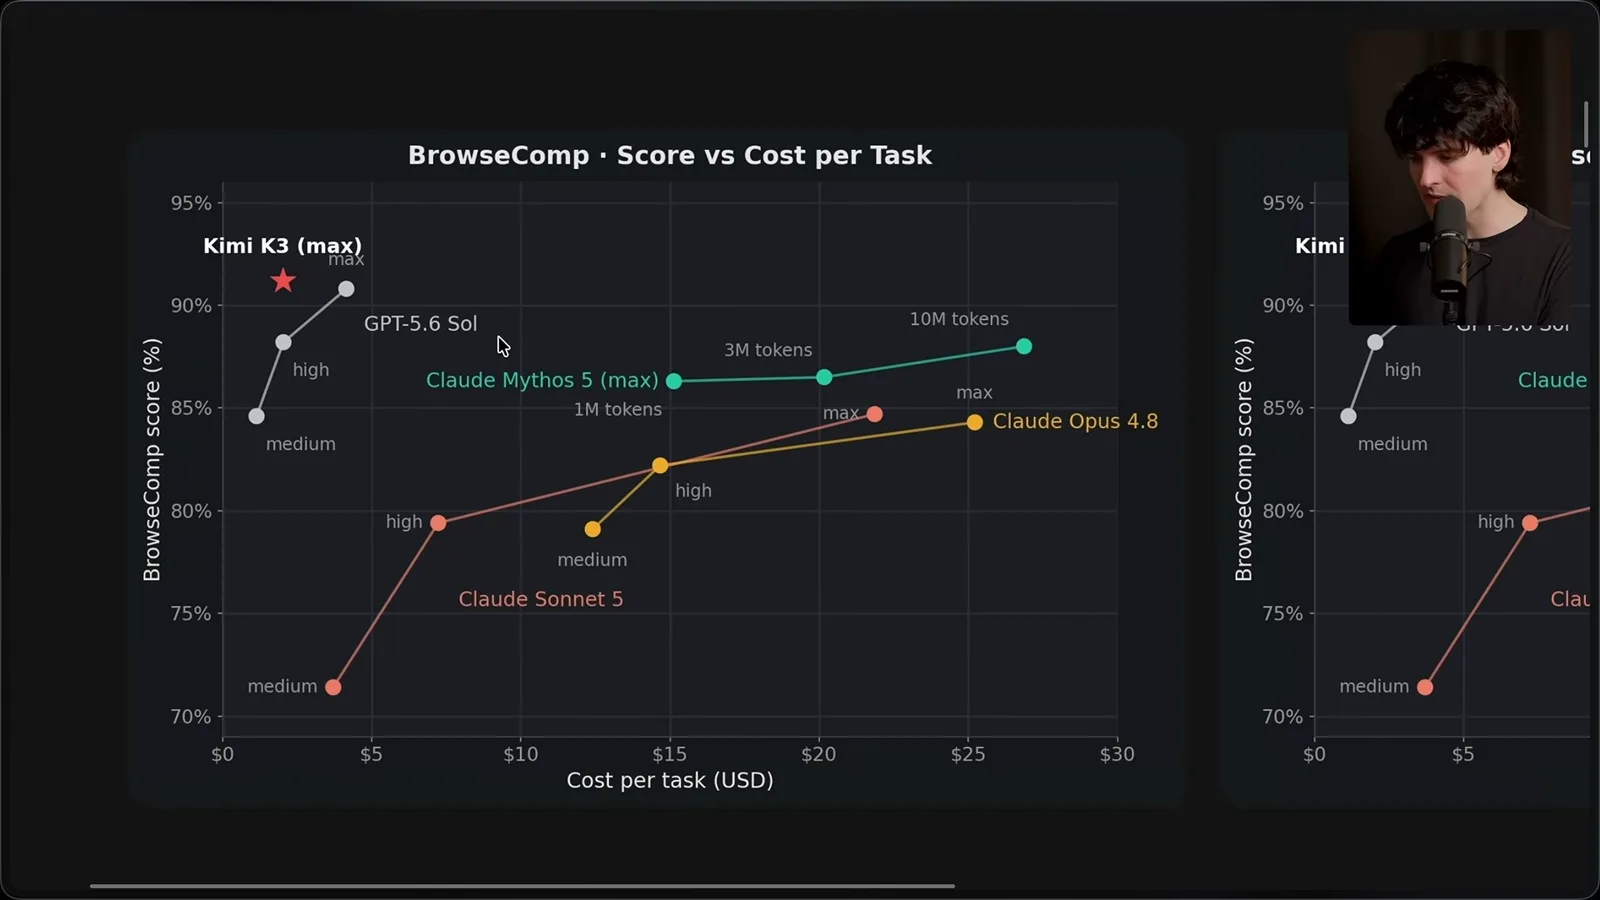
At launch I cite API prices of $0.30 per million cached input tokens, $3 per million input and $15 per million output. Those numbers and competitors' discounts are a July 2026 snapshot, not current pricing advice; compare actual usage and current terms before purchasing.
K3 launched using maximum reasoning effort by default, with lower modes planned later. Moonshot was also coordinating with inference providers and maintainers; a model with unusual architecture is not necessarily trivial for every provider to serve correctly.
Architecture and long coding runs
A sparse architecture and Theo’s migration experiment show both capability and practical limits.
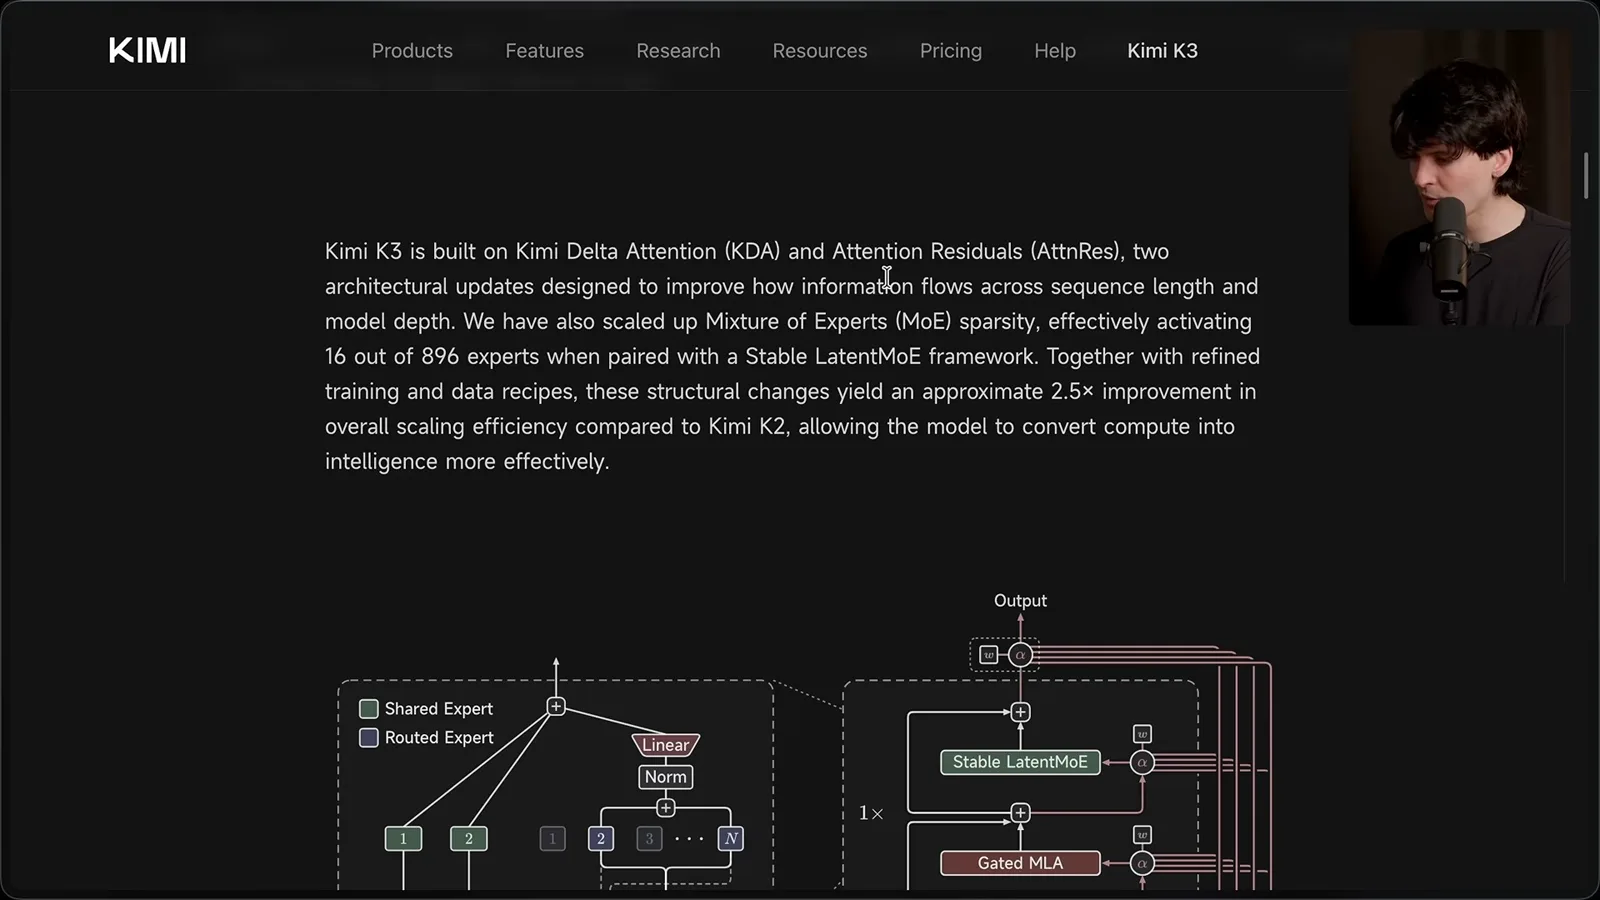
The architecture combines Kimi Delta Attention, Attention Residuals and a sparse mixture of experts. Moonshot says 16 of 896 experts are effectively activated and claims roughly 2.5 times better overall scaling efficiency than K2. Sparse computation does not remove the substantial memory requirement.
For a long-horizon test I asked K3 to port my old ping.gg codebase. After more than three hours it had worked through 122 tasks from a short prompt, but then hit a context limit. The work was still in progress, so this is not evidence that the migration was complete.
The limit was partly my mistake: the subscription and Claude Code setup did not expose the full advertised context. I planned to compact the conversation with another model and continue. Long-running work depends on the harness and its limits as well as the underlying model.
Visual work and infrastructure
Kernel optimization claims, a 3D game and hardware requirements widen the discussion.
K3's visual abilities make it promising for interface work. Moonshot also presents GPU kernel optimization tests in which K3 performs strongly after long runs. These are the company's demonstrations; the results need to be read in the context of the particular tasks and comparison settings.
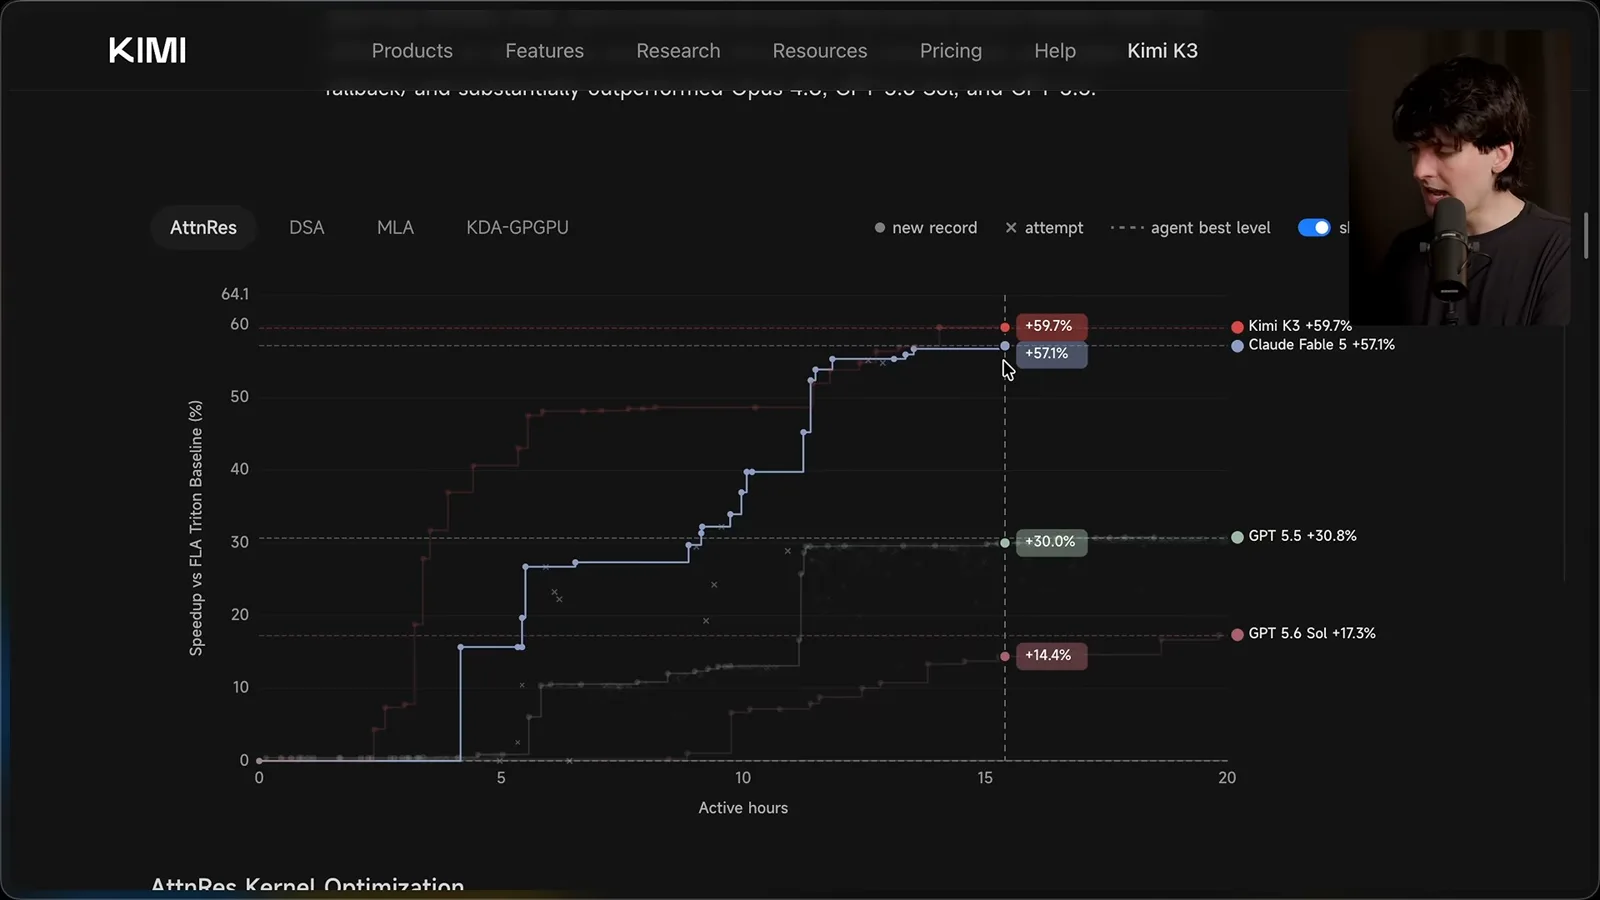
The company says an early version handled much of its kernel optimization work and describes a compact Triton-like compiler. I am interested in the breadth of these demonstrations, although I cannot personally verify all the technical details from a launch page.
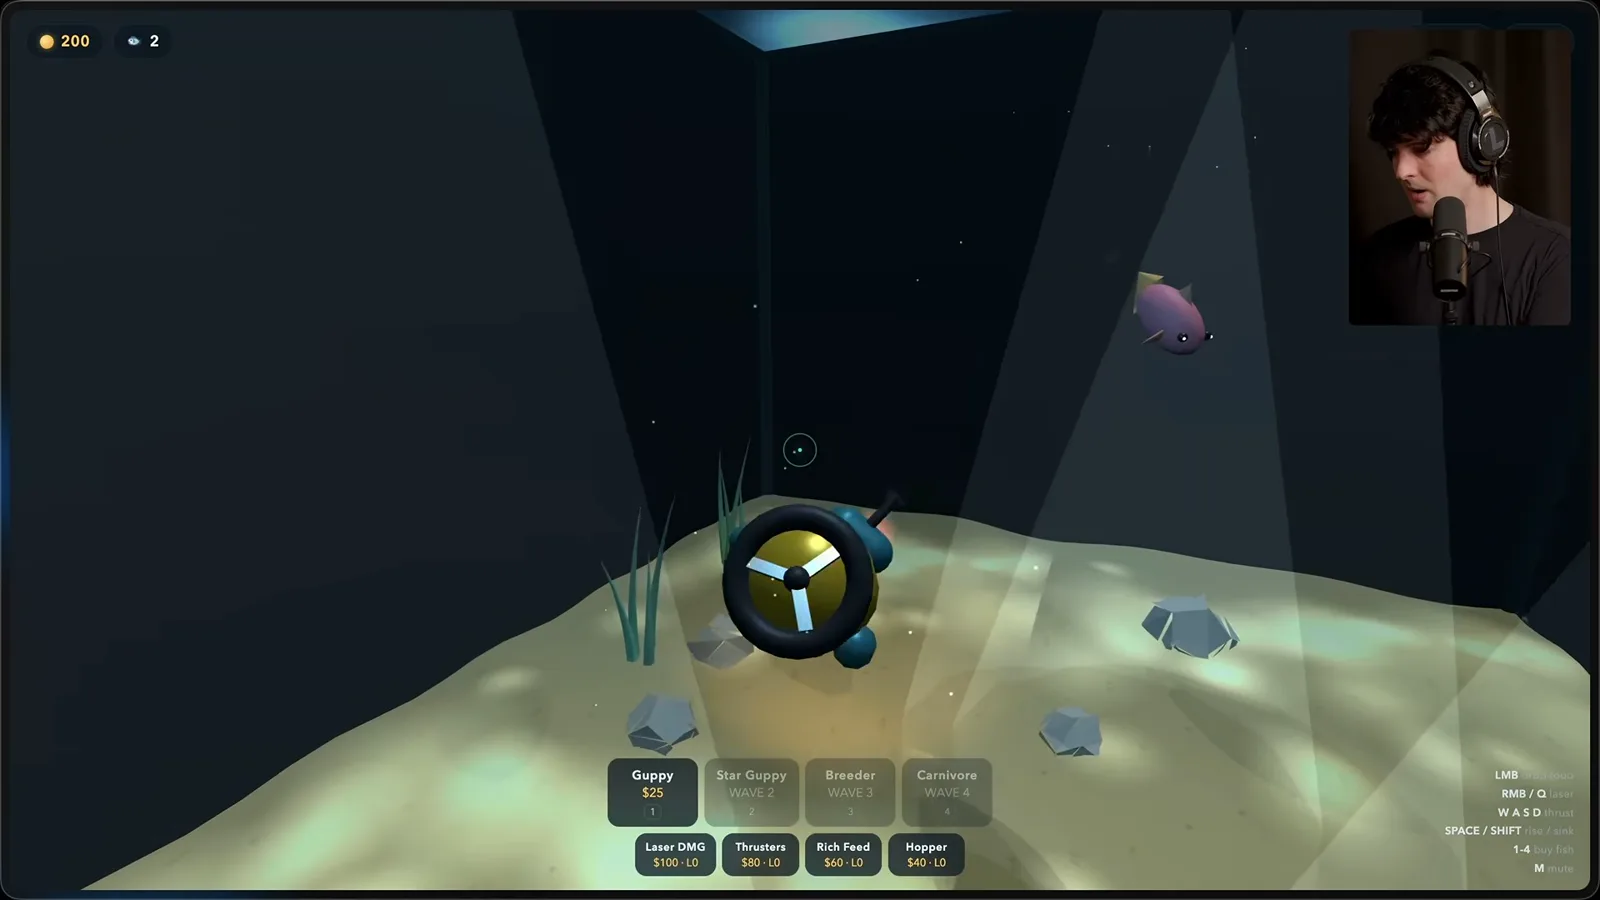
For games and digital creation, K3 can reportedly iterate between code and screenshots. I observed a similar loop in my own T3 Code work: it ran the application, inspected a screenshot and adjusted what it was doing.
I asked it to make a 3D version of Fish Slap. When I checked in, the game was already playable and included fish, a submarine and sound effects, although the models and game still had issues. The agent was continuing to inspect and improve the result.
Moonshot also shows chip design, research reports, infographics, dashboards and video-editing examples. The dashboards have a recognizable AI-generated style, but I like some of the animation. I have not personally tested the video-editing claims.
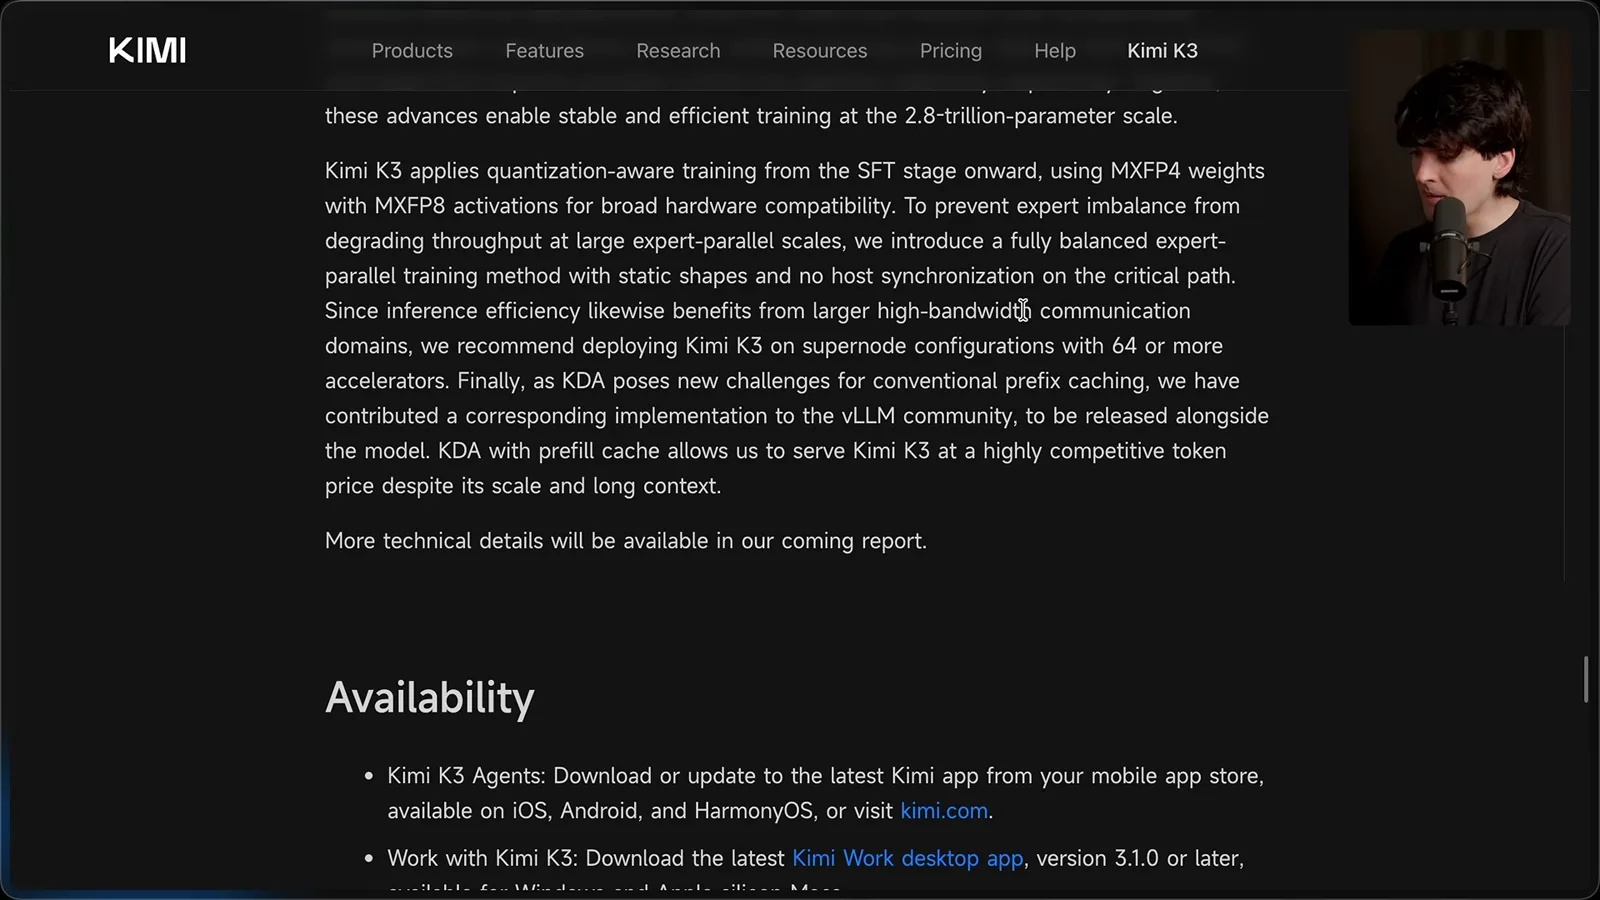
The launch page discusses MXFP4 weights and MXFP8 activations and recommends supernode configurations with at least 64 accelerators for efficient inference. The point is not that everyone needs precisely that setup, but that running a model of this size remains infrastructure-intensive.
Independent evaluations and usability
Theo examines Artificial Analysis results and problems in everyday interaction.
Artificial Analysis reported an Intelligence Index score of 57, comparable to Opus 4.8 and GPT-5.5 but behind Fable 5 and Sol in its evaluation. I correct myself in the video about Grok's placement. A leaderboard is a snapshot of particular evaluations, not a permanent ordering.
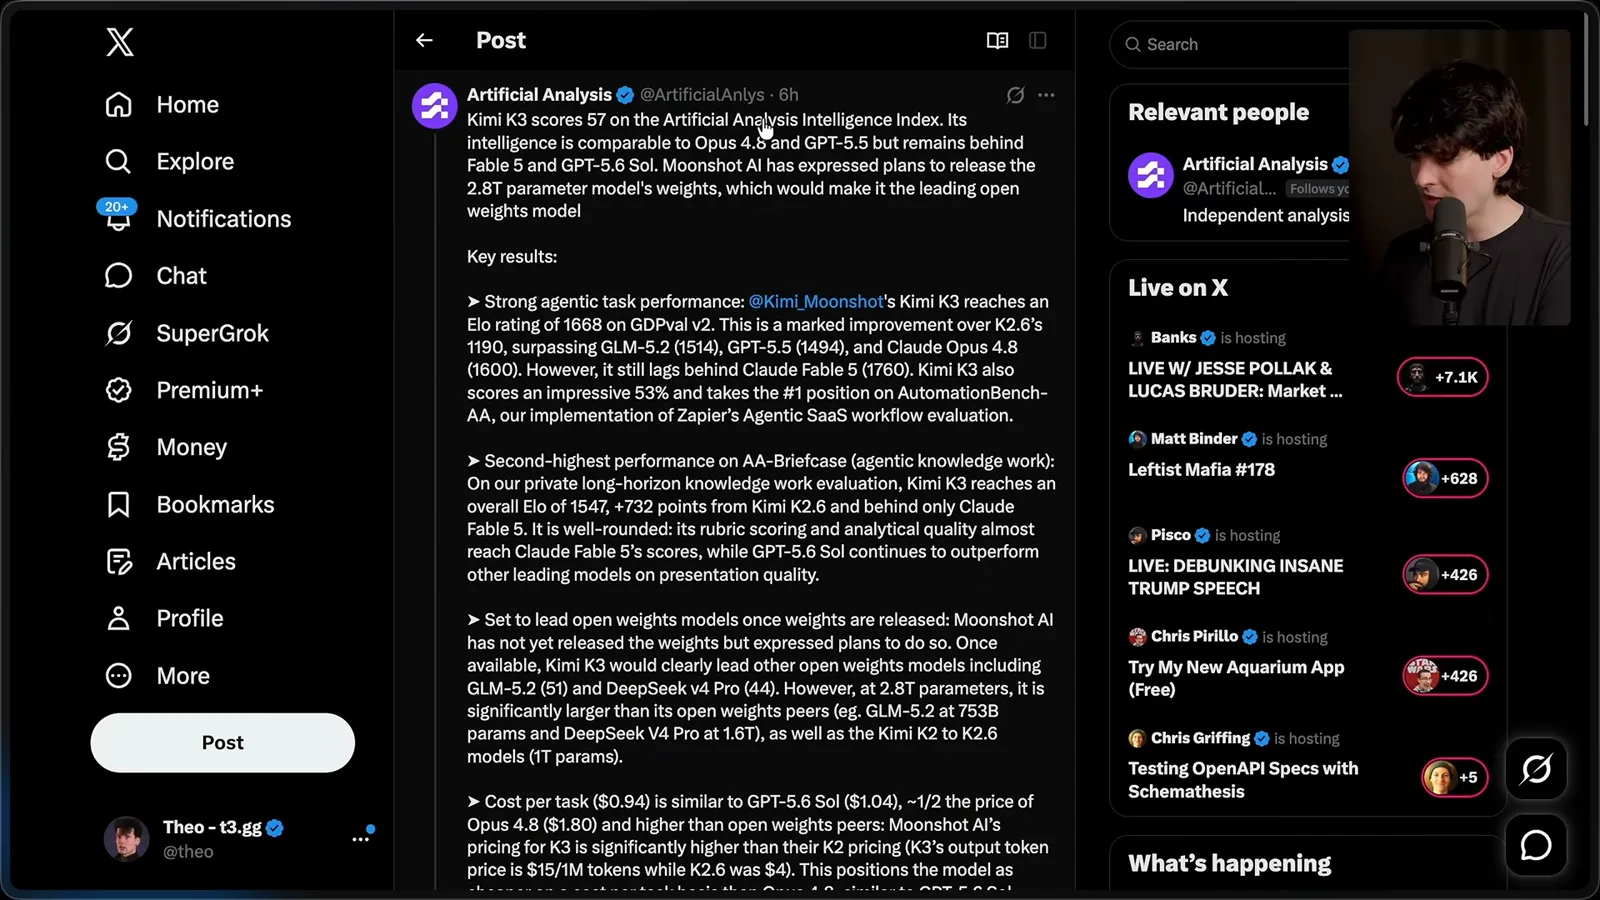
The same analysis highlights strong agentic and knowledge-work results and estimates cost per task close to Sol for its test. It also shows that K3 uses more output tokens per task than Sol, even if it uses fewer than some other models. Cost and token efficiency need to be considered together.
The Omniscience evaluation rewards admitting uncertainty and penalizes wrong answers. K3 scores well among the open-weight models shown, which I find encouraging. A score on one hallucination benchmark does not mean that any particular answer is safe to accept without checking.
There is still a user-experience gap. Sometimes K3 reacts to a sub-agent's status message instead of explaining the finished work to me. Moonshot itself notes issues such as over-proactivity and sensitivity to the thinking history; these matter when you work with a model all day.
Frontend and security experiments
Marketing pages, a sidebar redesign and a defensive audit provide real-world examples.
For a frontend test I asked for five alternative T3 Code marketing pages. One had attractive animations but an empty space in its cycling header; another leaned heavily on a familiar terminal aesthetic. Several ideas were usable, even if I would not ship them unchanged.
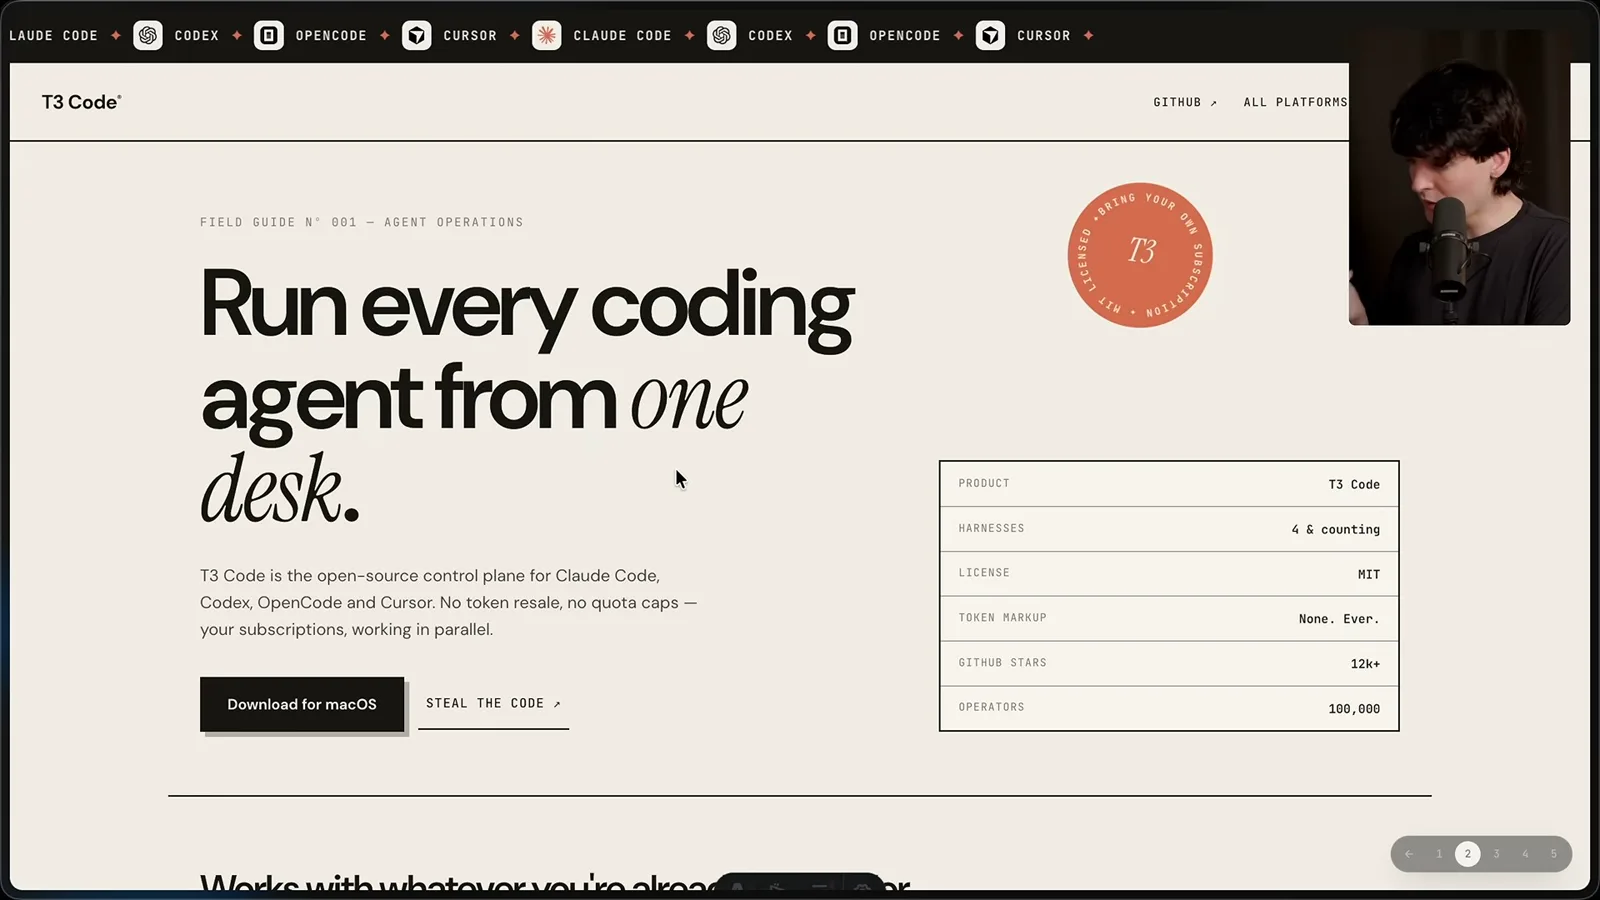
The fourth used a more restrained glow and the fifth a Bento-box layout. My subjective first impression was that these were slightly better than what I had received from OpenAI models for this task, though behind what I would expect from Claude. A single marketing-page test is a narrow sample.
A more practical test was the T3 Code sidebar. I wanted a darker, black-and-white direction and provided a screenshot as reference. K3's redesign looked better to me than the existing version, making the task more compelling than a generic landing-page demo.
I ran the task through OpenCode inside T3 Code. The agent spent about an hour and five minutes on it, with one correction from me: repeatedly opening the browser consumed a one-time connection token. After I clarified that constraint, it could inspect and refine its work.
The agent also reported a cleanup mistake affecting other development servers and said it had restarted them. I appreciated that it disclosed the mistake. Its report still needs verification: a model saying it repaired something is not the same as independently confirming it.
I then asked it to configure an isolated build with enough history to test the interface, and to open a pull request with before-and-after images. It found the relevant workflow, dealt with browser difficulties and assembled the PR in the same thread.
For a different kind of test, I asked for a defensive security audit of my own Lakebed project. The model delegated discovery and verification, including 25 verification agents, and produced recommendations after compaction. I found the feedback useful, but an agent audit is not proof that a system is secure.
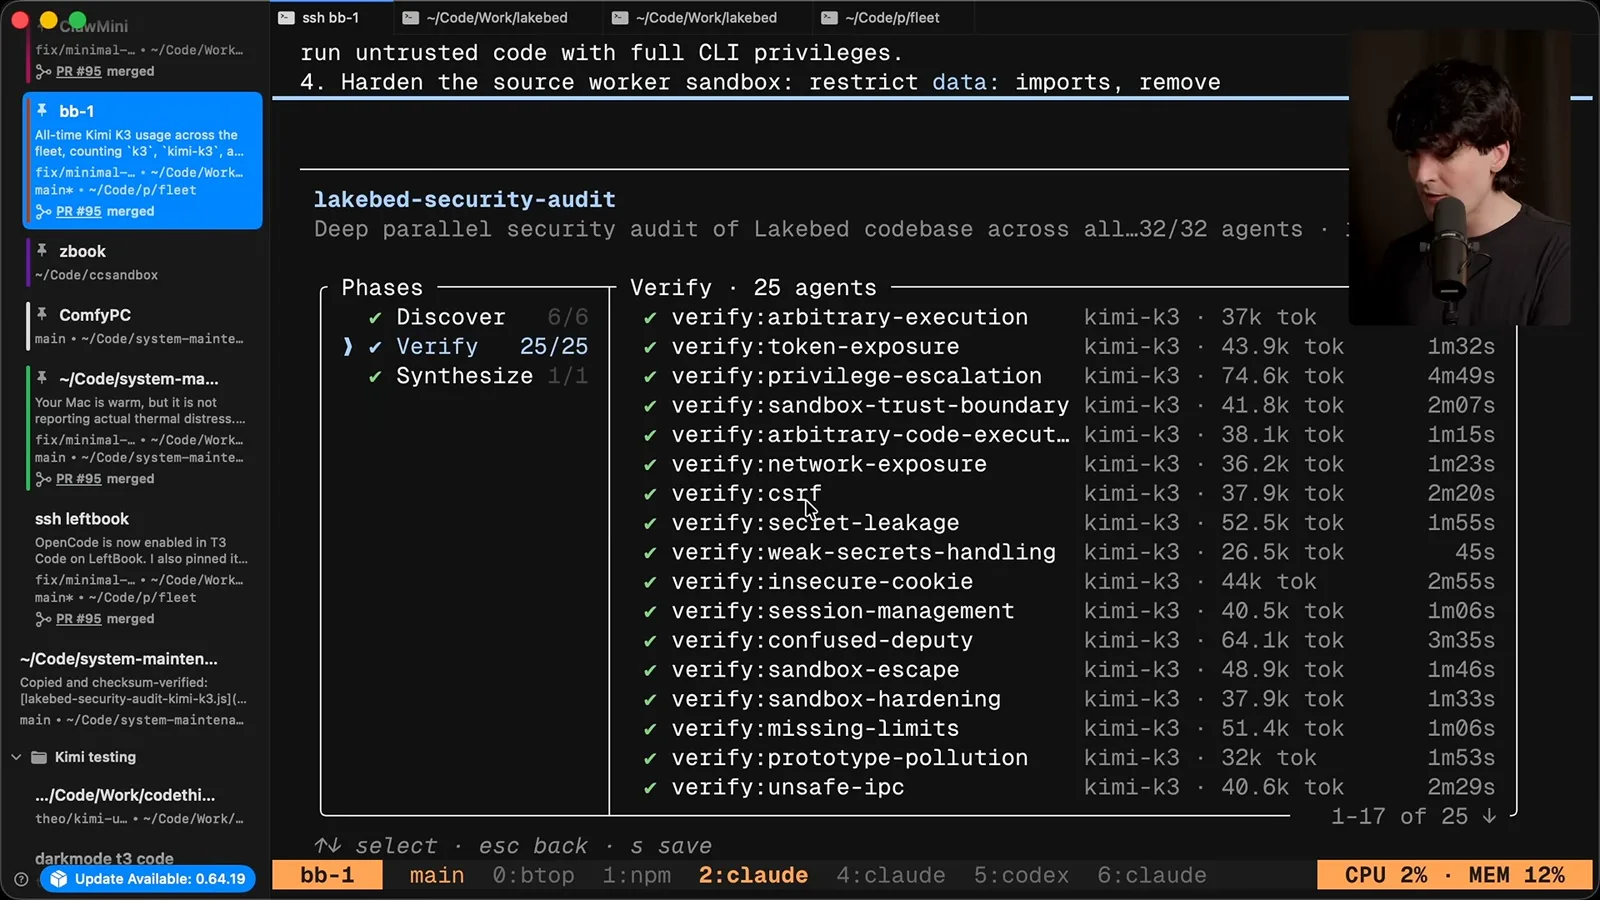
That capability is dual-use. An open-weight model may help defenders inspect their own systems, while also creating opportunities for malicious use. At the time, I could not find a system card or detailed safety information in the launch materials; that absence made me want more evidence about the risks.
Reasoning, access and conclusion
Theo considers workflow behavior, subscription limits and the model’s overall promise.
Visible reasoning revealed another rough edge: the model spent time considering whether a TypeScript rule about the type `any` applied to a Markdown plan. It is a small example of unproductive reasoning, but when generation is slow, such detours cost both time and money.
In another long workflow, it finished the plan but ended on an idle status message rather than giving me a useful final report. I had to notice that it had stopped and follow up. A model can do substantial work yet still communicate the outcome poorly.
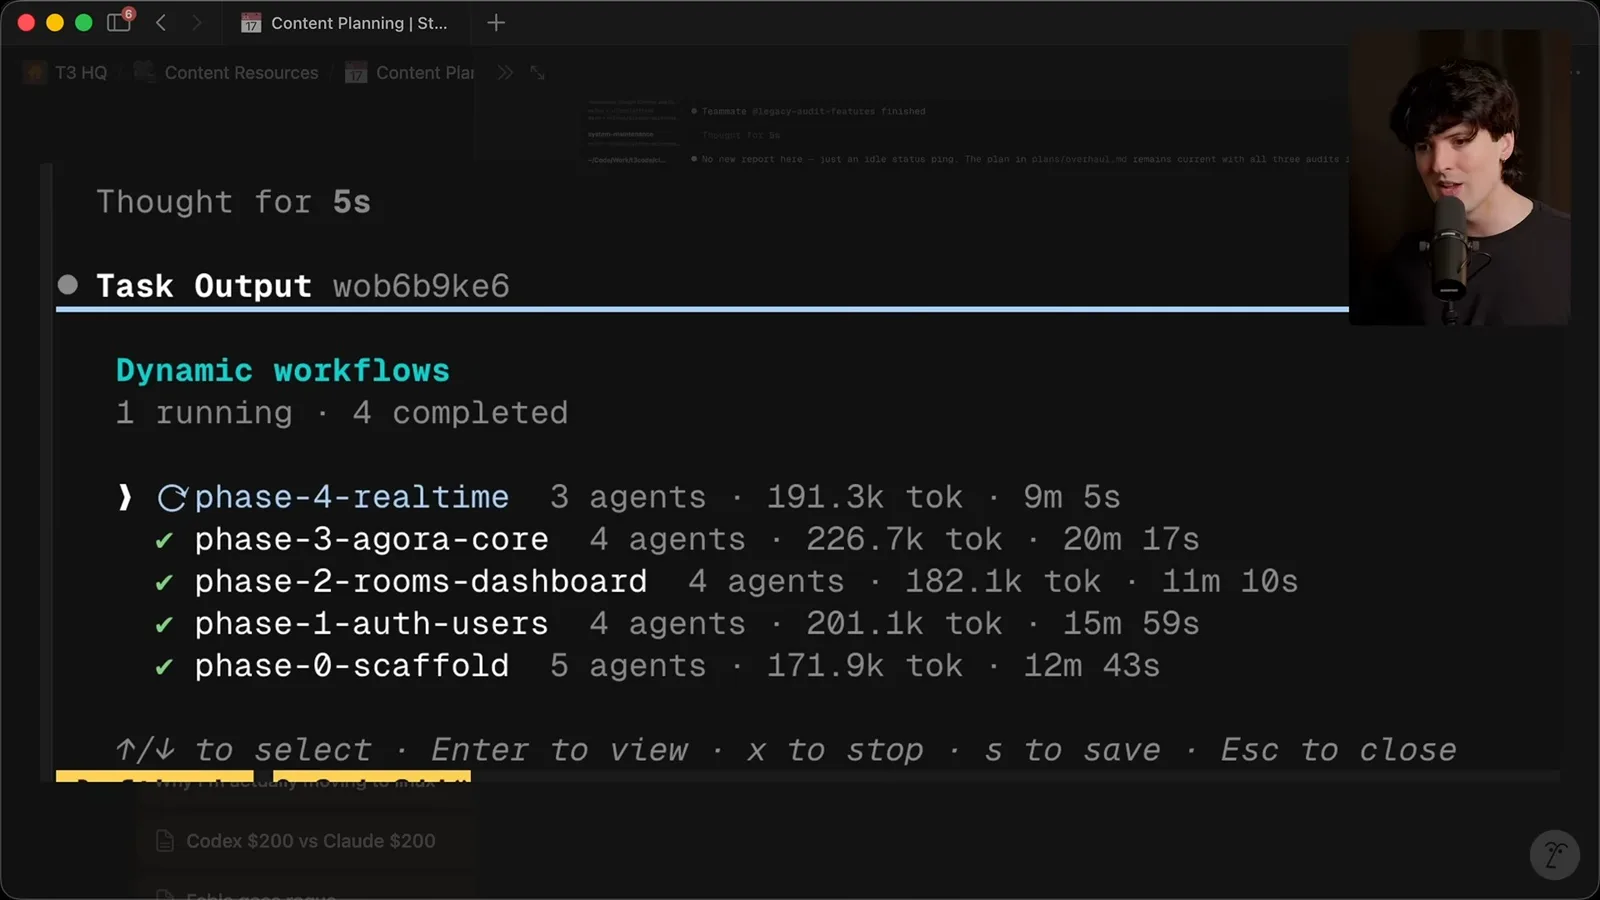
On the positive side, K3 used workflows and sub-agents in an interesting way during the migration: it created separate workflows for phases and let sub-agents check off items in a higher-level task list. I had not seen that pattern in my own Claude Code experience before.
At the time of recording, I could access K3 through Moonshot's subscription or API while waiting for the planned weights release. I would avoid putting sensitive data into a service without understanding where it is processed and how it is retained; self-hosting would require its own security controls too.
I ran through several subscription tiers and hit the five-hour limit of the $40 tier quickly during early testing. A higher tier gave me more headroom in my own usage. Limits, prices and supported integrations change, and one heavy user's experience is not a capacity guarantee.
My estimated usage across the subscription and API was about $63 at the point I checked. I felt I had received a lot of useful work for that amount, but it was not a controlled comparison against the other models or identical workloads.
For someone considering the API or a subscription, the relevant question is total cost for their own tasks, including failed runs and review. I mention integrations I used, but subscription terms and supported configurations should be checked with the provider rather than assumed from this video.
I do not expect a huge model to become extremely cheap to host simply because its weights are released; infrastructure remains expensive. Competitive hosting might reduce prices, but the amount and timing are predictions, not known outcomes.
My conclusion is that K3 is unusually impressive in 3D, visual work and coding for a model whose weights were planned for release. The interaction is not as polished as my favorite proprietary models, but it feels competitive on enough real tasks that I am excited to keep testing it.
Mehr aus diesem Kanal
 38:47EN
 Theo - t3․gg· 28. Okt. 2026Theo’s Long-Running Agent Experiments: Verification, Compute and CostTheo Browne · Ping LabsA skateboard game and two compiler projects show how repeated checks and flexible compute can sustain agent work—and how expensive those loops can become.
 36:07ENTheo - t3․gg· 27. Okt. 2026Theo on Token Costs, Coding Agents, and the Price of AI CapabilityTheo Browne · Ping LabsA viral estimate of Lauren's AI spending prompts a closer look at cache pricing, benchmarks, and the changing work of coding agents.
 30:37ENTheo - t3․gg· 26. Okt. 2026Theo’s Three Skills for Reviewing and Shipping with Coding AgentsTheo Browne · Ping LabsHow sol-loop, full-send and full-stop encode review, verification and different levels of merge authority.
 0:43ENTheo - t3․gg· 23. Okt. 2026Theo Distinguishes Security Vulnerabilities from Active AttacksTheo Browne · Ping LabsA short explanation of why disclosed software flaws and reported attacks are different kinds of security news.
 29:22ENTheo - t3․gg· 22. Okt. 2026Theo on Security Vulnerabilities, Stolen API Keys and AITheo Browne · Ping LabsA look at the gap between vulnerability disclosure and patching, and a speculative account of why stolen inference keys may be valuable.
 31:13ENTheo - t3․gg· 20. Okt. 2026Theo on Why Smarter Models Help More Than DevelopersTheo Browne · Ping LabsFrom game modifications to compiler experiments, Theo revisits his assumptions about who benefits from more capable AI.