In 30 Sekunden
Theo discusses announced OpenAI usage-limit changes and compares his estimates of Codex and Claude subscription value. He distinguishes API pricing from cost per task, examines the effect of resets, and shares a small personal comparison of model-generated code reviews.
- 1Limit changesTheo describes the announced increase and notes that some usage is now combined.
- 2Cost per taskToken prices alone do not show how much a model costs to complete a task.
- 3The effect of resetsTheo corrects an initial chart interpretation and explains why reset assumptions matter.
- 4A personal comparisonHis 83 review comparisons favored Opus, while estimated per-review costs favored Sol.
Das Wichtigste
- Theo says the increase restores the $200 tier roughly to its earlier allowance while increasing the $100 and $500 tiers.
- Per-token price, tokens per task and subscription allowances are different measures of value.
- Including resets can materially change retrospective subscription comparisons.
- A personal set of model-judged reviews favored Opus, though the result is specific to that sample.
- Combined usage across product surfaces can affect users differently.
Den bearbeiteten Text nach Kapiteln lesen
The new allowance
Theo discusses the announced increases and their relationship to earlier reductions.
I have historically defended Codex and OpenAI, but recent limit reductions and model releases have made that position harder. I still prefer Anthropic’s Opus 5.5 for many tasks. A new usage-limit announcement, however, looks like a step in the right direction.
According to the announcement I am discussing, usage limits doubled for the $100, $200 and $500 Pro tiers and Business Premium. The change has qualifications: some previously separate usage is now combined, so individual users may experience it differently.
To understand the change, consider the earlier reduction to the $200 plan. My reading is that the new increase restores that tier roughly to its previous level, while the $100 and $500 tiers receive a genuine increase. The $500 tier now offers a very large allowance, particularly if you do not heavily use faster modes.
The earlier explanation emphasized that as models improve, subscribers should be able to do more work at a given price. It also argued against tying allowances to an incentive to keep API list prices high. I think the work-completed guarantee is a useful principle, though the details of the allowance still matter.
API value and cost per task
He compares estimated allowances, token consumption and benchmark task costs.
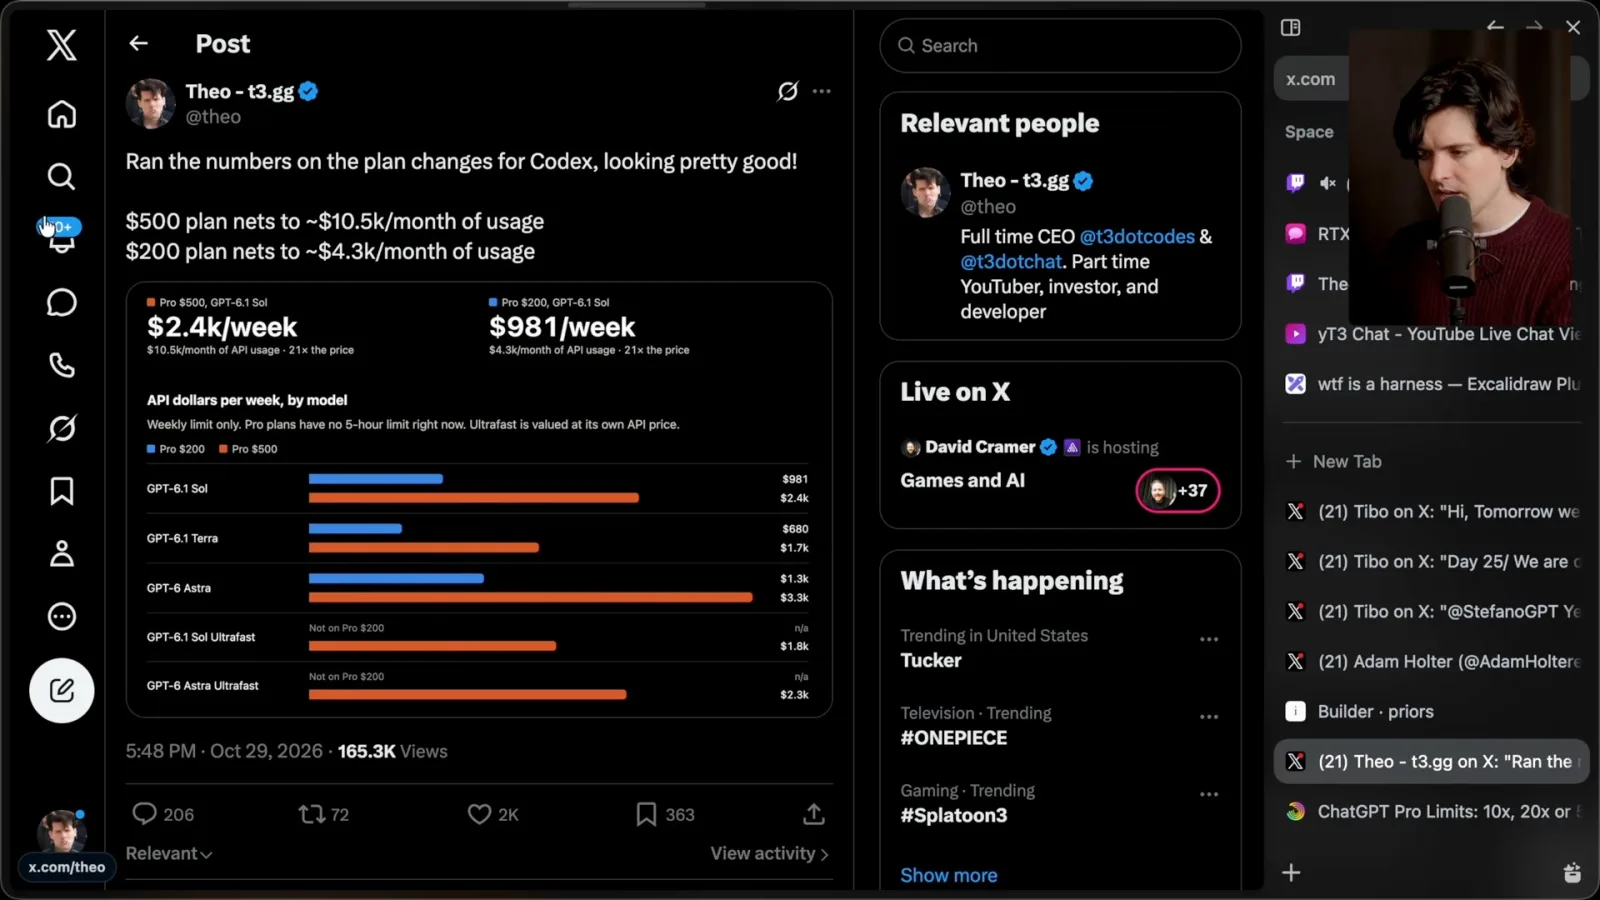
One way to compare plans is to estimate the API-equivalent value of their allowance. My calculation puts the $500 plan near $10,500 a month and the $200 plan near $4,300. I compare those with a higher estimate for the $200 Claude plan, while noting that some model-specific restrictions apply.
API-equivalent dollars are not the same as actual work completed. Per-token pricing is only one dimension; caching changes costs, and different models consume different numbers of tokens to solve a task. A cheaper price per token does not necessarily translate directly into a cheaper result.
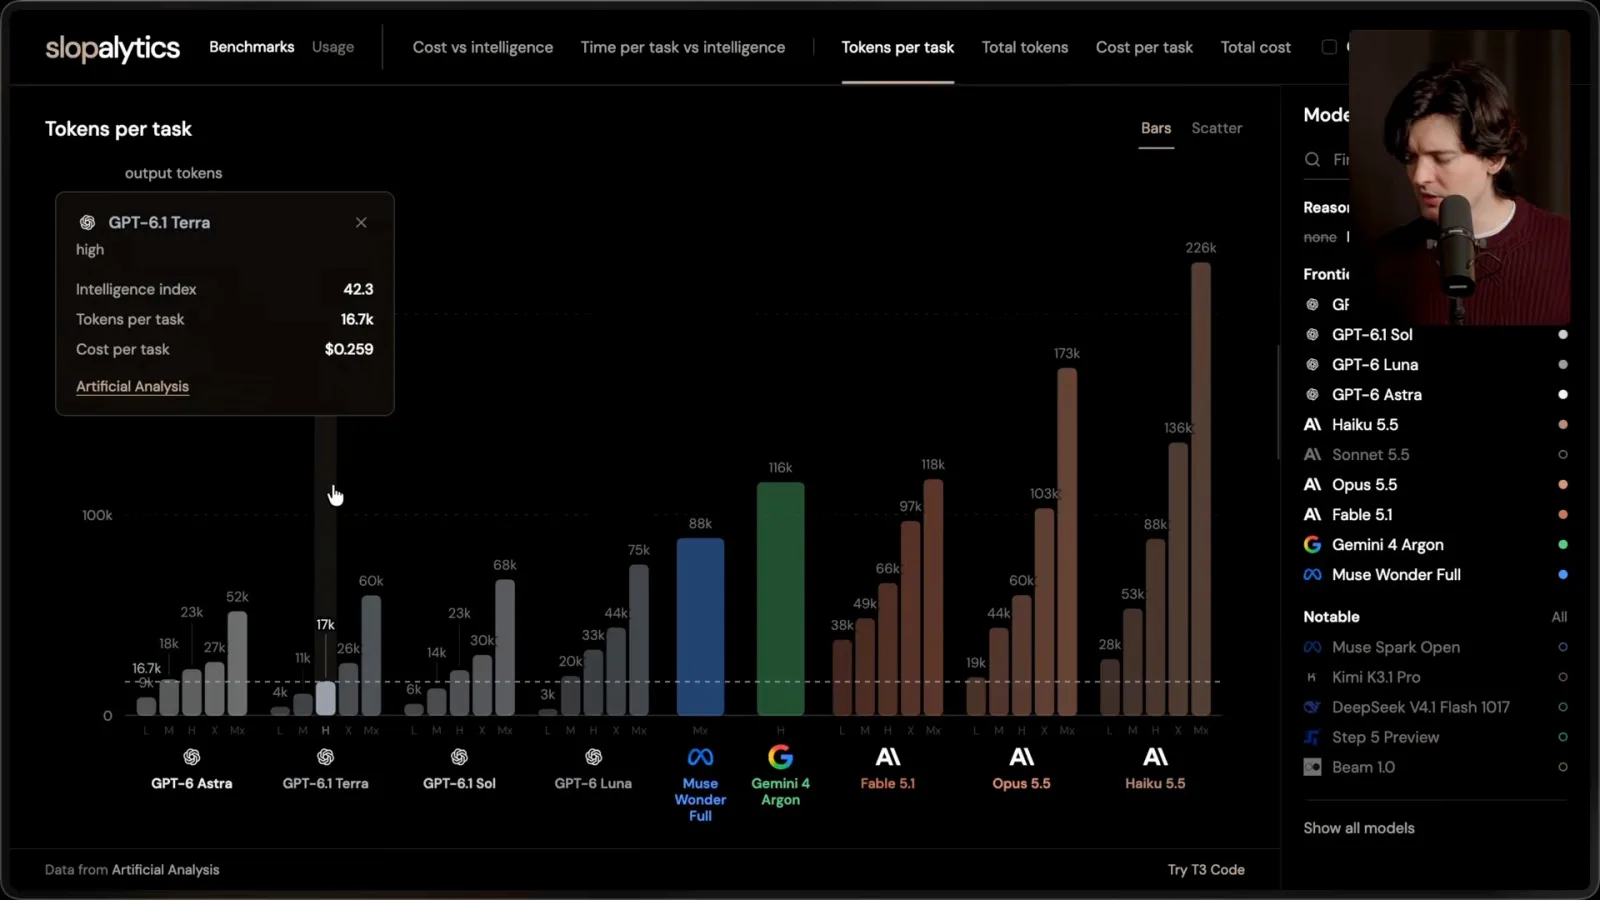
On the benchmark chart I show, OpenAI models generally use fewer tokens per task than the Anthropic models being compared. The comparison depends on model and reasoning level. I also compare an intelligence score with estimated cost per task, where the selected GPT-6.1 Sol configuration looks cheaper than the selected Opus configuration.
Subscriptions and resets
Subscription discounts and resets alter the value comparison.
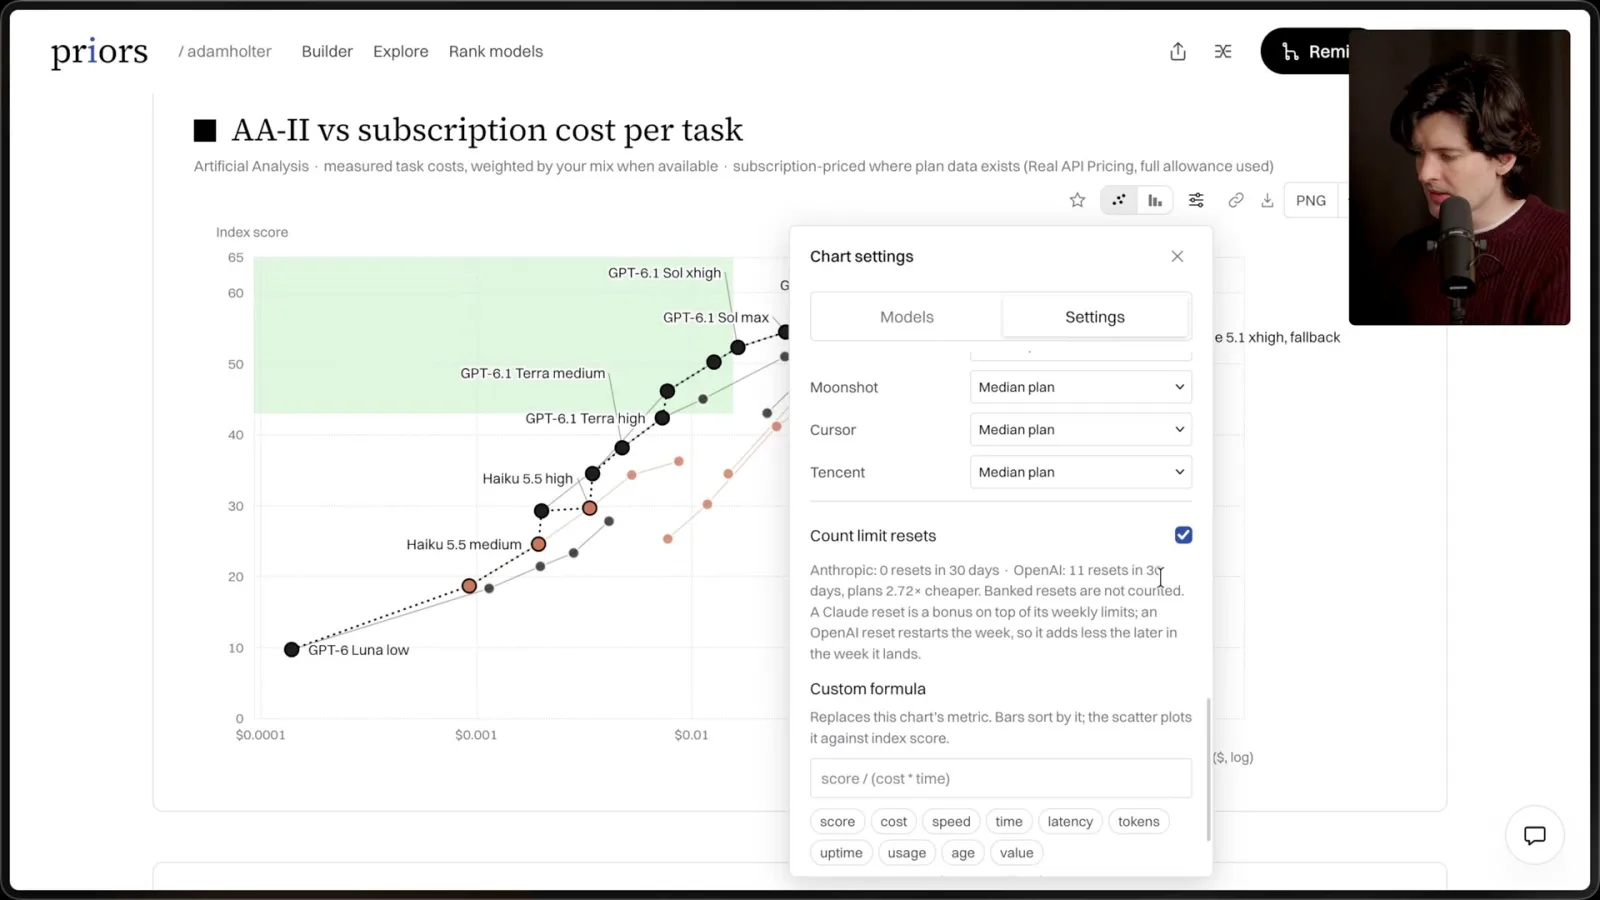
Subscription economics change the picture again. Adam Holter’s analysis adjusts task costs for the effective allowance under subscription plans. In the configurations I use most often, the estimated subscription cost per task for Opus 5.5 and GPT-6.1 Sol becomes much closer than the API list-price comparison suggests.
I then look at the value frontier: which model offers the best measured capability at a given cost. API pricing and subscription pricing can produce different frontiers. The chart is based on a particular benchmark and set of assumptions, so it should not be treated as a universal ranking for every task.
The charts also change depending on whether allowance resets are counted. I initially thought a difference between two views was due to the doubled limits, then corrected myself: one view included resets. The history of resets can materially affect a retrospective calculation of subscription value.
A personal review experiment
Theo compares model-generated assessments of reviews on his own tasks.
These figures still depend on benchmark tasks. To compare work closer to my own use, I have multiple models review the same proposed changes and then evaluate their reviews. This is a like-for-like comparison within my workflow, not a general proof of model quality.
In 83 comparisons, the model judges preferred the Opus review more often: Opus selected Opus 66 times and Sol selected it 54 times. My estimated median API-equivalent review costs were $1.65 for Opus and $0.36 for Sol. The judgments are model-generated and the experiment reflects my own review tasks.
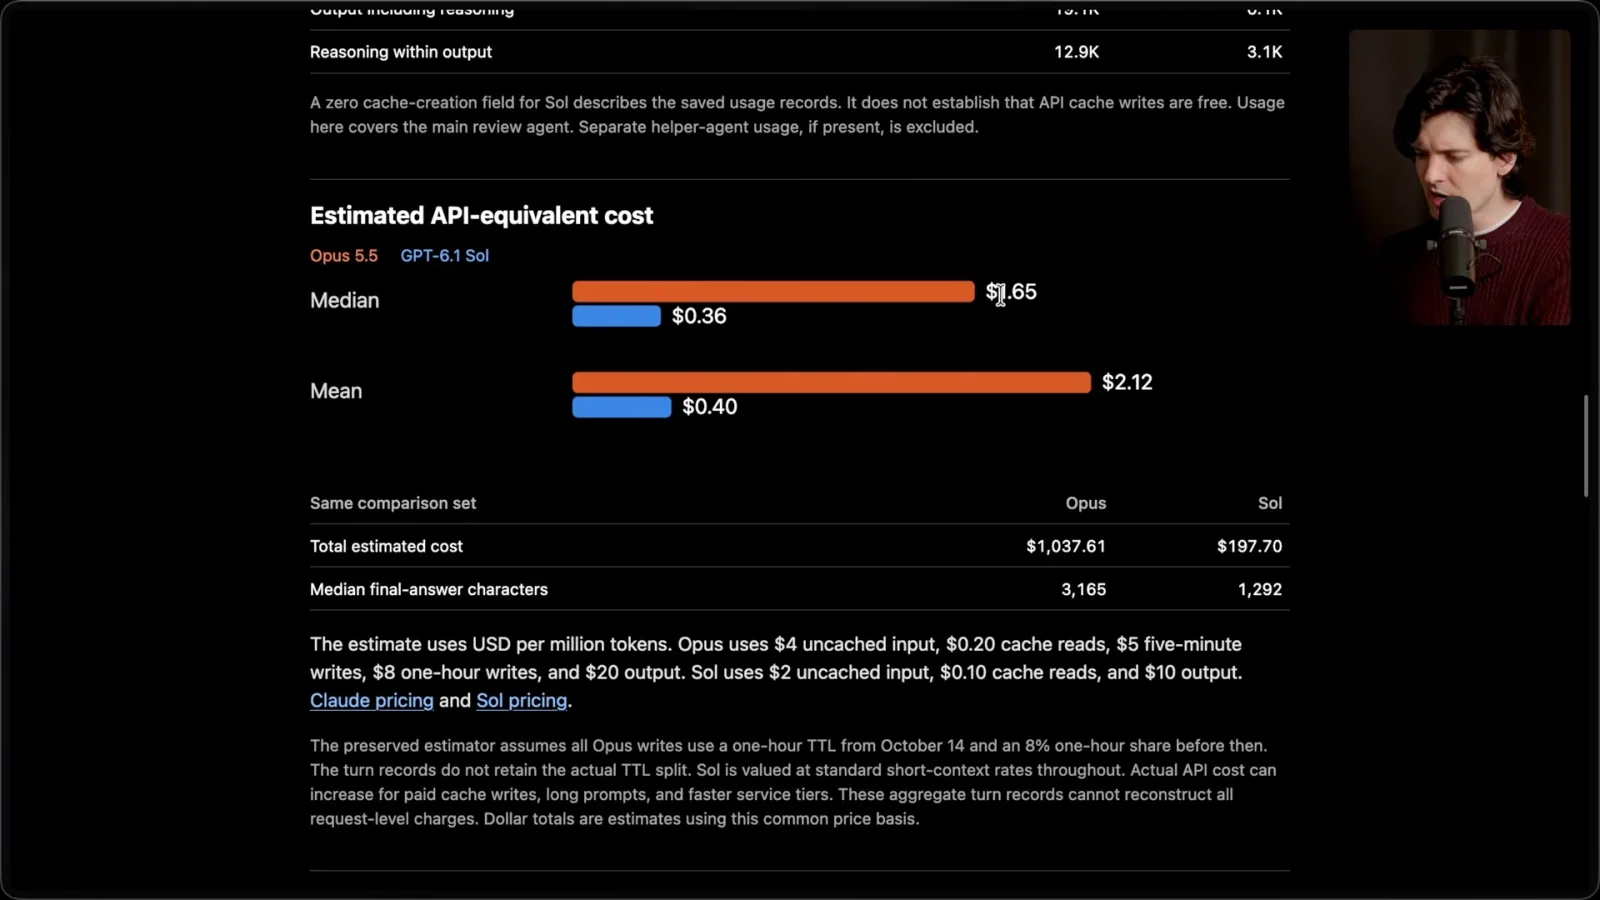
After accounting for subscription allowances, my calculation yields roughly 205 Opus reviews versus 290 Sol reviews on the compared plans. That is closer than the raw per-review API cost suggests. I would still choose Opus for its quality in this sample, while someone who values more reviews or faster completion may weigh the trade-off differently.
Shared limits and the remaining question
He discusses combined usage and his preference for a stronger model.
The announcement also combines ChatGPT and Work usage with the limits discussed for Codex. I expect many coding users to see little impact, but people who use those other surfaces heavily may differ. I am uncertain about how Dots is treated, so I would not rely on my guess as a definitive rule.
Overall, I welcome the increase, especially on the $100 and $500 tiers. For the $200 tier, I see it mainly as a restoration. My remaining concern is model quality: in my experience, OpenAI still needs a stronger competitor to Opus 5.5 for the work I value most.
Mehr aus diesem Kanal
 16:46EN
 Theo - t3․gg· 2. Nov. 2026Theo Browne on Claude Ultra, Five-Hour Limits and SDK UsageTheo Browne · Ping LabsA breakdown of the renamed subscription tier, verification and reported differences between interactive and SDK usage.
 49:29ENTheo - t3․gg· 30. Okt. 2026Theo on Agent Harnesses, Interfaces and Shifting AbstractionsTheo · T3 CodeThe T3 Code creator explains his model of harnesses and why he expects their differences to become less visible to users.
 41:49ENTheo - t3․gg· 29. Okt. 2026Theo Demonstrates T3 Code for Coordinating Coding AgentsTheo · t3.ggThe T3 Code creator walks through multiple agent providers, remote machines, thread organization and the tradeoffs of an open-source coding interface.
 38:47ENTheo - t3․gg· 28. Okt. 2026Theo’s Long-Running Agent Experiments: Verification, Compute and CostTheo Browne · Ping LabsA skateboard game and two compiler projects show how repeated checks and flexible compute can sustain agent work—and how expensive those loops can become.
 36:07ENTheo - t3․gg· 27. Okt. 2026Theo on Token Costs, Coding Agents, and the Price of AI CapabilityTheo Browne · Ping LabsA viral estimate of Lauren's AI spending prompts a closer look at cache pricing, benchmarks, and the changing work of coding agents.
 30:37ENTheo - t3․gg· 26. Okt. 2026Theo’s Three Skills for Reviewing and Shipping with Coding AgentsTheo Browne · Ping LabsHow sol-loop, full-send and full-stop encode review, verification and different levels of merge authority.