In 30 Sekunden
Theo Browne reviews GPT-5.5 launch data and shares early experiences with game, web and puzzle tasks. He praises coding capability and token efficiency while describing early stopping and difficult-to-correct threads; these conclusions come from particular tests and personal observations.
- 1Capability versus steerabilityTheo is impressed by coding ability but says some tasks require more explicit direction.
- 2Efficiency depends on the testLower output-token totals on a benchmark do not automatically establish lower cost for every workload.
- 3A 3D renderer is not a 3D gameA prototype used three-dimensional assets while retaining much of its earlier two-dimensional interaction.
- 4Context can reinforce a bad pathTheo reports threads that were difficult to redirect and sometimes restarted with clearer constraints.
- 5Puzzle timing needs contextTwo runs received different starting information, so their times are not directly comparable.
Das Wichtigste
- Early user impressions combine strong coding capability with concerns about stopping too soon or missing intent.
- Token counts, pricing and task success must be considered together when comparing cost.
- Informal demos and provider benchmarks do not determine performance on every workload.
- Explicit acceptance criteria and hands-on testing help detect incomplete implementations.
- A fresh thread can reset a drifting context if important facts and unfinished work are carried forward.
Den bearbeiteten Text nach Kapiteln lesen
A powerful but frustrating release
Theo separates his impressions from launch-era pricing and availability. He frames the review as early experience.
I expected to be excited about GPT-5.5, and in some ways I am. It is capable and produces impressive code, but my early experience has also been frustrating. It often completes a narrow interpretation of a task when I wanted it to carry the intent further.
At the time of this video I describe a listed price of $5 per million input tokens and $30 per million output tokens, twice the preceding model’s price in my comparison. Price per token is only part of total cost: a model that uses fewer tokens may cost less per completed task in some workloads. These are launch-era figures, not current pricing guidance.
OpenAI’s release material describes safety testing and early-access feedback, along with infrastructure work intended to serve a larger model efficiently. I am looking at the launch claims and my own early tests. These claims do not independently establish how the model will behave for every user or task.
I say that the standard API was not available to me at the time of recording, although I had some early access. Availability changes, so that observation should be read as a snapshot of my test rather than a statement about what is available now.
Benchmarks and token efficiency
Provider-reported results and an independent index suggest capability and efficiency gains under specific tests. Total task cost depends on more than output tokens.
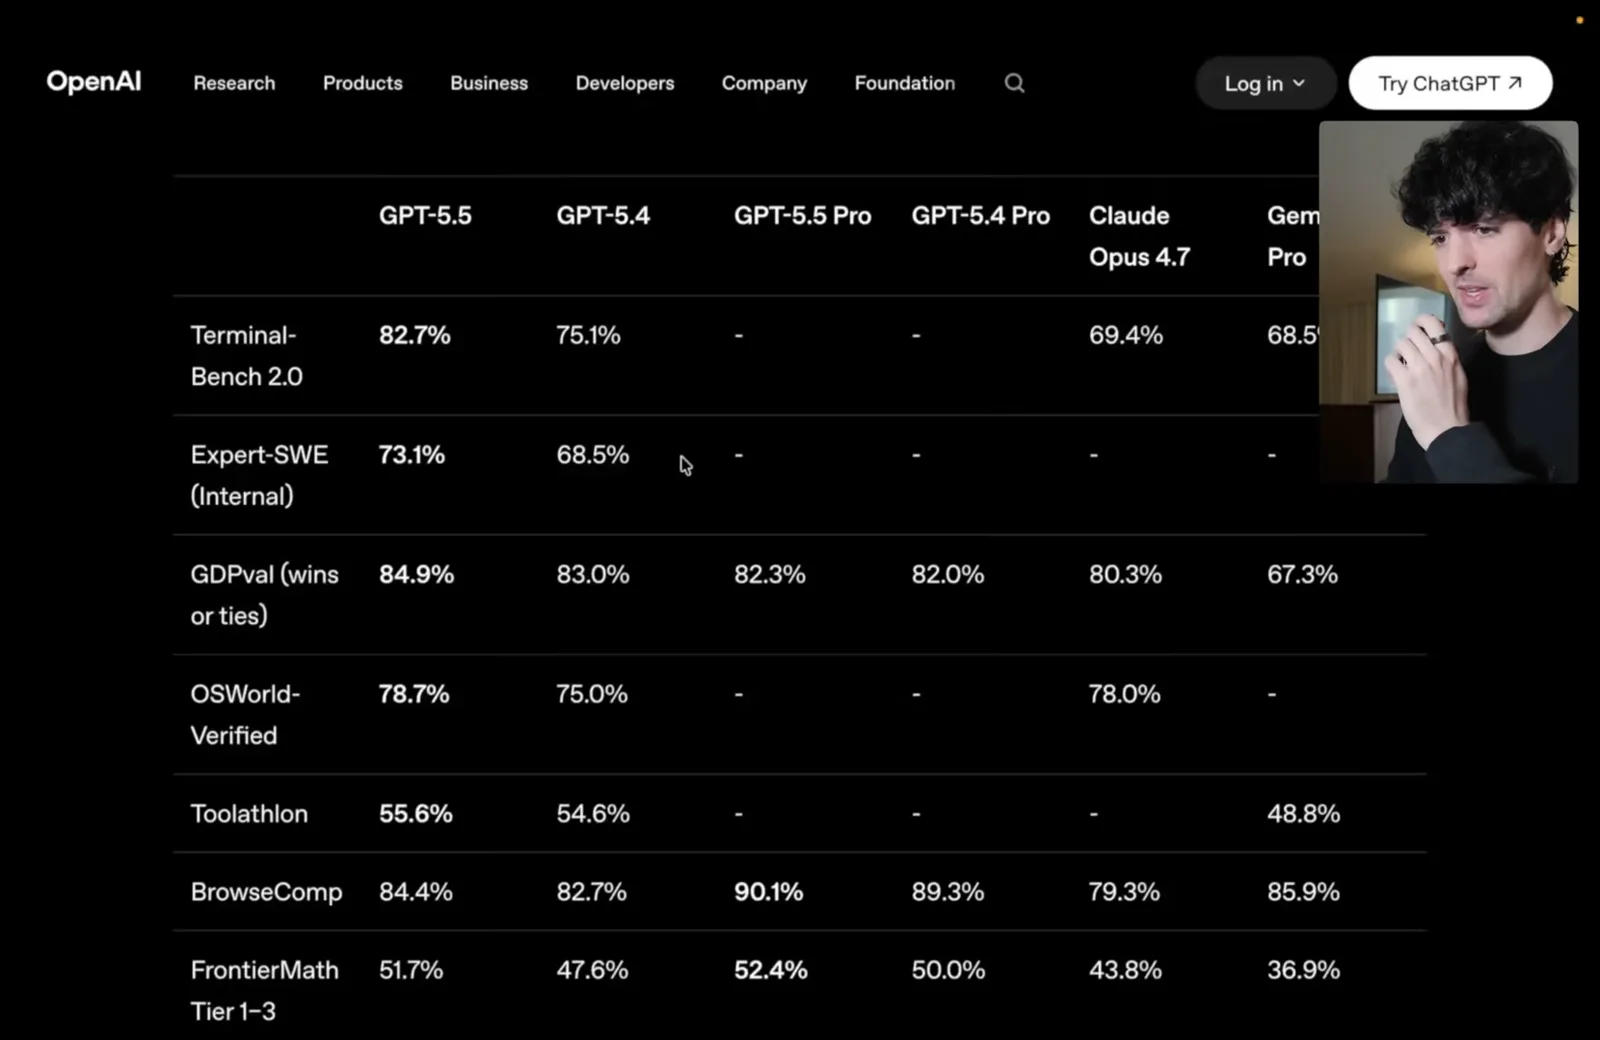
The displayed OpenAI results show 82.7% for GPT-5.5 versus 75.1% for GPT-5.4 on Terminal-Bench 2.0, and 73.1% versus 68.5% on its internal Expert-SWE evaluation. These are provider-reported results on particular tests. Harnesses, task selection and settings matter when interpreting them.
On GDPval, the figure shown combines wins and ties. I point out that an aggregate can rise even if the distribution of outright wins and ties changes in a less obvious way. When comparing benchmark numbers, read the underlying definition instead of assuming every percentage measures the same thing.
The table also includes computer-use, browsing and mathematics benchmarks. I find some of the results impressive but speculate that differences in tool use and long-running coherence may contribute to a browsing result. Those explanations are hypotheses, and a benchmark score alone cannot establish why a model performed as it did.
Artificial Analysis shows different reasoning settings on its intelligence index. In the chart I discuss, GPT-5.5 at medium appears close to GPT-5.4 at its higher setting while consuming fewer output tokens. That is a comparison within this benchmark, not a guarantee of equal quality or cost for every application.
The displayed output-token totals vary substantially by reasoning effort: I cite roughly 75 million for extra-high, 45 million for high and 22 million for medium across that evaluation. Those are totals for running the benchmark, not token usage for a single normal request.
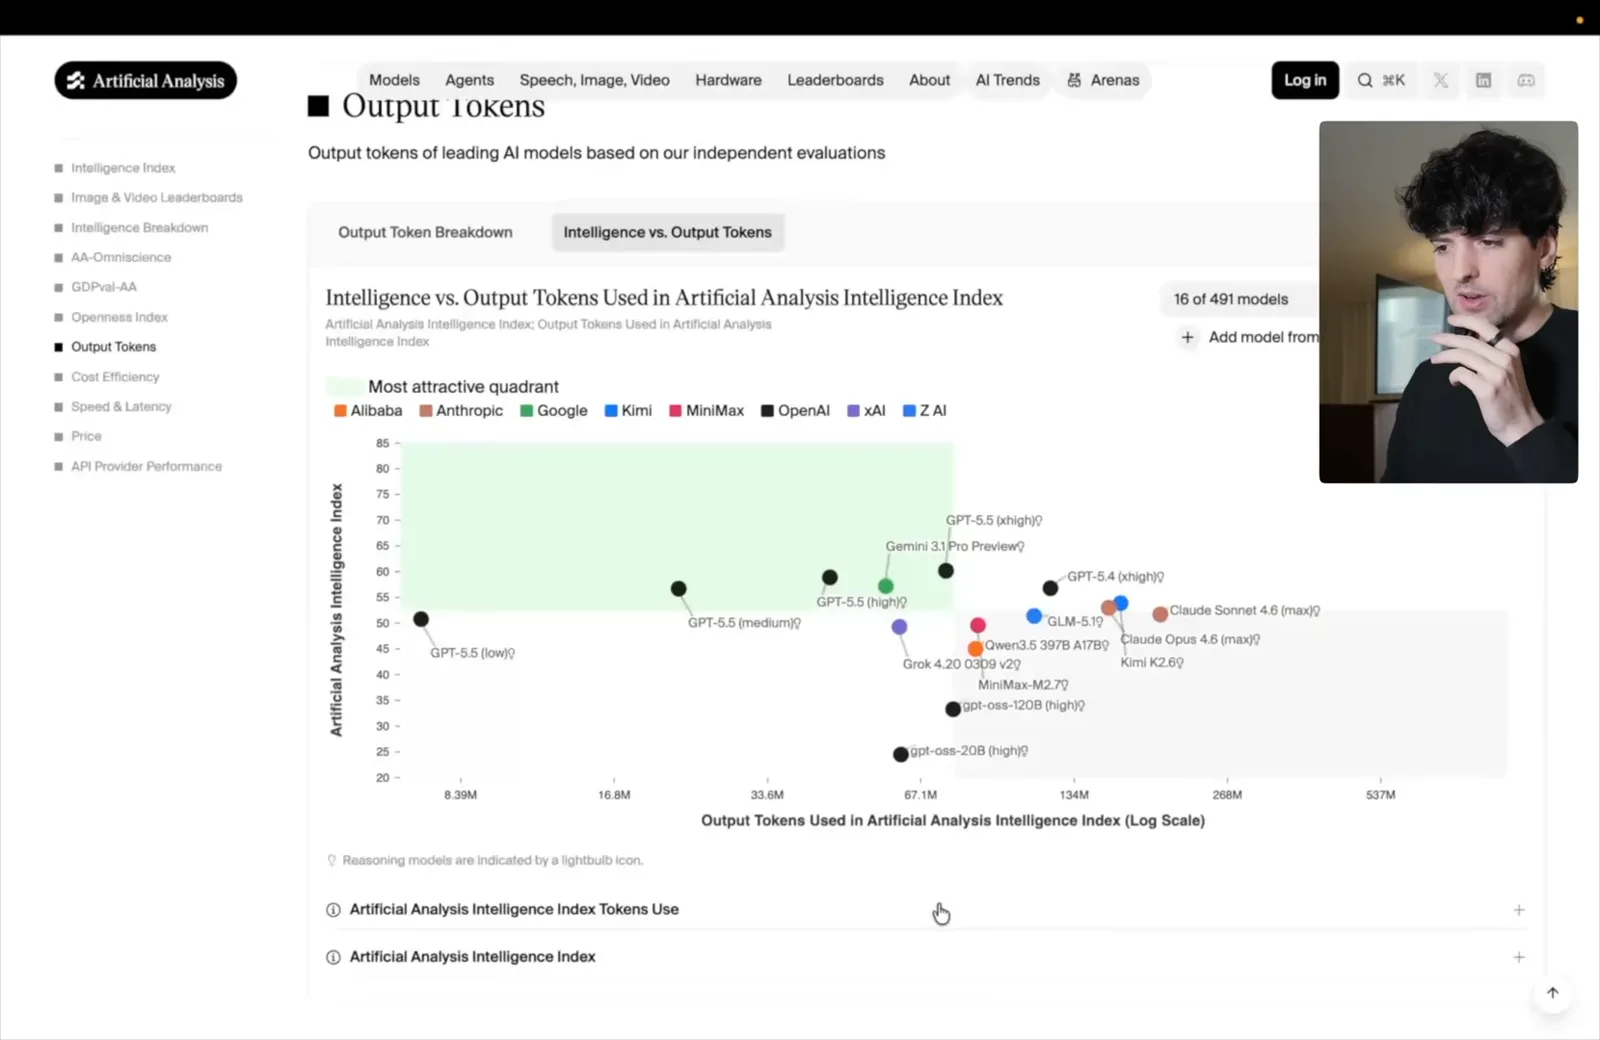
Token efficiency can make a model feel faster and partly offset a higher unit price. It does not by itself prove lower end-to-end cost: input tokens, output tokens, retries, latency and task success all matter. I would test lower reasoning levels on representative work and raise effort where it helps.
Testing a game and a page
Theo compares informal game prototypes and critiques a generated page. The examples expose both visual progress and missed intent.
The frontend demos are impressive in places, especially where they involve spatial or game-like output. My recurring aesthetic complaint is the number of unnecessary cards. I wanted to see how the model would behave on a project I already knew, rather than judge it only from a polished demo.
I returned to an old aquarium-inspired game prototype called Fish Slap. Its code needed cleanup, so I asked different models to modernize it and create a more reliable starting point. This is an informal comparison of particular prompts and runs, not a controlled benchmark.
The Opus version generated assets and improved some movement, but changed controls and had problems with feeding behavior. The GPT-5.4 version also ran, though I noticed screen resizing and fish dying too quickly. Both examples show why a working demo still needs hands-on testing.
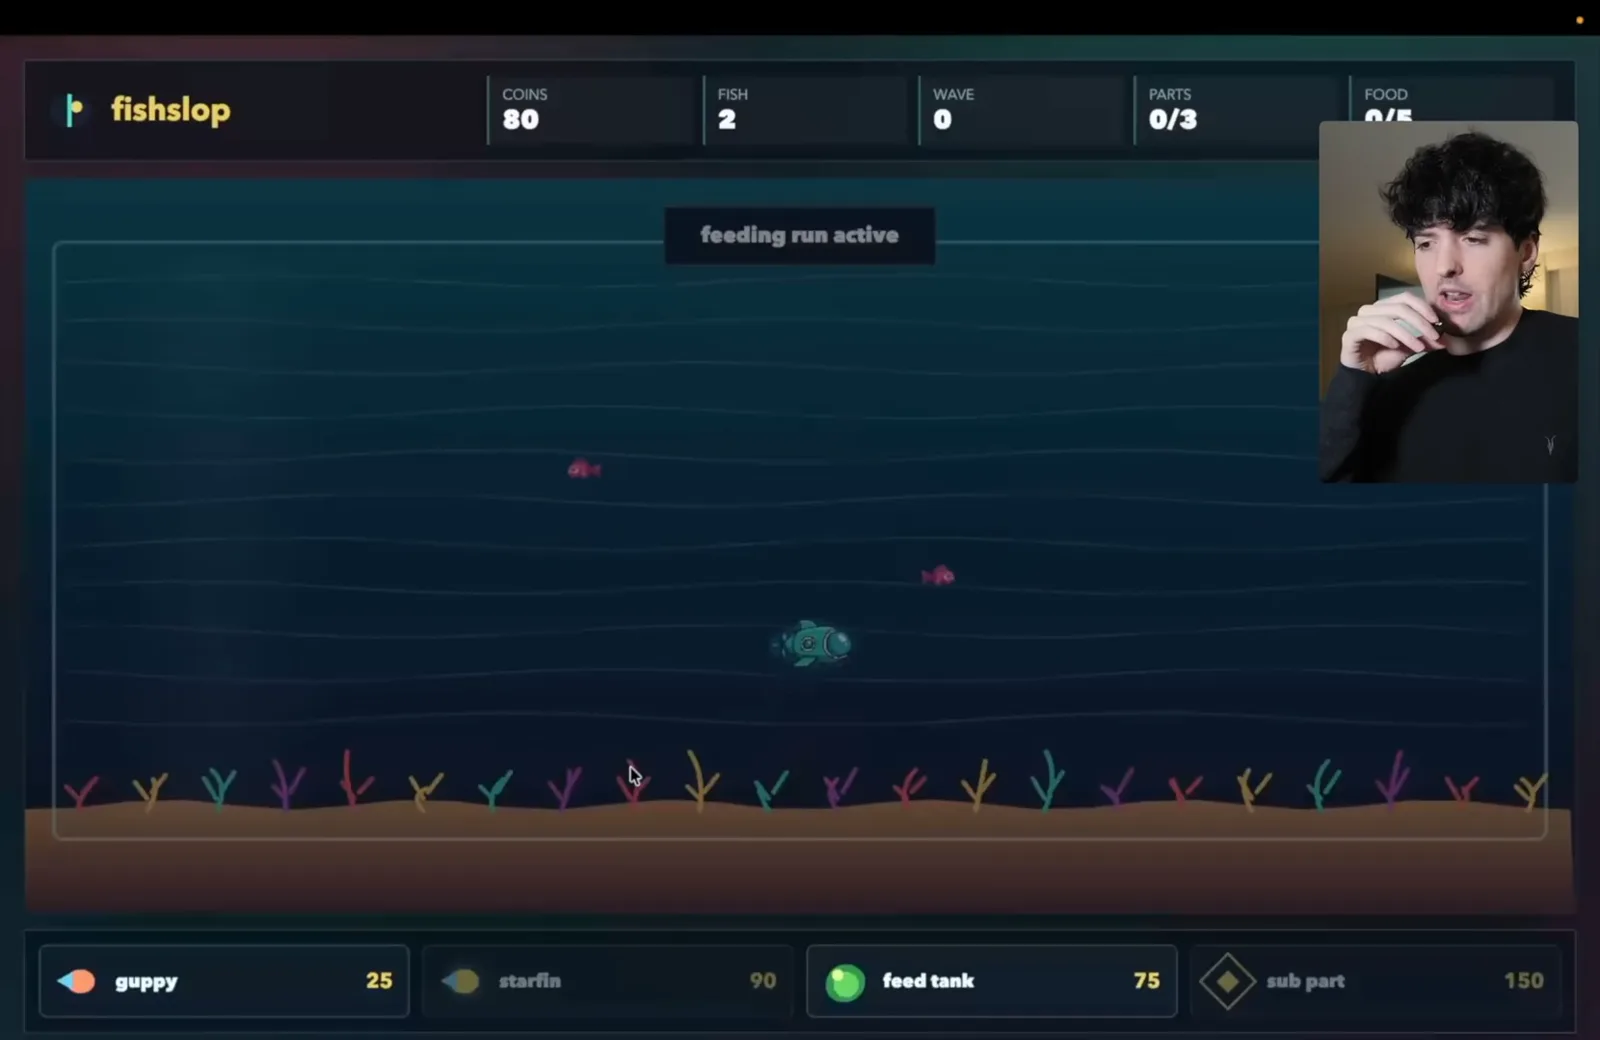
The GPT-5.5 version initially played and looked better to me. It reused some original assets and added new visual details, although I disliked the card-heavy interface. After follow-up prompts it removed some of that clutter, and I could imagine using the result as a starting point.
I then asked for a more three-dimensional game. The first result used 3D assets and a renderer but largely kept the old two-dimensional gameplay. Building that renderer was nontrivial; my disappointment was that the result did not match the experience I had intended.
After several attempts to redirect it, I started a new thread with stricter instructions and got a better result. My subjective impression is that the model can satisfy the literal wording without pursuing the broader goal. Clear acceptance criteria can help distinguish a genuine 3D interaction from merely displaying 3D objects.
I also asked it to redesign my sponsors page. The generated page looked acceptable at first, but I found unnecessary controls and a highlighted category that did not change as expected when navigating. A screenshot alone would not reveal that interaction problem; the page has to be exercised.
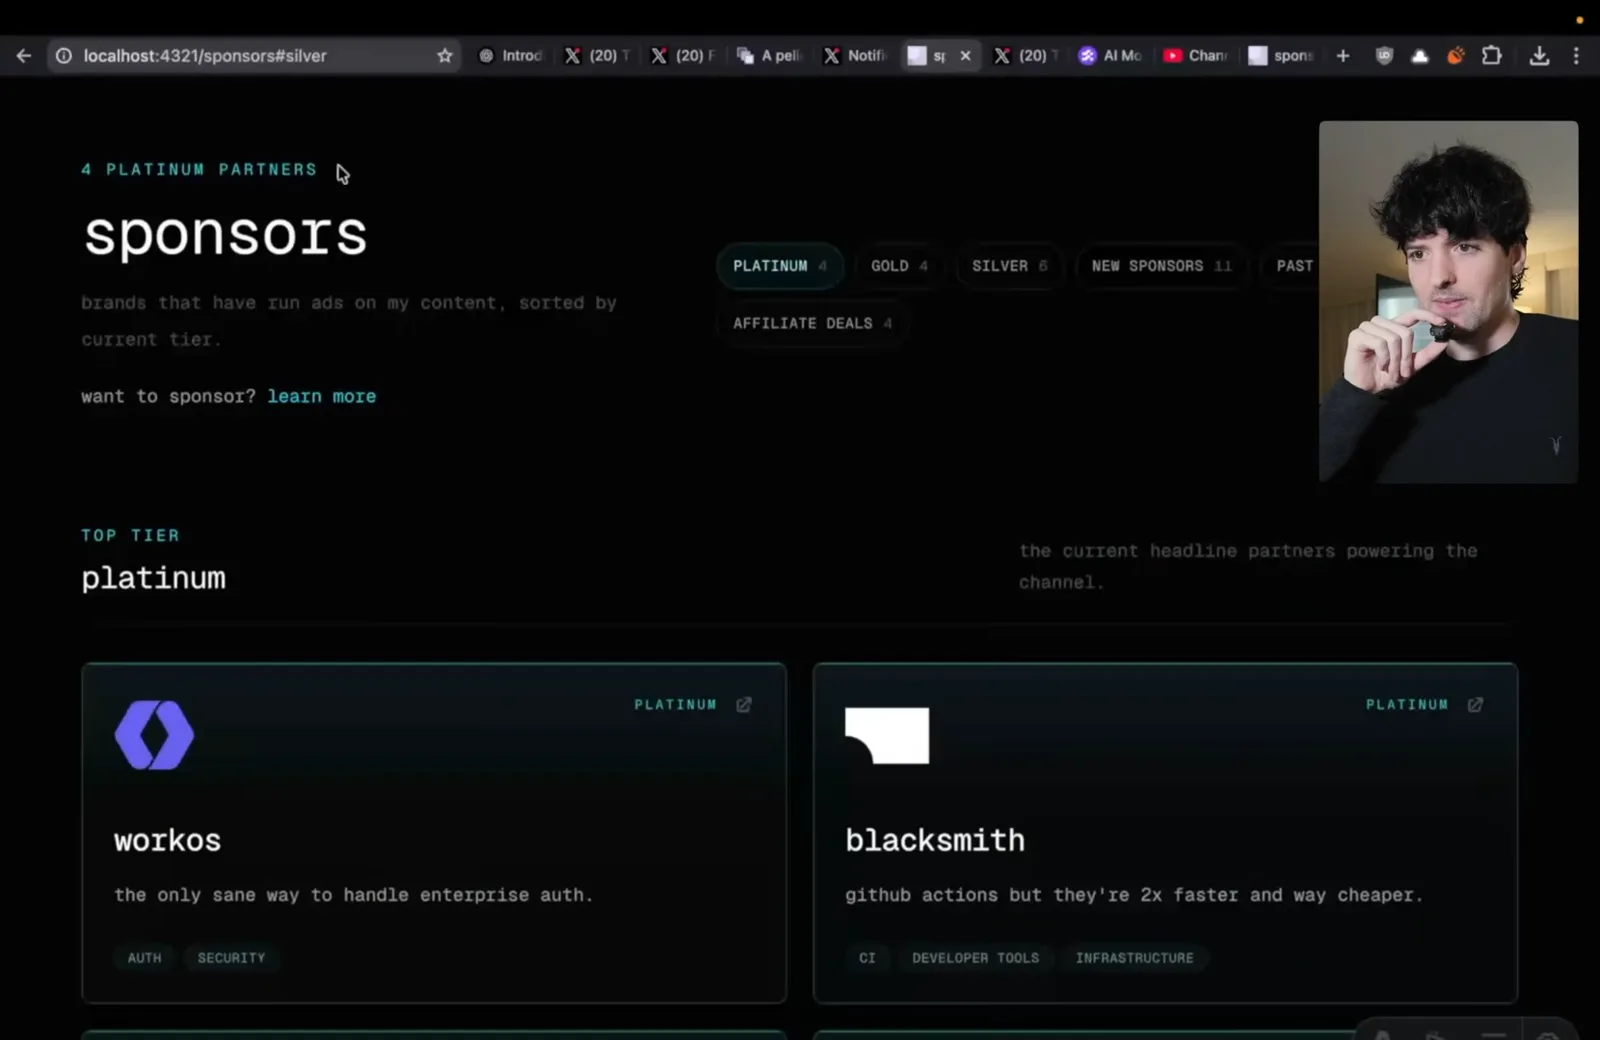
I suspect a clearer visual direction or reference could improve the result. Some other testers told me they created mockups with an image model and then asked the coding model to implement them. That separates visual exploration from implementation, but the resulting interface still needs review.
Steering and context
Other testers report stronger results, while Theo describes early stops and difficult-to-correct threads. These are observations rather than universal rules.
Other early users had more positive experiences. I quote companies describing stronger persistence, tool use and performance on difficult coding tasks. Their reports and mine are different observations under different conditions; neither should be treated as a universal ranking without independent, reproducible tests.
My main complaint is that the model sometimes stops too early and declares the task complete. I call this “lazy” as a description of the experience, not a claim about a model’s motivation. It may require more explicit direction about what a finished result should look like and how to verify it.
I also encountered threads where an early wrong direction seemed hard to correct. One example from Ben involved a request to commit changes followed by further unwanted commits. That is a reported workflow failure, not proof that later instructions can never override earlier context or that every session behaves this way.
For my own work I found it useful to start a fresh thread after repeated drift or a poor compaction. A new thread is one way to reset context, but it also loses useful history unless you carry forward the relevant facts, constraints and unfinished work.
I briefly show an SVG “pelican on a bicycle” test. The higher-effort result looks better to me than the medium result, but this is one visual coding prompt. It illustrates a difference between settings in that example rather than measuring overall model quality.
Pro and puzzle solving
Theo recounts long-running puzzle tests, including a run with different starting information. The claims are largely anecdotal.
My experience with GPT-5.5 Pro was more positive for long, difficult puzzles. I report that it solved several old security-community puzzles, but I cannot share all of those examples and results. That makes this an anecdotal claim rather than an independently reproducible evaluation.
I also tested a public puzzle where it made progress without solving the whole thing. I found the partial work useful, while acknowledging that I did not know whether all necessary information was available. A plausible partial answer still needs checking against the actual puzzle.
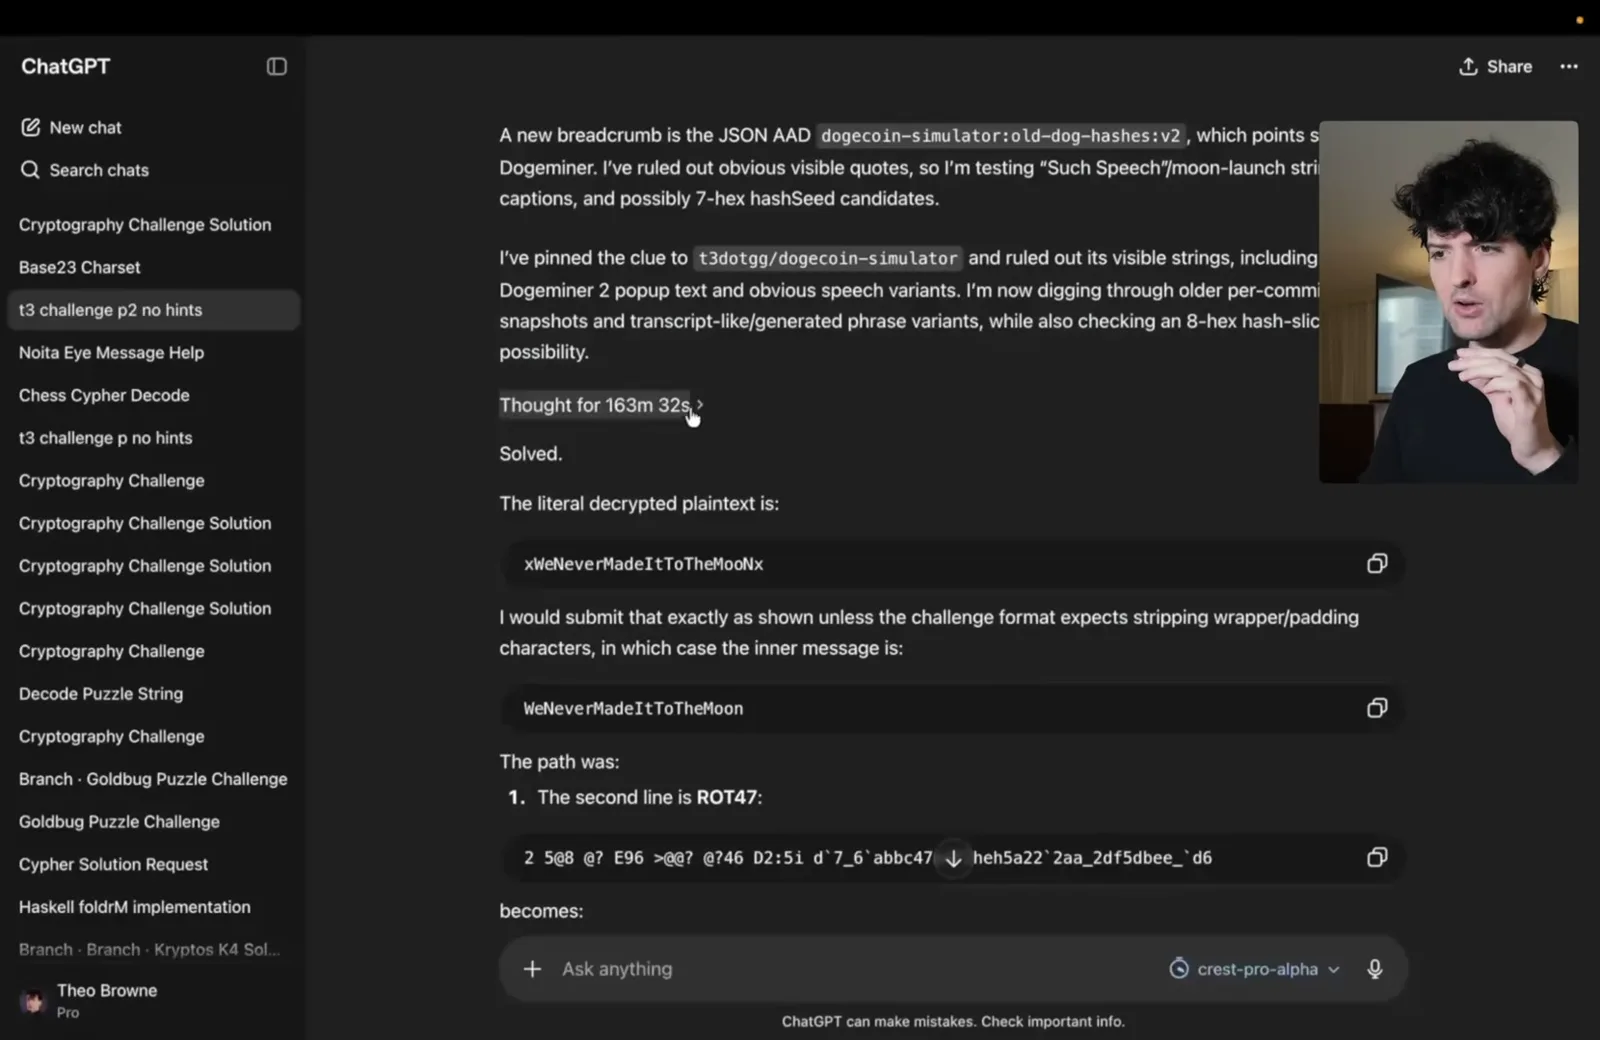
For a puzzle I designed myself, a ChatGPT run took about 163 minutes and reached the solution. A local run finished much faster after I supplied a link that may have acted as an extra hint. The different starting context prevents the two times from being a clean speed comparison.
I describe the puzzle’s stages: a simple encoded clue, a Git commit reference, a custom base-23 encoding and an encrypted payload. The point is not that the model broke modern encryption by itself; it followed a chain of clues in a deliberately constructed challenge.
How to work with the model
He recommends explicit outcomes, relevant context, verification and selective thread resets. He remains positive about capability while critical of steerability.
I remain impressed by the model’s coding and by Pro’s willingness to spend time on hard problems. At the same time, I have had to invest more effort in specifying outcomes, supplying the right resources and checking that the agent follows the intended path. Capability and ease of steering are separate qualities.
My practical advice from this early experience is to give direct instructions, define what success looks like, provide relevant references and make verification possible. If a thread repeatedly follows a bad assumption, consider a clean restart with a concise handoff. Continue checking the output because hallucinations and ordinary errors remain possible.
I speculate that future models may improve these rough edges, but I do not claim inside knowledge about their training or release plans. For now, I would revisit old prompts and workflows instead of assuming they will produce the same behavior with a new model.
Mehr aus diesem Kanal
 38:47EN
 Theo - t3․gg· 28. Okt. 2026Theo’s Long-Running Agent Experiments: Verification, Compute and CostTheo Browne · Ping LabsA skateboard game and two compiler projects show how repeated checks and flexible compute can sustain agent work—and how expensive those loops can become.
 36:07ENTheo - t3․gg· 27. Okt. 2026Theo on Token Costs, Coding Agents, and the Price of AI CapabilityTheo Browne · Ping LabsA viral estimate of Lauren's AI spending prompts a closer look at cache pricing, benchmarks, and the changing work of coding agents.
 30:37ENTheo - t3․gg· 26. Okt. 2026Theo’s Three Skills for Reviewing and Shipping with Coding AgentsTheo Browne · Ping LabsHow sol-loop, full-send and full-stop encode review, verification and different levels of merge authority.
 0:43ENTheo - t3․gg· 23. Okt. 2026Theo Distinguishes Security Vulnerabilities from Active AttacksTheo Browne · Ping LabsA short explanation of why disclosed software flaws and reported attacks are different kinds of security news.
 29:22ENTheo - t3․gg· 22. Okt. 2026Theo on Security Vulnerabilities, Stolen API Keys and AITheo Browne · Ping LabsA look at the gap between vulnerability disclosure and patching, and a speculative account of why stolen inference keys may be valuable.
 31:13ENTheo - t3․gg· 20. Okt. 2026Theo on Why Smarter Models Help More Than DevelopersTheo Browne · Ping LabsFrom game modifications to compiler experiments, Theo revisits his assumptions about who benefits from more capable AI.