In 30 Sekunden
Matthew Berman examines Alibaba’s Qwen3.8-Max using vendor-reported benchmarks, demonstrations and historical API prices. He welcomes alternatives to closed models while asking whether open-weight competition will persist if frontier labs accelerate research with AI. His estimates of rival model sizes and geopolitical scenarios are presented as speculation.
- 1Benchmark results need contextBerman calls the reported scores competitive but cautions that models can perform well on benchmarks without matching those results across all tasks.
- 2Research reproductionAlibaba reports that the model reproduced a paper and tested 18 improvement ideas over four rounds. Berman sees a possible precursor to automated research; it does not demonstrate open-ended recursive self-improvement.
- 3Cost per taskThe video compares historical token prices and emphasizes that token usage and task success matter to total cost. Its cost chart did not yet include Qwen3.8-Max.
- 4Choice and dependenceBerman values self-hosting and competition but worries that future model–hardware co-design could create new dependence. This is a hypothetical risk rather than a demonstrated necessity.
Das Wichtigste
- Reported benchmark scores are task-specific and may not reflect general performance.
- Alibaba describes a research-reproduction experiment and a bounded chip-design optimization task; these demonstrations do not establish unrestricted autonomous discovery or chip manufacturing.
- A lower token price does not necessarily mean a lower cost per completed task.
- Berman sees self-hosted open-weight models as a way to increase choice and reduce dependence on a single provider.
- His concerns about model–chip co-design and geopolitical dependence are scenarios, not established outcomes.
- Model size rumors and predictions of recursive self-improvement do not establish future competitive advantage.
Den bearbeiteten Text nach Kapiteln lesen
Qwen3.8-Max and benchmark claims
Berman introduces the model and highlights its promotional vision. He reviews reported benchmarks while warning about their limitations.
Alibaba has released Qwen3.8-Max, and I am struck by its promotional video’s optimistic vision: people fish, play tennis or climb while AI works on research and spreadsheets. I like the simple picture of technology giving people more time. The video is a vision, not evidence that these tasks can already be done reliably without supervision.
I describe Qwen3.8-Max as an open model with about 2.4 trillion parameters and compare it with Moonshot’s Kimi K3, another large model from China. Model size will matter to my later discussion of compute and competition. Claims about downloadability and licensing should be checked for the specific release; open weights and fully open-source systems are not necessarily the same thing.
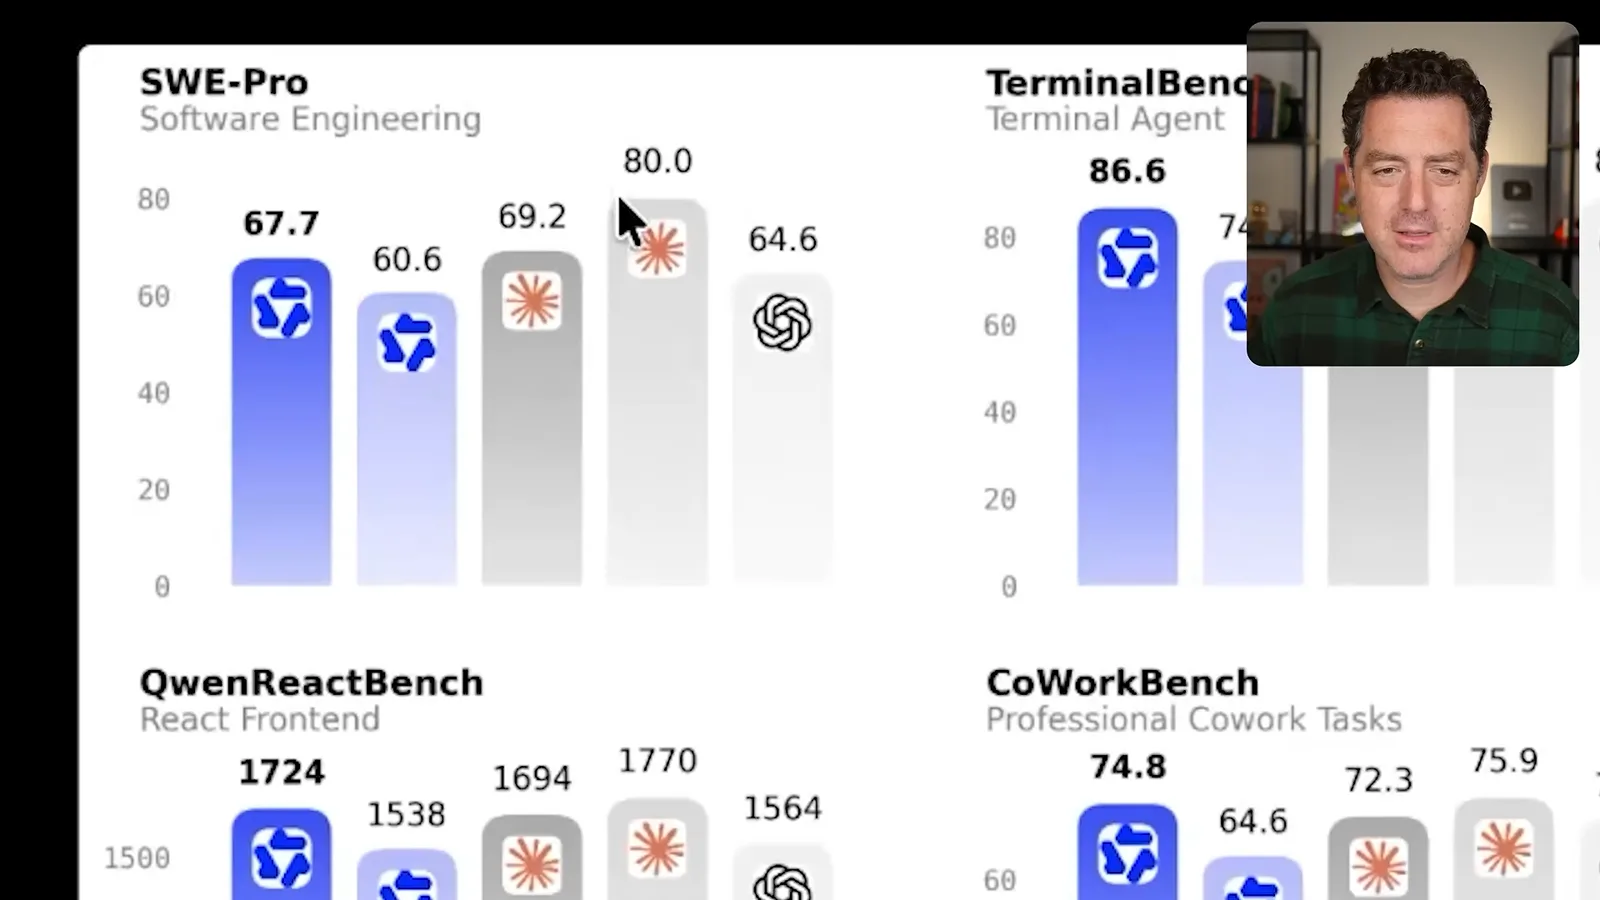
Before looking at benchmarks, a caveat: scores can be optimized for tests and need not represent general capability. The displayed SWE-Pro result is 67.7 for Qwen versus 80 for the leading comparison. The reported TerminalBench score is 86.6, compared with 84.6 for Fable; I see the results as competitive on these tests, not a guarantee across every task.
Research reproduction and hardware design
Alibaba presents a paper reproduction and iterative optimization example, followed by a bounded silicon-design task. Berman discusses what these demonstrations could mean for research.
Alibaba highlights a research reproduction experiment. The task was to read a paper, implement its methods, run code and reproduce its results, starting with the paper and GPUs rather than a ready-made pipeline. I see reproduction as an important component of automated research, because it requires connecting an idea to executable experiments.
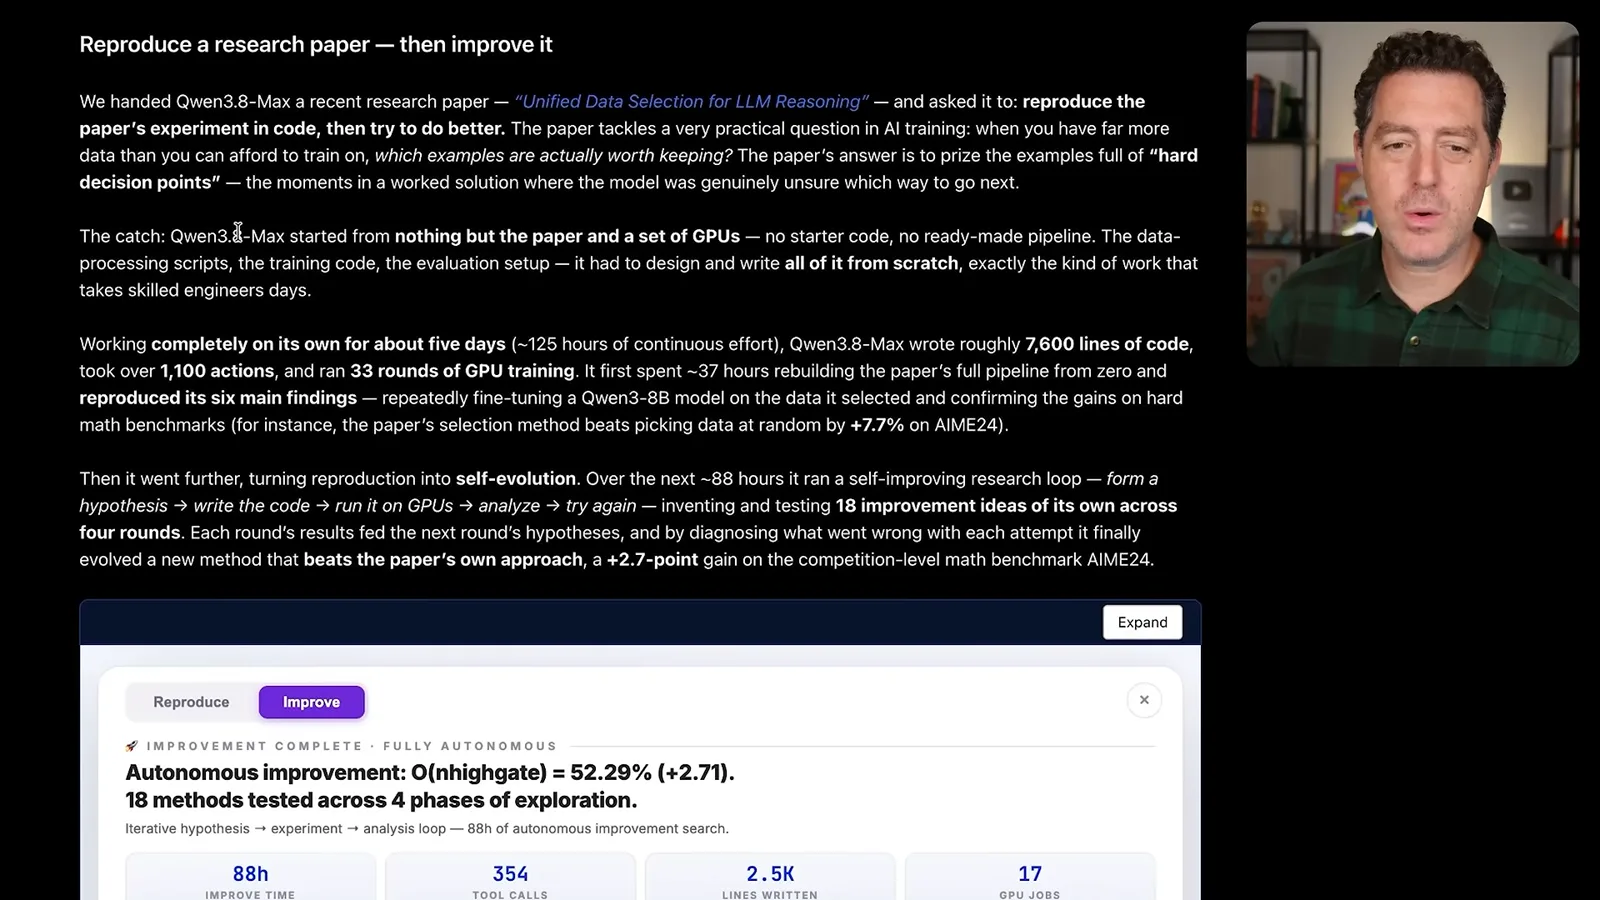
The company reports that the model then tested 18 improvement ideas across four rounds. I call this an iterative self-improvement loop and wonder whether a wider version could eventually help discover research ideas. This experiment improves a specific human-selected research task; it does not by itself prove open-ended recursive improvement of the model.
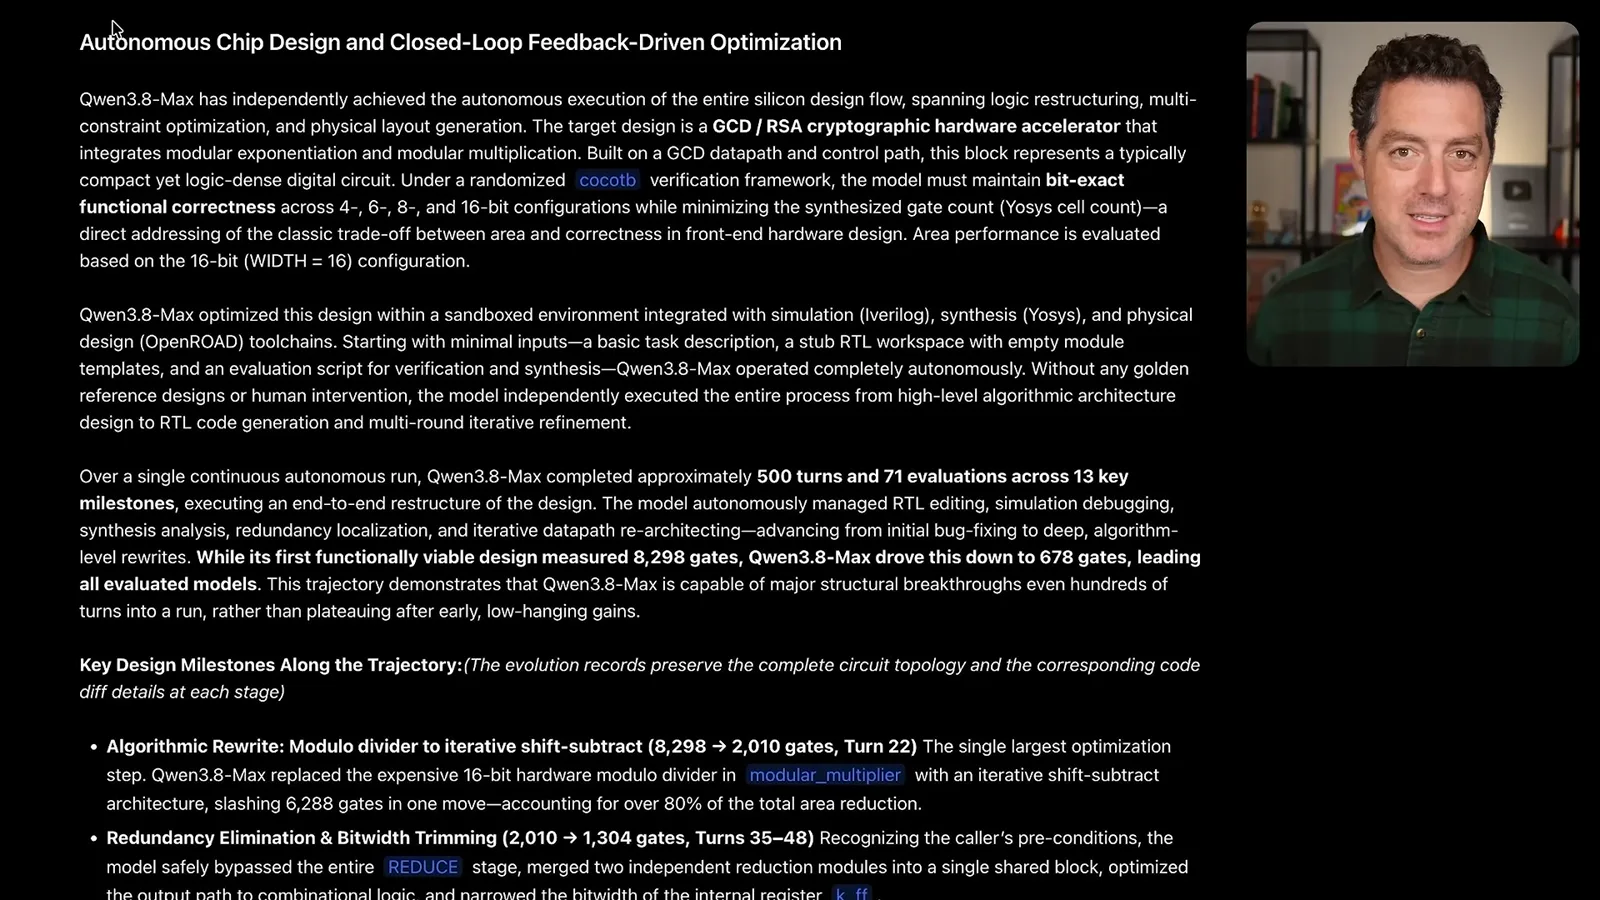
Another example concerns autonomous chip design. The vendor describes an optimization of a cryptographic hardware accelerator in a sandbox with simulation, synthesis and physical-design tools. I find the potential for AI-assisted chip design interesting, particularly given constraints on advanced chips, but this bounded demonstration does not establish autonomous production of leading-edge chips.
The Qwen post includes a large benchmark table. I used Codex to reorganize the results visually, making it easier to compare multimodal reasoning, visual agents and coding, office tasks, spatial understanding and visual perception. Different models lead on different tests; these are the results reported in the table, not independent proof of universal superiority.
Token pricing and cost per task
After a sponsor segment, Berman compares historical API prices and explains why usage per task changes the economics. A third-party chart illustrates the distinction.
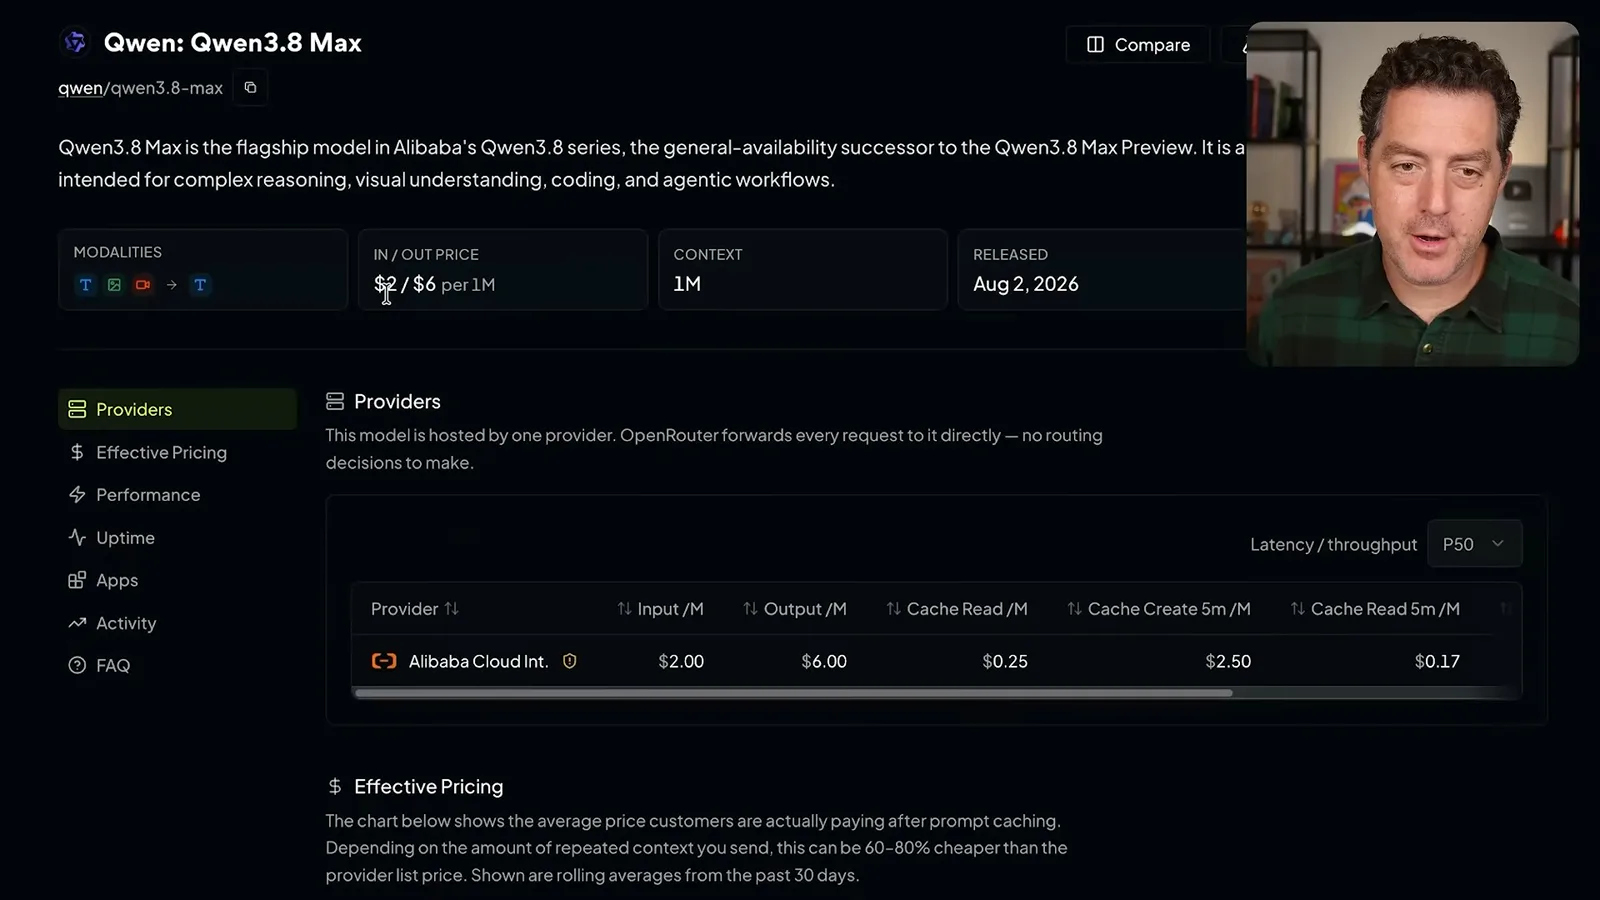
At the time of the video, OpenRouter listed Qwen3.8-Max at $2 per million input tokens and $6 per million output tokens. I compare that with the quoted prices for GPT-5.6 Sol and Fable, which were higher. These are historical prices for the listed services, not a promise about present rates.
Price per token is only half the calculation. If a model requires several times more tokens to complete the same task, its apparent advantage may narrow; quality and successful completion matter too. A lower unit price does not automatically mean a lower cost for the result you need.
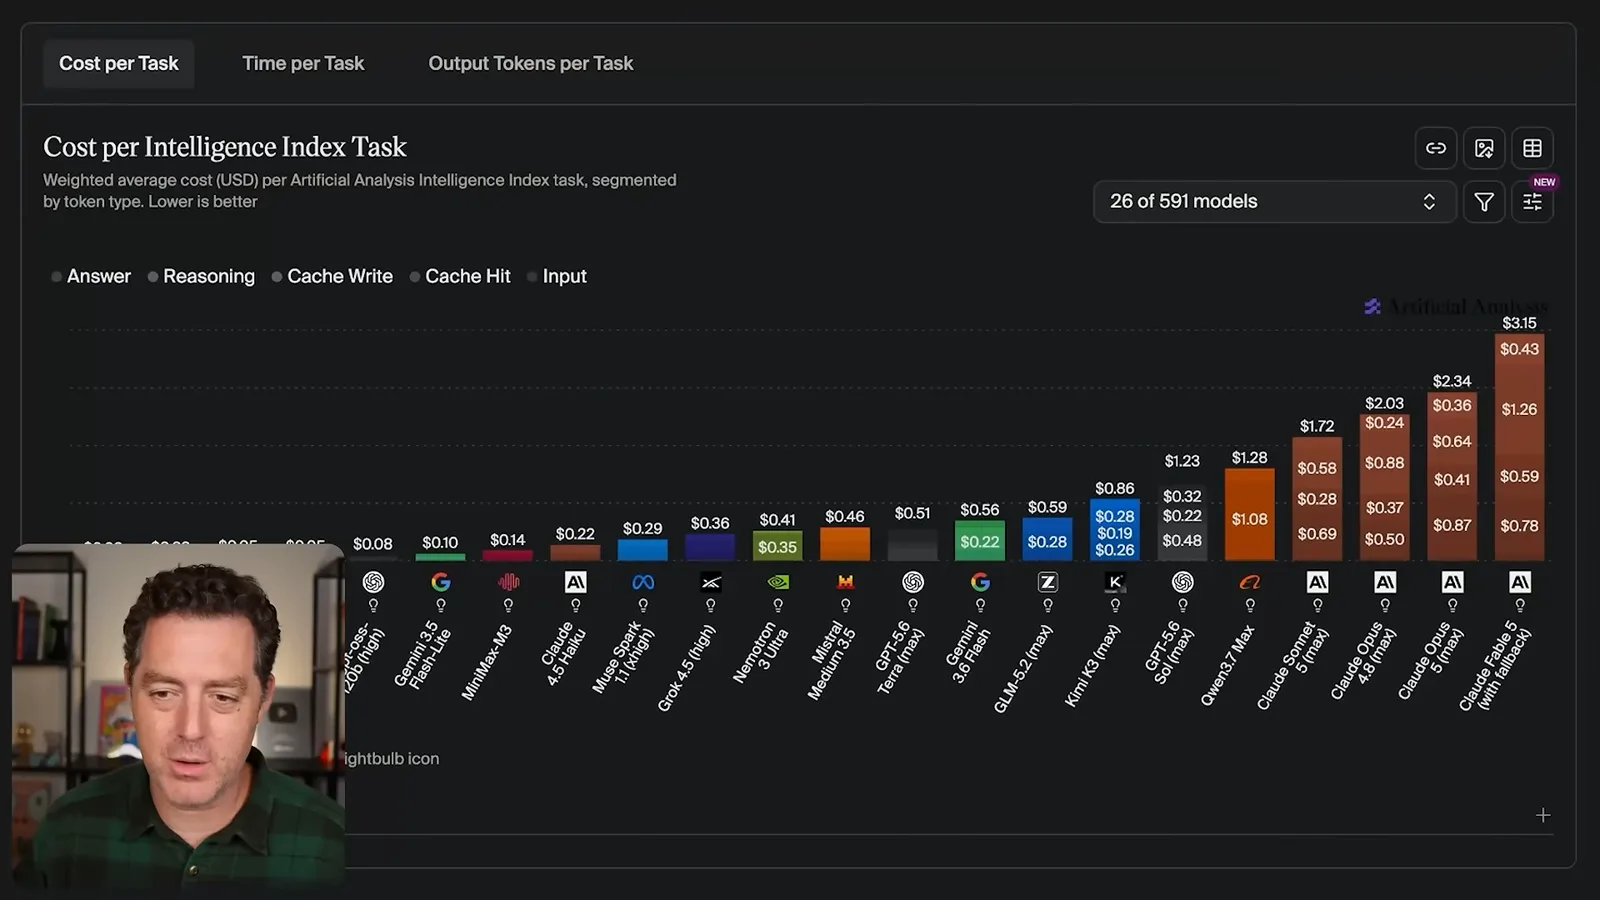
Artificial Analysis has a chart comparing cost per benchmark task. At the time, the new Qwen model had not been evaluated in that chart, so I refer to Qwen3.7 Max at $1.28 and GPT-5.6 Sol at $1.23 per task in the displayed comparison. These figures describe that benchmark and its settings, not every real-world workload.
Open weights and geopolitical tradeoffs
Berman discusses model size, compute and self-hosting options. He values open alternatives but speculates about future dependencies and competitive dynamics.
I return to model size and compute. The large Chinese models I discuss have parameter counts in the trillions, while I have heard rumors that some closed US models may be larger. The rival figures and the size of a future OpenAI model are not verified disclosures, and parameter count alone is not a reliable measure of capability or training cost.
In the short term I welcome strong open-weight alternatives. Depending on the model’s actual license and available weights, organizations may be able to host and adapt a model themselves, gain flexibility and reduce dependence on a single provider. Enthusiasts can experiment as well, although a model of this size can require substantial hardware.
At the same time, I worry about a possible longer-term dependence on Chinese AI. Running available weights on US infrastructure can keep inference local, but I speculate that future models and chips could be tightly co-designed, potentially making a particular hardware ecosystem cheaper or more attractive. That is a scenario, not an established requirement or proof that self-hosting resolves every data and supply-chain issue.
There is a tension in my thinking. Open-weight models can put competitive pressure on closed labs and potentially push down prices. But I also wonder whether companies with strong models and greater compute could use AI-assisted research to improve faster, leaving open alternatives behind. Both outcomes are uncertain.
I point to a reported OpenAI efficiency improvement and price reduction as an example of AI potentially helping optimize AI systems. Even if an individual engineering improvement is real, it does not establish an unlimited self-improving cycle or settle the competitive outcome. I remain convinced that open alternatives matter and leave the broader question open.
Mehr aus diesem Kanal
 34:21EN
 Matthew Berman· 27. Okt. 2026Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 0:36ENMatthew Berman· 25. Okt. 2026Kimi K3.1 and a Rubik’s Cube Solver DemonstrationMatthew Berman · Forward FutureMatthew Berman shows a scrambled virtual cube being solved and gives the Kimi K3.1 test a favorable assessment.
 25:50ENMatthew Berman· 24. Okt. 2026Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.
 32:20ENMatthew Berman· 23. Okt. 2026Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.
 1:03:37ENMatthew Berman· 23. Okt. 2026Matthew Berman’s Team Tests Kimi K3.1 on Animation, Games, and ChartsMatthew Berman, Alex, Brian · Forward FutureA live team AMA turns into an informal test of Kimi K3.1, from personal-agent workflows to motion graphics, a browser game, and a benchmark chart.
 0:53ENMatthew Berman· 22. Okt. 2026Sam Altman on AI and the Discovery of New KnowledgeSam Altman · OpenAIAltman expects progress in mathematical discovery to extend to biology, materials and energy.