In 30 Sekunden
Imec AI lead Steven Latré presents a benchmarking study of coding agents across models, harnesses and hardware. He explains how model quality, GPU memory, concurrency, utilization and harness choice affect the cost of moving from APIs to infrastructure.
- 1Test a specific workloadThe team used long-horizon SWE-bench Pro coding tasks across models, harnesses and hardware.
- 2Hardware cost changes the comparisonModels with similar task performance can require very different GPU configurations.
- 3Concurrency consumes memoryModel parameters and user KV caches must fit while latency remains acceptable.
- 4Utilization changes the economicsThe study reports different break-even levels for smaller and larger systems.
- 5Harnesses affect GPU timeIn one GLM comparison, Codex used about half the tokens and GPU time of the other harnesses.
Das Wichtigste
- Model quality and hardware cost do not change in a smooth linear relationship.
- Concurrency and KV-cache memory can constrain the economics of large models.
- Break-even utilization depends on the system and workload being compared.
- A harness can change token use and GPU time even when task performance is similar.
- The reported savings are specific to the coding workload and study assumptions.
Den bearbeiteten Text nach Kapiteln lesen
From semiconductor research to AI workloads
Latré describes imec and the evolution from APIs toward infrastructure.
I'm Steven Latré, and I lead AI at imec, a Belgian research organization better known for semiconductor R&D than for AI. We work with partners on next-generation chips, but our work extends from transistors to systems and workloads. My role is to connect AI workloads with their infrastructure requirements.
Our own experience with AI agents has gone through stages that may sound familiar. In 2024 and 2025, we focused on using the newest frontier models. As pricing evolved toward token-based usage, we increasingly routed tasks to an appropriate model instead of always choosing the largest one.
Model routing is a useful first optimization, but as token consumption grows, some organizations begin taking more control of the stack. We started with closed APIs, then optimized costs, and are now exploring hosted open-weight models and leased infrastructure, with owning infrastructure as a possible later step.
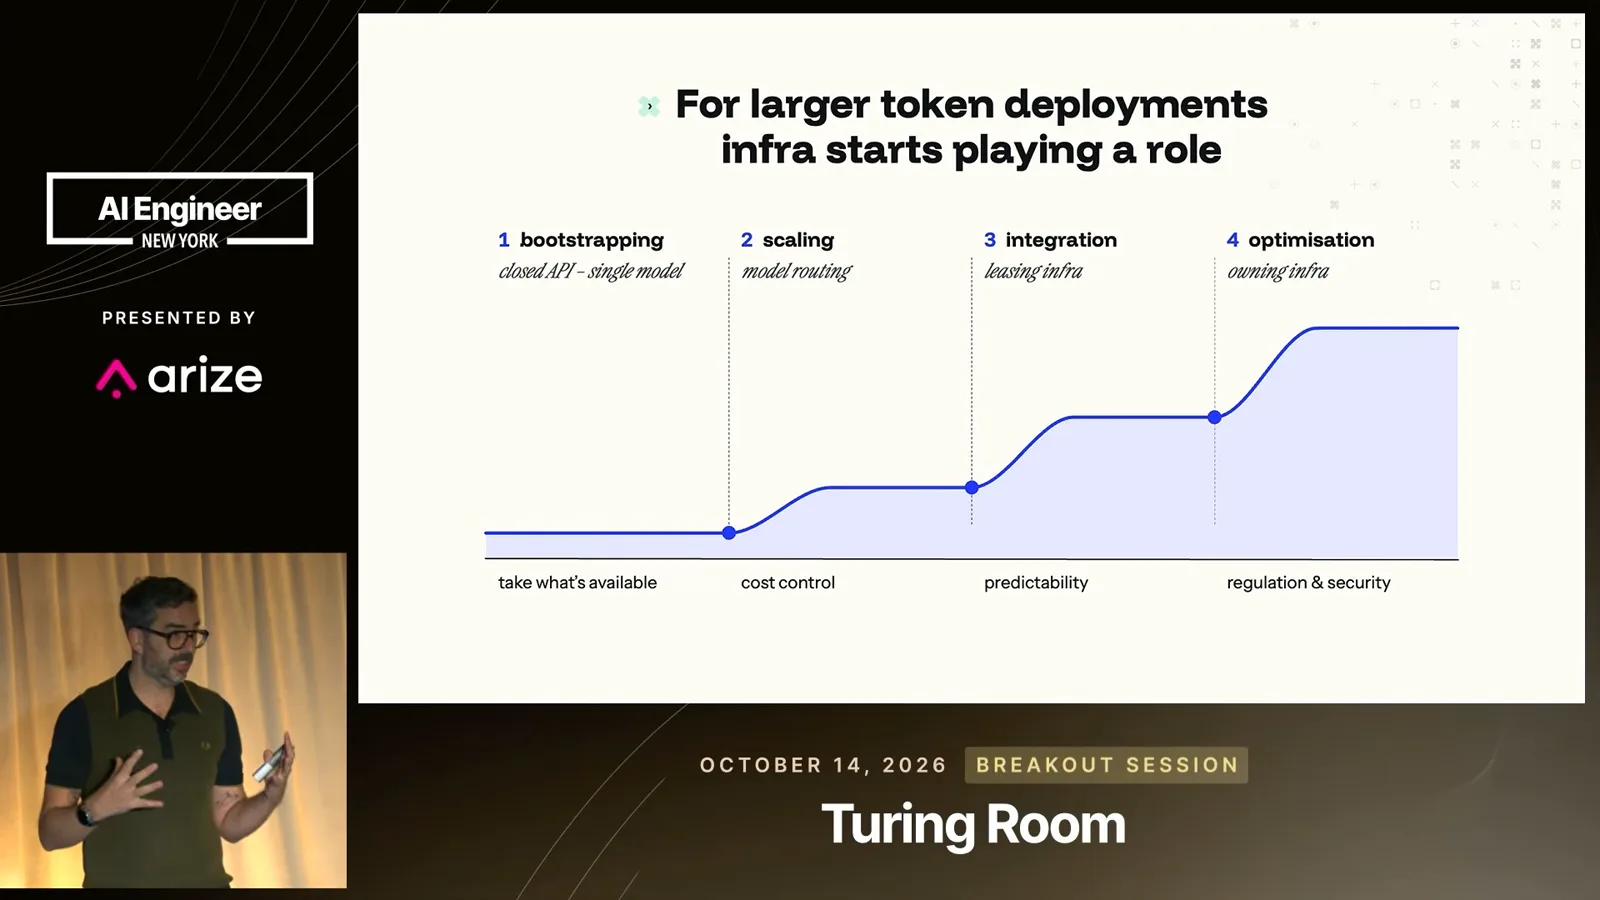
An API is relatively straightforward to consume. Owning more of the infrastructure expands the design space: teams must consider model choice and trust, coding harnesses, hardware architecture, the CPU-to-GPU balance and KV-cache optimization, rather than task accuracy alone.
How the benchmark was designed
The study compares long-horizon coding tasks across models, harnesses and hardware.
Our team ran thousands of benchmark runs to understand the move from API pricing to infrastructure and total cost of ownership for agentic AI. We asked what a given task performance costs and which harness, inference engine and hardware configuration make sense.
We chose long-horizon coding tasks from SWE-bench Pro. Long tasks may be an early fit for dedicated infrastructure; the economics of highly interactive use can differ. We varied coding harnesses, API and open-weight models, model sizes, and hardware configurations that could support concurrent users.
For each setup, we looked at task resolution rate, latency and cost, while increasing both model and hardware complexity. These findings come from one benchmark and workload, rather than a general ranking of all AI deployments.
Model performance and hardware cost
Results show why task quality and GPU costs must be evaluated together.
The models fell into broad performance groups. In our runs, smaller models such as Qwen and DeepSeek resolved roughly 35–40% of tasks. A GLM model performed around the Opus range, while Kimi K3 reached 86%. I noted that some benchmark material may have been in its training data; that possibility is not an established finding.
Adding hardware costs changes the comparison. Qwen and DeepSeek achieved roughly similar application performance in our tests, but their hardware requirements could produce a fourfold difference in GPU rental costs. Moving from GLM to Kimi K3 gave about a 20% improvement in accuracy for around a 15% increase in rented GPU cost in the configurations compared.
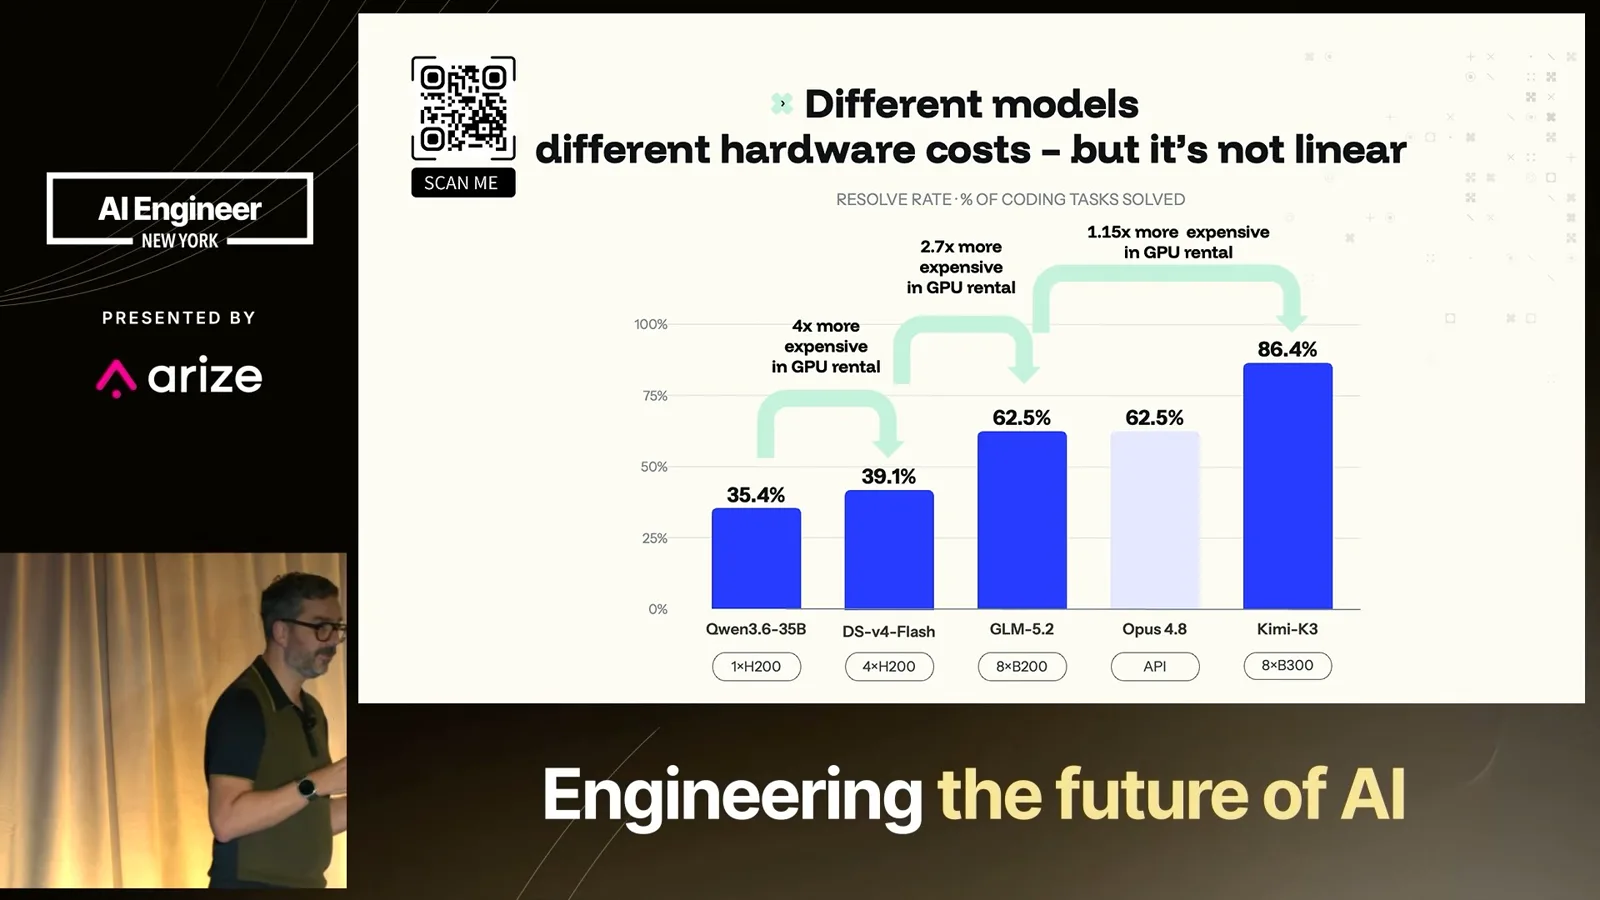
Cost does not follow model quality in a smooth line. It often changes in steps: a slightly different model can require a very different hardware architecture. When choosing open-weight models, evaluate the actual hardware constraints and costs together with task performance.
Concurrency and memory
The number of concurrent users affects KV-cache requirements and latency.
Concurrency introduces another question: how many users can share a machine while keeping latency acceptable? With an API, token latency and throughput are part of the service experience; with your own infrastructure, you have to manage those limits yourself.
Many systems are constrained by memory. Both model parameters and each user's KV cache must fit, and cache requirements grow with the number of users. We therefore tested comfortable concurrency for each model on its own suitable hardware configuration.
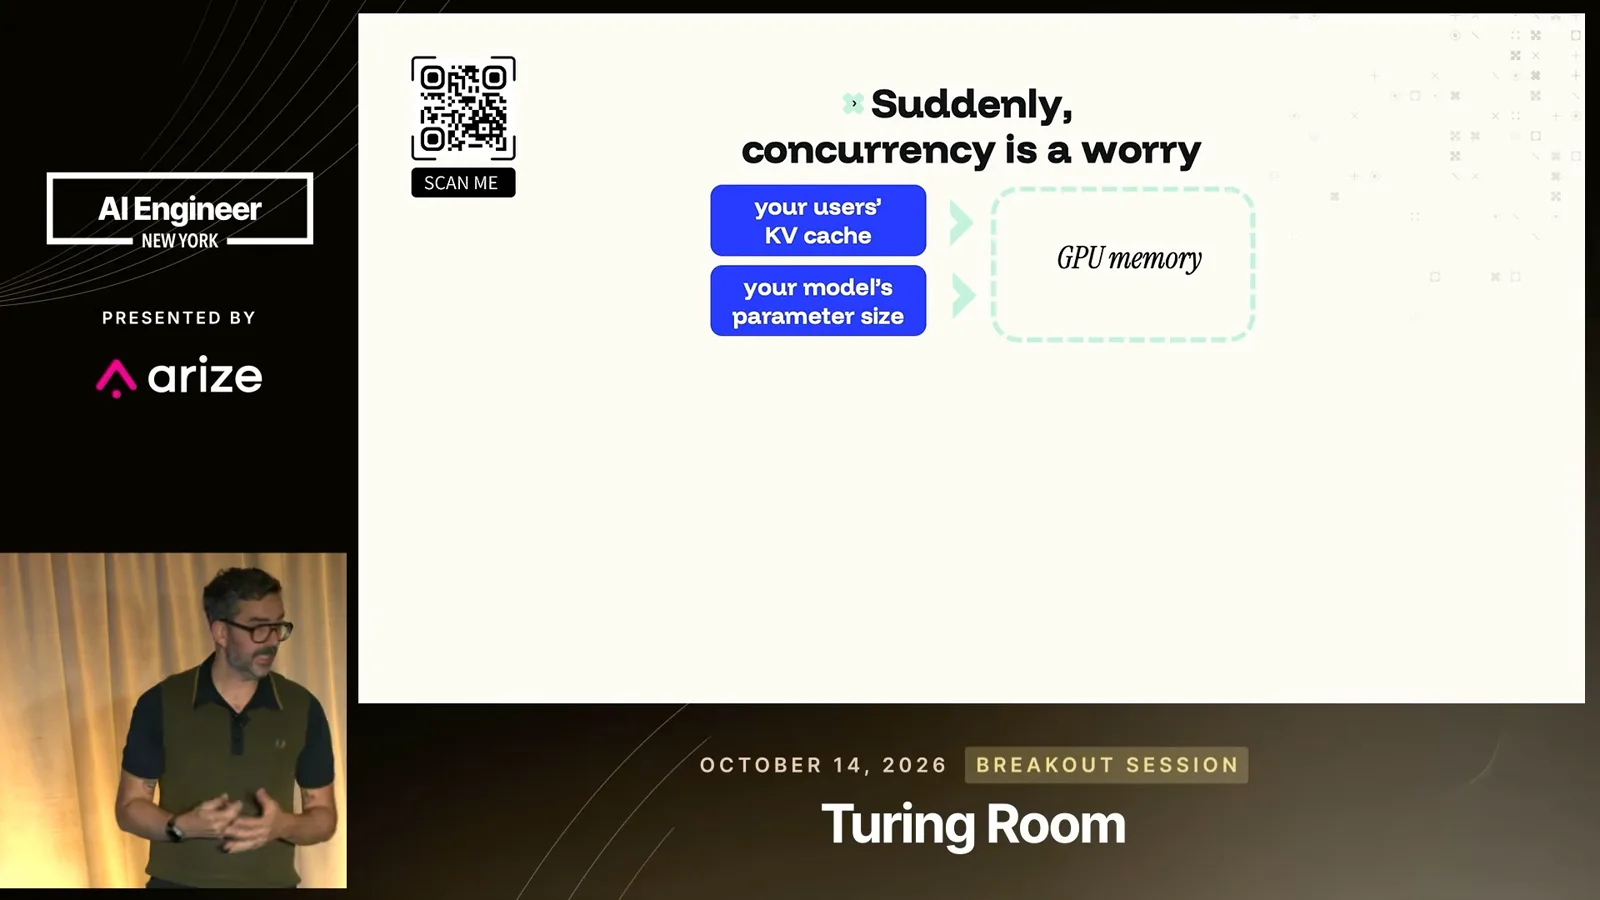
Larger models supported markedly fewer concurrent users, even with larger hardware, and our setups were slower than the Claude Code baseline. For the Kimi K3 configuration on these long-horizon tasks, we found roughly four reliably concurrent users and latency about three times slower than that baseline.
API, rental or ownership
The economic threshold depends on utilization and the configuration.
We next compared API use with GPU rental and purchase from a total-cost-of-ownership perspective. Other considerations can also motivate a move to owned infrastructure; the thresholds I describe concern this particular economic analysis.
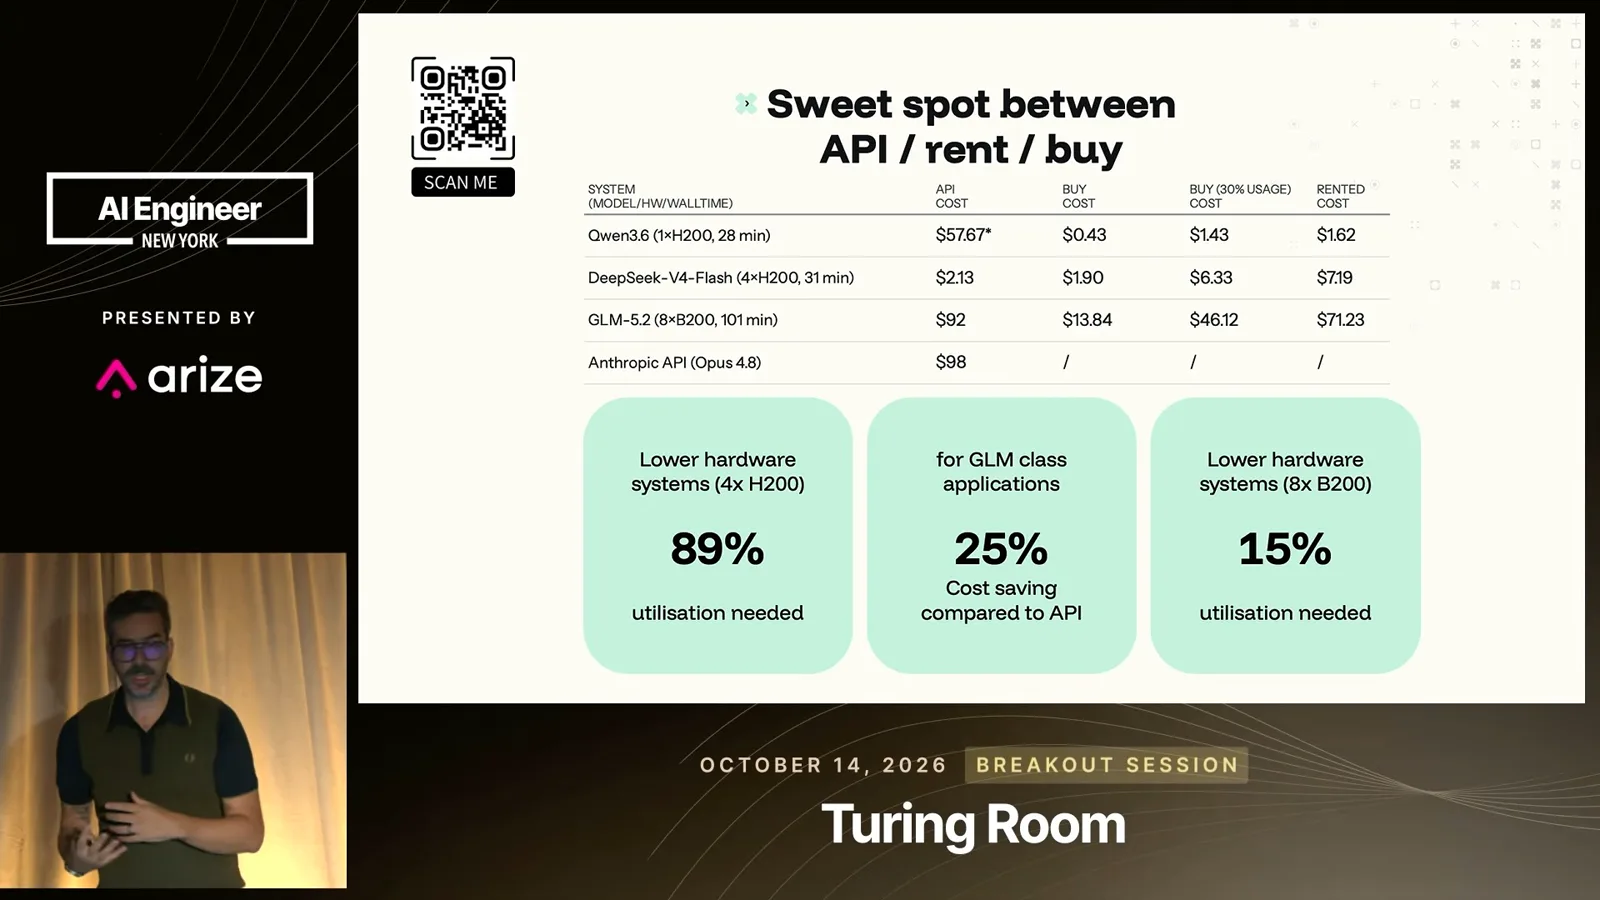
In our lower-end systems, moving away from an API required about 89% GPU utilization to break even: the GPU would need to be busy almost all the time. For a larger system such as eight B200 GPUs, the corresponding utilization was about 15%. The comparison depends on the workload and assumptions behind it.
For a GLM-class coding-assistant workload, our study identified a point where moving from API usage to infrastructure became attractive and estimated about 25% cost savings. This is an estimate for the evaluated application and setup, not a guarantee for every organization.
Why the harness matters
Similar task results can have very different token and GPU costs.
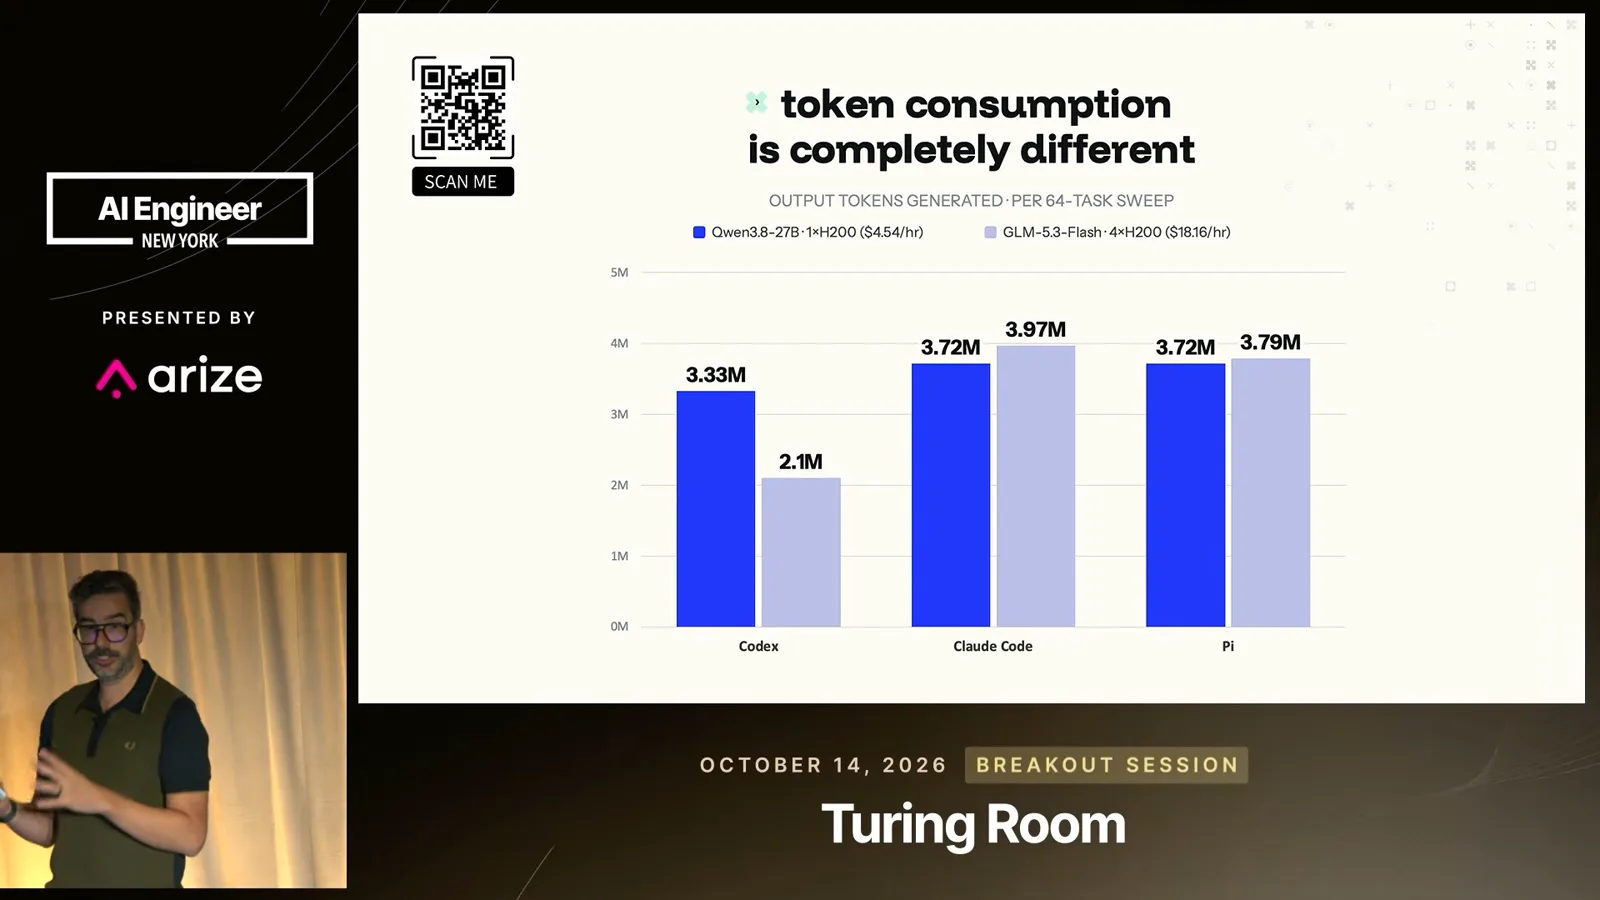
We also varied the coding harness. At first glance, task performance across the three harnesses did not change much for a given model. That might suggest the harness has little impact, but GPU wall-clock time becomes important when you pay for your own infrastructure.
Different harnesses consumed very different numbers of tokens. In the GLM case, Codex generated about half as many tokens and used about half the GPU wall time as the other harnesses in our comparison. Similar task performance therefore did not mean a similar GPU bill.
Limits of the study and next steps
The team plans a public benchmark and an alliance across software and hardware.
This is an initial study of one application. Real enterprises mix many workloads, which makes the decision more complex. We have not fully unpacked quantization or optimizations such as speculative decoding, and models and hardware are changing continuously.
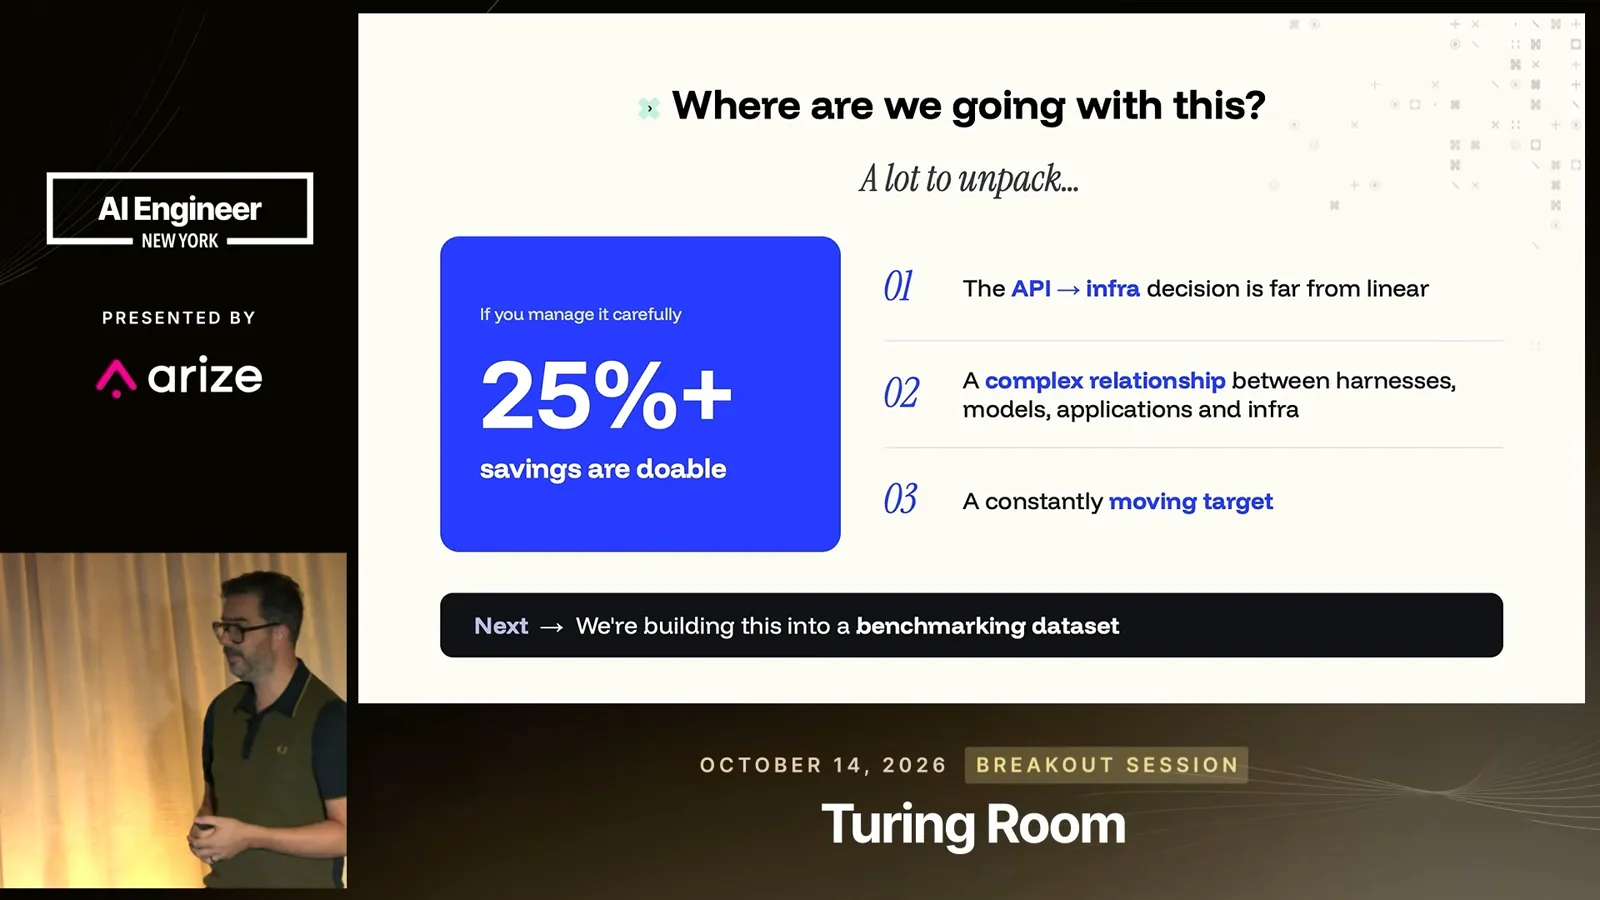
We are expanding the benchmarking pipeline into a public data set to track that moving target. As a nonprofit research organization, imec is also forming an alliance to bring software practitioners together with chip and infrastructure providers, because the two sides need to work more closely.
Mehr aus diesem Kanal
 14:44EN
 AI Engineer· 31. Okt. 2026Supriya Subudhi on Five Lessons From A/B Testing AI at BumbleSupriya Subudhi · BumbleA positive test is only the start: usage, output quality, model cost and regulation all shape whether an AI feature can scale.
 17:02ENAI Engineer· 31. Okt. 2026How Upstart Evaluates Voice Agents for Regulated Lending CallsBrooke Hopkins, Shiv Indap · CovalShiv Indap and Brooke Hopkins explain human review, LLM judges and simulation in a continuous evaluation loop.
 18:45ENAI Engineer· 30. Okt. 2026Jack Woodruff on AI and the Human Work of Stock PickingVinoo Ganesh, Jack Woodruff · KeplerThe former Candlestick Capital CIO discusses research, auditable data and how AI may reshape investment teams with Kepler CEO Vinoo Ganesh.
 15:27ENAI Engineer· 30. Okt. 2026Rayan Krishnan on Model Evaluation Beyond the Model CardRayan Krishnan · Vals AIThe Vals AI cofounder explains why task-level accuracy, total cost and company-specific evaluations can change which model is the best fit.
 19:06ENAI Engineer· 30. Okt. 2026Wojciech Pluta on Deciding What an AI Agent Should RememberWojciech Pluta · OracleOracle’s Wojciech Pluta explains memory promotion, a mortgage-agent demonstration, and the controls needed to carry useful information across sessions.
 16:43ENAI Engineer· 30. Okt. 2026Ishween Kaur on Securing Agent Payments with x402Ishween Kaur · SoFiA testnet walkthrough of price changes, replay, premature delivery, lookalike sellers and prompt injection in agent payment flows.