30초 요약
Theo describes how he used model reviewers to iteratively polish T3 Code’s interface and compare it with reference apps. He also turns historical MCP tool failures into a more measurable evaluation and uses it to reduce tool-description context.
- 1The review panelSeveral model reviewers critique screenshots and propose iterative changes.
- 2Noisy scoresTheo notes that repeated ratings and comparison context can change subjective results.
- 3Human directionA concrete request to restore color changes the direction of a later iteration.
- 4A measurable hill climbHistorical tool failures become an evaluation for shortening MCP descriptions.
핵심 정리
- Repeated screenshots and specific feedback can make incremental interface changes easier to inspect.
- Model-assigned design scores are noisy and can shift with prompts and reference context.
- A human can guide the process with concrete preferences and visual review.
- Historical failures can become a test suite for a more measurable optimization loop.
- Runtime and token-cost estimates depend on the models and pricing actually used.
챕터별로 다듬은 전문 읽기
A design experiment
Theo responds to UI criticism and describes the iterative review process.
Theo responds to criticism of T3 Code’s interface. The open-source project does not have a full-time designer, and he agrees that its visual and user-experience polish needed work.
He asks whether coding agents can improve a real application’s design through repeated evaluation. His experiment runs across several models and many review rounds, with an early version of the new interface available behind a beta setting.
The project began with a user’s comments about typography, corner radii, icons and visual hierarchy. Theo gave an agent the feedback and asked it to create a pull request, iterate and obtain high scores from a group of model reviewers.
His review skill delegates the same brief to several models, asks for read-only feedback and scores, and collects disagreements and next steps. He had used a similar process for code review but had not previously tested it on subjective interface design.
Unlike a performance benchmark or a passing test, visual quality has no stable programmatic score. Theo notes that the same model can give the same screenshot different scores on different runs; the ratings are noisy judgments, not objective measurements.
Comparisons and score variability
Annotated screenshots and competing references change the feedback and scores.
The initial interface received scores around six out of ten. After the agent made changes, the reviewers’ scores rose. Theo requested annotated before-and-after screenshots because the subtle differences were difficult for him to see at a glance.
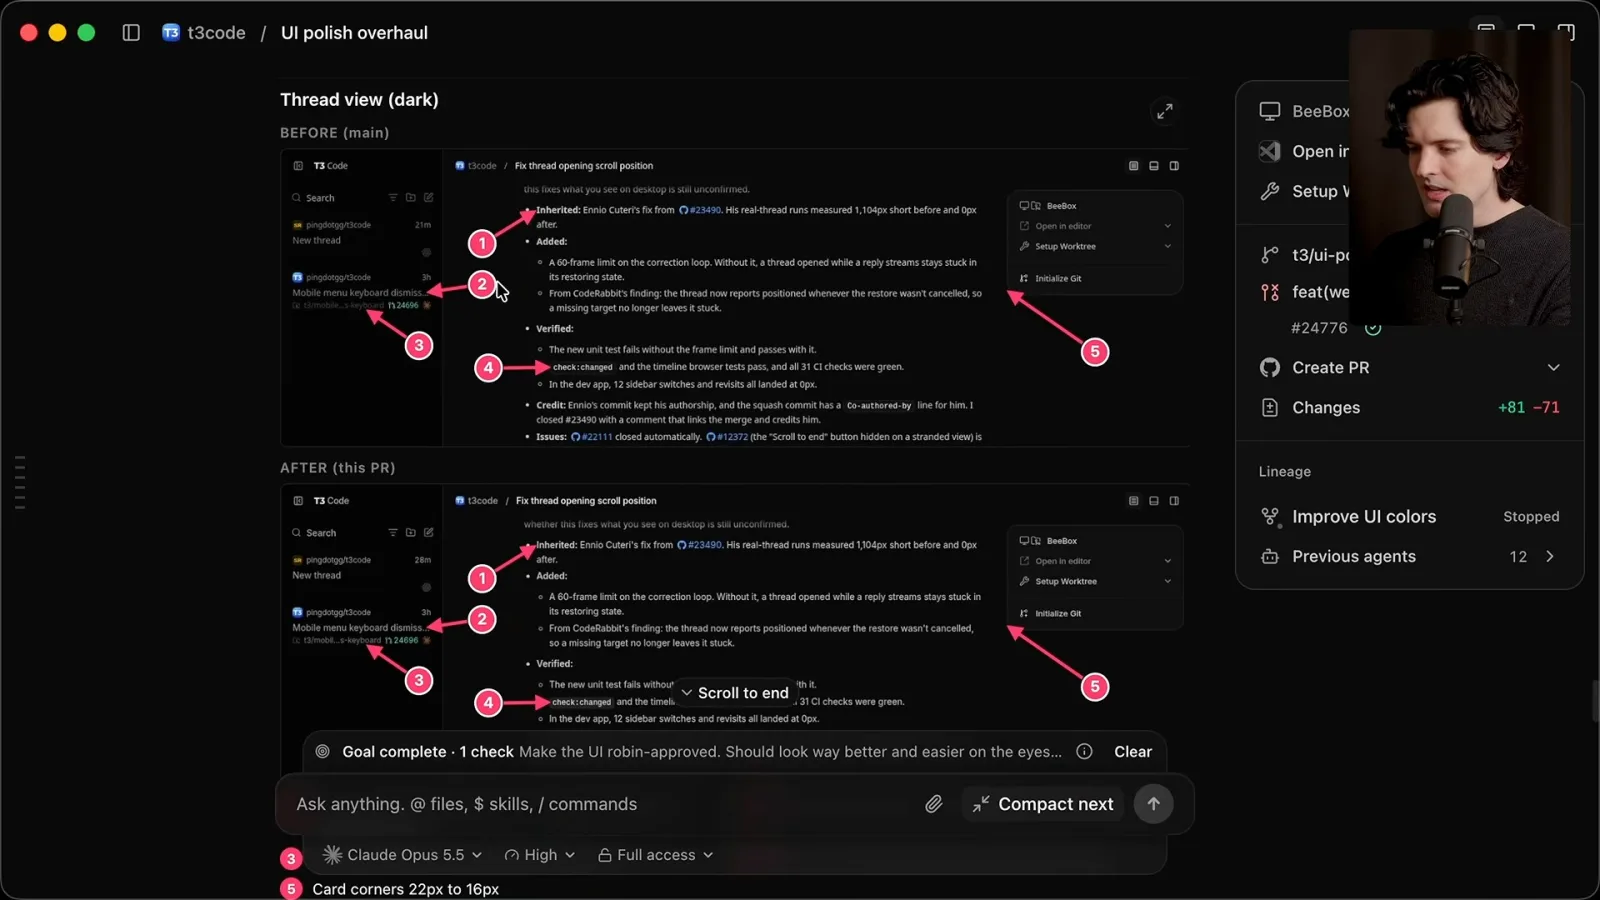
The comparison highlighted changes to fallback fonts, title hierarchy, branch-name truncation, card corners and inline-code styling. The review panel eventually rated the result at the target level, but Theo’s own comparison with other apps left him unsatisfied.
He started a fresh review and added screenshots of Claude Code and Codex as reference products. His goal changed from improving T3 Code in isolation to comparing it with those interfaces. The longer run took almost eighteen hours, according to his account.
The new context changed the scores substantially: a version previously rated nine was rated only slightly better than the original in the new comparison. Theo treats this as evidence that prompts, reference images and context affect subjective ratings.
He also observed scores for the unchanged reference screenshots rising during later rounds. That inconsistency reinforces the danger of treating the numbers as calibrated measurements, even if the feedback can guide iteration.
To control usage, he initially asked one model for reviews and brought the other reviewers back only when the first score was high enough. The changes improved consistency in labels, font and border treatments, sidebar hierarchy and light-mode contrast.
More iterations and costs
He raises the target, discusses possible score bias and reports runtime and cost estimates.
Theo forked the work into another worktree and raised the target to 9.5 in each category. The agent continued making changes and seeking reviews; one reviewer disagreed with the others after the first model reached the threshold.
He recognizes a possible source of bias: reviewers knew the target score, and the same reference screenshots received different ratings over time. He considers hiding the target from reviewers in future experiments.
A modest increase in the target required about ten additional rounds. Theo reports roughly 17.6 hours of parallel agent runtime and an estimated total near $400 across the broader experiment, with uncertainty around subscription-based model costs.
He later separates roughly $150 for an additional refinement run from the work shown so far. The estimates are his accounting of this experiment, not a promise of what another user’s subscription or API usage will cost.
In a further run he asked for ten out of ten and provided a concrete preference: restore color because the previous result felt too gray. He preferred the resulting contrast, more visible icon and clearer merge button.
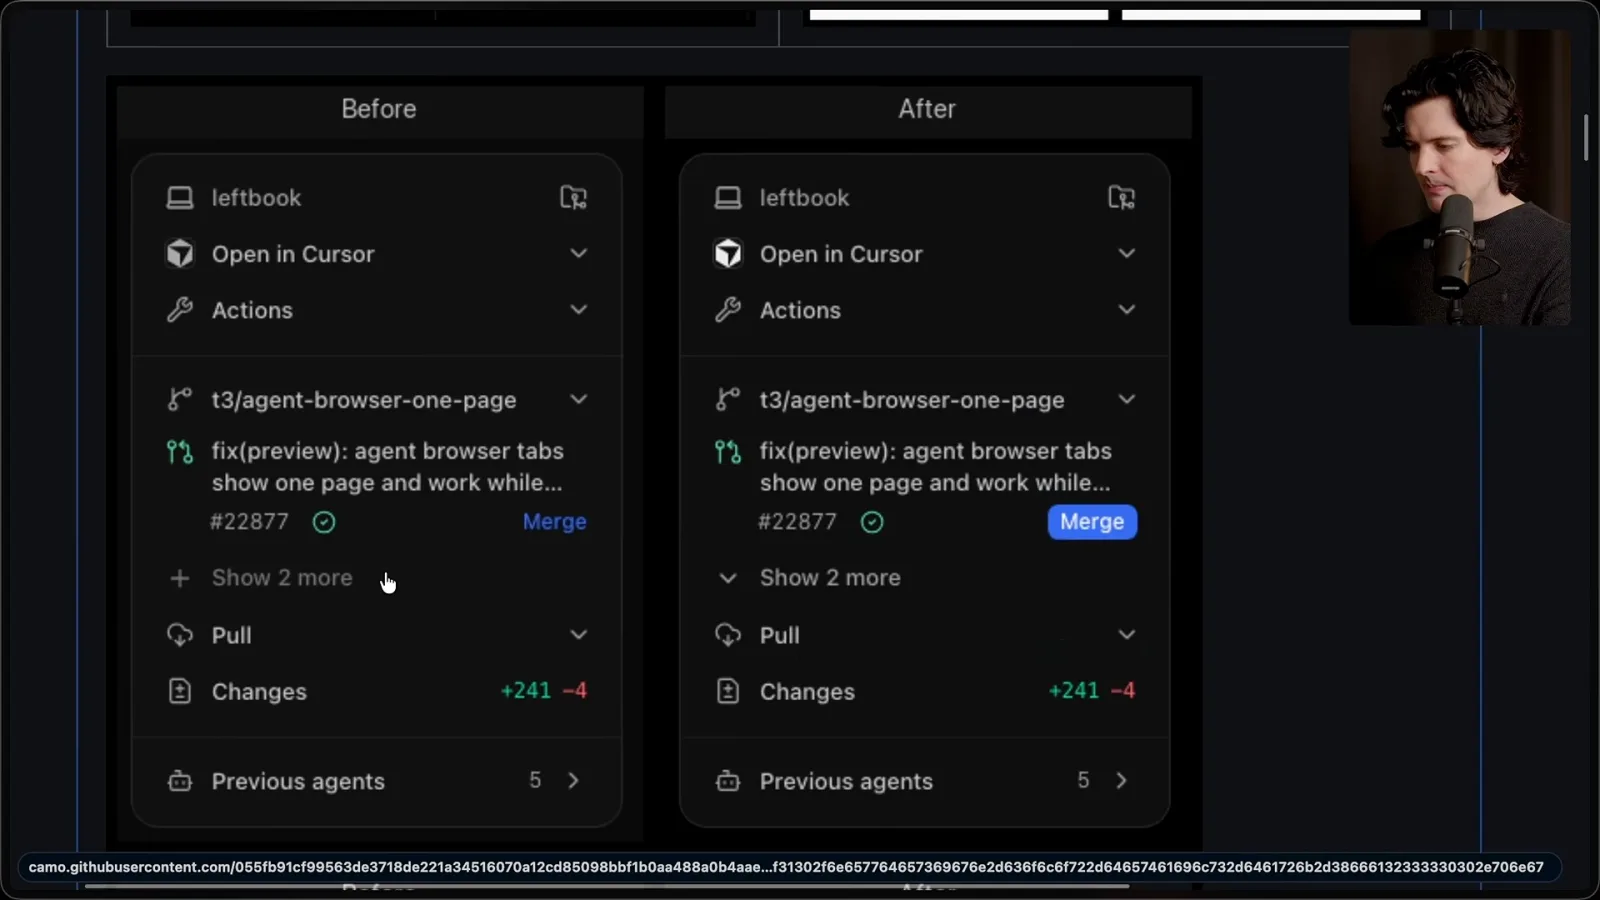
Theo’s takeaway is to make an iterative process explicit: compare the new screenshot with prior and reference versions, identify issues, revise and review again. His own visual inspection remains part of the assessment despite the model scores.
Testing MCP descriptions
A suite of historical failures enables a more concrete optimization of tool context.
He then describes a more directly measurable hill climb for T3 Code’s MCP tool descriptions. He collected examples where models used the wrong tool or handled a thread incorrectly, categorized them and turned the cases into an evaluation.
An initial model run passed roughly 60 of 88 collected cases. The agent developed a larger evaluation from those failures. Theo notes that the evaluation had not yet been merged at the time he discussed it.
The scores sometimes fell after changes, which helped expose regressions. He asked the agent first to achieve the desired test results, then to shorten the tool descriptions substantially while preserving those results.
He reports that the resulting descriptions used substantially less context, including reductions of 52% and 78% in two configurations. He says the changes were available in a nightly build, with a stable release planned.
Theo cautions that model behavior remains nondeterministic. Even so, he finds agents useful for tedious work such as categorizing historical failures and repeatedly testing changes—work he says would have taken him far longer by hand.
He closes by encouraging engineers to express problems as measurable objectives where possible and iterate against them. The UI example illustrates the potential and limits of subjective model reviewers; the MCP example uses a more concrete test suite.
같은 채널의 다른 글
 15:50EN
 Theo - t3․gg· 2026년 11월 3일Theo Compares Codex and Claude Subscription Value After Limit ChangesTheoTheo looks at estimated allowances, per-task costs and his own review experiments, while arguing that model quality remains decisive.
 16:46ENTheo - t3․gg· 2026년 11월 2일Theo Browne on Claude Ultra, Five-Hour Limits and SDK UsageTheo Browne · Ping LabsA breakdown of the renamed subscription tier, verification and reported differences between interactive and SDK usage.
 49:29ENTheo - t3․gg· 2026년 10월 30일Theo on Agent Harnesses, Interfaces and Shifting AbstractionsTheo · T3 CodeThe T3 Code creator explains his model of harnesses and why he expects their differences to become less visible to users.
 41:49ENTheo - t3․gg· 2026년 10월 29일Theo Demonstrates T3 Code for Coordinating Coding AgentsTheo · t3.ggThe T3 Code creator walks through multiple agent providers, remote machines, thread organization and the tradeoffs of an open-source coding interface.
 38:47ENTheo - t3․gg· 2026년 10월 28일Theo’s Long-Running Agent Experiments: Verification, Compute and CostTheo Browne · Ping LabsA skateboard game and two compiler projects show how repeated checks and flexible compute can sustain agent work—and how expensive those loops can become.
 36:07ENTheo - t3․gg· 2026년 10월 27일Theo on Token Costs, Coding Agents, and the Price of AI CapabilityTheo Browne · Ping LabsA viral estimate of Lauren's AI spending prompts a closer look at cache pricing, benchmarks, and the changing work of coding agents.