30초 요약
Theo reacts to a report that Anthropic expected its first operating profit and examines possible drivers of AI revenue growth. He discusses cloud access, pricing, compute and Simon Willison’s product–market fit argument; many of his explanations are hypotheses rather than verified financial disclosures.
- 1A forecast, not a completed resultThe reported $10.9 billion quarter and operating profit were expectations described to investors.
- 2Run rate versus revenueThe chart shows annualized snapshots rather than full-year realized revenue.
- 3Cloud economics are uncertainTheo’s revenue-share and infrastructure theories are not established financial disclosures.
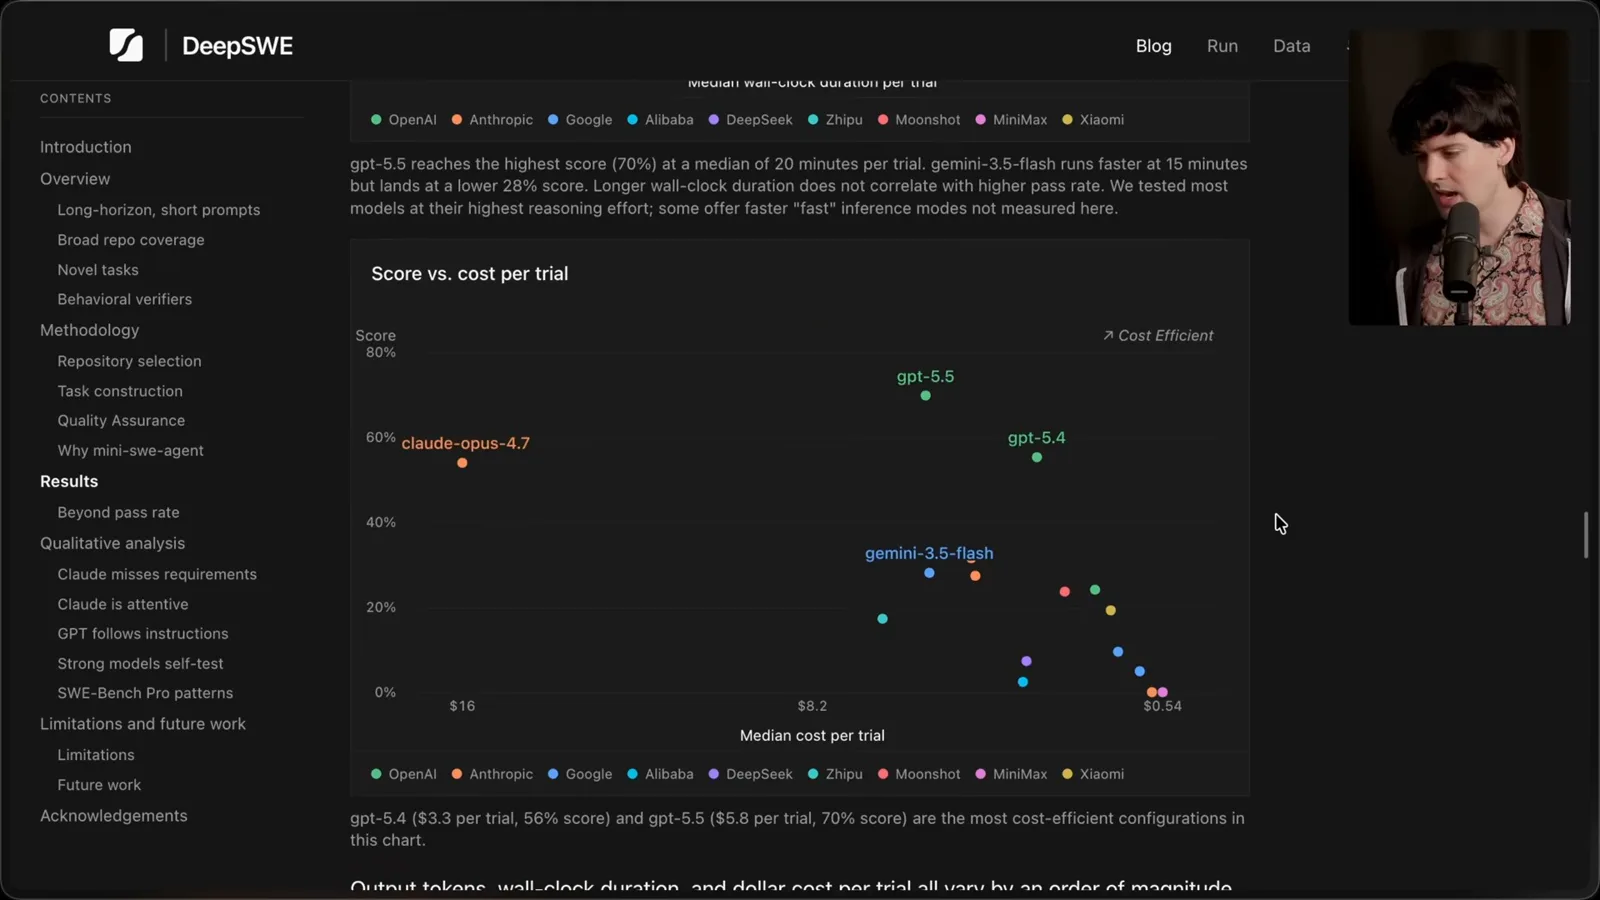
- 4Costs depend on the taskA benchmark shows median token use and cost for selected configurations, not every customer’s bill.
- 5A product–market fit argumentTheo discusses Simon Willison’s interpretation of enterprise agent demand.
핵심 정리
- The reported quarterly operating profit was a forecast, not a verified completed result.
- An annualized revenue run rate is not the same as full-year realized revenue.
- Cloud revenue shares, actual compute costs and company margins are not established in the video.
- A subscription fee and an API-equivalent token estimate measure different things.
- Demand and pricing may suggest product–market fit, but do not guarantee sustained profitability.
챕터별로 다듬은 전문 읽기
A reported profitable-quarter forecast
Theo discusses an expected operating profit and quarterly revenue. The report is a forecast rather than a completed result.
Anthropic has reportedly told investors it expects about $10.9 billion in second-quarter revenue and its first operating profit. That is a forecast reported in the article shown in the video, not a completed, audited quarterly result. Even if achieved, a profitable operating quarter would not by itself establish net profit, positive cash flow or lasting profitability.
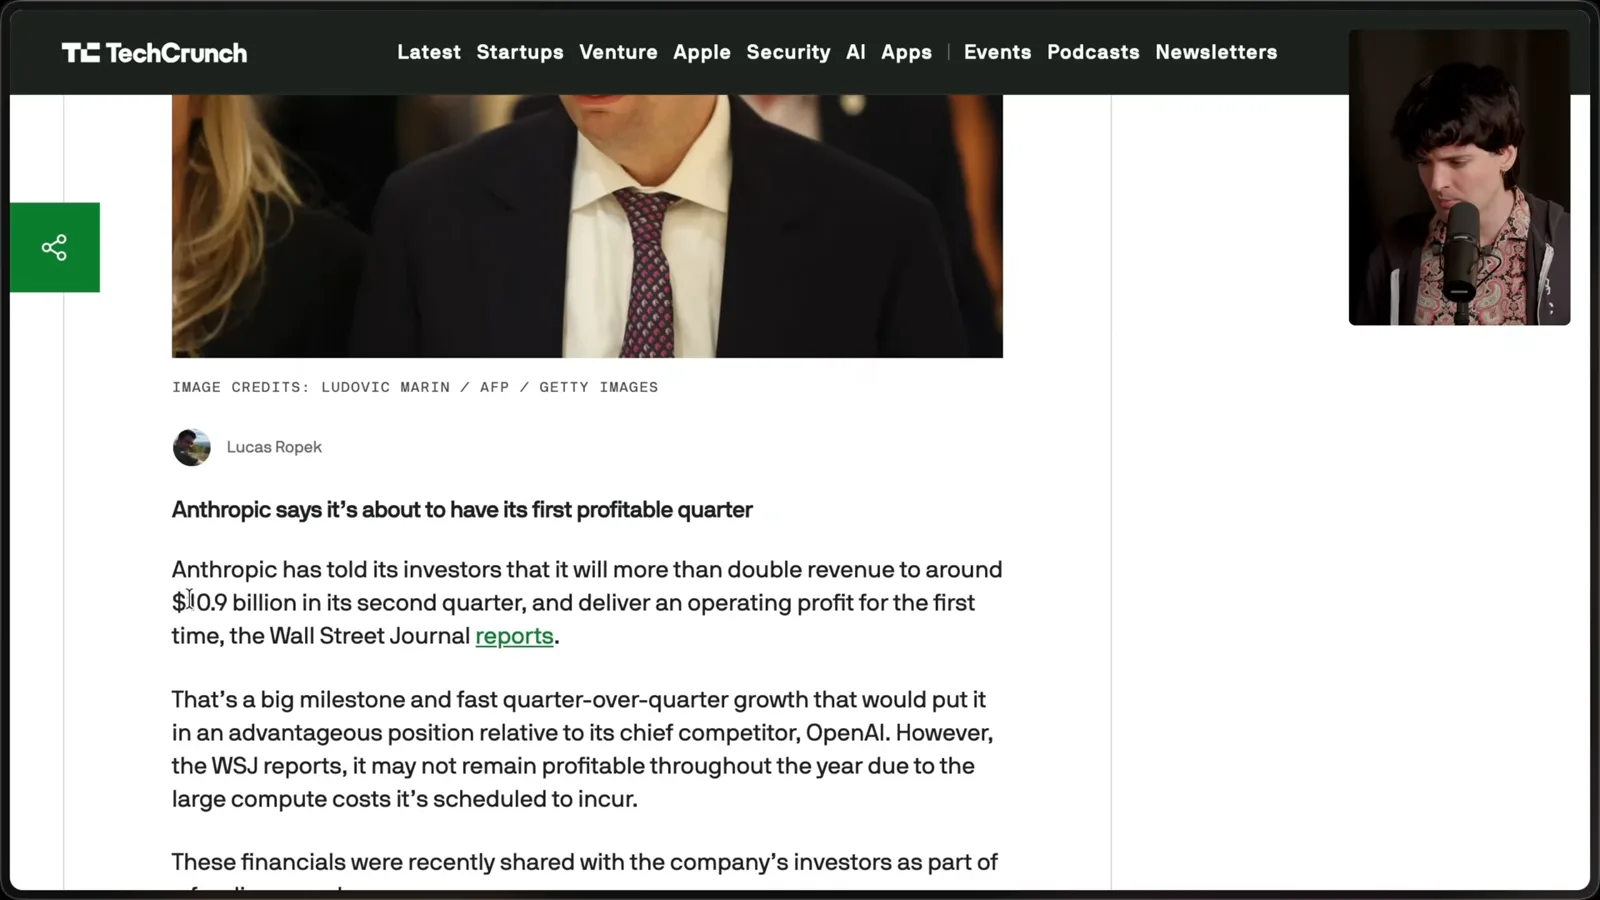
I did not expect the reported turning point so soon. My question is how revenue, enterprise distribution and computing costs might interact, and what the news says about demand for AI products. My explanations are hypotheses based on public reports and personal experience, not access to a complete set of company accounts.
Valuation, revenue and distribution
He examines reported run rates, funding and cloud access. The financial terms and their contribution remain uncertain.
I discuss reports of a new funding round and a much higher valuation than an earlier round. Fundraising terms and valuation are reported or proposed figures, not realized revenue or profit, and may change. Rapid changes in a private-company valuation do not tell us by themselves whether the business is financially sustainable.
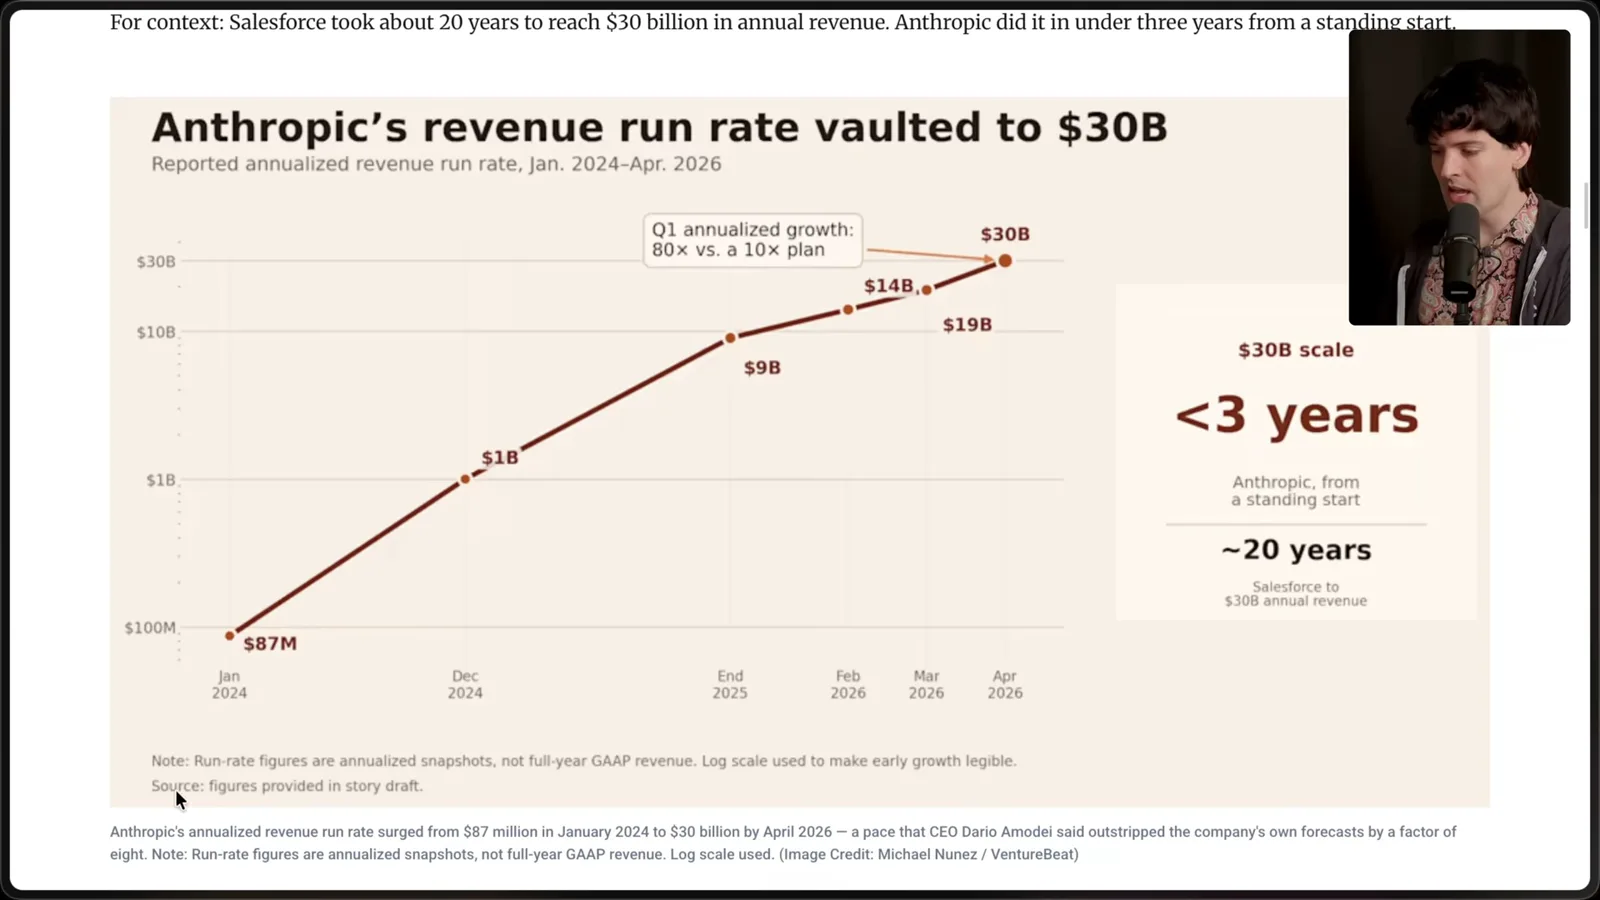
The chart I show tracks reported annualized revenue run rates, rising from $87 million in January 2024 to $30 billion in April 2026. A run rate extrapolates activity at a point in time; it is not the revenue actually earned over a full year. The chart uses a logarithmic scale, and the figures are reported estimates.
I compare that growth with reported spending on compute, including a figure I cite for a SpaceX agreement. The terms, timing and actual payments of such agreements matter, and I do not establish them fully in this video. A reported commitment should not automatically be treated as an expense already incurred in the same quarter.
One possible source of demand is distribution through major cloud platforms. I argue that making Claude models available where enterprises already buy infrastructure can reduce friction. My confidence in AWS partly reflects my own experience working at a company that used it, and the market-share numbers and comparisons I cite are estimates.
I discuss availability through AWS, Google Cloud and Azure as it was described at the time, contrasting that with OpenAI’s distribution. Hosting arrangements can differ from access through a reseller or a routed service, and they change over time. My broad claim that enterprises effectively had only one option is an opinion and oversimplifies a market with multiple choices.
I speculate that cloud agreements may give Anthropic attractive revenue shares while cloud partners provide some infrastructure. The exact economics and the share I mention are not established by the video. A revenue share is not pure profit: research, staff, infrastructure commitments and other costs still matter.
Capacity and pricing
Theo considers Claude Code demand, model tiers and tokenization. He presents several hypotheses about costs and restrictions.
Claude Code adds another demand channel. Developers who use it personally may advocate for the same models at work, potentially increasing enterprise adoption. I also speculate about competition between serving customer requests and allocating compute to research; the company’s internal allocation decisions are not demonstrated by my examples.
The video includes a satirical clip about cloud AI hardware. I use it to illustrate a view that some researchers prefer Nvidia’s ecosystem, but satire and my generalizations are not evidence of the reliability of any particular chip or the preferences of all researchers.
I interpret usage limits and product restrictions as responses to scarce capacity. That is my theory about company incentives; the video does not establish the internal reasons for each policy. Limits can also reflect security, fairness, cost control or other operational considerations.
My next argument is about effective pricing. Anthropic previously had Haiku, Sonnet and Opus tiers, and I believe many developers moved work that once used Sonnet to the more expensive Opus tier as capabilities changed. A lower listed price for one model name does not necessarily mean that a customer’s total bill for a changed workflow falls.
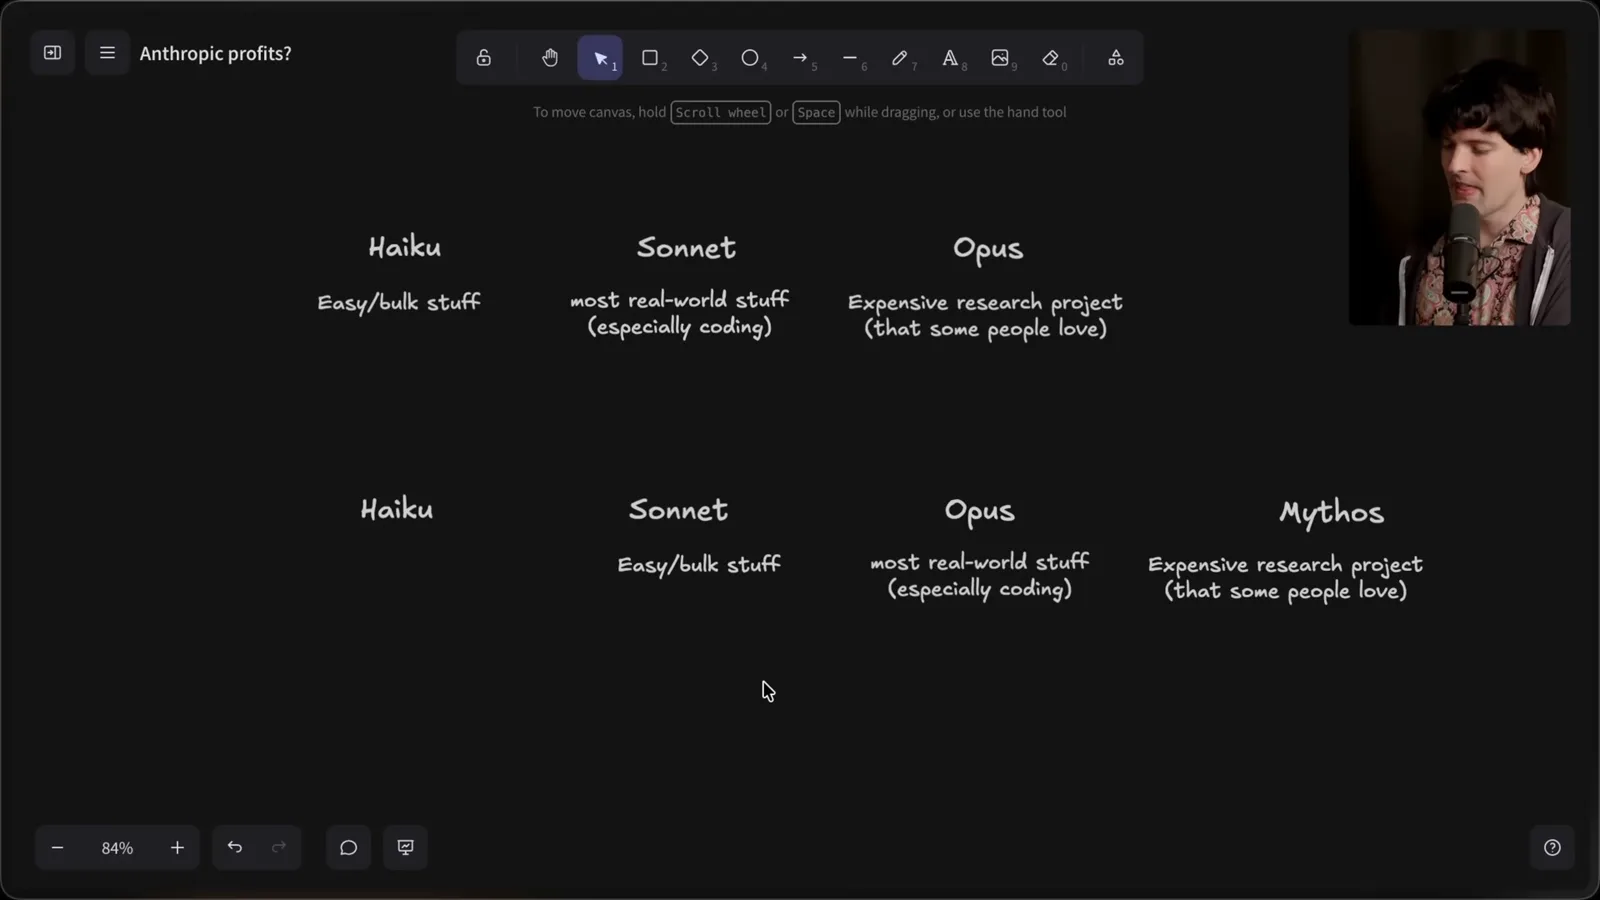
This comparison is about which model I think customers choose for a job, not a direct price increase for an unchanged product. Model capability, output quality and usage patterns also change. A proper cost comparison needs the same task, success criteria, token counts and the prices applicable to the customer.
I raise a concern that a tokenizer change can split the same text into more billable tokens. The size of that effect depends on the text and on both input and output billing; a 30–50% change for a particular comparison is not a universal increase in every customer’s bill. The total task cost also depends on how much the model generates and whether it succeeds.
An unsuccessful agent run can be expensive if it keeps exploring or retrying without resolving the problem, while a quick successful run may use fewer tokens. That is not a rule that every wrong answer costs more than every correct one. Limits, early stopping and evaluation of cost per successful task are useful considerations.
Usage and profitability
Benchmark-specific costs and hypothetical customer growth illustrate possible revenue drivers. Actual company economics require more evidence.
I cite DataCurve’s DeepSWE chart comparing success rates, output tokens and costs for particular model configurations. I am an investor in DataCurve, which is relevant context. The chart reports medians per trial; its numbers are benchmark-specific and cannot establish what every customer pays or how every task performs.
My hypothesis is that revenue can rise through more customers, more tasks per customer and higher spending on each task. Those factors could compound, but the hypothetical arithmetic is not evidence of Anthropic’s actual customer mix or the contribution of each factor to its revenue.
I also suggest that developer adoption can spread into companies: a person tries a model, finds it useful, and asks to use it at work. That is a plausible adoption path I have observed, but individual stories do not quantify how much it contributed to a company’s revenue.
Revenue is only half of profitability. Anthropic must also pay for compute, staff and other operations, and investment or contractual commitments can affect later periods. I speculate that constrained compute supply and relatively conservative commitments slowed cost growth, but the timing and accounting of those costs are not established by the video.
The reported possibility of an operating profit is therefore interesting, but I cannot conclude from it that profitability has already occurred or will continue. The article shown itself warns that future compute costs could affect later quarters. My causal explanation about capacity and pricing remains a hypothesis.
Product–market fit and enterprise pricing
Theo discusses Simon Willison’s analysis of demand and pricing. He distinguishes subscription use from API-equivalent estimates.
I turn to product–market fit: whether a product meets a market need strongly enough that people keep adopting and paying for it. Simon Willison argues that Anthropic and OpenAI have found it in coding and general-purpose agents. Strong spending can support that interpretation, but it is not a guarantee of durable demand or profit.
Willison compares the API-equivalent value of his personal usage with the subscription fees he paid. These are estimates based on list prices, not the providers’ actual cost to serve him. Individual subscription allowances, enterprise contracts and usage-based charges have different terms and can change.
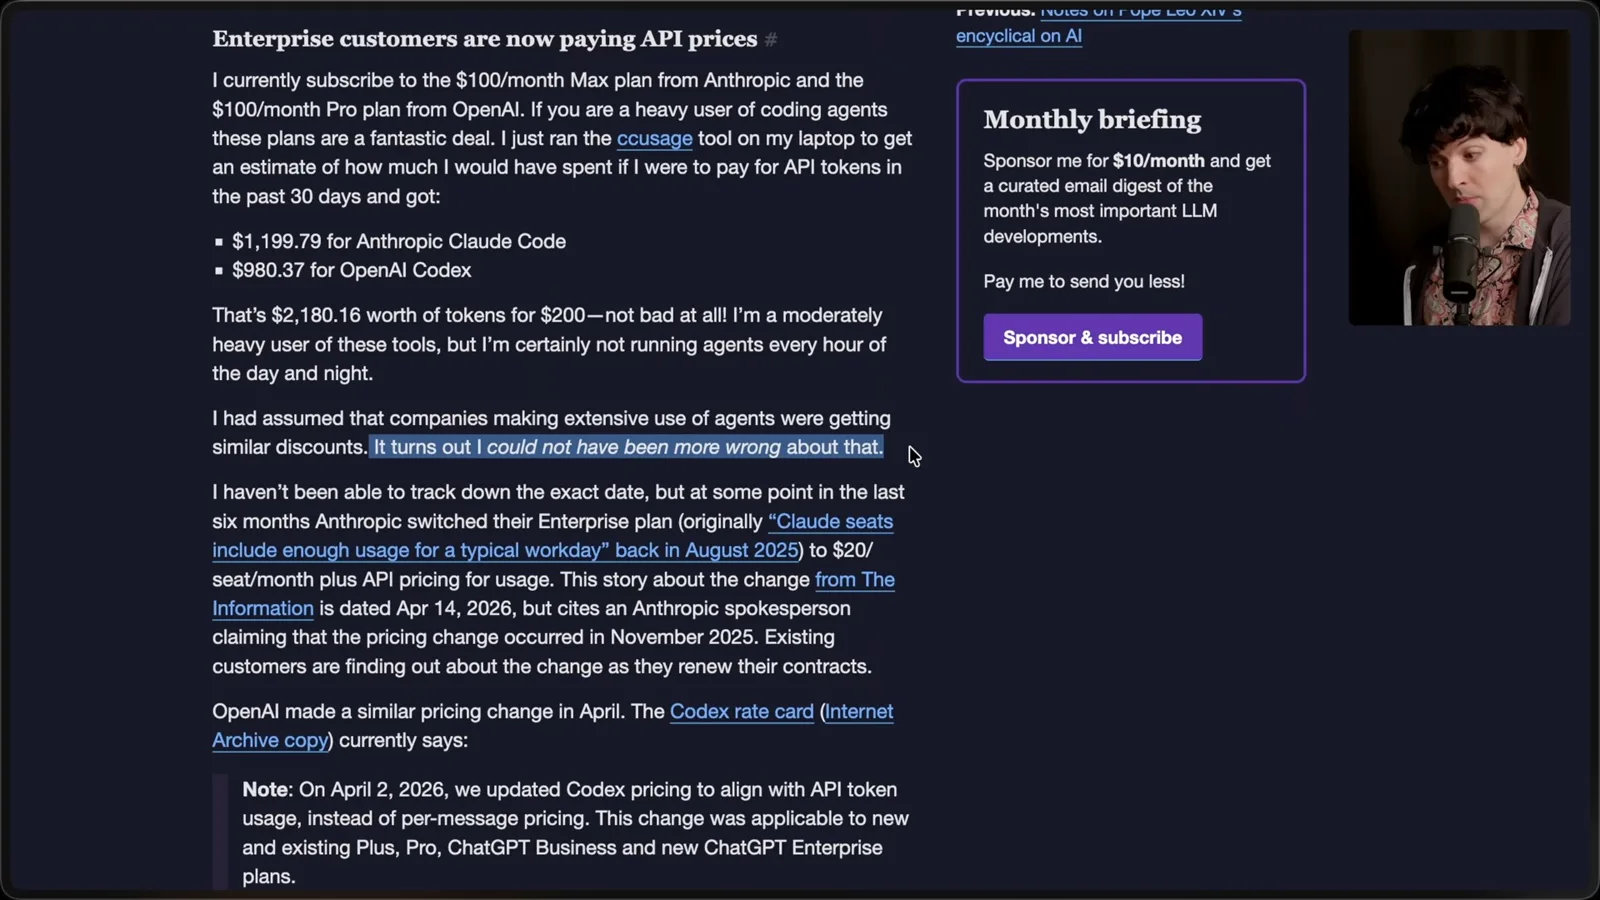
The article describes enterprise pricing that combines seats and usage charges and compares it with OpenAI’s credit-based pricing as understood at that time. I add my own experience of negotiating limited discounts. These are historical descriptions and individual experiences; customers should inspect their actual contracts and current rate cards.
I mention rumors of very high inference margins, but neither the company’s cost structure nor the specific margin is established here. API list price, customer invoice, cloud-provider revenue share, gross margin and operating profit are different quantities; one cannot be inferred directly from another.
Willison sees customers continuing to use agents despite substantial bills as evidence that the products deliver value. I agree this is a useful signal, but it needs context: customers may be experimenting, have negotiated contracts or later change their usage. Revenue growth alone does not prove a permanent competitive advantage.
Sales, products and the outlook
He discusses enterprise sales, model adoption and potential competition. The profitability forecast remains to be verified against actual results.
Enterprise sales can also require substantial human effort, from contract negotiation to customer support. I discuss job listings as one indication of this commercial focus, though a count of openings is not the same as headcount, revenue attribution or proof of a company’s eventual strategy.
I question simplified reports about Microsoft limiting direct Claude Code use and suggest that access through another interface may still involve Claude models. Those are claims about a particular historical arrangement, and the video does not establish every employee policy or contract term. The distinction between a product interface and the underlying model matters.
I view Opus 4.5 as an important improvement that made larger coding tasks feel practical and helped build demand. That is my experience and an explanation I find plausible, not a measured attribution of a specific share of enterprise revenue to one model release.
My closing view is that stronger products, enterprise distribution and increased use could all contribute to growth, while compute costs remain significant. I had expected profitability to take longer; the report makes me revisit that assumption. The forecast still needs to be checked against actual results when they become available.
I congratulate the team on the reported progress and hope competition reduces prices for customers. Whether a forecast quarter turns into sustained profitability depends on future revenue and costs, not simply on today’s enthusiasm or a single model launch.
같은 채널의 다른 글
 38:47EN
 Theo - t3․gg· 2026년 10월 28일Theo’s Long-Running Agent Experiments: Verification, Compute and CostTheo Browne · Ping LabsA skateboard game and two compiler projects show how repeated checks and flexible compute can sustain agent work—and how expensive those loops can become.
 36:07ENTheo - t3․gg· 2026년 10월 27일Theo on Token Costs, Coding Agents, and the Price of AI CapabilityTheo Browne · Ping LabsA viral estimate of Lauren's AI spending prompts a closer look at cache pricing, benchmarks, and the changing work of coding agents.
 30:37ENTheo - t3․gg· 2026년 10월 26일Theo’s Three Skills for Reviewing and Shipping with Coding AgentsTheo Browne · Ping LabsHow sol-loop, full-send and full-stop encode review, verification and different levels of merge authority.
 0:43ENTheo - t3․gg· 2026년 10월 23일Theo Distinguishes Security Vulnerabilities from Active AttacksTheo Browne · Ping LabsA short explanation of why disclosed software flaws and reported attacks are different kinds of security news.
 29:22ENTheo - t3․gg· 2026년 10월 22일Theo on Security Vulnerabilities, Stolen API Keys and AITheo Browne · Ping LabsA look at the gap between vulnerability disclosure and patching, and a speculative account of why stolen inference keys may be valuable.
 31:13ENTheo - t3․gg· 2026년 10월 20일Theo on Why Smarter Models Help More Than DevelopersTheo Browne · Ping LabsFrom game modifications to compiler experiments, Theo revisits his assumptions about who benefits from more capable AI.