30초 요약
Manish Kapur of Sonar and Addy Osmani of Anthropic discuss the gap between generating code quickly and verifying it before release. Osmani describes Anthropic’s first-pass agent review and emphasis on evidence such as browser checks, while Kapur recommends layered verification throughout development. They distinguish human-supervised and more autonomous software factories, discuss agent permissions and sandboxing, and argue that human accountability remains important even when an agent writes the code.
- 1Throughput and failed mergesKapur cites CircleCI analysis of 28 million workflows, reporting a 59% increase in throughput and about three in ten production merge attempts failing.
- 2Light and dark factoriesOsmani describes a spectrum between agents working with human judgment throughout and a more autonomous process that escalates exceptions.
- 3Anthropic’s review workflowOsmani describes a Claude first-pass review, practical checks and hooks that inspect edits; people review the resulting evidence.
- 4Make verification concreteOsmani emphasizes end-to-end, property and visual tests rather than treating verification as an unspecified step.
- 5Multiple verification layersKapur proposes deterministic checks, agentic review and supply-chain analysis at different points in the development loop.
- 6Ownership survives automationBoth speakers support identifying agent-written work; Osmani says a human owner remains accountable for the change.
핵심 정리
- Verification and review must keep pace with the volume of agent-generated changes.
- Agents can generate tests and evidence, but people remain responsible for evaluating the evidence and the outcome.
- End-to-end, property and visual checks can build confidence for different types of changes.
- Layered checks can combine deterministic analysis, agentic review and supply-chain security.
- Agent identity, permissions, telemetry and sandbox controls matter as agent deployments grow.
챕터별로 다듬은 전문 읽기
The verification gap
Kapur introduces Osmani and asks how teams review changes as coding agents increase throughput. They cite industry figures and define software factories.
Manish Kapur opens by asking how many attendees have had a coding agent open a pull request, and how many reviewed every line before merging. He introduces the gap between merging without manual review and merging after review, and welcomes Addy Osmani, who recently joined Anthropic after about 14 years at Google.
Osmani says he works on the developer experience of building with Claude Code. His team feeds opportunities for improvement back into the product and ships updates several times a day.
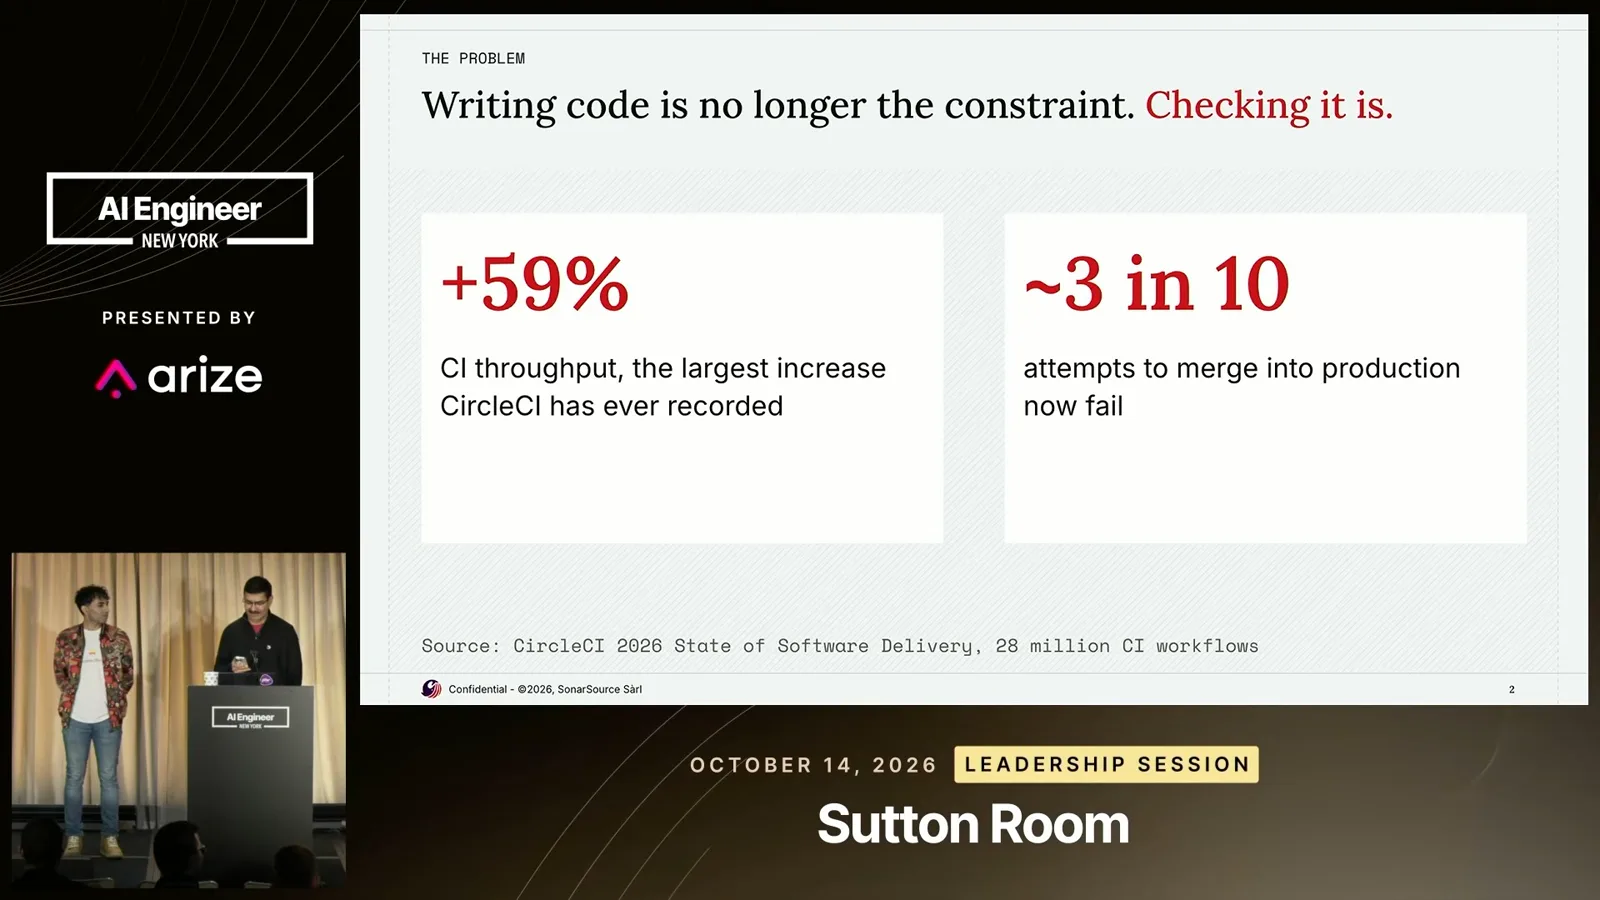
Kapur cites CircleCI’s analysis of 28 million CI workflows: throughput increased by about 59%, while roughly three in ten attempts to merge into production failed. He says he sees a similar trend among customers, and asks Osmani to explain software factories as loops at scale.
Osmani distinguishes a lights-on factory, where agents repeatedly plan, build, check and ship while people apply judgment, from a dark factory that works more autonomously and brings people in for exceptions. He sees teams across a spectrum, trying to automate more while earning trust.
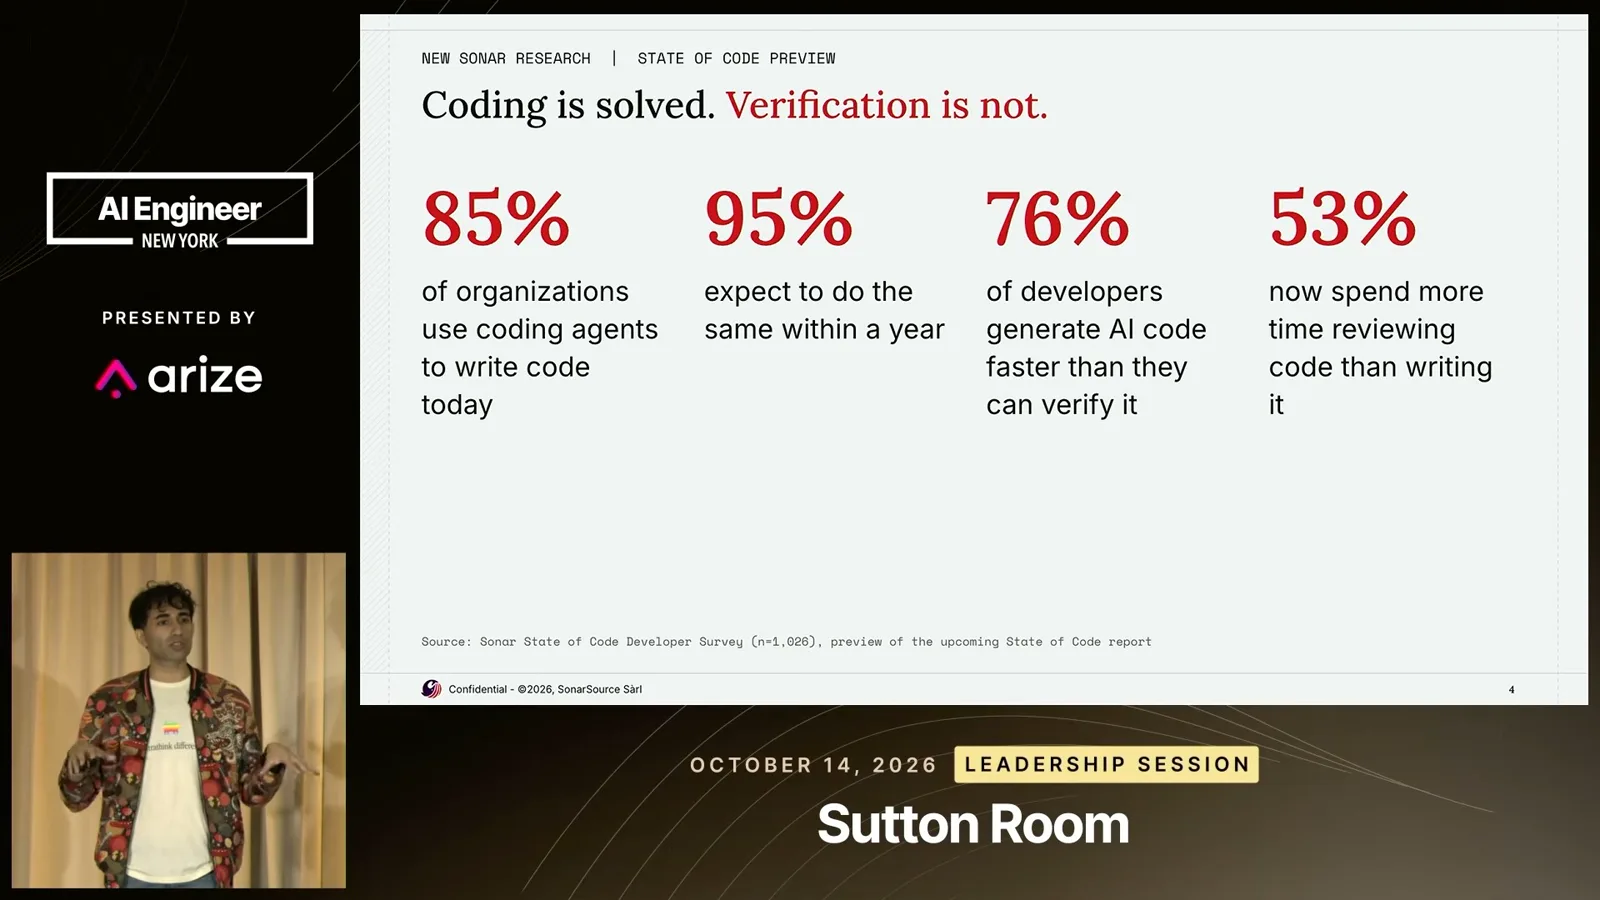
Kapur cites Sonar survey figures: 85% of organizations use coding agents, and 76% of developers generate AI code faster than they can verify it. He asks what engineering leaders most urgently need to address as review becomes a bottleneck.
Building confidence at scale
Osmani discusses tests, specifications and Anthropic’s first-pass review workflow. Human reviewers examine evidence generated by agents.
Osmani says teams want to ship faster with confidence. Tests, benchmarks and specifications give agents a way to check work, and agents can now help generate those checks more cheaply. He argues that making correctness and completeness verifiable can significantly improve outcomes.
Kapur asks about Anthropic’s reported growth from roughly 2,500 daily changes in May to about 30,000 per day. Osmani also points to a Claude.ai refresh that involved about 3,000 pull requests over a short period and contributions from engineers, product designers and other functions.
Osmani describes Claude performing an initial review. The agent needs a way to try the experience as a user would: run end-to-end tasks, open a browser, use tools, lint and perform other checks. Hooks run on edits and examine diffs to help teams correct gaps quickly.
Anthropic also uses a code-review product to automate more of the review. Osmani encourages teams to encode their own standards and judgment in shared files such as CLAUDE.md or AGENTS.md, so an agent can consult those rules while reviewing.
People remain responsible for checking the agent’s evidence. For a browser UI, Osmani wants proof that it was tested in the browser, potentially including a video of interactions or screenshots of mobile and desktop views. The aim is to make verification evidence available for human judgment.
From faster writing to trustworthy delivery
The speakers discuss survey figures, useful verification tests and the spectrum of human involvement in software factories.
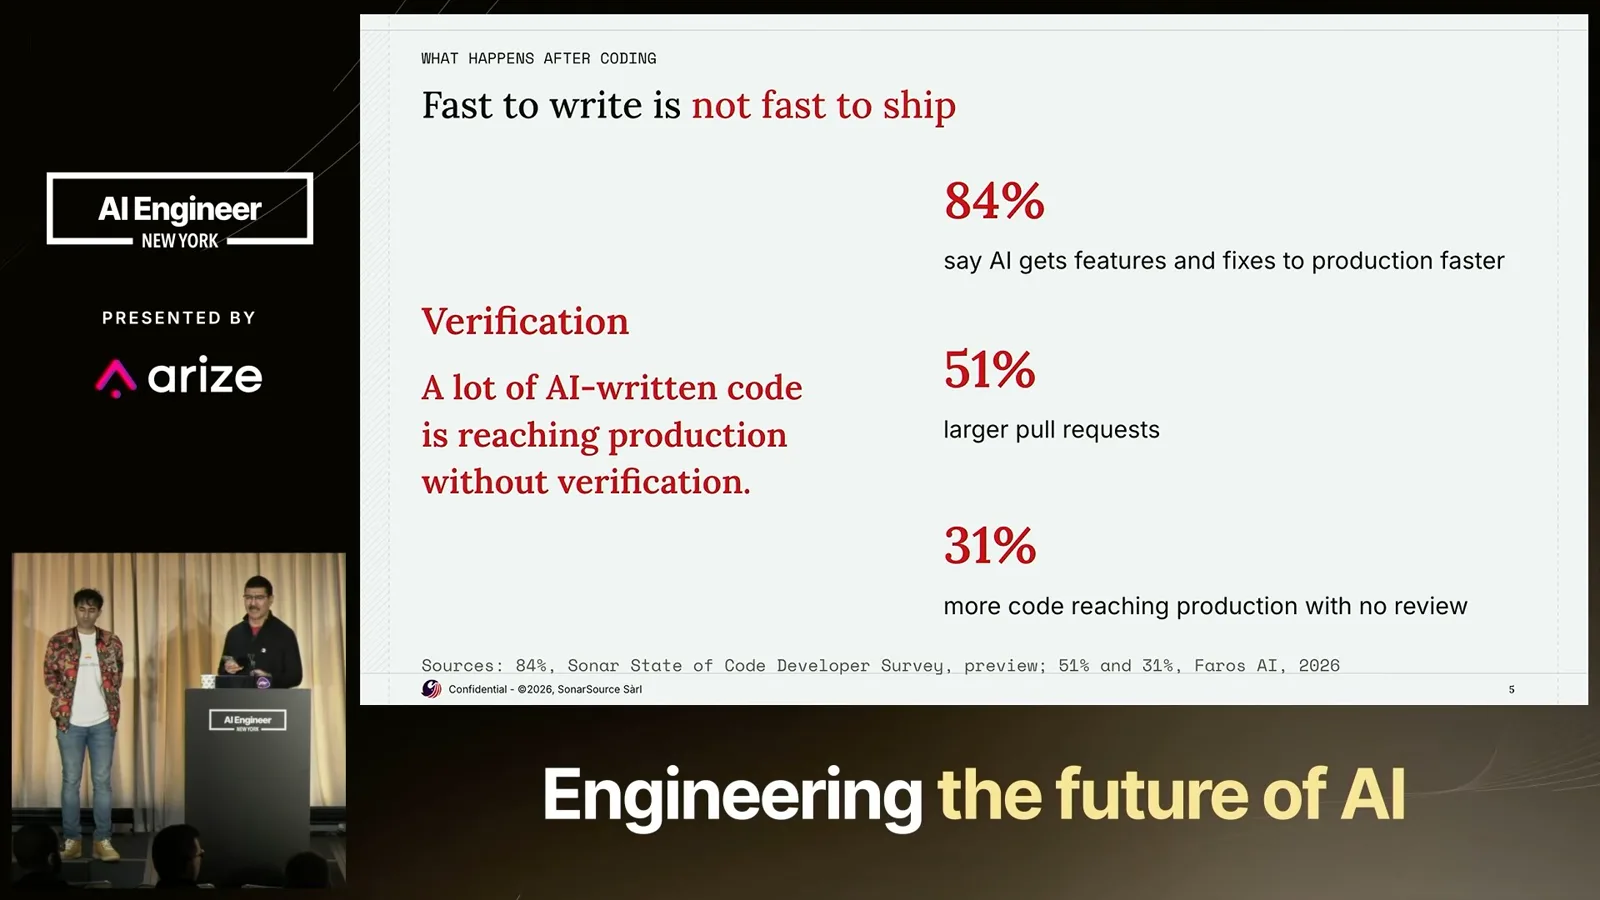
Kapur cites a preview of Sonar’s survey of more than 1,000 developers, saying 84% report that AI gets features and fixes to production faster. The slide also attributes larger pull requests and a 31% increase in code reaching production without review to Faros AI. He considers the latter concerning for regulated and mission-critical applications.
Osmani expects further gains from better models and, especially, better verification practices. Telling a team merely to verify the work is too vague: it must decide which tests provide evidence. He mentions end-to-end, property and visual verification tests as ways to build confidence for automated merging.
Kapur cites survey estimates that 5% of companies use software factories today and that more expect to do so. Osmani reiterates that a factory consists of loops at scale, with a range of human involvement. More reliable verification may let a team move toward greater autonomy, but many are not yet at that point.
Kapur compares the process to an assembly line: define intent and specifications, write code and perform the other development steps. A lights-on factory keeps people involved in many steps, while a dark factory aims to run independently around the clock.
Layered verification and controls
Kapur outlines Sonar’s layered approach. Osmani highlights identity, telemetry, permissions and sandboxing as agent use expands.
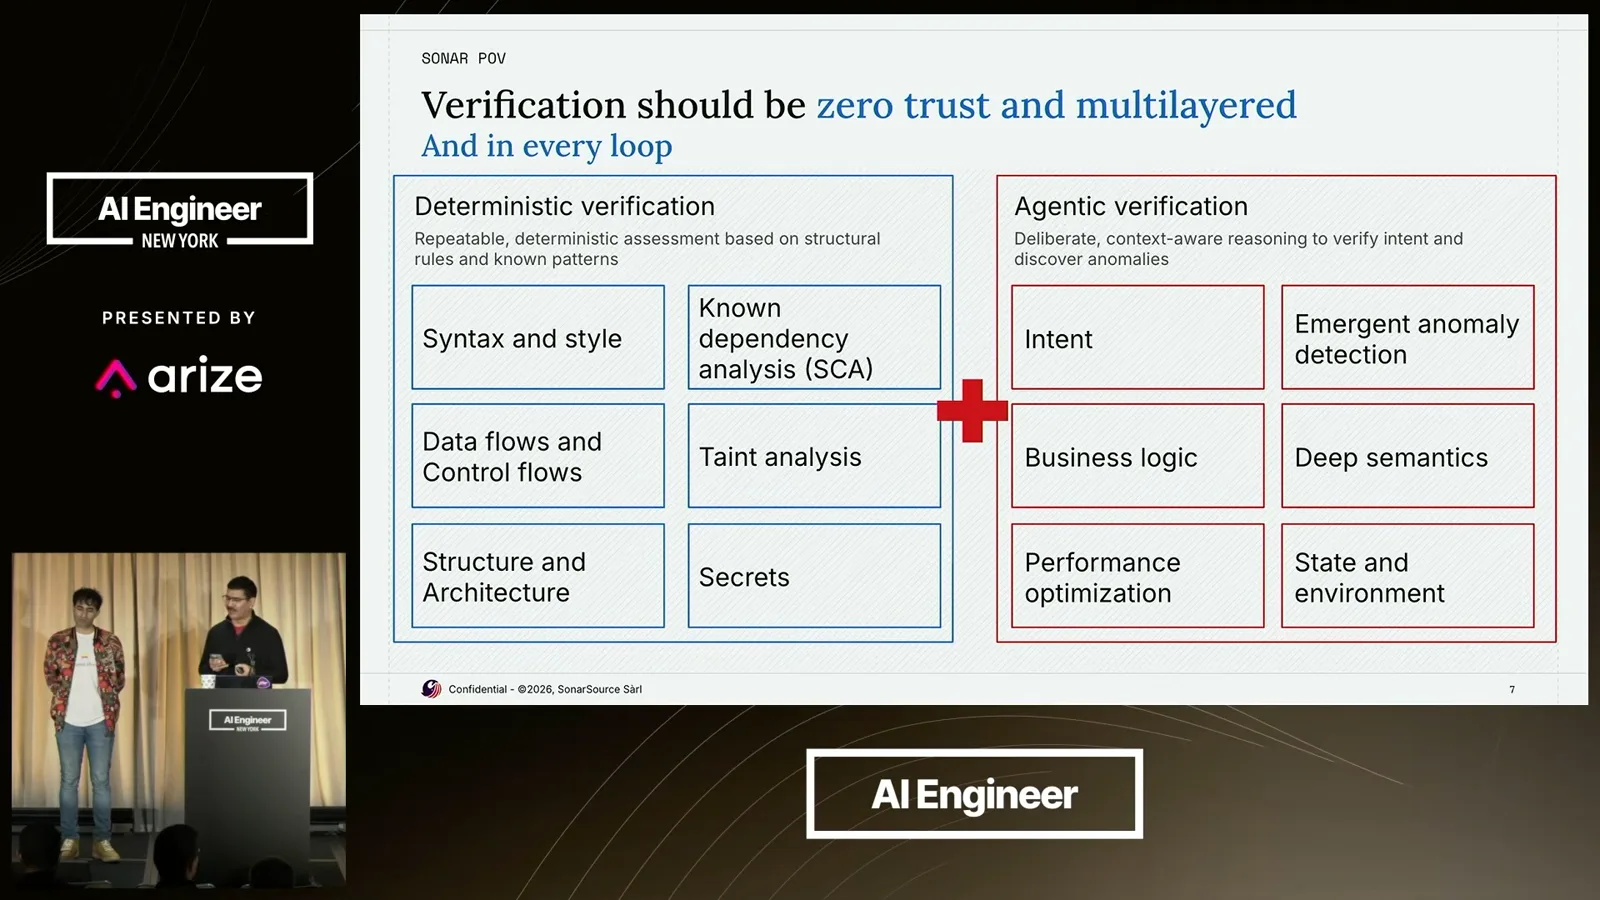
Kapur presents Sonar’s view that verification should be multilayered and occur inside each loop, including the agent, CI and maintenance loops. The first layer uses deterministic checks for bugs and security issues; an agentic review layer can investigate logic and intent.
A further supply-chain layer checks for known vulnerabilities, malware and malicious packages. Kapur argues that each layer should be tuned to the kinds of issues it can catch, rather than relying on a single form of verification.
Kapur cites a survey finding that some organizations have approved agents but few shared controls. Osmani says enterprises have found themselves with large numbers of agents touching systems and data, sometimes deploying to production, without a clear picture of what they are doing.
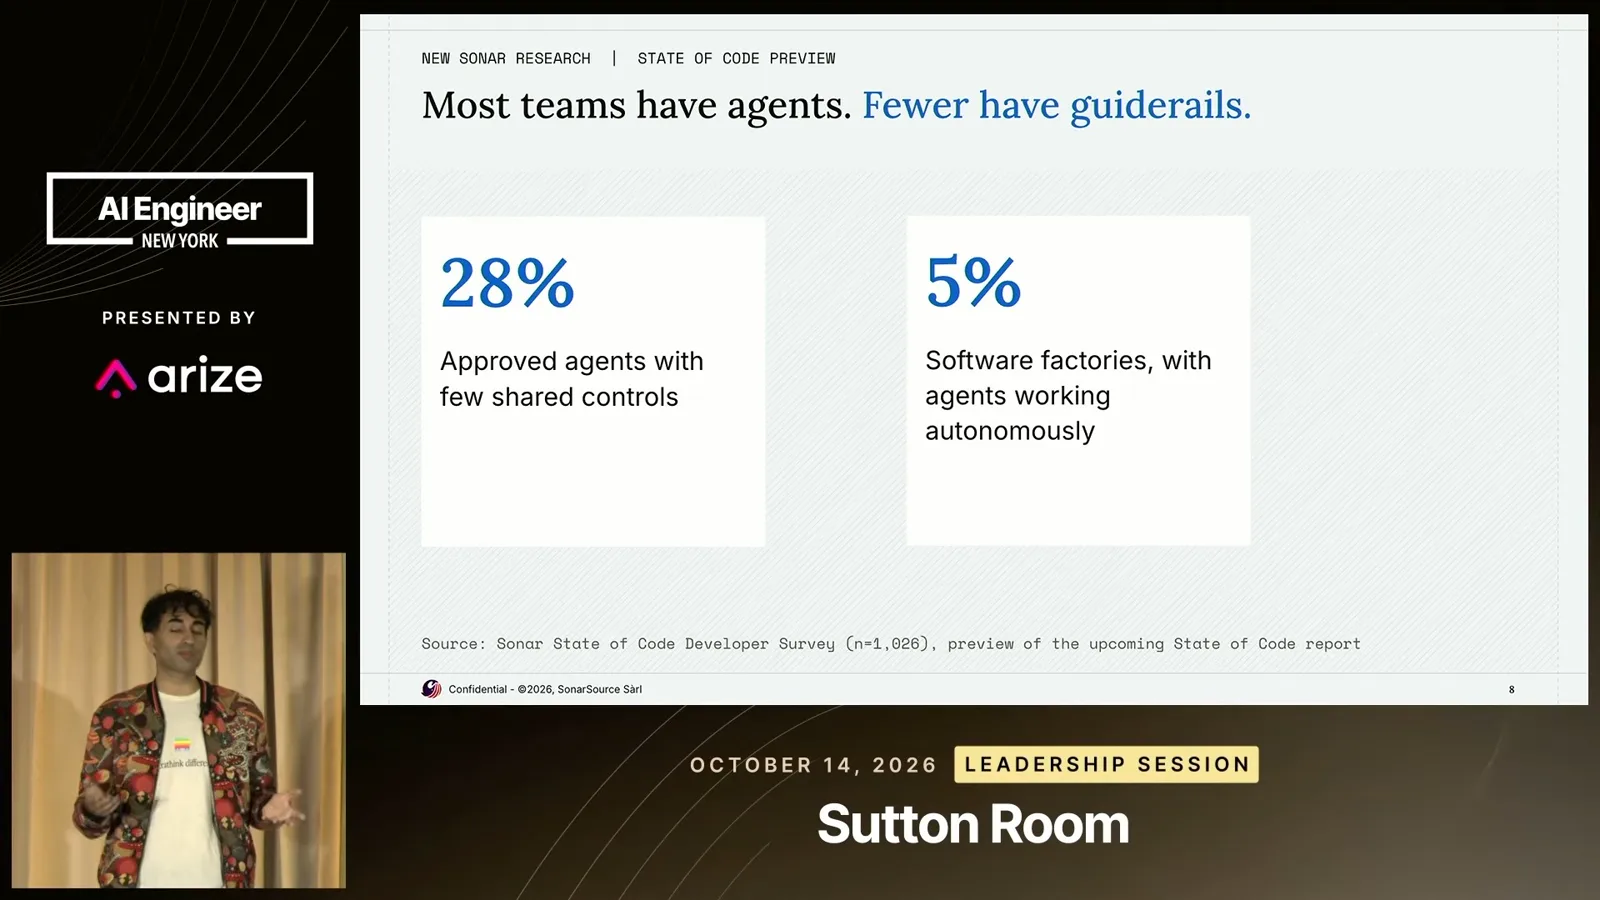
Osmani identifies control, permissions and sandboxing as major concerns, alongside agent identity and telemetry. Kapur calls these boundaries “guide rails”: the goal is to guide agents along an intended path and keep them within the permitted sandbox.
Accountability and the path to autonomy
In a lightning round, they discuss labeling agent-written code, human ownership and skills for verifying work. Kapur closes by emphasizing independent checks.
Asked whether most teams will use light or dark factories by the end of 2027, Osmani predicts lights-on factories with some autonomous “dark corners,” rather than complete dark factories everywhere.
Osmani personally supports labeling agent-written code in pull requests. He says Anthropic focuses on the quality of the outcome, and identifying agent-written work can help teams decide which constraints and extra checks to apply.
Kapur also favors labels in the near term, including for auditability in financial services. Osmani stresses that a human owner remains accountable: even if he starts a Claude run, he is responsible for fixing the change if something goes wrong.
For leaders, Osmani recommends helping teams define what verification means and identifying the gap between current tests and confidence in agent-led merging. Junior developers can gain experience with different kinds of tests, including end-to-end and property tests.
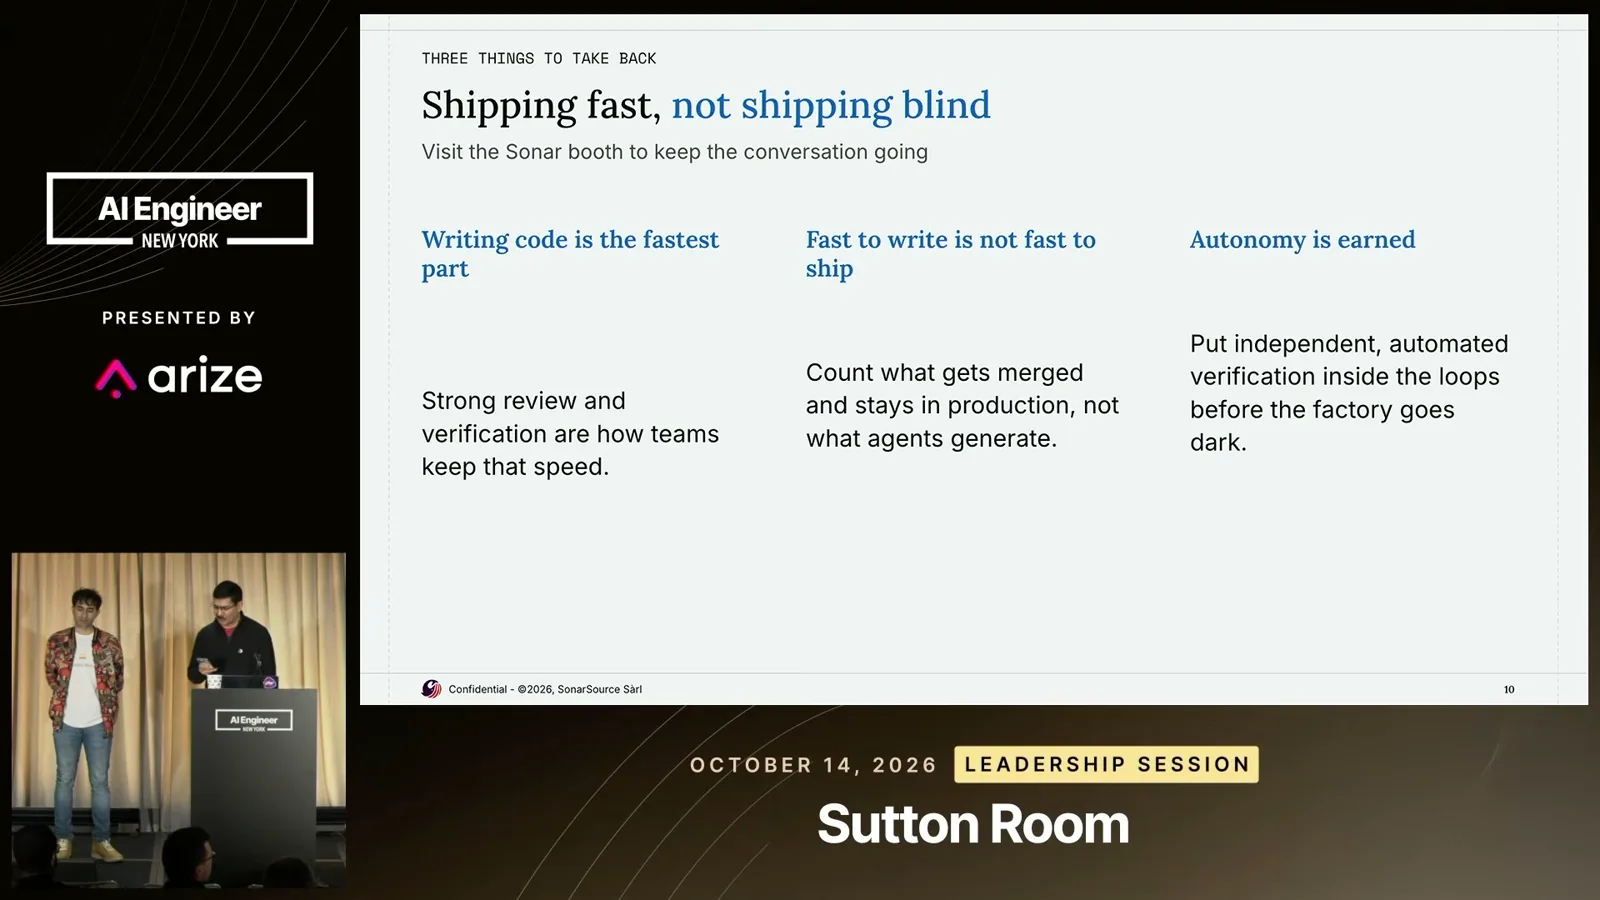
Asked when an agent’s pull request is safe to merge, Osmani answers that the team needs confidence that risks have been mitigated as much as possible. Kapur closes with three points: review sustains delivery speed, measure what is merged into production, and earn autonomy through independent automated verification in each loop.
같은 채널의 다른 글
 21:32EN
 AI Engineer· 2026년 10월 29일Shy Ruparel on AI agent reliability and recovery after failuresShy Ruparel · TemporalTemporal’s survey finds a gap between frequent agent use and dependable deployment. Ruparel demonstrates a synthetic payout workflow that resumes after workers stop.
 14:50ENAI Engineer· 2026년 10월 29일Cole Gannaway on code review, cross-repository risk and AI software factoriesCole Gannaway · QodoA one-line rename can pass local checks while affecting distant clients. Qodo’s Cole Gannaway explains how review context, shared rules and independent agents can expose those risks.
 11:47ENAI Engineer· 2026년 10월 29일Revolut’s David Abitbol on self-hosting AI coding models at scaleDavid Abitbol · RevolutAbitbol shares engineering delivery trends, GPU-serving costs and latency tuning, then describes controls for operating the tools in a regulated bank.
 21:47ENAI Engineer· 2026년 10월 28일Patrick Smyth on Open-Source Supply Chain Security in the AI EraPatrick Smyth · ChainguardChainguard’s Patrick Smyth discusses faster exploitation, malware in dependencies, zero-days and the expanding attack surface around developer workflows.
 14:09ENAI Engineer· 2026년 10월 28일Taylor Luttrell-Williams on Finding Logic Vulnerabilities with SonarQube Hunter AgentTaylor Luttrell-Williams · SonarSonar’s Taylor Luttrell-Williams explains how a security agent maps a codebase, investigates logic flaws and presents validated findings alongside conventional scans.
 16:29ENAI Engineer· 2026년 10월 28일Chris Vela on Benchmarking vLLM Configurations with Runpod BenchPodChris Vela · RunpodRunpod’s Chris Vela demonstrates a dashboard for comparing LLM serving configurations and choosing performance settings with workload-specific data.