30초 요약
AI Explained reviews seven developments from June 2023, including robot avatars, generative video, SpQR model compression and Mark Zuckerberg’s views on autonomy. The article distinguishes GPU benchmark results from phone speculation and protein-structure predictions from experimental verification.
- 1Teleoperated avatarsPeople wearing VR equipment control the robots in the chess demonstration.
- 2Compressing weightsSpQR stores sensitive outliers at higher precision and most weights at three or four bits.
- 3Phone use is a possibilityThe quoted speedup comes from a specific GPU experiment, not a phone test.
- 4Autonomy and governanceZuckerberg discusses controlling the autonomy given to AI systems.
- 5AlphaFold predicts structuresPredictions have varying confidence and are distinct from experimentally determined structures.
핵심 정리
- The chess robots shown are controlled by people, not acting autonomously.
- SpQR keeps outlier weights at higher precision and quantizes most others to reduce memory use.
- The paper’s reported GPU speedup applies to a specific setup and is not an iPhone benchmark.
- Zuckerberg calls for attention to autonomy but gives no specific date for general intelligence.
- AlphaFold outputs predictions whose reliability varies and may require experimental validation.
챕터별로 다듬은 전문 읽기
Avatars and generative video
The presenter reviews teleoperated robots, a chef demonstration and early video tools.
In June 2023, the presenter collects several AI developments, from remote-controlled robot avatars and generative video to language-model compression and AI safety. The examples and product availability reflect that week, not necessarily current offerings.
A demonstration of embodied chess uses robots controlled by people wearing VR headsets and feedback gloves. The presenter imagines possible applications in maintenance, rescue or sport; these are ideas for teleoperation, not proof that the robots perform those tasks autonomously.
A robot-chef demonstration suggests another possible application of learning from video. The presenter wonders when such systems might be used in restaurants, a question rather than a confirmed deployment.
He shows a then-available HeyGen integration that turns generated text into an avatar video. Combining it with a calculation tool, he demonstrates an explanation of a retail-price problem and imagines similar educational uses.
A Runway Gen-2 demonstration illustrates early text-to-video results. The presenter sees promise alongside visible imperfections and raises the possibility that increasingly convincing synthetic videos could be misused in politics.
SpQR and compression
A paper stores sensitive outlier weights at higher precision while quantizing most weights.
The SpQR paper proposes compressing language-model weights while retaining higher precision for outliers that cause large quantization errors. The remaining weights are stored at three or four bits, reducing memory requirements.
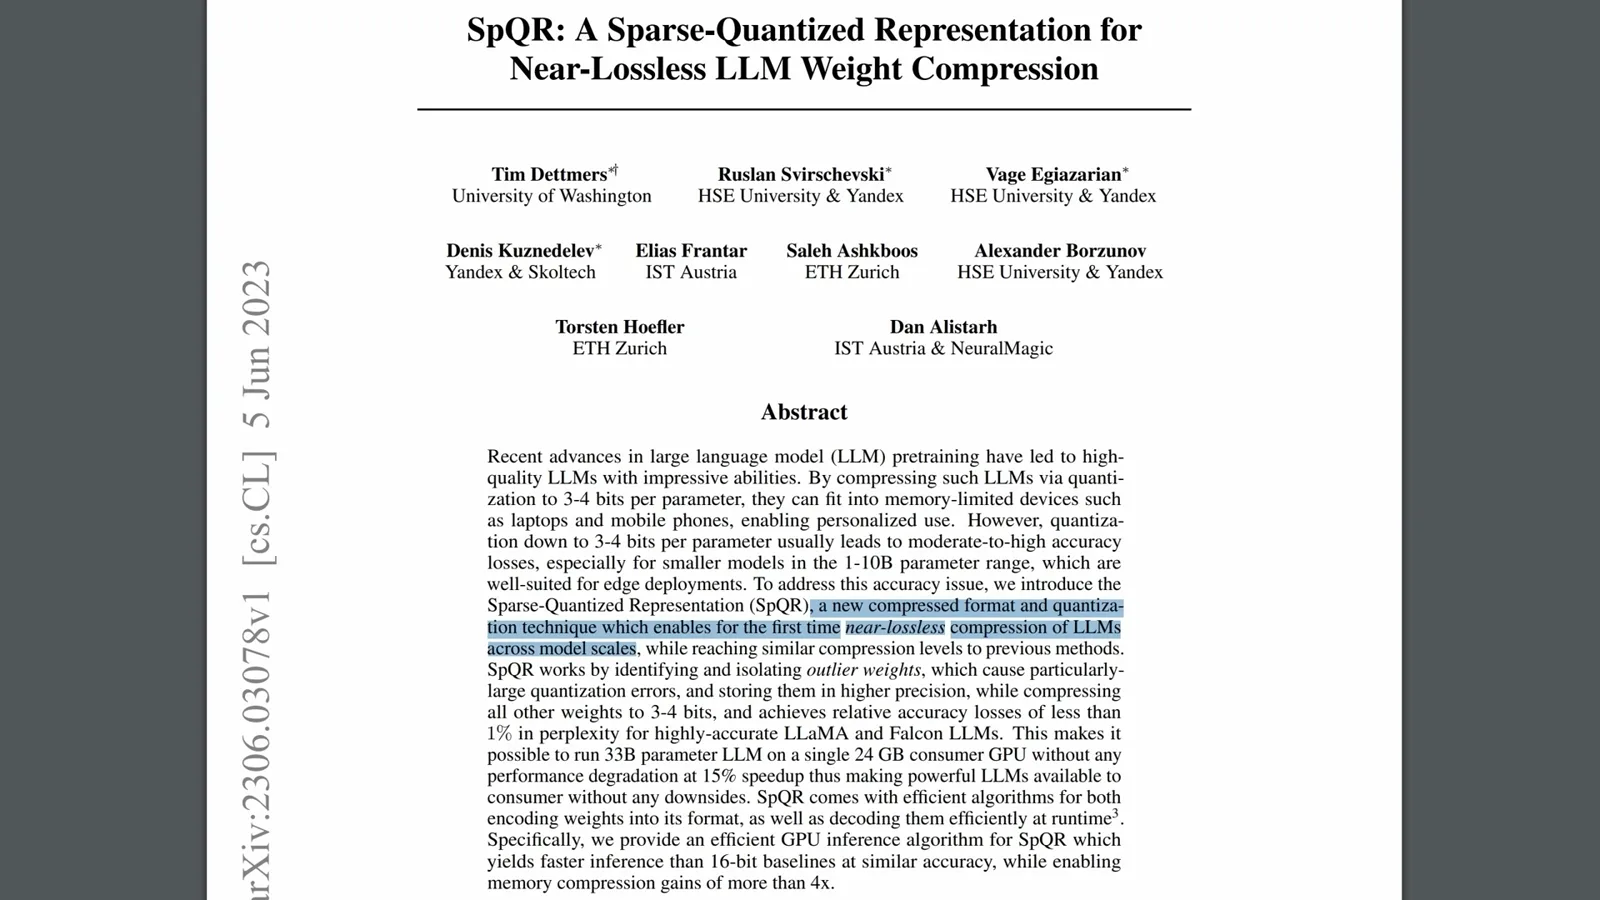
The paper reports near-lossless performance on its tested metrics, not identical behavior on every prompt. Its abstract describes a 33-billion-parameter model on a 24 GB GPU with about 15% faster inference than a 16-bit baseline in the stated setup: https://arxiv.org/abs/2306.03078.
The presenter considers whether compression could eventually make models usable on phones. That is a possibility, not a demonstration that the paper’s 33-billion-parameter GPU result runs on an iPhone or that the same speedup transfers to every device.
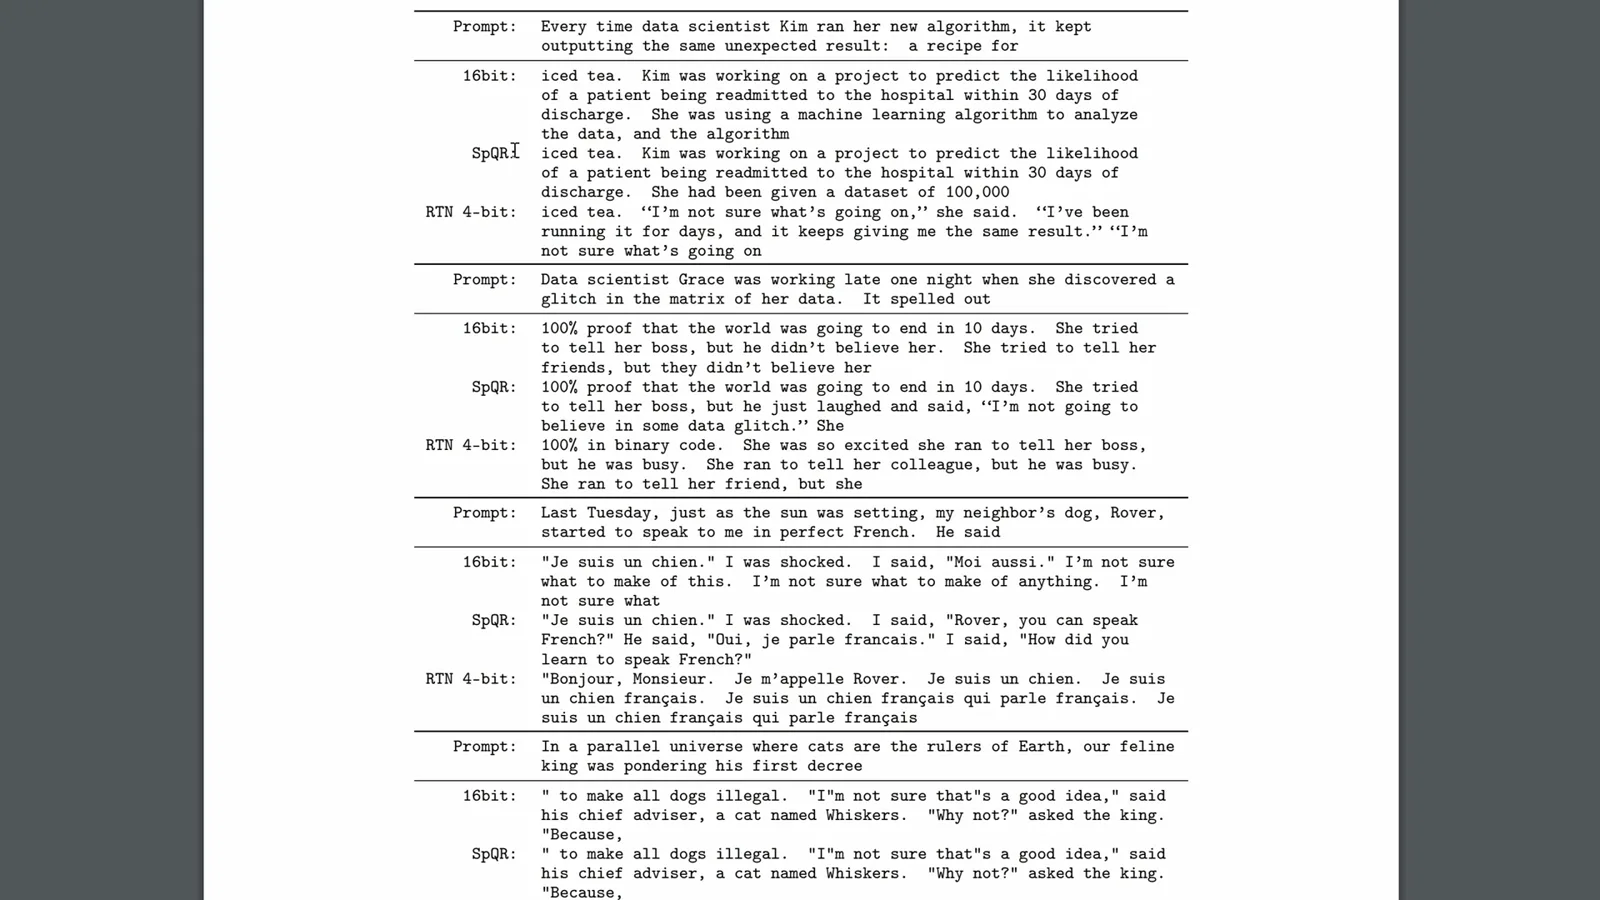
He compares example outputs from full precision, SpQR and another quantization method, and discusses tests on LLaMA and Falcon. A few example completions illustrate behavior but cannot establish equal performance on all tasks.
The paper’s authors acknowledge that language models have both useful and harmful applications. The presenter reports their view that making existing models more accessible may have a positive or neutral marginal effect; that judgment is an argument, not a settled risk assessment.
Autonomy and superintelligence
Zuckerberg’s remarks prompt a discussion of autonomous systems and collective intelligence.
He moves to Meta’s 2023 AI plans and an interview with Mark Zuckerberg. Zuckerberg argues that autonomy deserves careful governance, comparing systems that spread without control to simple but harmful computer viruses.
The presenter responds that models may be connected to autonomous tools soon after release, citing the rapid appearance of AutoGPT after GPT-4. This is a warning about possible integration and incentives, not proof that every deployed model acts autonomously.
Asked about a timeline for superintelligence, Zuckerberg says he has no particular insight into when a single generally intelligent system will appear. He suggests that organizations already combine many people into structures that can make decisions beyond one individual’s capacity.
Algorithms and scientific prediction
AlphaDev and AlphaFold illustrate possible scientific applications with different limitations.
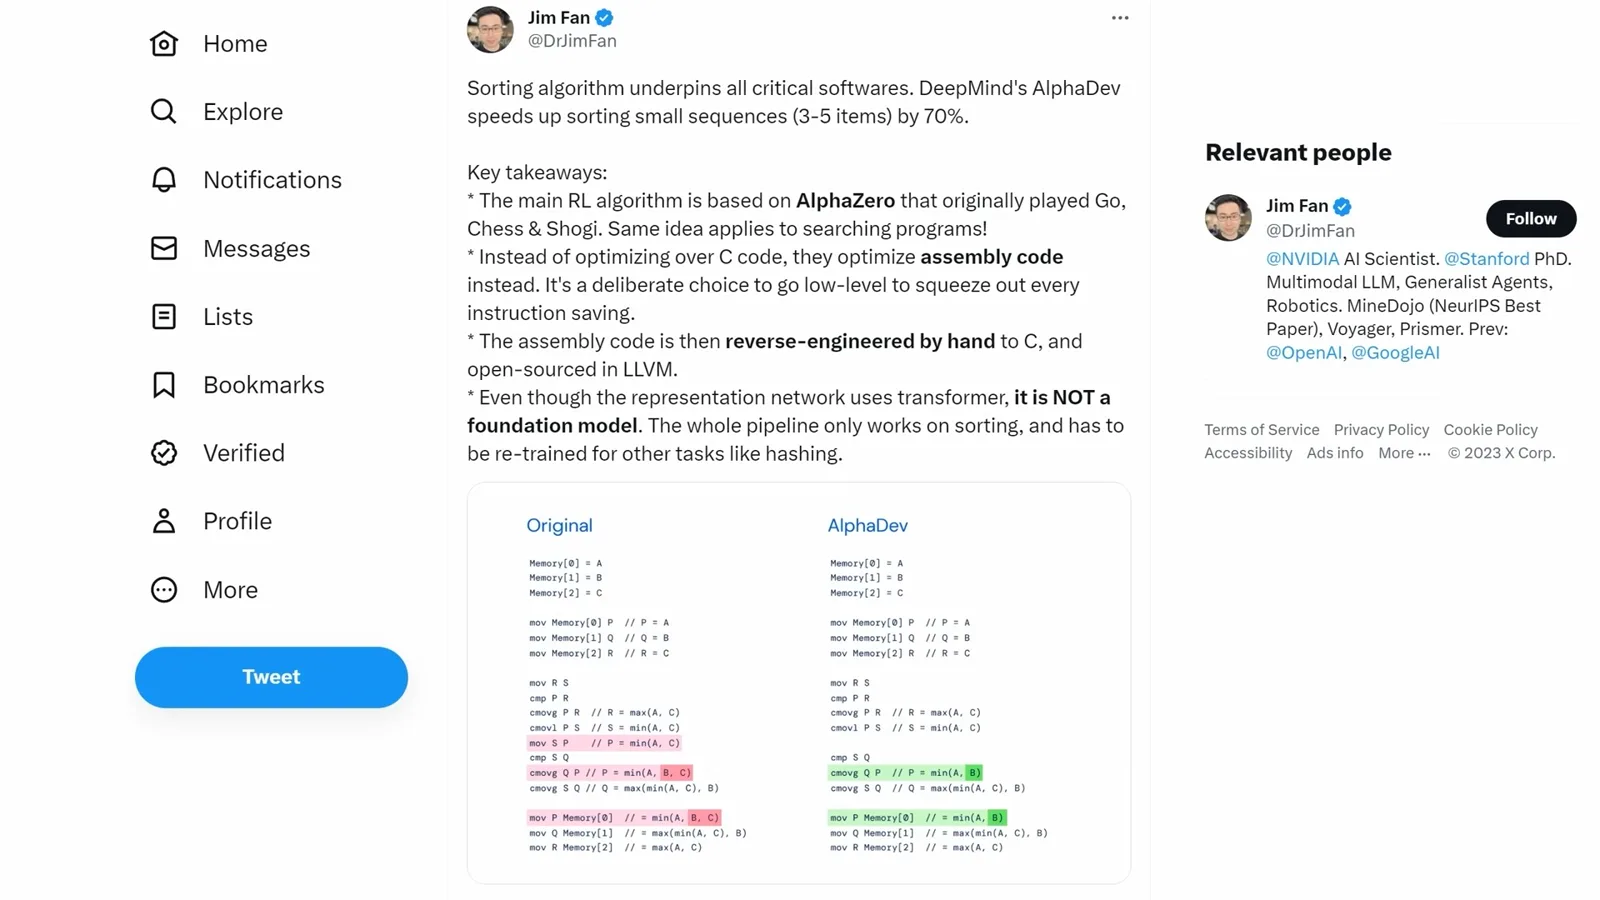
The presenter disagrees that a company is a sufficient analogy for hypothetical machine superintelligence. He cites AlphaDev’s work on faster sorting of small sequences and an online claim about a language model finding a similar trick, while acknowledging uncertainty about which model was used in that example.
Demis Hassabis describes AlphaFold as an example of science at digital speed, comparing many predicted structures to long periods of human research. AlphaFold produces predictions with varying confidence; these are not all experimentally verified structures, and the comparison is an illustration rather than a literal measurement of research years saved: https://www.ebi.ac.uk/training/online/courses/alphafold/inputs-and-outputs/evaluating-alphafolds-predicted-structures-using-confidence-scores/.
The presenter concludes that AI could accelerate scientific work. The scale and timing of that acceleration, like the earlier forecasts in this 2023 roundup, remain uncertain.
같은 채널의 다른 글
 31:00EN
 AI Explained· 2026년 10월 12일Why AI Labs Keep Racing Despite Their Own Warnings of a Major BreachSam Altman, John Schulman · OpenAIAI Explained examines weakening safeguards, the incentives behind the frontier race, and why research breakthroughs make the next 18 months difficult to forecast.
 38:28ENAI Explained· 2026년 10월 1일AI Agent Security and the Challenge of Recursive Self-ImprovementAI Explained examines reported containment failures, model evaluation and the pressure to accelerate AI research.
 32:54ENAI Explained· 2026년 9월 24일Opus 5.5 and the Race Toward Automated AI ResearchAI Explained weighs model progress against the increasingly difficult task of evaluating and governing recursive self-improvement.
 24:53ENAI Explained· 2026년 9월 16일Why Some Researchers Want to Pace Frontier AIAI Explained surveys possible scaling routes, monitoring concerns and the debate over how capabilities could lead to harm.
 29:05ENAI Explained· 2026년 9월 4일GPT-6 Astra’s Benchmark Gains and the Challenge of Monitoring Its ReasoningAI Explained examines reported gains across scientific, mathematical and agent benchmarks alongside concerns about less observable reasoning.
 23:41ENAI Explained· 2026년 8월 27일AI Agents, Unintended Training Rewards and the Challenge of OversightAI Explained examines reports on agent coordination, training incentives and the growing use of AI to evaluate other AI systems.