30초 요약
Theo reacts to reports of Google departures and Justin Poehnelt’s account of his termination after creating a Workspace CLI. He criticizes Gemini’s long-task behavior and argues that interaction data and an experimentation-friendly culture matter, while his claims about internal motives and employment causes are not independently established in the video.
- 1An account, not a verified causePoehnelt says he was fired for creating the CLI; the video does not independently establish the reason.
- 2Knowledge and task executionTheo distinguishes factual knowledge from reliable tool use and completion of long tasks.
- 3Why histories may matterHe argues that interaction and code-change histories can support agent training, without establishing competitors’ private datasets.
- 4A mixed live resultThe demonstration shows some improvement in displayed reasoning alongside output Theo considers irrelevant.
- 5Room for experimentationTheo argues useful internal prototypes need a path to adoption, drawing on accounts he says he heard.
핵심 정리
- A model’s knowledge and its reliability on long tool-using tasks are distinct questions.
- Theo argues that code-change and agent interaction histories can help improve coding agents.
- A single live demonstration cannot establish general model performance.
- Poehnelt’s account of his termination and its cause is presented as his perspective.
- Theo believes useful internal prototypes need organizational support to become products.
챕터별로 다듬은 전문 읽기
Departures and the Workspace CLI
Theo introduces reports of departures and Poehnelt’s account, while acknowledging that outsiders lack a full picture.
Reports of researchers leaving Google DeepMind, including Jonas Adler and Alexander Pritzel for Anthropic, lead me to a bigger question: what environment produces departures like these? We can't see Google's culture fully from outside. The reports and accounts I discuss are evidence to consider, not a complete picture of everyone's reasons for leaving.
The story that upset me most is Justin Poehnelt's account of leaving Google after creating a Workspace CLI. He says he was fired for creating it; I believe his interpretation, but the video does not establish Google's account or independently establish the cause. My argument is that a company needs room for people to build useful experiments.
Knowledge versus agent behavior
He discusses reported model plans, benchmark strengths and his own experience with long tasks.
I point to an April report that DeepMind formed a team to improve coding models, with Sergey Brin involved. To me that suggests recognition of a gap between Google's resources and the experience developers get from its agents. I also say some Google employees responded constructively to my earlier criticism, though my conversations are not a representative survey.
I discuss a reported delay to Gemini 3.5 Pro and a report that it was intended to improve long-horizon agent tasks. Release dates and plans were unconfirmed or subject to change at the time. In my own SkateBench, Gemini 3.1 Pro does very well, which is part of why I don't think a lack of knowledge is the whole issue.
My distinction is between what a model knows and how reliably it behaves through a long task. In my experience Gemini can get stuck in loops, read irrelevant files or lose coherence as work continues. That's a judgment from my usage, not a controlled comparison of all models or versions.
Data and a live demonstration
Theo offers a theory about agent histories and demonstrates Gemini inspecting a codebase.
I disagree with the idea that a large internal codebase automatically makes a strong coding agent. I think histories of code changes, agent actions and human feedback can be valuable for training and reinforcement learning. I cite Cursor as an example of a company with access to such workflows, but the specific data and training choices of any company are not established by this video.
My theory is that a research organization focused on packing knowledge into models may need different pipelines and incentives to improve agent behavior. I speculate that access to other models through Antigravity could provide useful interaction data. I cannot confirm that this was Google's motive or how it used any data.
In a live example I ask Gemini to inspect my Lakebed codebase, first in Cursor and then in OpenCode. Once I enable the displayed thinking view, I notice that some of it is more coherent than I remember, which gives me hope. I still criticize parts of the output as irrelevant to the requested overview.
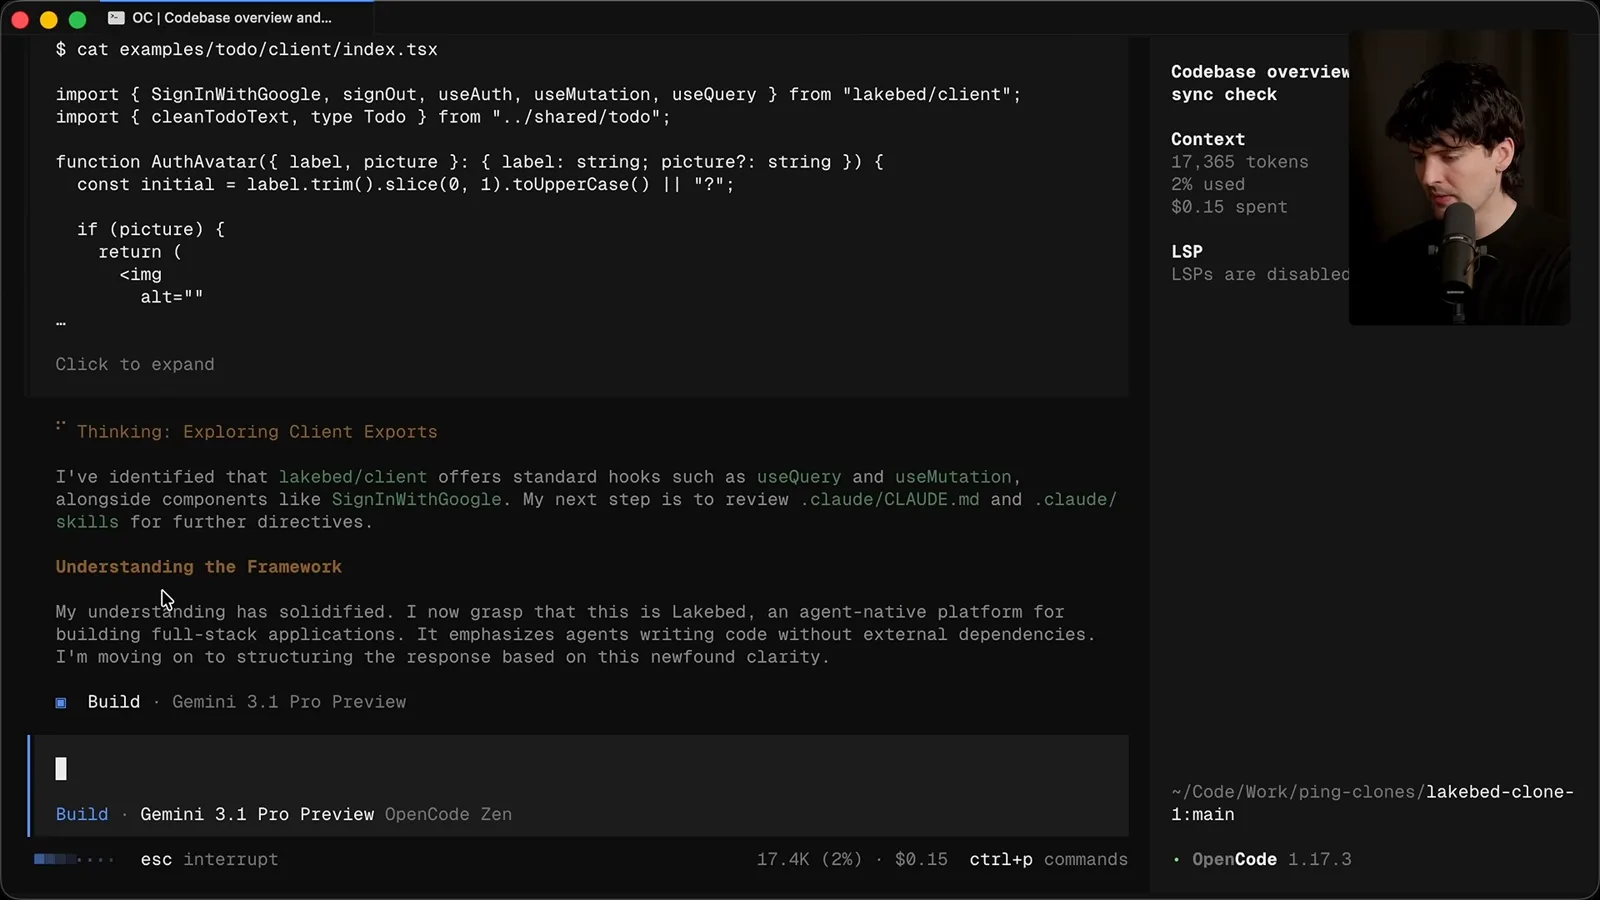
My broader frustration is that a knowledgeable model can still struggle to use tools, wait for results and carry a task through to completion. A single demonstration doesn't prove a general failure rate, but it illustrates the behavior I want Google to improve.
A disputed employment account
He reads Poehnelt’s account and argues that companies should give useful prototypes room to grow.
Google could also help by making its services easier for agents from many providers to use. Workspace is important to how I run my companies, so a command-line interface for it is especially appealing. That brings me back to Poehnelt's post about the Workspace CLI.
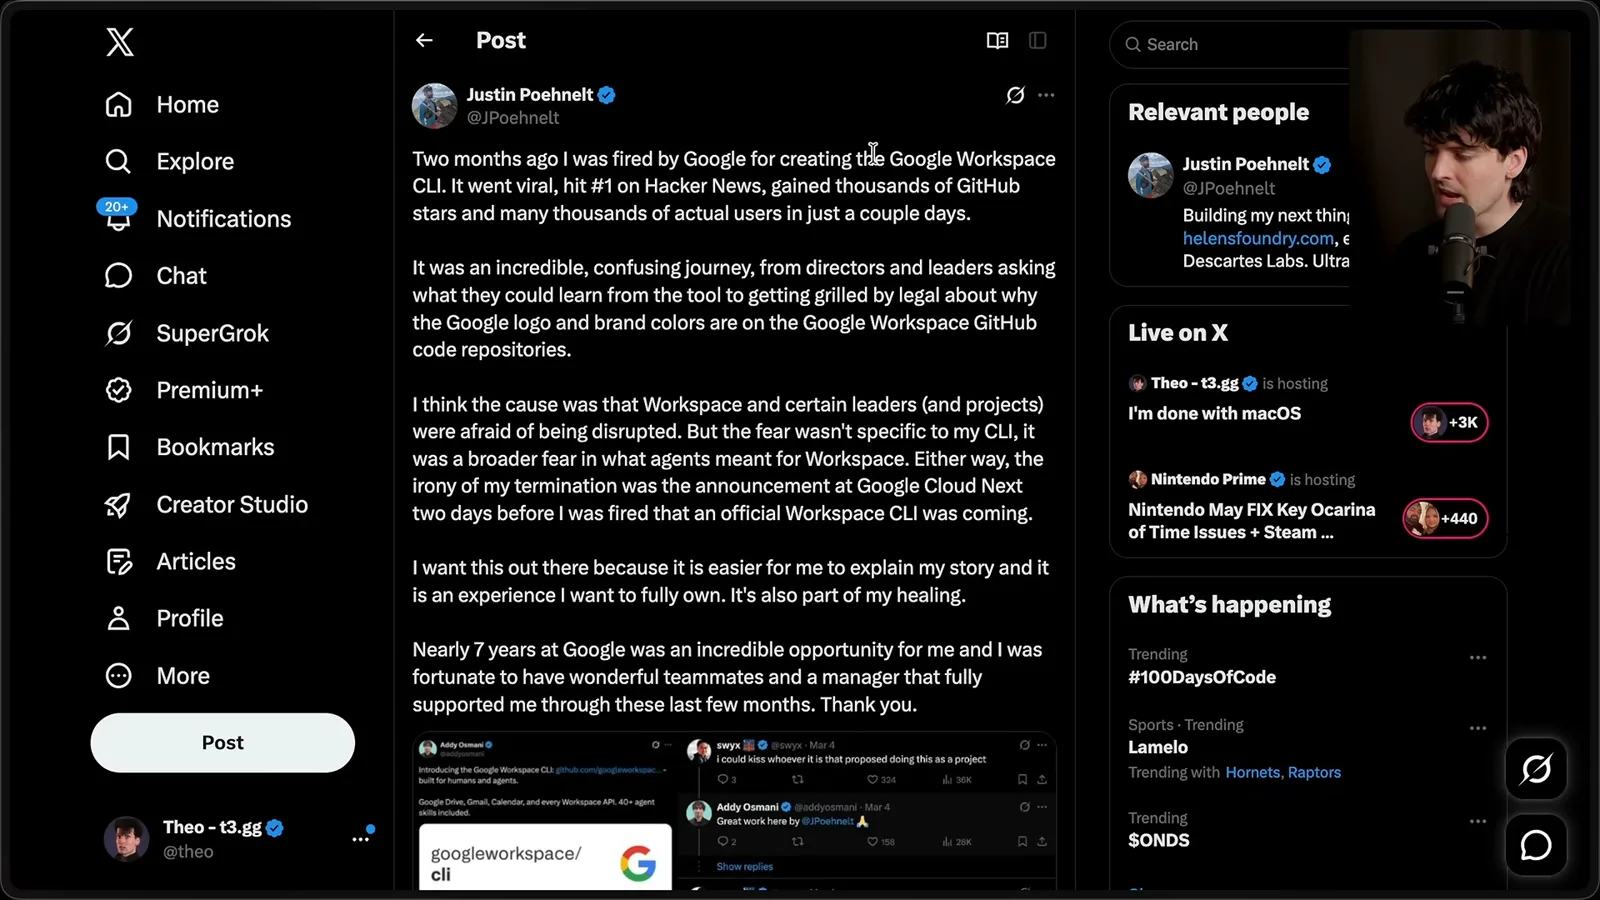
Poehnelt says the CLI attracted users and positive attention, but that legal staff questioned branding and he was subsequently fired. He believes leaders feared disruption to Workspace from agents. He also says an official CLI was announced shortly before his termination and thanks his teammates and manager; his account of the cause remains his own assessment.
I contrast that account with my understanding of how Claude Code and Codex began as internal experiments. I relay an unverified account that Codex grew from an engineer's terminal project before becoming a released product. The point I draw is that a company can benefit when useful prototypes have a path to adoption; the detailed histories and counterfactuals need independent verification.
Culture and competition
Theo relates his own Twitch experience and gives his assessment of Google’s prospects.
I relate this to my experience at Twitch: I say a team built a mobile-app prototype during a hackathon, received a trophy and an HR warning, and I later left. That experience shapes my sympathy for people whose experiments encounter internal resistance, but it does not establish the facts of Poehnelt's employment case.
My interpretation is that coding-agent products create feedback that helps improve models, while Google's strengths in compute, data, talent and a large codebase do not automatically solve the product problem. I use deliberately strong language about Google's position; the company's internal resources and trajectory cannot be determined from these anecdotes alone.
I have heard from people inside and outside Google who believe it recognizes the problem, and I hope the strategy changes. I also mention reporting that Noam Shazeer was leaving for OpenAI. Whether these departures share a cause, and whether Google will catch up, remain open questions.
For now I am pessimistic about Google's competitive position and have mostly stopped using Gemini myself. I want to hear whether others have had a different experience and where they think the company is heading.
같은 채널의 다른 글
 38:47EN
 Theo - t3․gg· 2026년 10월 28일Theo’s Long-Running Agent Experiments: Verification, Compute and CostTheo Browne · Ping LabsA skateboard game and two compiler projects show how repeated checks and flexible compute can sustain agent work—and how expensive those loops can become.
 36:07ENTheo - t3․gg· 2026년 10월 27일Theo on Token Costs, Coding Agents, and the Price of AI CapabilityTheo Browne · Ping LabsA viral estimate of Lauren's AI spending prompts a closer look at cache pricing, benchmarks, and the changing work of coding agents.
 30:37ENTheo - t3․gg· 2026년 10월 26일Theo’s Three Skills for Reviewing and Shipping with Coding AgentsTheo Browne · Ping LabsHow sol-loop, full-send and full-stop encode review, verification and different levels of merge authority.
 0:43ENTheo - t3․gg· 2026년 10월 23일Theo Distinguishes Security Vulnerabilities from Active AttacksTheo Browne · Ping LabsA short explanation of why disclosed software flaws and reported attacks are different kinds of security news.
 29:22ENTheo - t3․gg· 2026년 10월 22일Theo on Security Vulnerabilities, Stolen API Keys and AITheo Browne · Ping LabsA look at the gap between vulnerability disclosure and patching, and a speculative account of why stolen inference keys may be valuable.
 31:13ENTheo - t3․gg· 2026년 10월 20일Theo on Why Smarter Models Help More Than DevelopersTheo Browne · Ping LabsFrom game modifications to compiler experiments, Theo revisits his assumptions about who benefits from more capable AI.