








필터 결과
1,543개정렬
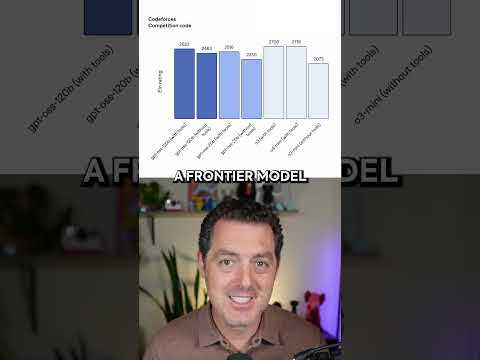 1:01EN
 Matthew Berman· 2025년 8월 5일OpenAI’s gpt-oss Release and a Coding BenchmarkMatthew Berman · Forward FutureMatthew Berman introduces two open-weight models and reviews a Codeforces comparison from the launch.
 10:28ENMatthew Berman· 2025년 8월 5일OpenAI’s gpt-oss Models: Open Weights, Benchmarks and SafetyMatthew Berman · Forward FutureMatthew Berman reviews the 120b and 20b models, local deployment claims, selected evaluations and the scope of OpenAI’s safety testing.
 3:13ENMatthew Berman· 2025년 8월 5일Claude Opus 4.1: Anthropic’s August 2025 Benchmark UpdateMatthew Berman · Forward FutureMatthew Berman reviews the model’s reported coding, reasoning and tool-use results, including one benchmark that declined.
 1:27:01EN
 Cognitive Revolution "How AI Changes Everything"· 2025년 8월 2일팟캐스트The $16 Trillion Services Market Is Being Bought, Not Sold To진행자 Nathan LabenzMarc Bhargava of General Catalyst explains how AI-enabled rollups turn low-margin service firms into compounding, software-like businesses.
 8:17ENMatthew Berman· 2025년 7월 31일ASI-Arch: An Automated Search for Neural Network ArchitecturesMatthew Berman · Forward FutureMatthew Berman explains a 2025 research system that proposes, trains and evaluates model designs in an iterative loop.
 15:30ENMatthew Berman· 2025년 7월 31일Qwen3 Tested: Coding Demos, Long Context and Response BehaviorMatthew Berman · Forward FutureMatthew Berman tests generated simulations, political and safety prompts, hand tracking and word puzzles using a hosted Qwen3 model.
 11:28ENMatthew Berman· 2025년 7월 30일GLM-4.5: Coding Demos, Model Sizes and Z.ai’s BenchmarksMatthew Berman · Forward FutureMatthew Berman tests interactive applications built with GLM-4.5 and examines Z.ai’s reported comparisons with leading models in July 2025.
 2:14:55ENCognitive Revolution "How AI Changes Everything"· 2025년 7월 26일팟캐스트From Character AI to a 1% Warning Shot: Gabriel Weil's Case for Liability as AI Governance진행자 Nathan LabenzA Touro law professor tells Nathan Labenz how negligence, strict liability, and punitive damages could make frontier labs treat public risk as a hit to their own balance sheet.
 6:53ENMatthew Berman· 2025년 7월 24일Qwen3-Coder: An Open-Weight Coding Model and Its Command-Line AgentMatthew Berman · Forward FutureMatthew Berman examines Qwen’s July 2025 coding model, its training and benchmark results, and tries its command-line tool on a Snake game.
 23:39ZH
 跟李沐学AI· 2025년 7월 23일李沐:给文本大模型加入一千万小时语音,开源 Higgs Audio李沐 · Boson AI李沐介绍团队如何在文本大语言模型的训练里加入大量语音数据,做成能听能说的 AudioLLM,并把 Higgs Audio 开源。他讲了架构取舍、token 压缩、数据从哪来,以及怎么在 3090 上跑起来。
 1:56:16ENCognitive Revolution "How AI Changes Everything"· 2025년 7월 22일팟캐스트SB 813 Would Hand AI Safety Checks to Licensed Private Firms — If Government Can Watch the Watchers진행자 Nathan LabenzGillian Hadfield and Andrew Freedman want California to set AI safety outcomes, license competing certifiers, and give companies a rebuttable presumption in court if they pass.
 38:10ENCognitive Revolution "How AI Changes Everything"· 2025년 7월 16일팟캐스트Plus Five for Format, Plus Ten if It Compiles진행자 Nathan LabenzPredibase CEO Dev Rishi explains how reinforcement fine-tuning, production feedback, and narrow specialist models turn one-off training into systems that keep learning.
 12:14ENMatthew Berman· 2025년 7월 16일AI News: Windsurf’s Acquisition, Meta Compute Plans, Grok and VoxtralMatthew Berman · Forward FutureA July 2025 roundup examines developer-tool deals, AI infrastructure, model behavior, reward methods and speech recognition.
 15:23ENMatthew Berman· 2025년 7월 13일Grok 4’s Early Reception: Impressive Demos, Safety Questions and Mixed User FeedbackMatthew Berman · Forward FutureMatthew Berman surveys early reactions to xAI’s 2025 model release, from physics simulations and benchmark results to concerns about bias, safety and speed.
 26:09ENMatthew Berman· 2025년 7월 11일Grok 4 and Heavy Tested: Coding, Images, Reasoning and Practical QuestionsMatthew Berman · Forward FutureMatthew Berman’s July 2025 hands-on trials produce interactive prototypes and several failures, with important limits on what single examples can establish.
 1:28:48ENCognitive Revolution "How AI Changes Everything"· 2025년 7월 10일팟캐스트Doctors code at 45%. The model beat them by 12 points — then 4,000 physicians had to try it once.진행자 Nathan LabenzAmbience Healthcare and Cleveland Clinic walk through the AI scribe that cut pajama time, climbed ICD-10 with reinforcement fine-tuning, and won 75% voluntary use.
 13:07ENMatthew Berman· 2025년 7월 10일AI News: Grok Controversy, New Models and the Competition for TalentMatthew Berman · Forward FutureMatthew Berman surveys Grok’s antisemitic posts, coding and creative tools, model releases, antibody design and AI hiring in July 2025.
 1:42:06ENCognitive Revolution "How AI Changes Everything"· 2025년 7월 8일팟캐스트Every Frontier Lab Is Spending a Billion a Year on Data. Here Is Where It Goes진행자 Nathan LabenzLabelbox CEO Manu Sharma on the $15 billion Scale deal, RL “gyms,” $250,000 trainers, and why post-training now eats the budget that used to belong to pre-training.
 1:19:46ENCognitive Revolution "How AI Changes Everything"· 2025년 7월 5일팟캐스트Suspended from Columbia, He Raised $15 Million to Cheat on Everything진행자 Nathan LabenzRoy Lee, founder of Cluely, argues that an undetectable desktop overlay, AI maximalism, and a post-AGI life of 800-year spans are the same bet.
 1:25:32ENCognitive Revolution "How AI Changes Everything"· 2025년 7월 2일팟캐스트o3 Invented a Voting Rule and Kept the Job: Four Weeks Inside the AI Village진행자 Nathan LabenzAdam Binksmith on putting Claude, o3, and Gemini in a shared world for weeks—and why most people still imagine multi-agent life as one AI times four.
 27:40ENMatthew Berman· 2025년 6월 28일Seedance 1.0 vs. Veo 3: An Informal Text-to-Video ComparisonMatthew Berman · Forward FutureMatthew Berman compares visual quality, motion and prompt adherence across gymnastics, action, animation and fantasy scenes.
 1:23:32ENCognitive Revolution "How AI Changes Everything"· 2025년 6월 28일팟캐스트HTTP 402 Slept for Thirty Years. Coinbase Turned It Into a Payment Protocol for AI Agents진행자 Nathan LabenzNemil Dalal, Coinbase's developer platform lead, explains x402, the open standard that lets agents pay for APIs with stablecoins instead of ads or credit cards.
 20:44ENMatthew Berman· 2025년 6월 27일AI News: DeepSeek Reports, OpenAI Disputes and Google’s New ToolsMatthew Berman · Forward FutureMatthew Berman reviews June 2025 reporting on model development, talent moves, trademark and copyright disputes, and new AI products and research.
 4:05:15EN
 Lex Fridman· 2025년 6월 26일팟캐스트They could not agree whether Iran was building a bomb. They still wanted the same next move.진행자 Lex FridmanAfter the Iran-Israel ceasefire, Scott Horton and Mark Dubowitz spend four hours on Lex Fridman arguing over enrichment math, a stolen archive, and whether bombing Fordo makes a weapon more likely or less.
더 보기1,543개 중 24개 표시