30 秒でわかる
At the July 2025 Grok 4 launch, xAI described using more reinforcement-learning compute and explicitly training the model to use tools. Grok 4 Heavy used multiple agents to work on and compare answers; the team showed benchmark charts and live examples, including a simplified black-hole visualization and a simulated vending business. Musk also acknowledged weaknesses in image understanding and presented future capabilities as plans and predictions.
- 1xAI increased reinforcement-learning computeThe presenters distinguish pretraining from the additional compute devoted to reasoning and reinforcement learning.
- 2Grok 4 Heavy compares work from multiple agentsThe team describes parallel agents solving a problem and comparing candidate solutions rather than relying on a simple majority vote.
- 3The black-hole demonstration intentionally simplified physicsA presenter says the browser visualization exaggerates waves and uses approximations rather than a full general-relativity calculation.
- 4The team identifies visual understanding as a weaknessMusk says image understanding and generation needed improvement and describes a newer foundation model in training.
- 5Vending-Bench tests a simulated business over timeThe benchmark’s presenters describe inventory, supplier and pricing decisions and report stronger results for Grok 4 in their simulation.
ポイント
- xAI described training Grok 4 to use tools and using multiple agents in the Heavy variant.
- The team demonstrated a browser visualization and a simulated vending business; the visualization used explicit physical simplifications.
- Musk identified image understanding as a weakness and discussed later improvements as future work.
チャプターごとに整えた全文を読む
Training Grok 4 and testing reasoning
Musk and the xAI team introduce the model, its reinforcement-learning training and Humanity’s Last Exam.
Elon Musk opens the July 2025 Grok 4 release, saying the team will show benchmark results and examples of the model’s reasoning.
Musk says training increased substantially between Grok 2, Grok 3 and Grok 4. The team distinguishes pretraining compute from compute used for reinforcement learning and reasoning.
The presenters describe scaling training and using problems with verifiable outcomes to reward correct reasoning. They attribute the model’s improvement in part to increased reinforcement-learning compute.
The team introduces Humanity’s Last Exam, a benchmark with 2,500 expert-curated questions across mathematics, sciences, engineering and other subjects. They describe examples in category theory, chemistry and linguistics.
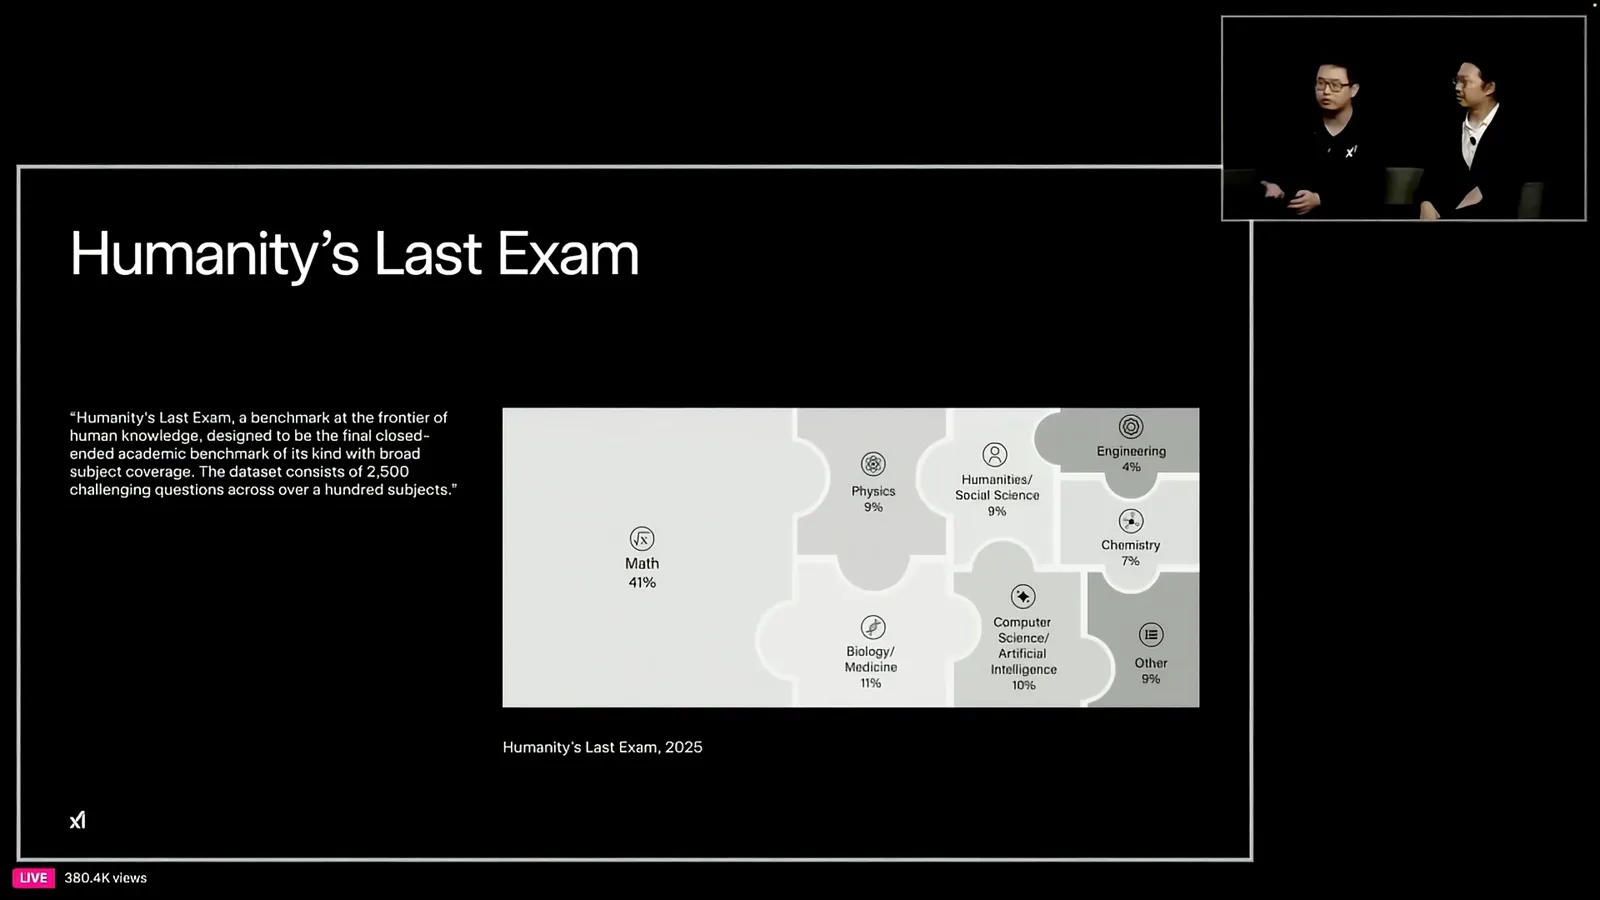
Musk argues the model performs exceptionally on academic questions across disciplines. He acknowledges that it can lack common sense and had not yet invented new technologies or discovered new physics; he predicts those capabilities will follow.
An xAI presenter says more training compute improved results on the exam. The team also trained the model explicitly to use tools, rather than only prompting it to use tools without specific training.
Tool use, safety and multiple agents
The team discusses training for tool use, safety goals and a multi-agent Heavy variant.
Musk says existing tool use is still limited compared with engineering software used at Tesla or SpaceX. He describes giving AI access to more capable simulation tools and, eventually, robots that interact with the physical world.
Musk discusses AI safety and argues for a model that seeks truth. He compares the challenge to instilling values in a child who may later become much more capable.
Musk speculates about a much larger future economy and the energy available at planetary or stellar scale. He says he expects AI to be beneficial, while acknowledging uncertainty.
The team describes a training-data challenge: reinforcement learning needs difficult problems and reliable signals that distinguish correct from incorrect answers. As models improve, finding enough challenging tasks becomes harder.
Musk says real-world outcomes can test AI-generated ideas: for example, whether a rocket reaches orbit, a car works or a medicine is effective.
The presenters say additional test-time compute improves performance. Musk describes Grok 4 Heavy as multiple agents working independently, comparing their approaches and putting forward an answer.
A presenter starts an exam problem and a prediction-market research task using Grok 4 Heavy. The team says the latter will examine the odds of baseball teams winning the World Series.
Live demonstrations and benchmark comparisons
Presenters show a math problem, prediction-market research and a simplified black-hole visualization.
Another presenter demonstrates a visualization of two black holes merging. He says the browser animation exaggerates gravitational waves to make them visible and uses approximations rather than a full general-relativity calculation.
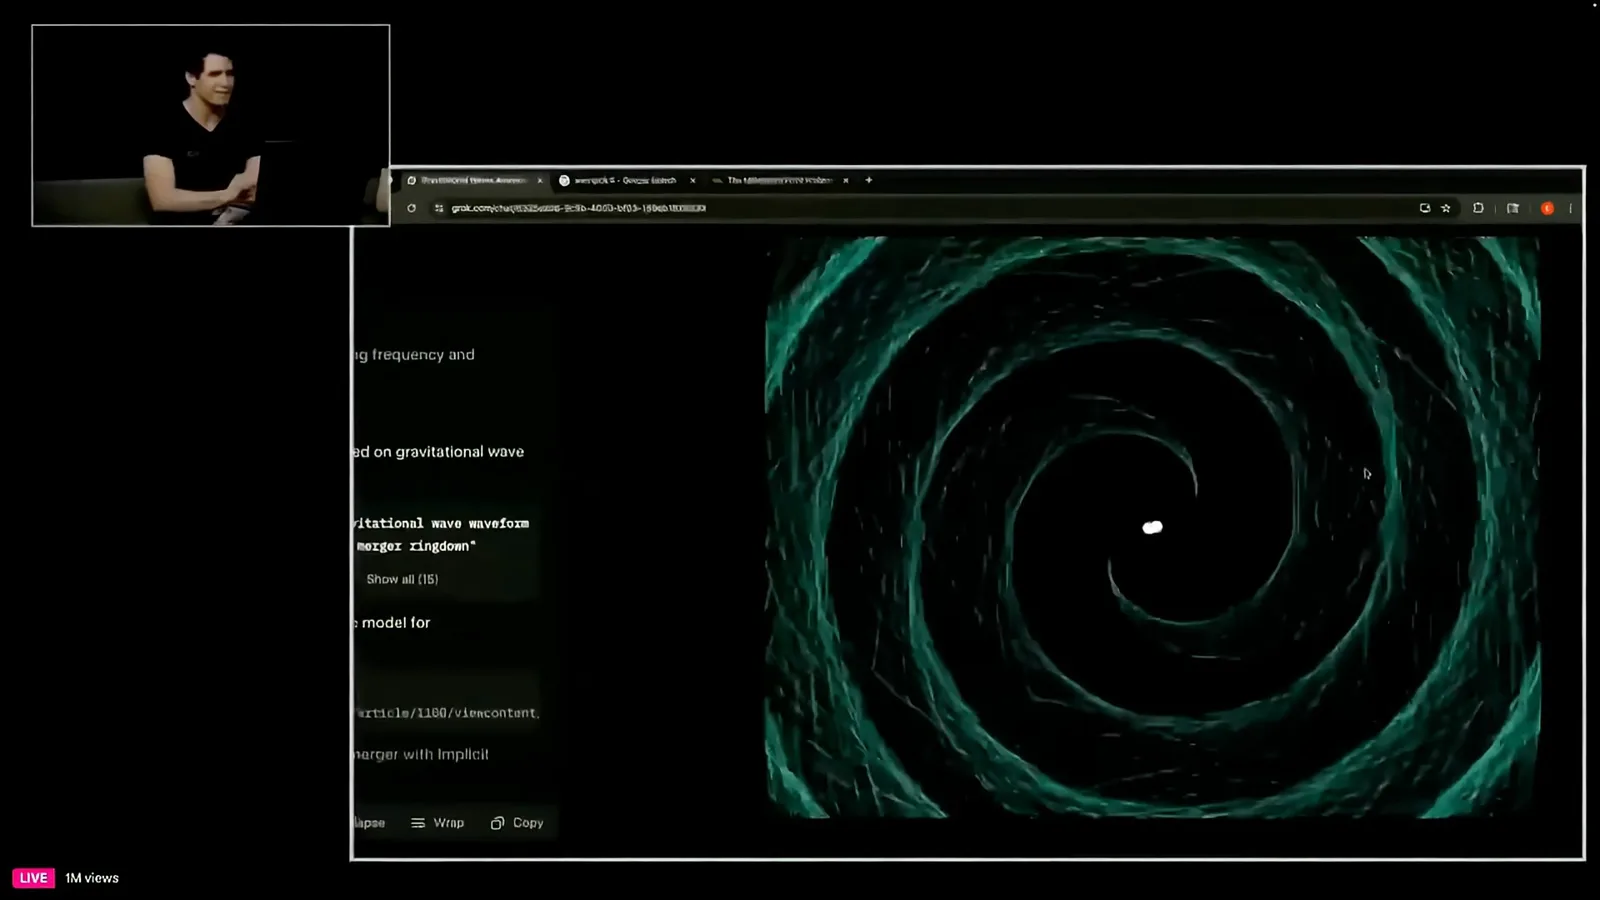
The presenter says the model searched for sources and considered constants for the visualization. Musk suggests that future models could be connected to the simulation tools used by physics researchers.
The team returns to the math task and describes the model’s working process. It also shows research that collects benchmark announcements and results over time.
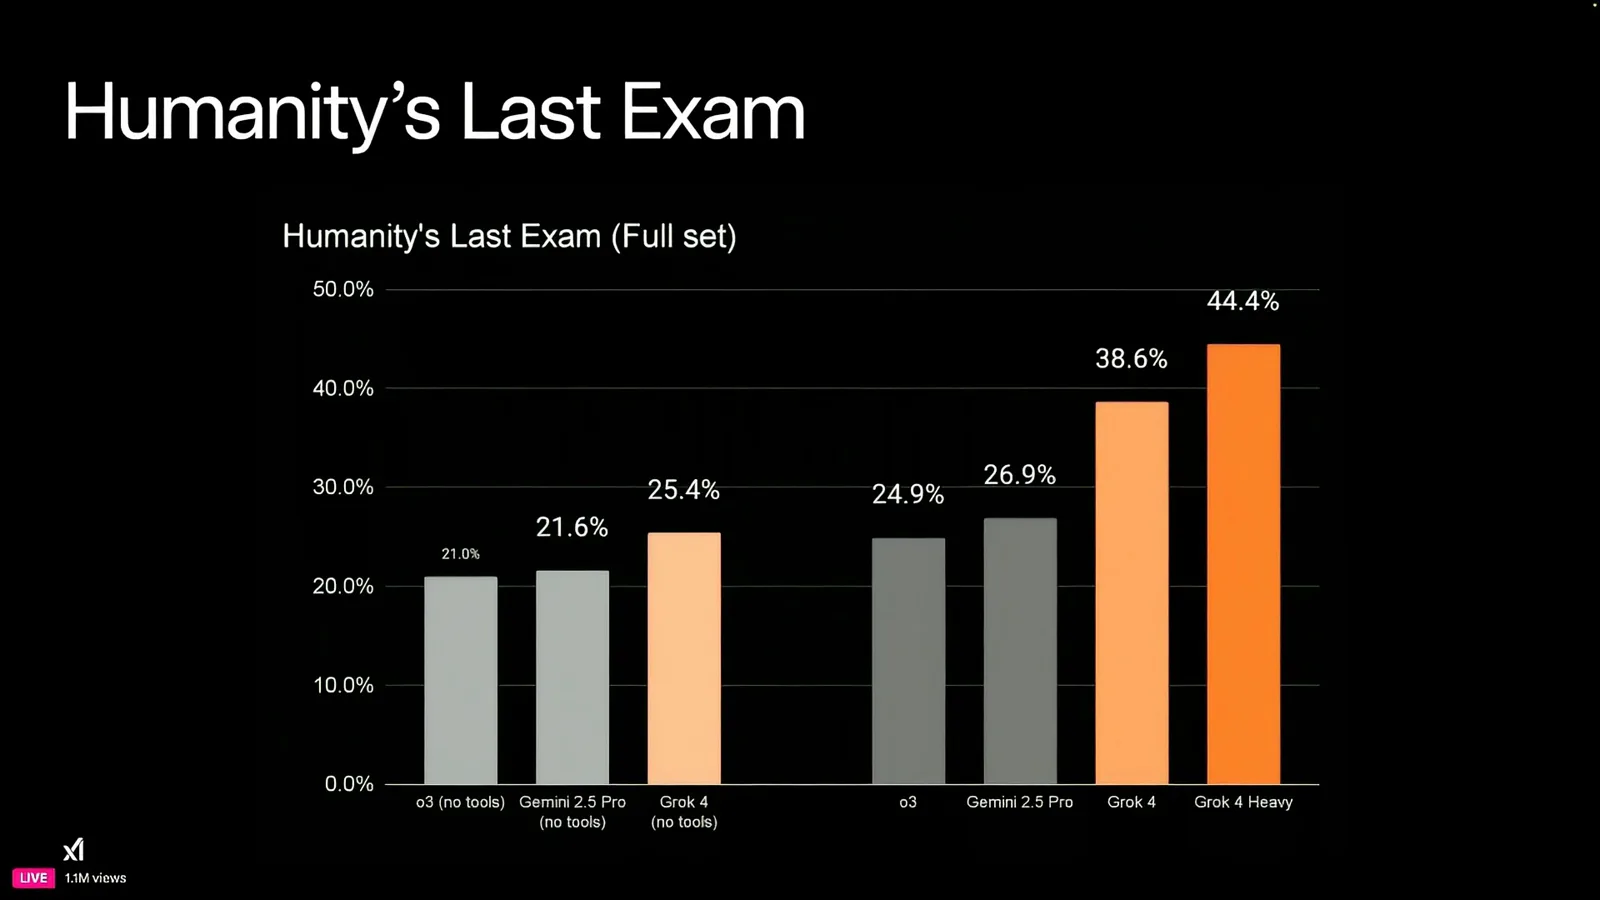
The presenters show results on the full Humanity’s Last Exam, including image-based questions. Musk says visual understanding is a weakness and describes another foundation model being trained to improve it.
The Heavy research demonstration reports a 21.6% estimate for the Dodgers to win the World Series. The presenter says the model consulted odds sites and took about four and a half minutes of compute.
The team shows additional mathematics, science and coding benchmarks. These are results presented by xAI at launch, with comparisons and test conditions shown on its slides.
The presenters introduce access to Grok 4 and Grok 4 Heavy and say they limited usage during the live demonstration. They describe Heavy as a way to deploy several research agents on a task.
Voice, API and a simulated vending business
The team demonstrates voice interaction, discusses ARC-AGI and presents Vending-Bench results.
The team introduces updated voice options and demonstrates a British voice responding to conversational prompts, including a request to whisper and another to sing.
The presenters compare response timing and interruptions in a short voice interaction. They say they have reduced latency and intend to continue improving the experience.
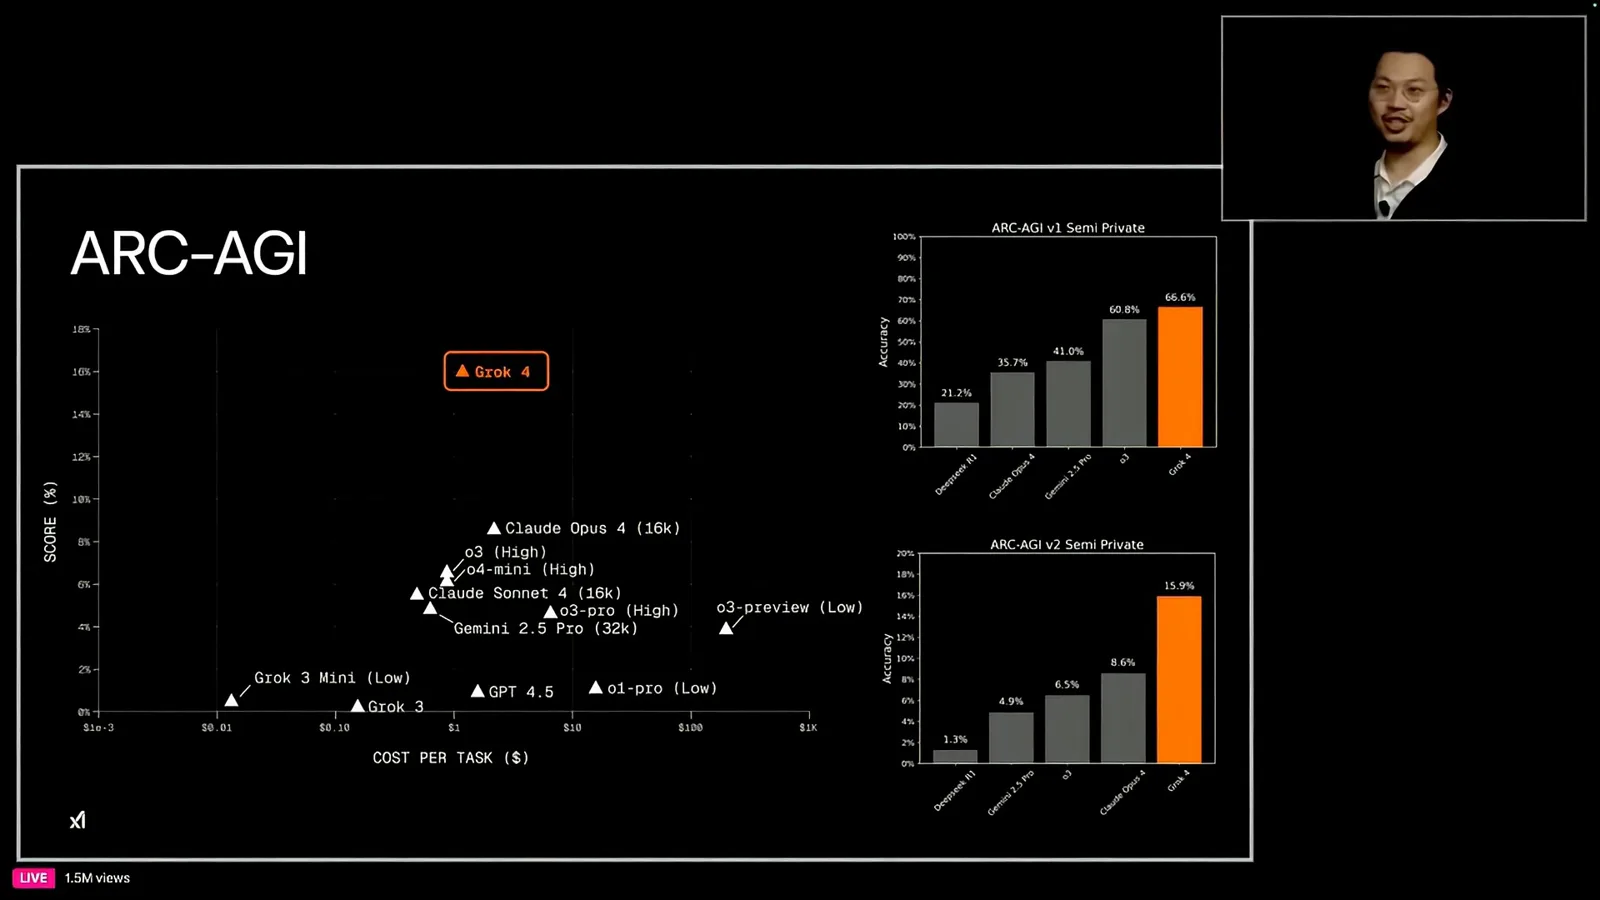
The team says Grok 4 is also available through an API. It presents ARC-AGI results and attributes the reported evaluation to an independent tester with early access.
Representatives of the Vending-Bench project describe a simulated vending-machine business. The model must manage stock, contact suppliers and set prices across an extended sequence of decisions.
The benchmark presenters report that Grok 4 achieved higher simulated net worth than models they had tested. They emphasize consistency and the value of testing AI in scenarios resembling real work.
The xAI team describes early examples in research and finance, and says the API supports a 256,000-token context. It presents these as applications developers were beginning to explore.
Applications and future model plans
Presenters discuss research, games, coding and planned improvements in multimodal and video capabilities.
A game-development example shows a first-person game created with model assistance. The presenters emphasize finding and preparing assets as well as writing game logic.
Musk says future models will need better video understanding to play and evaluate games. He predicts improvements in game and video creation, presenting the timing as an expectation.
The team says a specialized coding model is under development and identifies multimodal understanding as an area for improvement. It describes plans for later image, video and audio capabilities.
The presenters discuss a future video-generation model and possible interactive content. Musk says training is expected to begin in the coming weeks, before the team closes the launch.
同じチャンネルの記事
 37:06EN
 Brighter with Herbert· 2026年9月2日The AI Power Shortfall and the Missing Plan for Workersゲスト Jo Bhakdi, Elon Musk · ホスト Herbert OngHerbert Ong and Jo Bhakdi discuss Musk’s AI forecasts, orbital computing and how displaced workers might share the gains.
 21:07ENBrighter with Herbert· 2026年6月5日Why Musk Says SpaceX Needed Public Capitalゲスト Elon Musk · ホスト Jamie DimonAt a JPMorgan roadshow, Musk discusses planned Starlink expansion, orbital AI, Starship reuse and the company’s culture.