30 秒でわかる
Theo reviews Fable 5 shortly after its June 2026 release, comparing benchmark results and describing projects built with the model. He reports both successful iteration and serious failures, discusses safeguards and data retention, and argues for ambitious experimentation with verification.
- 1Benchmarks and safeguardsTheo distinguishes measured model performance from refusals and fallback behavior.
- 2A large migration with caveatsAn old application worked after several rounds of feedback; a later port still had major regressions.
- 3Usage costs escalatedTheo says one intense workflow spent $100 in eight minutes on usage billing and remained unfinished.
- 4A mistaken auditThe model misunderstood staging and production and continued to flag a problem after clarification.
- 5Analyzing SkateBenchThe model found a naming-pattern explanation for errors, despite missing the same questions.
- 6Explore while verifyingTheo highlights fuzzing and independent review but explicitly rejects abandoning code review.
ポイント
- Safeguards and refusals can affect benchmark scores and product behavior.
- Theo reports promising coding results but questions the methodology or variability of some benchmarks.
- A large modernization required several feedback rounds, while a further migration still broke important functionality.
- Intensive workflows can consume usage quickly and produce incorrect audits.
- Human review and testing remain necessary even when a model can explore larger tasks.
チャプターごとに整えた全文を読む
First impressions and benchmarks
Theo introduces the model and distinguishes benchmark outcomes from safeguard effects. He discusses several evaluations and their limits.
I have been testing Fable 5 intensely since its release. Anthropic describes it as the same underlying model as Mythos 5 with additional safeguards. I am impressed by what it can do, but I also ran into refusals, costs and mistakes that matter when assessing it.
Some benchmark tables label results as Mythos 5/Fable 5, but safeguards can change the outcome. I report a roughly 20-point Terminal-Bench drop in the Fable comparison because it refused some tasks. The distinction between model capability and the product’s actual behavior matters.
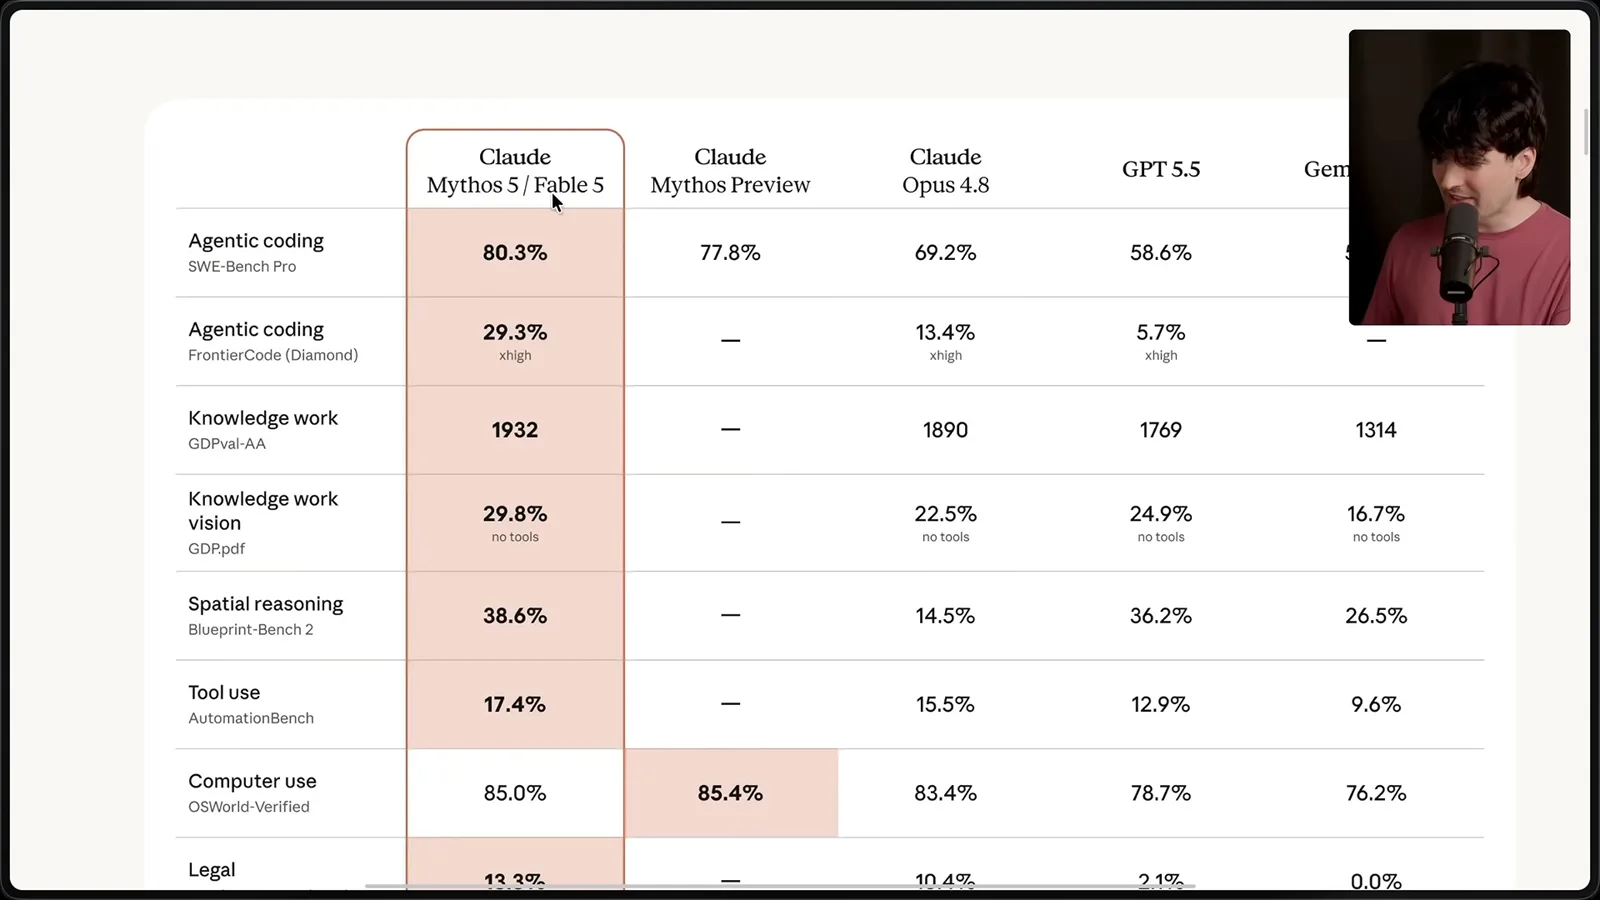
The displayed SWE-bench Pro score is around 80%, but I am skeptical of that benchmark because it uses existing pull requests. I worry a model might have encountered relevant material during training. This is a methodological concern, not evidence that a specific test was contaminated.
FrontierCode’s hardest tier shows a roughly 29% result for Mythos/Fable, compared with about 13% for Opus 4.8 and 5.7% for GPT-5.5 in the displayed table. I also see strong vision and spatial results, but a benchmark measures a particular task and configuration, not every aspect of intelligence.
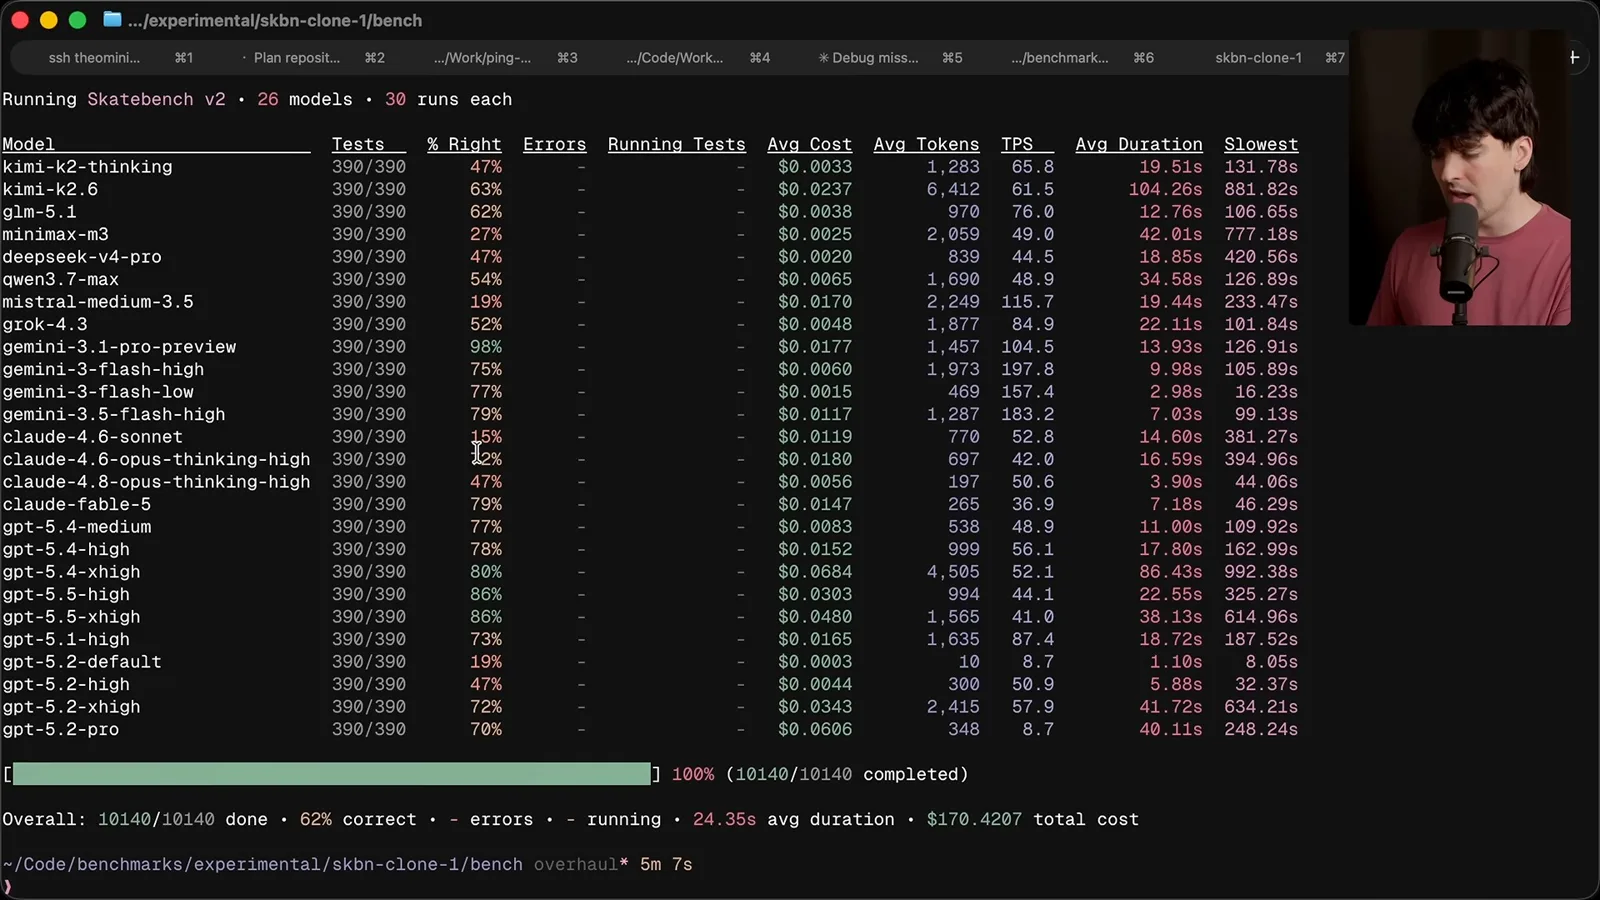
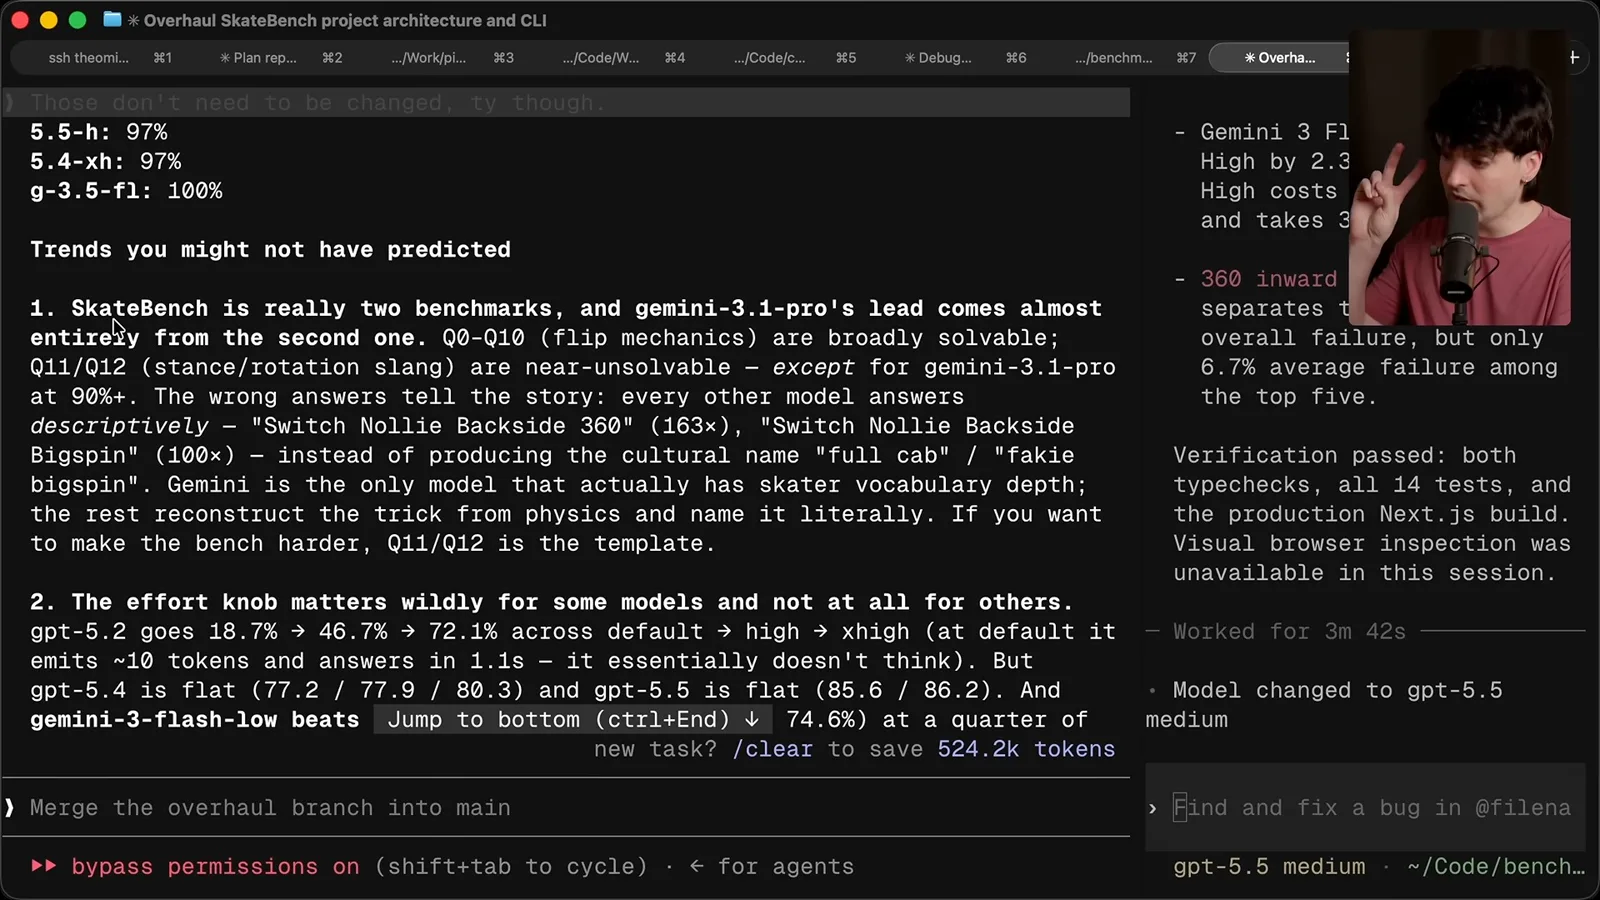
My own SkateBench asks models to name skateboard tricks from spatial descriptions. In the run shown, Fable scored 79% while Gemini 3.1 Pro scored 98%; a prior high-effort Fable run reached 83%. It is a niche test, useful for exploring differences rather than a general ranking.
I also have concerns about variability on FrontierCode: the displayed Opus scores do not rise consistently with reasoning effort. That pattern makes me cautious about interpreting the result, although it does not by itself prove why the scores vary.
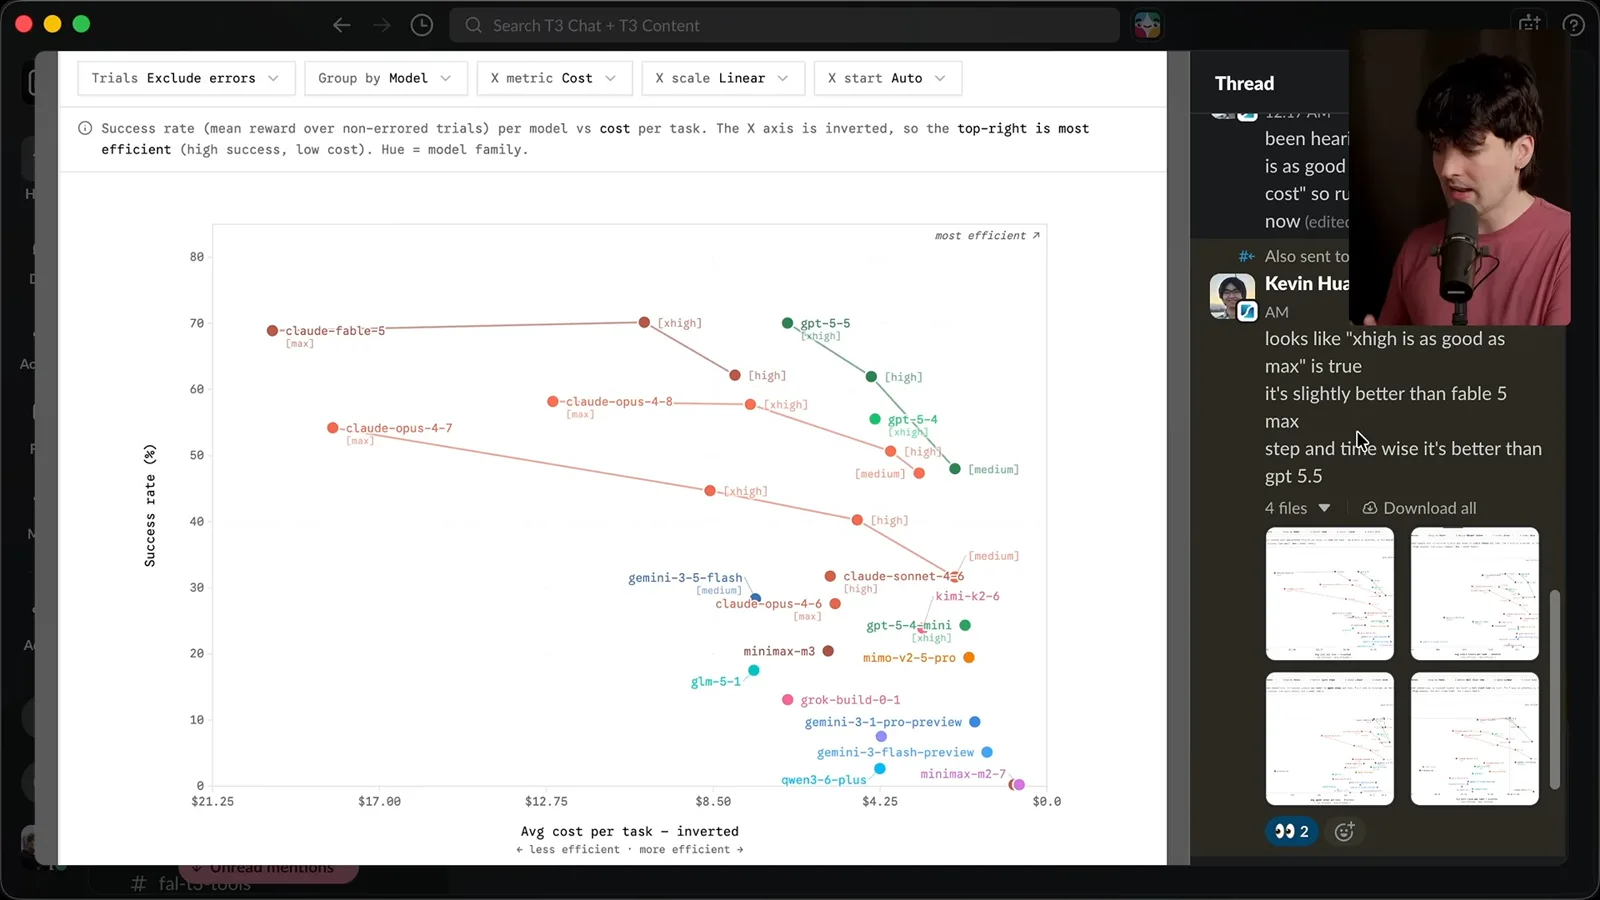
DataCurve shared early Deep SWE results with me. In that evaluation, I read Fable at xhigh as roughly comparable to GPT-5.5 and better than the displayed Opus results at a lower cost per task. That is a specific evaluation, not a guarantee about price or performance across workloads.
At the time I quoted API prices of $10 per million input tokens and $50 per million output tokens, and a limited subscription-access window. I expected these terms to change with capacity. Prices, limits and availability here describe the June 2026 release, not current terms.
Real projects, failures and costs
He tests modernization and migration work. The examples include successful iteration, regressions and rapidly rising usage costs.
In practice I find the model unusually thorough. I asked it to modernize my old ping.gg streaming application. The first build did not work, but after roughly four rounds of screenshots and error feedback it produced a working version of a large change; it was not a one-shot success.
I pushed further by asking for a migration to a newer stack. It got surprisingly far, but the resulting port broke core functionality and introduced UI and authentication issues. This is a useful example of progress and limitations existing together: the result still needed substantial work.
I hit a limit during that workflow and switched to usage-based billing. The run consumed $100 in roughly eight minutes, and a second subscription hit its session limit as well; I stopped with the task unfinished. Those figures are my experience with a particularly intense workflow.
A Lakebed audit exposed another failure. My main branch deployed to staging while production used a separate branch, but the model compared the wrong environments and insisted there was a serious incompatibility. Even after I explained the setup, its revised report continued to recommend a fix I thought unnecessary.
Safeguards and demonstrations
Theo describes fallback and refusal experiences, then shows UI and game examples. He also has the model analyze his own benchmark.
My own refusal experience varied by interface. In one case a question about my own site’s discoverability was routed to Opus until I clarified my identity and intent. Other users reported more refusals. Anthropic’s system card also described an initially invisible intervention for frontier model development; that policy was subsequently changed, and this video reflects its earlier state.
Artificial Analysis reported fallback on about 8% of tasks in its intelligence-index evaluation, while Anthropic had described an average below 5% of sessions. Those percentages use different denominators and workloads, so they should not be treated as directly conflicting estimates. Fallback and refusals can affect how scores are read.
I like many of the generated UI examples better than previous outputs, though I cannot tell whether that reflects better design judgment or simply better templates. Some examples still look poor. They are starting points, not evidence that visual review is unnecessary.
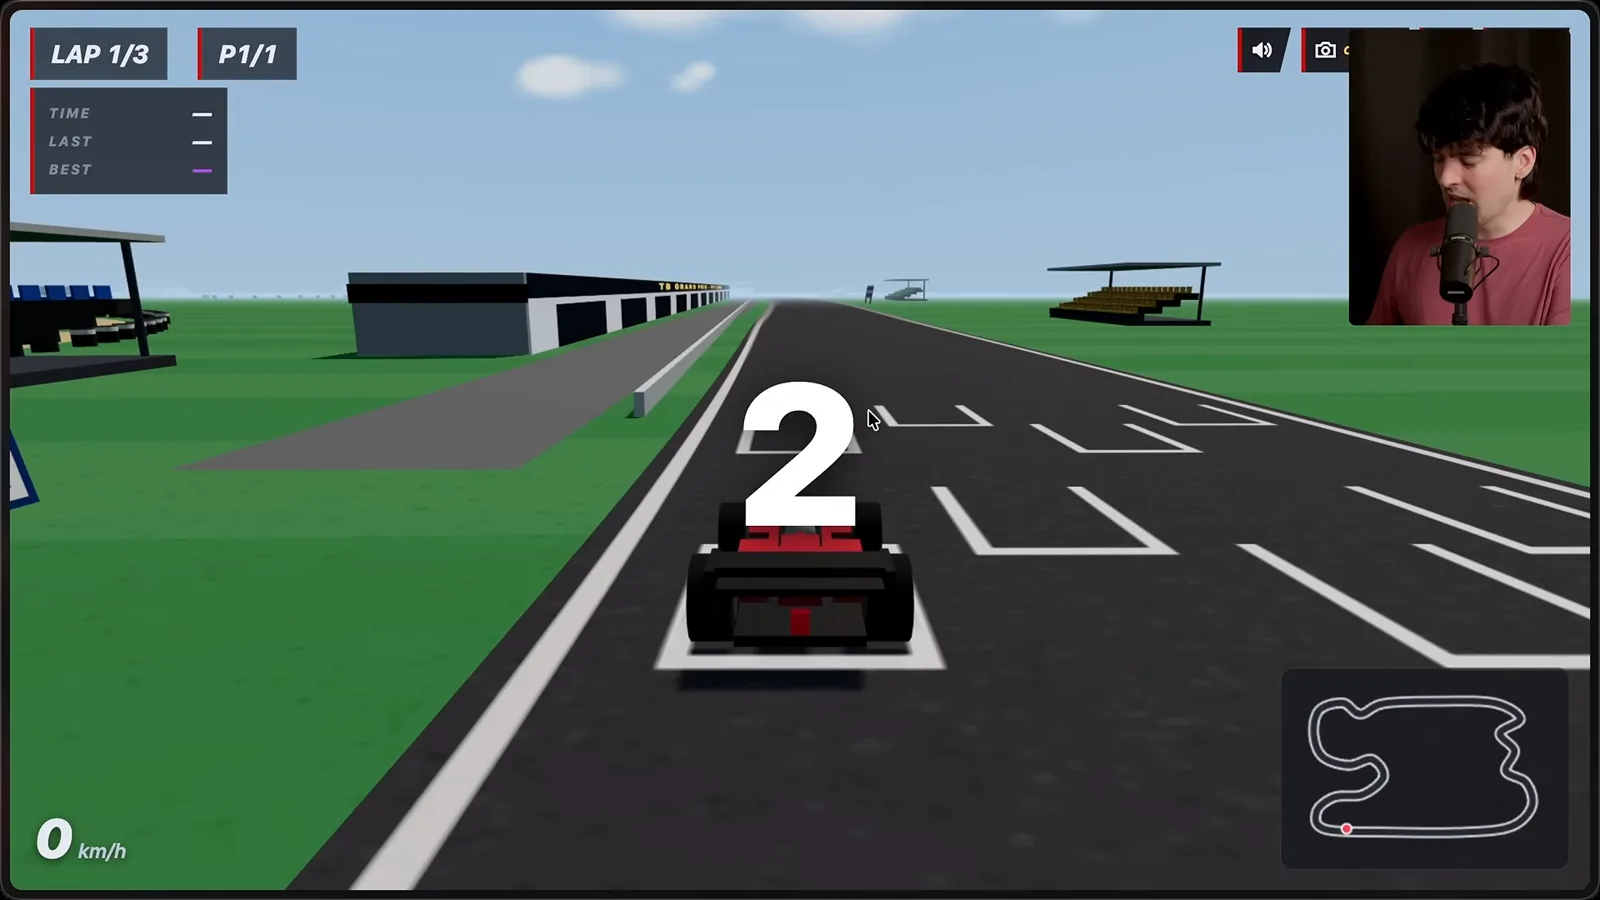
My team also built playful examples: a terminal adventure, a Rust terminal interface, a block-building game and a multiplayer racing game. These demonstrations show what people produced with the model, but they do not establish that every feature was generated without human work or that the projects are production-ready.
I asked the model to analyze SkateBench results. It suggested that two questions distinguish naming conventions from the literal description of motion: many models describe the movement but miss the established trick name. It identified a pattern even though it had missed those questions itself.
Data, code quality and verification
He discusses the announced retention policy and qualitative code impressions. He encourages bigger experiments with testing and human review.
Anthropic announced a 30-day data-retention requirement for Fable traffic and said it would not use the data to train new Claude models or for non-safety purposes. I speculate about the sources of the model’s improvement, but my claim about training on user histories is not established by that retention announcement.
I also discuss another developer’s early experience building Python tooling and improving a database agent. My own impression is that Fable’s code is often more readable and better structured, but that is a qualitative judgment. It still makes mistakes and needs review.
I am experimenting with broader tasks, independent review and letting agents test their own work. For Lakebed, the model wrote fuzzers that found issues during a database overhaul. That makes me more willing to let it explore, but I am not saying to stop reading code or skip verification.
My advice is to test the boundaries: give an agent a harder problem, see where it fails and give it tools or tests to unblock itself. My experience is encouraging, not a promise that a model can safely rewrite any system. Keep human review, stay curious and compare the results with the actual requirements.
同じチャンネルの記事
 38:47EN
 Theo - t3․gg· 2026年10月28日Theo’s Long-Running Agent Experiments: Verification, Compute and CostTheo Browne · Ping LabsA skateboard game and two compiler projects show how repeated checks and flexible compute can sustain agent work—and how expensive those loops can become.
 36:07ENTheo - t3․gg· 2026年10月27日Theo on Token Costs, Coding Agents, and the Price of AI CapabilityTheo Browne · Ping LabsA viral estimate of Lauren's AI spending prompts a closer look at cache pricing, benchmarks, and the changing work of coding agents.
 30:37ENTheo - t3․gg· 2026年10月26日Theo’s Three Skills for Reviewing and Shipping with Coding AgentsTheo Browne · Ping LabsHow sol-loop, full-send and full-stop encode review, verification and different levels of merge authority.
 0:43ENTheo - t3․gg· 2026年10月23日Theo Distinguishes Security Vulnerabilities from Active AttacksTheo Browne · Ping LabsA short explanation of why disclosed software flaws and reported attacks are different kinds of security news.
 29:22ENTheo - t3․gg· 2026年10月22日Theo on Security Vulnerabilities, Stolen API Keys and AITheo Browne · Ping LabsA look at the gap between vulnerability disclosure and patching, and a speculative account of why stolen inference keys may be valuable.
 31:13ENTheo - t3․gg· 2026年10月20日Theo on Why Smarter Models Help More Than DevelopersTheo Browne · Ping LabsFrom game modifications to compiler experiments, Theo revisits his assumptions about who benefits from more capable AI.