30 秒でわかる
Theo describes a period of intensive Fable use and experiments with subscription limits, multi-agent workflows and remote machines. He illustrates PR comparison and prioritization, and acknowledges that higher code output does not guarantee validated or useful work. His account and price estimates reflect the time of recording.
- 1Usage is not the same as valueTheo reports high estimated inference usage but says the exercise is not about efficiency per token.
- 2Compare competing PRsAgents independently audit three Lakebed implementations and synthesize a recommendation.
- 3Surface work worth reviewingA ranked PR queue helps maintainers see promising work and the next action.
- 4Long tasks and sleepA remote machine can keep work running after closing a laptop, while the temptation to keep checking remains.
- 5Solve problems, then verifyTheo urges experimentation while acknowledging that generated code still needs validation.
ポイント
- Estimated inference value is not the same as actual savings or useful output.
- Parallel agent reviews can compare competing implementations but still require verification.
- Ranked PR queues and readable plans can help teams find and coordinate work.
- Remote execution can support long tasks without keeping a laptop open, though it does not resolve overwork by itself.
- Focus on solving problems and checking results rather than simply generating more code.
チャプターごとに整えた全文を読む
The temporary testing window
Theo describes heavy use and estimated inference value. His figures and plan terms reflect his own experience at recording time.
I have been using Fable heavily enough that it has affected my sleep and video schedule. At recording time I expected access through certain Claude subscriptions to end soon, so I wanted to experiment with what the model could do before that window closed. Availability and plan terms discussed here are historical.
I estimate that my recent inference across a laptop and a Mac mini would have cost thousands of dollars at the measured rates. That is an estimate of usage value, not money I saved or a promise about anyone else’s plan. This video is about exploring generous limits, not maximizing useful output per token.
I describe a five-hour session window and a separate weekly limit as they appeared on my accounts. I tried starting a session window early and scheduling a small request so it would reset sooner. This is a snapshot of my own setup; limits, product behavior and permitted use can change.
I used Hermes Agent on a Mac mini for that scheduled task and discuss switching between two Claude accounts. I also warn that the desktop app’s session history did not follow my account switches as I expected. My account-switching experience is not a guarantee that a workflow can always be recovered or that every use is permitted.
A multi-agent PR comparison
He assigns agents to audit and compare competing implementations. He watches usage rise as the workflow runs.
A more useful example is a Lakebed file-storage decision. Three PRs, 35, 37 and 39, implement similar features in different ways. I had agents compare earlier implementations and synthesize a third, but I still wanted a more thorough independent review before deciding what to merge.
I asked for a workflow with separate judges to audit each PR, compare them and identify useful pieces to carry forward. The resulting process included audit, judgment, verification, harvesting and synthesis. It is a way to generate evidence for a decision, not proof that the chosen implementation is correct.
Parallelism burns through usage quickly. In my demonstration eight agents were running at once, and the workflow accumulated hundreds of thousands of tokens very rapidly. It also showed how a limit interruption can be disruptive when a large workflow does not resume cleanly.
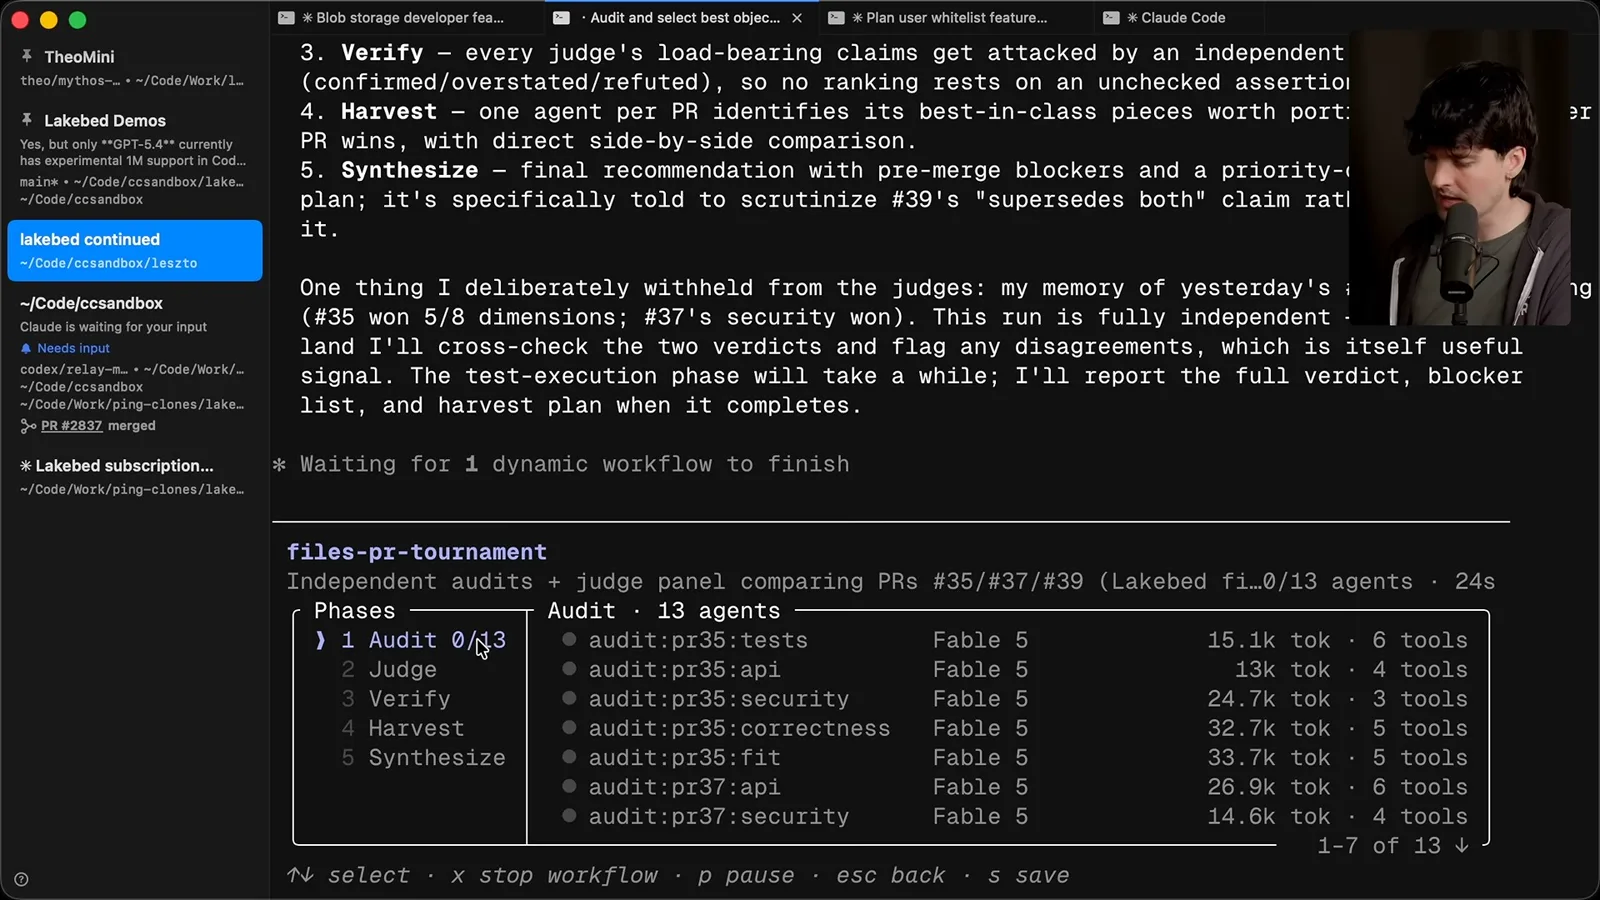
On one account I observed a rough relationship between the five-hour and weekly limits, but that was basic personal testing, not a published guarantee. I was aiming to use the remaining allowance in a short window; that strategy is not necessarily economical or useful for someone else.
Prioritization and readable plans
Agents surface promising pull requests and produce HTML plans. Theo shares these artifacts with teammates and other agents.
I maintain several repositories, and T3 Code receives more issues and PRs than I can comfortably read. Instead of trying to inspect everything manually, I have an agent produce a ranked queue that surfaces promising, low-friction changes and explains the next action. A teammate quickly merged one small fix after seeing the list.
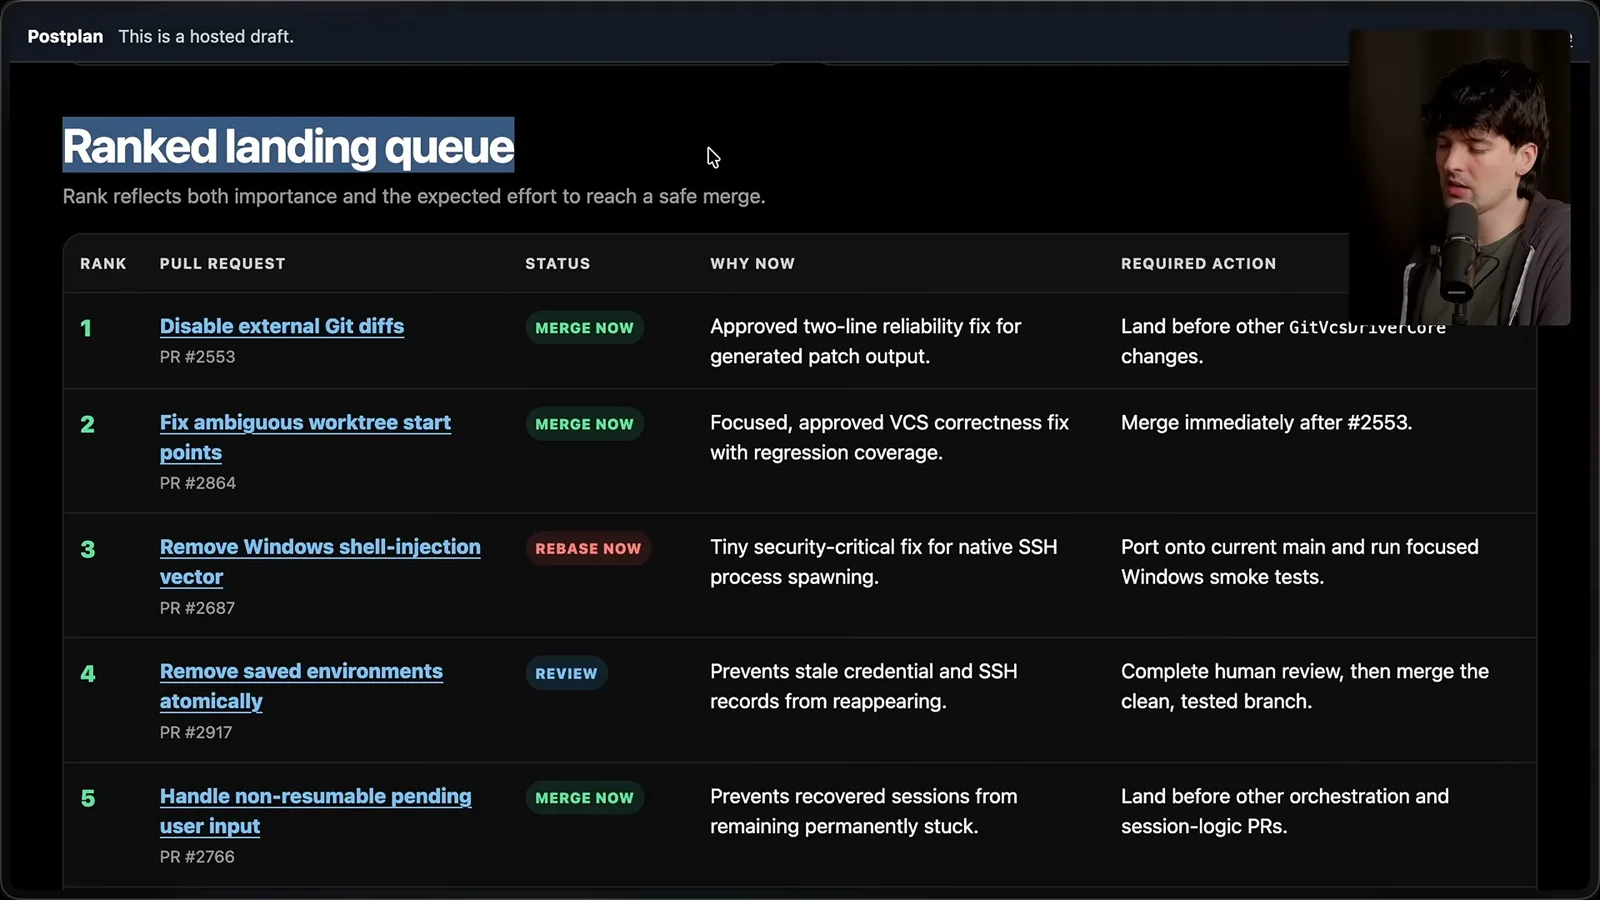
I host agent-generated HTML plans so my team and I can read them in a browser or on a phone. I can also hand a review link to another agent and ask it to implement the useful feedback while explaining disagreements. The readable artifact makes passing context between people and agents easier.
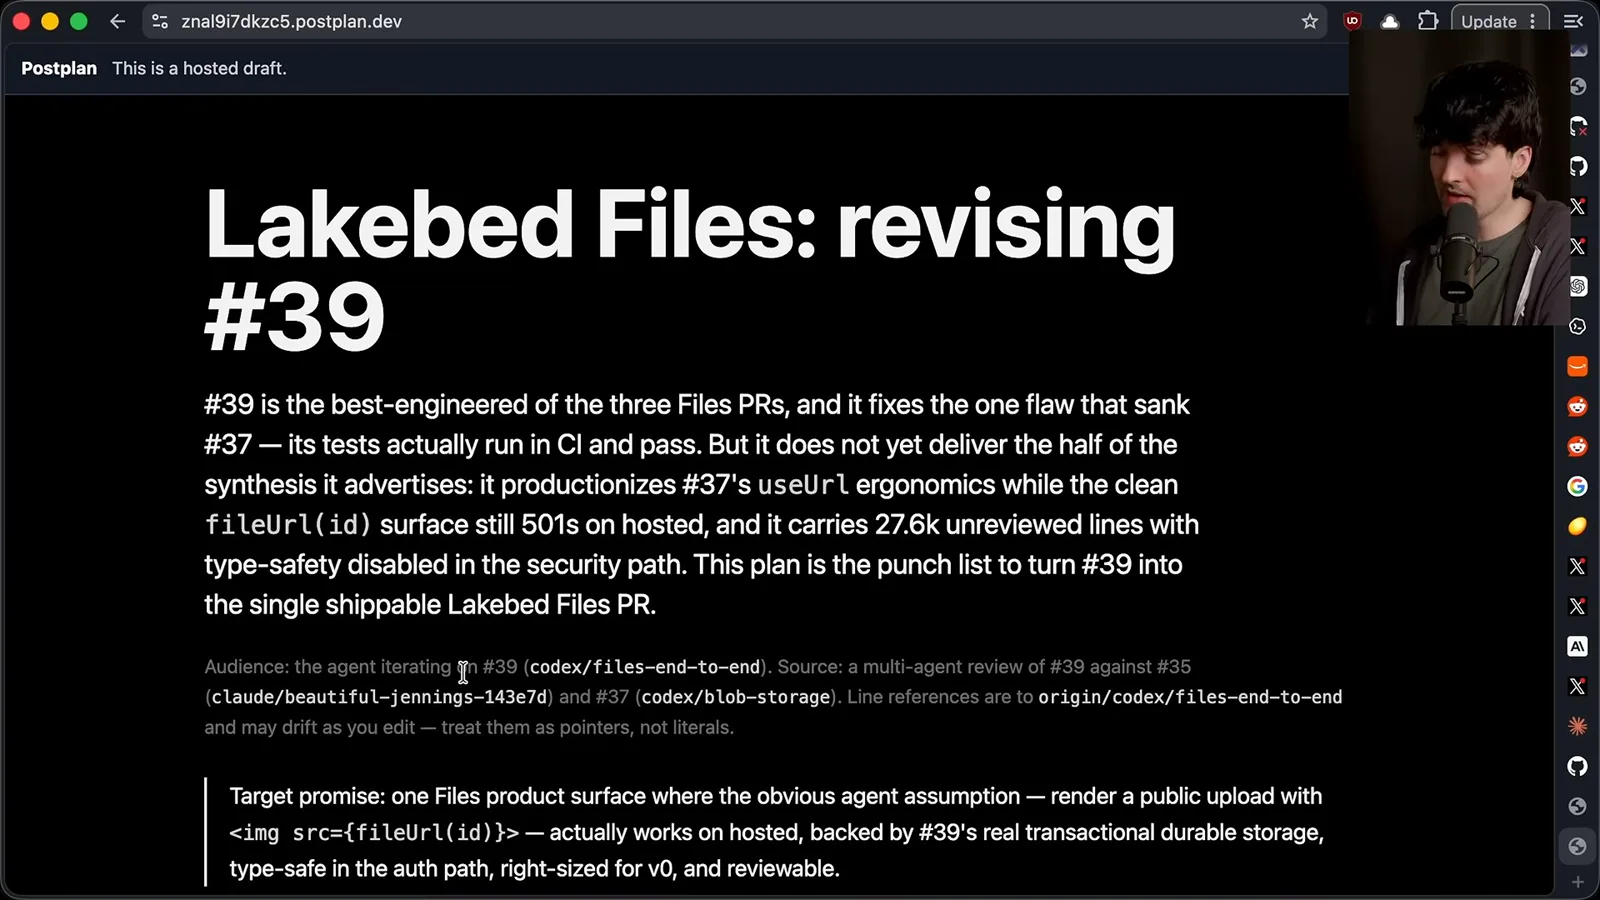
Existing skills can suggest ways to audit and improve a project. I keep a list of potential tasks and prompts to revisit later, but a skill’s instructions and source still need evaluation. An automated audit can surface questions; its recommendations should be checked before they become changes.
Remote work and orchestration
A remote machine allows long tasks to continue without an open laptop. Theo discusses review loops and agent coordination.
There is a personal downside: waiting for one more agent result can keep me at my desk much longer than intended. I do not claim to have solved that. Running work on a separate Mac mini lets me close my laptop without stopping a long task, though it does not automatically solve the urge to keep checking.
I access the remote machine through SSH, Tailscale and macOS screen sharing, and I also show remote access to T3 Code. Different tools and setups can achieve similar results. The benefit for me is being able to let an exploratory task continue without tying it to an open laptop.
Agents can review one another’s work, watch PR feedback or use a browser to test changes. I point to Peter Steinberger’s example of a coordinator that wakes periodically and directs work into separate threads. Those handoffs can reduce manual work, but the results still need appropriate human judgment and verification.
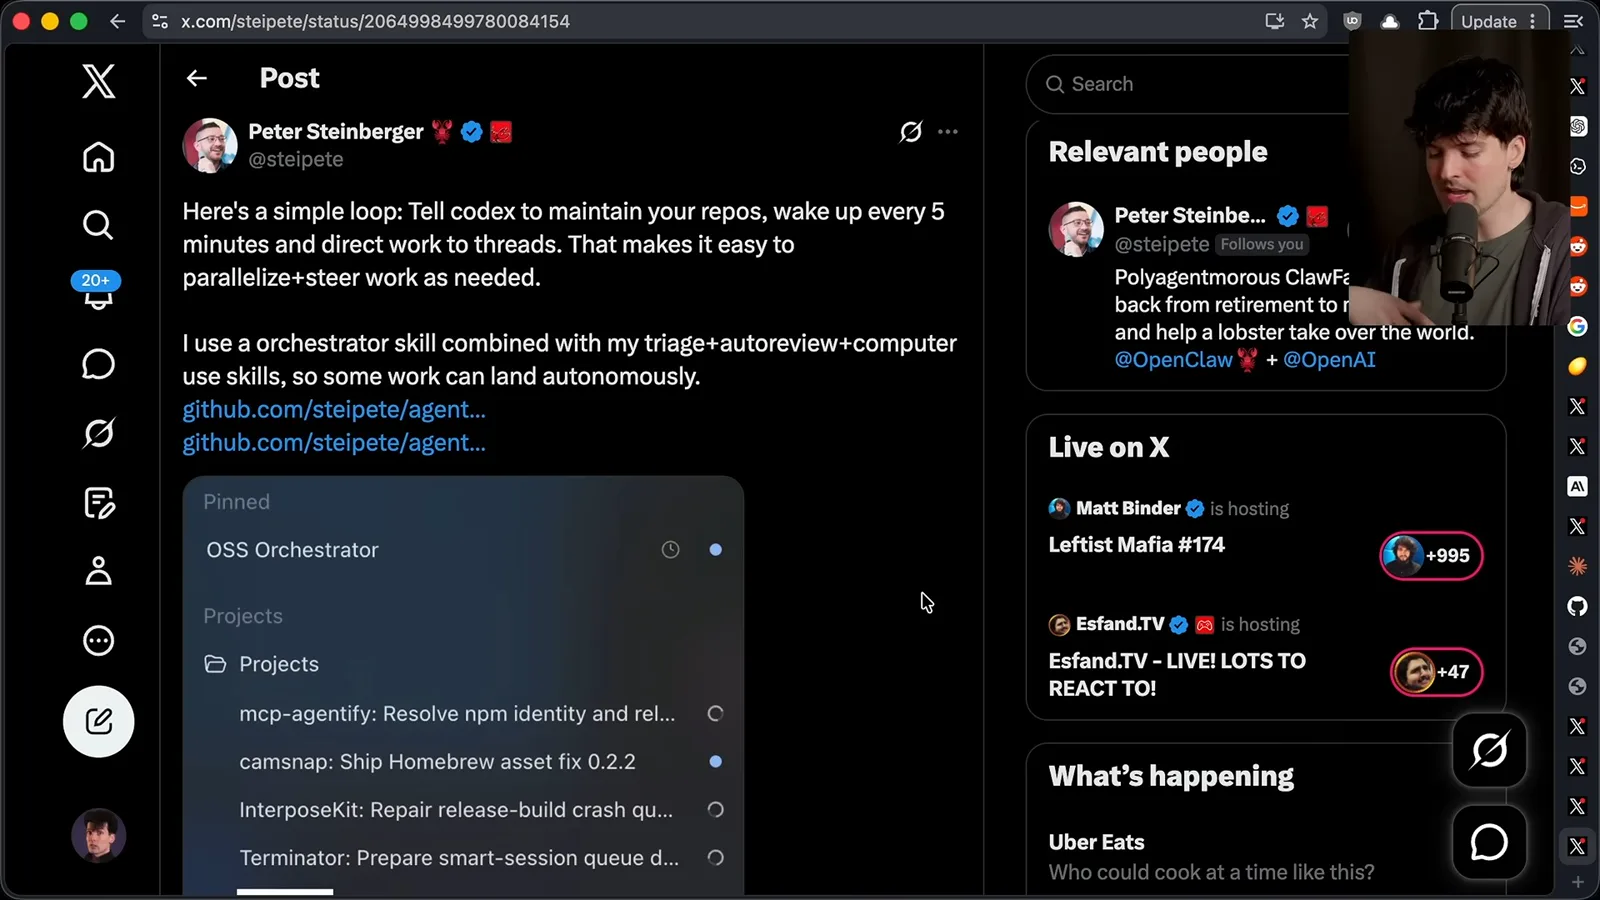
I encourage bigger experiments: have agents validate a plan, explore a larger implementation, debug a problem or use a browser. When a strong model coordinates many subagents, selecting less expensive models for suitable subtasks can reduce usage. More tokens alone do not make the answer better.
Focus on problems and verification
Theo encourages ambitious experiments while acknowledging validation limits. He closes by recommending rest and reflection.
I believe developers can generate much more code with these tools, but I also acknowledge they cannot necessarily validate that all of it is good or worth shipping. The goal should be solving more problems, not producing more lines or working from fear of losing a job.
When I approached agents with curiosity, I built a custom cloud, useful packages and tailored versions of software I use. Those are examples from my own experience, not a guarantee of the same outcome for everyone. I want people to lower the threshold for trying ideas and be more ambitious about where they take them.
If an agent struggles, inspect its history and tool calls, ask what went wrong and add guidance or verification where it helps. Keep experimenting without becoming attached to one model or tool. And after queuing the work, I plan to catch up on sleep.
同じチャンネルの記事
 38:47EN
 Theo - t3․gg· 2026年10月28日Theo’s Long-Running Agent Experiments: Verification, Compute and CostTheo Browne · Ping LabsA skateboard game and two compiler projects show how repeated checks and flexible compute can sustain agent work—and how expensive those loops can become.
 36:07ENTheo - t3․gg· 2026年10月27日Theo on Token Costs, Coding Agents, and the Price of AI CapabilityTheo Browne · Ping LabsA viral estimate of Lauren's AI spending prompts a closer look at cache pricing, benchmarks, and the changing work of coding agents.
 30:37ENTheo - t3․gg· 2026年10月26日Theo’s Three Skills for Reviewing and Shipping with Coding AgentsTheo Browne · Ping LabsHow sol-loop, full-send and full-stop encode review, verification and different levels of merge authority.
 0:43ENTheo - t3․gg· 2026年10月23日Theo Distinguishes Security Vulnerabilities from Active AttacksTheo Browne · Ping LabsA short explanation of why disclosed software flaws and reported attacks are different kinds of security news.
 29:22ENTheo - t3․gg· 2026年10月22日Theo on Security Vulnerabilities, Stolen API Keys and AITheo Browne · Ping LabsA look at the gap between vulnerability disclosure and patching, and a speculative account of why stolen inference keys may be valuable.
 31:13ENTheo - t3․gg· 2026年10月20日Theo on Why Smarter Models Help More Than DevelopersTheo Browne · Ping LabsFrom game modifications to compiler experiments, Theo revisits his assumptions about who benefits from more capable AI.