30 秒でわかる
Theo - t3.gg ranks models for his own coding and agent workflows, placing Fable 5 at the top while using GPT-5.6 Sol as his default. He discusses open-weight models, multimodal access, token efficiency and task-level cost; the rankings and historical prices reflect his experience at recording time.
- 1Sol as the defaultTheo values Sol for long-running work, while noting that its output still needs verification.
- 2Small models for background tasksLuna supports titles, summaries and structured data in his workflow; he exercises care with irreversible actions.
- 3Kimi K3 and costIts open weights and visual capabilities impressed Theo, but hosting price and token usage affect its value.
- 4Measure the finished taskToken generation speed alone does not establish total latency or cost when models produce different token counts.
- 5Fable versus SolTheo rates Fable highest for difficult coding while preferring Sol as a general default.
ポイント
- A single ranking hides differences in task, model behavior, speed, price and data handling.
- Theo ranks Fable 5 highest for his important coding work but uses GPT-5.6 Sol as his everyday default.
- He values Luna and DeepSeek V4 Flash for inexpensive background tasks, with different tradeoffs around open weights and vision.
- Open weights do not automatically mean low hosting cost, and license terms should be checked for the intended use.
- Cost per completed task depends on token usage as well as the price per token.
- Benchmark charts and model prices are specific to their settings and date.
チャプターごとに整えた全文を読む
A personal ranking
Theo explains why a tier list compresses many tradeoffs. He starts with Sol, his default model.
There are many capable models, but a single tier list hides important differences in task, price, speed and behavior. I am making one anyway, based on my own coding and agent workflows as of August 2026. It is a personal snapshot, not a universal or permanent benchmark.
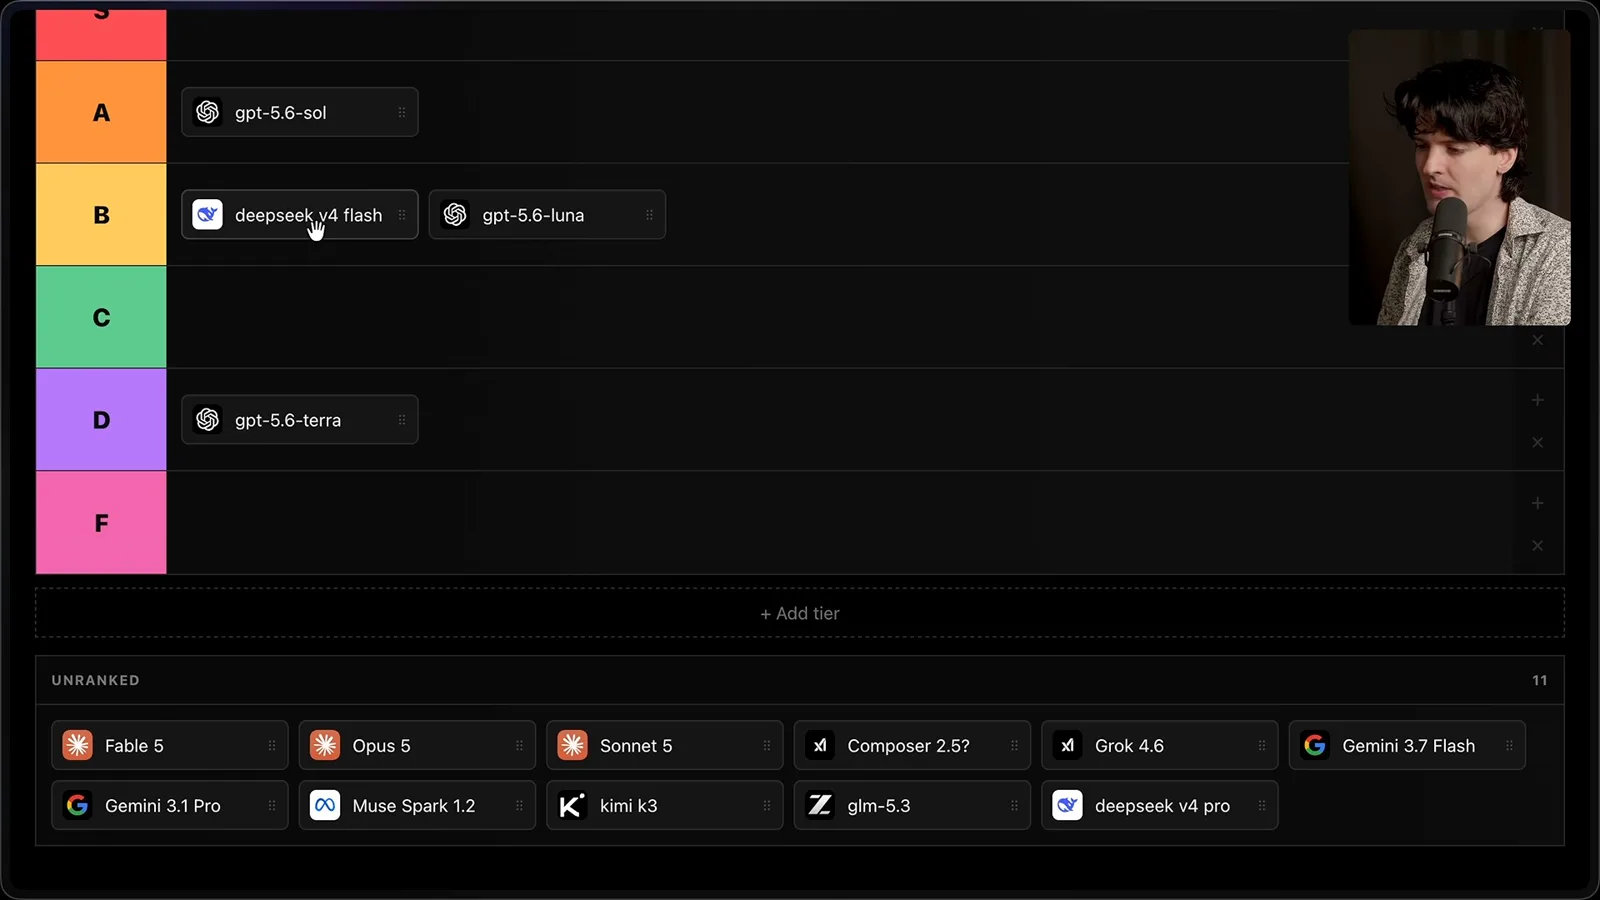
I start with GPT-5.6 Sol, which I used to build the tier-list app itself. Its first version missed or mishandled several logos; after I showed it a screenshot, it fixed them. That mix of impressive capability and mistakes I still need to catch is why I initially place it in A.
Sol is my default for many long-running tasks. I used it to build a SwiftUI rewrite of the T3 Code mobile app in one thread. In my experience it is a large improvement over its predecessor, even though another model is still my preference for important code I intend to merge.
Terra, Luna and DeepSeek
He compares task costs and explains uses for smaller models. Vision and open weights affect his preferences.
GPT-5.6 Terra costs less per output token than Sol, but can use more tokens. In the benchmark charts I consult, it can cost less per task and sometimes looks competitive per dollar. I have nevertheless struggled to find a task in my own workflow where I would choose it over the alternatives.
For my purposes I would often choose Luna to save money or Sol at a lower effort level for responsiveness. That is a judgment about my usage, not proof that Terra has no suitable use cases. The list later changes as I add more tiers.
GPT-5.6 Luna earns a high placement for a different reason: it is fast and inexpensive for background work. I use it for titles, status, categorization and turning context into structured JSON, rather than relying on it for important code changes.
Luna can call tools and gather information, but I would not entrust it with irreversible actions without oversight. Its value to me comes from handling many small, reversible tasks at a low cost. Subscription availability and promotional API rates are time-dependent.
DeepSeek V4 Flash is another low-cost option. I am discussing the newer snapshots, because models with the same V4 name had multiple releases with different behavior. It is open-weight, which gives users the option to run it themselves if they have suitable hardware.
I find V4 Flash useful for summaries and background tasks, though it can loop or lose direction more than Luna in my experience. Self-hosting offers flexibility but has hardware costs; open weights do not make a large model free to run.
After learning that the version I am considering lacks image input, I place V4 Flash behind Luna for my own use because I paste screenshots frequently. I judge V4 Pro especially harshly for lacking vision at its size and price. Availability and multimodal support depend on the specific version and endpoint.
Kimi, GLM and Composer
Theo discusses open-weight capability, hosting cost, vision and availability. His license-related explanation is speculative.
Kimi K3 impressed me as an open-weight model that could handle longer, multi-step work and visual tasks. I liked some of its design and 3D results. I put it near the top of B rather than above Sol, primarily because its actual cost in my workflow is higher than many people assume.
An open-weight model is not automatically cheap to serve. When I compared the settings I use, K3 could cost more per task than Sol at xhigh despite a lower nominal token price. The result depends on provider prices, output length, effort setting and the task.
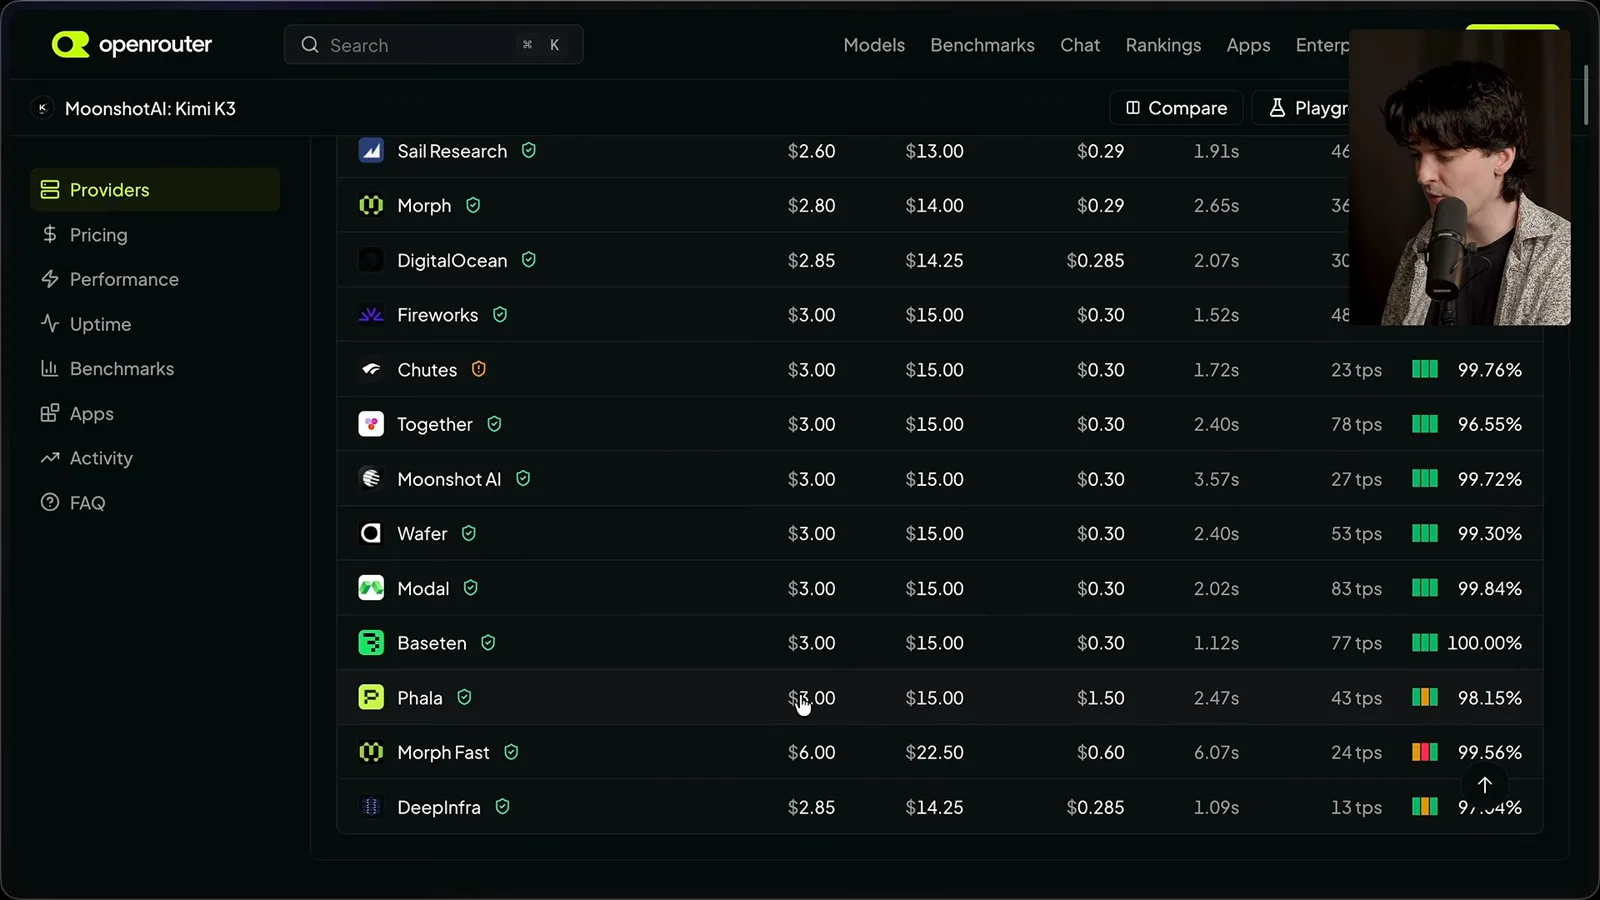
The OpenRouter prices I show cluster around $3 per million input tokens and $15 per million output tokens for many providers at that time, with exceptions. I speculate about hosting economics and licensing as possible causes. I have not established the terms of providers’ private agreements, so that explanation is not a finding.
I still give K3 credit for advancing open-weight capabilities. But in my own day-to-day work, the cost and behavior mean I usually return to Sol. Pricing, licenses and available model snapshots should be checked for the intended deployment.
GLM-5.3 is an improvement over 5.2 in my experience: it stays on task better and loops less. I nevertheless do not choose it often, and the lack of vision in the version I discuss lowers its position for me. This refers to GLM-5.3, not the later Flash model.
Cursor’s Composer 2.5 is technically impressive, especially at speed, but I do not reach for it frequently. I correct myself in the video: Composer 2 and 2.5 were based on Kimi K2.5. The limited availability and difference between advertised fast and cheaper slower options affect my ranking.
Grok, Muse and Gemini
He compares speed, data terms, pricing and model behavior. Benchmarks are tied to specific settings.
Grok 4.6 can orchestrate multiple tasks and, in my experience, improves on 4.5 in some respects. But it uses more tokens and feels slower, undermining the speed that made its predecessor attractive to me. I put it around C and may still use it for assistant-like work.
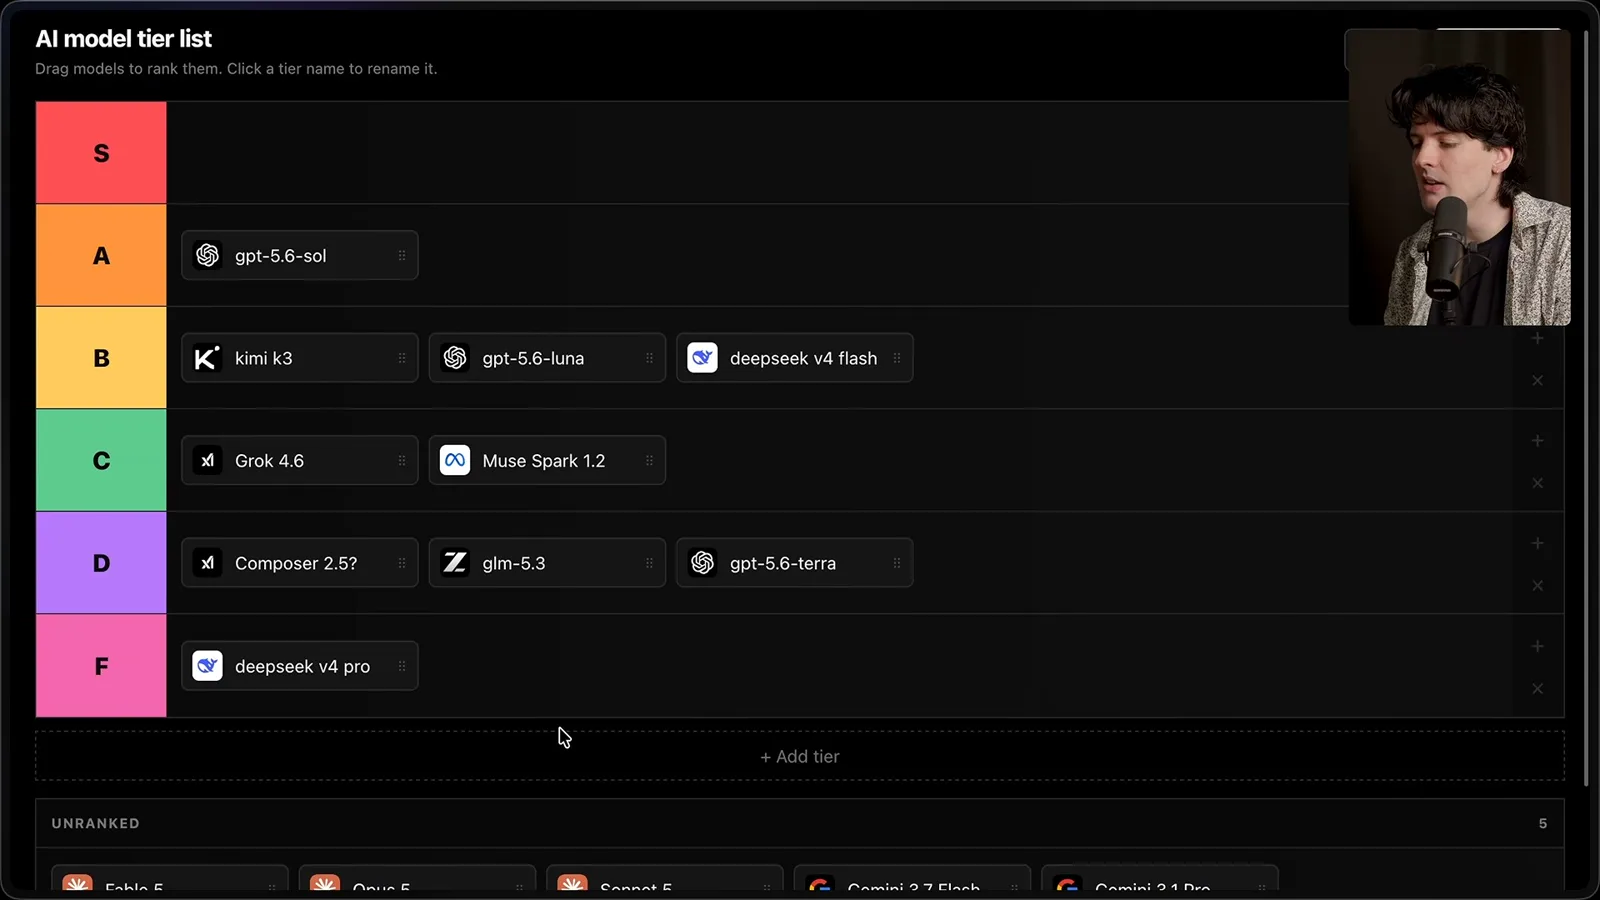
Muse Spark also sits around C for me. I do not like its code as much as Grok’s, but I have found it fast for triaging PRs. Its low-cost contributor option involves data being used for training, so price and data terms have to be considered together.
I am much more negative about the Gemini models in this list. I used to value Gemini 2.0 Flash for low cost, speed and multimodal inputs, but I find the later versions less compelling for the tasks and pricing I am evaluating. That is my assessment, not a claim about every possible use.
My cost argument is not just dollars per token. Reasoning can increase the number of output tokens as well. A model with a low token price can still be expensive per completed task if it produces much more text or reasoning than another model.
The video shows introductory Gemini 3.7 Flash rates and a stated end to the discount. Those are historical figures from the page displayed at recording time, not a current price quote. Check the provider’s current pricing and terms before using them for a decision.
Gemini 3.1 Pro did well on my personal Skatebench and has had useful visual capabilities, even though I dislike its agent behavior. This is an example of why one ranking cannot summarize all strengths: a model may know a topic well and still frustrate a particular workflow.
Tokens per second can also mislead when models need different numbers of tokens to complete the same task. I would rather compare elapsed time, quality and total cost for the actual work than assume the model with the fastest token stream finishes first.
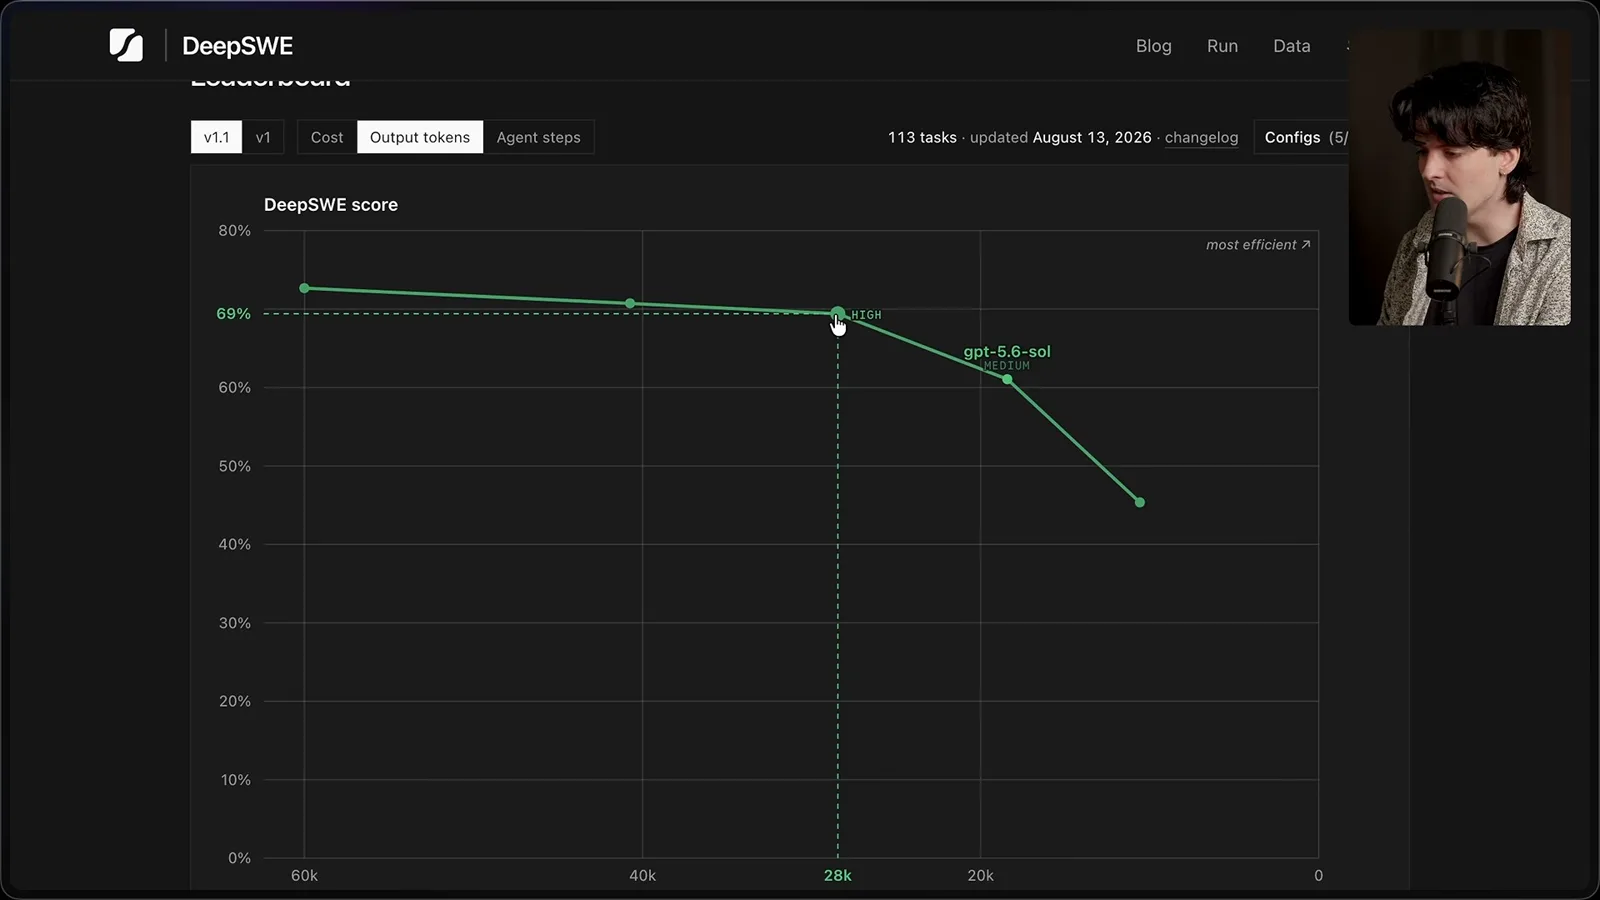
In the DeepSWE chart shown, Sol at high effort uses roughly 28,000 output tokens per task, versus about 60,000 at max, with a smaller score difference. The Gemini configurations I inspect use more in that benchmark. These are specific benchmark settings, not a guarantee for every workload.
Sonnet, Opus and Fable
Theo evaluates the Anthropic models against his own work. Fable ranks highest, while Sol remains his default.
Sonnet 5 has a limited role for me inside a Claude Code subscription, including small subagent experiments with vision. I do not find its API price attractive for my tasks and place it low. Subscription economics and API economics can lead to different choices.
Opus 5 initially impressed me with detailed plans and useful observations. My later experience merging its code was less positive: I found that confident, sophisticated-sounding output did not always translate into code I wanted to ship. I place it in D based on that experience.
Fable 5 takes the top tier for me. It is not perfect: it can take shortcuts, lose track or touch things I did not intend. But it gives me the strongest code and the most useful help on difficult problems among the models I have used.
Sol remains my everyday default. If I could keep only one, I say I would miss Sol more, even though I rank Fable higher for the quality of important code and deep discussions. That distinction between preferred default and strongest specialist is hard to capture in a single list.
Fable’s access restrictions and refusals frustrate me, but I value it enough to maintain multiple subscriptions. I would not personally pay its full API price for the volume I use; my preference depends in part on subscription economics. My speculation about unreleased internal models is not confirmed information.
Interpreting the gaps
He explains different levels of oversight and compares the leading models. The list is a dated personal snapshot.
The gaps between tiers are not equal. For models such as K3, Luna and V4 Flash, I usually stay closer to the task and review the work as it progresses. With Sol and Fable I am more comfortable giving a broader request, provided there is verification and review.
Fable tends to understand my intent and produce code I am happier to merge; Sol is thorough and easier for me to steer, and I have found it stronger for iOS work. These are observations about my projects, not claims that either model will perform the same way for everyone.
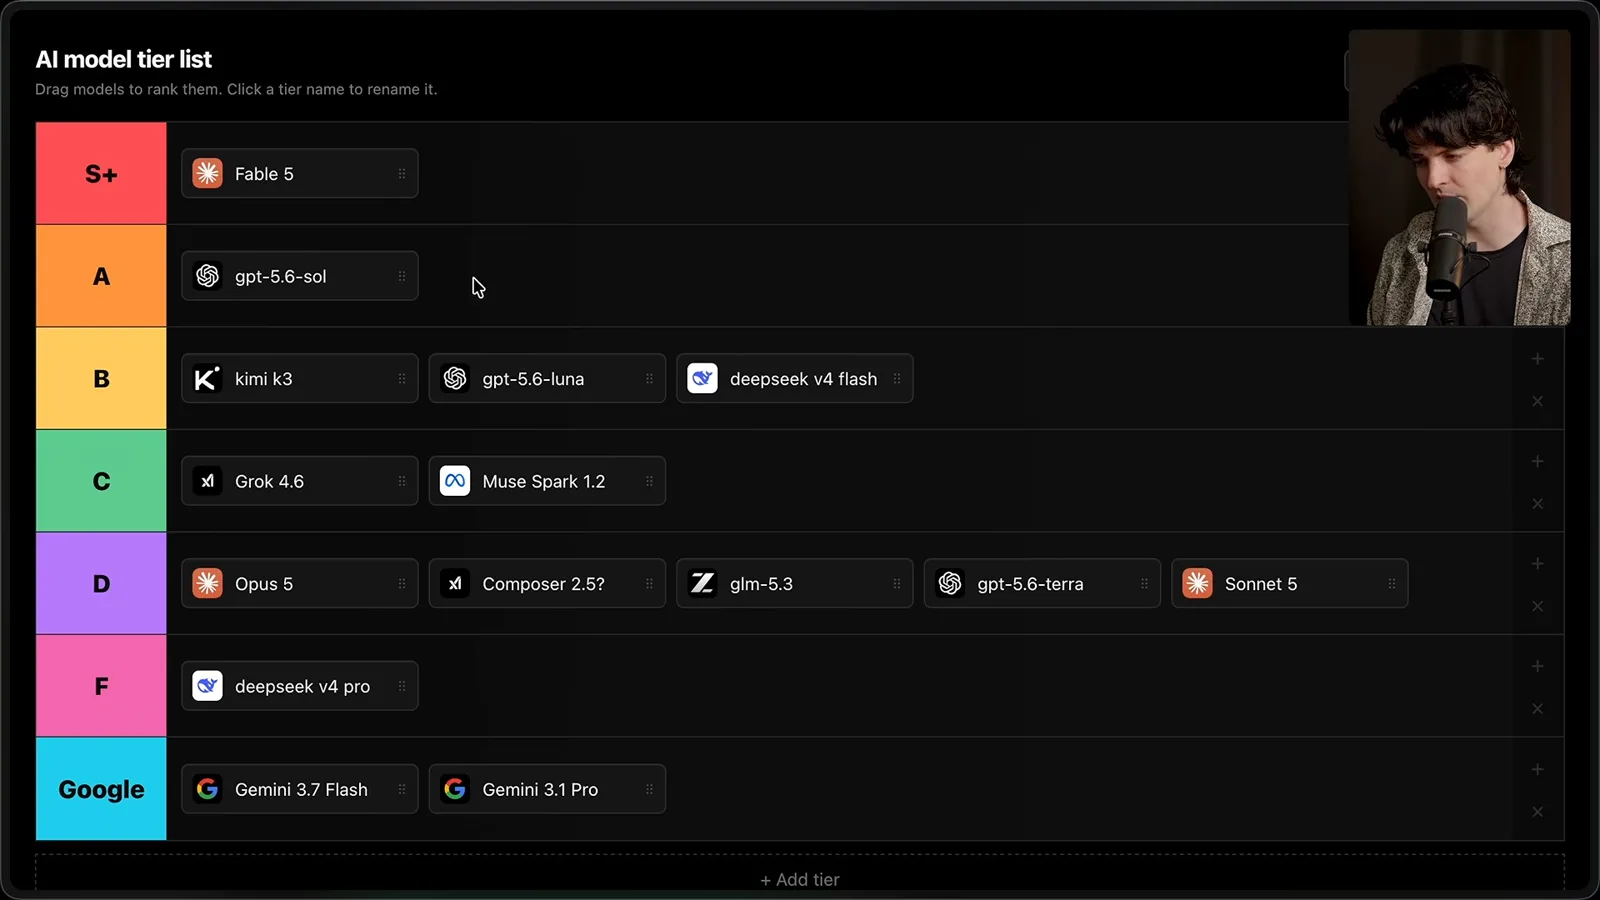
I use Fable and Sol for most important work, with cheaper models for specific background tasks. A good selection depends on the workload, available tools, privacy requirements, speed and cost per result. The models and prices will change, so treat this list as a dated account of my experience.
同じチャンネルの記事
 38:47EN
 Theo - t3․gg· 2026年10月28日Theo’s Long-Running Agent Experiments: Verification, Compute and CostTheo Browne · Ping LabsA skateboard game and two compiler projects show how repeated checks and flexible compute can sustain agent work—and how expensive those loops can become.
 36:07ENTheo - t3․gg· 2026年10月27日Theo on Token Costs, Coding Agents, and the Price of AI CapabilityTheo Browne · Ping LabsA viral estimate of Lauren's AI spending prompts a closer look at cache pricing, benchmarks, and the changing work of coding agents.
 30:37ENTheo - t3․gg· 2026年10月26日Theo’s Three Skills for Reviewing and Shipping with Coding AgentsTheo Browne · Ping LabsHow sol-loop, full-send and full-stop encode review, verification and different levels of merge authority.
 0:43ENTheo - t3․gg· 2026年10月23日Theo Distinguishes Security Vulnerabilities from Active AttacksTheo Browne · Ping LabsA short explanation of why disclosed software flaws and reported attacks are different kinds of security news.
 29:22ENTheo - t3․gg· 2026年10月22日Theo on Security Vulnerabilities, Stolen API Keys and AITheo Browne · Ping LabsA look at the gap between vulnerability disclosure and patching, and a speculative account of why stolen inference keys may be valuable.
 31:13ENTheo - t3․gg· 2026年10月20日Theo on Why Smarter Models Help More Than DevelopersTheo Browne · Ping LabsFrom game modifications to compiler experiments, Theo revisits his assumptions about who benefits from more capable AI.