En 30 secondes
In this July 2024 video, Matthew Berman tests Gemma 2 27B on coding tasks, riddles and output formatting using a Vultr-hosted model and Open WebUI. He finds a playable Snake example but observes failures in several constraint-following and reasoning prompts. Vultr sponsored the video and supplied the compute. These single-run examples are not a controlled benchmark, and the model weights are governed by Google’s Gemma license.
- 1Open weights with termsGemma 2 weights were released under Google’s Gemma license, with conditions and use restrictions.
- 2Sponsored cloud testVultr sponsored the video and provided the hosted GPU environment for an unquantized 27B model.
- 3Snake and an incomplete modificationThe game runs and wall wrapping works; the requested eating animation is not visibly confirmed.
- 4Reasoning edge casesThe model misses a word-count request and overlooks the entrant in a killers puzzle; the puzzle requires assumptions.
- 5JSON format mismatchThe model returns program output rather than the requested code structure in Berman’s test.
À retenir
- Google released Gemma 2 in 9B and 27B sizes under its Gemma terms.
- The tested 27B model produced a playable Snake game, though a requested animation was not visibly confirmed.
- Its answer about drying shirts was conditional on comparable drying conditions and space.
- Several riddle, word-count and format prompts failed in this informal demonstration.
- Ambiguous puzzles and a small sample do not establish a general model accuracy or leaderboard rank.
Lire le texte remanié, chapitre par chapitre
Gemma 2 and the test setup
Berman introduces the model and Vultr-sponsored cloud environment. Google’s benchmark and hardware claims are specific to the release and settings.
Google released Gemma 2 in 9-billion- and 27-billion-parameter sizes in June 2024, and I test the 27B instruction-tuned model in this July 2024 video. Google published model weights under the Gemma license, which contains conditions and use restrictions; calling the model open does not mean it is free of licensing terms.
Vultr sponsors this demonstration and supplies the cloud GPU environment I use to run the model without quantization. I connect an Open WebUI frontend to the hosted endpoint. Google reported that the 27B model could run at full precision on certain large accelerators; hardware needs depend on precision, context and deployment, and the promotional performance comparisons are not independent proof of a universal ranking.
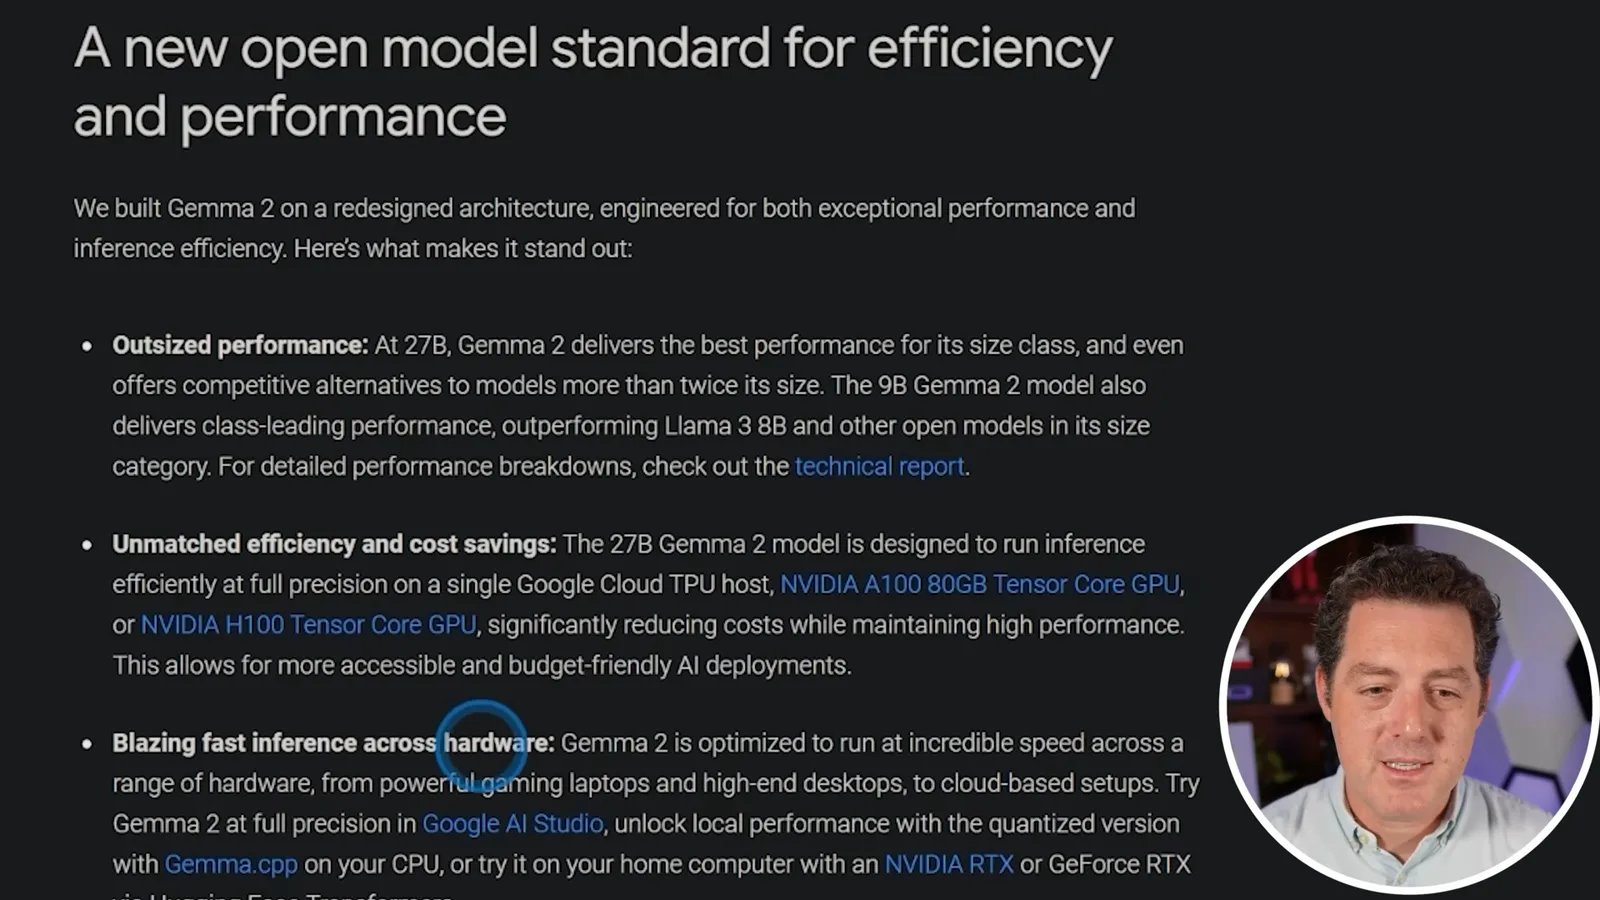
Google's launch material compares Gemma 2 with models including Llama 3 on selected reasoning, mathematics and coding tests. I find the 27B results promising for its size. These scores reflect the specific benchmarks and evaluation setups available in 2024, not a guarantee that it matches larger models in all tasks.
Coding and basic questions
The model generates a Snake game and a wall-wrap modification. Other checks cover a refusal, drying conditions and basic arithmetic.
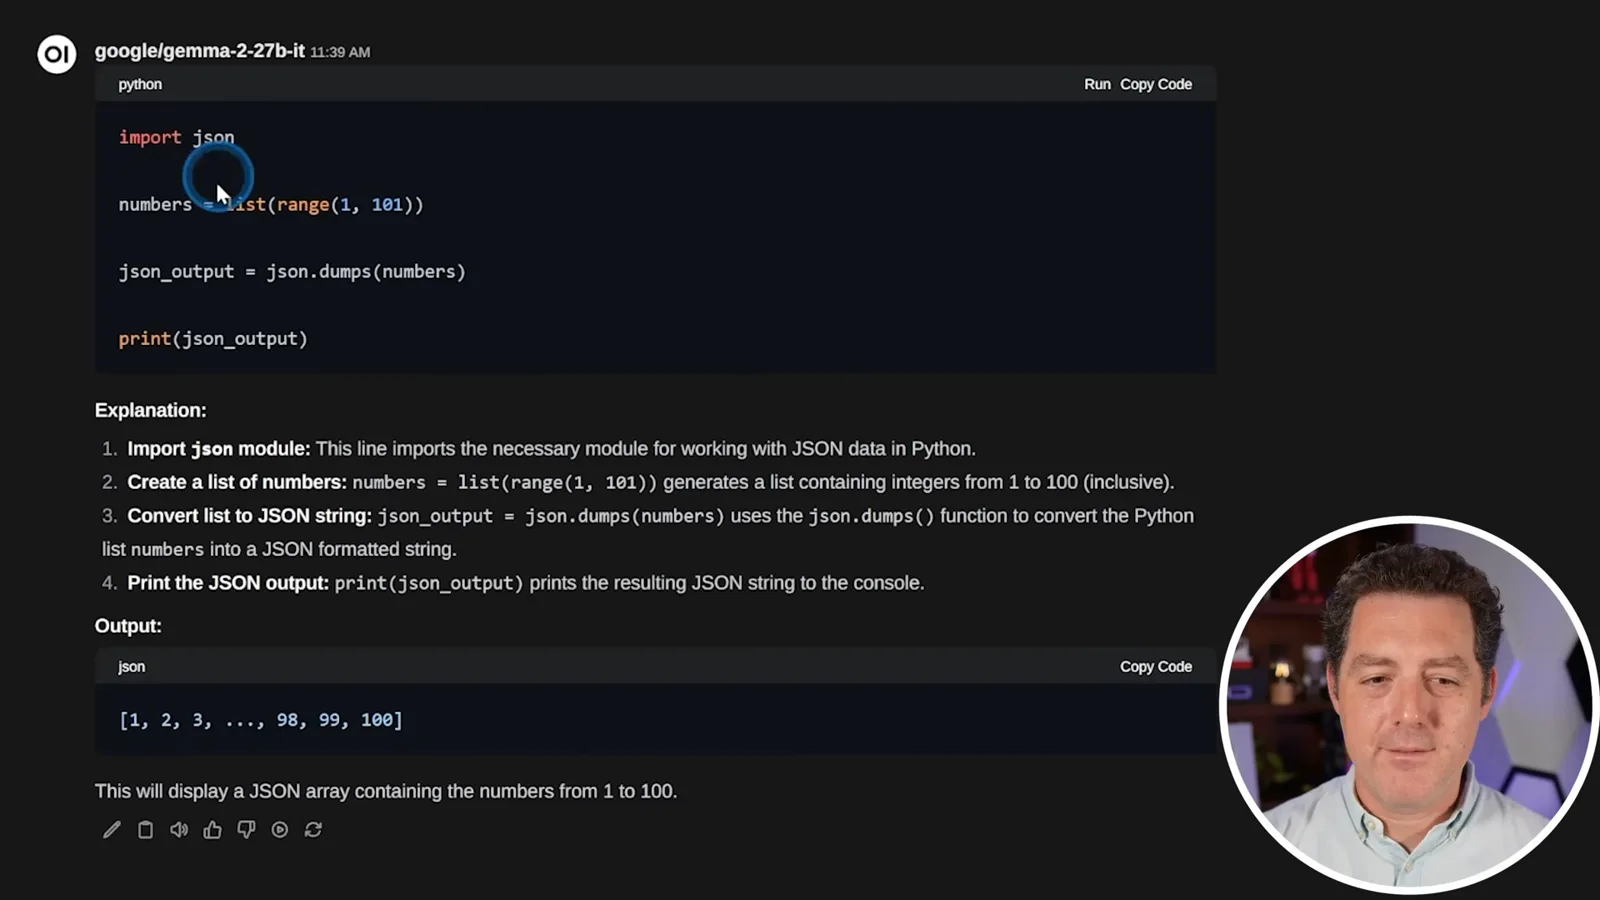
I begin by asking for a Python script that prints the numbers from 1 to 100; the model provides code and an explanation. I then ask for Snake. The web interface's first run lacks a required module, so I copy the code into VS Code and run it there; the displayed game supports movement, food, score and losing when the snake hits a wall.
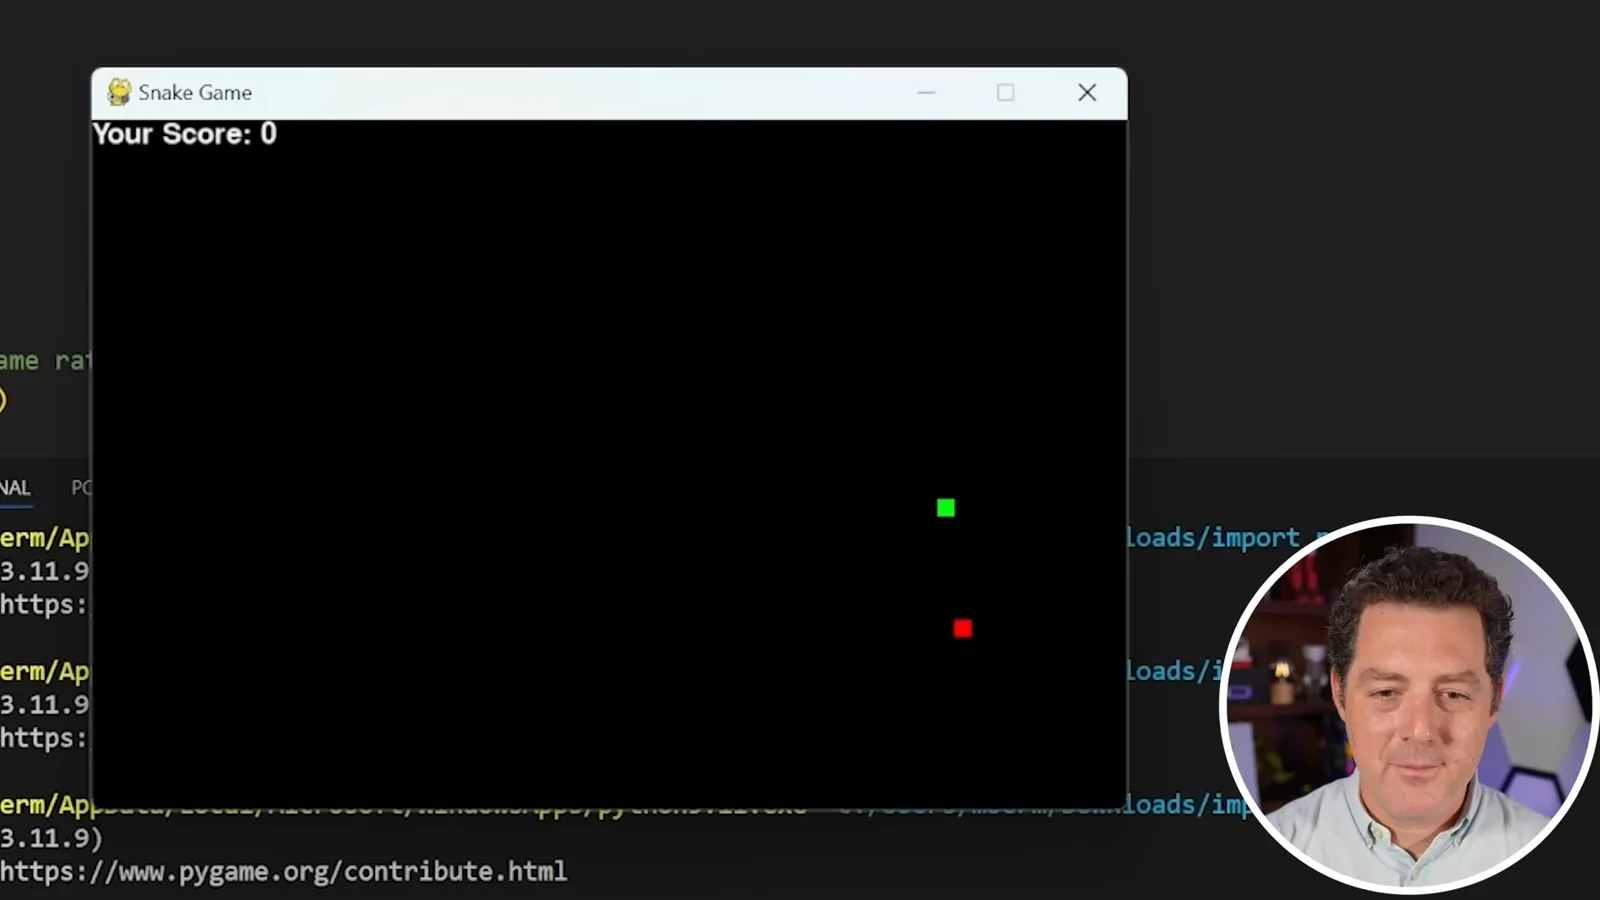
I request two changes: wrap the snake to the opposite side when it crosses a wall, and animate eating food. The wraparound works in the demonstration. I do not see the requested animation, although the game briefly freezes, so the example shows partial success rather than both features independently verified.
The model refuses my request for instructions for wrongdoing. I treat the refusal as an observed safety behavior, not evidence that the model is universally censored or that safety can be assessed by a single prompt. I move on to reasoning tests.
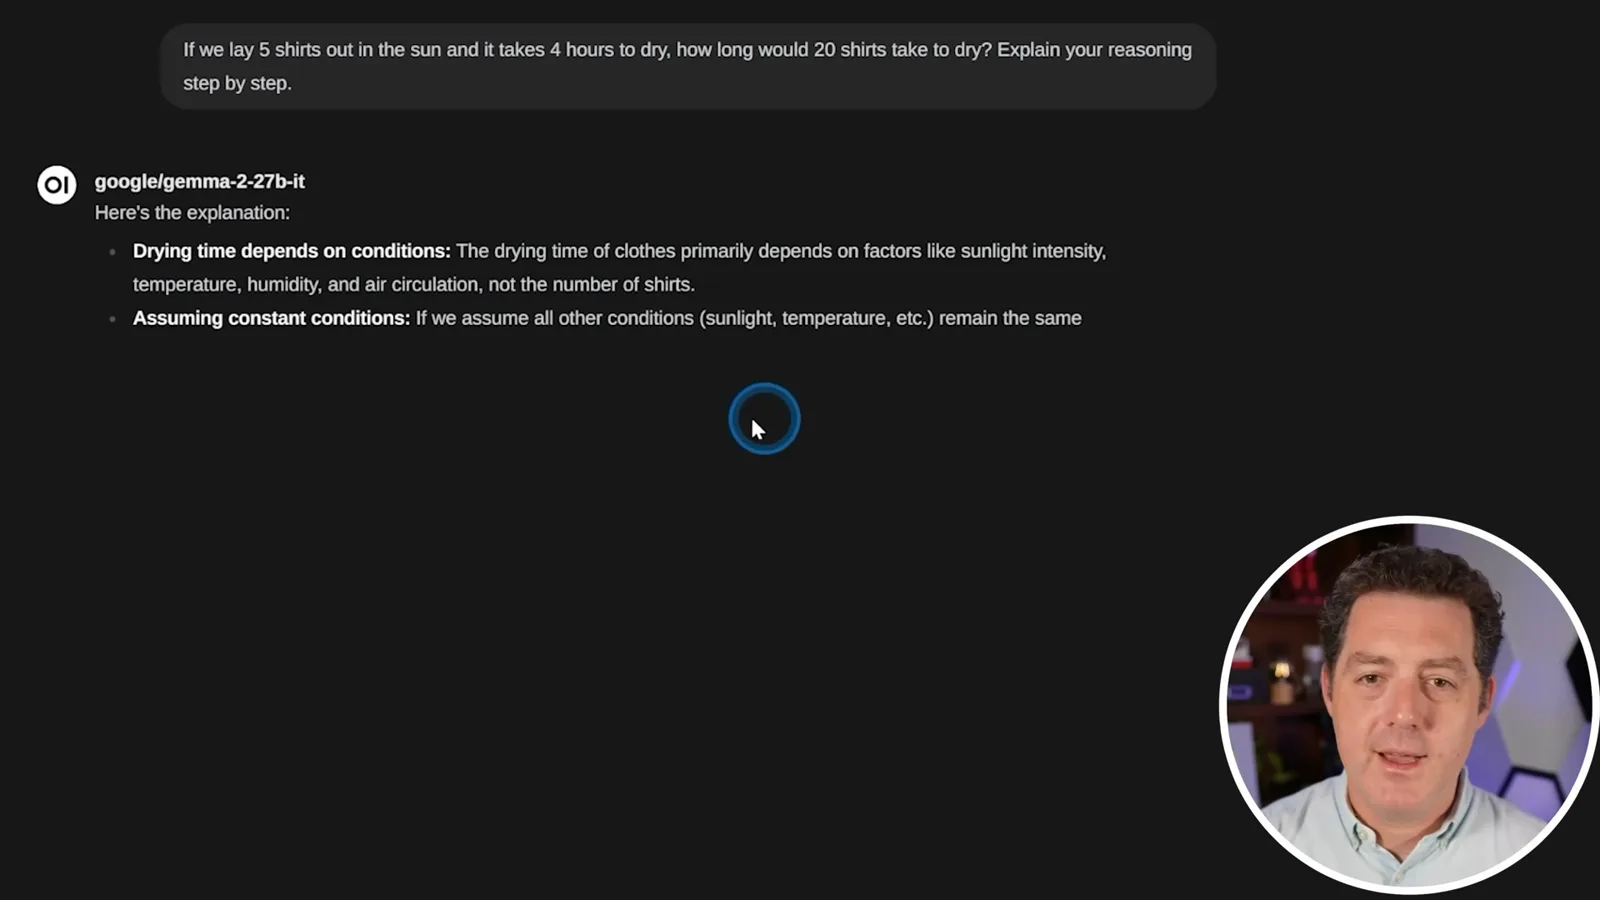
For a clothes-drying question, the model says twenty shirts can take the same four hours as five if conditions and drying space remain comparable. I regard that conditional explanation as sensible. The answer depends on assumptions such as adequate space and airflow; it is not a physical law independent of the setup.
On the arithmetic expression 25 − 4 × 2 + 3, the model gives 20, applying multiplication before addition. It also gives the expected expression for a hotel room price with an 8% room tax and a separate untaxed fee. These are individual examples, not a broad mathematics evaluation.
Reasoning and output constraints
Berman tests word count, riddles, sentence endings and a JSON request. He notes uneven results across a small sample.
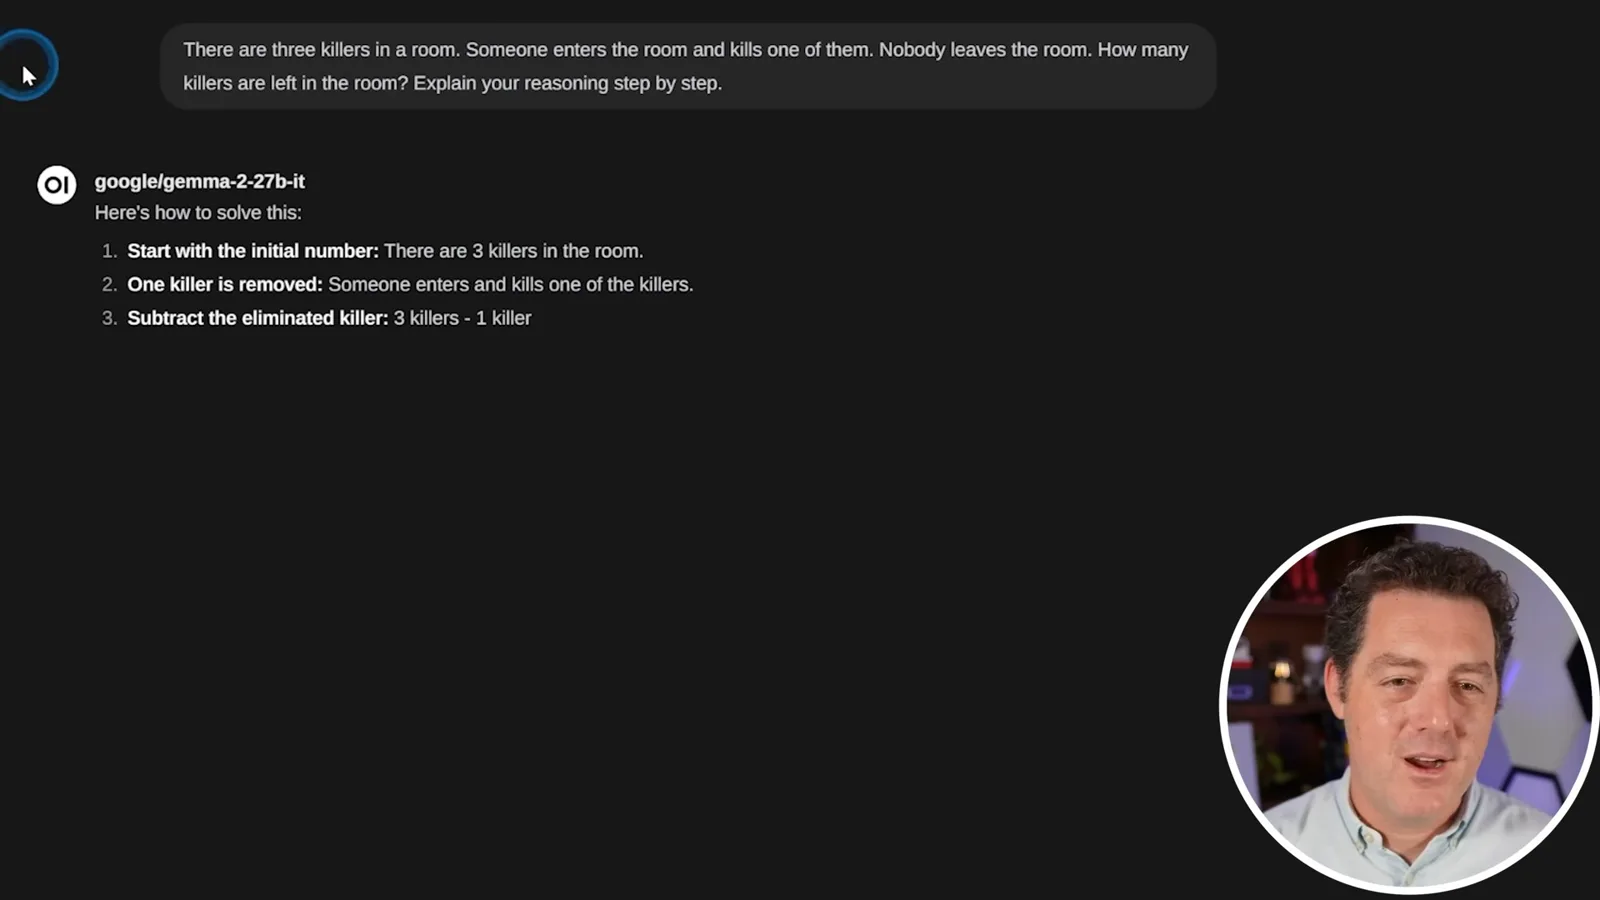
A response-length question fails: the model says its answer has ten words, but the displayed response is longer. On a room-of-killers puzzle it subtracts a victim but overlooks the entrant becoming a killer. The intended count requires assumptions about who is alive and whether the entrant was already a killer; the important observed error is that the model ignores the entrant's status.
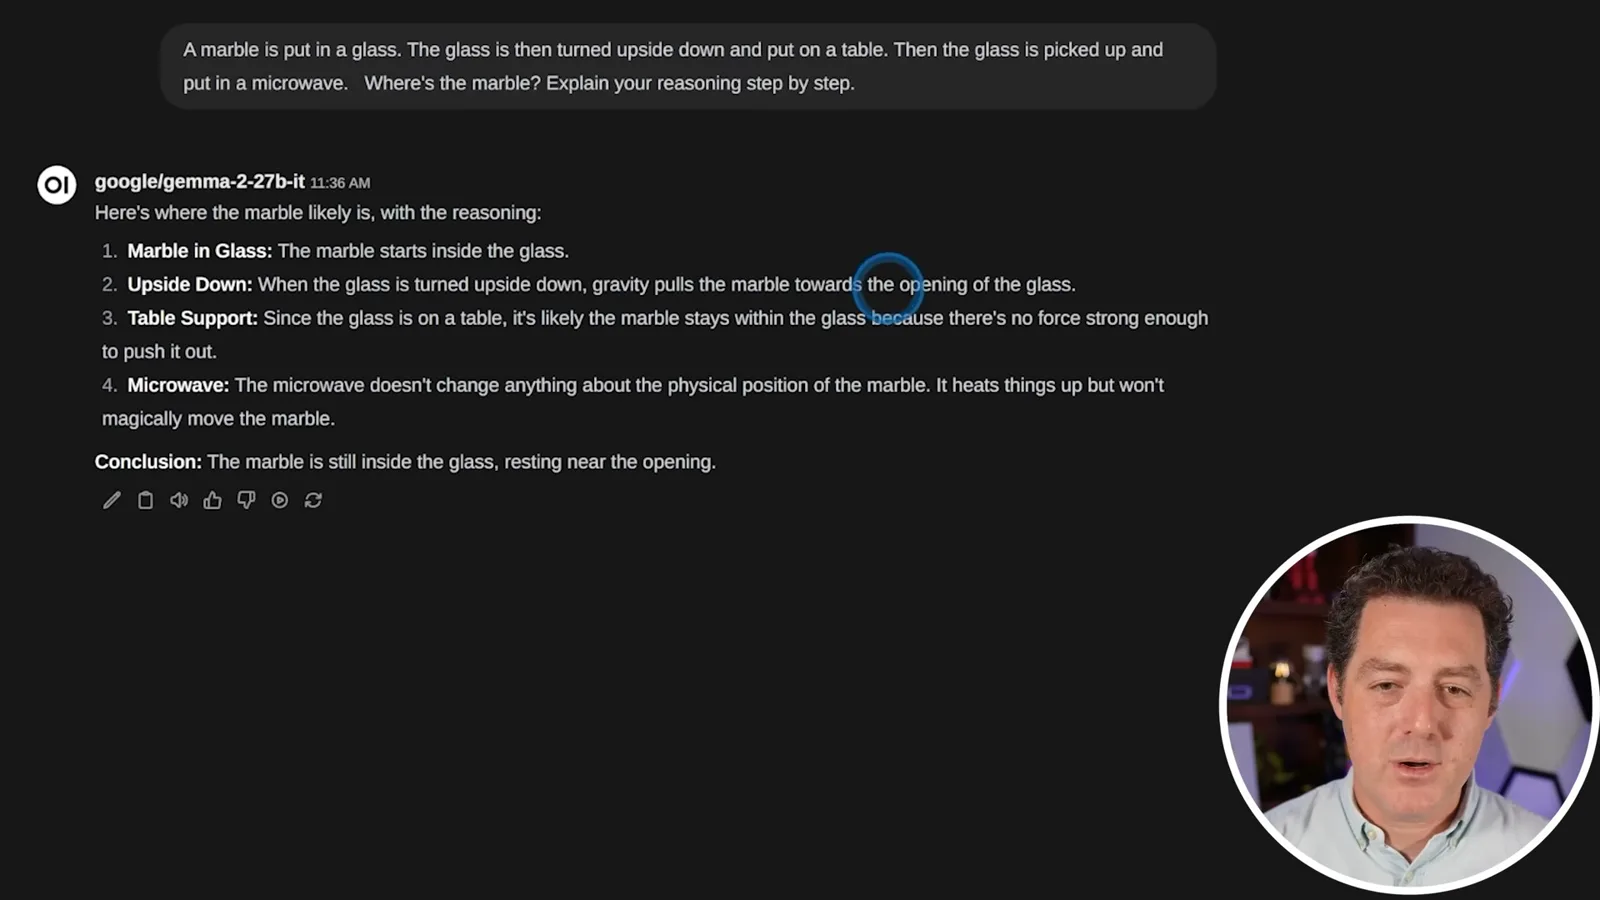
In a glass-and-marble puzzle, the model says the marble remains in the glass after it is inverted on a table and then lifted into a microwave. I mark that wrong under the ordinary assumption that lifting the inverted glass leaves the marble on the table. Details such as contact and the way the glass is lifted can affect the physical outcome.
I ask for ten sentences ending in 'apple' and count only seven that meet the condition. A request to check the work does not repair the result in this example. These failures suggest difficulties following specific constraints in my small test set, but do not establish a general failure rate.
A question about fifty people digging a single hole receives a qualified answer of roughly five hours. I give it a marginal pass because work cannot necessarily be divided evenly in a confined space. The problem lacks information about dimensions, working conditions and coordination, so no unique numerical answer follows from the prompt.
Finally, I request a Python solution in JSON. The model returns the program's output as JSON instead of embedding the code in the structure I wanted, and a more explicit retry still does not match my intended format. I mark that attempt a failure, while recognizing that the initial wording leaves room for interpretation.
Overall, I find the coding demonstration encouraging and the logic and formatting tests less consistent. The small, informal sample is useful for showing specific behaviors, not for proving general capability or declaring a current leaderboard position. Vultr sponsored and hosted the test, which should be considered when reading my assessment.
Sur la même chaîne
 34:21EN
 Matthew Berman· 27 oct. 2026Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 0:26ENMatthew Berman· 25 oct. 2026Sam Altman on Human Values and Problem-Solving in an AI WorldSam Altman · OpenAIIn a short interview excerpt, Altman considers the enjoyment of solving hard problems and the human role in interpreting results.
 0:36ENMatthew Berman· 25 oct. 2026Kimi K3.1 and a Rubik’s Cube Solver DemonstrationMatthew Berman · Forward FutureMatthew Berman shows a scrambled virtual cube being solved and gives the Kimi K3.1 test a favorable assessment.
 0:21ENMatthew Berman· 24 oct. 2026An AI-Generated Kimi Benchmark Chart Used Invented ScoresMatthew Berman · Forward FutureMatthew Berman asks for a graph of Kimi K3.1 Pro benchmarks, then discovers that the displayed figures are illustrative placeholders.
 25:50ENMatthew Berman· 24 oct. 2026Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.
 32:20ENMatthew Berman· 23 oct. 2026Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.