En 30 secondes
WorkOS engineering manager Nick Nisi describes a simulated fruit fly trained to associate code-derived smells with rewards and punishments. He uses its mixed results to motivate a review process that escalates risk to humans and preserves evidence of what changed and why.
- 1Review becomes the bottleneckGenerated code increases pull-request volume while humans remain responsible for approvals.
- 2A connectome as a reviewerA simulated fly brain receives code features as smells and learns from sweet and bitter feedback.
- 3Audience versus flyThe audience classified three examples correctly; the fly got two and the real pull-request demo was inconclusive.
- 4Escalate the risky changesNisi proposes team-owned review skills, a classifier and automated review before human escalation.
- 5Show evidenceScreenshots, tests and reproducible steps can demonstrate what a change actually does.
À retenir
- Treat review capacity as a bottleneck when generated code increases pull-request volume.
- A simulated fly learns associations between code-derived sensory features and test-based rewards; it does not understand JavaScript.
- In Nisi's demonstration the fly got two of three audience examples right and achieved about 88% in his own testing.
- Combine team-owned review rules, a risk classifier and automated reviewers, escalating failures to humans.
- Give reviewers evidence of behavior and the context for why a change was made.
Lire le texte remanié, chapitre par chapitre
The review bottleneck
Nisi argues that code generation is increasing the load on human reviewers. He suggests focusing on intended behavior and context.
I'm Nick Nisi, a software engineer and engineering manager at WorkOS, where I lead the developer and agent experiences team. Code is being written faster than ever and more pull requests are arriving, but even with CI, linting and automated agents, changes wait for me. I've become the bottleneck. If we aren't writing all the code ourselves, we should question why a human must review every line rather than focus on whether the functionality is right.
Coding agents have made us more like managers of work. We already run CI and reviewers such as Graphite and CodeRabbit against pull requests; when those checks give me confidence, the question I care about is whether the change does what I expect. I think human review will increasingly bring the change and its purpose back into context, rather than exist solely to catch a defect a machine supposedly cannot find.
A simulated fly brain
He describes a connectome-based simulation and how a model converts code into sensory features. Reward and punishment train associations in the simulated circuit.
The familiar story of a moth found in a relay in 1947 gives us a playful link between bugs and software. I'm going to use a bug to find software bugs: a simulated fruit fly. Others have used a fly connectome to play games; I decided to make mine review JavaScript.
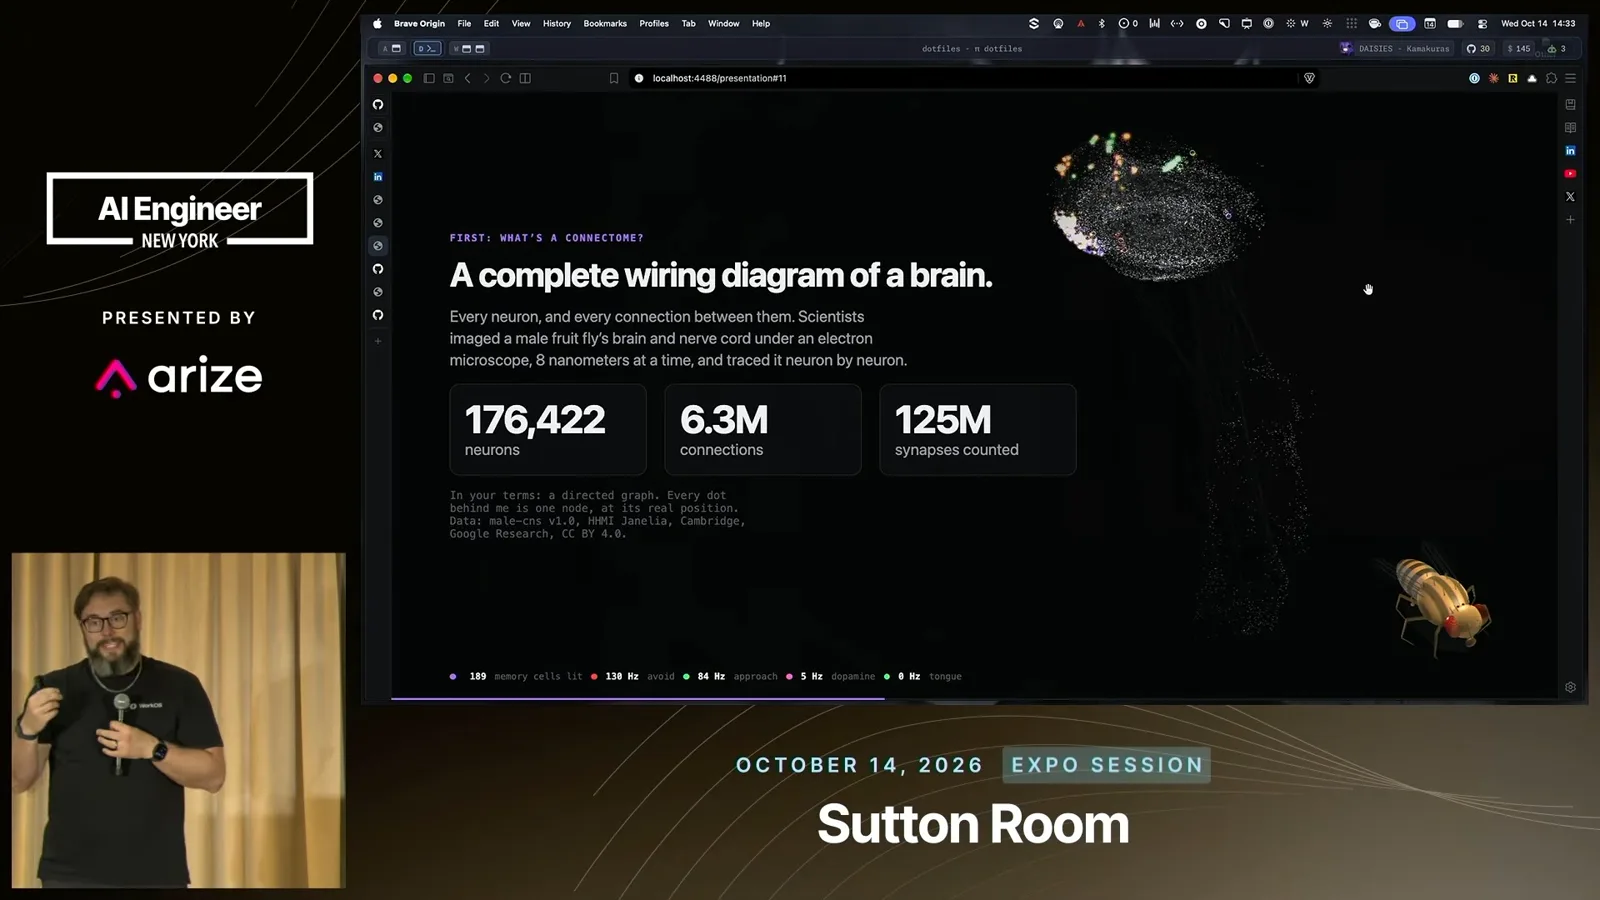
A connectome is a wiring diagram of a brain. Researchers sliced and imaged a male fruit fly's brain and nerve cord and traced its neurons and their connections: the diagram I use contains 176,422 neurons, 6.3 million connections and over 125 million synapses. I got the simulation running and changed a small subset of neurons used to retain memories, so it could learn associations between examples of good and bad code.
A fly doesn't know what code is. Its sensory hairs act as a nose, so I use a small AI model as that nose: it answers 30 unbiased yes-or-no questions about a change and turns the answers into a smell for the simulated brain. This makes the phrase 'code smell' literal in the demo.
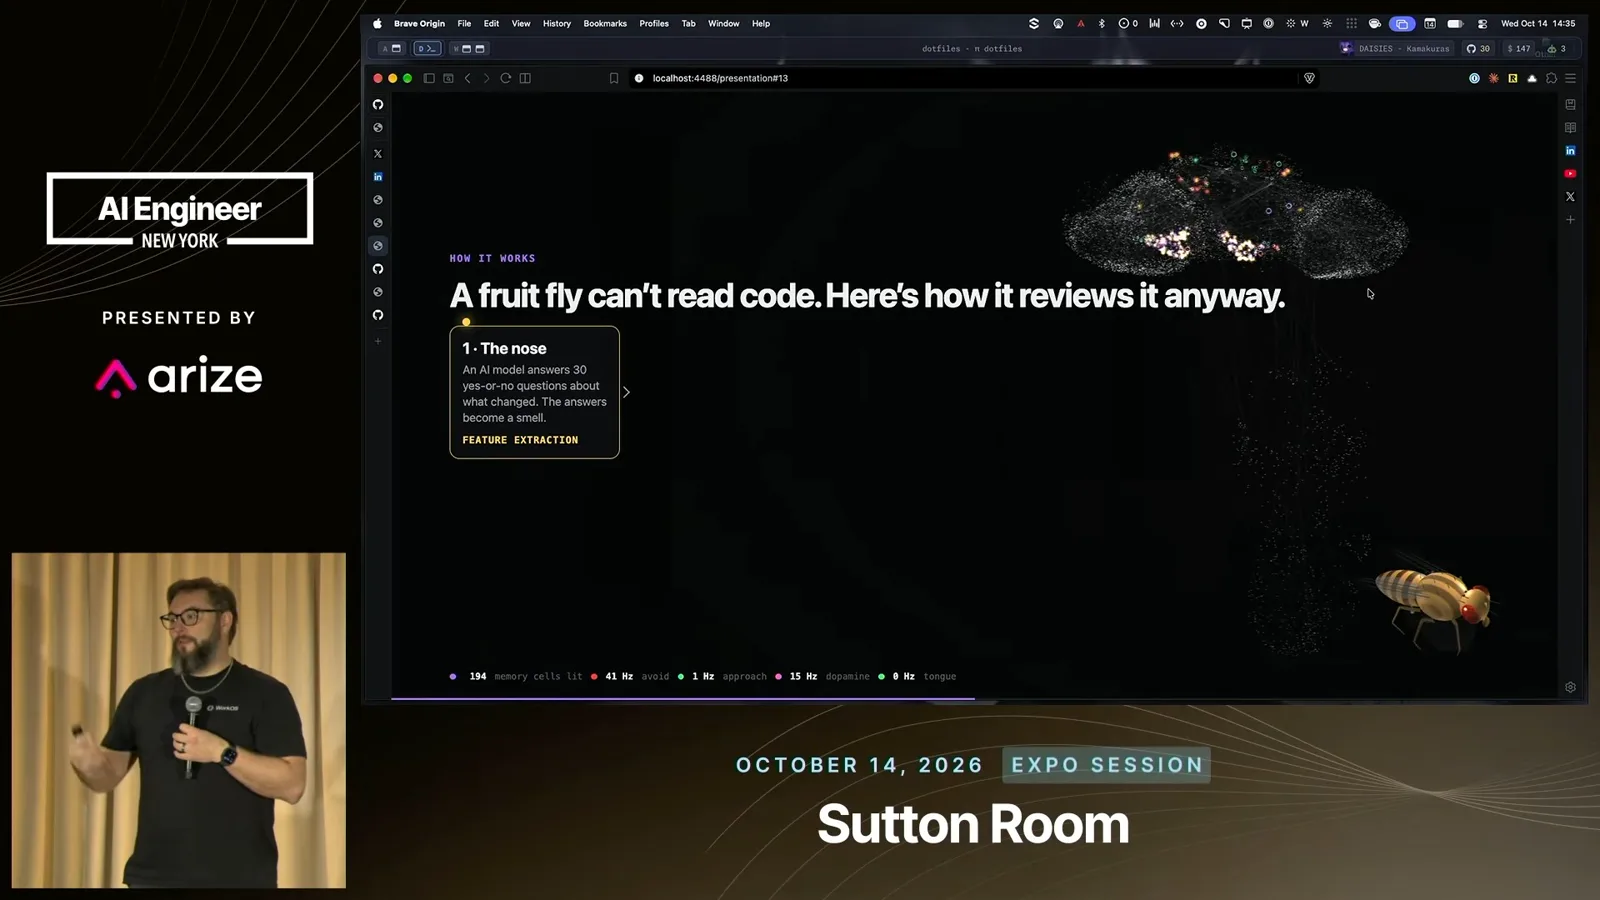
Before evaluating a pull request, the fly is trained on examples from the codebase. Good examples are associated with a sugar-like reward and bad ones with a bitter punishment. Those reinforcement signals affect connections in the memory circuit. Different changes produce different combinations of sensory input, and the trained circuit produces an approach or avoidance response.
The response becomes a vote: a tongue extension means the change smells acceptable, while withdrawal suggests changes are needed. I think of the memory as somewhat like a hash table whose keys deliberately collide, with test results writing the values. Rewards and punishments adjust the pathways associated with approaching or avoiding each smell.
I worried that the language model might be making the actual decision and the fly would be redundant. In my experiment, removing the learned memories scrambled the simulated fly's responses: it no longer knew which sensory patterns had led to reward or punishment. That ablation suggests the learned circuit contributes to the decision, although it doesn't make the fly a conventional code reviewer.
Testing the fly
An audience compares its decisions with the fly on three code changes. Nisi reports his testing and shows the limitations of a live pull-request demo.
We played a game with three changes drawn from the project's codebase. For the first, the room requested changes but the fly approved; the tests revealed a bug, so the fly was wrong. In a PKCE example, both the audience and fly approved a harmless change. On the final example both rejected a bug.
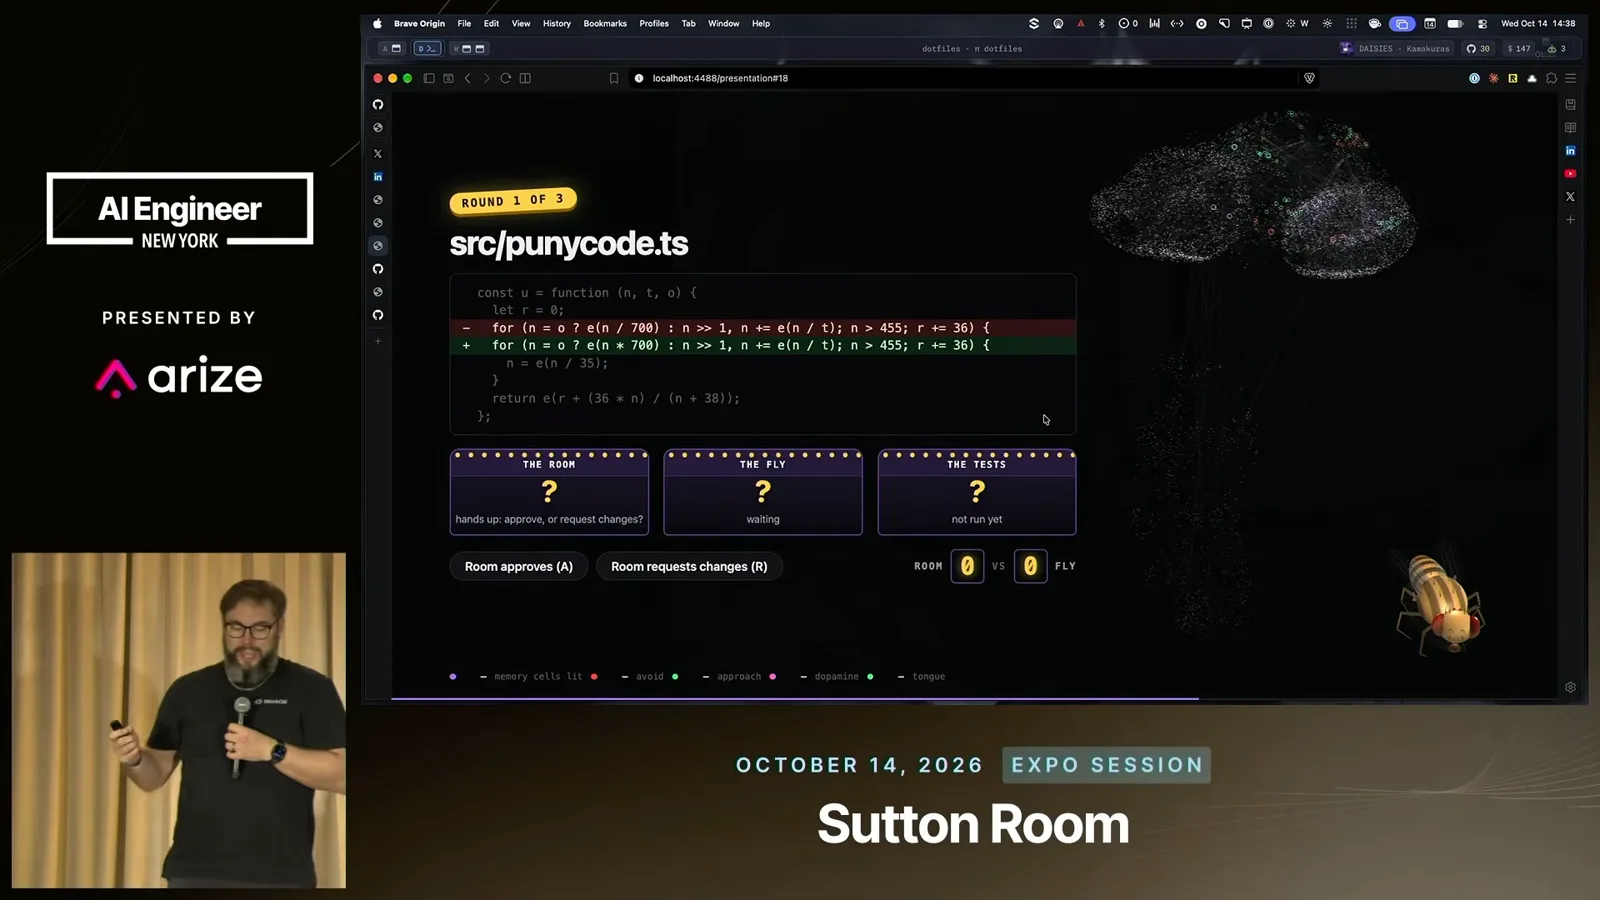
The room went three for three and the fly two for three. In my own testing I saw roughly 88% accuracy, but that doesn't mean a fly should review production code. A live attempt to evaluate a real pull request from one of my extensions produced no clear decision, including with my backup. You can experiment with the demo at fruitfly.review.
I also gave it harder tests. In two examples I reported it requested changes 96% and 98% of the time. The system can pick up patterns associated with changed conditionals or removed logic, but the fly doesn't understand JavaScript or explain a fix; at best its response says a change smells wrong.
A proposed review pipeline
Team-maintained rules, a classifier and automated reviewers would escalate risky changes to a human. Evidence and summaries would preserve accountability and context.
Existing automated reviewers can do this kind of analysis much better. The more interesting issue is why a change is being made and why behavior should change. I think humans should retain that context, while we reconsider whether every pull request needs a person to inspect it.
My proposed pipeline begins with a team review skill. At WorkOS, GitHub code owners can identify changes involving my developer experience team. We could maintain a script or skill that expresses the minimum checks a DX engineer would apply, and keep it current as our expectations change.
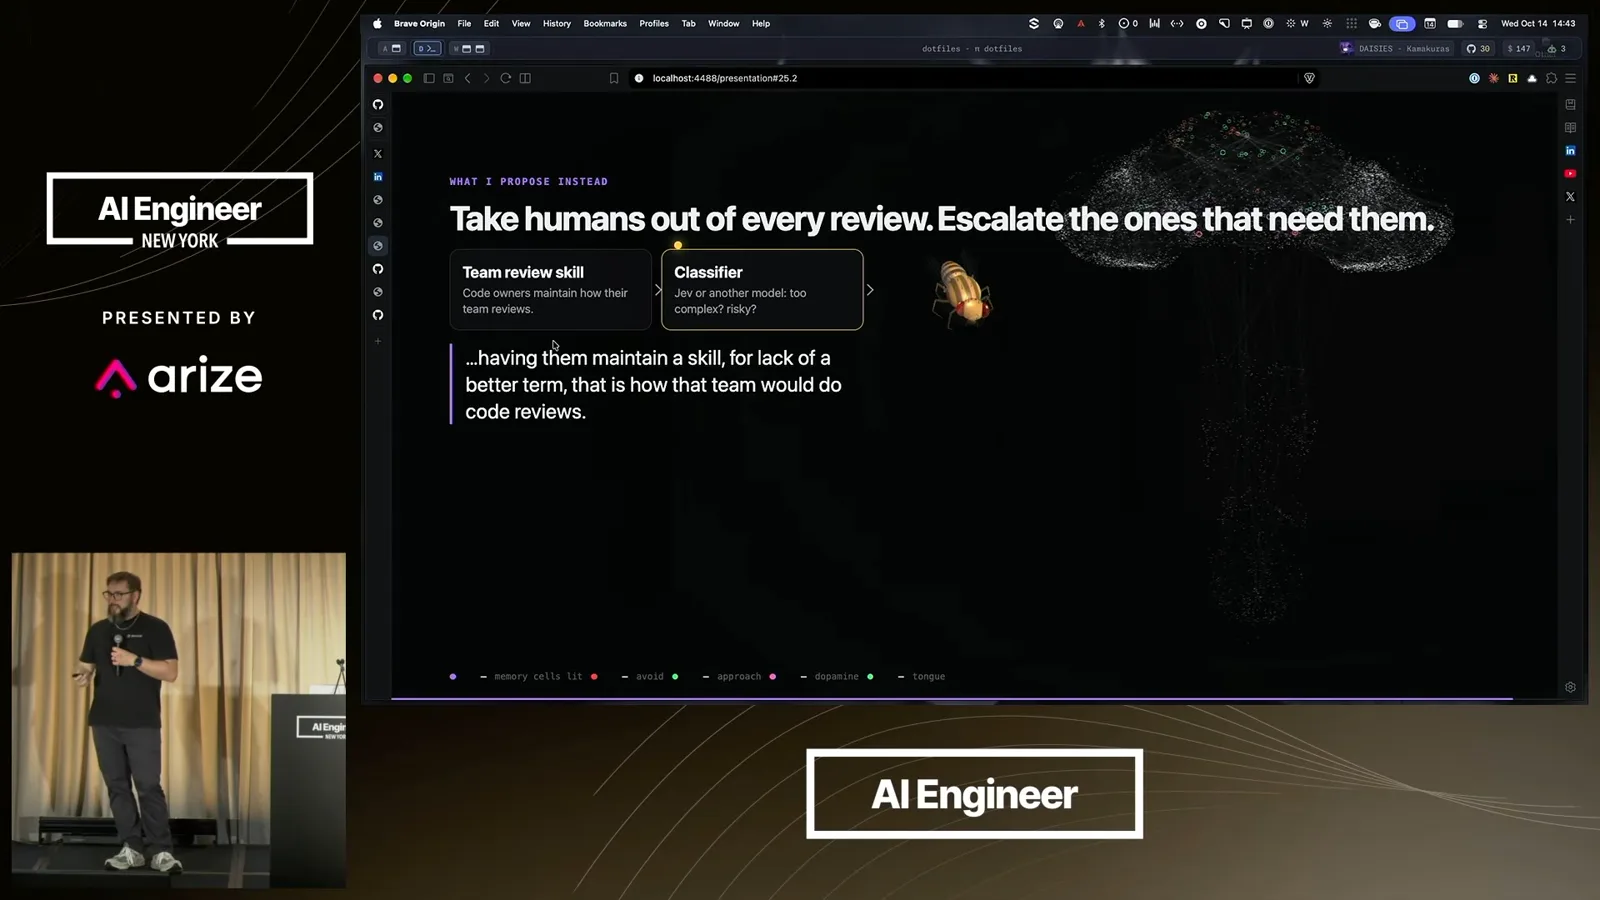
Next, a lightweight classifier could assess whether the change is too complex, carries substantial risk, or does what it claims. A specialized automated reviewer then adds another check. If any stage fails, escalate the pull request to a person; if all pass, I suggest that sufficiently safe changes could merge without holding up another engineer.
When something breaks, audit the process: could the team skill or an automated reviewer have caught it next time? Fix the code and update the safeguards. The human should also receive a summary of what changed and why, including whether business logic changed and which alternatives were considered.
The review should provide evidence that the change does what it promises. That might mean screenshots, video, test results, command output, smoke tests or clear steps for reproducing the behavior manually. As we build justified trust in those checks, we may need less routine manual verification.
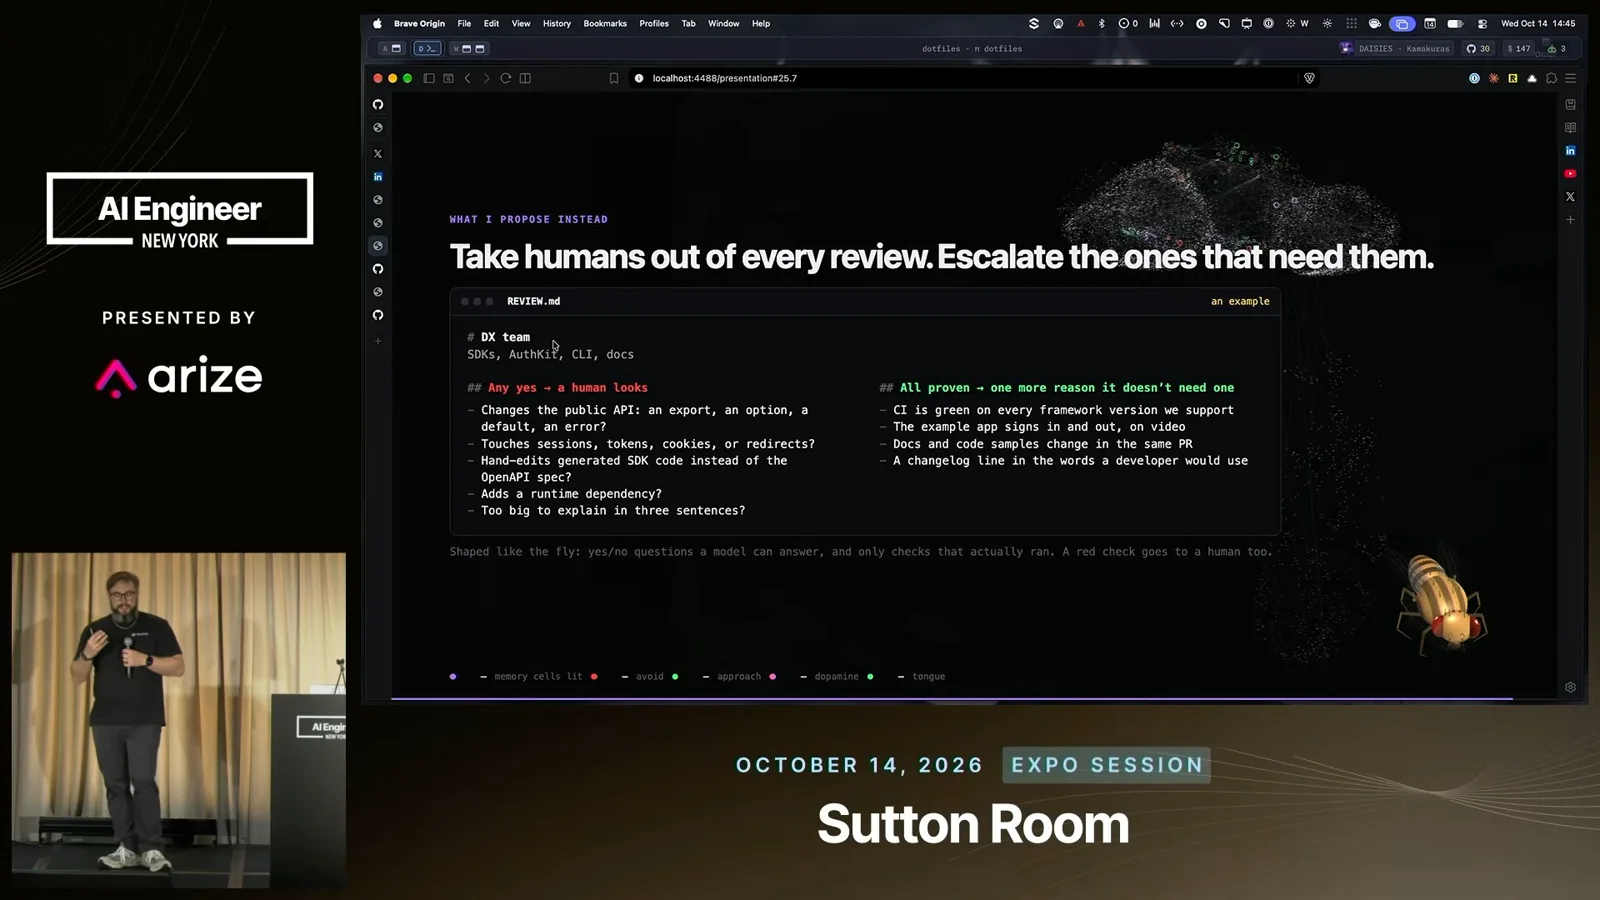
The actual review skill depends on the team. A DX team's criteria differ from a platform team's, and each can define what warrants human attention in its own area. Teams maintain those criteria and use them to decide which changes to escalate. The demo, slides and references are available at fruitfly.review.
Sur la même chaîne
 15:51EN
 AI Engineer· 2 nov. 2026Adam Nahari: Six Moves to Turn AI Pilots Into Financial ImpactAdam Nahari · ApolloAn airline crew-scheduling example shows why financial outcomes depend on workflow redesign, adoption and disciplined measurement.
 18:33ENAI Engineer· 2 nov. 2026Zack Proser: Build a Factory to Help Others Tell Their StoriesZack Proser · WorkOSA WorkOS blog assistant and a bedtime-story app show how AI tools can share expertise while humans retain responsibility.
 18:57ENAI Engineer· 2 nov. 2026Andrew Norrish: Code Context for AI-Era Incident ResponseAndrew Norrish · SourcegraphA Sourcegraph engineer describes review pressure and bounded workflows for investigating, preventing and fixing incidents.
 15:44ENAI Engineer· 1 nov. 2026Yijia Liang on Building Office-Compatible Engines for Finance AgentsYijia Liang · Compound AICompound’s approach combines shared agent inboxes, document engines and cited access to large data rooms.
 18:52ENAI Engineer· 1 nov. 2026Hahnbee Lee and Lincoln Murr on Documentation and Payments for AI AgentsHahnbee Lee, Lincoln Murr · MintlifyAs agents increasingly read docs and use services, Mintlify and Coinbase describe the importance of accurate content, APIs, payment permissions and maintenance.
 18:45ENAI Engineer· 1 nov. 2026Ramakrishnan Lokanathan: Evaluate the AI Agent’s Job, Not Just Its AnswerRamakrishnan LokanathanA practical framework for testing complete AI workflows, combining human feedback and regression checks with more challenging evaluations.