En 30 secondes
In December 2023, Matthew Berman predicts that AI will eventually eliminate most conventional programming and describes how he already combines ChatGPT, Copilot and his own testing. He discusses an illustrative cost calculation by Matt Welsh, tools for navigating codebases, an app-building demo and a proposed timeline. The timeline and claims of broad automation are predictions, not established outcomes; software engineering also includes requirements, review, security, maintenance and accountability beyond producing code.
- 1The value and difficulty of codingBerman recounts learning to code and founding Sonar while explaining why complex systems and edge cases are hard for humans.
- 2His AI-assisted workflowHe asks ChatGPT for code, tests it and uses Copilot to connect pieces, describing himself as the orchestrator.
- 3A rough cost comparisonIn an inserted clip, Matt Welsh contrasts developer compensation with estimated model-output costs. Berman acknowledges iteration costs, and the comparison does not establish equivalent engineering output.
- 4An imagined agent teamBerman proposes a human product manager, AI coding and testing agents, and human quality assurance as a possible workflow.
- 5A speculative timelineBerman forecasts wider nontechnical development in one to two years, agent teams in five years and natural language to computation in ten, measured from 2023.
À retenir
- Berman values learning to code but predicts that natural language and AI agents will eventually replace much conventional programming.
- His 2023 workflow combines ChatGPT-generated code, human testing and GitHub Copilot assistance; he says he was not then building production applications.
- Welsh's illustrative comparison of developer compensation with model output costs is not a measurement of equivalent, tested software engineering work.
- Context limits, stale knowledge, unreliable prompts and debugging remain central limitations in the account.
- Berman's one-to-two-, five- and ten-year timelines were forecasts made in December 2023, not verified outcomes.
Lire le texte remanié, chapitre par chapitre
Why programming mattered to Berman
Berman explains the value coding brought him and the difficulties of building complex systems. He traces the development of languages and tools.
I believe conventional programming is heading toward a profound change and perhaps an eventual end. This is my forecast from December 2023, influenced by Matt Welsh's talk on large language models and programming; it is not proof that programmers or software engineering have already become unnecessary.
Learning to code was one of the most valuable skills of my life. I started in high school because I wanted to build games, and after college it let me turn ideas into working software without waiting for someone else. I wrote the initial code for my company Sonar, found its first customers and then brought in a team to build it further.
Coding is also hard. Even after more than twenty years, I still struggle with details such as Python package management. Designing complex systems means reasoning through many interactions and edge cases, expressing them precisely and finding bugs that are easy to overlook.
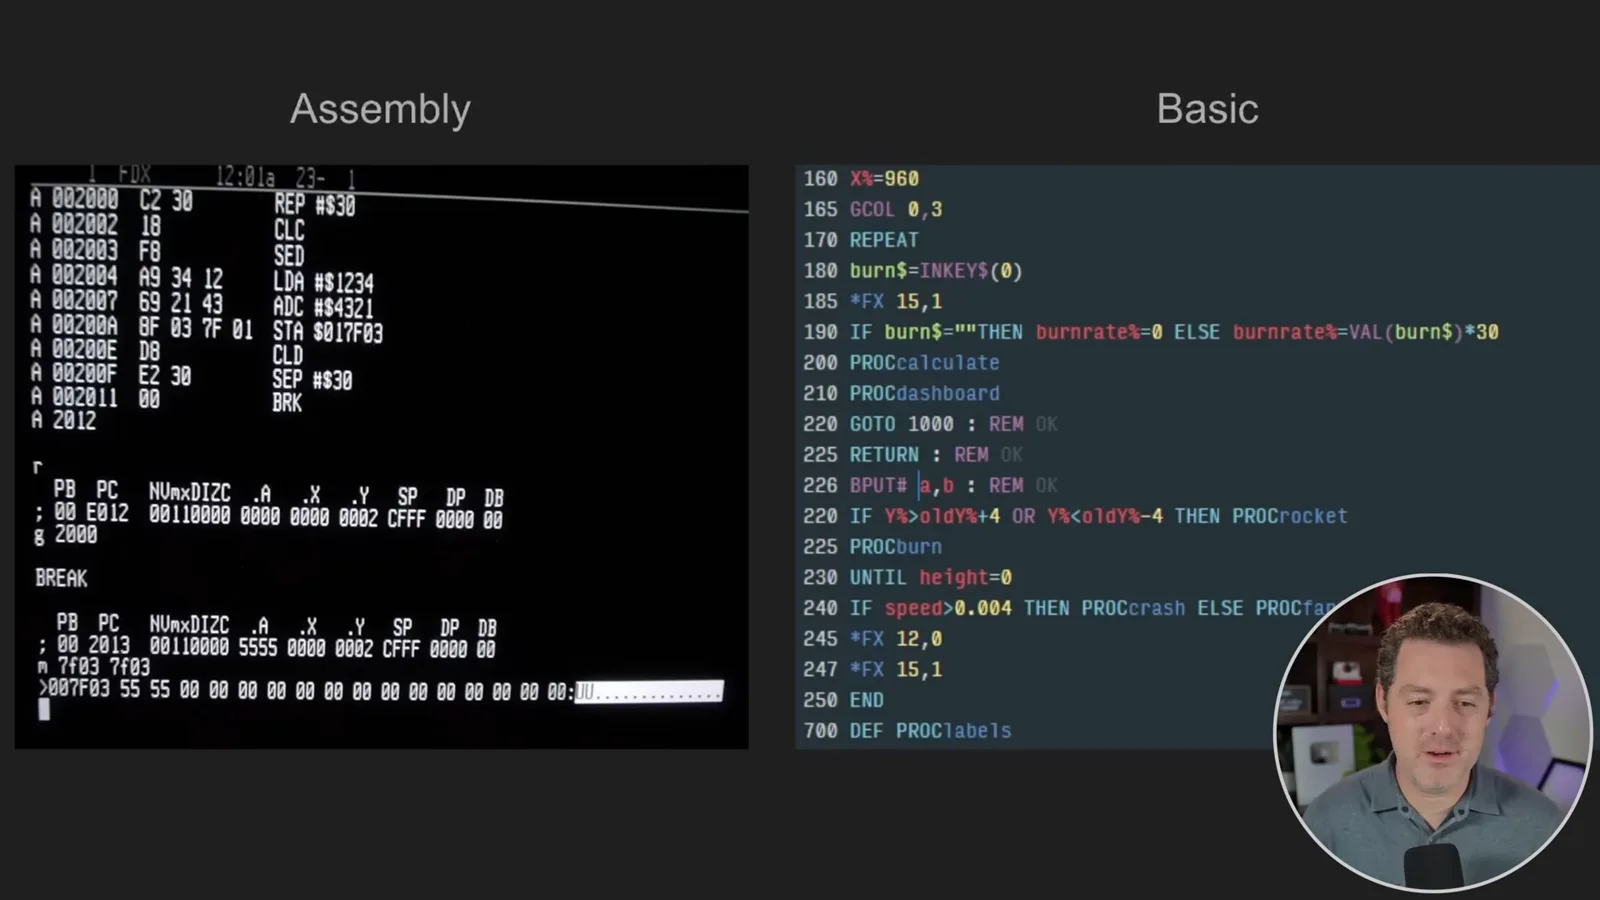
Programming has become more approachable over time, from room-sized computers and punched cards through assembly, BASIC and later languages with richer abstractions. Modern editors, syntax highlighting, version control, tests, automation and package tools help, though they do not make the underlying engineering challenges disappear.
Copilot, workflow and a cost comparison
He describes AI assistance and shares Matt Welsh's illustrative calculation. Berman acknowledges that iteration complicates the arithmetic, which does not compare complete engineering work.
GitHub Copilot felt like an inflection point to me: an assistant could complete code from surrounding context and help me stay focused rather than repeatedly leave my editor to search for syntax. My productivity and quality judgments are personal impressions; outcomes vary by task, developer, tool and review process.
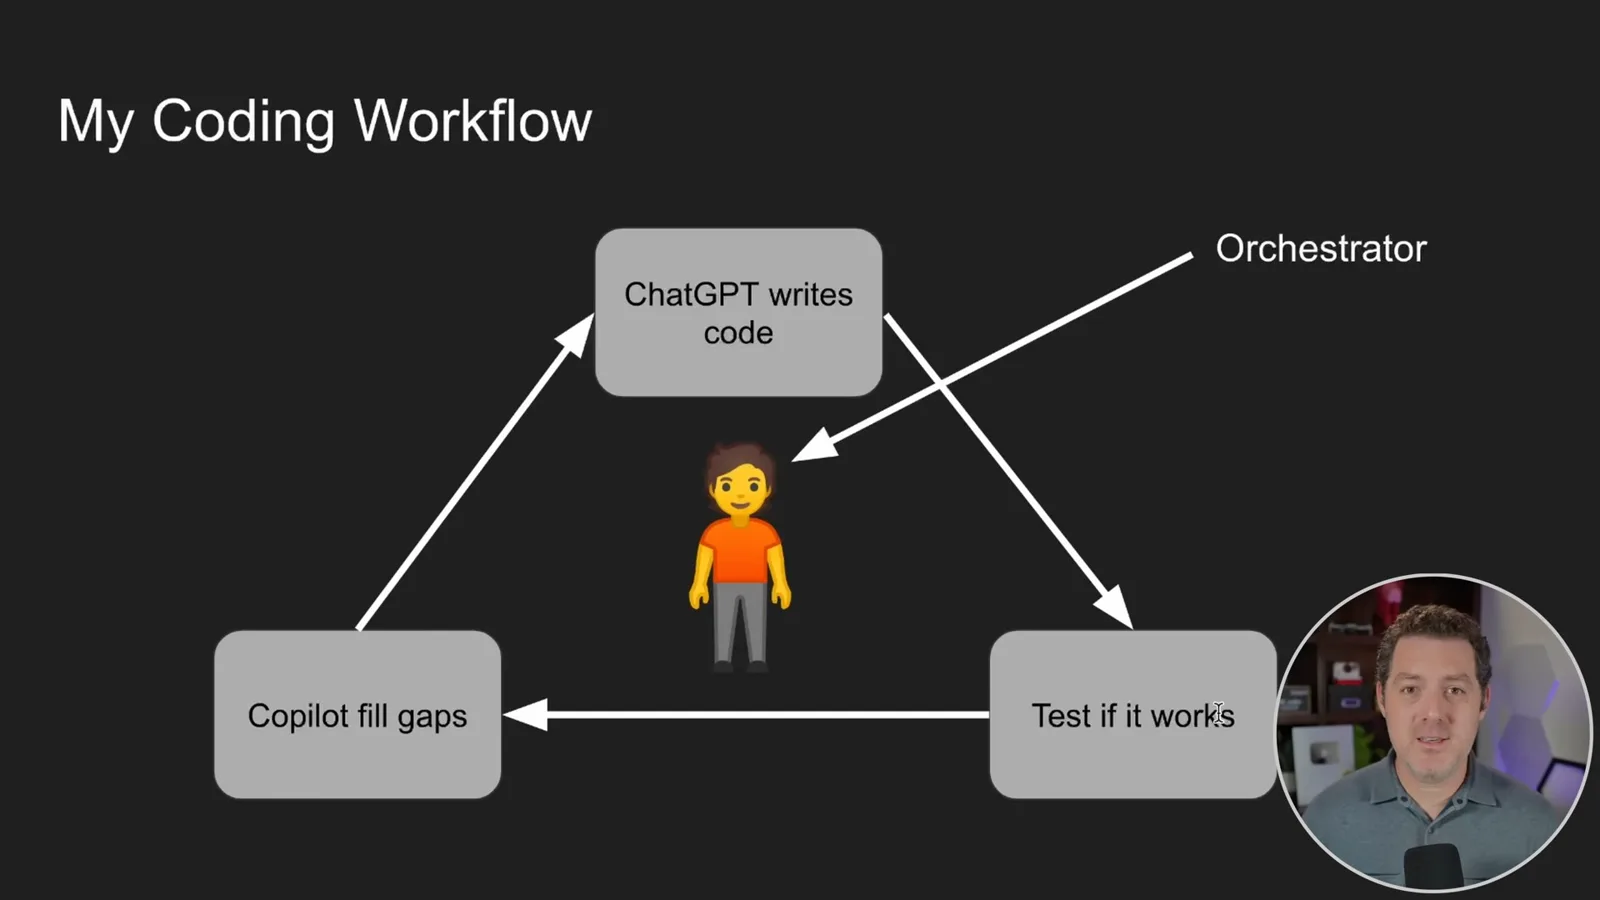
My workflow at the time was to ask ChatGPT for code, paste it into my project, test it and use Copilot to fill gaps. I act as an orchestrator. I also note that I was experimenting with AI projects daily, not building production-level applications at that point.
I argue that AI coding can scale more easily than hiring and that models can help with tedious syntax and data access. My broader assertion that AI is better, faster and cheaper than human programmers should be read as a prediction and comparison dependent on the task, quality requirements and full cost of supervision.
In a clip from his talk, Matt Welsh compares an assumed $220,000 salary plus $92,000 in additional compensation with an estimated 100 checked-in lines per day. He then equates that code volume with about 1,000 model tokens and cites a 12-cent generation cost. His example is deliberately rough: the displayed rate of two cents per 1,000 tokens would by itself yield two cents, and the clip does not explain the difference.
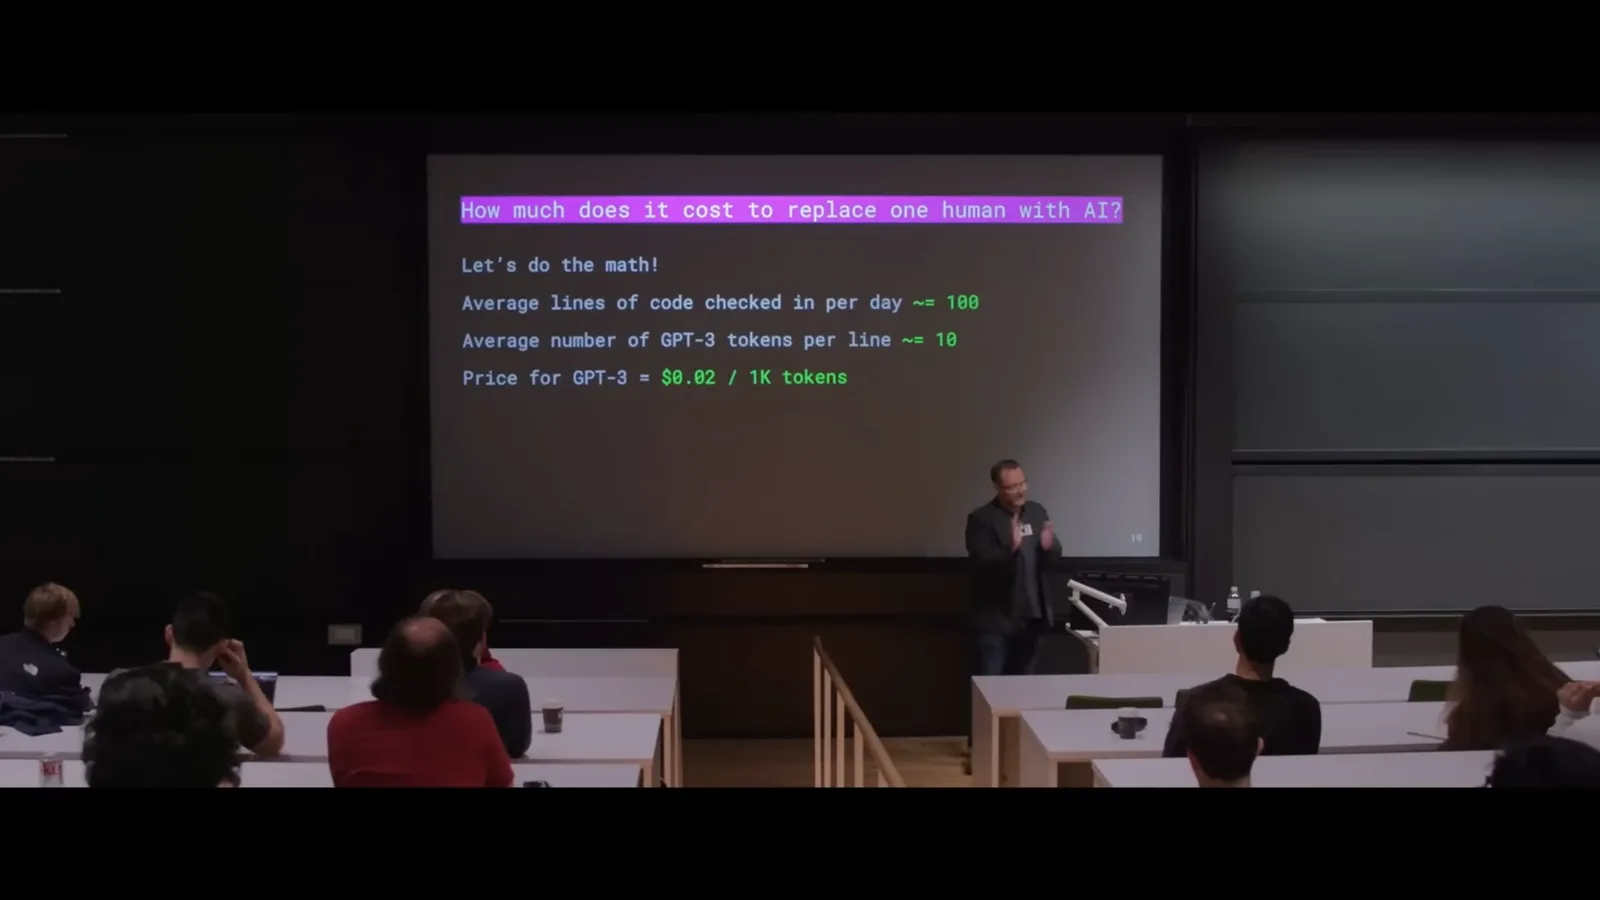
I point out a further limitation in Welsh's calculation: generated code often needs repeated attempts and iteration. Even beyond that, lines of output do not measure requirements gathering, review, debugging, security, integration or maintenance, so the comparison cannot establish the cost of replacing a developer or delivering equivalent software.
Limitations and proposed improvements
Berman discusses context, stale knowledge, synthetic data and repository mapping. He presents AI-agent teams as a future scenario.
In 2023, large codebases could exceed model context limits, and models might miss relevant details in long prompts or lack current API knowledge. Retrieval and web access can help but can also fail. I see data and compute as constraints and expect investments in hardware and additional training data to improve the situation.
I imagine a feedback loop in which human- and AI-produced code supplies training material for better models. That improvement is a possibility, not automatic: data quality, rights, filtering and evaluation affect whether additional synthetic code actually helps.
One approach I discuss is a compact map of a codebase. I cite Aider's use of repository mapping to give a model structural context without sending every file in full. Larger contexts, better retrieval and coding-specific fine-tuning might also help, but a map is not proof that a model fully understands a repository.
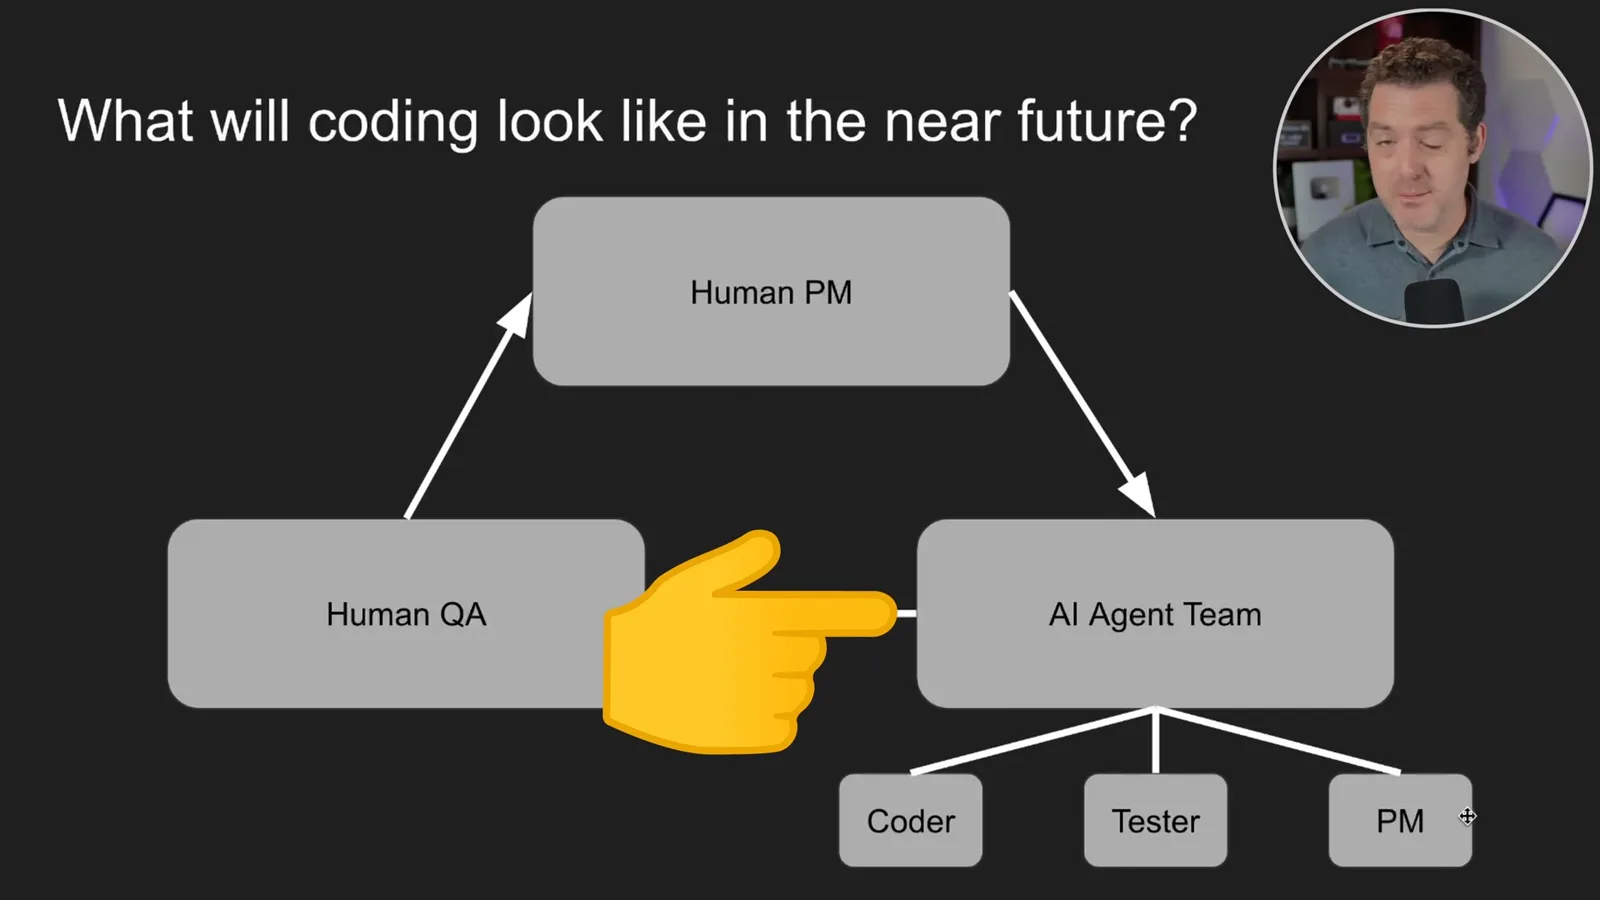
For the near future, I picture a human product manager translating business requirements into a task for AI agents that code, test and coordinate, followed by human quality assurance. The diagram has no human programmer. It is a proposed workflow and forecast, not evidence that all production projects can safely operate this way.
Natural language and a live example
He discusses a hackathon example, prompting challenges and McKay Wrigley's voice-driven app demo. These examples do not establish production readiness or eliminate the need for oversight.
I cite a Replit hackathon example shared by Amjad Masad in which a product manager built a project using AI tools, and Vinod Khosla's prediction that natural-language programming could broaden access. These examples suggest a lower barrier to prototypes; one contest does not prove that complex products can be maintained without technical expertise.
Natural-language instructions have their own friction. As Bindu Reddy observes in the example I discuss, changing a prompt to fix one case can break another; prompting therefore needs testing, versioning, monitoring and evaluation. I expect humans to remain in the loop at least in the short and medium term.
I show McKay Wrigley's Jarvis demo: he speaks requests for a Next.js and Tailwind social app, including a profile form, profile viewer, user list and responsive dark styling. The assistant describes creating a repository, database and deployment; Wrigley then checks the page and database. This is a small demonstration, not a complete security, reliability or maintainability assessment.
Long-term predictions and learning to code
Berman presents his speculative vision and a timeline from 2023. Despite his prediction, he says he would still encourage his children to learn coding and computer science.
I see AI coding adoption growing rapidly and point to search-interest data as a sign of attention. Search volume is not itself a measure of adoption or a guarantee of exponential future progress. My longer-term vision is a model translating natural-language requests into actions on devices, with far less conventional programming between the user and computation.
I am unsure which roles would remain in that future. Computer scientists might still do deep technical work, and humans may continue to check quality and alignment. Those possibilities reflect uncertainty about what automation will actually accomplish.
My estimates from December 2023 are that nontechnical people would increasingly build software within one to two years, manage large AI-agent teams within five years, and reach natural-language-to-computation in ten years. These are dated predictions rather than confirmed milestones, and the eventual pace and scope are uncertain.
Despite believing programming will change dramatically, I would still teach my children to code. It is interesting and teaches decomposition, logic and reasoning. I also expect learning to work with AI to become more valuable, even though I feel sad at the possibility that a skill I love could become less needed.
Sur la même chaîne
 34:21EN
 Matthew Berman· 27 oct. 2026Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 0:36ENMatthew Berman· 25 oct. 2026Kimi K3.1 and a Rubik’s Cube Solver DemonstrationMatthew Berman · Forward FutureMatthew Berman shows a scrambled virtual cube being solved and gives the Kimi K3.1 test a favorable assessment.
 0:21ENMatthew Berman· 24 oct. 2026An AI-Generated Kimi Benchmark Chart Used Invented ScoresMatthew Berman · Forward FutureMatthew Berman asks for a graph of Kimi K3.1 Pro benchmarks, then discovers that the displayed figures are illustrative placeholders.
 25:50ENMatthew Berman· 24 oct. 2026Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.
 32:20ENMatthew Berman· 23 oct. 2026Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.
 1:03:37ENMatthew Berman· 23 oct. 2026Matthew Berman’s Team Tests Kimi K3.1 on Animation, Games, and ChartsMatthew Berman, Alex, Brian · Forward FutureA live team AMA turns into an informal test of Kimi K3.1, from personal-agent workflows to motion graphics, a browser game, and a benchmark chart.