En 30 secondes
Theo Browne discusses a Linux kernel mailing-list debate around Sashiko and Linus Torvalds’s position on AI tools. He argues that automated review and verification can help, while recognizing maintainer burden and comparing differing experiences of AI with earlier TypeScript debates.
- 1Sashiko reviews kernel patchesThe project reports a specific evaluation and cautions that model output is probabilistic.
- 2Report quality and volumeGreg Kroah-Hartman describes better reports, while Theo notes that smaller projects may struggle with volume.
- 3Torvalds’s mailing-list responseHe says Linux is not categorically anti-AI and argues that tools should help maintainers.
- 4A TypeScript analogyTheo’s conceptual floor-and-ceiling diagram illustrates why different developers may experience a tool differently.
- 5Verification beyond generationTheo suggests tests and PR triage while maintaining that code reading remains useful.
À retenir
- Sashiko’s reported bug-finding rate applies to a particular evaluation and model, not all code review.
- Generated findings need validation, and large volumes can burden maintainers.
- Torvalds argues for tools that help kernel maintainers and for decisions based on technical merit.
- A developer’s experience with a tool depends on their work and existing expertise.
- AI can assist with tests and triage as well as code generation.
Lire le texte remanié, chapitre par chapitre
Linux and AI review
Theo introduces the debate and Sashiko’s reported evaluation. He explains why automated review can add checks around human work.
I begin with a deliberately sarcastic claim that Linux and Linus Torvalds must be against AI. His recent mailing-list response says the opposite: the kernel project is not categorically anti-AI. I want to explore what that position means for maintainers, code review and the rest of software development.
The immediate context is Sashiko, an open-source, agentic review system for Linux kernel patches. It can examine patches from mailing lists or local Git and works with multiple model providers. The project reports results for a particular test of recent upstream commits marked as fixes.
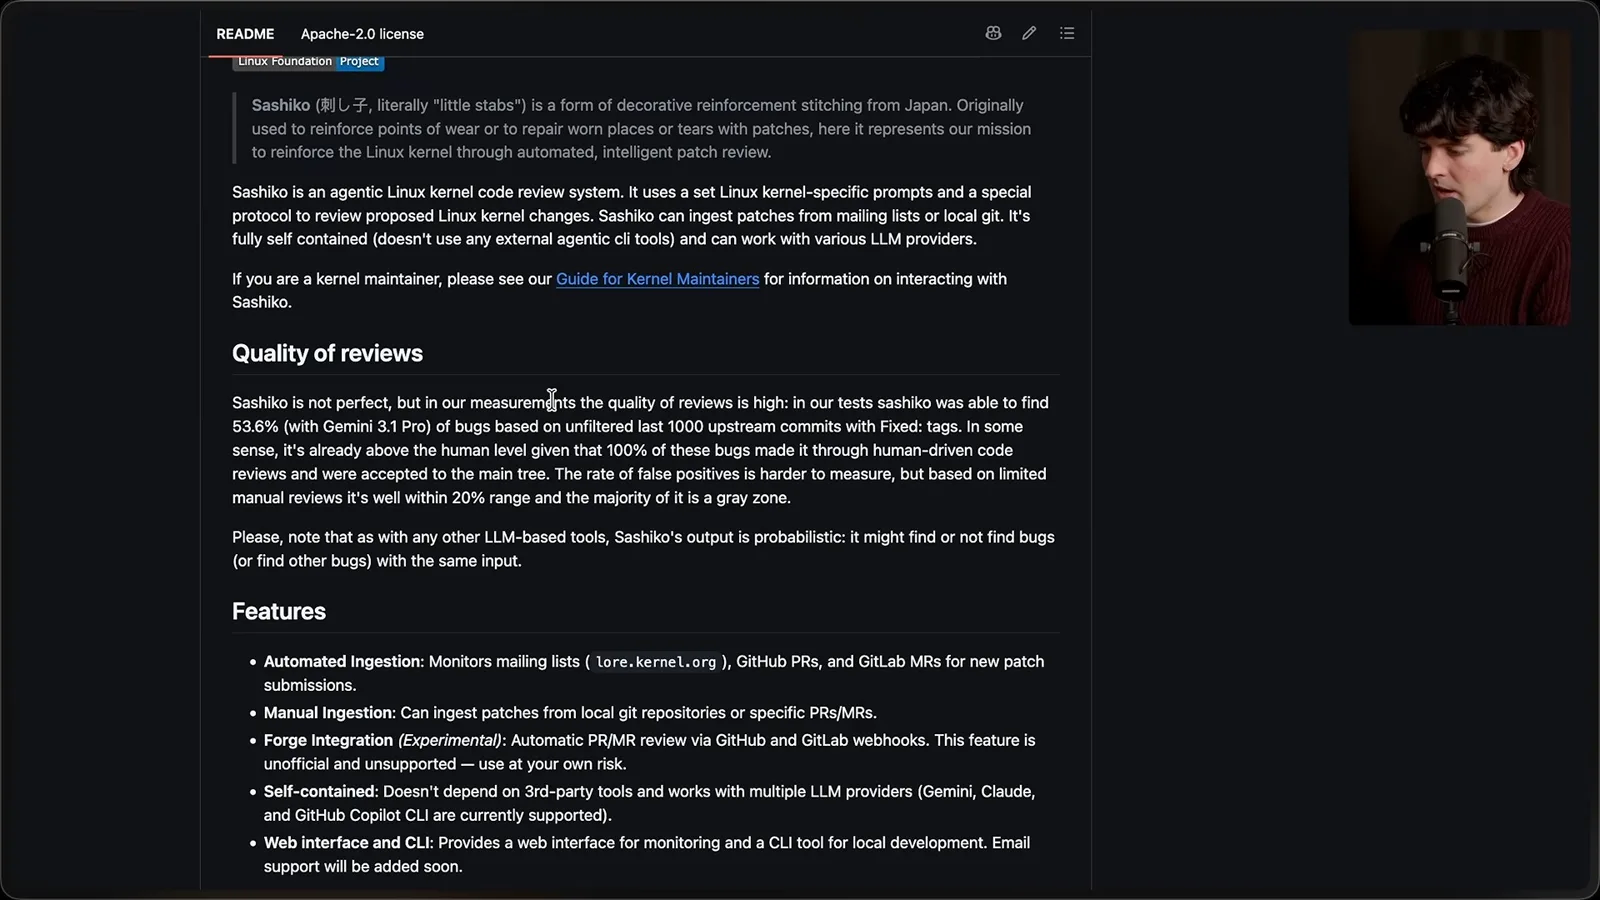
In the reported test, Sashiko found 53.6% of bugs in the selected set using Gemini 3.1 Pro. Its authors say false positives are harder to quantify and cite limited manual review. These numbers describe that evaluation, not a general comparison proving that AI reviewers outperform humans on all code.
The authors also note that model output is probabilistic: the same input may produce different findings on different runs. That is a healthy qualification. I see value in another reviewer and in additional tests that help a maintainer evaluate a patch, rather than treating a model’s answer as a final verdict.
When I argue for using AI to review code and build verification tools, I am not saying nobody should read a patch before merging it. For many projects human review is still a good idea. The opportunity is to add checks, including temporary tests that need not be committed, around the change.
Maintainer burden and security reports
A kernel maintainer describes changing report quality. Theo discusses review volume and the capacity of small projects.
Theo discusses a report quoting kernel maintainer Greg Kroah-Hartman, who described an improvement in the quality of AI-assisted security reports after an earlier wave of obvious junk. That is the maintainer’s reported experience, not evidence that all generated reports are now reliable.
My guess is that better models reached more developers, who then learned to build workflows around them. That is speculation, not a demonstrated cause of the change Greg observed. The important practical issue is whether a report gives maintainers reproducible evidence rather than another confident but unverified claim.
Even when reports identify real issues, volume creates work. A large, distributed kernel team has more capacity than a small open-source project. Faster automated feedback can help submitters revise a patch before a human review, but maintainers still need time to triage and validate the results.
I point to a large number of Linux CVE records as evidence of the scale of security work and argue that both defenders and attackers can use automation. A CVE count is not the same as a count of newly discovered or actively exploited vulnerabilities; it should not be used alone to infer either.
The mailing-list disagreement
Torvalds argues that the kernel project should assess tools on merit and ensure they help maintainers. Theo responds to the ethical disagreement.
The mailing-list disagreement began around Sashiko and broadened into an objection to LLMs generally. Torvalds responded that Linux is not an anti-AI project, and that people who disagree can choose another project or fork it. Theo agrees with his position that a useful tool should be judged on its merits.
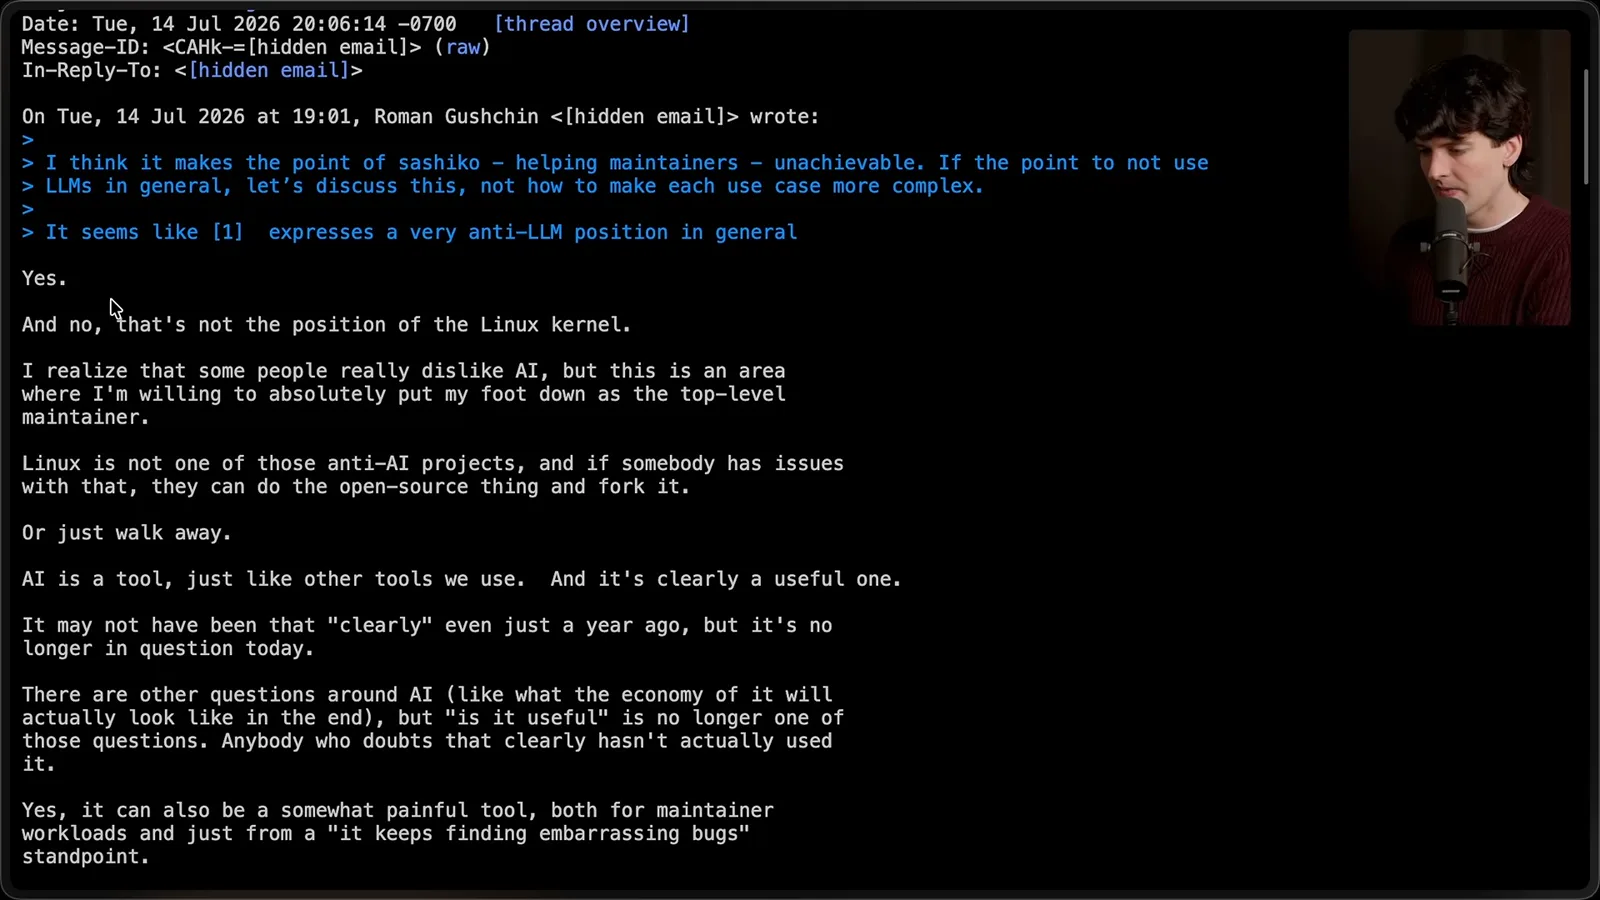
Torvalds also acknowledges questions about AI’s economics and the pain it can cause maintainers, including a stream of embarrassing bug findings. His proposed direction is to make the tools help maintainers rather than burden them. That is a different claim from requiring every contributor to use them.
I think model providers should have helped open-source maintainers earlier, especially given the importance of open-source code to the ecosystem. Useful support can include direct funding, access to tools, private security work and contributions that are properly checked before they reach a maintainer.
Torvalds argues that kernel decisions should focus on technical merit and says individuals may choose whether to use AI. Another participant, Laurent, objects on ethical grounds. Theo agrees with Torvalds, while the disagreement shows that contributors can evaluate the same tools through different technical and ethical lenses.
I have changed my own expectations as coding models improved, moving from small edits to more ambitious tasks. I expect more developers to find useful applications, but that is my forecast, not proof that every maintainer must adopt the same workflow or reach the same conclusion.
TypeScript as an analogy
Theo compares different developers’ experiences with TypeScript and AI. He ends with examples of using AI for verification.
I compare the disagreement with early debates over TypeScript. Experienced JavaScript developers on small teams did not necessarily feel the same need for it as large teams coordinating many contributors. Different tools solve different problems, and a benefit to one group does not mean every individual experiences the same gain.
Theo describes TypeScript as a way to help large teams catch changes that break distant parts of a codebase. He credits Anders Hejlsberg and Microsoft’s need to work at scale. Type definitions can shift work to library maintainers even as they make those libraries easier for others to use.
I recall a discussion with SolidJS creator Ryan Carniato, who said he had used TypeScript for years without being convinced it improved his own productivity. He described an intuitive API that was quick to create but difficult to type well. I see that as a real cost, not a reason to dismiss his experience.
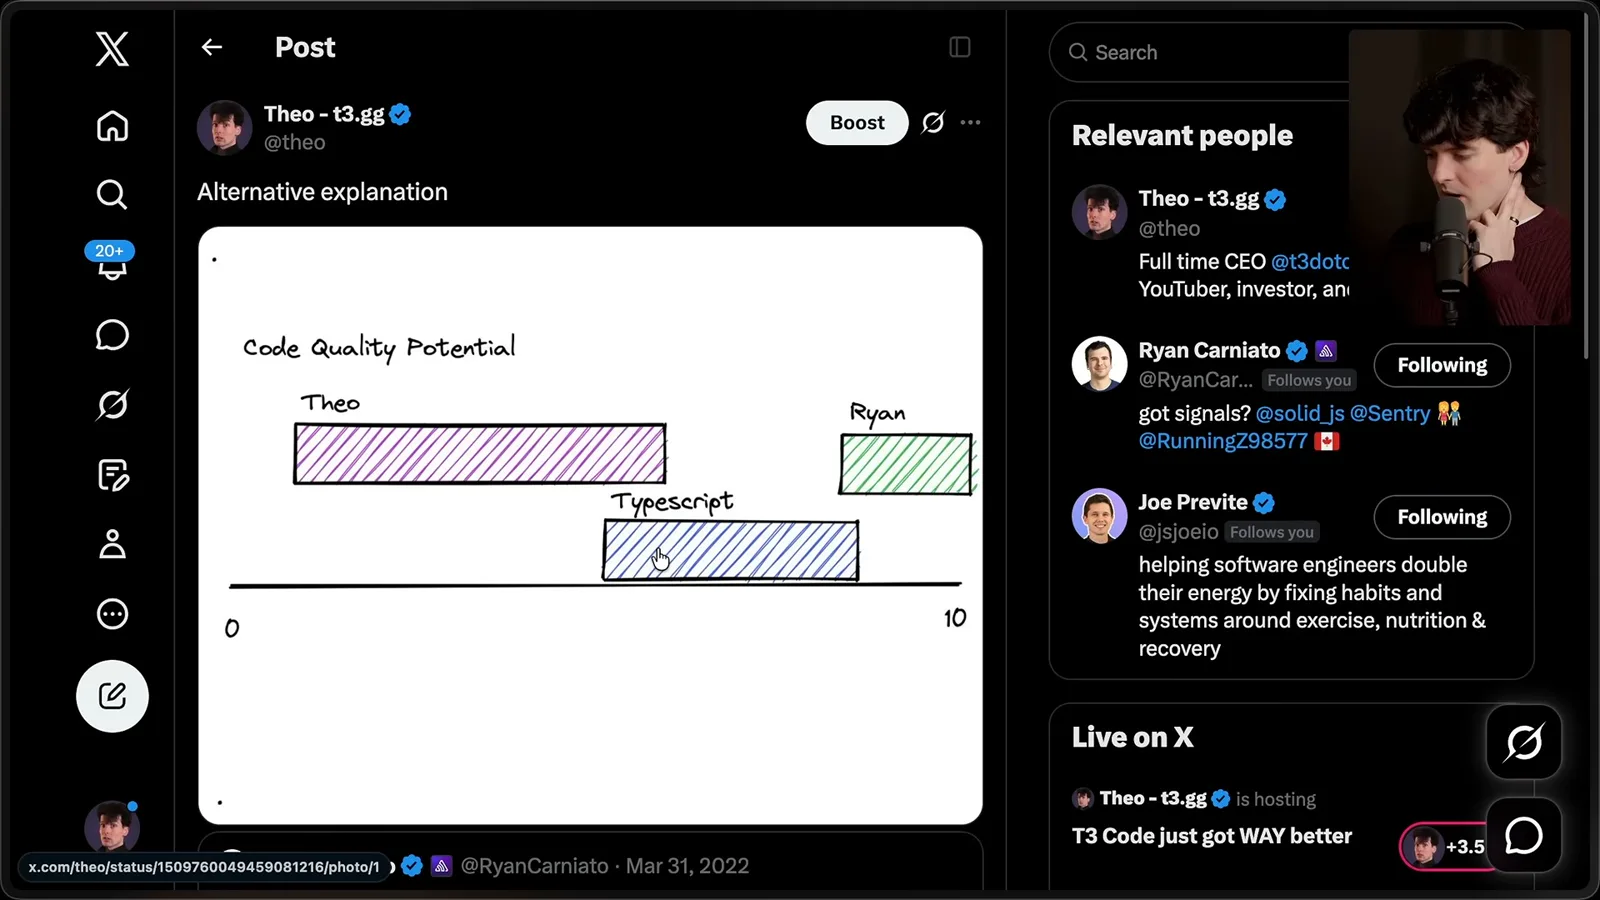
My diagram suggests TypeScript raises the floor for many developers while potentially constraining some highly skilled work at the upper end. This is a conceptual model, not a measured distribution. I use it to explain why I benefited from the tool while another experienced developer could reasonably feel differently.
I see a similar possibility with AI: an expert kernel maintainer may write better kernel code than a model, while a skilled developer from another specialty might find assistance useful. That does not make generated code correct. Domain review and verification remain necessary.
I mention Torvalds using a model for visualization outside his usual specialty as an example of a tool helping someone move more quickly in an unfamiliar area. My own experience with TypeScript, and now AI, has similarly made me more willing to attempt work beyond my established routines.
There are useful applications besides submitting generated code: audit open pull requests, build targeted tests, or investigate whether an existing change behaves as expected. I still do not mean that people should stop reading code. I want teams to use inexpensive generated work to strengthen their verification.
I am optimistic about future model progress, but nobody has to adopt every tool immediately. Experiment where it helps your own work, consider the burden placed on maintainers, and judge the results rather than assuming that more generated output is automatically better.
Sur la même chaîne
 38:47EN
 Theo - t3․gg· 28 oct. 2026Theo’s Long-Running Agent Experiments: Verification, Compute and CostTheo Browne · Ping LabsA skateboard game and two compiler projects show how repeated checks and flexible compute can sustain agent work—and how expensive those loops can become.
 36:07ENTheo - t3․gg· 27 oct. 2026Theo on Token Costs, Coding Agents, and the Price of AI CapabilityTheo Browne · Ping LabsA viral estimate of Lauren's AI spending prompts a closer look at cache pricing, benchmarks, and the changing work of coding agents.
 30:37ENTheo - t3․gg· 26 oct. 2026Theo’s Three Skills for Reviewing and Shipping with Coding AgentsTheo Browne · Ping LabsHow sol-loop, full-send and full-stop encode review, verification and different levels of merge authority.
 0:43ENTheo - t3․gg· 23 oct. 2026Theo Distinguishes Security Vulnerabilities from Active AttacksTheo Browne · Ping LabsA short explanation of why disclosed software flaws and reported attacks are different kinds of security news.
 29:22ENTheo - t3․gg· 22 oct. 2026Theo on Security Vulnerabilities, Stolen API Keys and AITheo Browne · Ping LabsA look at the gap between vulnerability disclosure and patching, and a speculative account of why stolen inference keys may be valuable.
 31:13ENTheo - t3․gg· 20 oct. 2026Theo on Why Smarter Models Help More Than DevelopersTheo Browne · Ping LabsFrom game modifications to compiler experiments, Theo revisits his assumptions about who benefits from more capable AI.