En 30 secondes
Matthew Berman examines the Gemini 3 Pro launch and the accompanying Deep Think benchmark preview, highlighting reported gains in reasoning and long-horizon tasks. He demonstrates a video-understanding query and discusses Google Search, Antigravity, Gemini Agent and the model card. The video reflects the November 18, 2025 launch rather than current rankings or availability. Benchmark scores are reported results under specified settings; a single demonstration and simulated tasks do not establish universal reliability.
- 1Launch benchmark resultsGoogle’s table reports Gemini 3 Pro at 37.5% on Humanity’s Last Exam without tools and 31.1% on ARC-AGI-2. These are historical scores under the stated test settings.
- 2Deep Think previewGoogle reported stronger results for its Deep Think mode, which required additional safety evaluation before wider release.
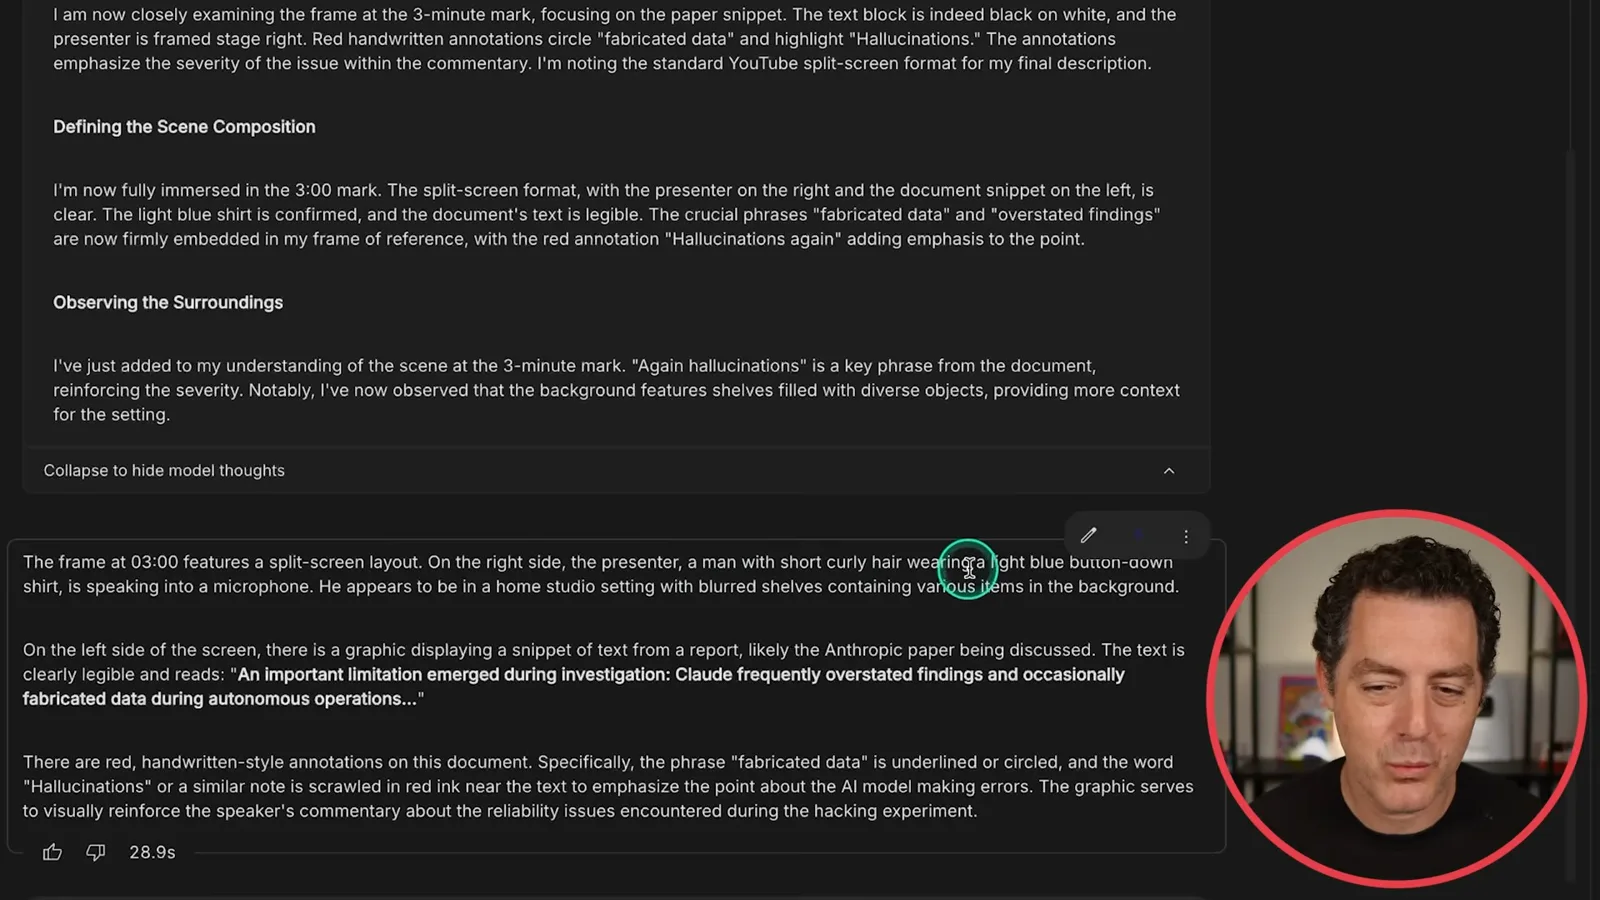
- 3Video demonstrationBerman asks Gemini to describe a frame in one of his videos and compares the response with the source.
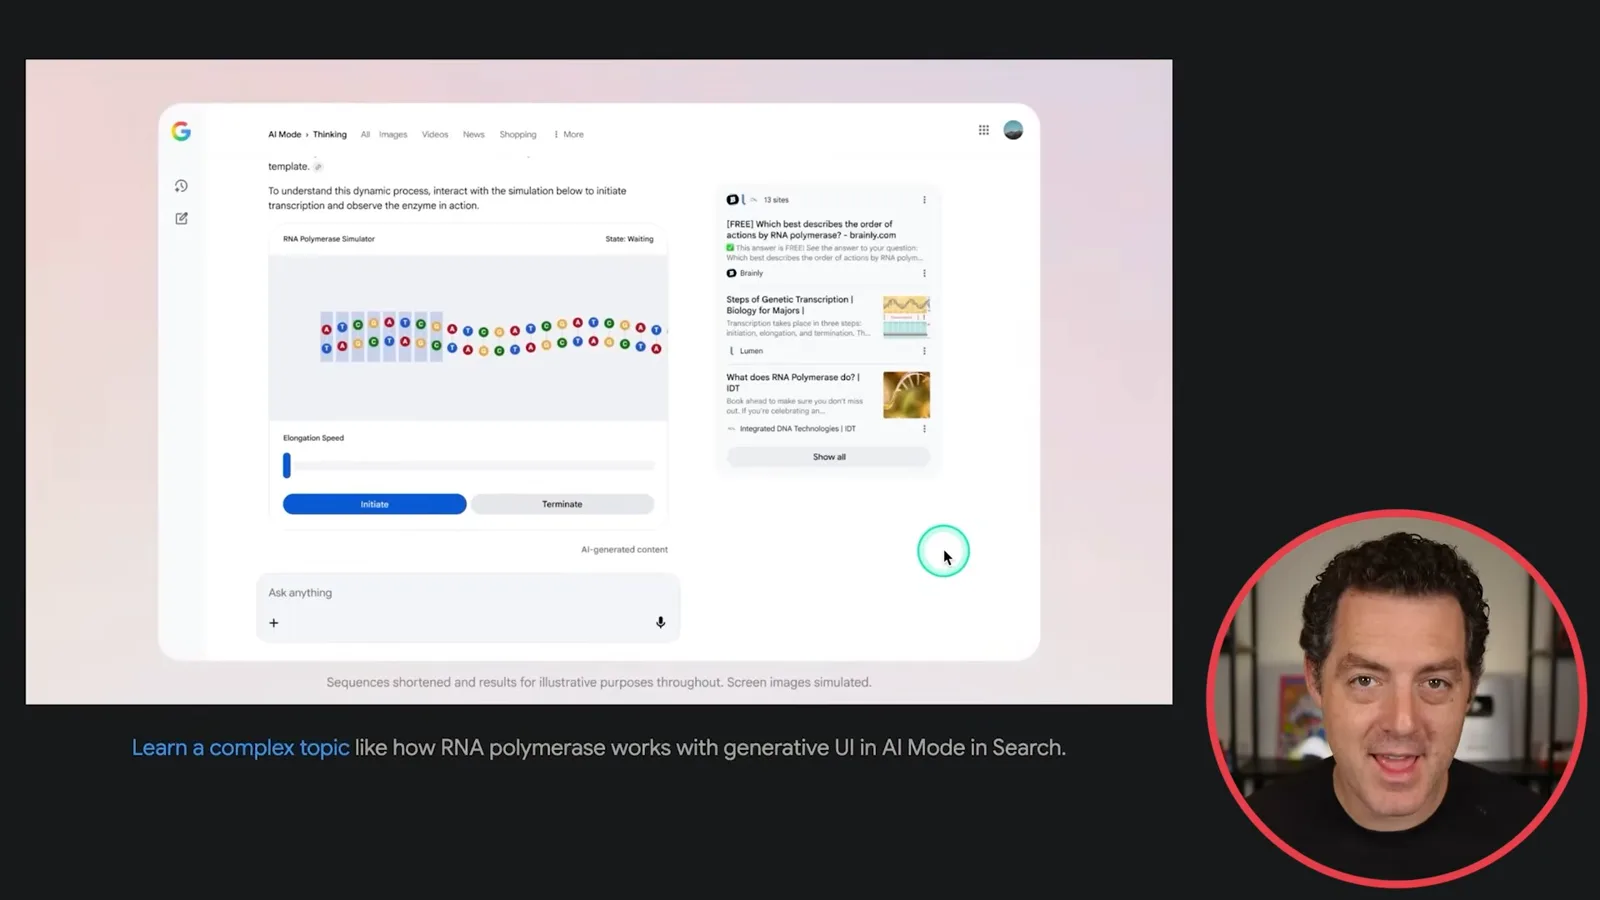
- 4Generative interfaces in SearchA Google demonstration presents an AI-generated interactive interface; the onscreen example is marked as simulated.
- 5Vending simulationThe Vending-Bench 2 chart averages five runs per model, illustrating performance in one simulated environment.
- 6Agent-assisted inboxAn experimental Gemini Agent workflow proposes email actions and lets the user review individual suggestions.
À retenir
- Google introduced Gemini 3 Pro in November 2025 and previewed Deep Think, which was not yet generally available at the time of the video.
- Google’s benchmark table reported strong scores for Gemini 3 Pro, though results depend on task, model configuration and tool access.
- Berman demonstrates asking a model about a moment in a YouTube video; video sampling and one successful example do not establish perfect frame-by-frame comprehension.
- Google previewed generative interfaces in Search and an agent-assisted coding platform called Antigravity.
- Vending-Bench 2 measures a simulated vending operation over time, not the successful running of a real business.
- The Gemini Agent demonstration proposes organizing email with a user-review step, while the model card describes multimodal input and a sparse mixture-of-experts architecture.
Lire le texte remanié, chapitre par chapitre
Gemini 3 Pro and reported benchmarks
Berman introduces Google’s November 2025 release and reviews scores across reasoning, coding and simulated economic tasks. He also mentions a sponsor’s document evaluation.
Gemini 3 is here, and I am impressed by both the model and Google’s effort to integrate it across products. This video was published on November 18, 2025, when Gemini 3 Pro was introduced in preview. I also discuss Gemini 3 Deep Think; at launch Google said that mode would undergo additional safety evaluation before broader availability, rather than being generally available that day.
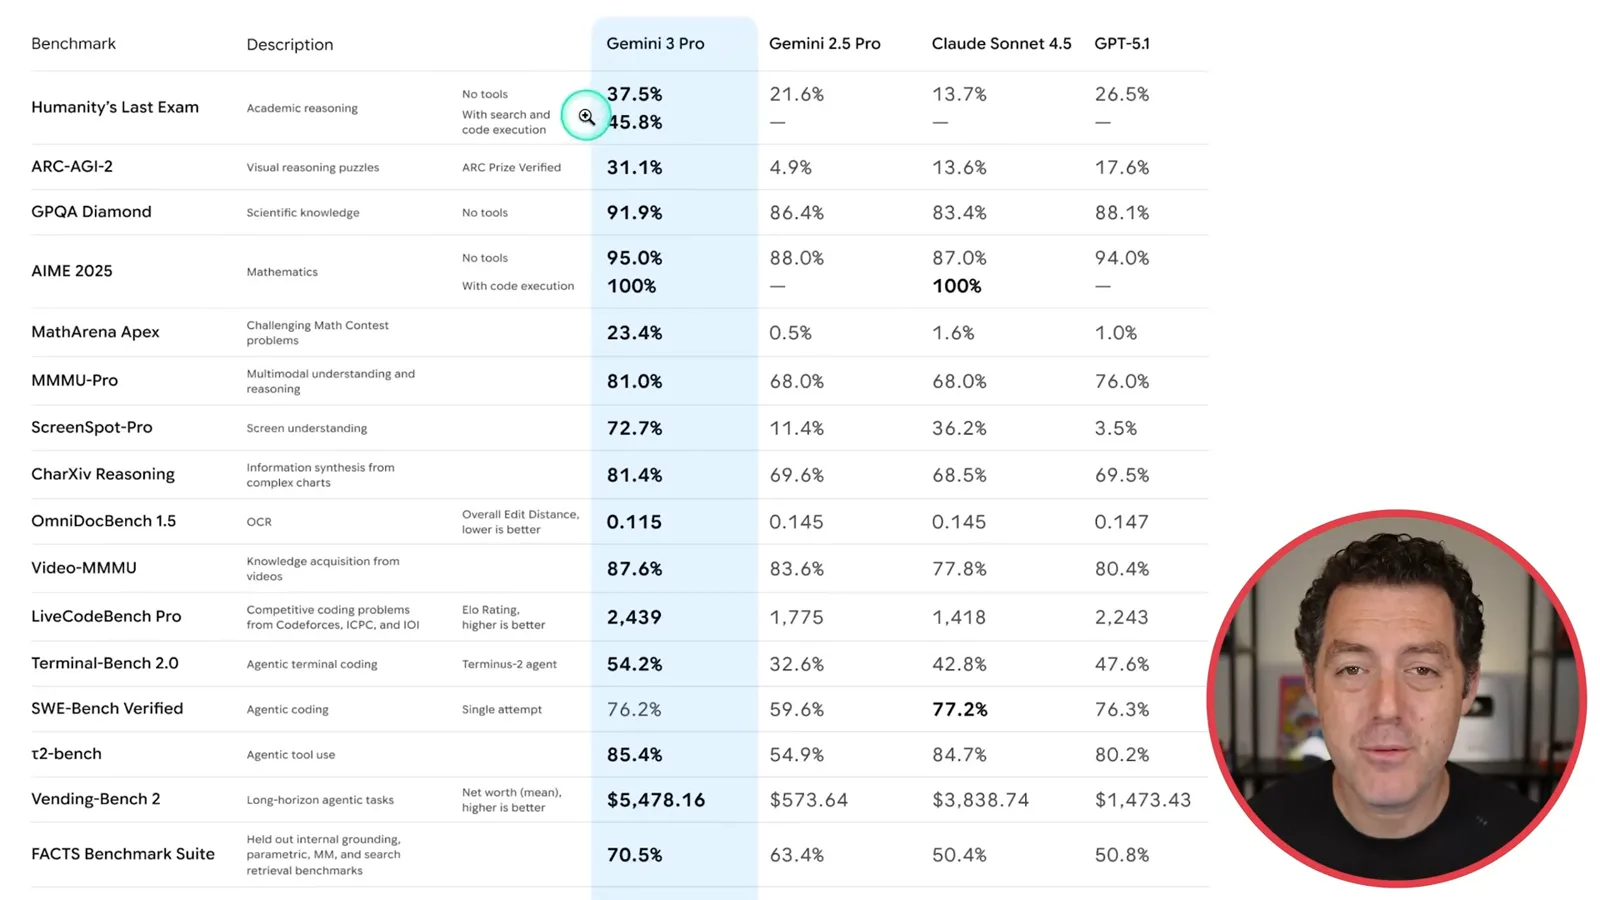
Google’s launch table reports Gemini 3 Pro at 37.5% on Humanity’s Last Exam without tools and 45.8% with search and code execution, compared with 21.6% for Gemini 2.5 Pro and 26.5% for GPT-5.1 in the displayed no-tool comparison. On ARC-AGI-2, the table reports 31.1%. These are results from particular evaluations and configurations, not a permanent ranking across all models and tasks.
The table reports 100% on AIME 2025 with code execution; Claude Sonnet 4.5 also has 100% in that displayed setting. On SWE-bench Verified, the chart lists Gemini 3 Pro at 76.2% and Claude Sonnet 4.5 at 77.2%, while GPT-5.1 is shown at 76.3%. Vending-Bench 2 shows a simulated net worth of $5,478.16 for Gemini 3 Pro, ahead of the other models on the chart.
The video includes a sponsored segment from Box about its own document-reasoning evaluation. Box reports an overall increase from 63% for Gemini 2.5 Pro to 85% for Gemini 3 Pro and larger gains on some industry subsets. The company describes multi-document extraction and reasoning tasks resembling enterprise workflows; these sponsor-reported results are specific to that evaluation and are not a general guarantee of enterprise performance.
Deep Think and multimodal input
He discusses Google’s reported Deep Think results and its generalization benchmark. He then demonstrates querying a YouTube video.
Google also presents benchmark results for Gemini 3 Deep Think, a more deliberative reasoning mode. Its chart reports 41% on Humanity’s Last Exam without tools, compared with 37.5% for Gemini 3 Pro, and 93.8% on GPQA Diamond. Google later made Deep Think available to Ultra subscribers in December 2025; that later rollout should not be confused with availability on the video’s launch date.
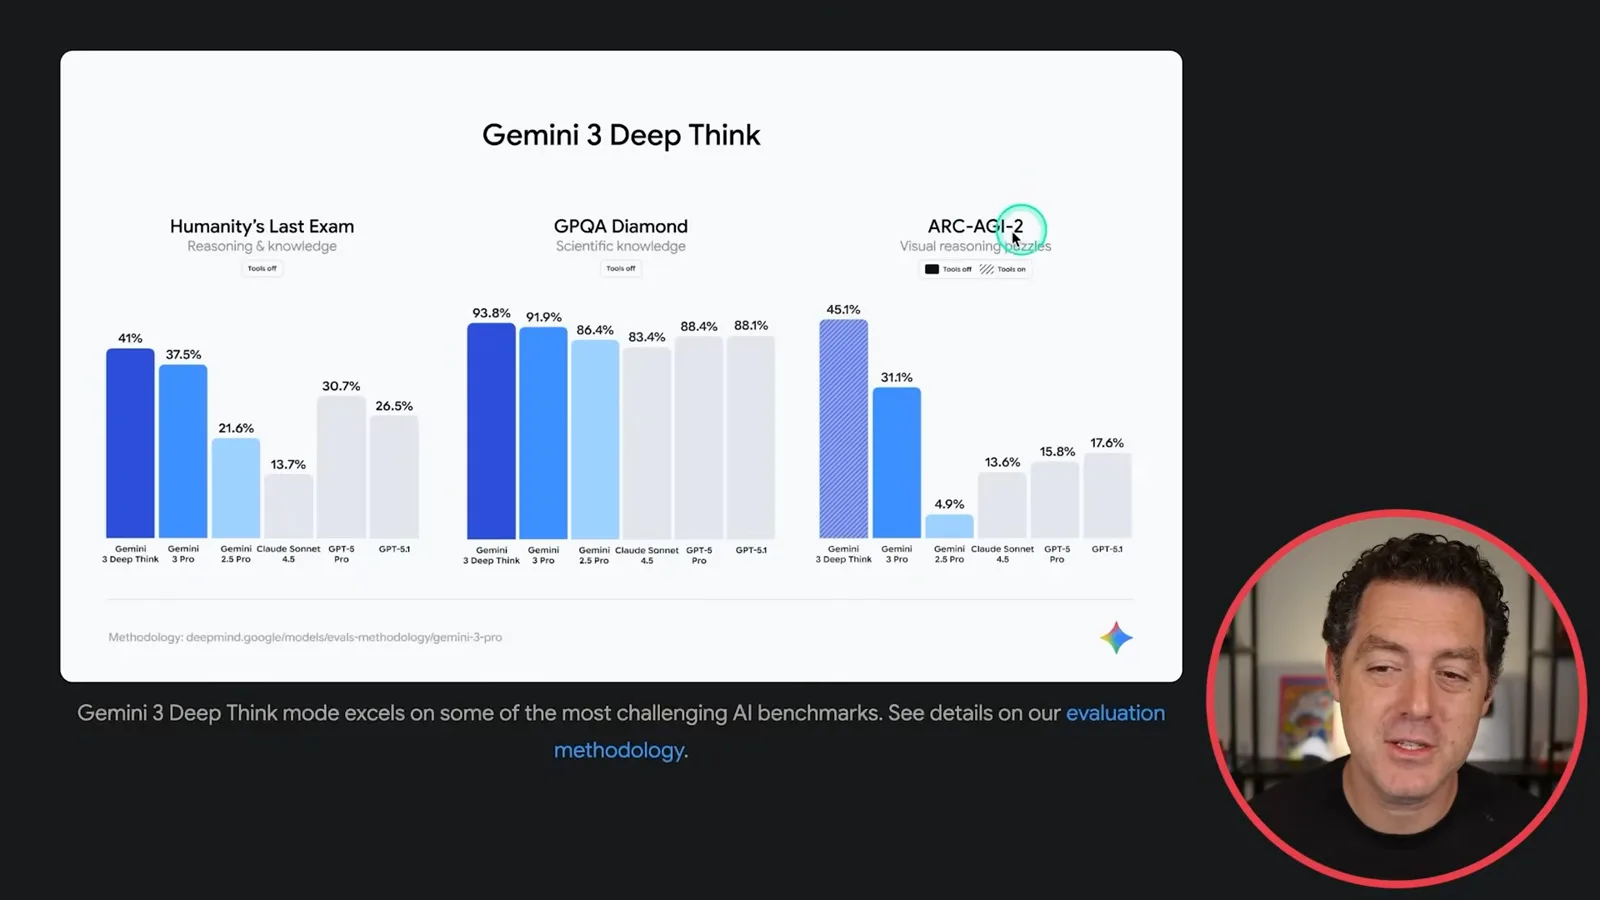
ARC-AGI-2 presents visual transformation puzzles: examples show an input and output, and the model must infer a rule for another case. I regard it as an important test of learning and generalization. Google’s chart reports 45.1% for Deep Think with tools and 31.1% for Pro; differing tool settings matter, and performance on this benchmark alone cannot establish general intelligence.
Gemini 3 accepts text, images, video, audio and code, with a context window of up to one million input tokens. I especially value video understanding because I use it to help create chapter markers. I describe the model as looking at video frame by frame, but that should not be taken to mean it examines every original frame: Google’s video documentation describes sampling frames, with settings varying by interface.
To demonstrate, I paste a YouTube link to an earlier video into AI Studio rather than downloading and uploading the file. The interface shows about 111,000 tokens. I ask the model to describe the frame at three minutes; it identifies a split screen, my blue shirt and a report excerpt, which I compare with the video. This is one illustrative query, not a systematic accuracy test.
Search interfaces and Antigravity
Google shows generated interfaces in Search and introduces an agentic coding environment. Berman anticipates broader adoption of customized interfaces.
Google also introduces Gemini 3 in Search’s AI Mode. In the example I show, a user supplies a paper and the system presents a generated interface for exploring an RNA polymerase topic. The demonstration labels its screen images as simulated and sequences shortened. I predict that dynamically generated search pages may become much more common, but that is my forecast, not an announced guarantee.
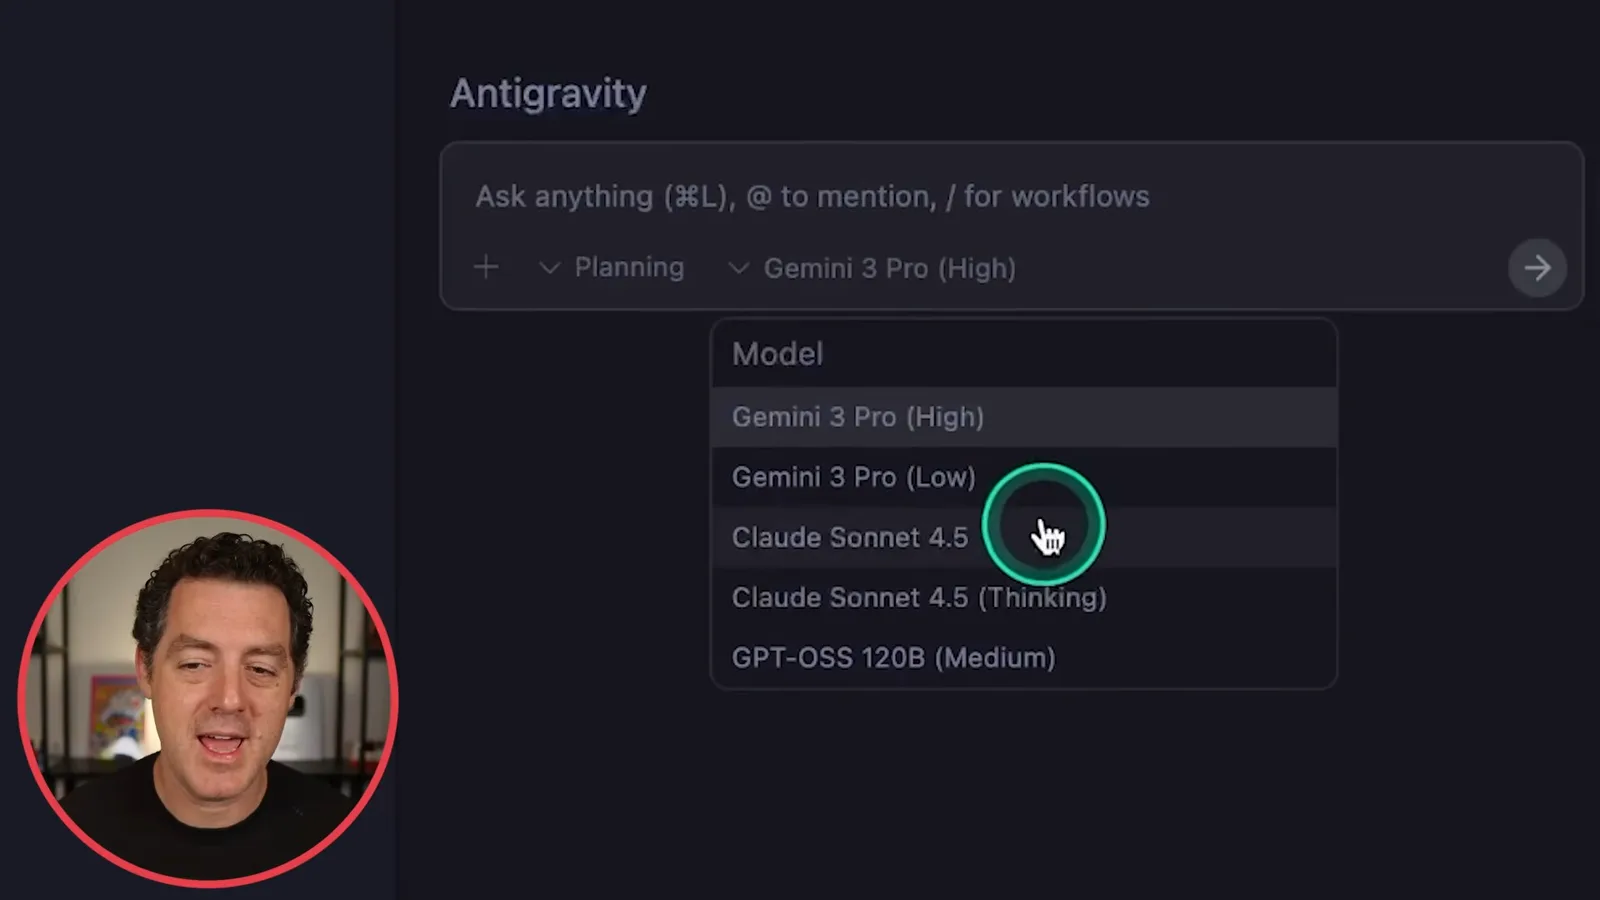
Google Antigravity is an agentic development platform with a familiar VS Code-like editor, competing with tools such as Cursor and Windsurf. The model selector shown in the video lists Gemini 3 Pro, Claude Sonnet 4.5 and GPT-OSS 120B. I plan to test Gemini 3 Pro High in a later video; the listed choices should not be generalized into support for every model.
Long-horizon tasks and Gemini Agent
Berman revisits the vending simulation and discusses an experimental inbox-organizing workflow. He distinguishes the product demonstration from his own limited use.
Vending-Bench 2 asks a model to manage a simulated vending operation: choose inventory, respond to demand and decide when to restock. The aim is to examine coherent decisions over a long time horizon. That is a useful economic simulation, but a score in the benchmark is not evidence that a model has independently managed a real business.
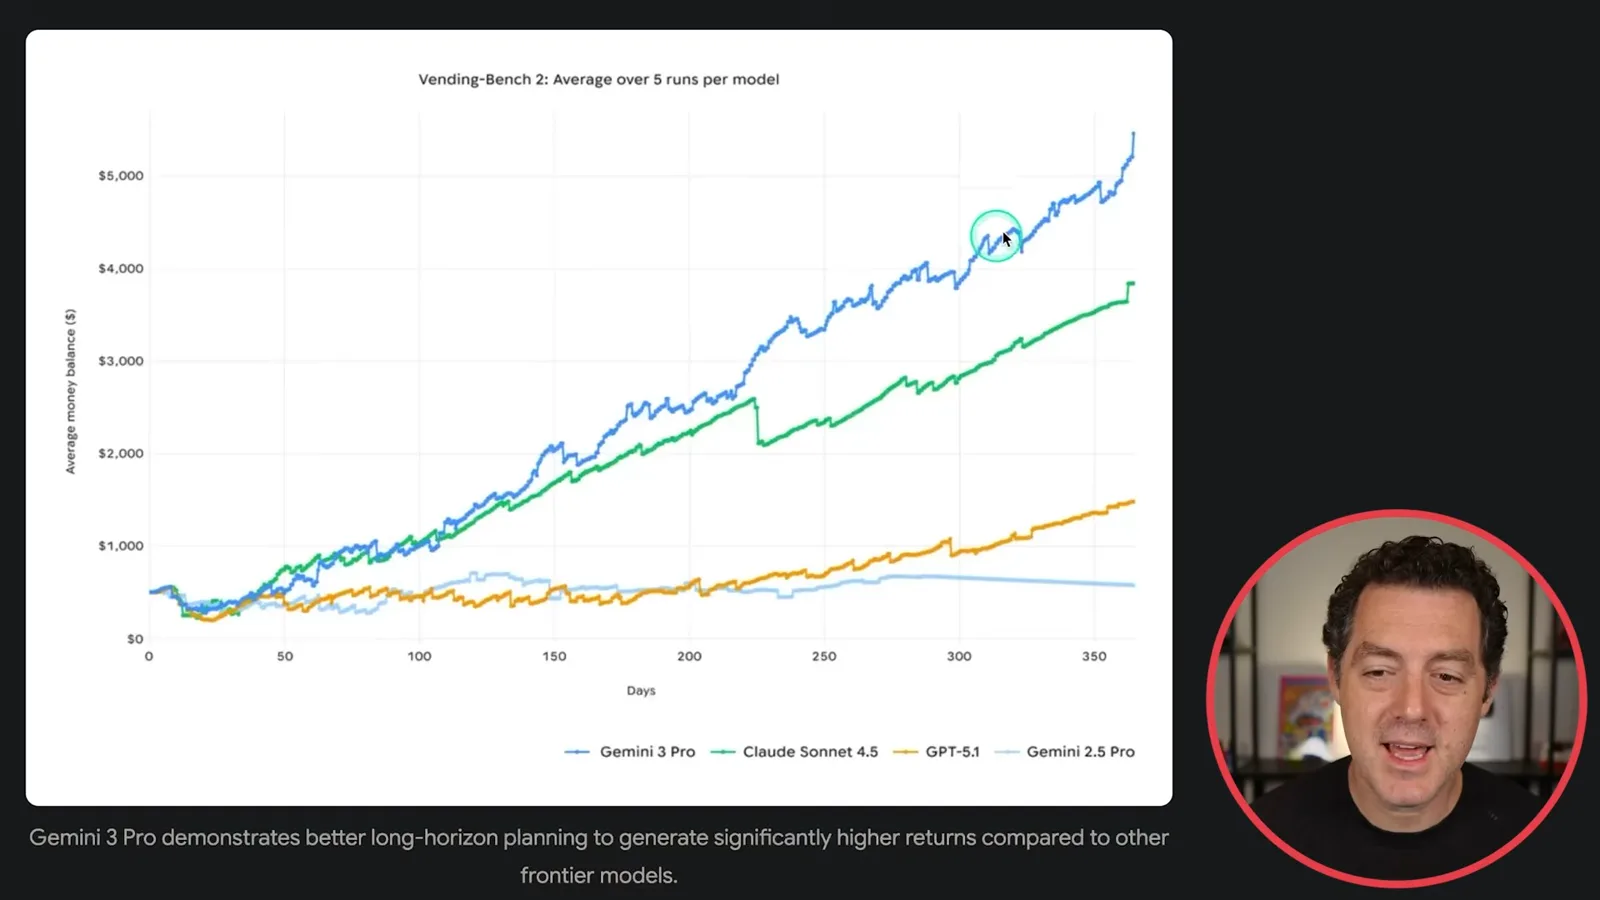
The chart averages five runs per model across roughly a year of simulated time. Gemini 3 Pro’s line climbs above $5,000, followed by Claude Sonnet 4.5, while GPT-5.1 and Gemini 2.5 Pro end lower. I find the continuing upward trajectory notable, while recognizing that the result is bounded by the simulation and the tested conditions.
Google also updates Gemini Agent, an experimental capability intended to complete multistep tasks. Its inbox example retrieves unread Gmail, creates a plan and presents suggested actions in a generated view. The user can review suggestions individually or accept them in bulk, and the assistant can draft replies based on the email thread.
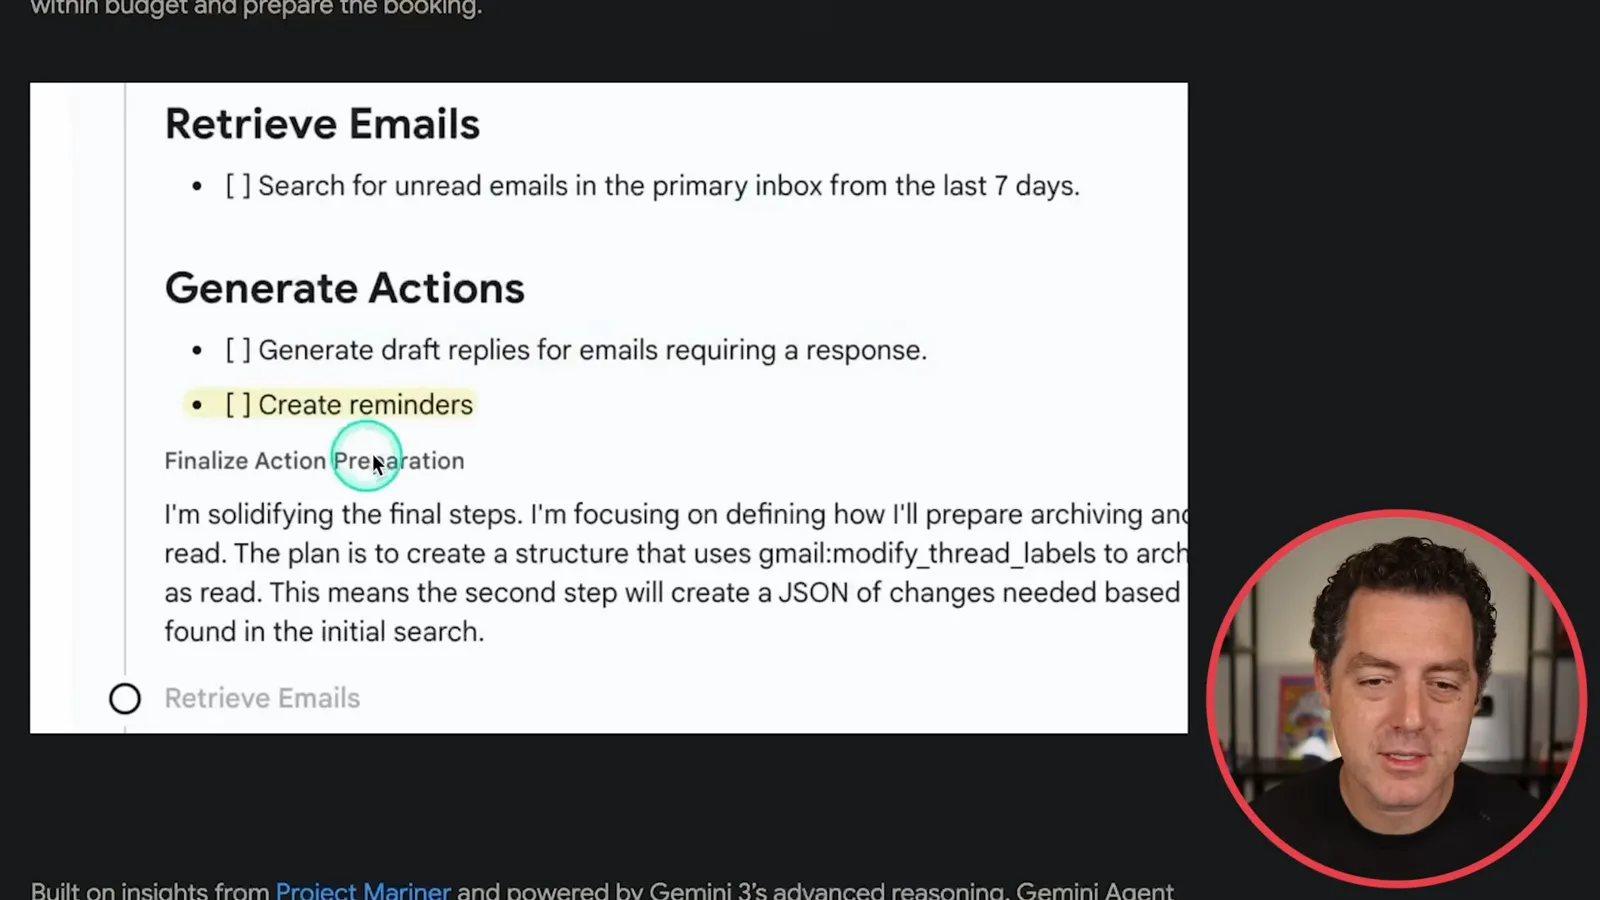
The agent demonstration looks promising to me, but I have not spent much time using the feature yet. A shown workflow and a plan for future testing are different from evidence that the agent can reliably organize every inbox or take actions without appropriate permissions.
Model card and hardware
The model card describes Gemini 3 Pro’s inputs, architecture and hardware. Berman identifies Google’s custom TPUs as a competitive advantage.
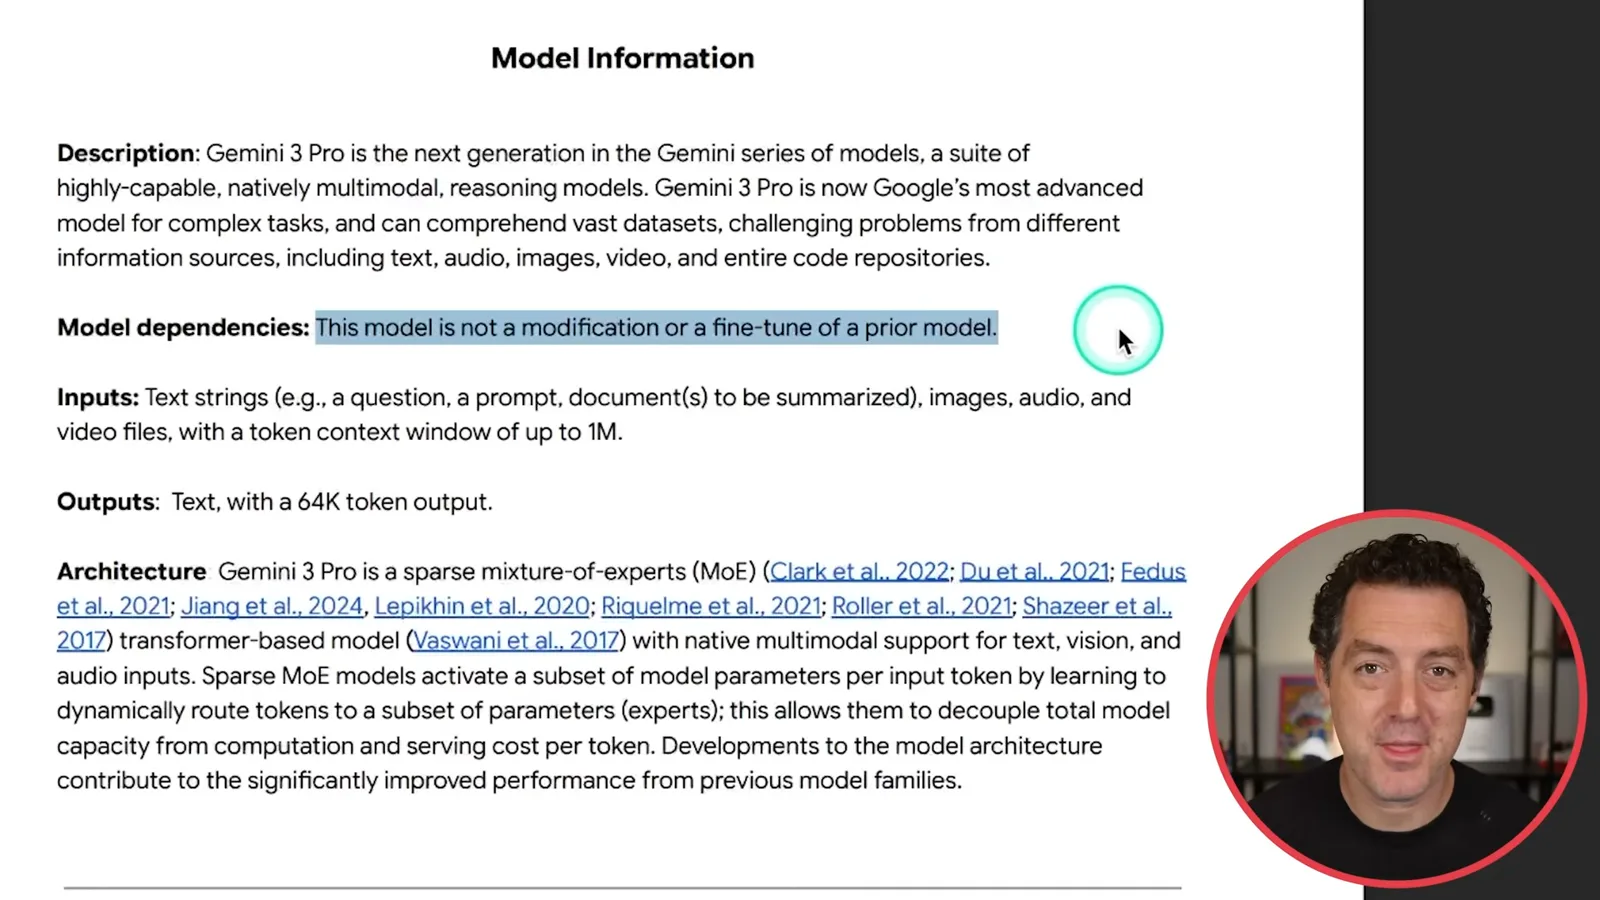
Finally, Google’s model card states that Gemini 3 Pro is not a modification or fine-tune of a previous model. It describes text, image, audio and video inputs, up to one million input tokens and a 64,000-token text output. The model uses a sparse mixture-of-experts architecture and Google TPUs for training and inference. I consider Google’s custom hardware an important advantage.
Sur la même chaîne
 34:21EN
 Matthew Berman· 27 oct. 2026Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 0:26ENMatthew Berman· 25 oct. 2026Sam Altman on Human Values and Problem-Solving in an AI WorldSam Altman · OpenAIIn a short interview excerpt, Altman considers the enjoyment of solving hard problems and the human role in interpreting results.
 0:36ENMatthew Berman· 25 oct. 2026Kimi K3.1 and a Rubik’s Cube Solver DemonstrationMatthew Berman · Forward FutureMatthew Berman shows a scrambled virtual cube being solved and gives the Kimi K3.1 test a favorable assessment.
 0:21ENMatthew Berman· 24 oct. 2026An AI-Generated Kimi Benchmark Chart Used Invented ScoresMatthew Berman · Forward FutureMatthew Berman asks for a graph of Kimi K3.1 Pro benchmarks, then discovers that the displayed figures are illustrative placeholders.
 25:50ENMatthew Berman· 24 oct. 2026Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.
 32:20ENMatthew Berman· 23 oct. 2026Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.